An Initial Step towards a Vision-Language Foundation Model for Autonomous Driving
Qwen Team · Huazhong University of Science and Technology
📑 Technical Report |
📖 Blog |
🤗 Hugging Face |
🤖 ModelScope
Welcome to the GitHub repository of Qwen-Drive-1.0. Here you can find official information about
Qwen-Drive, and post your questions (Issues).
Introduction
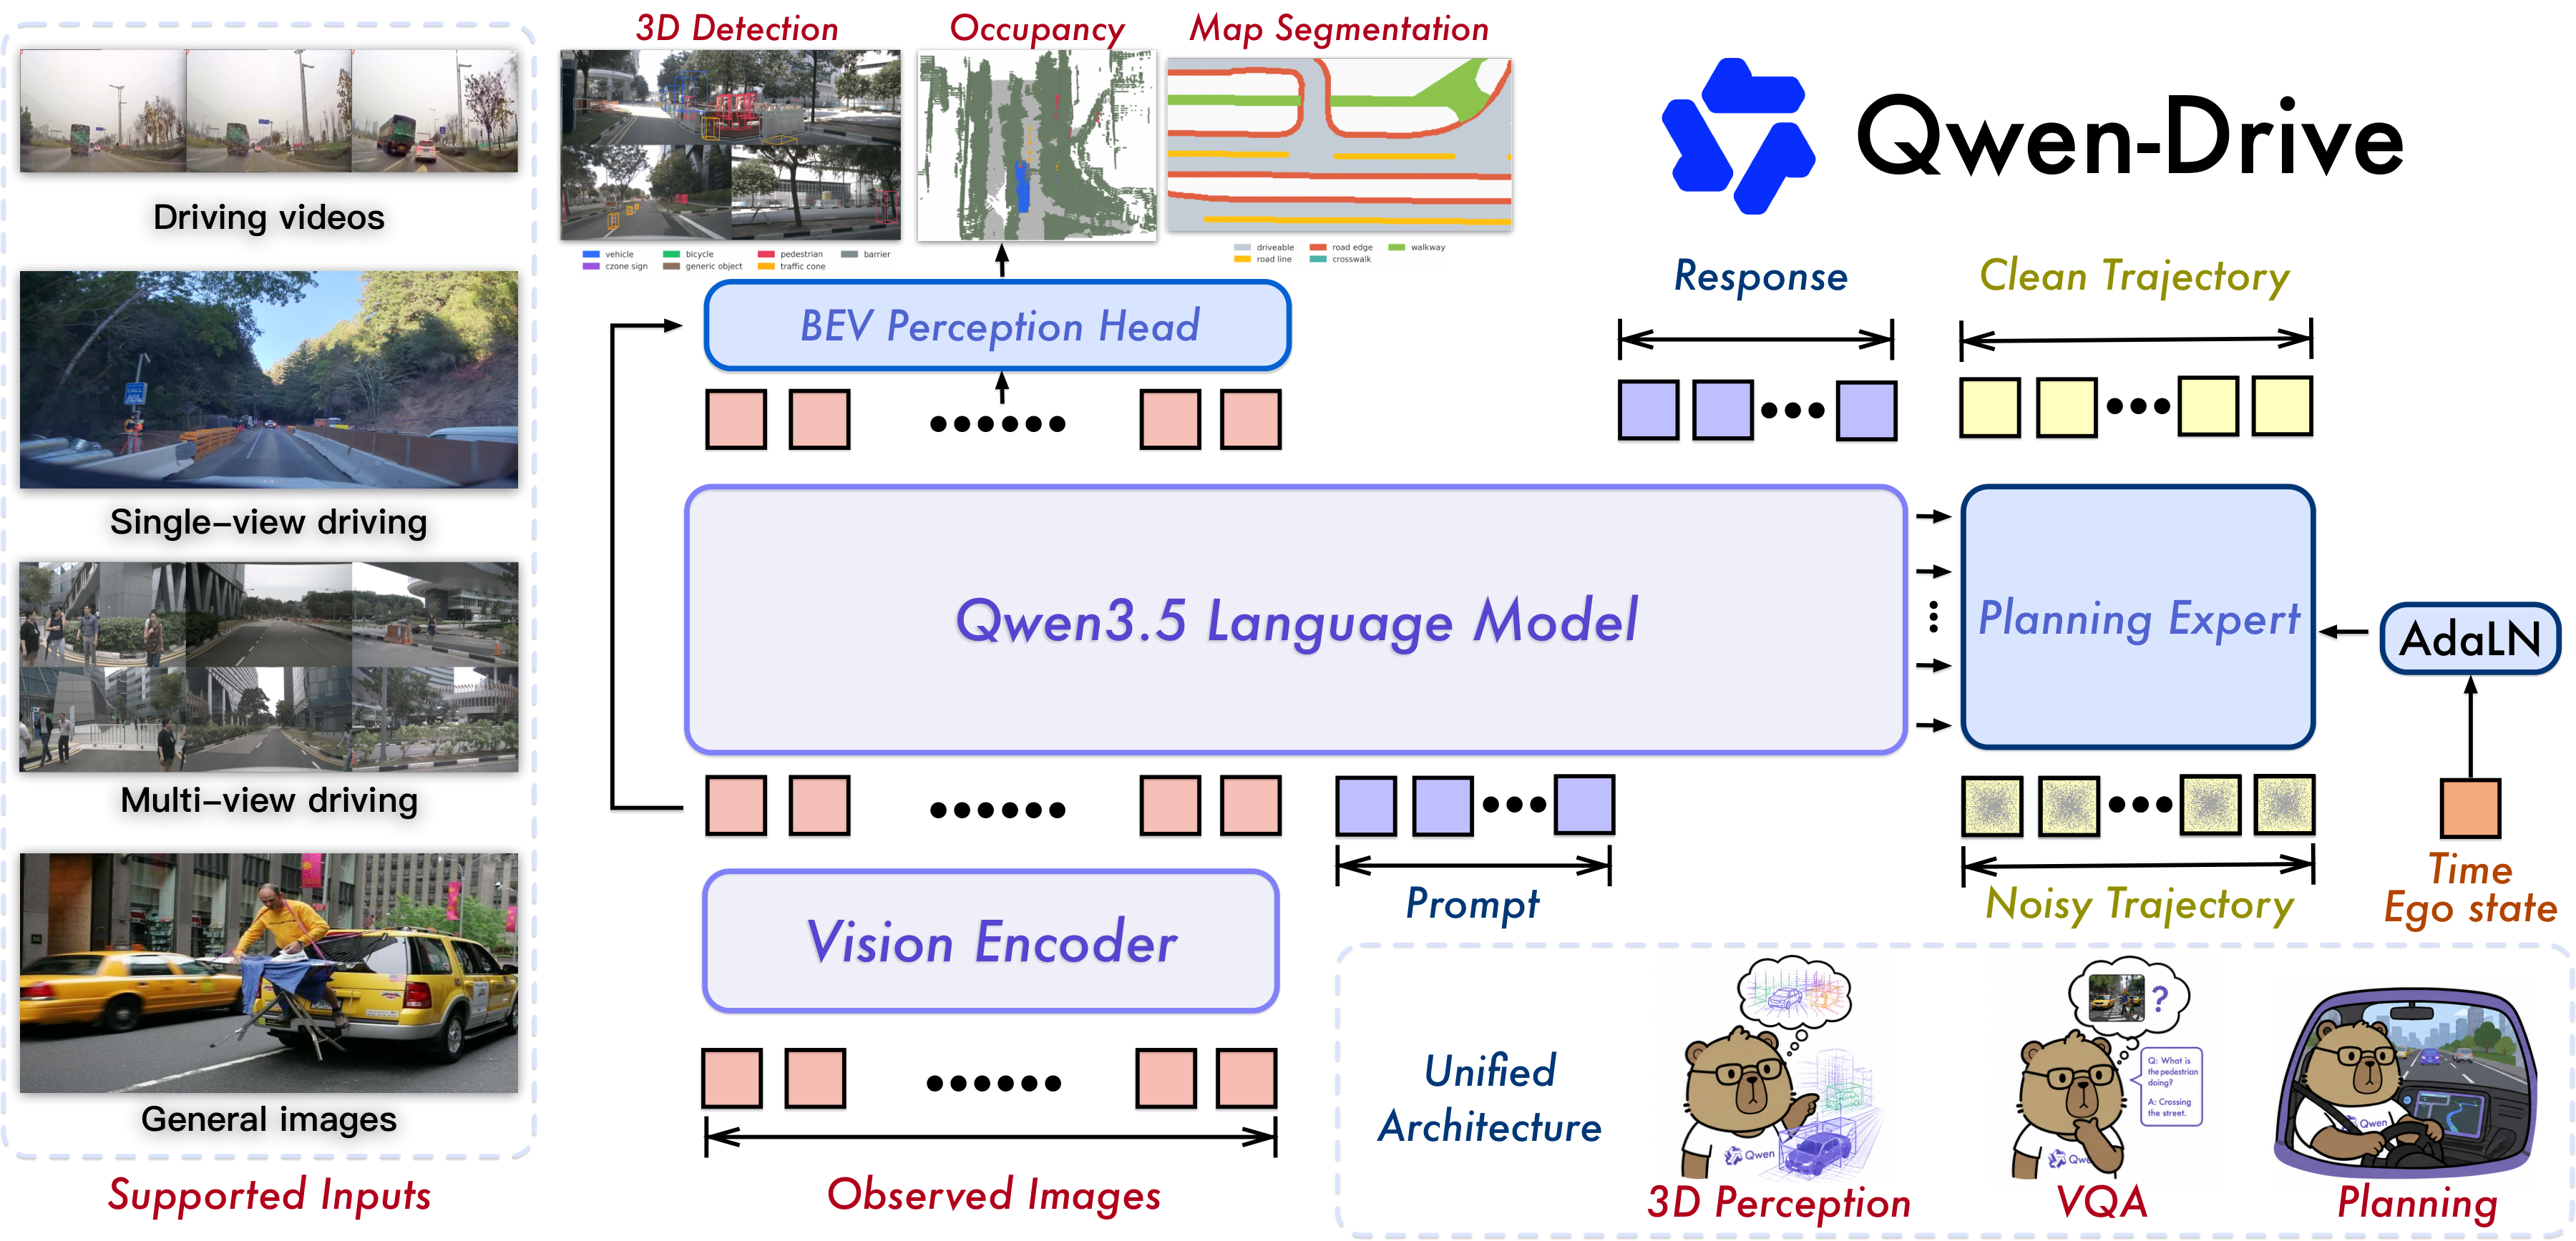
Qwen-Drive-1.0 retains the architecture of the pretrained Qwen3.5 vision-language model and
integrates 3D perception, visual question answering, and motion planning within a
unified framework. The natively multimodal Qwen3.5-4B serves as the shared VLM, with two
external modules attached:
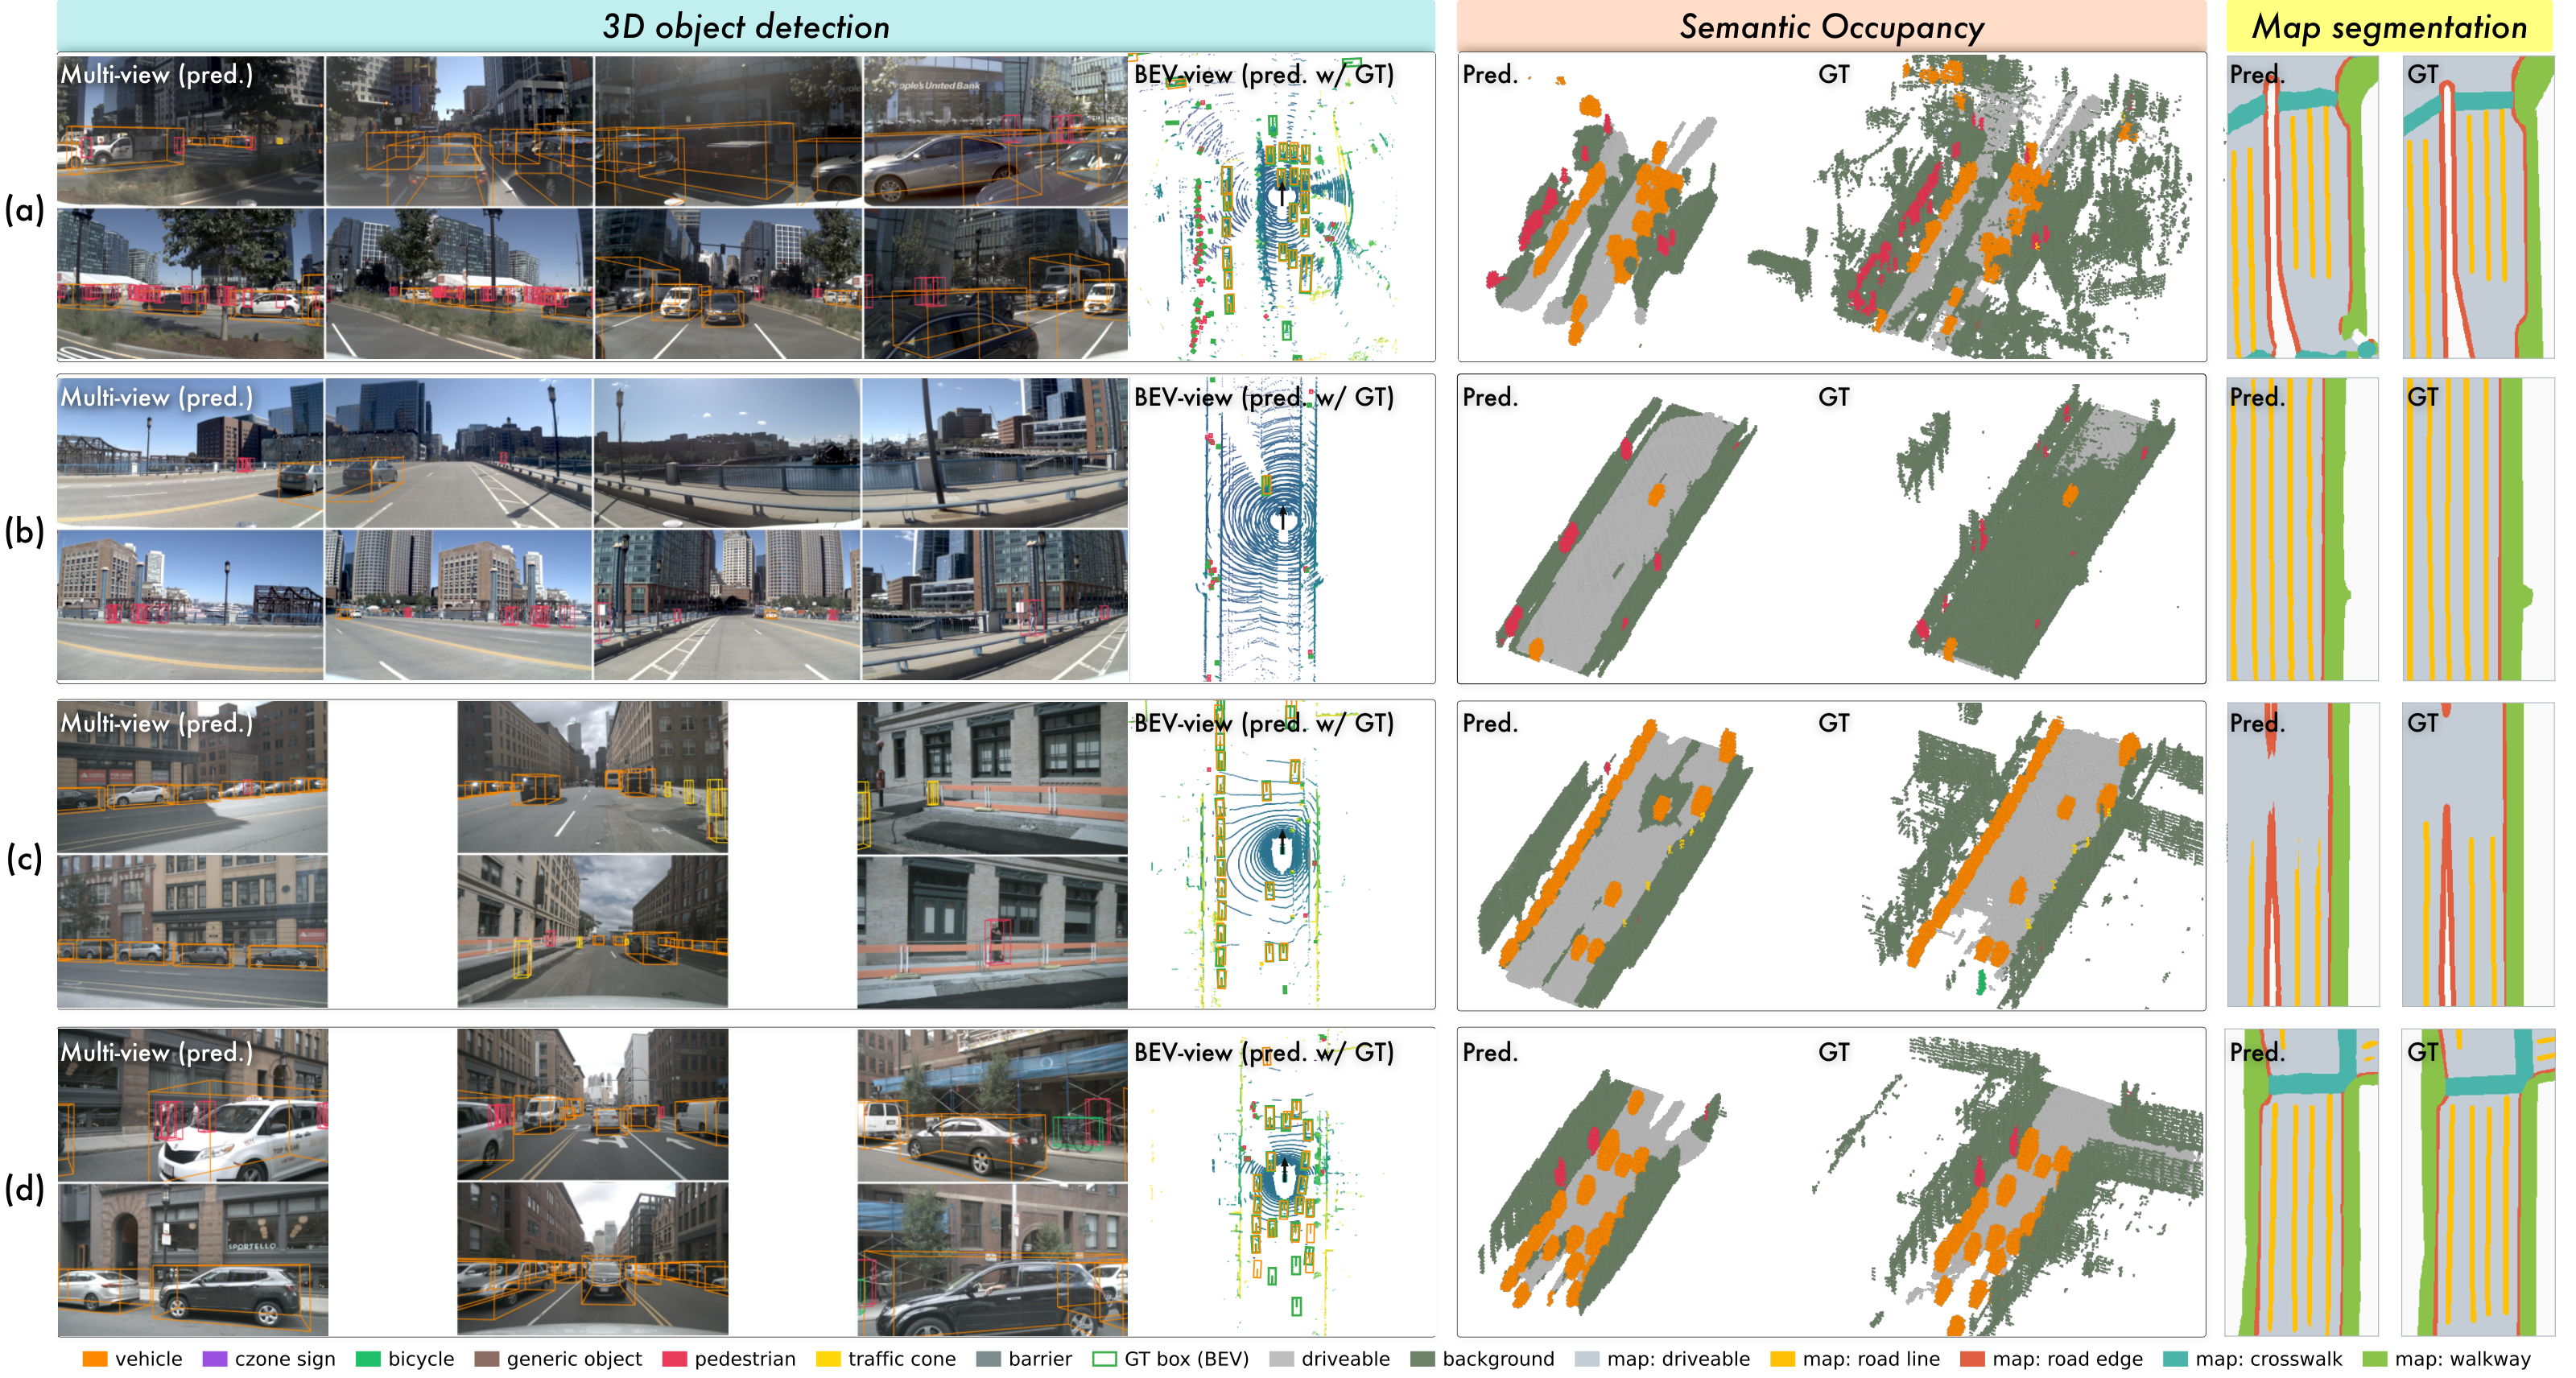
- A BEV Perception Head jointly performs 3D object detection, semantic occupancy
prediction, and BEV map segmentation. It serves as a probe of the 3D information accessible
from the shared representations and provides an explicit, inspectable interface to 3D scene
structure.
- A Planning Expert conditions on shared VLM representations to generate future ego
trajectories.
- The original VLM's LLM Decoder remains unchanged, and can handle both General VQA and Driving VQA tasks.
We propose a staged training strategy that integrates perception, language, and planning objectives. By combining driving-specific supervision with general-purpose vision-language data, the model achieves specialized driving competence while retaining broad visual understanding and instruction-following capabilities. This approach is supported by a unified data pipeline that: (1) maps heterogeneous perception annotations into a shared label space; (2) re-annotates driving VQA responses to ensure format and factual consistency; and (3) standardizes trajectories from multiple public driving datasets into a unified waypoint representation.
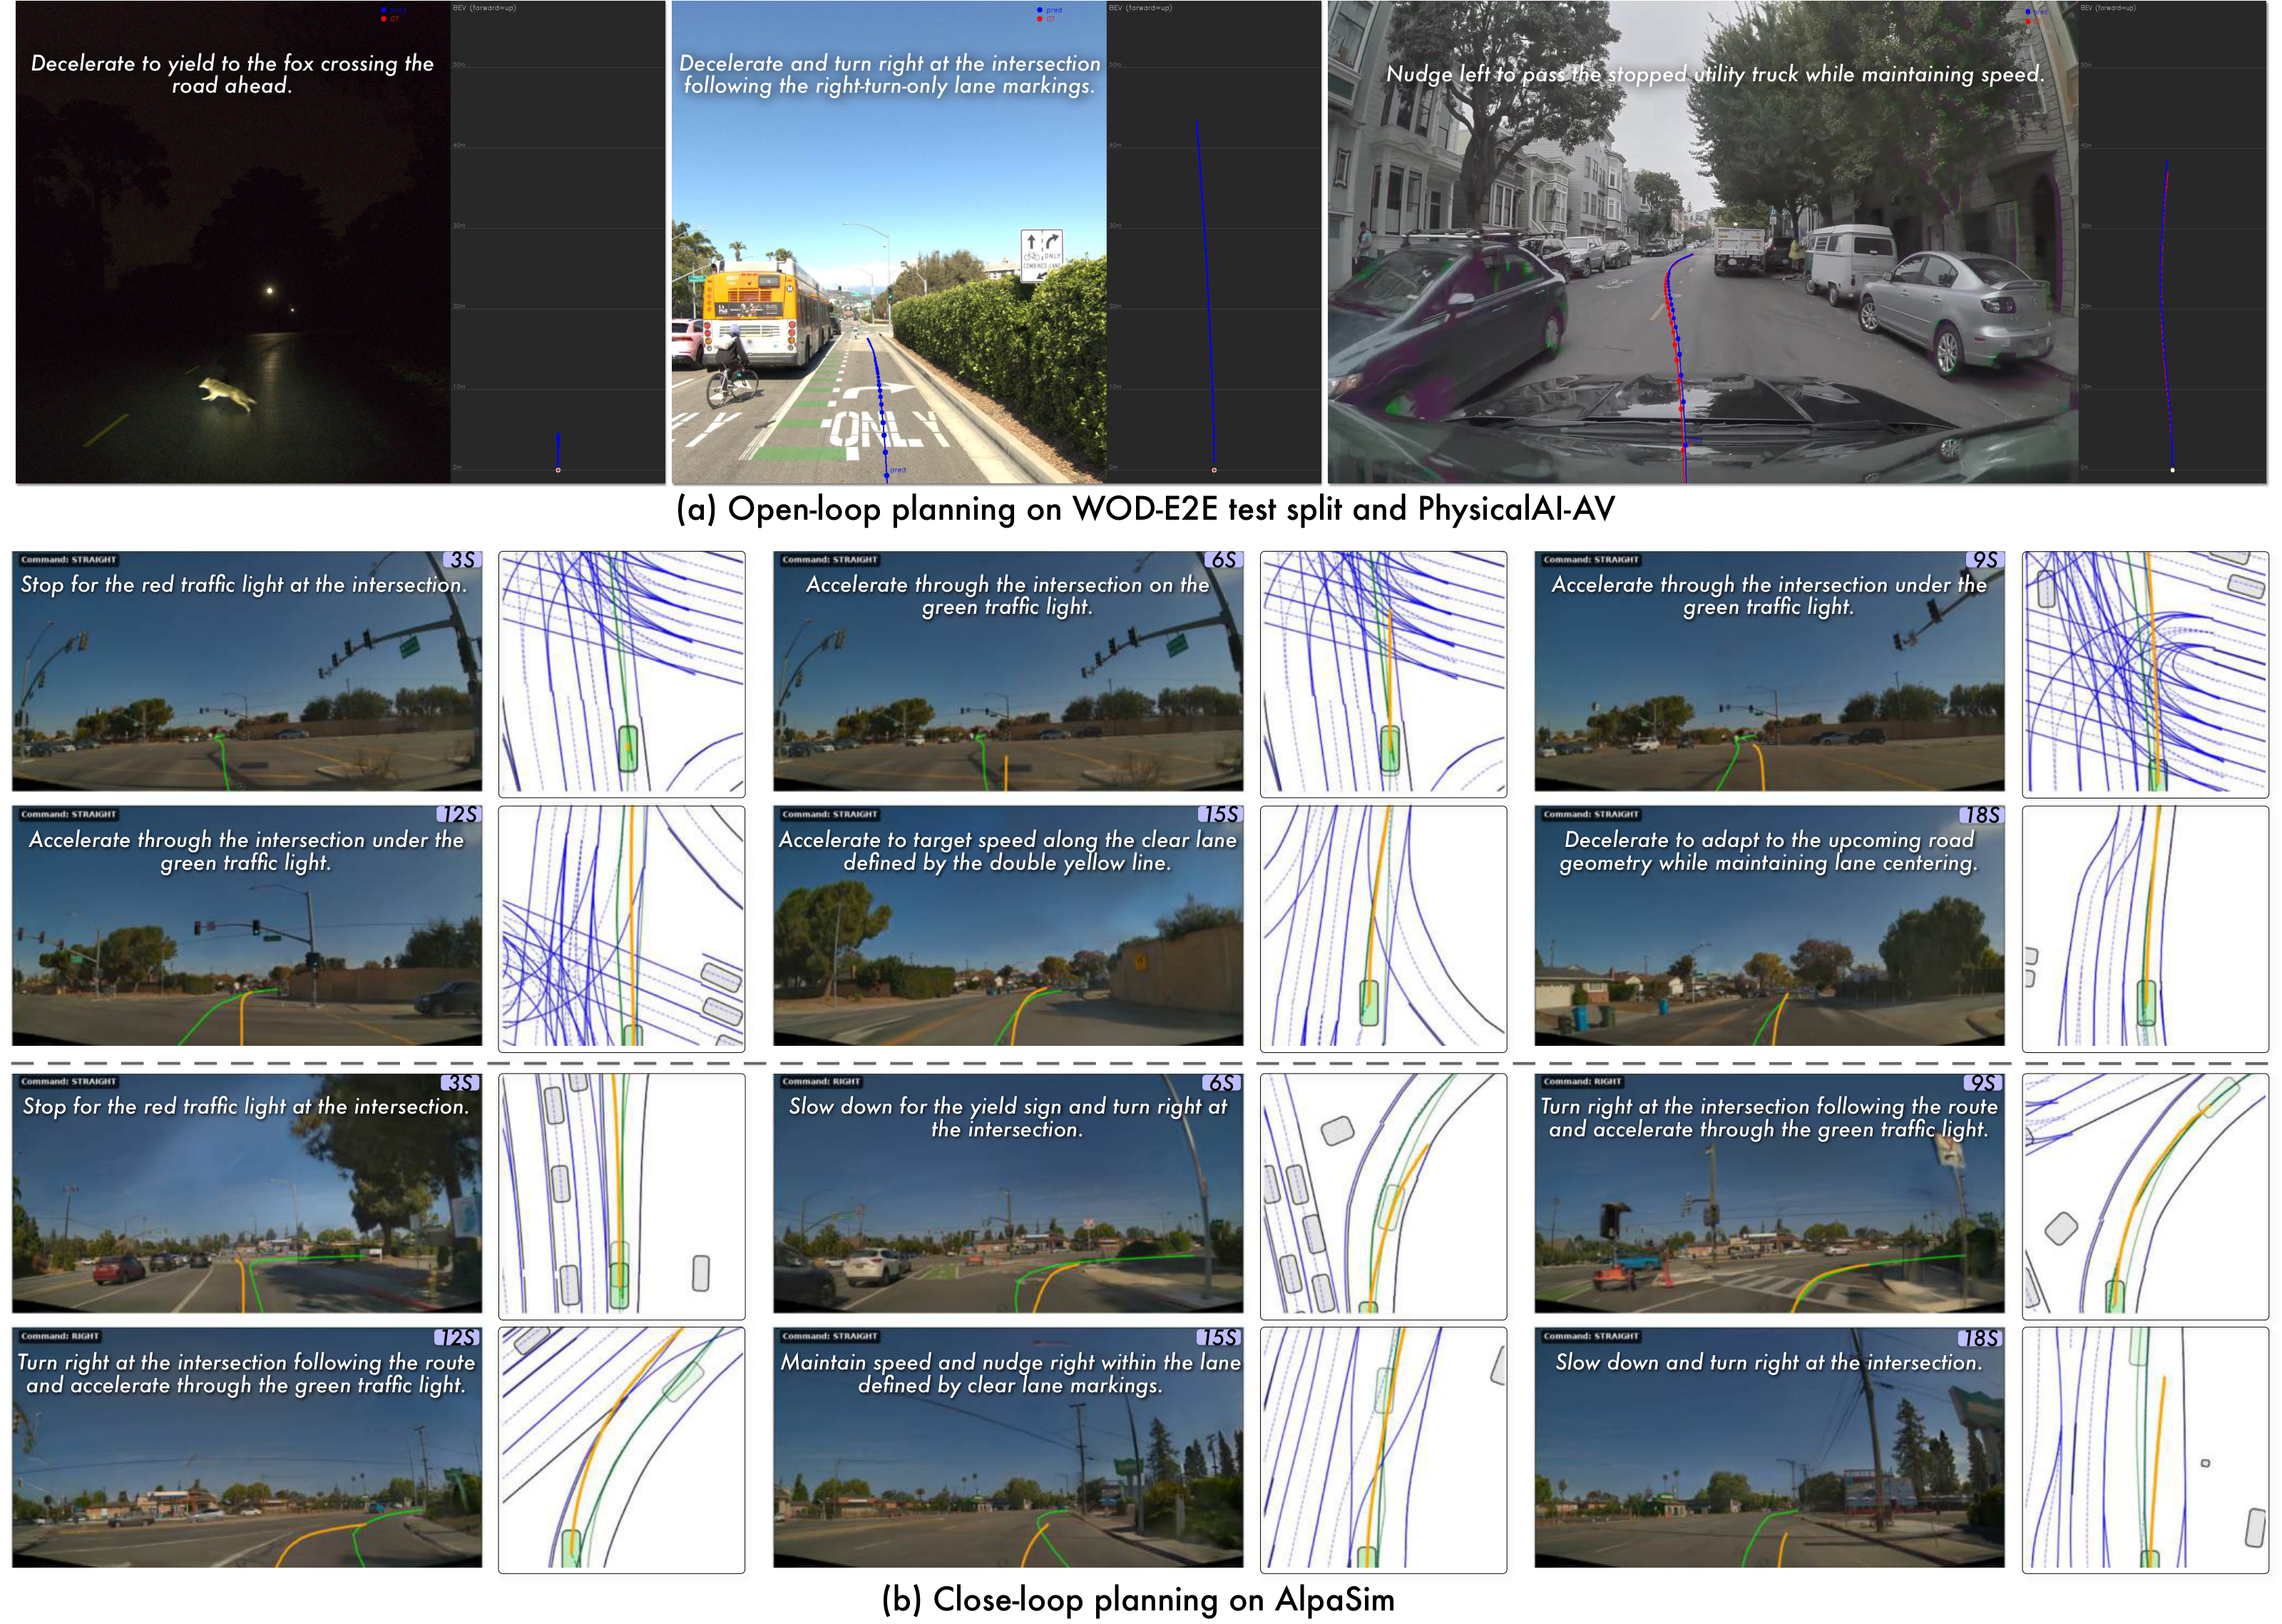
Planning
|
SFT |
RL |
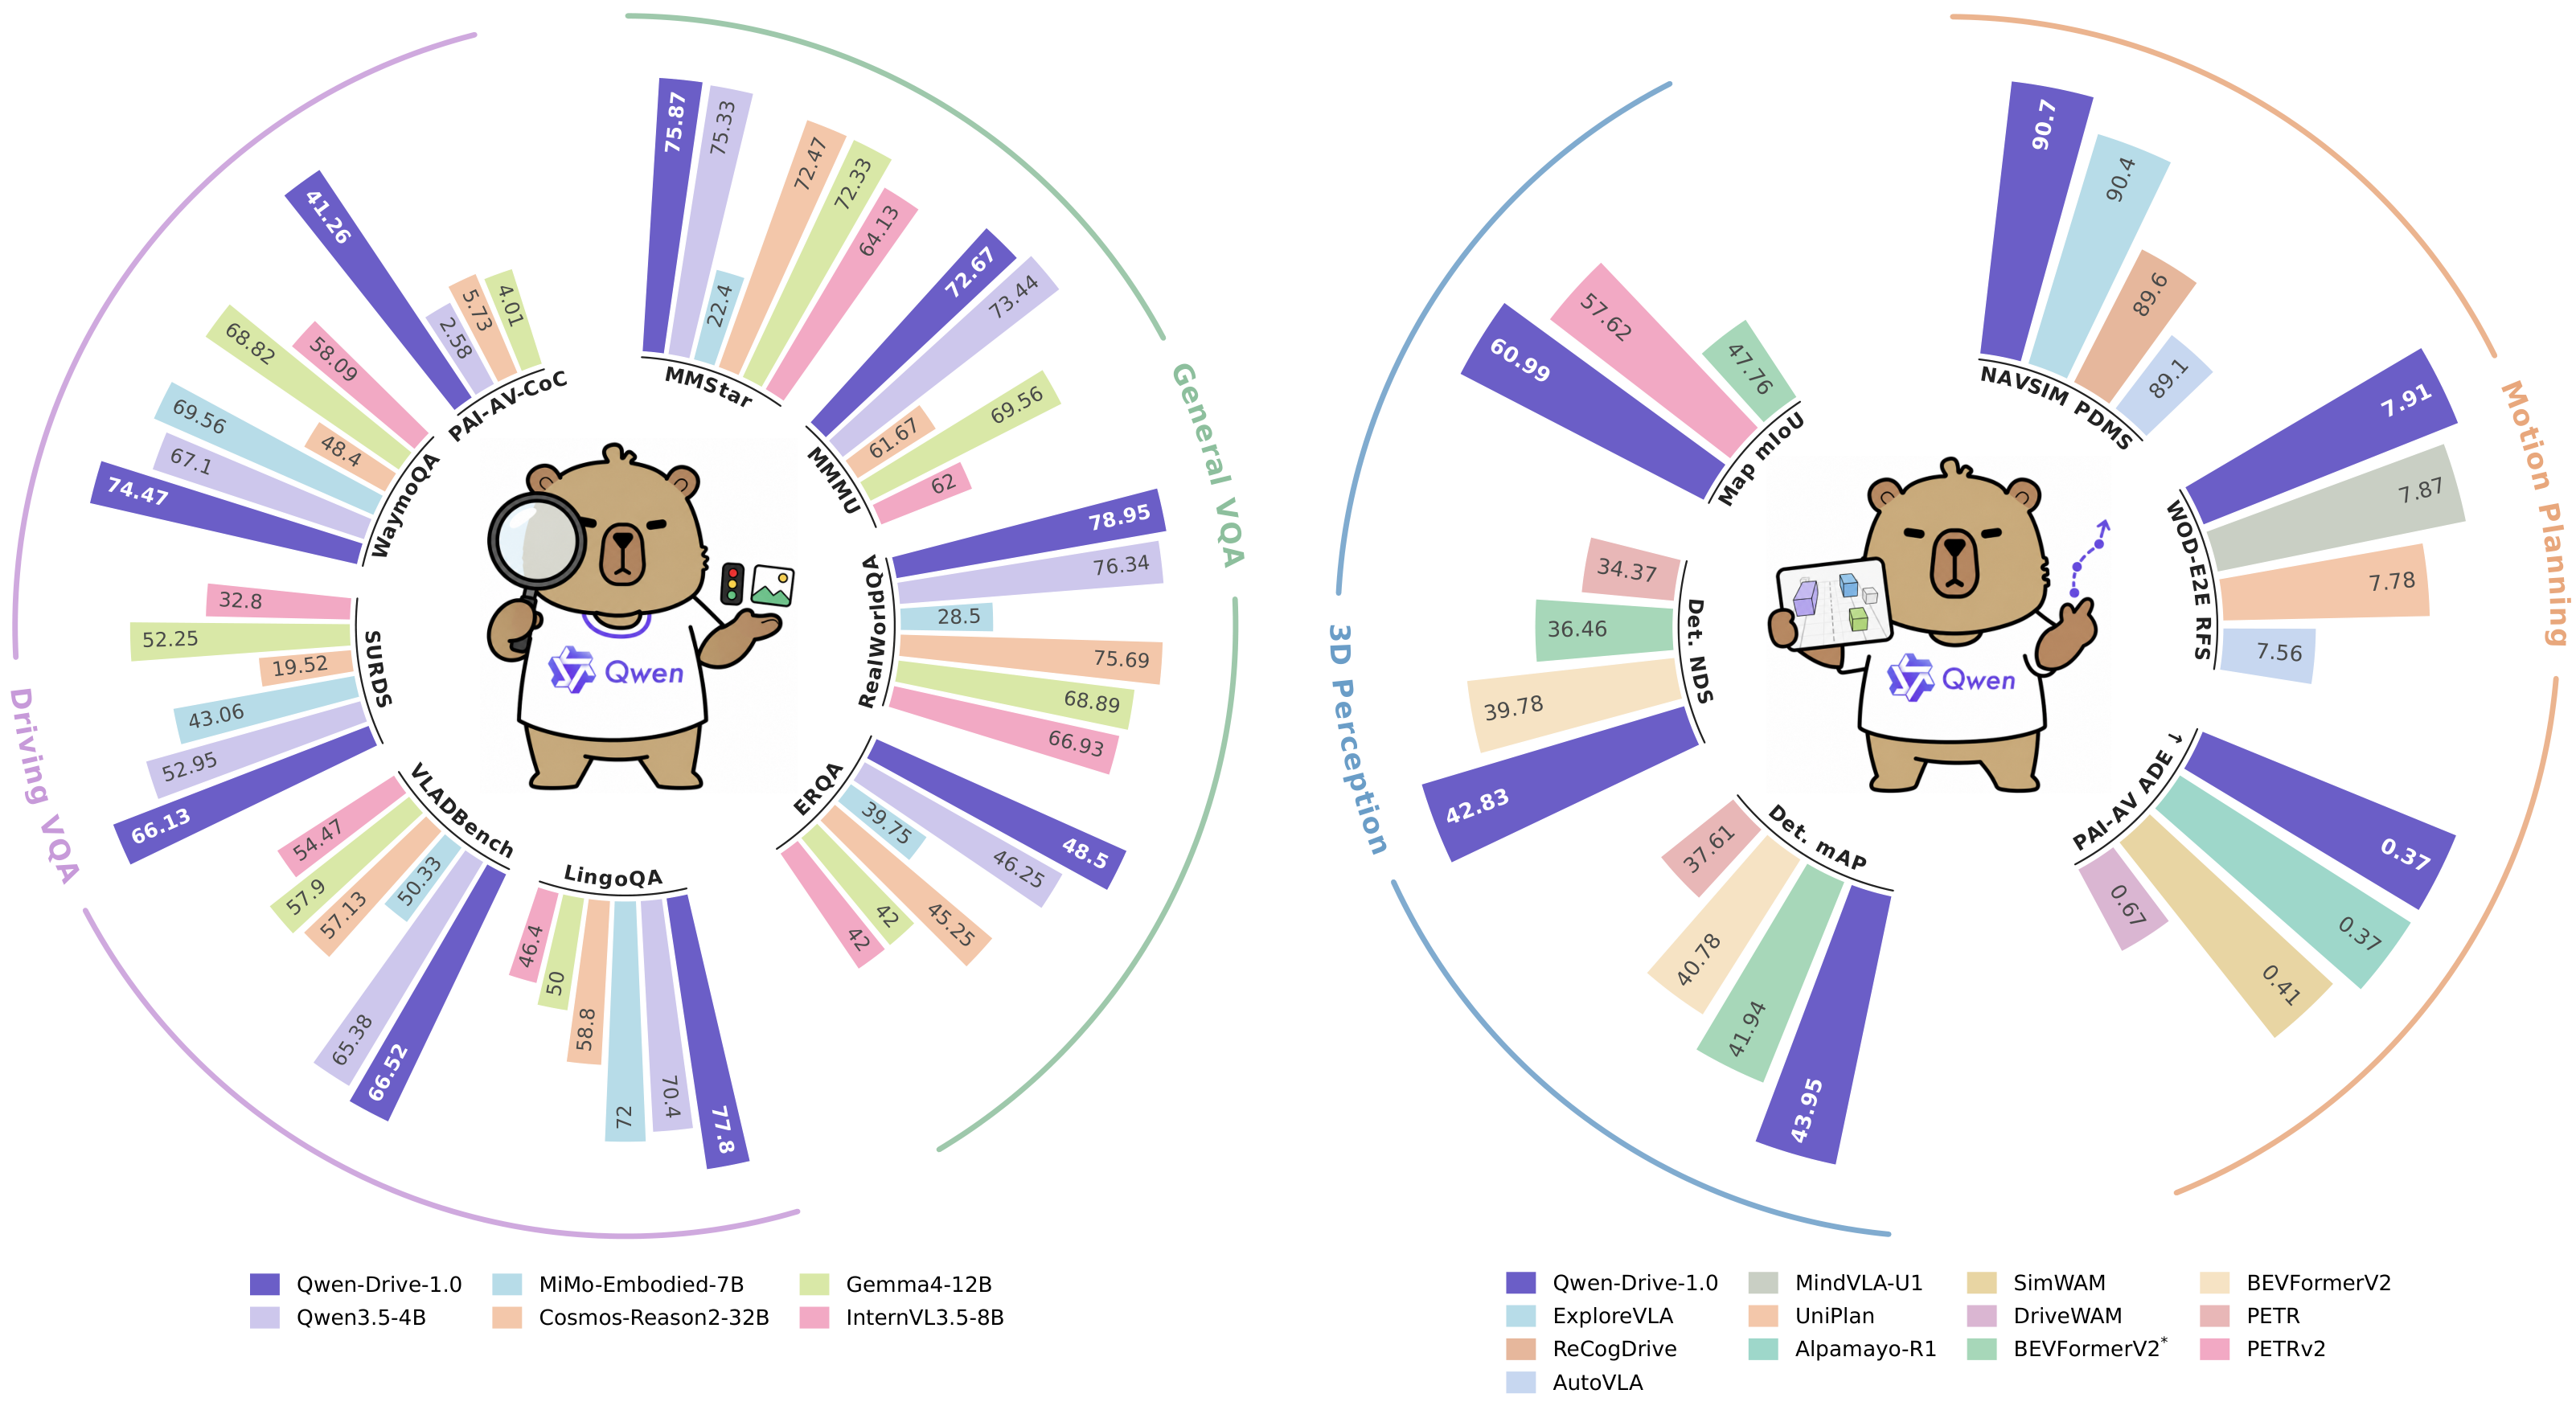
| NAVSIM v1.1 navtest, PDMS |
88.2 (89.3 best-of-6) |
90.7 (91.4 best-of-6) |
| Waymo Open Dataset E2E test, RFS |
7.78 |
7.91 |
| NVIDIA PhysicalAI open-loop, minADE 3 s |
0.34 m |
0.38 m |
SFT is the imitation-trained Planning Expert. RL is the same expert after reward
optimization on the benchmark objectives. Both share one VLM. 3D detection, occupancy and
map segmentation results are in the technical report, full planning tables in
docs/evaluation.md.
Driving VQA
|
LingoQA |
Ego3D RMSE ↓ |
VLAD |
SURDS |
WaymoQA safety |
WaymoQA all |
CoC all |
IH |
| InternVL3.5-8B-Instruct |
46.4 |
23.01 |
54.5 |
32.8 |
54.5 |
58.1 |
– |
47.5 |
| LLaVA-OV2-8B |
41.2 |
24.97 |
58.7 |
38.6 |
49.7 |
55.2 |
0.6 |
54.0 |
| Qwen3.5-4B |
70.4 |
13.17 |
65.4 |
53.0 |
62.5 |
67.1 |
2.6 |
59.0 |
| Cosmos-Reason1-7B |
45.2 |
26.71 |
33.6 |
8.5 |
39.5 |
43.9 |
3.2 |
30.5 |
| Cosmos-Reason2-8B |
59.6 |
12.62 |
56.4 |
19.5 |
57.7 |
57.9 |
1.7 |
56.0 |
| Cosmos3-nano |
65.0 |
22.41 |
57.7 |
39.7 |
56.9 |
58.4 |
4.0 |
2.0 |
| MiMo-Embodied-7B |
72.0 |
9.85 |
50.3 |
43.1 |
66.5 |
69.6 |
– |
61.0 |
| Alpamayo-1.5-10B |
64.0 |
25.31 |
9.1 |
3.1 |
42.6 |
44.4 |
3.4 |
3.0 |
| Qwen-Drive-1.0-SFT |
77.8 |
7.78 |
66.5 |
66.1 |
70.7 |
74.5 |
41.3 |
71.0 |
LingoQA is scored with Qwen-Plus as the judge instead of the official LingoJudge, which we found to score leniently and inconsistently across scenarios. Under the official LingoJudge protocol Qwen-Drive-1.0-SFT obtains a LingoScore of 79.4. – marks an invalid or unparsable response.
On driving-scene understanding, Qwen-Drive-1.0 improves markedly over its Qwen3.5-4B base
while keeping general vision-language ability intact. Driving QA and spatial understanding,
with overall causal-reasoning accuracy on PAI-AV Chain-of-Causation (CoC) and an in-house
Chinese urban driving-decision set (IH):
General VQA and Reasoning:
|
MMBench |
MMStar |
MMMU |
MMMU-Pro std |
MMMU-Pro vis |
CharXiv |
OCRBench |
RealWorldQA |
SimpleVQA |
CountQA |
| InternVL3.5-8B-Instruct |
80.0 |
64.1 |
62.0 |
46.4 |
42.3 |
41.7 |
83.2 |
66.9 |
40.8 |
20.9 |
| LLaVA-OV2-8B |
82.7 |
64.9 |
54.7 |
36.3 |
26.0 |
40.1 |
79.3 |
71.8 |
36.7 |
22.6 |
| Qwen3.5-4B |
87.1 |
75.3 |
73.4 |
64.9 |
61.3 |
65.1 |
86.9 |
76.3 |
47.8 |
35.9 |
| Cosmos-Reason1-7B |
80.0 |
63.5 |
54.2 |
38.4 |
35.8 |
39.7 |
85.2 |
67.5 |
45.0 |
18.5 |
| Cosmos-Reason2-8B |
82.8 |
65.3 |
59.1 |
36.1 |
43.5 |
42.5 |
87.0 |
67.5 |
45.3 |
22.3 |
| Cosmos3-nano |
79.6 |
66.7 |
60.9 |
46.4 |
40.8 |
42.1 |
85.2 |
69.7 |
45.0 |
23.6 |
| MiMo-Embodied-7B |
– |
22.4 |
– |
27.4 |
28.1 |
57.5 |
78.8 |
28.5 |
– |
22.6 |
| Alpamayo-1.5-10B |
7.5 |
26.1 |
27.4 |
15.6 |
13.5 |
1.5 |
3.2 |
46.9 |
– |
4.7 |
| Qwen-Drive-1.0-SFT |
85.5 |
75.9 |
72.7 |
62.7 |
59.7 |
64.4 |
86.4 |
79.0 |
46.1 |
31.7 |
Spatial Understanding and Grounding:
|
EmbSpatial |
ERQA |
RefSpatial |
Omni3D |
ODinW13 |
| InternVL3.5-8B-Instruct |
74.2 |
42.0 |
– |
– |
– |
| LLaVA-OV2-8B |
78.4 |
42.3 |
– |
– |
– |
| Qwen3.5-4B |
76.0 |
46.3 |
54.5 |
47.4 |
40.8 |
| Cosmos-Reason1-7B |
68.8 |
38.5 |
0.4 |
– |
4.8 |
| Cosmos-Reason2-8B |
77.6 |
43.3 |
51.8 |
32.9 |
40.2 |
| Cosmos3-nano |
77.9 |
41.3 |
– |
32.3 |
35.9 |
| MiMo-Embodied-7B |
45.1 |
39.8 |
2.2 |
– |
– |
| Alpamayo-1.5-10B |
20.6 |
27.5 |
– |
– |
– |
| Qwen-Drive-1.0-SFT |
78.9 |
48.5 |
50.8 |
45.8 |
45.9 |
Comparisons are reproduced under one protocol with near-deterministic decoding; see
the technical report for the full setup.
Models
The model can be downloaded from Hugging Face or ModelScope. Everything ships in one directory. The VLM sits at its root, shared by every task, and each task head in a subfolder beside it.
Qwen-Drive-1.0-4B/          9.1 GB  the VLM, which on its own serves the VQA mode
├── planner-sft/            2.1 GB  Planning Expert, imitation-trained
├── planner-rl/             2.1 GB  Planning Expert after reward optimization
└── perception/             0.5 GB  BEV perception head
A head is attached when the VLM is loaded:
model = QwenDriveForPlanning.from_pretrained(
    "Qwen-Drive-1.0-4B", planner="Qwen-Drive-1.0-4B/planner-rl", dtype=torch.bfloat16
)
planner-rl was reward-optimized only on reasoning-conditioned rollouts, so run it in the
reasoning planning mode. planner-sft covers both direct and reasoning planning.
Install
A GPU with 24 GB+ of memory is recommended.
git clone <repository-url> qwen-drive && cd qwen-drive

# Any Python virtual environment works; conda is shown here
conda create -n qwen-drive python=3.10
conda activate qwen-drive

pip install -e. --no-build-isolation        # or: pip install -r requirements.txt
Quick start
data/demo/ bundles four WOD-E2E planning scenes with their frames in one Parquet file and
six perception frames, so the commands below need nothing but the weights. The scenes cover
a night intersection whose light turns green, a left turn, a right turn, and a slow-down past
a parked truck.
scripts/demo.py --plot writes a summary figure: the camera ring of the scene on the left,
one row per view and one column per timestep, the predicted trajectories against the ground
truth on the right, and the generated reasoning underneath.
export PYTHONPATH=src
python scripts/demo.py --model Qwen-Drive-1.0-4B --planner Qwen-Drive-1.0-4B/planner-rl \
    --scenes data/demo/planning_scenes.jsonl --image-archive data/demo/frames.parquet \
    --plot demo.png
import torch
from qwen_drive import InferenceMode, QwenDriveForPlanning
from qwen_drive.benchmarks import read_scene_file
from qwen_drive.images import ImageArchive

model = QwenDriveForPlanning.from_pretrained(
    "Qwen-Drive-1.0-4B",
    planner="Qwen-Drive-1.0-4B/planner-rl",
    dtype=torch.bfloat16,
    attn_implementation="flash_attention_2",
).to("cuda").eval()

scene = next(
    read_scene_file(
        "data/demo/planning_scenes.jsonl",
        image_archive=ImageArchive.open("data/demo/frames.parquet"),
    )
).scene

result = model.run(InferenceMode.REASONING_PLANNING, scene=scene, num_samples=6)
print(result.reasoning)
print(result.trajectories.shape)   # (6, 50, 3) -> (x, y, heading), 5 s at 10 Hz
docs/cookbook.md has recipes for VQA, best-of-N planning, benchmark
runs, multi-GPU evaluation, perception inference and visualization.
Documentation
Repository layout
qwen-drive/
├── src/qwen_drive/             # VQA + planning: model, scenes, benchmarks, metrics
├── src/qwen_drive_perception/  # perception mode (+ CUDA kernels under ops/)
├── scripts/                    # demo, prediction and scoring, visualization
├── data/demo/                  # bundled demo scenes and perception frames
├── data/benchmarks/            # the four benchmark scene files (relative frame paths)
├── assets/                     # figures
└── docs/
Citation
If you find our work helpful, feel free to cite us.
@misc{zhou2026qwendrive10initialstepvisionlanguage,
      title={Qwen-Drive-1.0: An Initial Step towards a Vision-Language Foundation Model for Autonomous Driving},
      author={Xin Zhou and Zongchuang Zhao and Zhibo Yang and Mingsheng Li and Humen Zhong and Shuai Bai and Du Chu and Ruizhe Chen and Zhaohai Li and Jun Tang and Qiuyue Wang and Mingkun Yang and Jiazhao Zhang and Dayiheng Liu and Dingkang Liang and Xiang Bai},
      year={2026},
      eprint={2609.00111},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.00111},
}
License
Qwen-Drive-1.0 is released under the Apache 2.0 license. Please find more details in the
LICENSE file.

 Qwen-Drive-1.0 是一个面向自动驾驶的视觉语言基础模型,构建于 Qwen3.5-4B VLM 之上,在同一个统一模型中扩展了 3D 感知、视觉问答和运动规划能力。