SenseNova-U series: Native Unified Paradigm with NEO-unify from the First Principles
English | 简体中文


📣 Updated News
[2026.09.01] Community contributor realrebelai on Hugging Face (GitHub @RealRebelAI) released a Q8 GGUF checkpoint for SenseNova-U1.5-8B-MoT (21.2 GB). Thank you for continuing to maintain and share quantized SenseNova-U1.5 weights with the community.
[2026.08.20] Release SenseNova-U1.5-8B-MoT, which further improves instruction following, text and layout, native 4K generation, image editing, and visual control. Alongside the base checkpoint, we release SenseNova-U1.5-8B-MoT-LoRA-8step for faster and more efficient inference; see example script for usage. We are also preparing the technical report and the full training pipeline, from SFT and RL to MOPD, for open-source release.
[2026.08.04] Community contributor smthem on Hugging Face (GitHub @smthemex) released a Q8 GGUF checkpoint for SenseNova-U1.5-8B-MoT-Preview (19.9 GB). Thank you for continuing to maintain and share quantized SenseNova-U1 weights with the community.
[2026.07.31] Release SenseNova-U1.5-8B-MoT-Preview that focuses on native 4K image generation, finer local textures and realistic materials, more complex layout generation, and stronger preservation of subjects and unedited regions during image editing. See the U1.5 Preview documentation for details.
Click to expand older SenseNova-U1 updates
[2026.07.16] Release SenseNova-U1-8B-MoT-Infographic-V3 📊, designed for integrated infographic generation and editing. It retains strong text-to-image (T2I) capabilities while significantly enhancing infographic editing, supporting localized text and content editing, global style editing, and global layout editing. See ✨ U1 Infographic Model Series for model details and benchmark results. A corresponding supported ComfyUI workflow is also available.
[2026.06.29] Release SenseNova-U1-8B-MoT-Infographic-V2 📊, an upgraded infographic model with improved dense small-text rendering with sharper text edges, stronger complex dense-layout generation, and better overall visual aesthetics and harmony, plus a fix for the black-background issue. Model details and visual examples are available in ✨ U1 Infographic Model Series.
[2026.06.12] Release SenseNova-U1-8B-MoT-Infographic-LoRA-8step-V1.0 for faster infographic generation. Please see the example script.
[2026.06.11] Release SenseNova-U1-8B-MoT-Interleaved 📖, specially optimized for interleaved image-text generation, with notably improved narrative coherence, character and style consistency, and text-image alignment in multi-page content.
[2026.05.21] Release the full-parameter fine-tuning training code for SenseNova-U1.
[2026.05.15] Release SenseNova-U1-8B-MoT-Infographic 📊 model for improved infographic generation. See U1 Infographic Model Series for details, and ✨ Infographic Showcases for 100 generated examples.
[2026.05.10] Release 🔥SenseNova-U1 Technical Report🔥 and the weights for SenseNova-U1-A3B-MoT-SFT & SenseNova-U1-A3B-MoT.
[2026.05.08] Add GGUF quantized checkpoints and layer-offload VRAM modes for low-VRAM single-GPU inference. See Memory-efficient inference. GGUF weights for SenseNova-U1-8B-MoT-Merger are available at 🤗 smthem/SenseNova-U1-8B-MoT-Merger-gguf — many thanks to @smthemex for contributing the quantized weights.
[2026.05.06] Release SenseNova-U1-8B-MoT-LoRA-8step-V1.0. Please see the example script.
[2026.04.30] Release the preview version of the 8-step inference model SenseNova-U1-8B-MoT-8step-preview. In most cases, the image generation quality of this model closely matches that of the base model (see comparison and existing issues). To test this model, you can use the inference scripts, but with the following parameters: --cfg_scale 1.0 --num_steps 8 .
[2026.04.27] Initial release of the weights for SenseNova-U1-8B-MoT-SFT and SenseNova-U1-8B-MoT.
[2026.04.27] Initial release of the inference code for SenseNova-U1.
🚀 SenseNova-U1.5
🌟 Overview
SenseNova-U1.5-8B-MoT is our latest native unified multimodal checkpoint for more accurate, consistent, reliable, and aesthetically compelling visual creation. Built on NEO-unify, we further strengthen the patchify layers, data quality and distribution, task formulation, prompt enhancement, and post-training pipeline.
The official release focuses on six user-visible improvements:
- Higher-quality image generation: improved composition and color harmony, with more realistic material rendering, natural lighting, stronger visual fidelity, and finer local details.
- Better text rendering and infographic generation: more legible Chinese and English text, with clearer information hierarchy in posters, infographics, brand assets, and other text-dense designs.
- More efficient native 4K generation: more coherent global structure, color harmony, and stable high-resolution output with improved generation efficiency.
- More reliable native image editing: stronger preservation of subject identity and unedited content across local, text, multi-reference, insertion, and replacement edits.
- Stronger complex-instruction following: more consistent execution of object counts, spatial relationships, layouts, styles, and multiple constraints within a single request.
- More precise visual control: more accurate region- and object-level control through bounding boxes, visual markers, and single- or multi-image references.
📊 Key Benchmarks
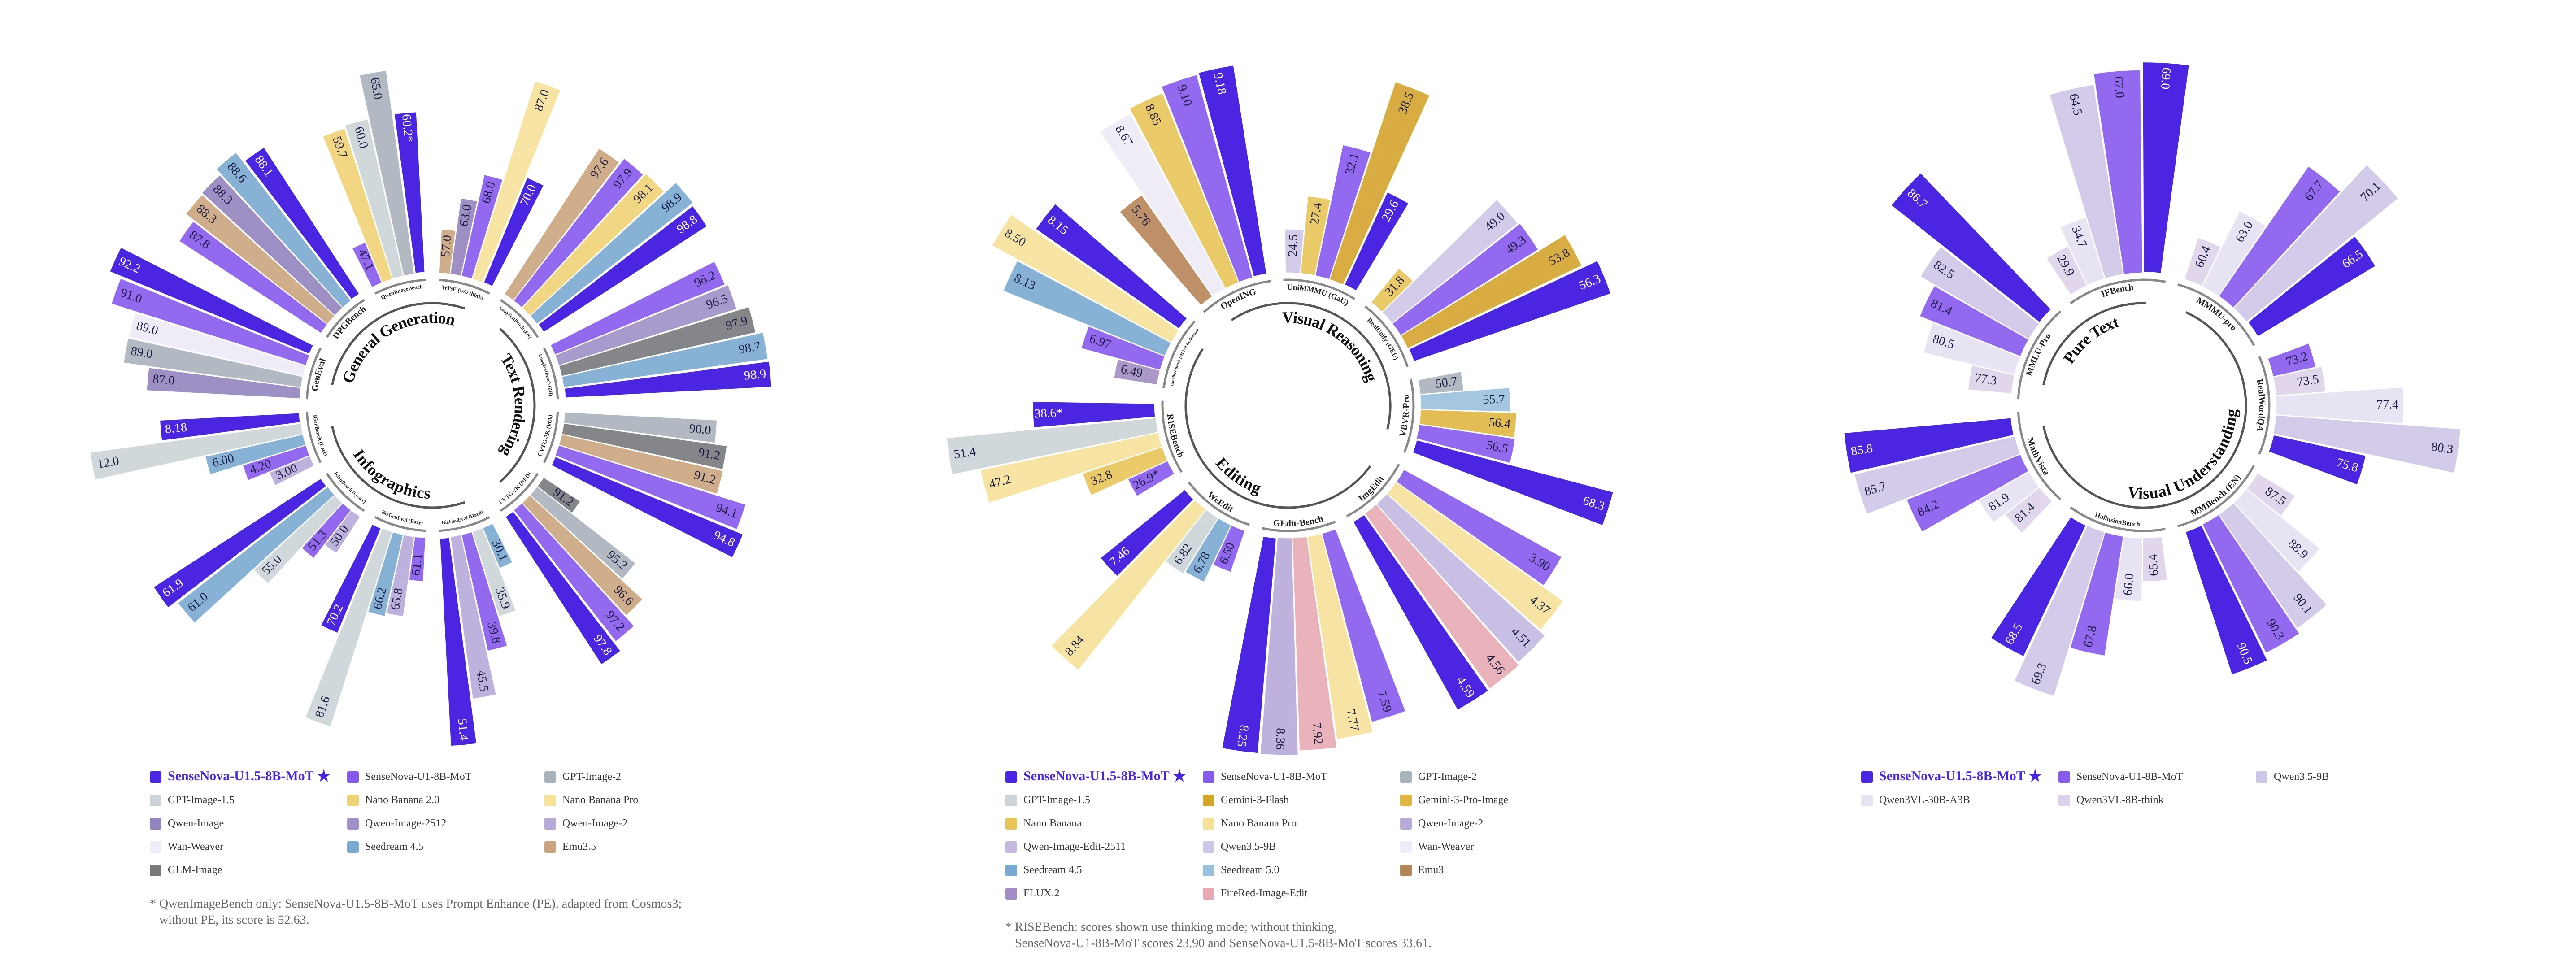
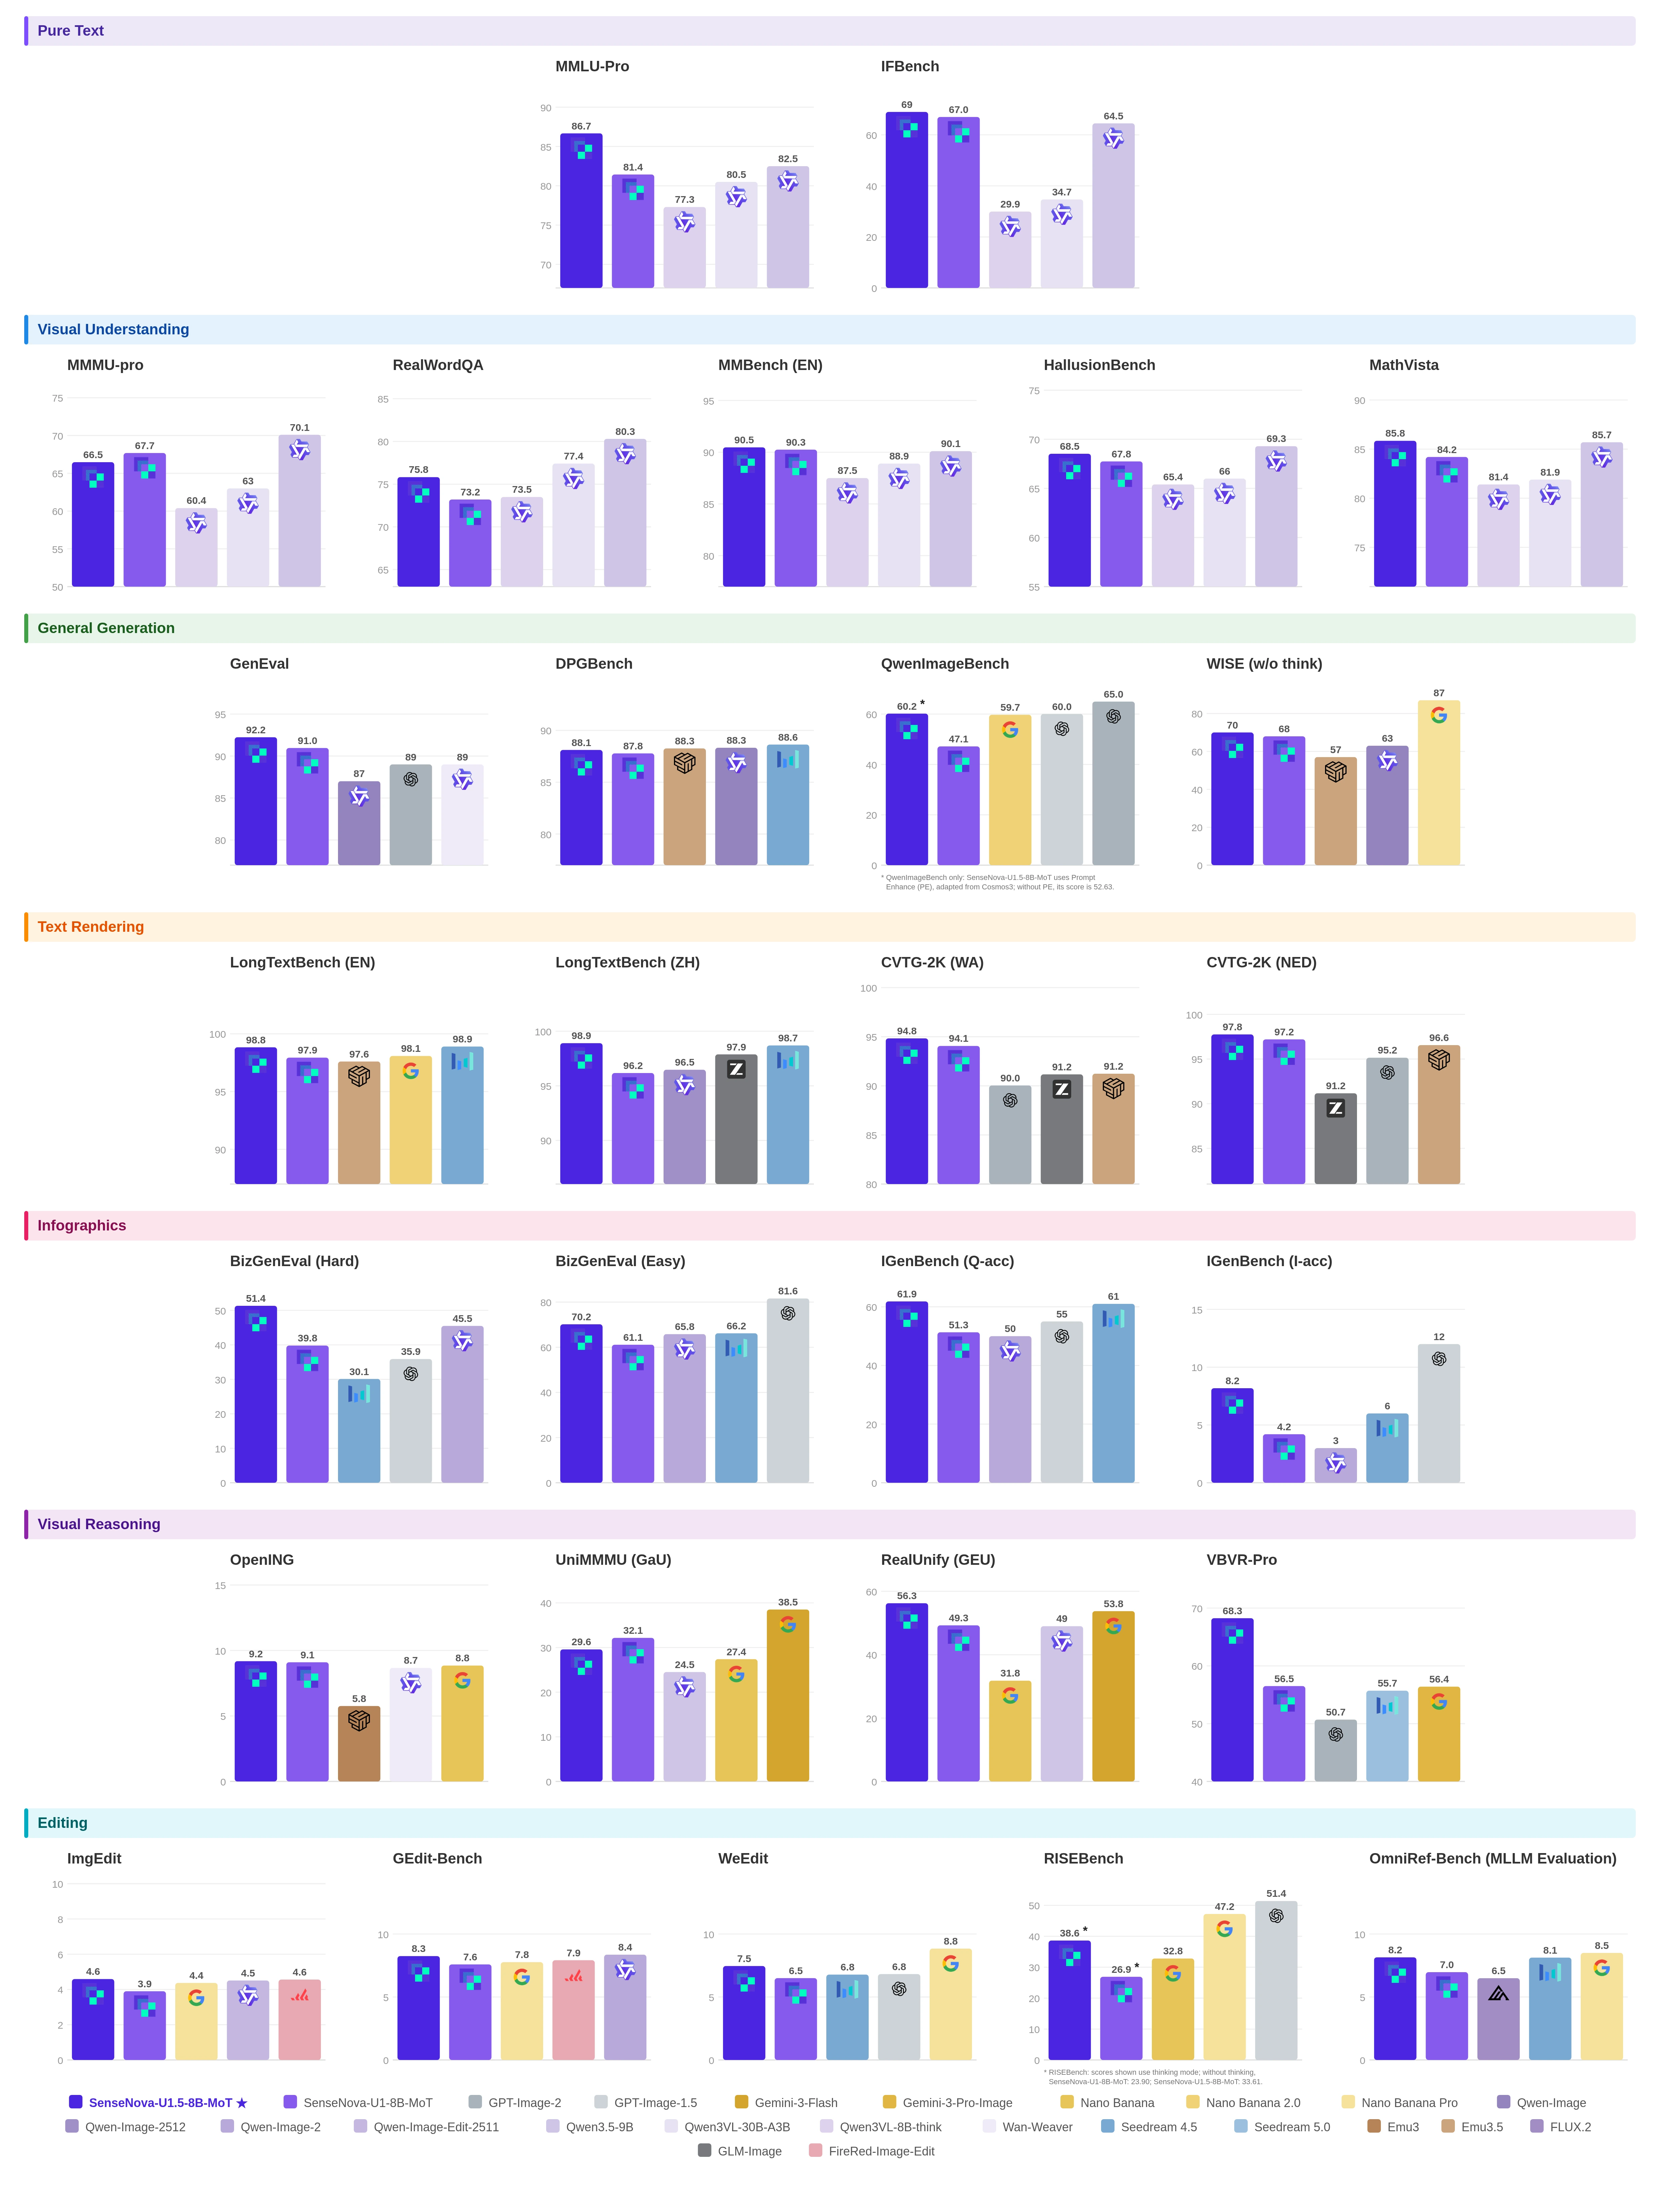
View detailed benchmark results
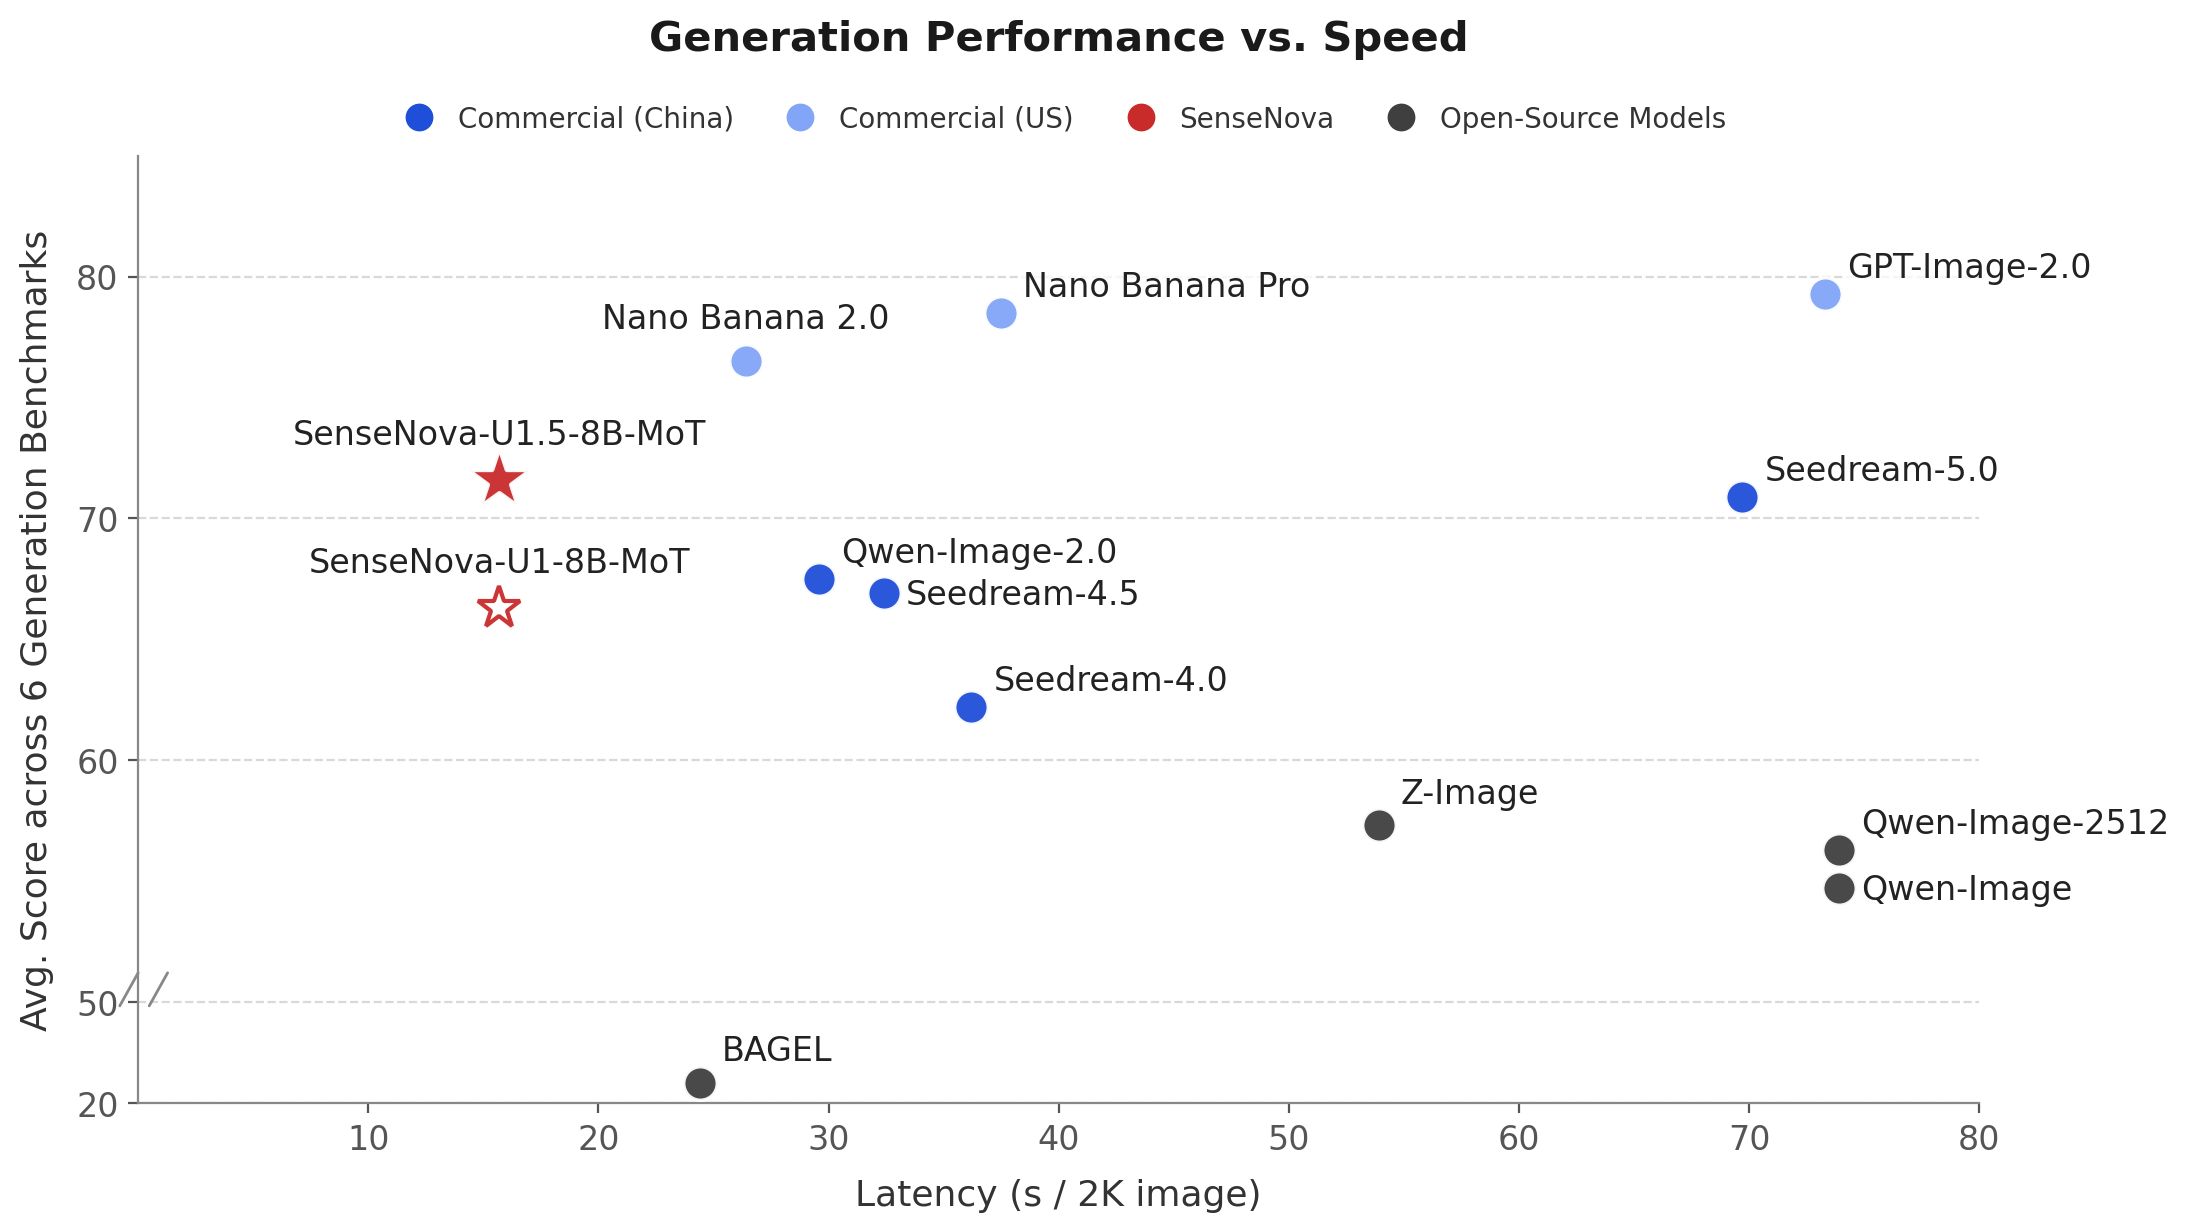
Generation Latency vs. Averaging Performance on OneIG (EN, ZH), LongText (EN, ZH), BizGenEval (Easy, Hard), CVTG, IGenBench and Qwen-Image-Bench.
🎦 Best Practices [Strong Recommendation]
Direct natural-language prompts work well for clear tasks with few constraints. For complex generation or editing, use PE when additional planning is needed, explicitly specify what should remain unchanged, and gradually lower cfg_scale if high-frequency details or colors become overemphasized. See the U1.5 Showcases and Best Practices guide for workflow recommendations, setup instructions, and visual comparisons. SenseNova U1.5 will also be available on SenseNova-Studio, where everyone can experience the model directly.
⚠️ Ongoing Improvements
The official release improves upon the Preview, though challenges remain in:
- Over-emphasized details or colors: Some prompts may produce excessive high-frequency detail or oversaturated colors, which can often be mitigated by lowering
cfg_scale.
- Dense text errors: Dense, lengthy, small, or mixed Chinese-English text may contain errors.
- Constrained layout: Exact counts, alignment, or hierarchy may be imperfect in highly constrained layouts.
- Unstable human details: Small faces, hands, limbs, and fine-grained object structures may remain unstable.
- Complex editing drift: Broad, multi-turn, or multi-reference edits may drift, especially when many regions must be preserved simultaneously.
⚙️ Deployment Guidance
- Quick start with Transformers
# Text-to-Image
python examples/t2i/inference.py \
  --model_path sensenova/SenseNova-U1.5-8B-MoT \
  --prompt "A formal portrait depicts a man in 18th-century attire seated with a scroll, wearing a red cloak and ornate medals, against a classical landscape with ancient ruins and inscriptions." \
  --output output.png

# Image Editing
python examples/editing/inference.py \
  --model_path sensenova/SenseNova-U1.5-8B-MoT \
  --image examples/editing/data/images/1.webp \
  --prompt "Change the jacket of the person on the left to bright yellow." \
  --output edited.png

# Interleaved Generation
python examples/interleave/inference.py \
  --model_path sensenova/SenseNova-U1.5-8B-MoT \
  --prompt "I want to learn how to cook tomato and egg stir-fry. Please give me a beginner-friendly illustrated tutorial." \
  --resolution "16:9" \
  --output_dir outputs/interleave/ \
  --stem demo \
  --profile

# Visual Understanding
python examples/vqa/inference.py \
  --model_path sensenova/SenseNova-U1.5-8B-MoT \
  --image examples/vqa/data/images/menu.jpg \
  --question "My friend and I are dining together tonight. Looking at this menu, can you recommend a good combination of dishes for 2 people? We want a balanced meal — a mix of mains and maybe a starter or dessert. Budget-conscious but want to try the highlights." \
  --output outputs/answer.txt \
  --max_new_tokens 8192 \
  --do_sample \
  --temperature 0.6 \
  --top_p 0.95 \
  --top_k 20 \
  --repetition_penalty 1.05 \
  --profile
Production serving: For deployment with LightLLM + LightX2V, see the deployment guide.
GGUF quantized inference: SenseNova-U1.5-Lite GGUF weights are coming soon. Their inference workflow will be similar to that of the community Q8 GGUF checkpoint for SenseNova-U1.5-8B-MoT-Preview. Keep --model_path pointed to the matching base checkpoint.
# Install the optional dependencies once
uv pip install -e ".[gguf]"  # or: pip install "gguf>=0.10.0" "diffusers>=0.30.0"

python examples/t2i/inference.py \
  --model_path sensenova/SenseNova-U1.5-8B-MoT-Preview \
  --gguf_checkpoint /path/to/SenseNova-U1.5-8B-MoT-Preview-Q8.gguf \
  --prompt "A male peacock trying to attract a female" \
  --output output_gguf.png
🚀 SenseNova-U1
Expand the original SenseNova-U1 overview, showcase, and deployment
🌟 Overview
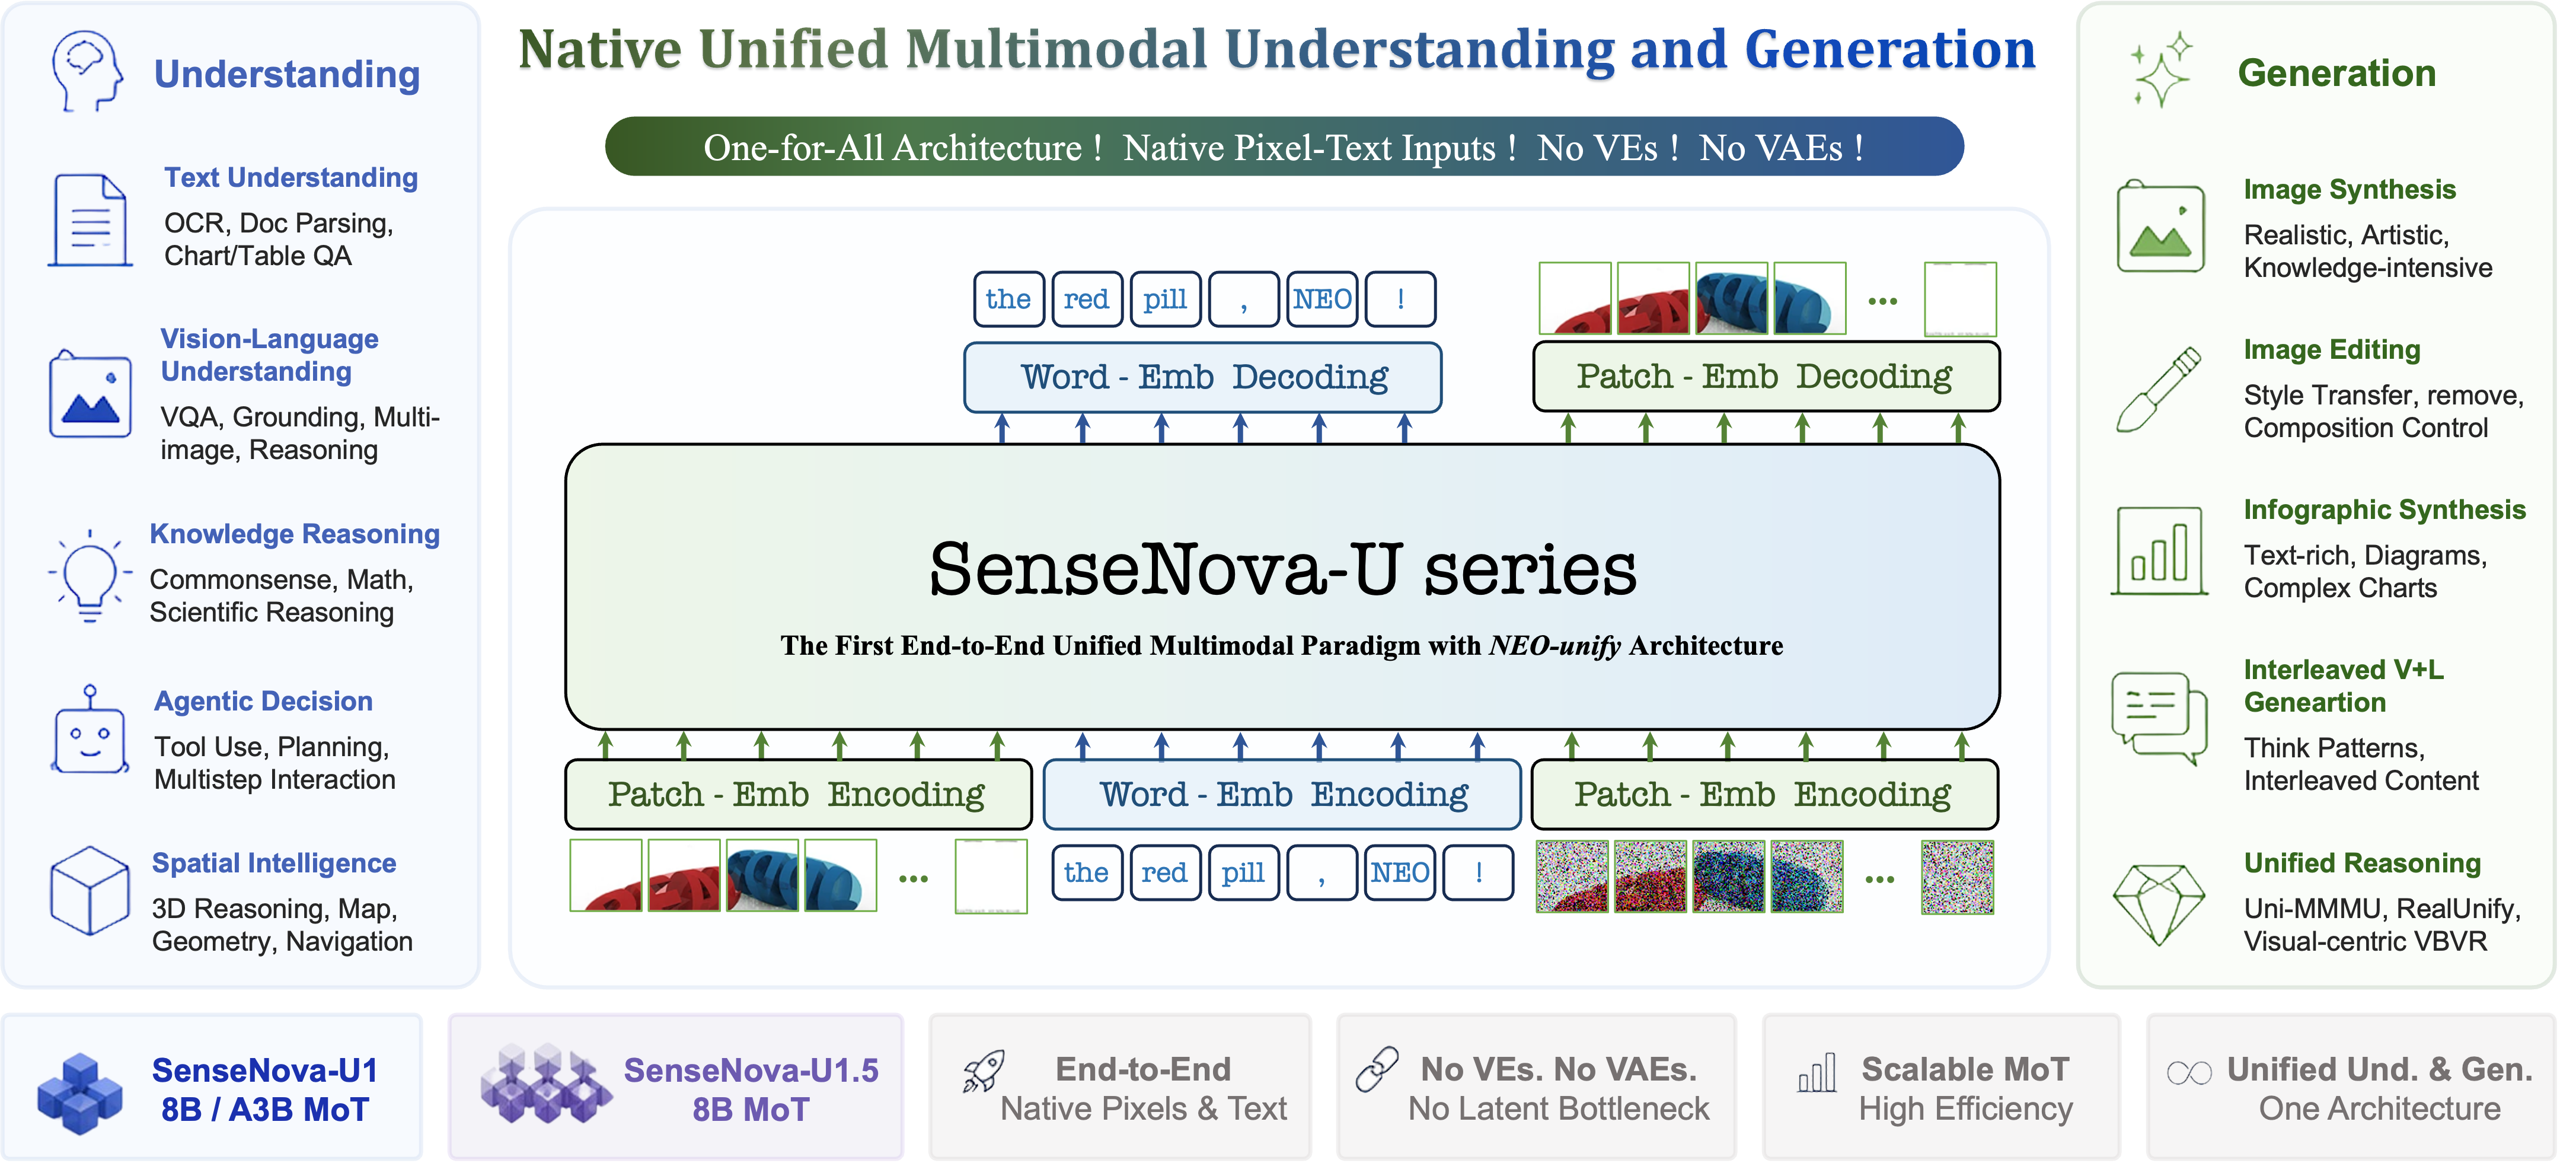
🚀 SenseNova-U1 is a new series of native multimodal models that unifies multimodal understanding, reasoning, and generation within a monolithic architecture.
It marks a fundamental paradigm shift in multimodal AI: from modality integration to true unification. Rather than relying on adapters to translate between modalities, SenseNova-U1 models think-and-act across language and vision natively.
Unifying visual understanding and generation in an end-to-end architecture from pixel to word opens tremendous possibilities, enabling highly efficient and strong understanding, generation, and interleaved reasoning in a natively multimodal manner.
🏗️ Key Pillars:
At the core of SenseNova-U1 is NEO-unify, a novel architecture designed from the first principles for multimodal AI: It eliminates both Visual Encoder (VE) and Variational Auto-Encoder (VAE) where pixel-word information are inherently and deeply correlated. Several important features are as follows:
- 🔗 Model language and visual information end-to-end as a unified compound.
- 🖼️ Preserve semantic richness while maintaining pixel-level visual fidelity.
- 🧠 Reason across modalities with high efficiency & minimal conflict via native MoTs.
✨ What This Unlocks:
Powered by this new core architecture, SenseNova-U1 delivers exceptional efficiency in multimodal learning:
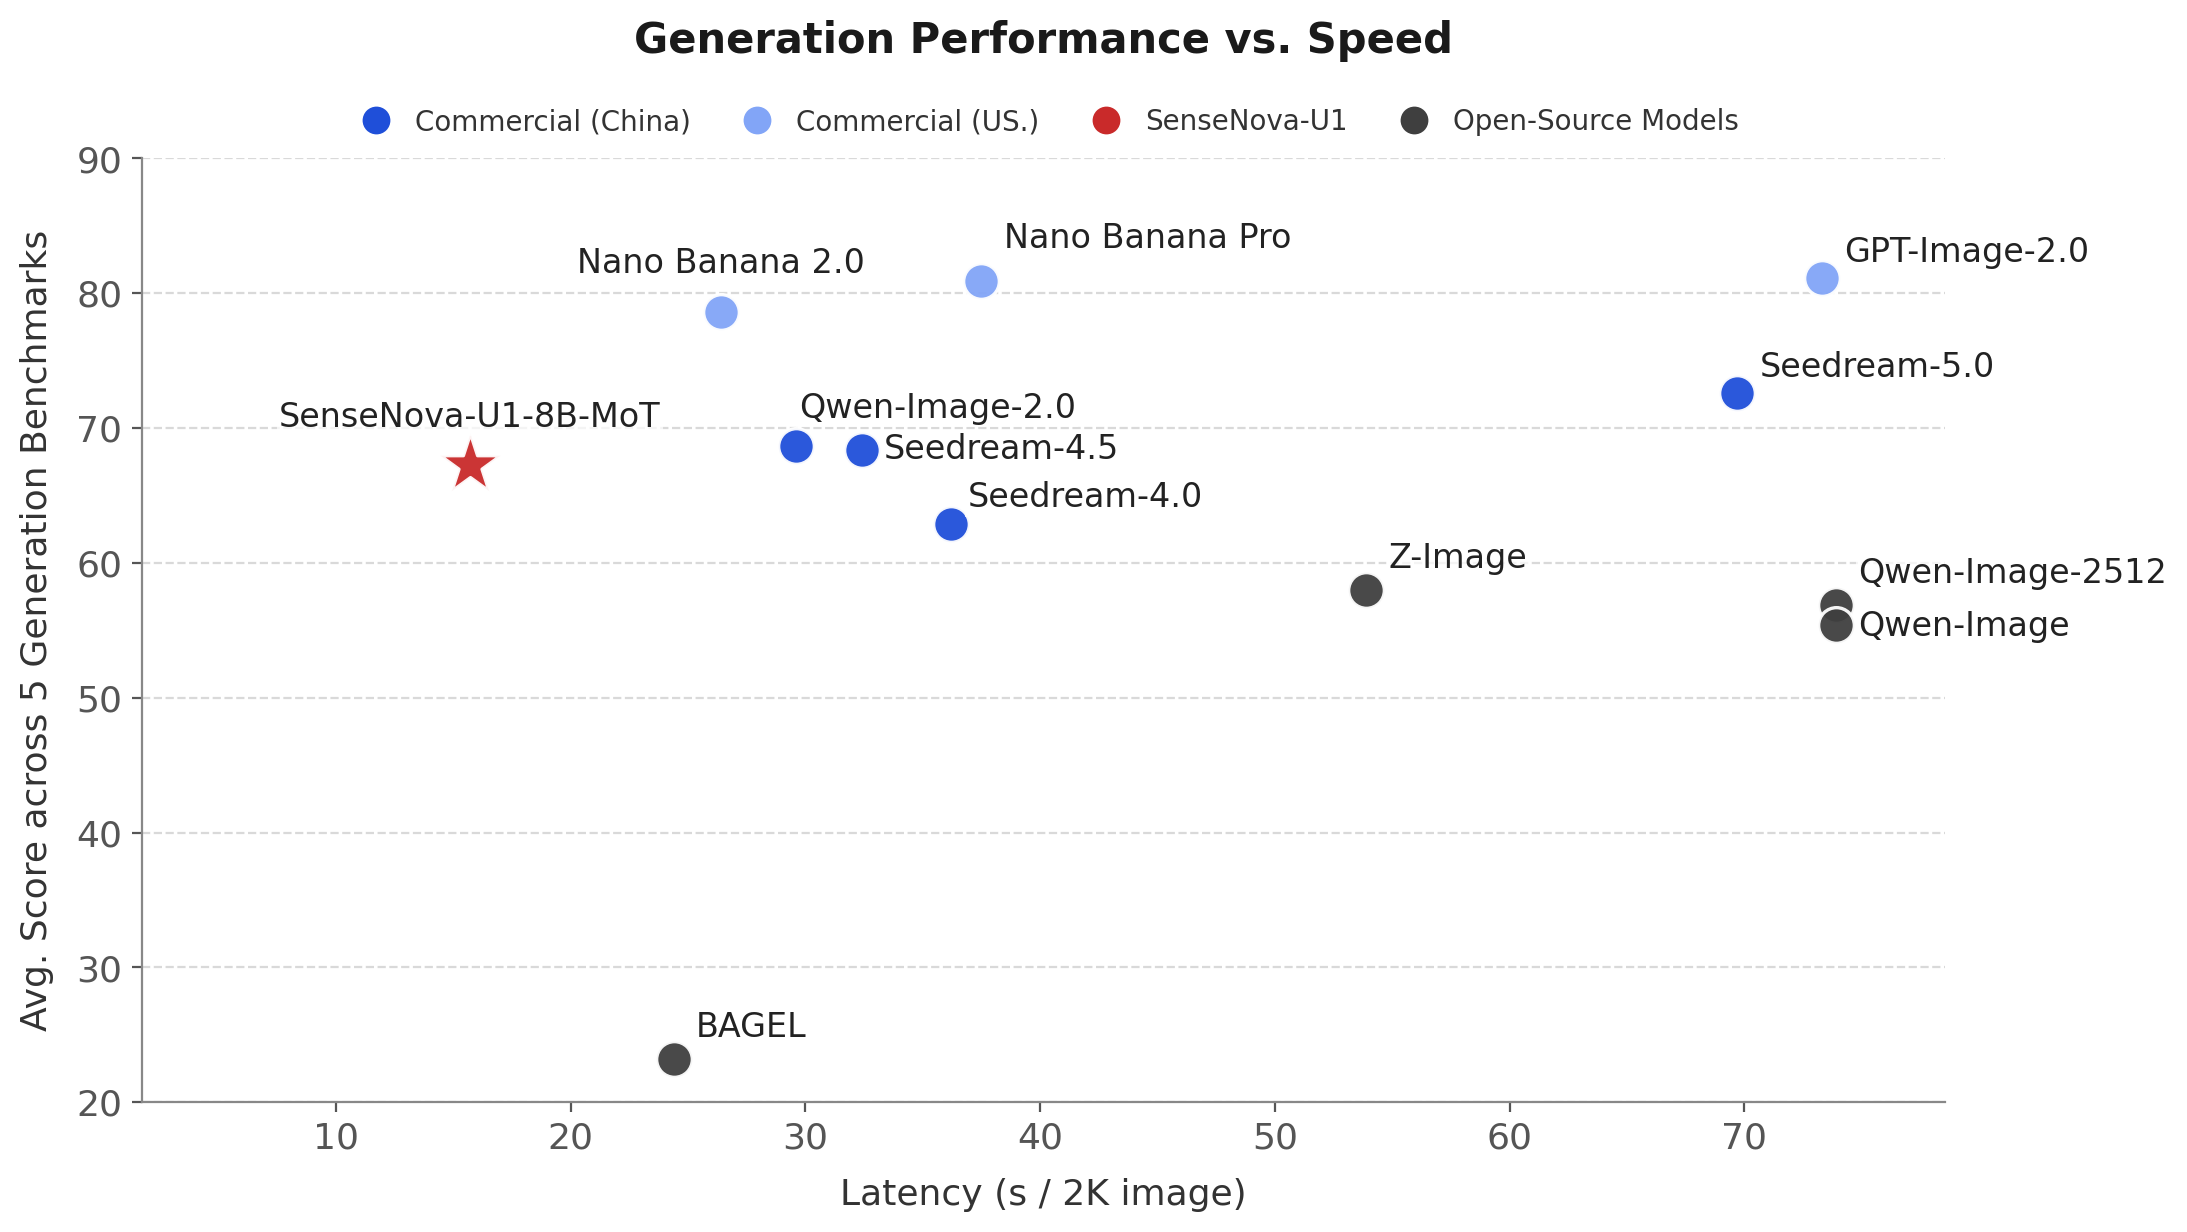
Left: Generation Latency vs. Averaging Performance on OneIG (EN, ZH), LongText (EN, ZH), BizGenEval (Easy, Hard), CVTG and IGenBench.
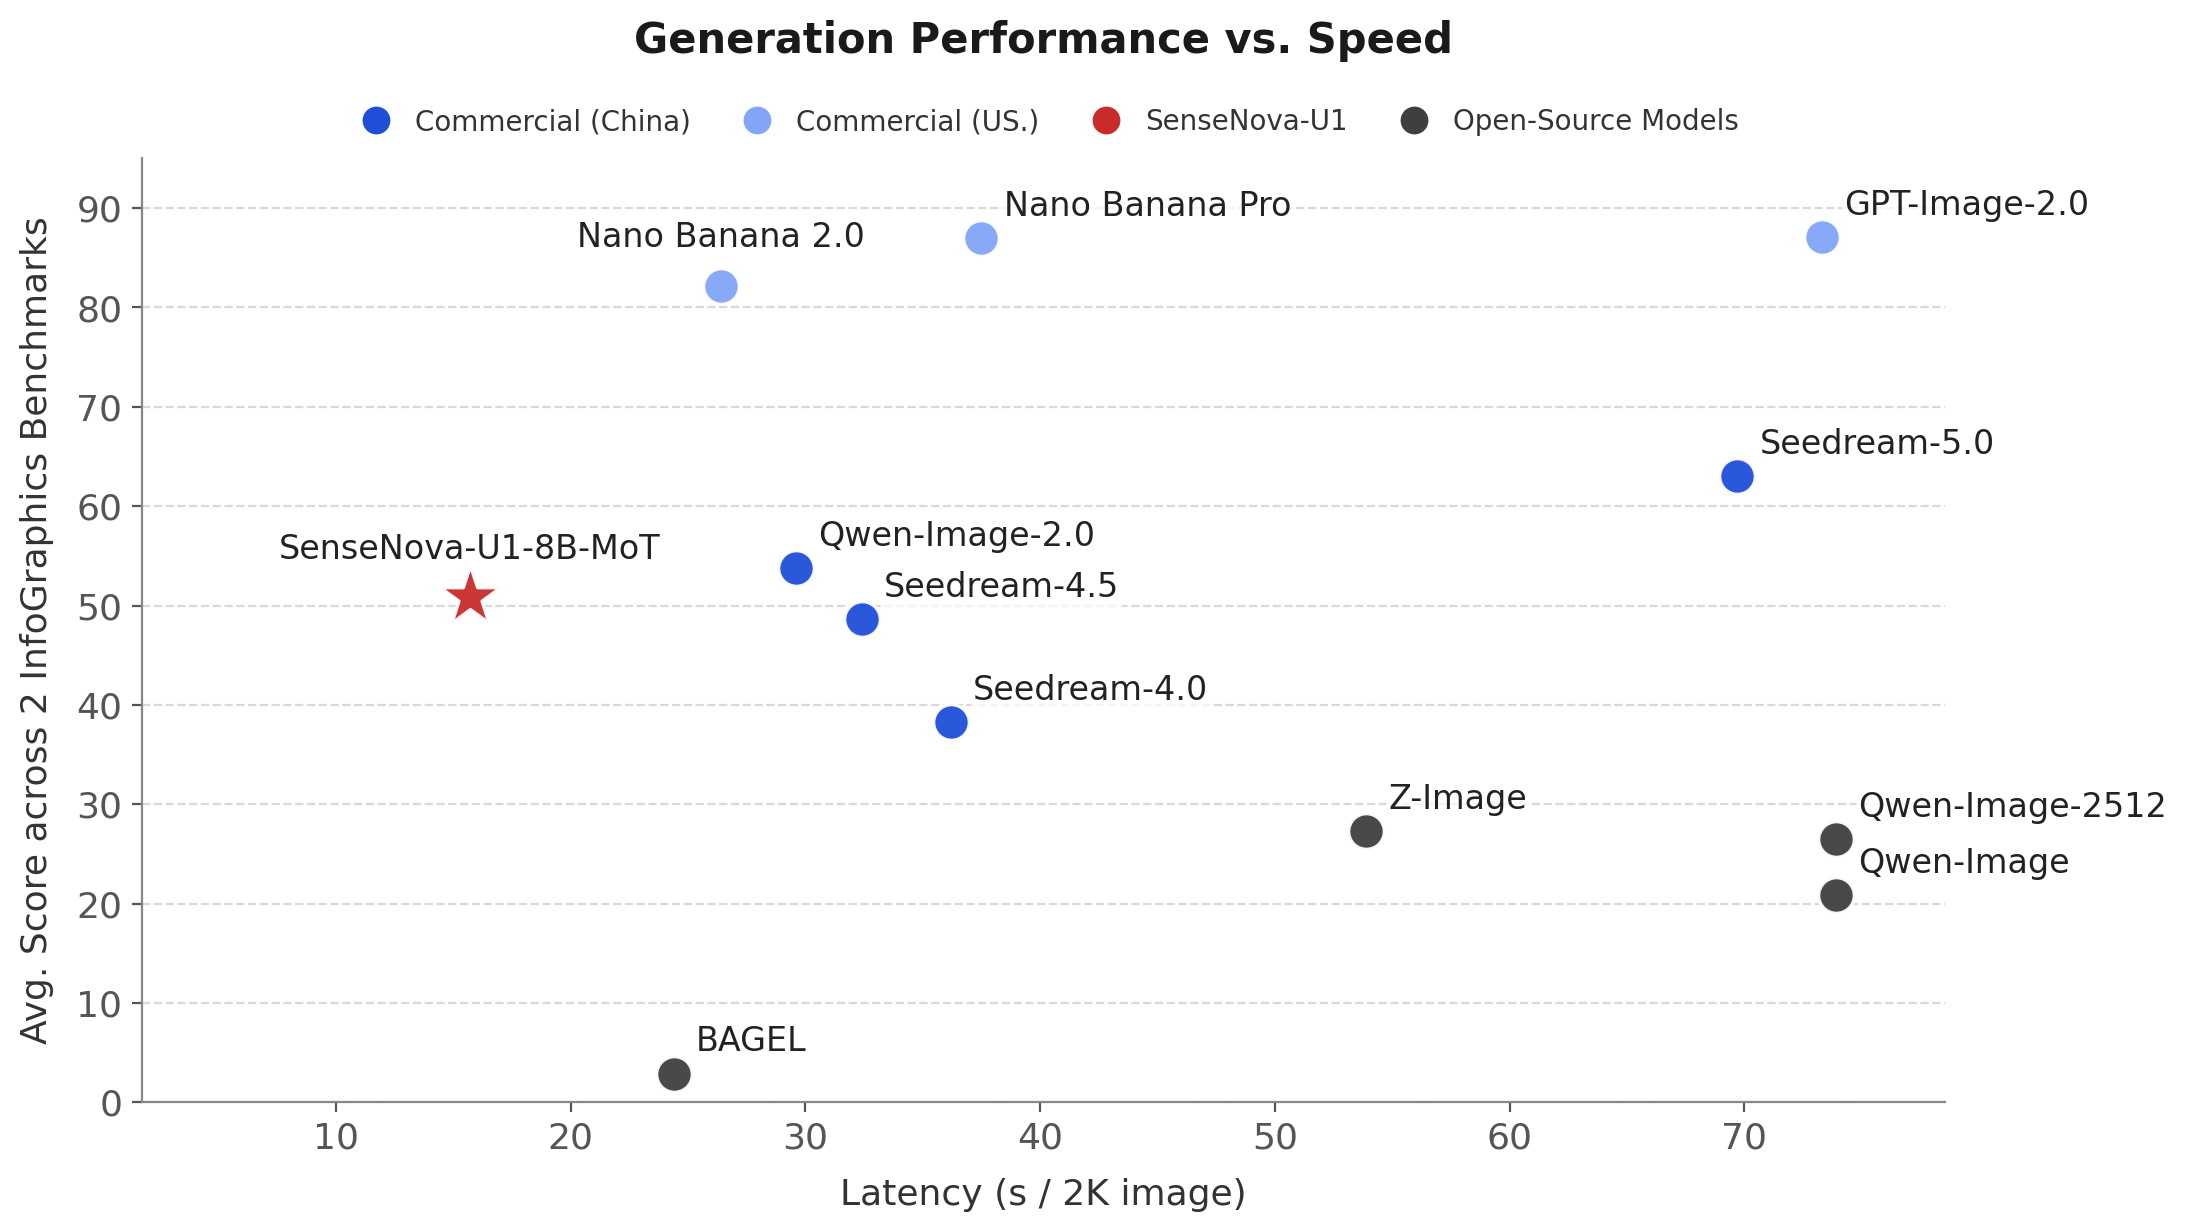
Right: Generation Latency vs. Averaging Performance on Infographic Benchmarks, i.e., BizGenEval (Easy, Hard), and IGenBench.
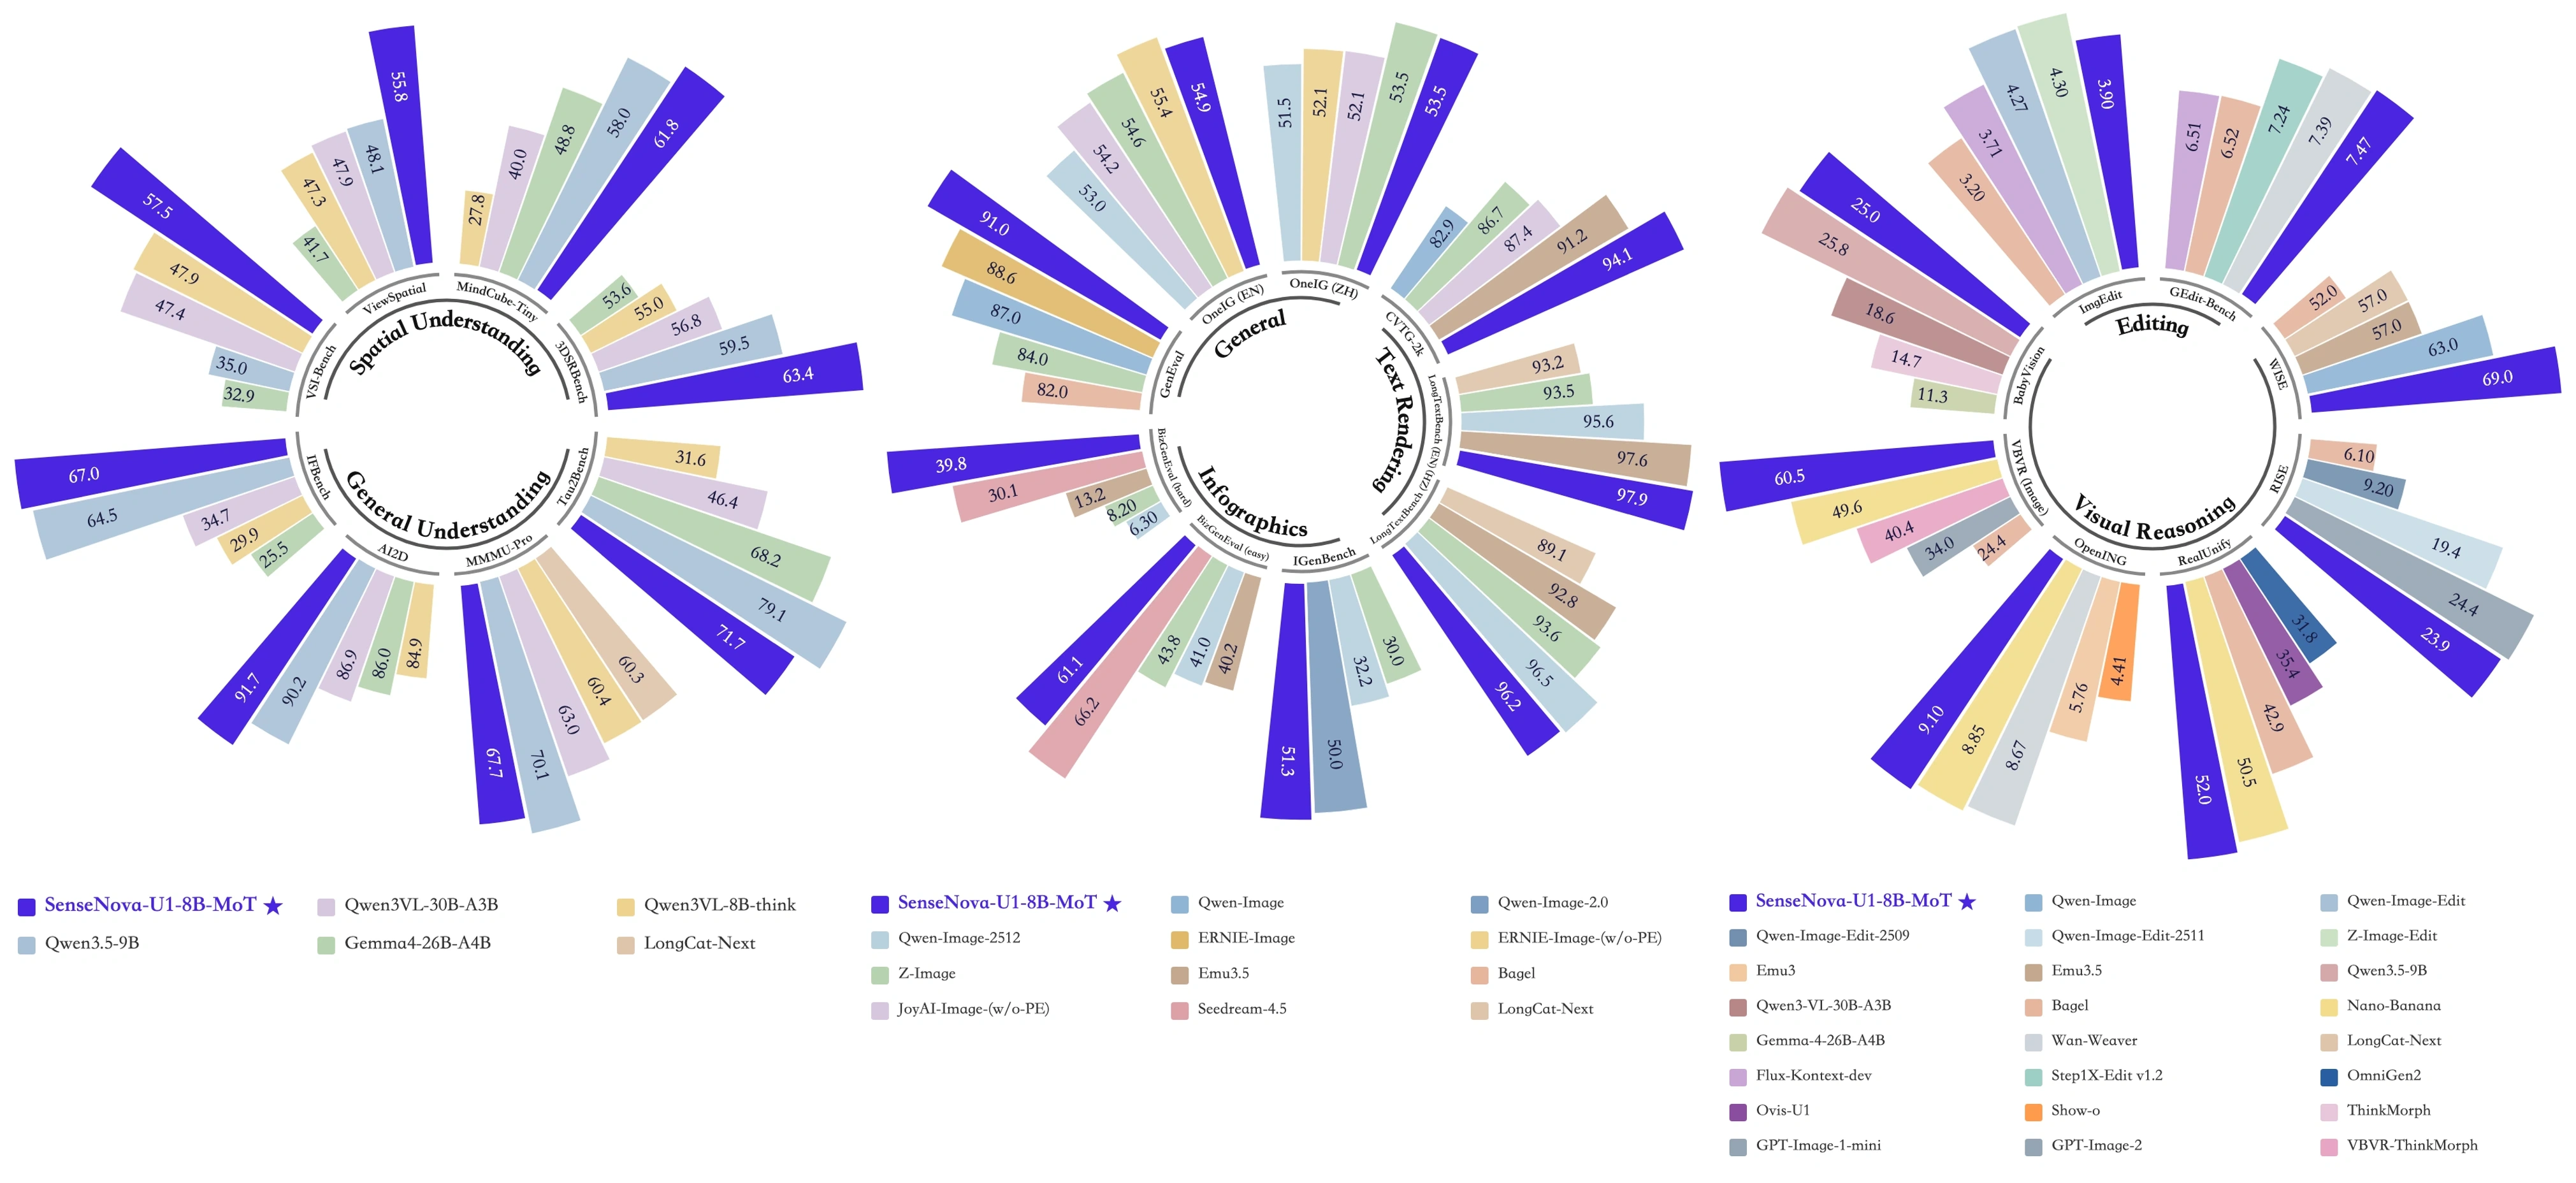
🏆 Open-source SoTA in both understanding and generation: SenseNova-U1 sets a new standard for unified multimodal understanding and generation, achieving state-of-the-art performance among open-source models across a wide range of understanding, reasoning, and generation benchmarks.
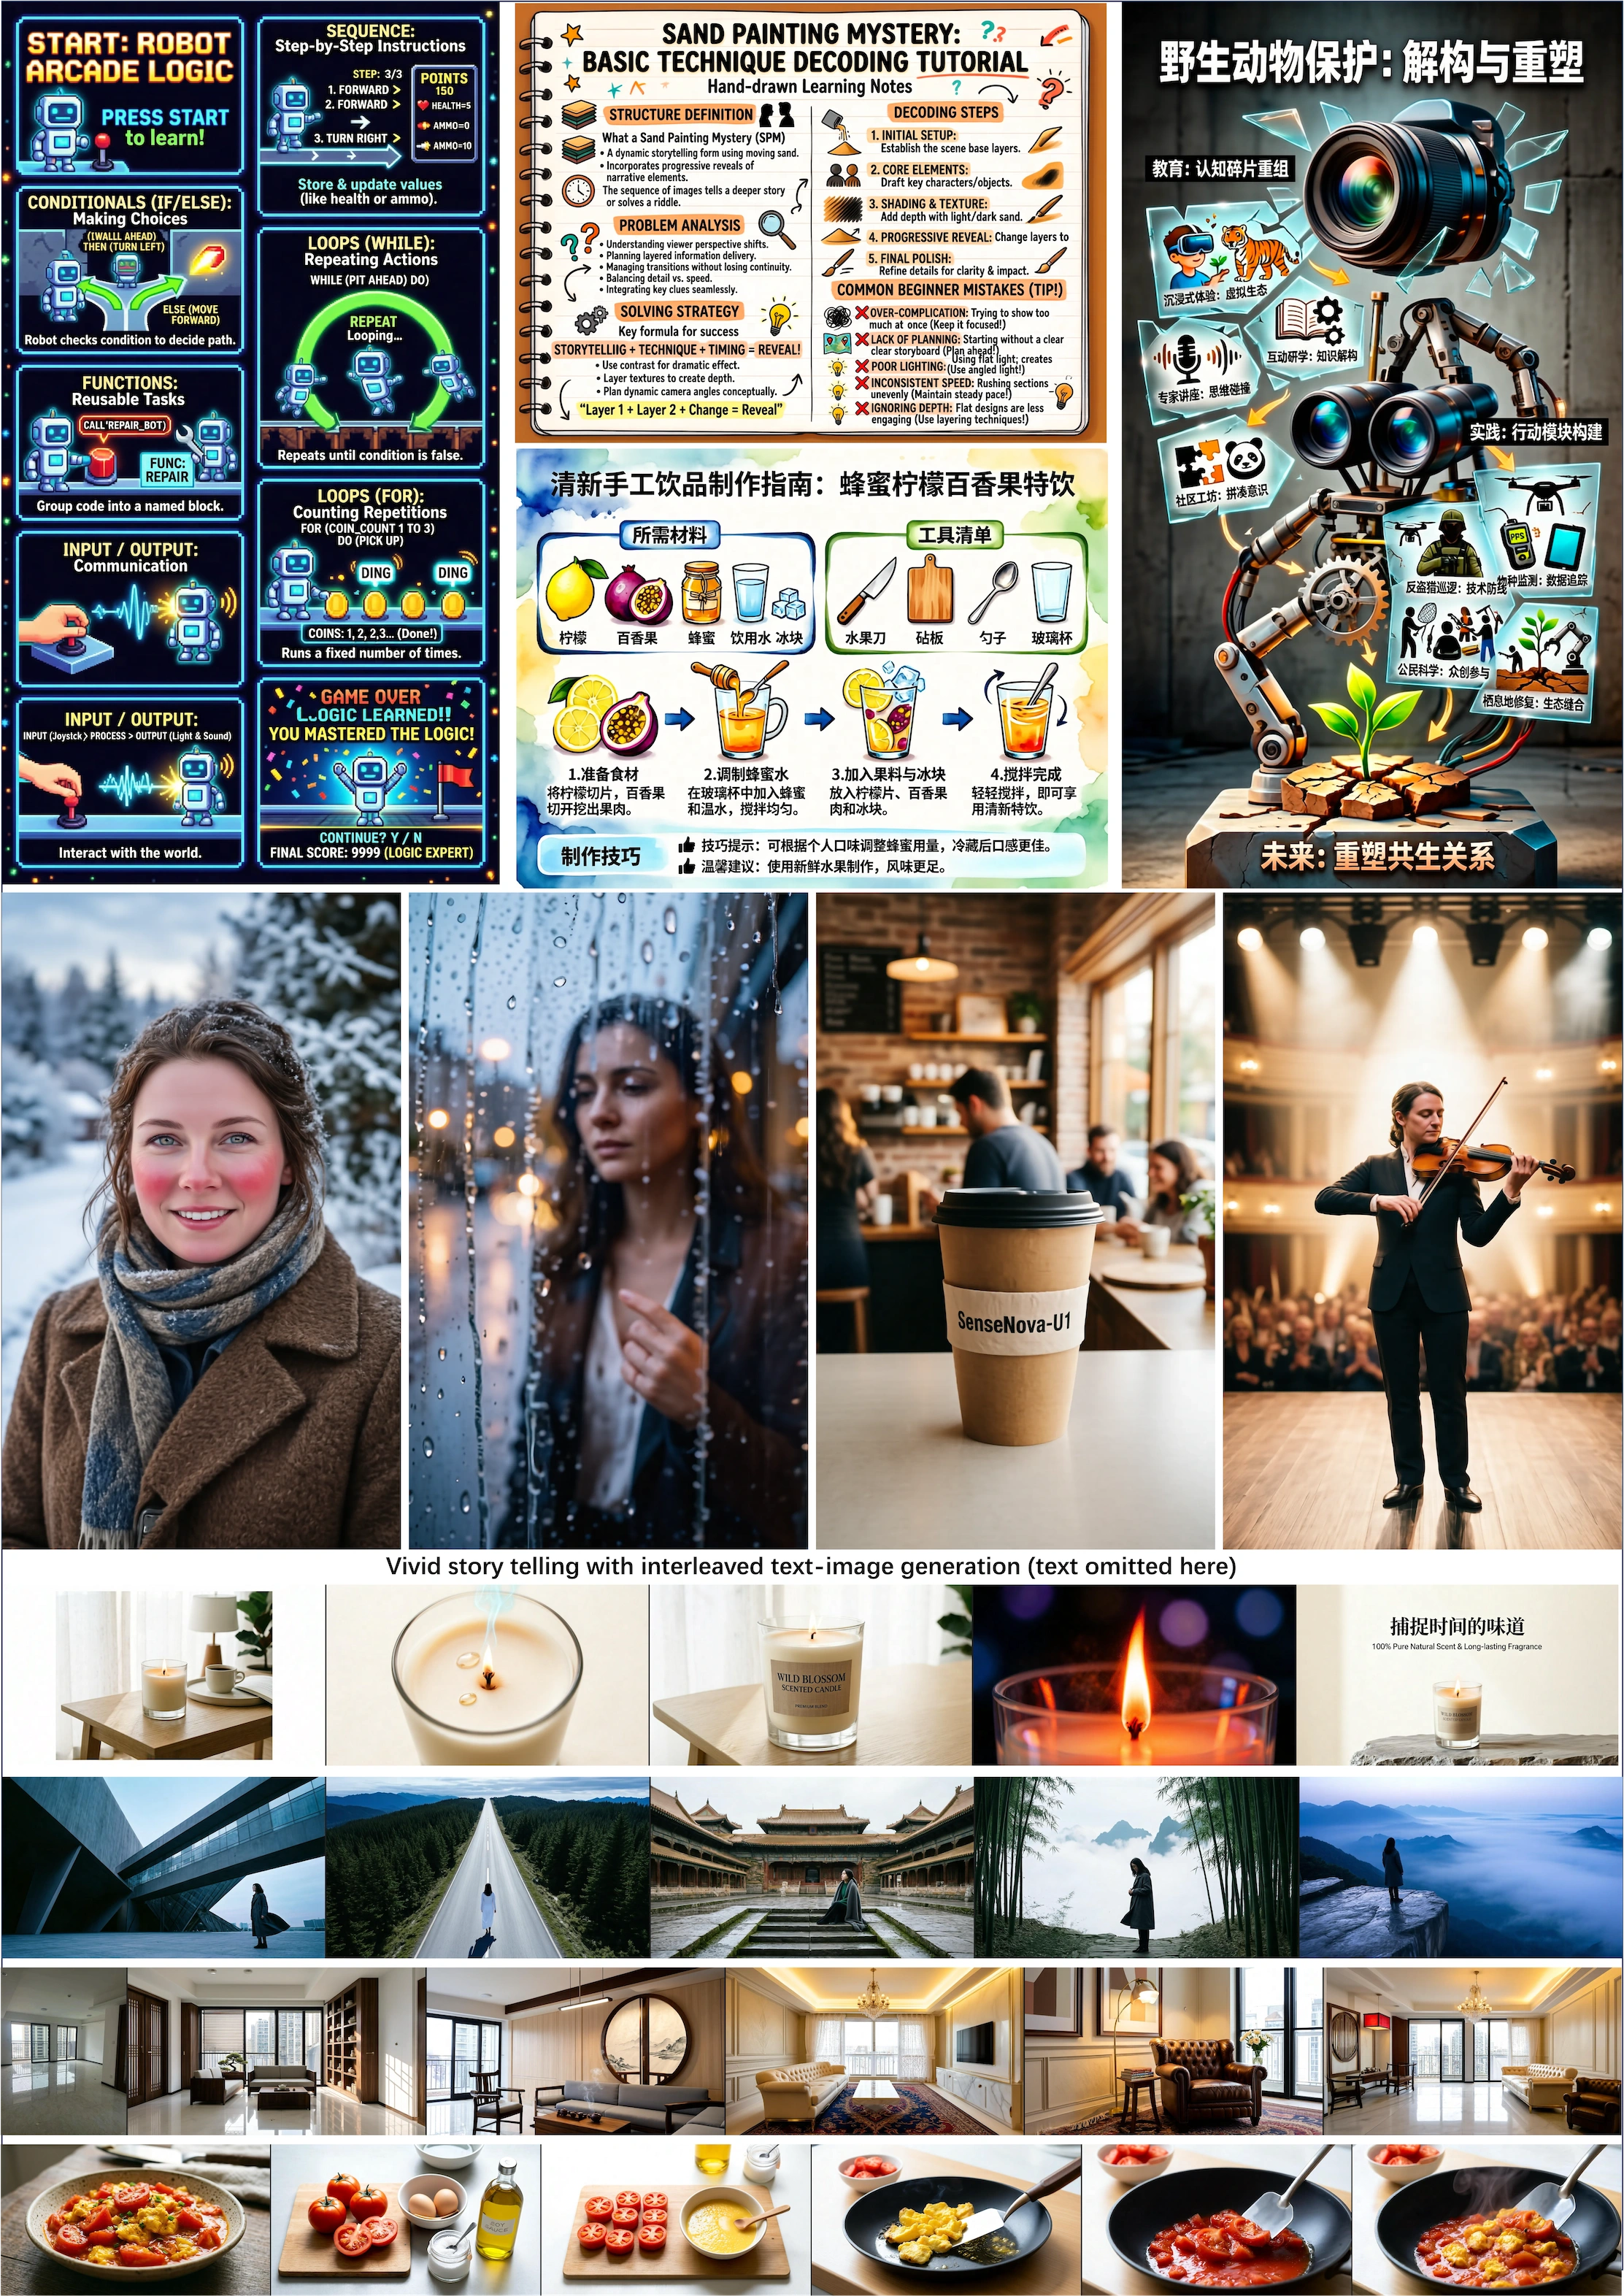
📖 Native interleaved image-text generation: SenseNova-U1 can generate coherent interleaved text and images in a single flow with one model, enabling use cases such as practical guides and travel diaries that combine clear communication with vivid storytelling and transform complex information into intuitive visuals.
📰 High-density information rendering: SenseNova-U1 demonstrates strong capabilities in dense visual communication, generating richly structured layouts for knowledge illustrations, posters, presentations, comics, resumes, and other information-rich formats.
🌍 Beyond Multimodality:
- 🤖 Vision–Language–Action (VLA)
- 🌐 World Modeling (WM)
📋 Project Status
🎨 Showcases
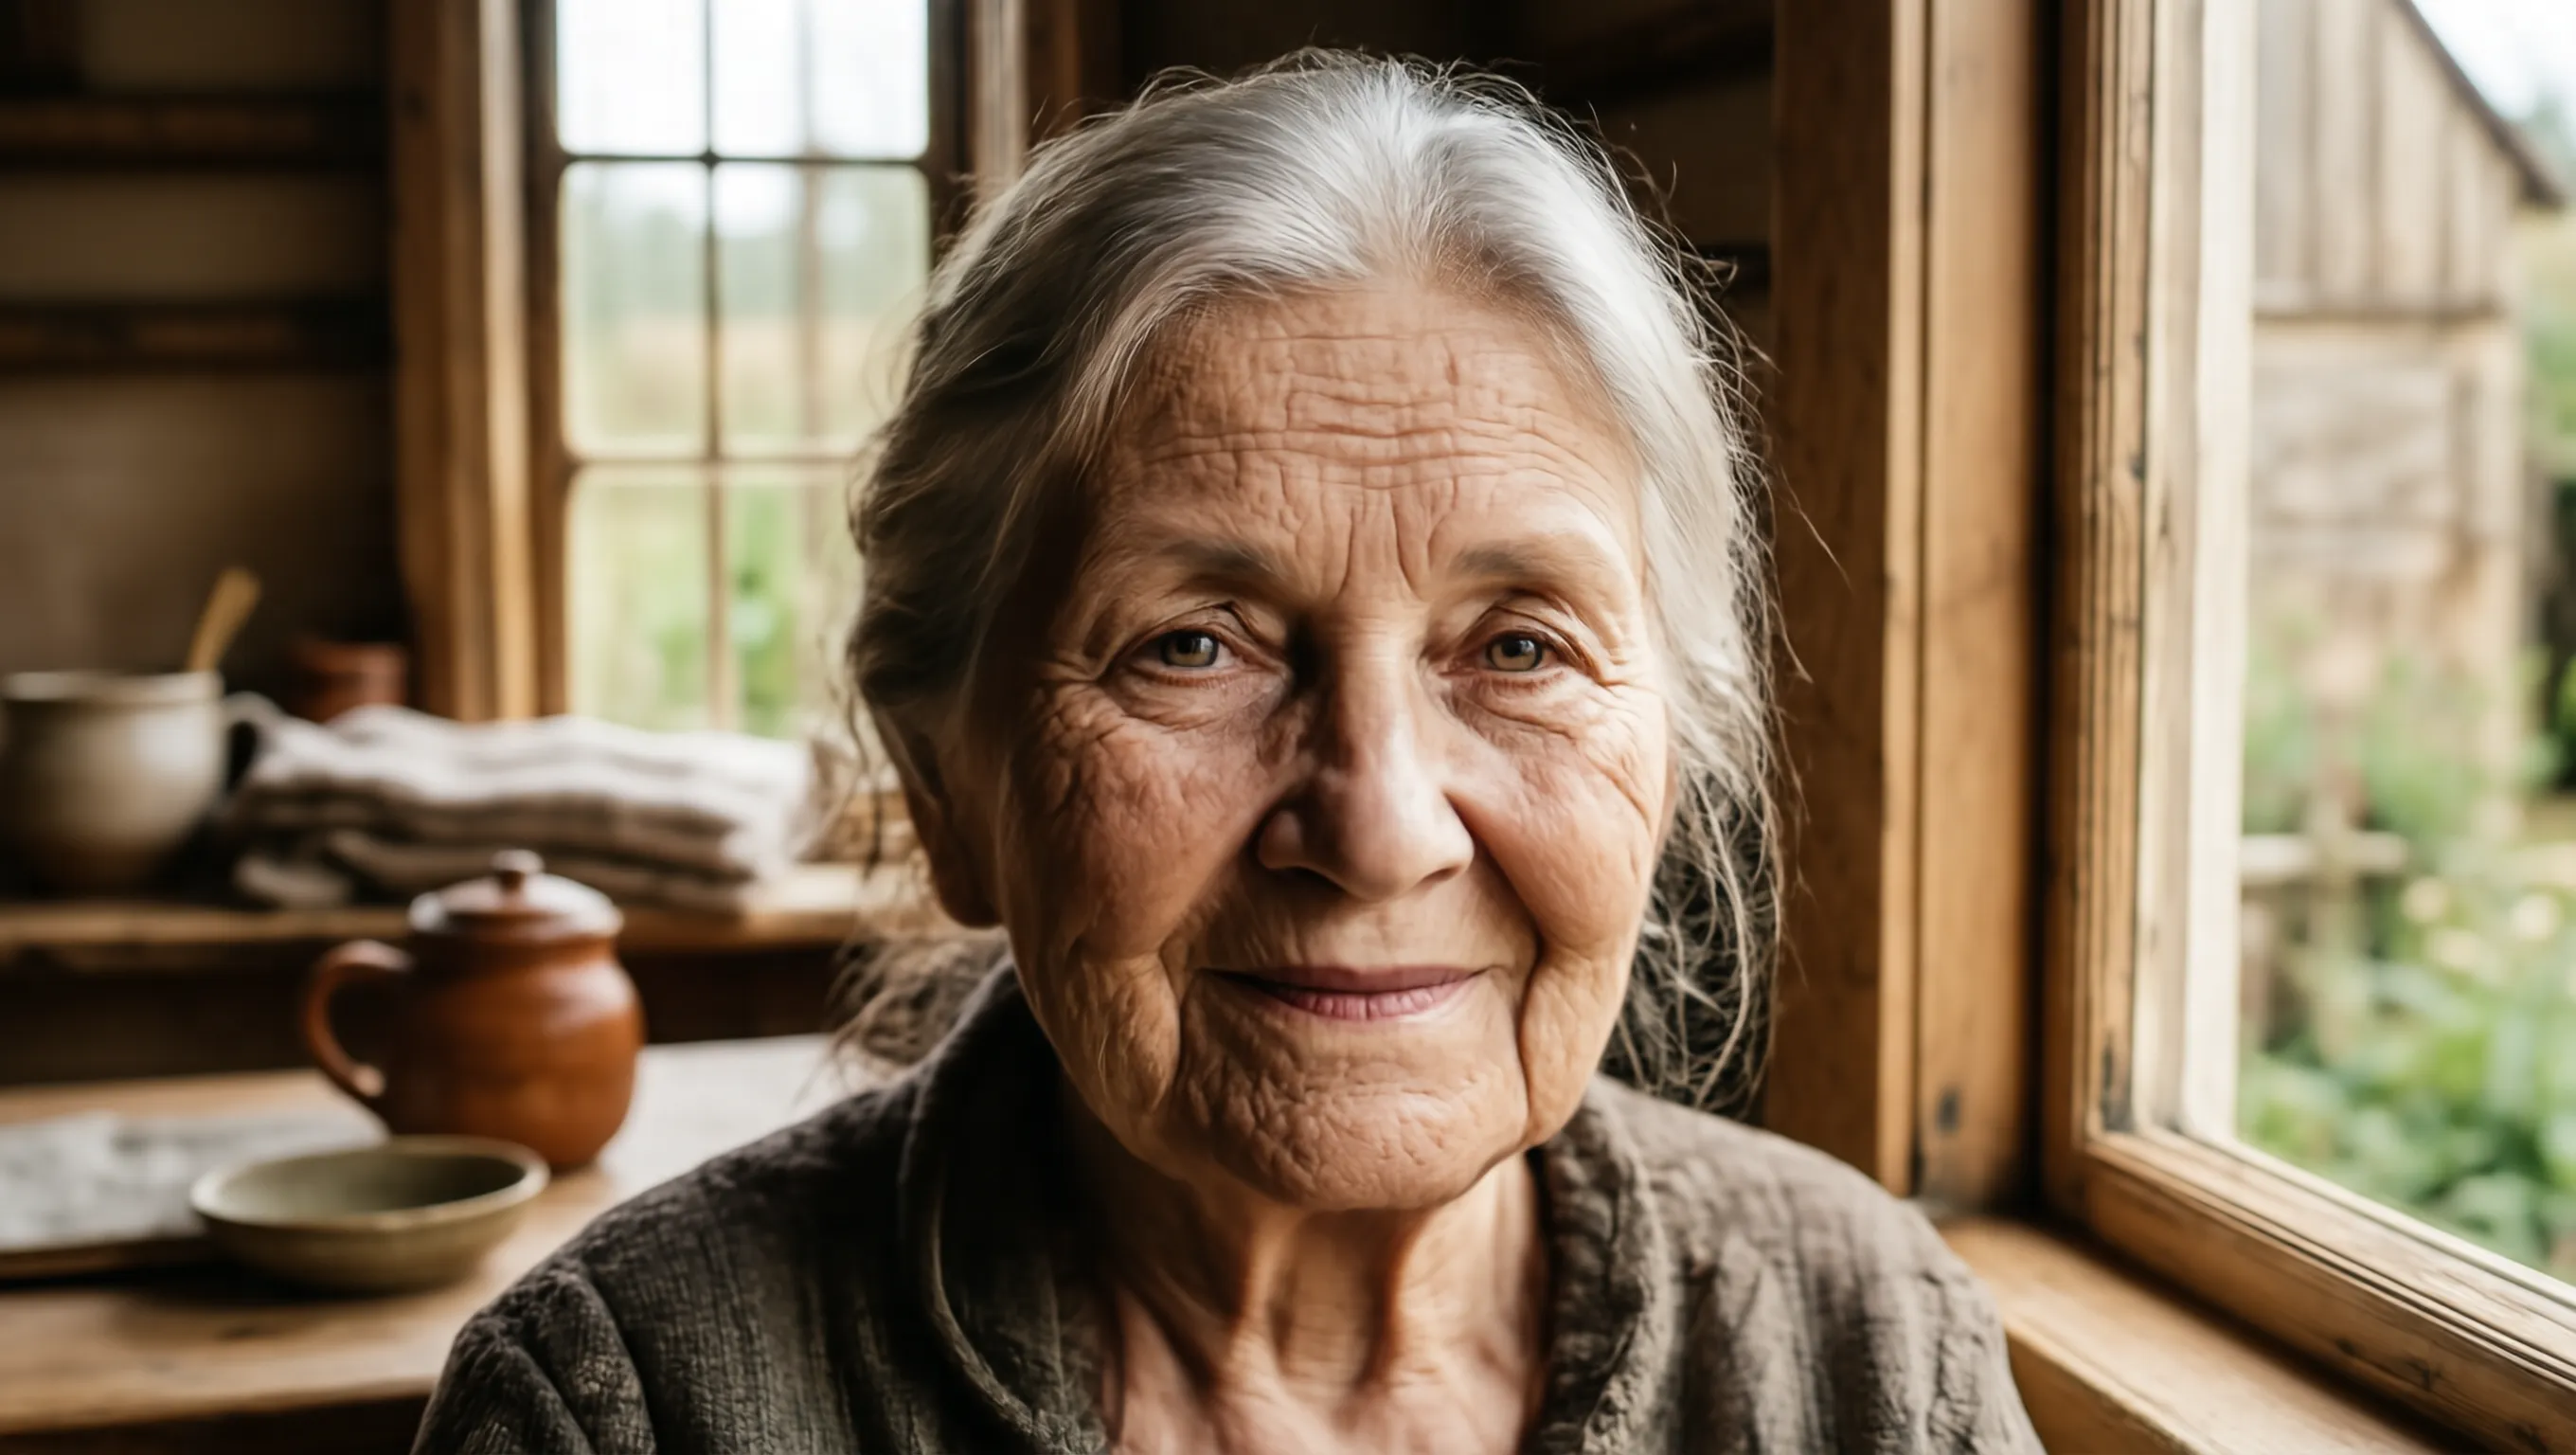
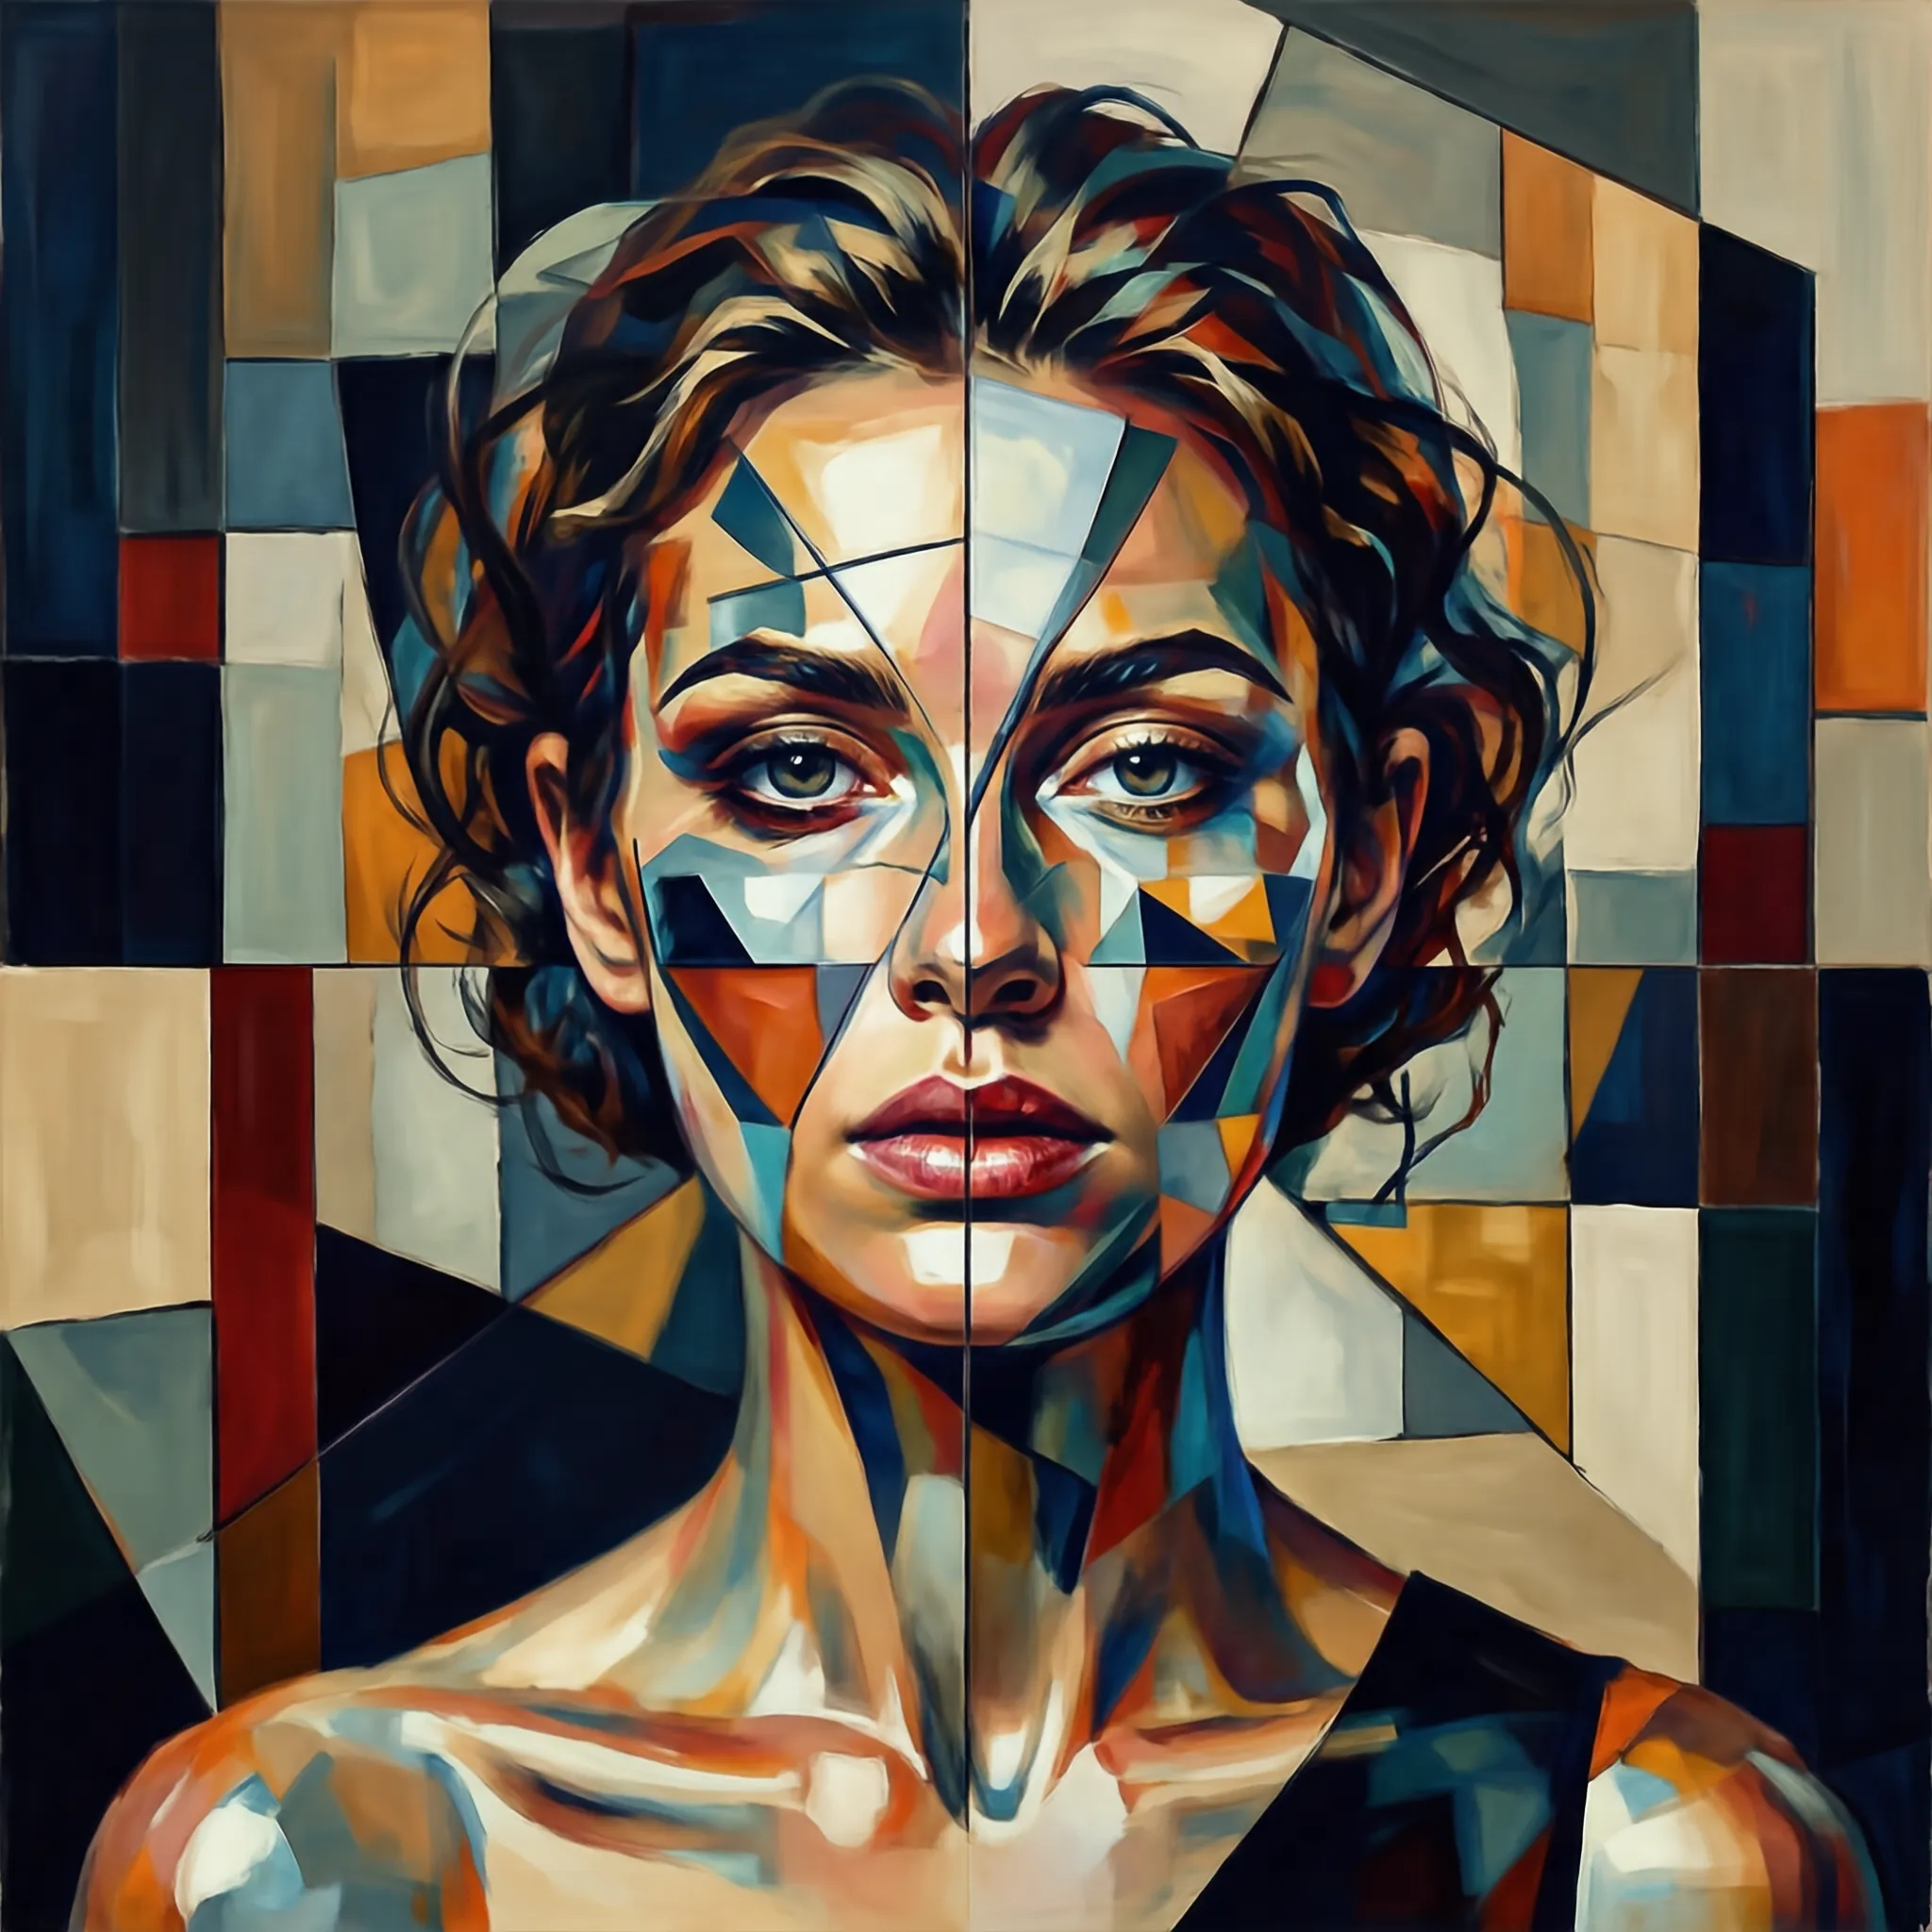
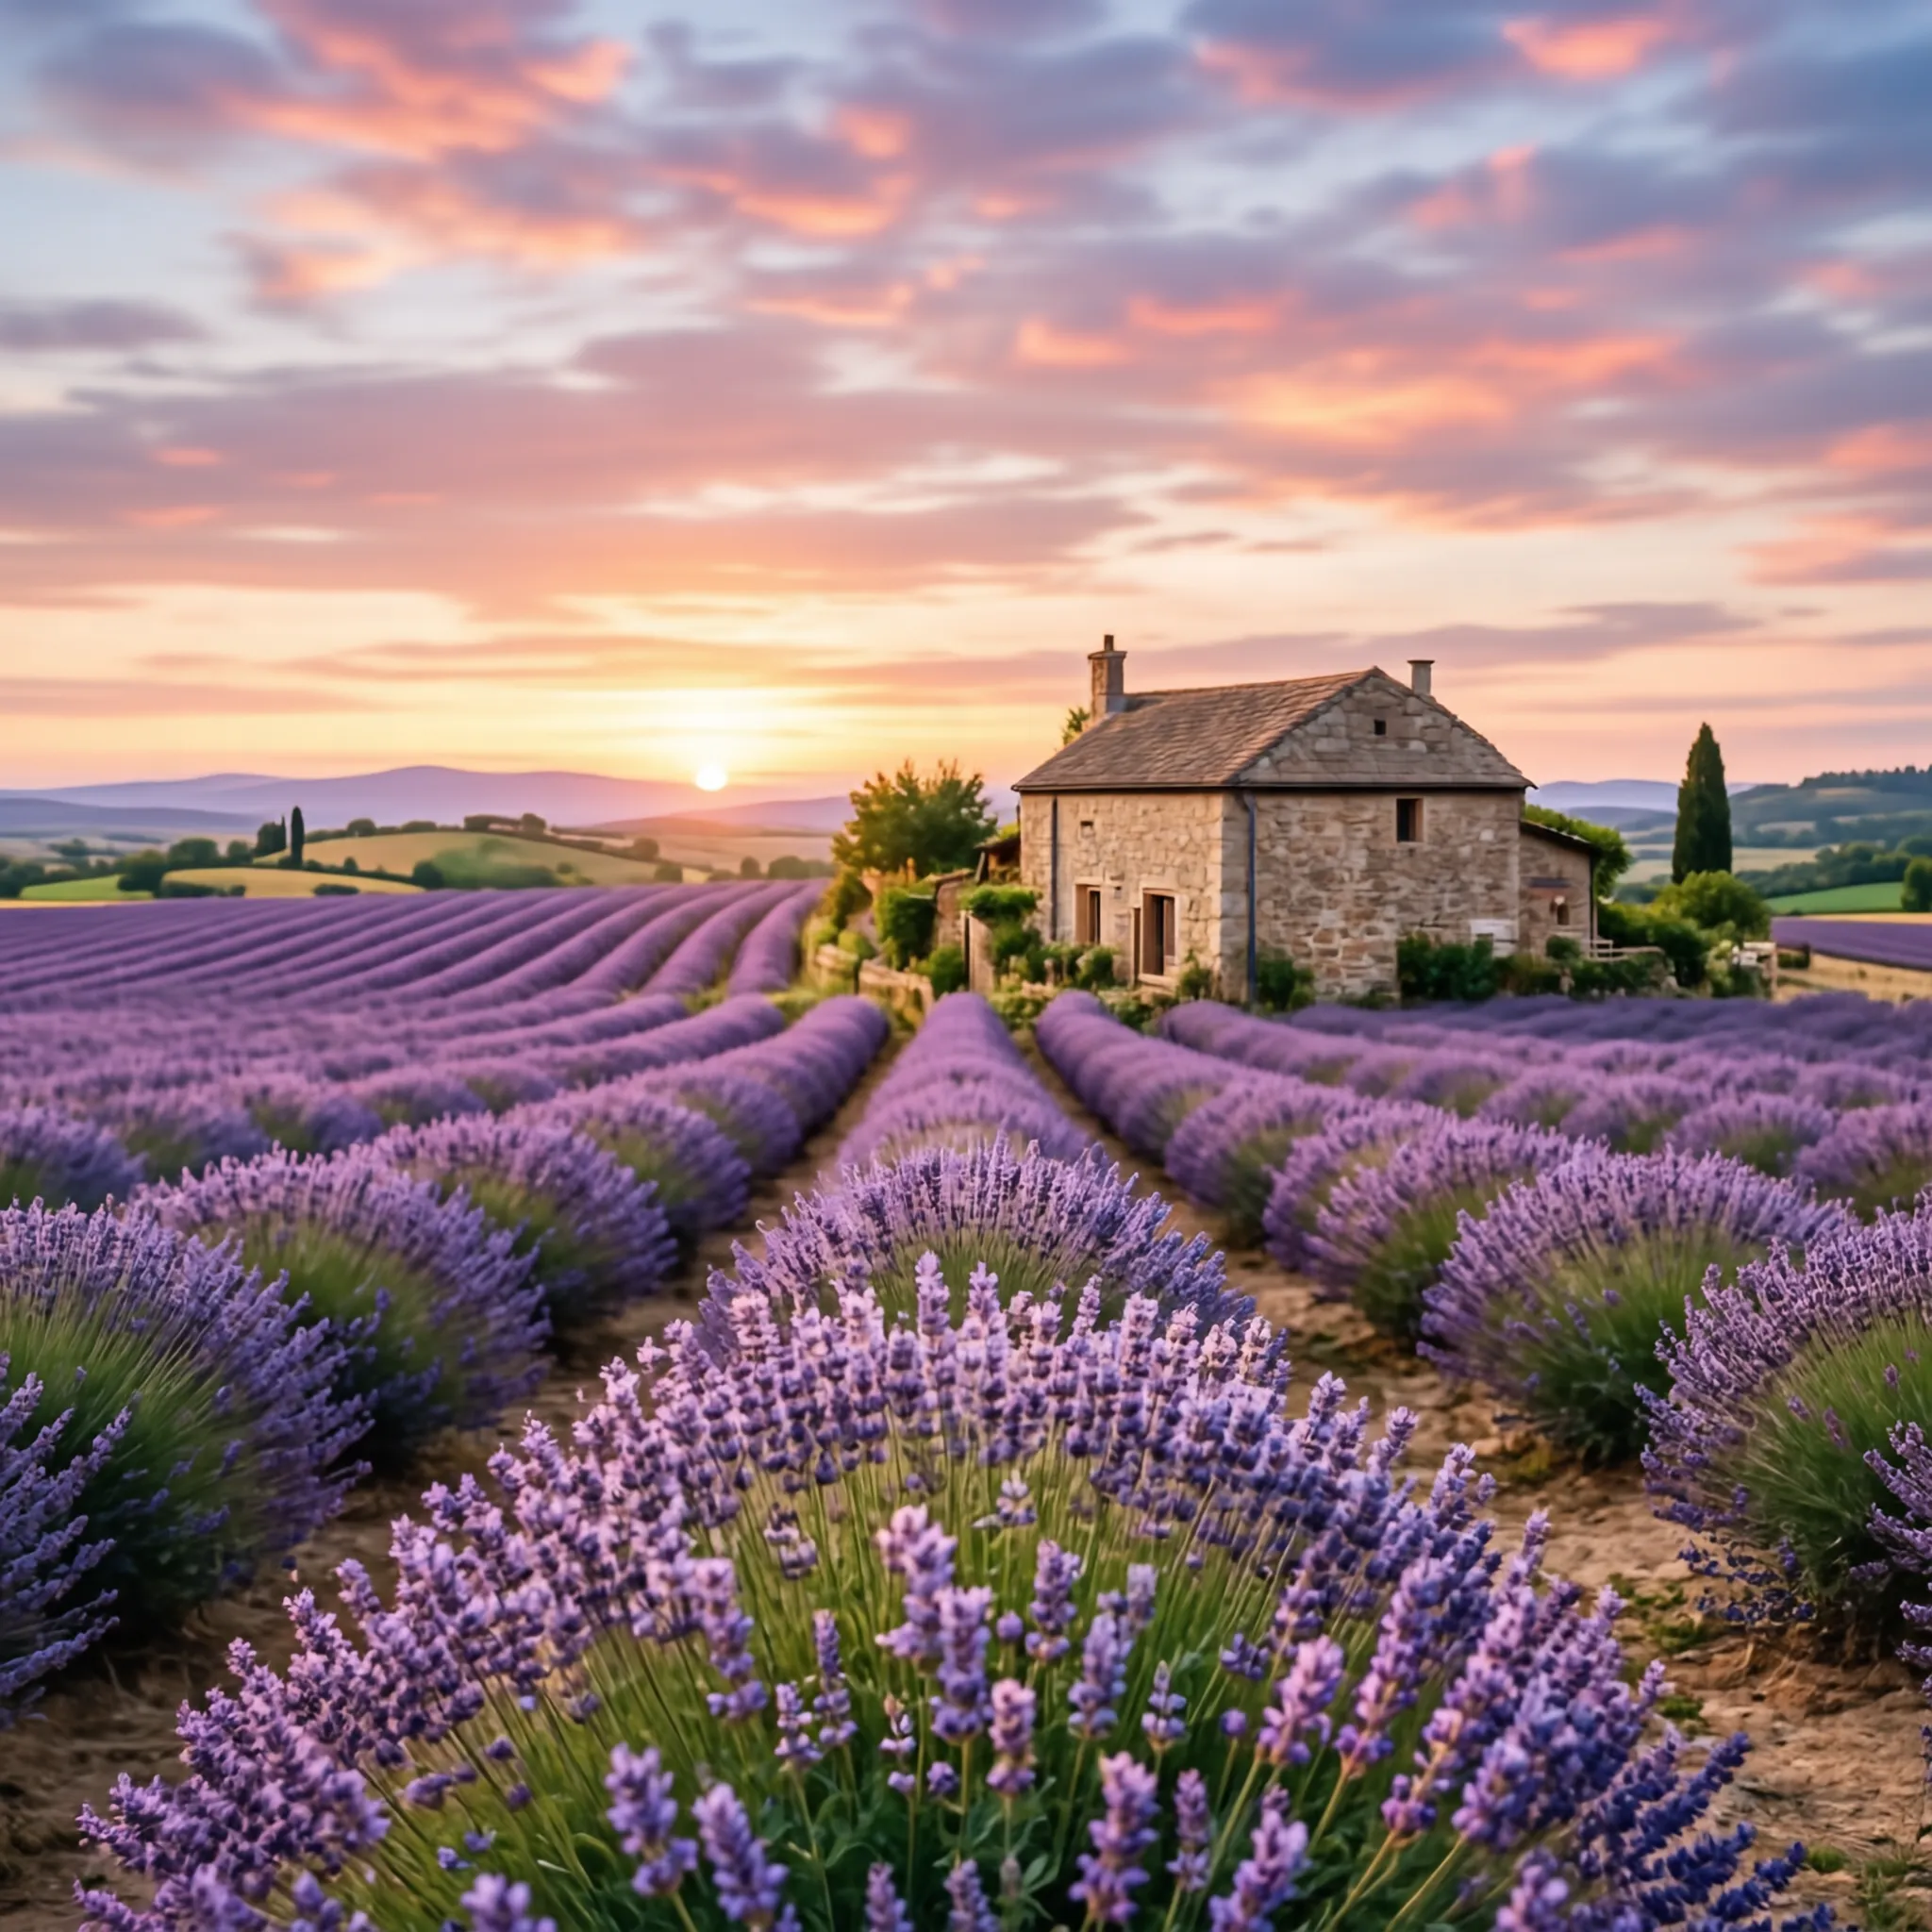
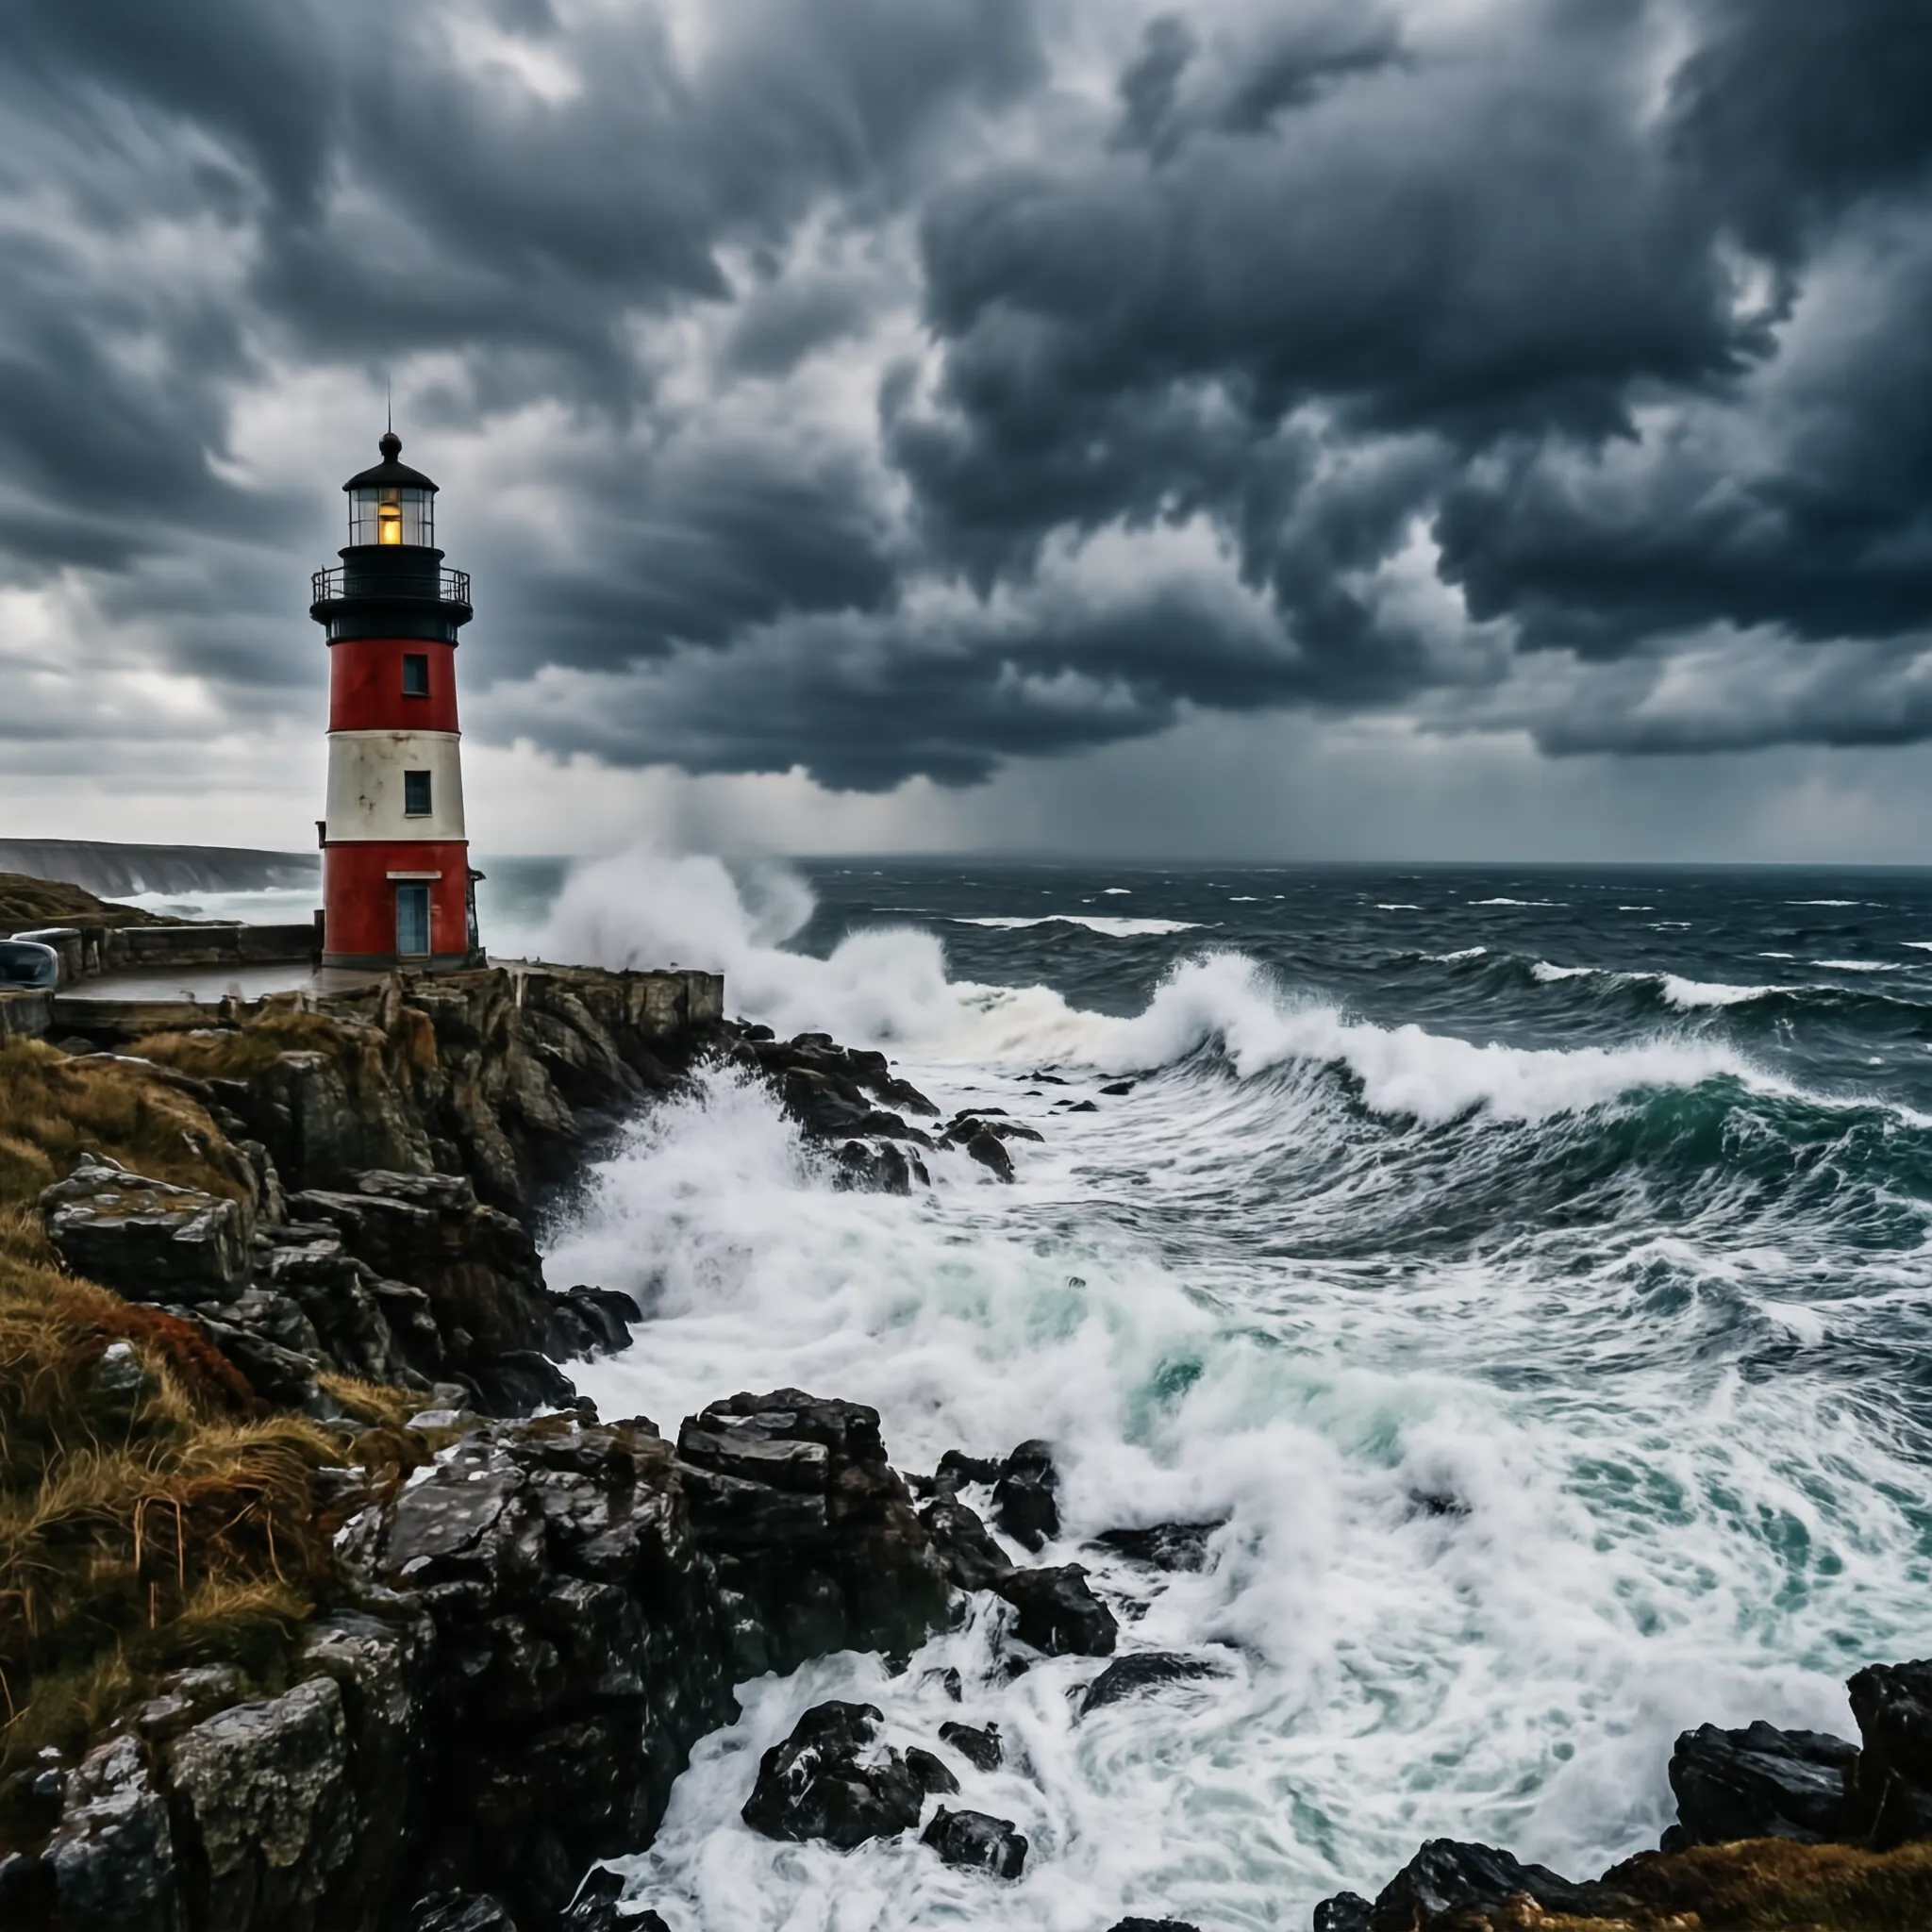
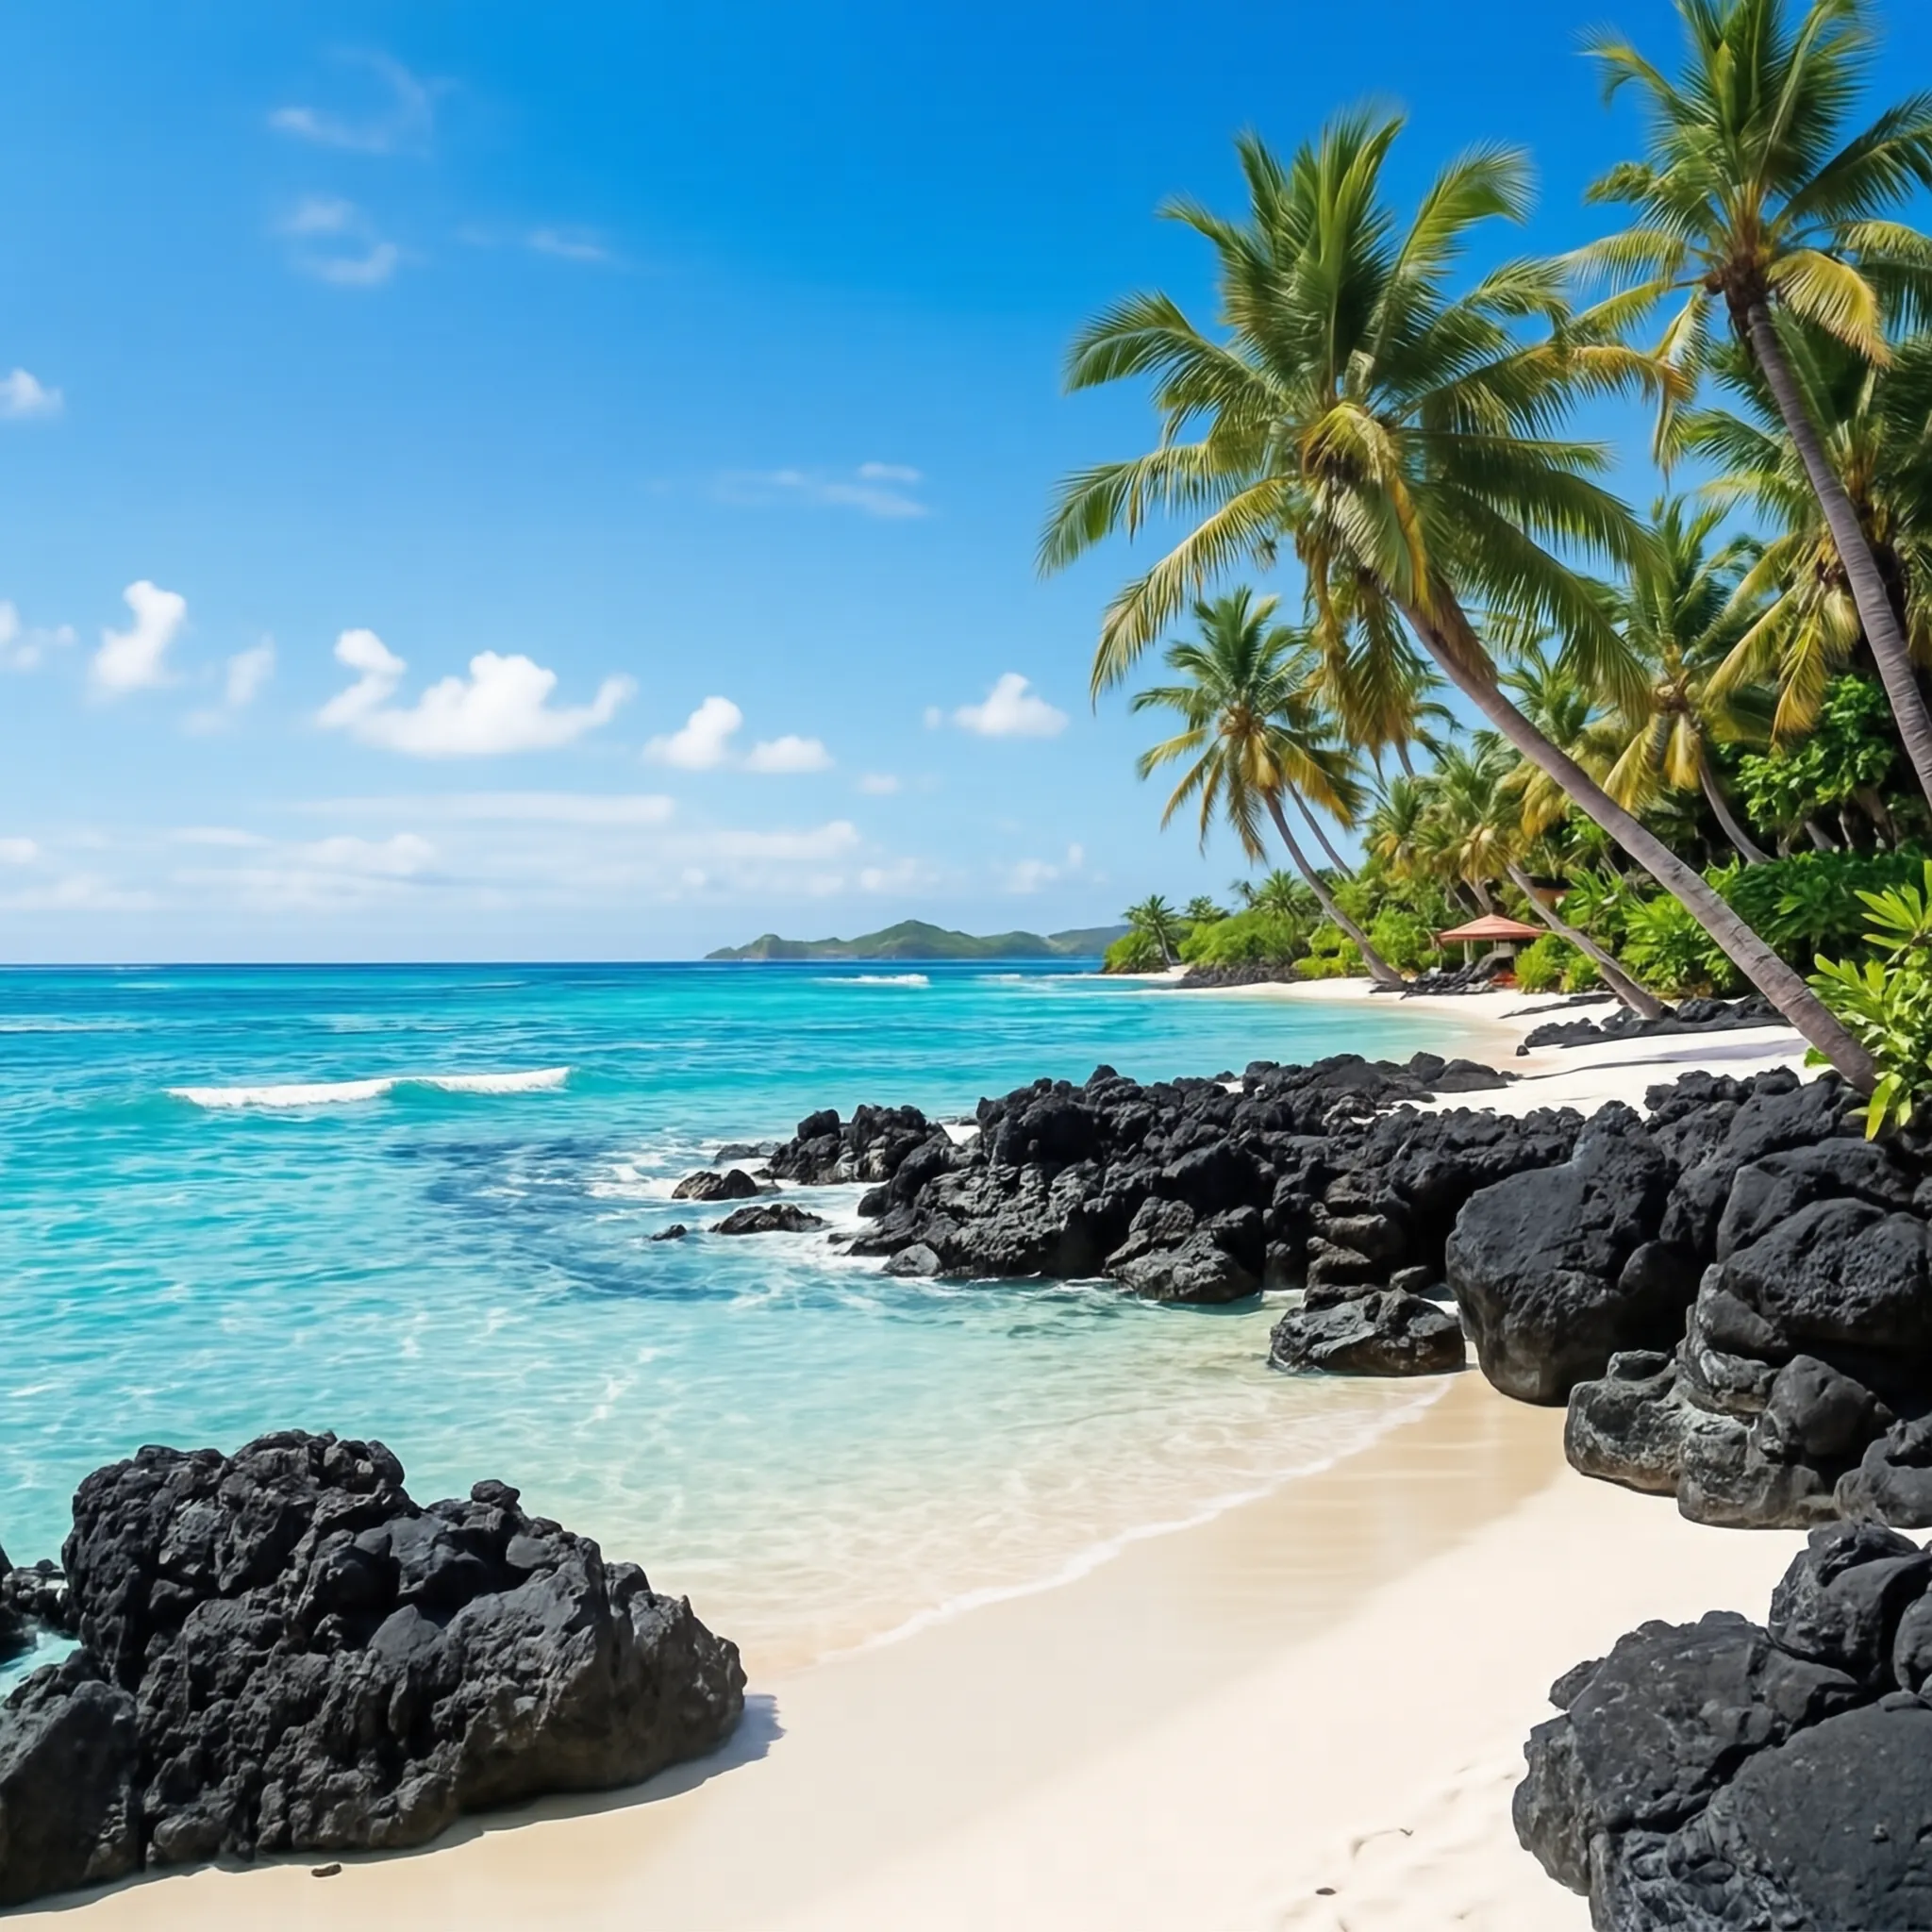
🖼️ Text-to-Image (General)
|
|
|
 |
 |
 |
 |
 |
 |
 |
 |
 |
 |
 |
[ ](./docs/assets/showcases/t2i_general/9_16_artistic_07. |


 开源多模态模型,把图像理解、推理和图像生成统一在同一个架构里。当前发布的版本是 SenseNova-U1.5-8B-MoT,可以生成和编辑最高原生 4K 分辨率的图片。