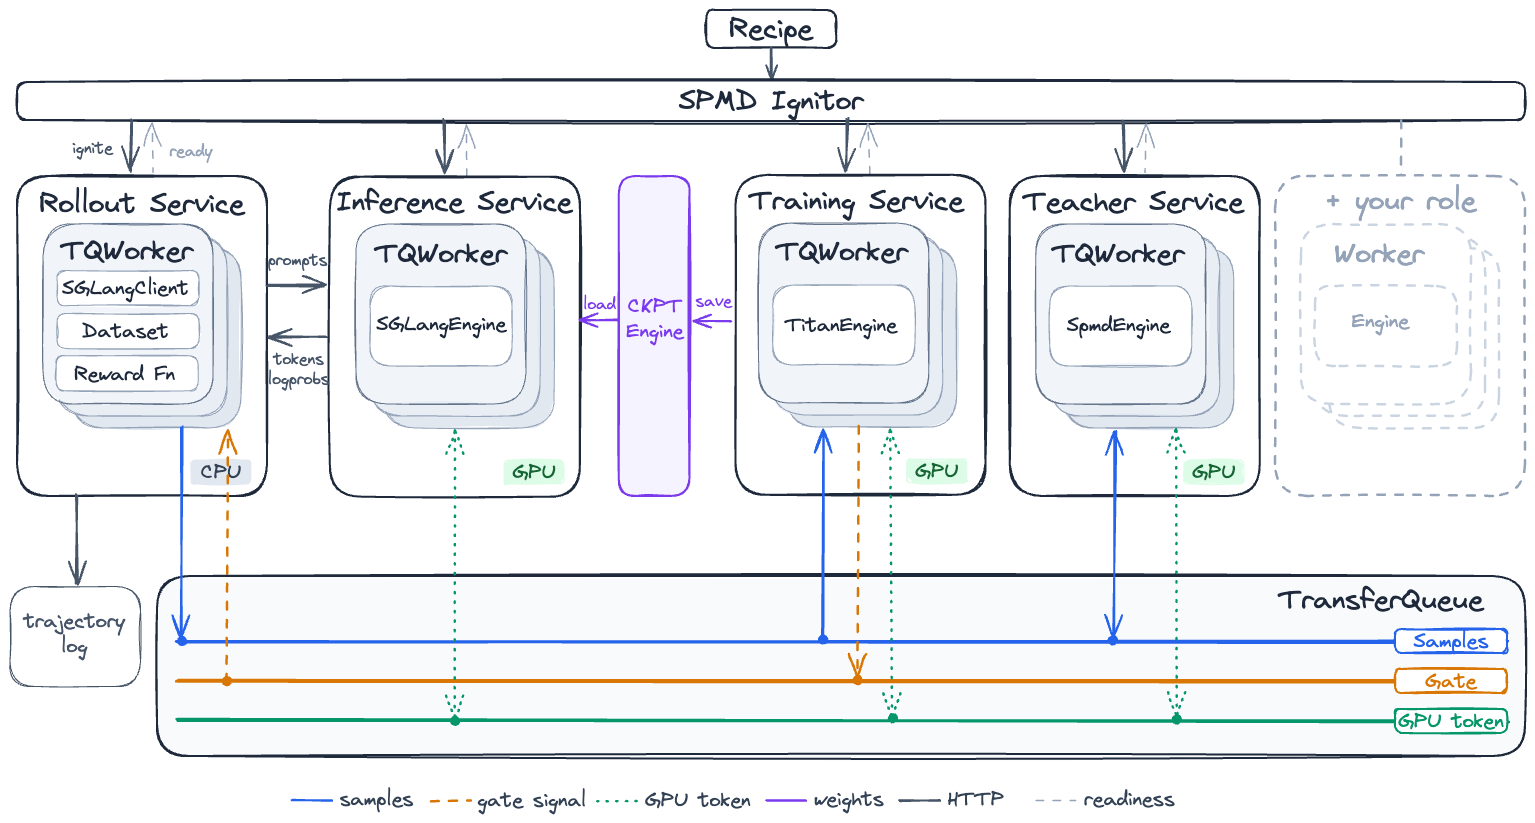
Meshy models every role of an RL run as an
independent service. Samples flow between services through a single
TransferQueue data plane, control flow is driven by data availability, and the
whole topology is derived locally by each process from one declarative recipe.
Built on SGLang and torchtitan.
Highlights
🧩 Every role as a service. Inference, training and rollout run as
independent processes that talk through queue columns and a handful of gate
signals. There is no driver that fans out RPCs or forwards every tensor.
🗂️ TransferQueue as both data and control plane. All communication happens through queue columns; column readiness is the only control signal, so services never handshake directly. Gate pulses, GPU ownership, and tensors themselves travel in the same middleware.
⚡ Native async algorithm support. Recipes for on-policy, bounded
off-policy and fully asynchronous training use the same set of services, with
only the rollout pacing window as a knob.
🧭 Topology as a pure function. Full placement is calculated SPMD-style on
each machine, without the need for service discovery. A misplaced recipe is
identified at startup.
🔄 Colocation with any number of services. GPU
ownership is a token passed over TransferQueue; developers can freely
arrange any number of services colocated on the same set of GPUs.
🪶 Lightweight and debuggable. Logs are kept one file per service with full
tracebacks. When something stalls, the queue shows it as piled-up unconsumed
columns.
News
- [2026.09.07] 🎉 Meshy is now open-source! Visit our blog for details.
Quick Start
Prerequisites
- NVIDIA GPU with CUDA 12.9 support
- Docker with NVIDIA Container Toolkit (or a native Ubuntu 24.04 environment)
- Python 3.12+ (if installing manually)
Option 1: Use the Prebuilt Docker Image (Recommended)
The easiest way to get started is to pull and run our prebuilt image:
docker pull ztonyzhao/meshy:0.1.0-alpha
docker run --gpus all -it --rm ztonyzhao/meshy:0.1.0-alpha
Option 2: Use the Provided Dockerfile
You can also build the Docker image yourself.
docker build -t meshy .
docker run --gpus all -it --rm meshy
This will drop you into a shell with the virtual environment already activated at /opt/meshy. All dependencies (PyTorch, SGLang, TorchTitan, TransferQueue) are pre-installed.
Option 3: Manual Installation
If you prefer to set up the environment without Docker, follow the step-by-step guide in docs/manual_install.md.
Run a recipe
From the repository root, launch any recipe with the same command. The
launcher starts TransferQueue, then runs torchrun with one ignitor per
GPU:
python scripts/launch.py --recipe recipe.grpo_gsm8k
This is the smallest end-to-end run: Qwen3-1.7B on GSM8K, one GPU by default. Model weights are downloaded from Hugging Face on first use.
Logs, checkpoints, and TensorBoard events land under .xrl_runtime/<timestamp>/.
For the JustRL lock-step GRPO setup (8 colocated cards), swap the module:
python scripts/launch.py --recipe recipe.justrl
Use recipe.justrl_smoke for a two-batch sanity check of that layout. The
table below lists every bundled recipe; only the module name after --recipe
changes.
Recipes
A recipe is a plain Python module under recipe/ that declares the services of
a run and hands them to the ignitor. Every recipe below runs through the same
launcher:
python scripts/launch.py --recipe recipe.<name>
| Recipe |
Model / data |
GPUs and layout |
Pacing |
What it shows |
grpo_gsm8k |
Qwen3-1.7B · GSM8K |
XRL_NGPUS cards; XRL_TOPOLOGY=colocate (1×TPN + FSDPN on the same cards) or disaggregate (N×TP1 + FSDP on the rest) |
1 |
The minimal, env-tunable baseline; the same file switches topology |
grpo_gsm8k_qwen3_8b |
Qwen3-8B · GSM8K |
8 cards; 8×TP1 inference colocated with 1×FSDP8 trainer |
1 |
Asymmetric colocation: inference and training partition the same cards differently |
justrl |
R1-Distill-Qwen-1.5B · DAPO-Math-17k |
8 cards; 8×TP1 + DDP8 colocated |
1 |
Lock-step GRPO with the JustRL hyper-parameters |
justrl_async |
same |
same |
2 |
Bounded off-policy overlap: generation may run one batch ahead of training |
justrl_fully_async |
same |
16 cards; 8×TP1 inference + 1×DDP8 trainer, disaggregated |
None |
Fully asynchronous with stream_minibatch: the trainer steps as chunks arrive |
justrl_smoke |
same |
8 cards, colocated |
1 |
Two-batch, one-epoch version of justrl for end-to-end checks |
justrl_minicpm5_1b / _2b / _2b_4gpu |
MiniCPM5-1B / 2B · DAPO-Math-17k |
8 cards (or 4) colocated |
1 |
JustRL setup on the MiniCPM5 family |
justrl_qwen3_30b_a3b |
Qwen3-30B-A3B (MoE) · DAPO-Math-17k |
8 cards; 1×(TP8 + EP8) inference colocated with 1×FSDP8 trainer |
1 |
MoE inference with expert parallel; 16k context |
math_grpo_minicpm5_2b / _4gpu |
MiniCPM5-2B · local S9 math set |
8 cards (or 4); 8×TP1 inference colocated with a CP4 trainer |
None |
128k context: context parallel, dynamic batching, custom advantage shaping, 1024 in-flight requests |
Same services, one knob
justrl, justrl_async and justrl_fully_async train the same model with the
same hyper-parameters. They differ only in the rollout config and, for the last
one, the GPU layout:
|
pacing_window |
async_max_running_request |
Trainer |
Topology |
justrl |
1 |
— |
batch |
colocate |
justrl_async |
2 |
1.5 × batch |
batch |
colocate |
justrl_fully_async |
None |
1.5 × batch |
stream_minibatch=True |
disaggregate |
There is no separate synchronous or asynchronous code path in the framework:
the trainer always emits one gate per weight version, and the rollout service
decides how many gates it waits for.
Writing your own recipe
A recipe exports three things: SERVICE_GROUPS, COLOCATIONS (when GPU
groups share cards) and main(). Roles are typed configs; wiring between
them is derived by the ignitor.
from meshy.config import InferenceServiceConfig, RolloutServiceConfig, TrainingServiceConfig
from meshy.service.base import ServiceGroup
from meshy.service.colocation import ColocationRing, SchedulingMode
from meshy.service.ignite import Ignitor

SERVICE_GROUPS = [
    ServiceGroup(
        id="actor_infer",
        config=InferenceServiceConfig(model_path=MODEL, server_args={"tp_size": 1, "enable_memory_saver": True}),
        n_replicas=8, n_gpus_per_replica=1,
    ),
    ServiceGroup(
        id="actor_train",
        config=TrainingServiceConfig(model_path=MODEL, trainer_config=..., batch_size=2048),
        n_replicas=1, n_gpus_per_replica=8,
    ),
    ServiceGroup(
        id="rollout",
        config=RolloutServiceConfig(
            model_path=MODEL,
            dataset="meshy.dataset.math:MATH",
            reward="meshy.dataset.math:MATH.reward",
            group_size=8, pacing_window=1,
        ),
        n_replicas=1, n_gpus_per_replica=0,
    ),
]

COLOCATIONS = [
    ColocationRing(
        group_id="actor_card",
        ring=(("actor_infer", SchedulingMode.FALLBACK),
              ("actor_train", SchedulingMode.ON_DEMAND)),
    ),
]


def main() -> None:
    Ignitor(SERVICE_GROUPS, COLOCATIONS).run()
dataset, reward and advantage accept "module:attr" strings, so a new
task is a class with next_batch() and a reward function — no framework
edit.- Drop
colocate_with and COLOCATIONS to run disaggregated; the same
services run unchanged with a no-op colocation manager.
- A new role is a
ServiceConfig subclass pointing at a Service class; add
it to SERVICE_GROUPS and, if it needs to share GPUs, to a ring.
See docs/how_to_build_a_recipe.md for a
step-by-step guide.
Citation
If you find Meshy helpful, please cite us.
@misc{zhao2026meshy,
    title   = {Meshy: A Role-Driven RL Training Framework under SPMD Paradigm},
    author  = {Tianyun, Zhao and Ao, Sun and Changlong, Li and Yinghao, Chen and Haoxuan, Pan and Jinqian, Zhang and Zekai, Qu and Bingxiang, He and ChaoJun, Xiao and Xu, Han},
    year    = {2026},
    url     = {https://maydomain.notion.site/meshy-blog-en},
    note    = {Blog post},
    urldate = {2026-09-06},
 }
Acknowledgements
Meshy composes a handful of outstanding open-source projects:
- torchtitan — PyTorch-native
distributed training engine behind every trainer
- SGLang — Fast serving framework
for large language models, and the memory saver that makes colocation work
- TransferQueue —
High-performance distributed data transfer queue, used here as the one and
only data and control plane
Its design is indebted to the pioneering work of
verl,
slime,
miles and
Relax.
The bundled recipes stand on open datasets and published setups: justrl*
reproduces JustRL on
DAPO-Math-17k, with models from the
MiniCPM and
Qwen families.



 Meshy 是一个用于运行强化学习(RL)训练任务的开源框架,其中每个角色(推理、训练、rollout)都作为独立服务运行,通过共享的 TransferQueue 数据平面通信。它构建在 SGLang 和 torchtitan 之上。