
Model-Optimizer README

The project's README from github.com/NVIDIA/Model-Optimizer. As one markdown file: README.md.

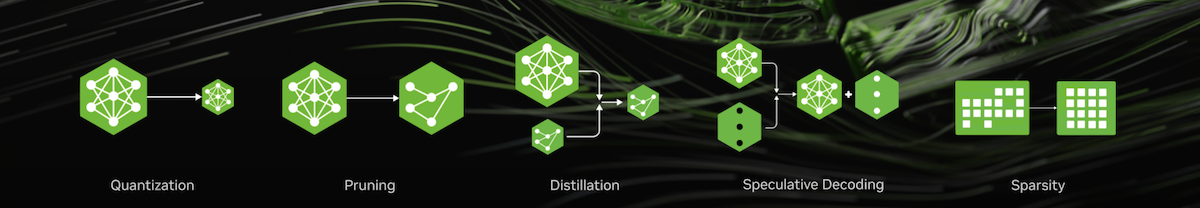
Banner image

NVIDIA Model Optimizer

Documentation version license

Documentation | Roadmap | Announcement Blogs


NVIDIA Model Optimizer (referred to as Model Optimizer, or ModelOpt) is a library comprising state-of-the-art model optimization techniques including quantization, pruning, Neural Architecture Search (NAS), distillation, speculative decoding and sparsity to accelerate models.

[Input] Model Optimizer currently supports inputs of a Hugging Face, PyTorch or ONNX model.

[Optimize] Model Optimizer provides Python APIs for users to easily compose the above model optimization techniques and export an optimized quantized checkpoint. Model Optimizer is also integrated with NVIDIA Megatron-Bridge, Megatron-LM and Hugging Face Accelerate for training required inference optimization techniques.

[Export for deployment] Seamlessly integrated within the NVIDIA AI software ecosystem, the quantized checkpoint generated from Model Optimizer is ready for deployment in downstream inference frameworks like SGLang, TensorRT-LLM, TensorRT, or vLLM. The unified Hugging Face export API now supports both transformers and diffusers models.

Latest News

Previous News

Install

To install stable release packages for Model Optimizer with pip from PyPI:

pip install -U nvidia-modelopt[all]

Model Optimizer will download and install additional third-party open source software projects. Review the license terms of these open source projects before use.

To install from source in editable mode with all development dependencies or to use the latest features, run:

# Clone the Model Optimizer repository
git clone [email protected]:NVIDIA/Model-Optimizer.git
cd Model-Optimizer

pip install -e .[dev]

You can also directly use NVIDIA container images, which have Model Optimizer pre-installed:

Before pulling and using the container images, please review their respective license terms. Make sure to upgrade Model Optimizer to the latest version as described above. Visit our installation guide for more fine-grained control on installed dependencies or for alternative docker images and environment variables to setup.

Techniques

Technique Description Examples Docs
Post Training Quantization Compress model size by 2x-4x, speeding up inference while preserving model quality! [HF LLMs / VLMs] [Megatron-Bridge LLMs / VLMs] [Diffusers] [ONNX] [Windows] [docs]
Quantization Aware Training / Distillation Refine accuracy of quantized models even further with a few training steps! [Hugging Face] [Megatron-Bridge] [docs]
Pruning Reduce your model parameters or memory footprint and accelerate inference by removing unnecessary weights! [General] [Megatron-Bridge]
Distillation Reduce deployment model size by teaching small models to behave like larger models! [Hugging Face] [Megatron-Bridge] [Megatron-LM] [docs]
Speculative Decoding Train draft modules to predict extra tokens during inference! [Hugging Face] [Megatron-LM] [docs]
Sparsity Efficiently compress your model by storing only its non-zero parameter values and their locations [Hugging Face] [docs]

Pre-Quantized Checkpoints

Resources

Model Support Matrix

Model Type Support Matrix
LLM / VLM Quantization View Support Matrix
Diffusers Quantization View Support Matrix
ONNX Quantization View Support Matrix
Windows Quantization View Support Matrix
Quantization Aware Training View Support Matrix
Pruning View Support Matrix
Distillation View Support Matrix
Speculative Decoding View Support Matrix

Deprecation Policy

Model Optimizer follows a structured approach to managing deprecated features:

Citation

If you use NVIDIA Model Optimizer in your research, please cite it as follows:

@misc{nvidia-modelopt,
  author       = {{NVIDIA Corporation}},
  title        = {{NVIDIA Model Optimizer}},
  howpublished = {\url{https://github.com/NVIDIA/Model-Optimizer}},
  year         = {2024--2026},
  note         = {GitHub repository}
}

Contributing

Model Optimizer is now open source! We welcome any feedback, feature requests and PRs. Please read our Contributing guidelines for details on how to contribute to this project.

AI Agents

ModelOpt's agent skills can be installed from this repository and used in any workspace.

Claude Code

claude plugin marketplace add https://github.com/NVIDIA/Model-Optimizer.git
claude plugin install modelopt@modelopt

Codex

codex plugin marketplace add https://github.com/NVIDIA/Model-Optimizer.git

Then open /plugins, select the modelopt marketplace, and install modelopt. Contributors can also use the skills directly from a checkout. See the agent tooling notes.

Top Contributors

Contributors

Happy optimizing!

Model-Optimizer (NVIDIA/Model-Optimizer)

Searching Database…

这是什么?NVIDIA Model Optimizer(ModelOpt)是一个 Python 库,集成了最先进的模型压缩技术——量化、剪枝、神经架构搜索、蒸馏、投机解码和稀疏化——用于在部署前缩小和加速深度学习模型。
这是一个独立应用,还是接入我自己流水线的库?它是一个提供可组合 API 的 Python 库:你拿一个 Hugging Face、PyTorch 或 ONNX 模型,用 Model Optimizer 处理后导出优化过的检查点——没有需要单独运行的应用。
使用它需要什么样的模型和框架配置?你需要提供 Hugging Face、PyTorch 或 ONNX 格式的输入模型;导出的检查点则面向 TensorRT-LLM、TensorRT、vLLM 或 SGLang 等 NVIDIA 生态的推理框架。
API 稳定吗?更新之间会不会出问题?项目仍处于 1.0 之前的阶段,被弃用的功能在移除前只有一个版本的迁移窗口(约 1 个月)并伴随警告,而且次版本号升级也可能包含破坏性变更。
优化过的检查点可以部署到哪些推理框架?Model Optimizer 生成的量化检查点可以直接部署到 TensorRT-LLM、TensorRT、vLLM 和 SGLang。
它提供现成的量化模型吗,还是一切都得自己量化?NVIDIA 已经在其 Hugging Face 集合中发布了 DeepSeek-R1、Llama 3.1/3.3 和 Nemotron 等模型的 FP8 和 NVFP4 预量化检查点,可直接部署在 TensorRT-LLM、vLLM 和 SGLang 上。
Claude Code 这类 AI 编程代理能直接使用这个项目吗?能——ModelOpt 提供可安装的代理技能;在 Claude Code 或 Codex 中打开 /plugins,选择 modelopt 市场,就能把技能安装到任意工作区。
这个项目以前叫别的名字吗?是的,它在 2025 年 12 月从“NVIDIA TensorRT Model Optimizer”更名为“NVIDIA Model Optimizer”。
What are similar projects?MiniCPM, DMI, jeeves, halo, decider, lectures, verl, Hy4-preview
Creator
NVIDIA
Size
166.1 MB
Stars
5.3K
Age
2y
Commits · 90 Days