
Grounded-Segment-Anything






We plan to create a very interesting demo by combining Grounding DINO and Segment Anything which aims to detect and segment anything with text inputs! And we will continue to improve it and create more interesting demos based on this foundation. And we have already released an overall technical report about our project on arXiv, please check Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks for more details.
We are very willing to help everyone share and promote new projects based on Segment-Anything, Please check out here for more amazing demos and works in the community: Highlight Extension Projects. You can submit a new issue (with project tag) or a new pull request to add new project's links.
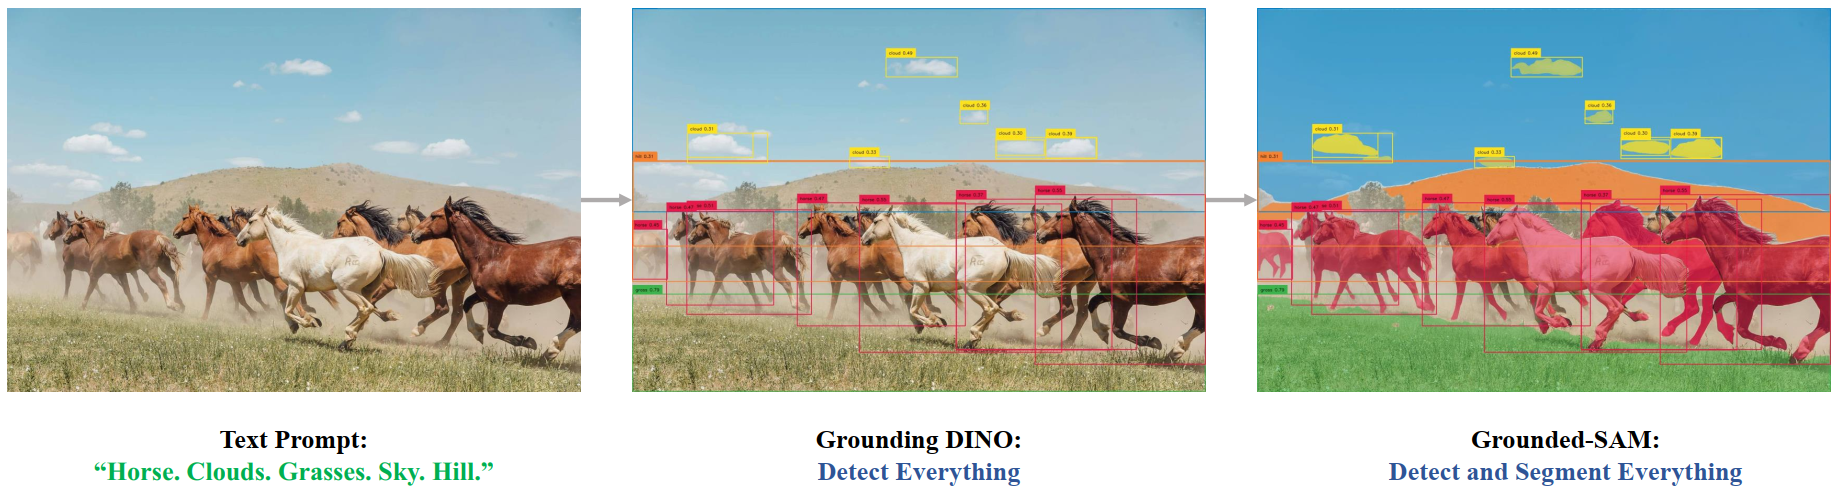
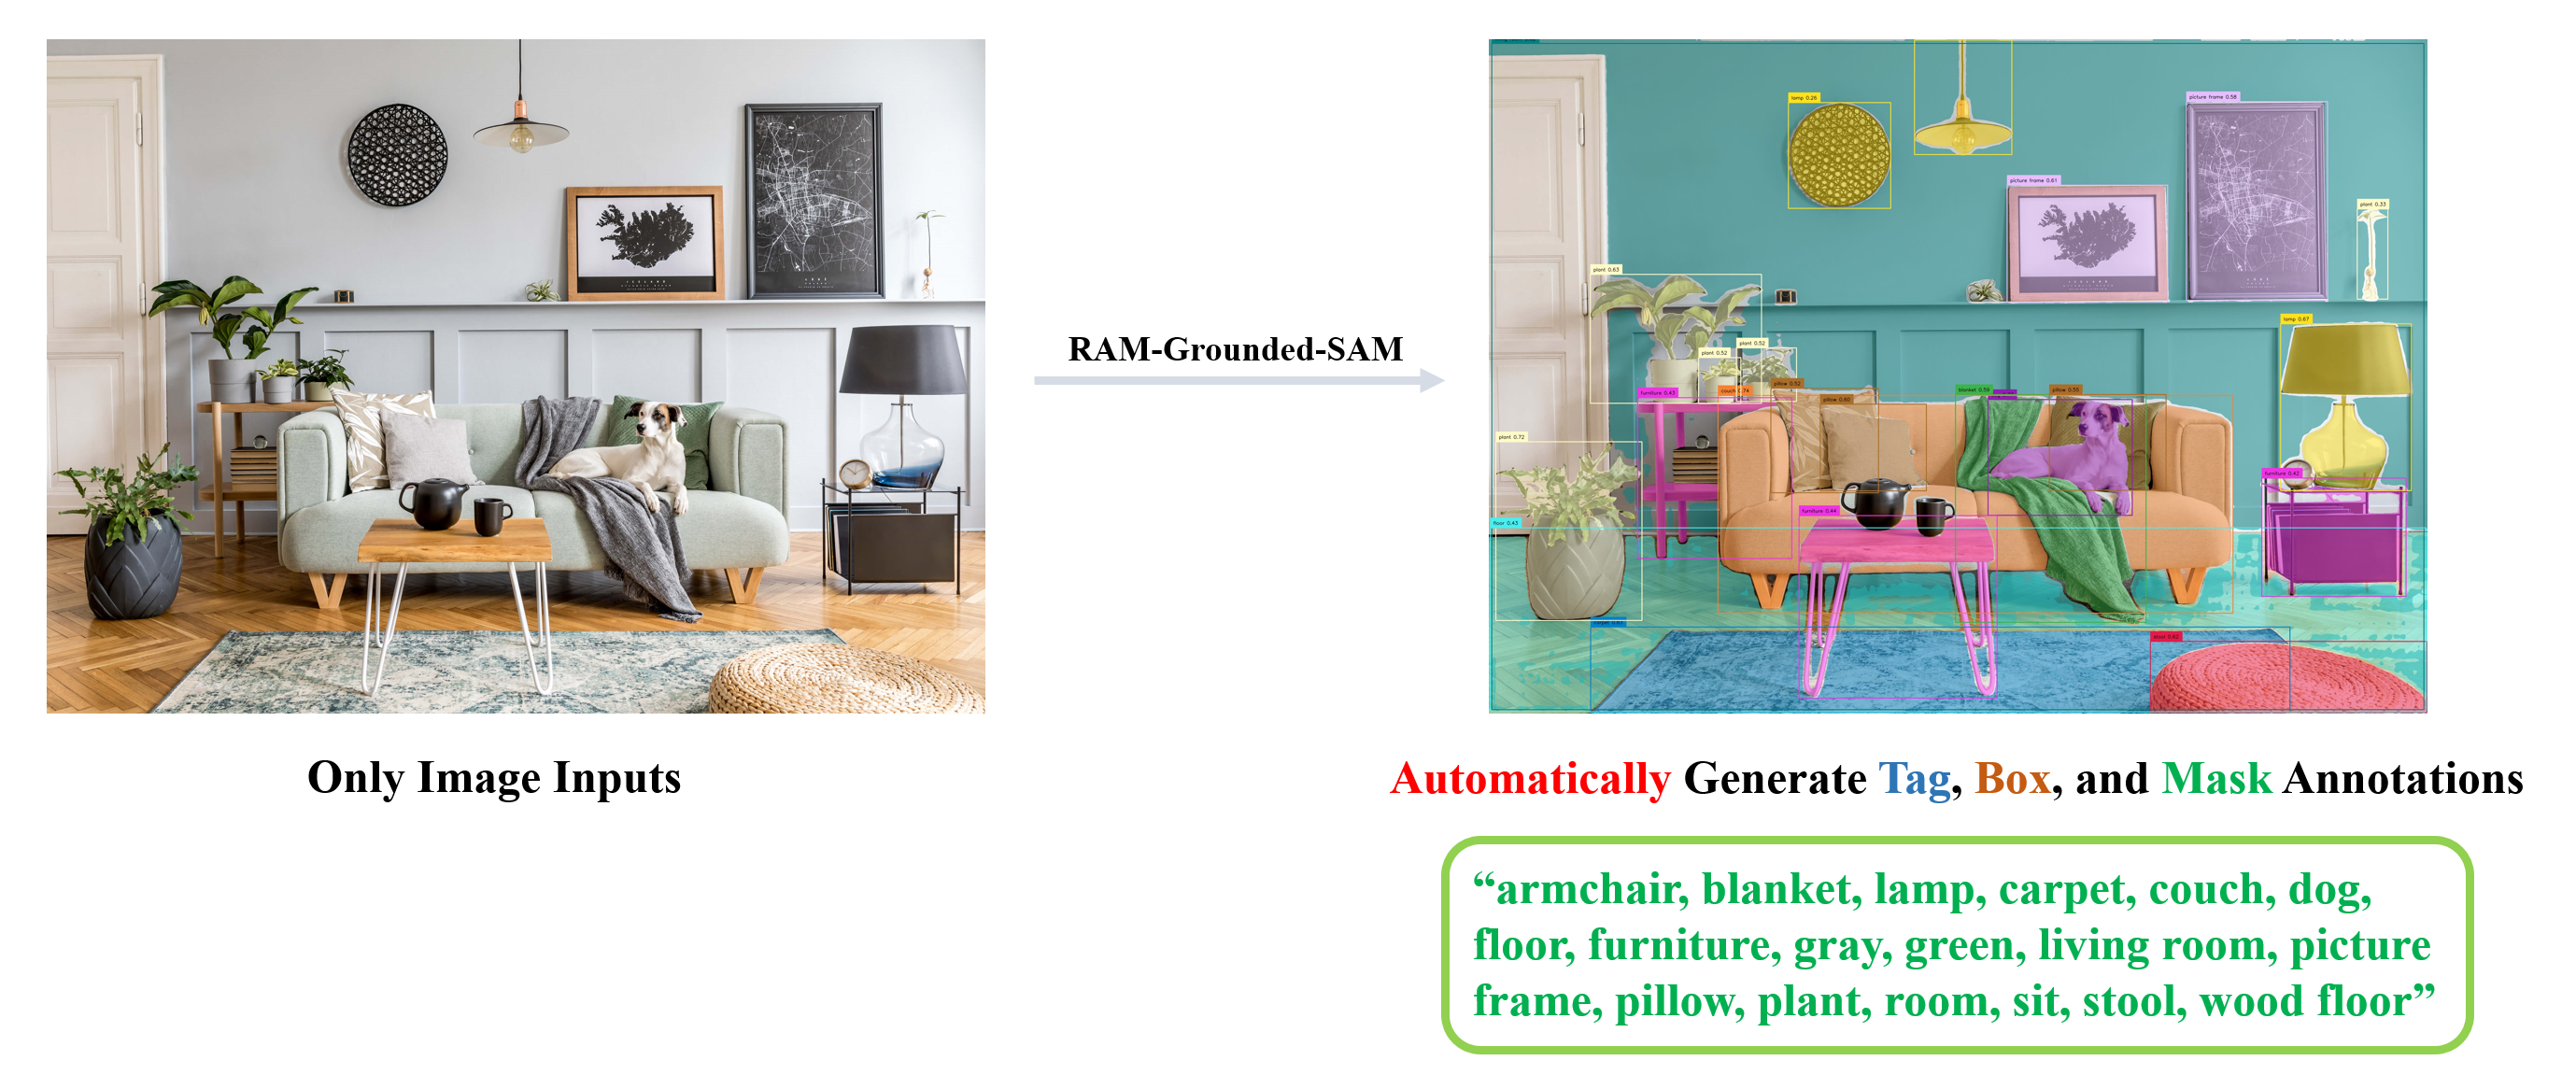
🍄 Why Building this Project?
The core idea behind this project is to combine the strengths of different models in order to build a very powerful pipeline for solving complex problems. And it's worth mentioning that this is a workflow for combining strong expert models, where all parts can be used separately or in combination, and can be replaced with any similar but different models (like replacing Grounding DINO with GLIP or other detectors / replacing Stable-Diffusion with ControlNet or GLIGEN/ Combining with ChatGPT).
🍇 Updates
2024/01/26 We have released a comprehensive technical report about our project on arXiv, please check Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks for more details. And we are profoundly grateful for the contributions of all the contributors in this project.2023/12/17 Support Grounded-RepViT-SAM demo, thanks a lot for their great work!2023/12/16 Support Grounded-Edge-SAM demo, thanks a lot for their great work!2023/12/10 Support Grounded-Efficient-SAM demo, thanks a lot for their great work!2023/11/24 Release RAM++, which is the next generation of RAM. RAM++ can recognize any category with high accuracy, including both predefined common categories and diverse open-set categories.2023/11/23 Release our newly proposed visual prompt counting model T-Rex. The introduction Video and Demo is available in DDS now.2023/07/25 Support Light-HQ-SAM in EfficientSAM, credits to Mingqiao Ye and Lei Ke, thanks a lot for their great work!2023/07/14 Combining Grounding-DINO-B with SAM-HQ achieves 49.6 mean AP in Segmentation in the Wild competition zero-shot track, surpassing Grounded-SAM by 3.6 mean AP, thanks for their great work!2023/06/28 Combining Grounding-DINO with Efficient SAM variants including FastSAM and MobileSAM in EfficientSAM for faster annotating, thanks a lot for their great work!2023/06/20 By combining Grounding-DINO-L with SAM-ViT-H, Grounded-SAM achieves 46.0 mean AP in Segmentation in the Wild competition zero-shot track on CVPR 2023 workshop, surpassing UNINEXT (CVPR 2023) by about 4 mean AP.2023/06/16 Release RAM-Grounded-SAM Replicate Online Demo. Thanks a lot to Chenxi for providing this nice demo 🌹.2023/06/14 Support RAM-Grounded-SAM & SAM-HQ and update Simple Automatic Label Demo to support RAM, setting up a strong automatic annotation pipeline.2023/06/13 Checkout the Autodistill: Train YOLOv8 with ZERO Annotations tutorial to learn how to use Grounded-SAM + Autodistill for automated data labeling and real-time model training.2023/06/13 Support SAM-HQ in Grounded-SAM Demo for higher quality prediction.2023/06/12 Support RAM-Grounded-SAM for strong automatic labeling pipeline! Thanks for Recognize-Anything.2023/06/01 Our Grounded-SAM has been accepted to present a demo at ICCV 2023! See you in Paris!2023/05/23: Support Image-Referring-Segment, Audio-Referring-Segment and Text-Referring-Segment in ImageBind-SAM.2023/05/03: Checkout the Automated Dataset Annotation and Evaluation with GroundingDINO and SAM which is an amazing tutorial on automatic labeling! Thanks a lot for Piotr Skalski and Roboflow!
Table of Contents
Preliminary Works
Here we provide some background knowledge that you may need to know before trying the demos.
| Title |
Intro |
Description |
Links |
| Segment-Anything |
 |
A strong foundation model aims to segment everything in an image, which needs prompts (as boxes/points/text) to generate masks |
[Github]
[Page]
[Demo] |
| Grounding DINO |
 |
A strong zero-shot detector which is capable of to generate high quality boxes and labels with free-form text. |
[Github]
[Demo] |
| OSX |
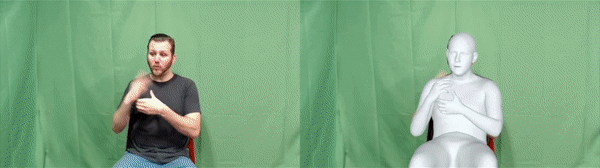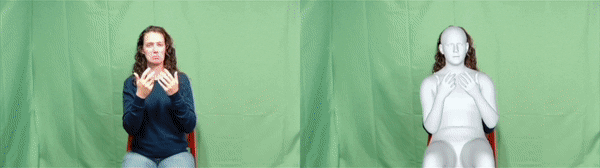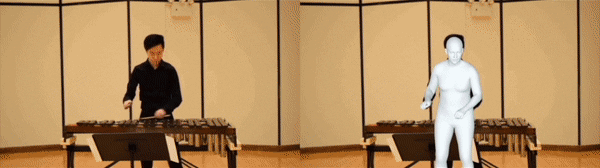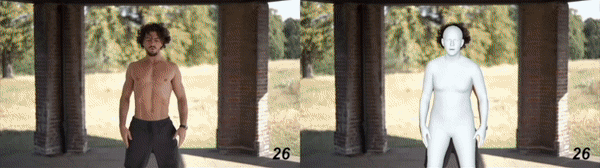 |
A strong and efficient one-stage motion capture method to generate high quality 3D human mesh from monucular image. OSX also releases a large-scale upper-body dataset UBody for a more accurate reconstrution in the upper-body scene. |
[Github]
[Page]
[Video]
[Data] |
| Stable-Diffusion |
 |
A super powerful open-source latent text-to-image diffusion model |
[Github]
[Page] |
| RAM++ |
 |
RAM++ is the next generation of RAM, which can recognize any category with high accuracy. |
[Github] |
| RAM |
 |
RAM is an image tagging model, which can recognize any common category with high accuracy. |
[Github]
[Demo] |
| BLIP |
 |
A wonderful language-vision model for image understanding. |
[GitHub] |
| Visual ChatGPT |
 |
A wonderful tool that connects ChatGPT and a series of Visual Foundation Models to enable sending and receiving images during chatting. |
[Github]
[Demo] |
| Tag2Text |
 |
An efficient and controllable vision-language model which can simultaneously output superior image captioning and image tagging. |
[Github]
[Demo] |
| VoxelNeXt |
 |
A clean, simple, and fully-sparse 3D object detector, which predicts objects directly upon sparse voxel features. |
[Github] |
Highlighted Projects
Here we provide some impressive works you may find interesting:
| Title |
Description |
Links |
| Semantic-SAM |
A universal image segmentation model to enable segment and recognize anything at any desired granularity |
[Github]
[Demo] |
| SEEM: Segment Everything Everywhere All at Once |
A powerful promptable segmentation model supports segmenting with various types of prompts (text, point, scribble, referring image, etc.) and any combination of prompts. |
[Github]
[Demo] |
| OpenSeeD |
A simple framework for open-vocabulary segmentation and detection which supports interactive segmentation with box input to generate mask |
[Github] |
| LLaVA |
Visual instruction tuning with GPT-4 |
[Github]
[Page]
[Demo]
[Data]
[Model] |
| GenSAM |
Relaxing the instance-specific manual prompt requirement in SAM through training-free test-time adaptation |
[Github]
[Page] |
We also list some awesome segment-anything extension projects here you may find interesting:

 Grounded SAM 是一个研究演示项目,把 Grounding DINO 和 Segment Anything 结合起来,只需输入一段普通文字,就能检测并分割图片中的任意物体;项目还扩展集成了 Stable Diffusion、RAM、Whisper 等模型。