










Что это такое?
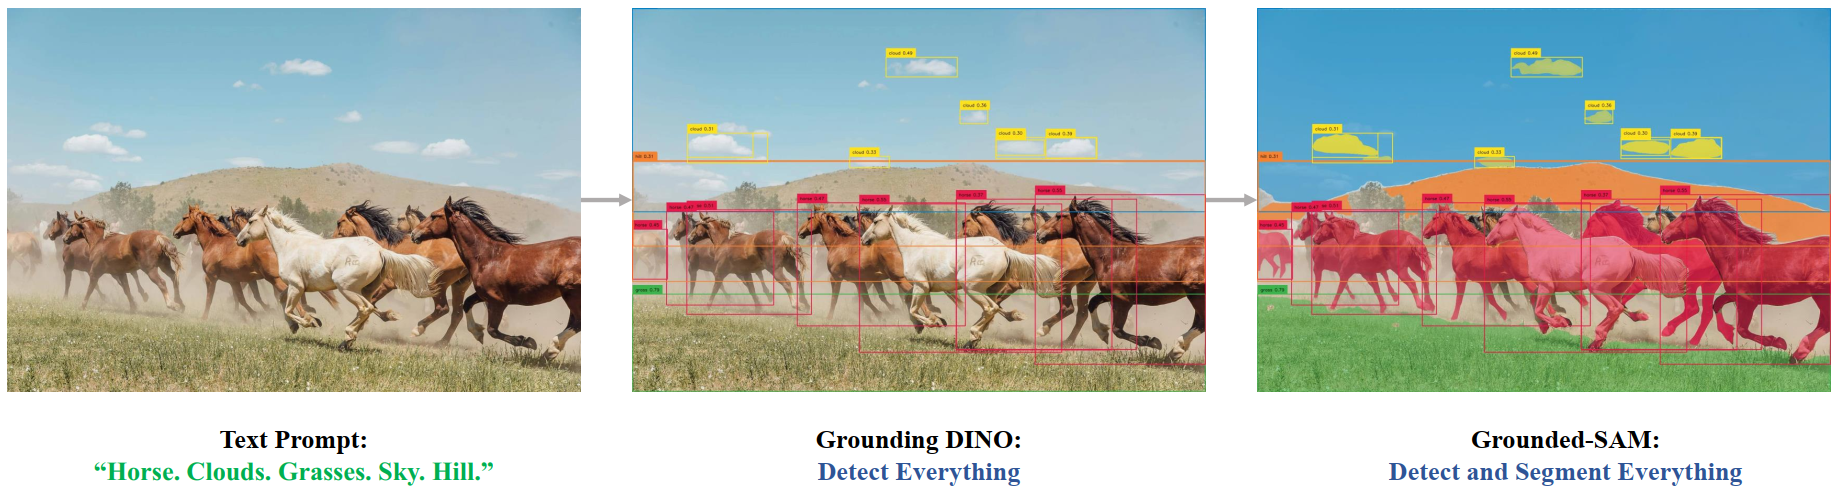
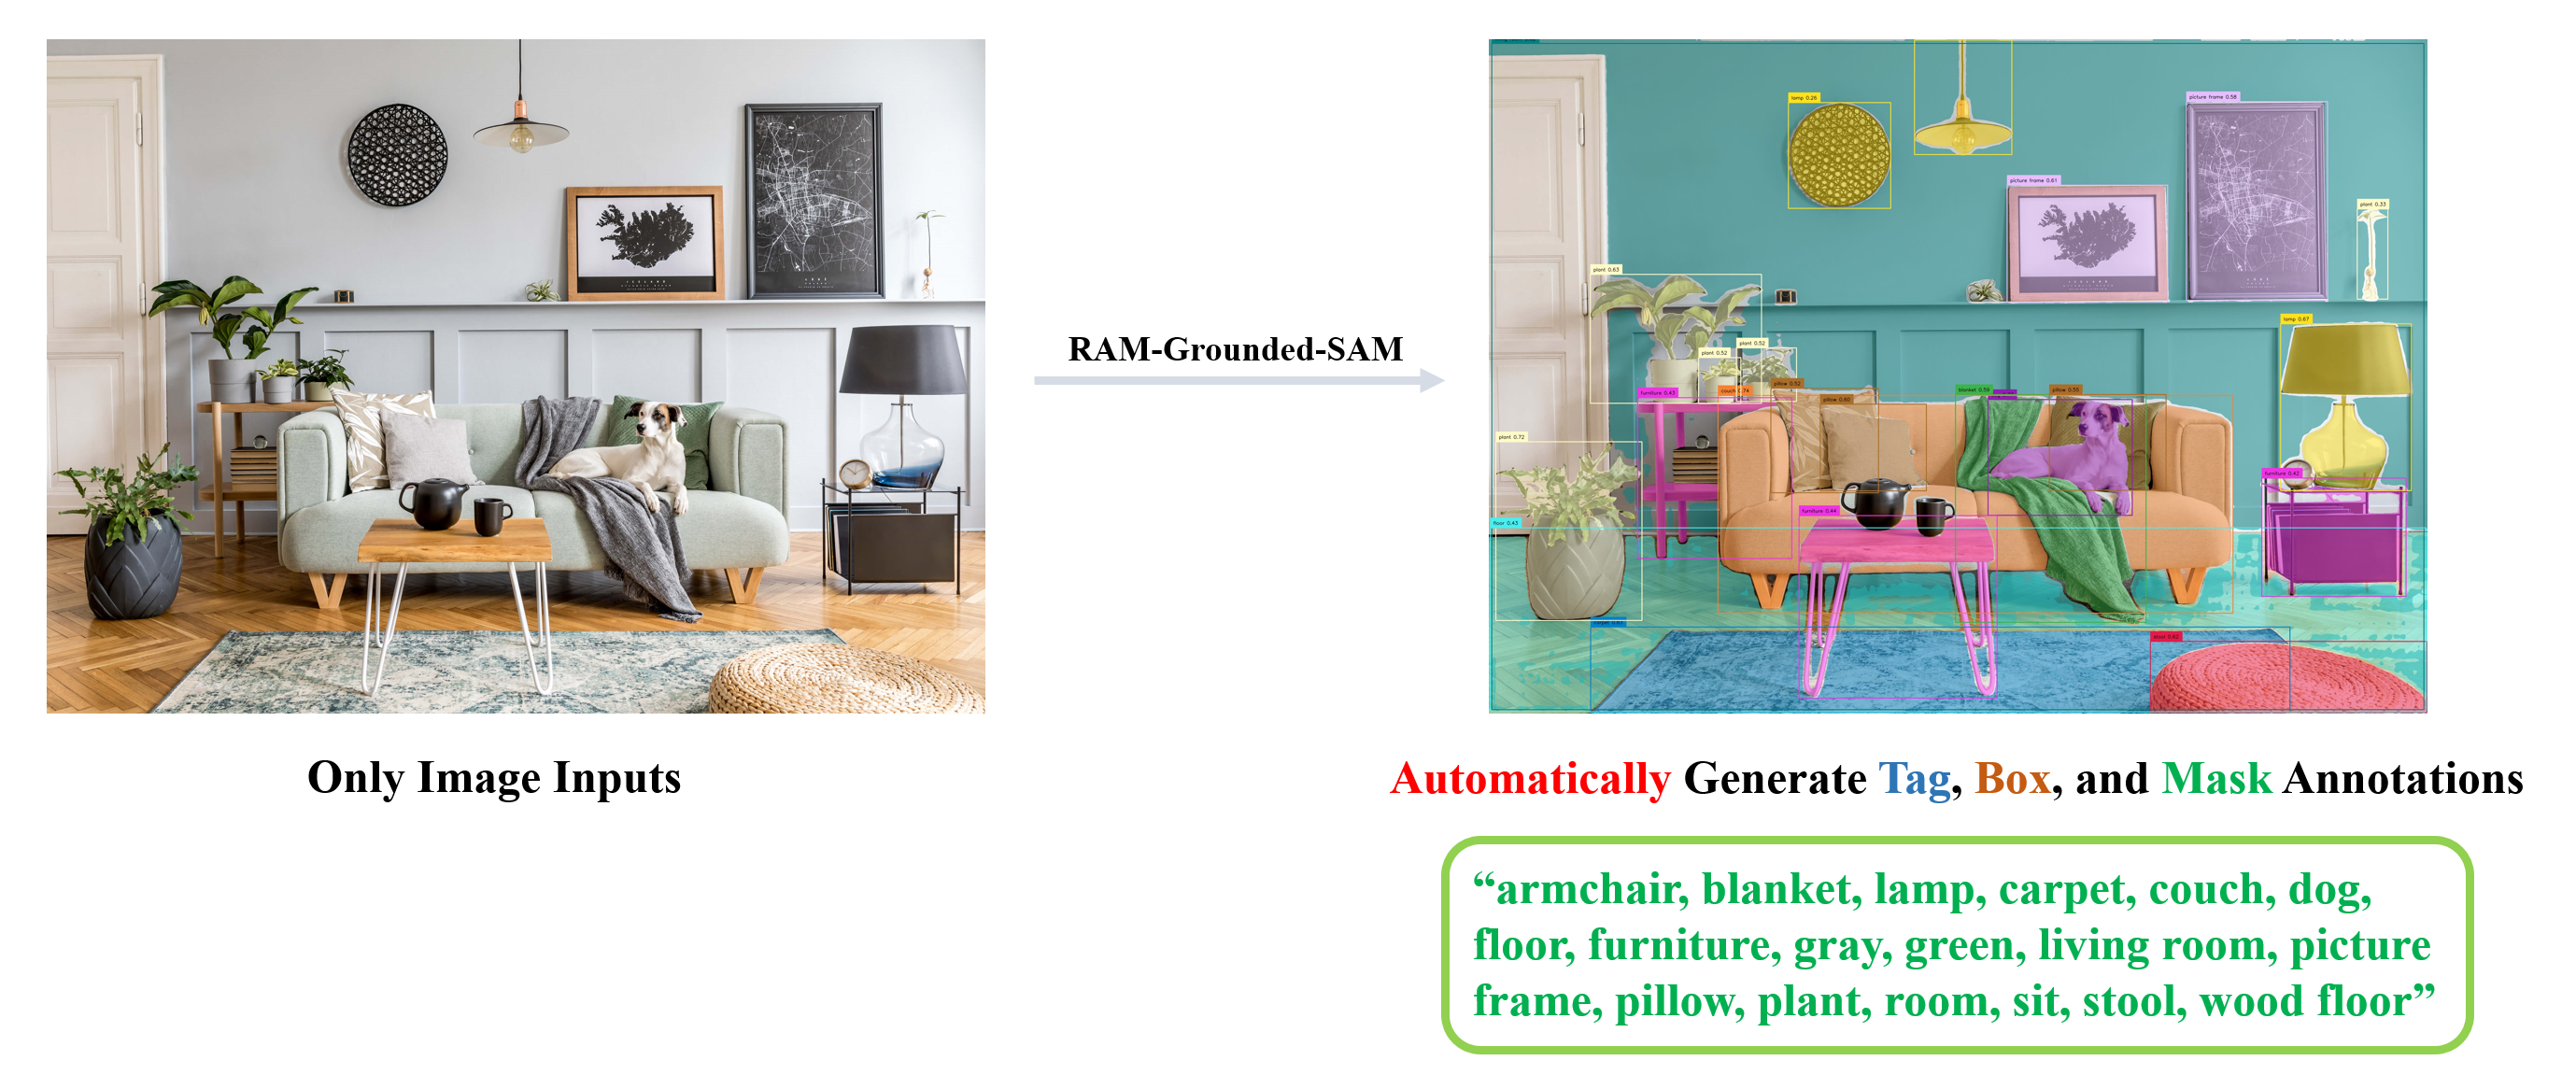
 Grounded SAM — исследовательский демо-проект, который объединяет Grounding DINO и Segment Anything, чтобы находить и выделять любой объект на изображении по обычному текстовому запросу; дополнен Stable Diffusion, RAM, Whisper и другими моделями.
Это библиотека, которую можно импортировать, или набор демо, которые я запускаю?Это набор готовых исследовательских демо, а не устанавливаемый пакет: пошаговые демо в виде ноутбуков, Grounded-SAM playground и приложения на Gradio, плюс вариант установки через Docker.
Это набор готовых исследовательских демо, а не устанавливаемый пакет: пошаговые демо в виде ноутбуков, Grounded-SAM playground и приложения на Gradio, плюс вариант установки через Docker.Как мне его запустить?Склонируйте репозиторий и следуйте разделу Installation в README: установите всё через Docker или настройте локальное окружение Python, затем запустите нужное демо-ноутбук или приложение на Gradio.
Склонируйте репозиторий и следуйте разделу Installation в README: установите всё через Docker или настройте локальное окружение Python, затем запустите нужное демо-ноутбук или приложение на Gradio.Какие модели на самом деле работают под капотом?Сразу несколько тяжёлых open-world моделей: Grounding DINO для детекции, Segment Anything для масок, плюс по желанию Stable Diffusion для inpainting, RAM или BLIP для автоматической разметки и Whisper для аудиозапросов.
Сразу несколько тяжёлых open-world моделей: Grounding DINO для детекции, Segment Anything для масок, плюс по желанию Stable Diffusion для inpainting, RAM или BLIP для автоматической разметки и Whisper для аудиозапросов.Сегментация полностью автоматическая или мне нужно писать промпт?Промпт нужен всегда: самому SAM требуются подсказки — рамки, точки или текст — чтобы строить маски; в этом пайплайне их за вас формирует Grounding DINO из вашего свободного текста.
Промпт нужен всегда: самому SAM требуются подсказки — рамки, точки или текст — чтобы строить маски; в этом пайплайне их за вас формирует Grounding DINO из вашего свободного текста.Что такое Grounding DINO?Zero-shot open-world детектор от IDEA-Research: вы даёте ему произвольный текст, а он возвращает качественные bounding box и метки для упомянутых в тексте объектов — без обучения на ваших классах.
Zero-shot open-world детектор от IDEA-Research: вы даёте ему произвольный текст, а он возвращает качественные bounding box и метки для упомянутых в тексте объектов — без обучения на ваших классах.Можно ли заменить модели в пайплайне?Да. Авторы представляют его как набор из экспертных моделей, где каждая часть может работать отдельно или в связке и быть заменена — например, GLIP вместо Grounding DINO или ControlNet и GLIGEN вместо Stable Diffusion.
Да. Авторы представляют его как набор из экспертных моделей, где каждая часть может работать отдельно или в связке и быть заменена — например, GLIP вместо Grounding DINO или ControlNet и GLIGEN вместо Stable Diffusion.Можно ли попробовать без установки чего-либо?Есть онлайн-демо RAM-Grounded-SAM на Replicate, а Grounding DINO и Grounded SAM поддерживаются на Hugging Face с официальной документацией.
Есть онлайн-демо RAM-Grounded-SAM на Replicate, а Grounding DINO и Grounded SAM поддерживаются на Hugging Face с официальной документацией.Что такое Grounded SAM 2?Более новая версия, где Grounding DINO работает в паре с SAM 2: к исходной схеме «детекция и сегментация по текстовому промпту» добавилось отслеживание любого объекта в open-world сценариях.
Более новая версия, где Grounding DINO работает в паре с SAM 2: к исходной схеме «детекция и сегментация по текстовому промпту» добавилось отслеживание любого объекта в open-world сценариях.What are similar projects?stable-diffusion-webui-colab, IOPaint, latent-diffusion, ControlNet, stable-diffusion-webui, InstantID, TaskMatrix, stable-diffusion
stable-diffusion-webui-colab, IOPaint, latent-diffusion, ControlNet, stable-diffusion-webui, InstantID, TaskMatrix, stable-diffusionWhich topics is it in?data-labeling, tracking, image-segmentation, inpainting, speech, foundation-models, stable-diffusion, gradio, whisper, image-editing, object-detection, diffusion-models
data-labeling, tracking, image-segmentation, inpainting, speech, foundation-models, stable-diffusion, gradio, whisper, image-editing, object-detection, diffusion-models