






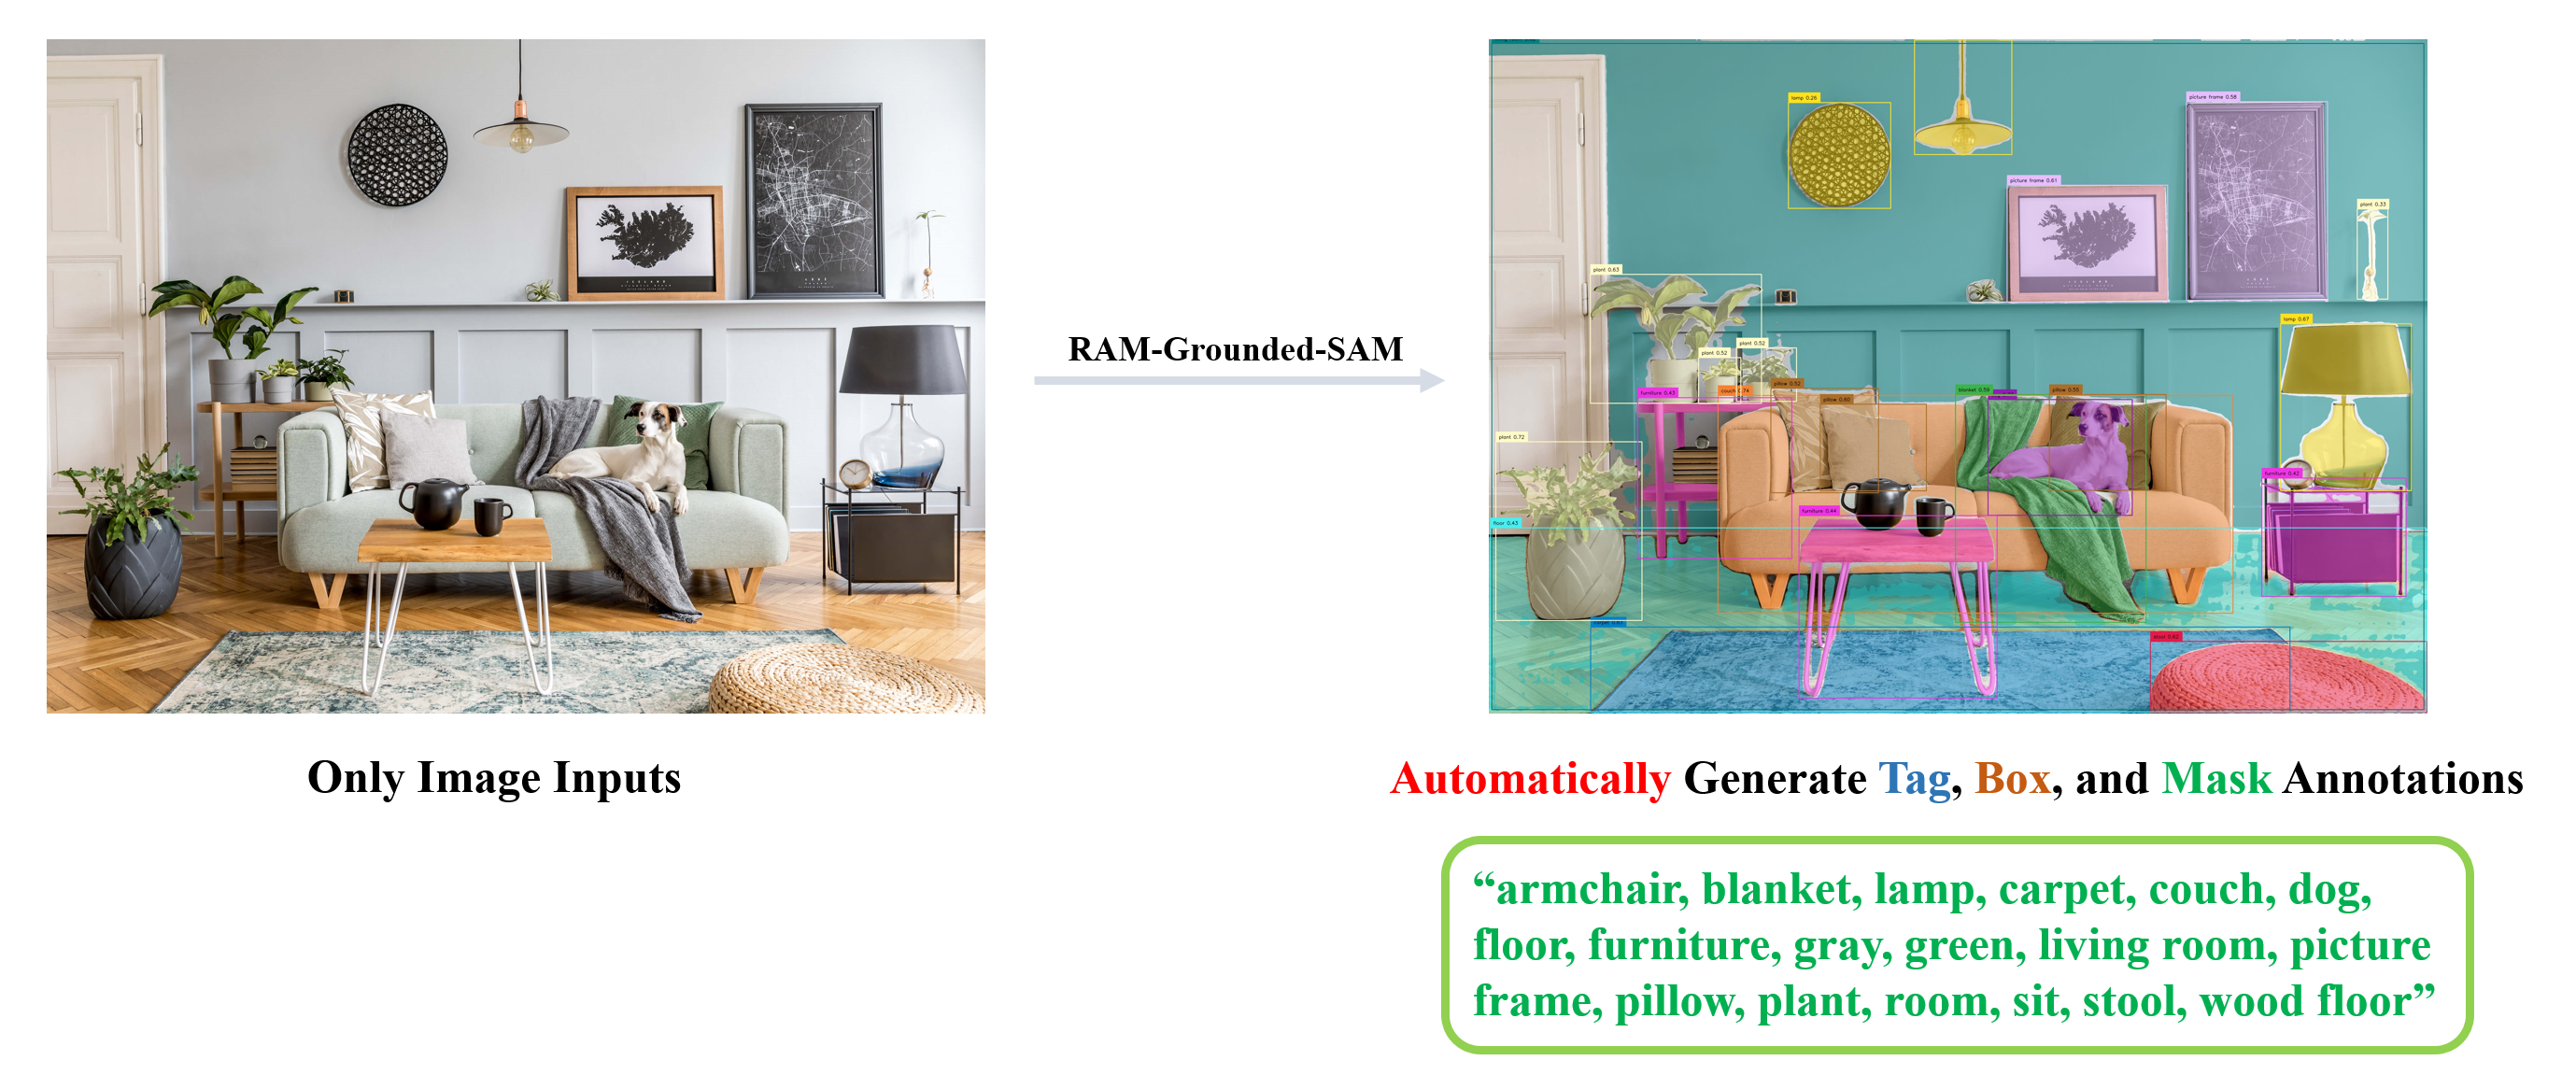




What is this?
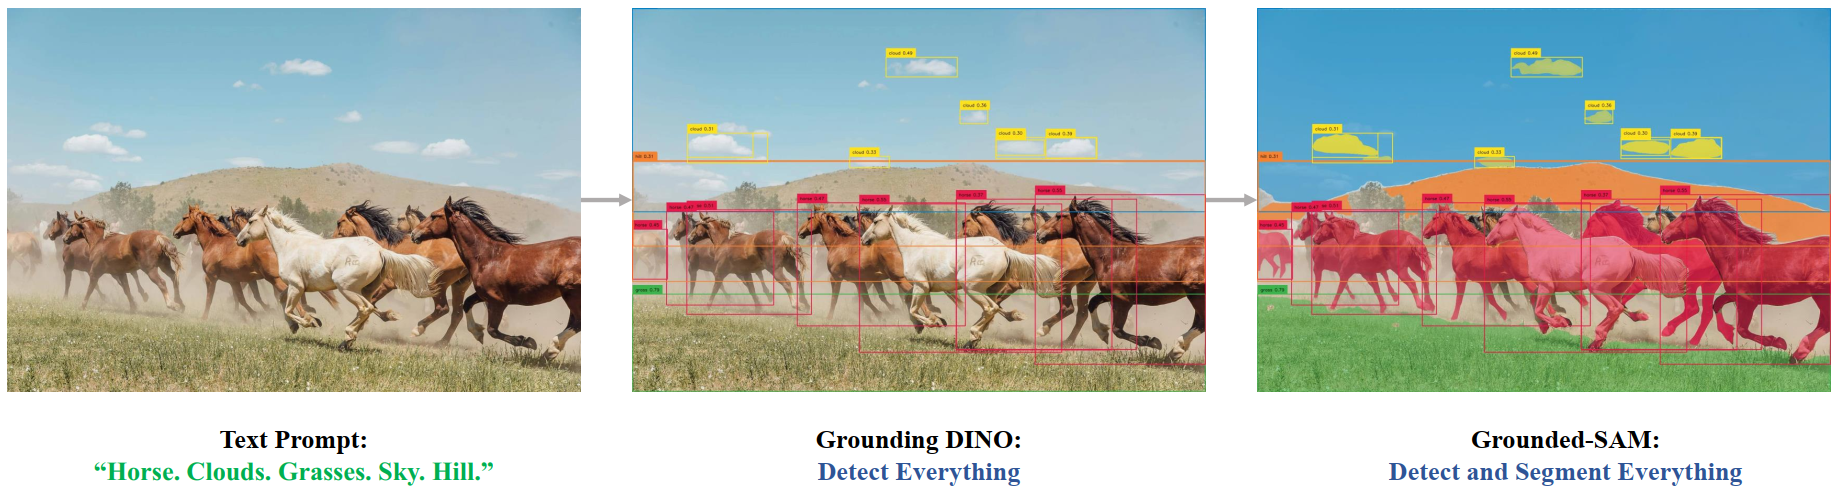
 Grounded SAM, a research demo project that combines Grounding DINO with Segment Anything to detect and segment any object in an image from a plain text prompt, extended with Stable Diffusion, RAM, Whisper and more.
Is it a library I can import, or a set of demos I run?It is a collection of runnable research demos rather than an installable package: step-by-step notebook demos, a Grounded-SAM playground, and Gradio apps, with a Docker install option.
It is a collection of runnable research demos rather than an installable package: step-by-step notebook demos, a Grounded-SAM playground, and Gradio apps, with a Docker install option.How do I get it running?Clone the repo and follow the Installation section of the README: either install with Docker or set up the local Python environment, then run the notebook demo or Gradio app you want.
Clone the repo and follow the Installation section of the README: either install with Docker or set up the local Python environment, then run the notebook demo or Gradio app you want.Which models am I actually running under the hood?Several heavyweight open-world models together: Grounding DINO for detection, Segment Anything for masks, plus optional Stable Diffusion for inpainting, RAM or BLIP for automatic labeling, and Whisper for audio prompts.
Several heavyweight open-world models together: Grounding DINO for detection, Segment Anything for masks, plus optional Stable Diffusion for inpainting, RAM or BLIP for automatic labeling, and Whisper for audio prompts.Is the segmentation fully automatic, or do I have to prompt it?You always prompt it: SAM itself needs prompts like boxes, points or text to produce masks — in this pipeline Grounding DINO supplies them from your free-form text.
You always prompt it: SAM itself needs prompts like boxes, points or text to produce masks — in this pipeline Grounding DINO supplies them from your free-form text.What is Grounding DINO?IDEA-Research's zero-shot open-world detector: you feed it free-form text and it returns high-quality bounding boxes and labels for the objects the text names, without training on your classes.
IDEA-Research's zero-shot open-world detector: you feed it free-form text and it returns high-quality bounding boxes and labels for the objects the text names, without training on your classes.Can I swap models in the pipeline?Yes. The authors frame it as a workflow of expert models where every part can run separately or in combination and be replaced — e.g. GLIP instead of Grounding DINO, or ControlNet and GLIGEN instead of Stable Diffusion.
Yes. The authors frame it as a workflow of expert models where every part can run separately or in combination and be replaced — e.g. GLIP instead of Grounding DINO, or ControlNet and GLIGEN instead of Stable Diffusion.Can I try it without installing anything?There is a RAM-Grounded-SAM online demo on Replicate, and both Grounding DINO and Grounded SAM are supported on Hugging Face with official documentation.
There is a RAM-Grounded-SAM online demo on Replicate, and both Grounding DINO and Grounded SAM are supported on Hugging Face with official documentation.What is Grounded SAM 2?The newer iteration that pairs Grounding DINO with SAM 2, adding tracking of any object in open-world scenarios on top of the original text-prompted detect-and-segment flow.
The newer iteration that pairs Grounding DINO with SAM 2, adding tracking of any object in open-world scenarios on top of the original text-prompted detect-and-segment flow.What are similar projects?stable-diffusion-webui-colab, IOPaint, latent-diffusion, ControlNet, stable-diffusion-webui, InstantID, TaskMatrix, stable-diffusion
stable-diffusion-webui-colab, IOPaint, latent-diffusion, ControlNet, stable-diffusion-webui, InstantID, TaskMatrix, stable-diffusionWhich topics is it in?data-labeling, tracking, image-segmentation, inpainting, speech, foundation-models, stable-diffusion, gradio, whisper, image-editing, object-detection, diffusion-models
data-labeling, tracking, image-segmentation, inpainting, speech, foundation-models, stable-diffusion, gradio, whisper, image-editing, object-detection, diffusion-models