这是什么?
 FreeToken 是一个面向边缘设备的混合专家(MoE)推理服务引擎,用于在游戏电脑等消费级硬件上运行前沿规模的开放权重模型,包括参数量达 290B+ 的模型。
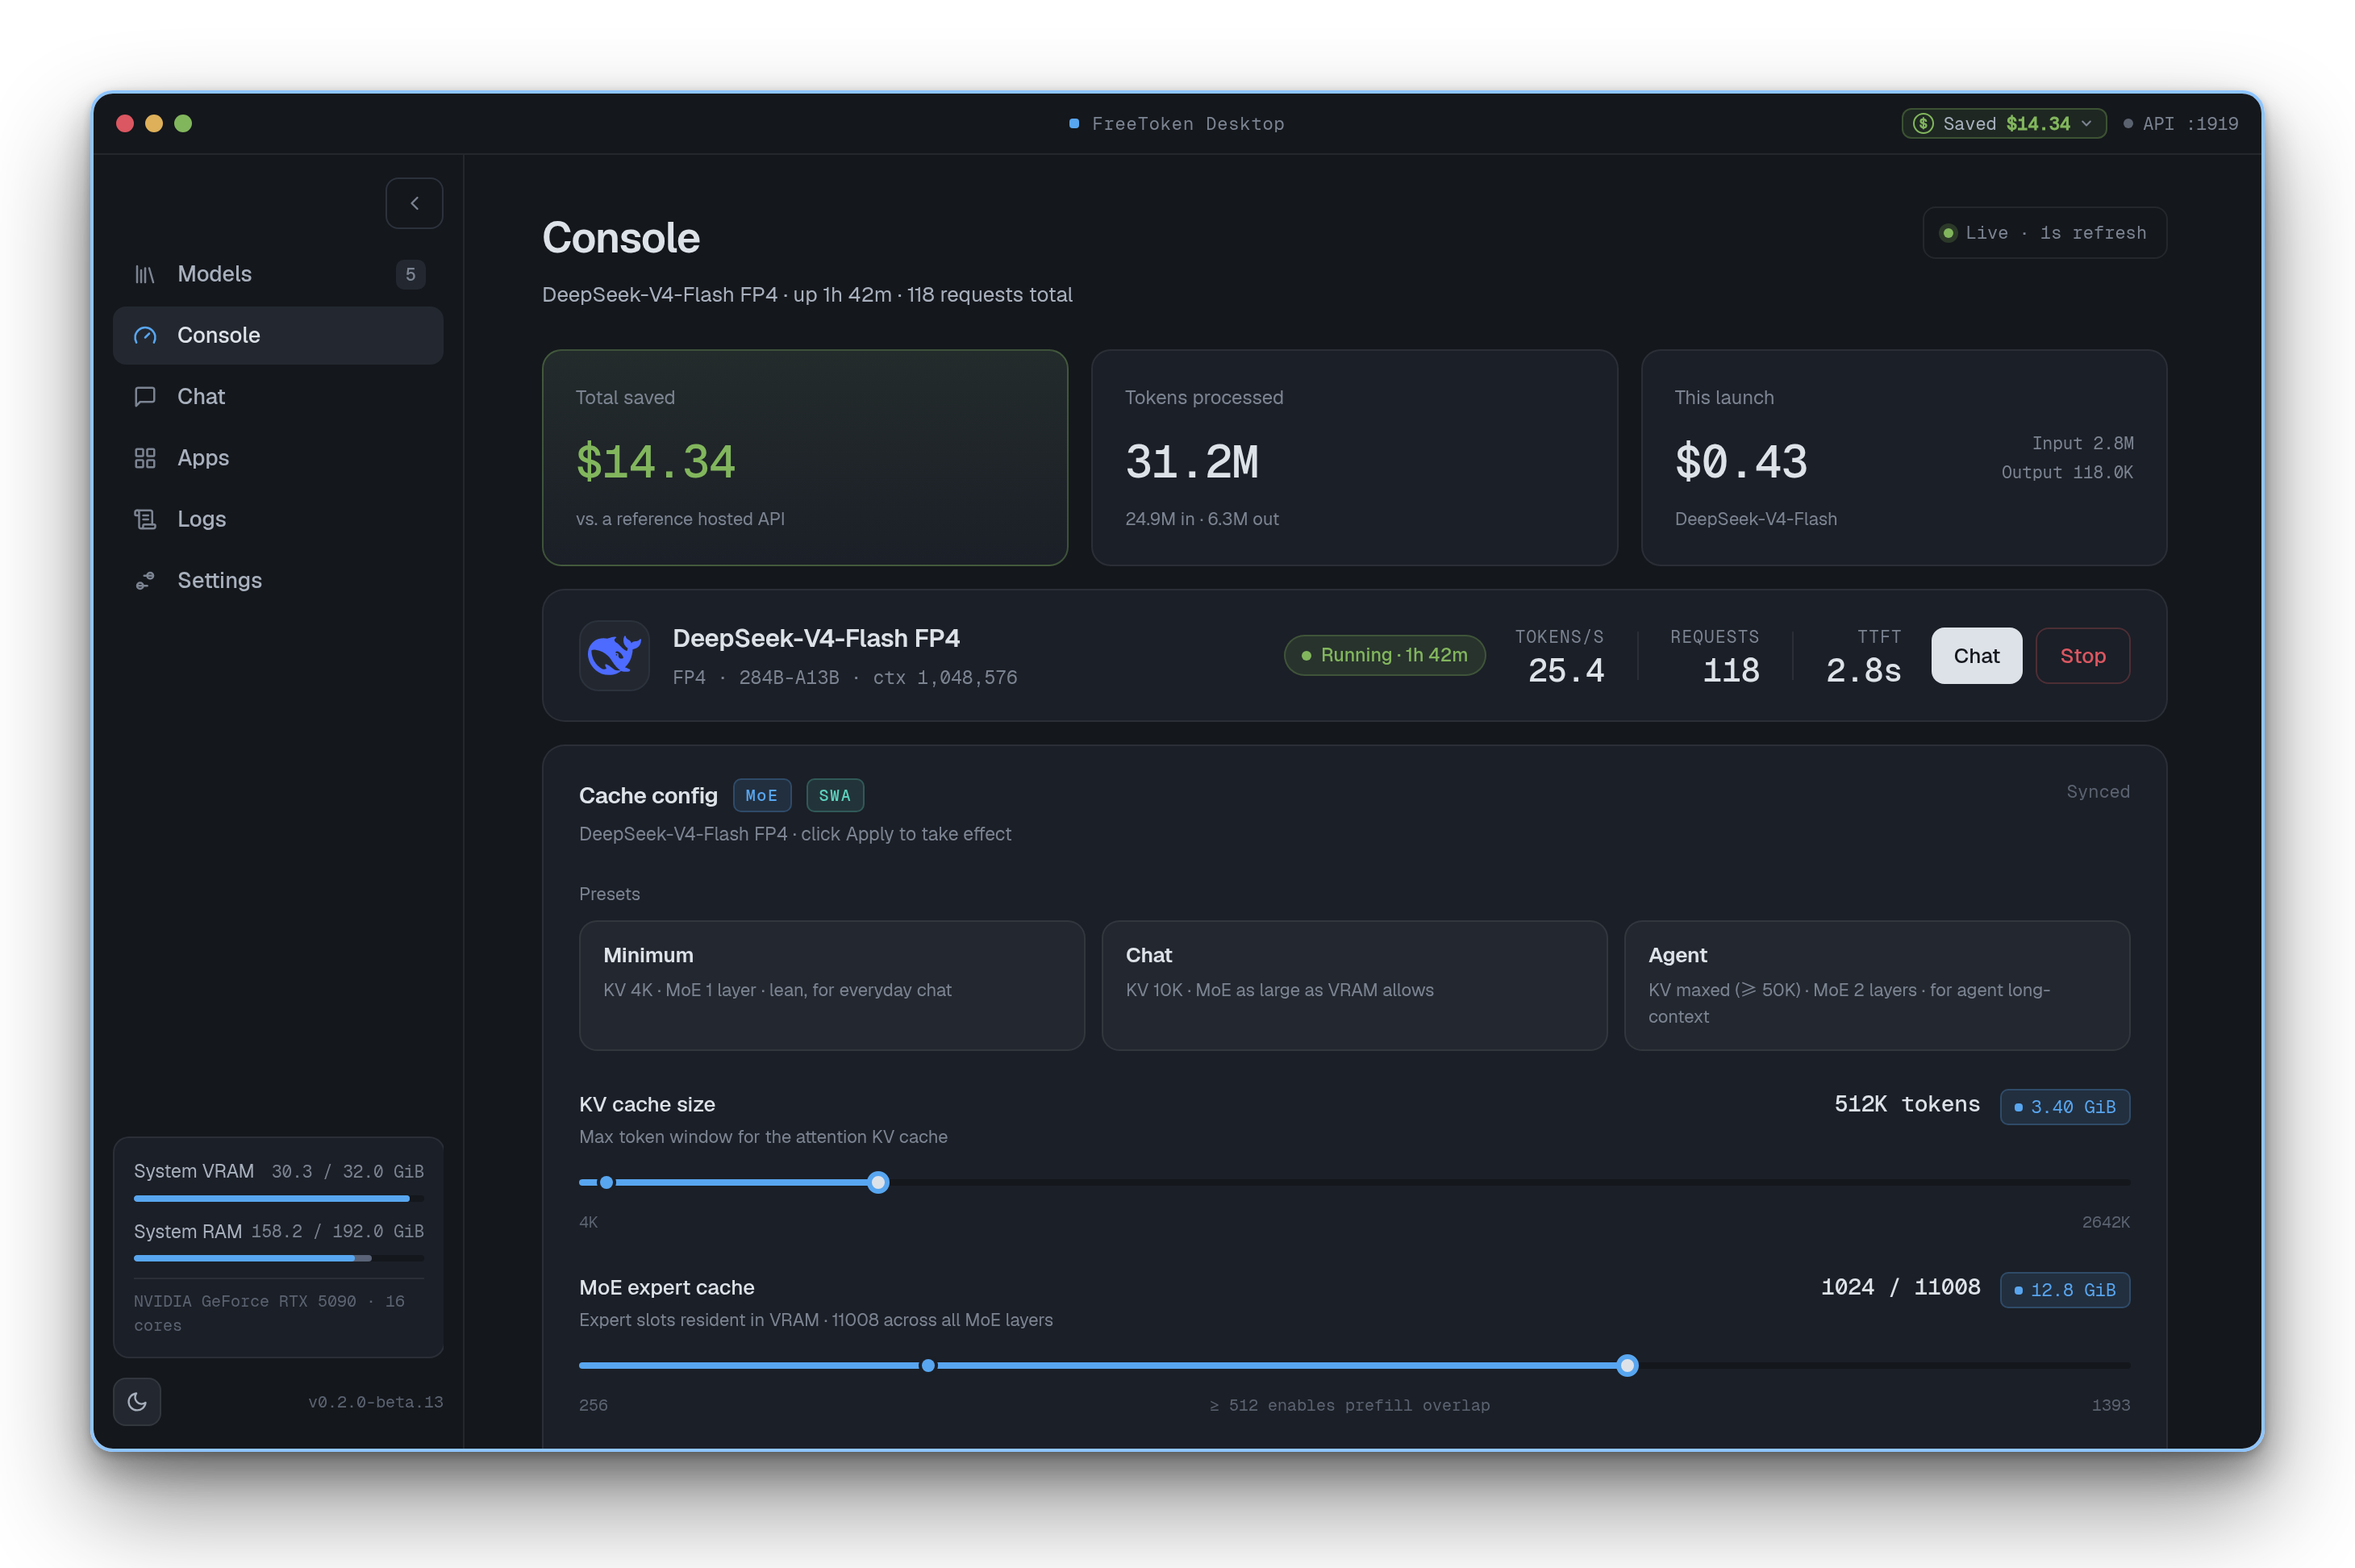
这是桌面应用还是命令行工具?两者都有:Windows 和 Linux 上有带图形界面的桌面应用,可以自动帮你配置好引擎;另外也可以单独安装命令行工具,获得更多控制。
两者都有:Windows 和 Linux 上有带图形界面的桌面应用,可以自动帮你配置好引擎;另外也可以单独安装命令行工具,获得更多控制。我该怎么让它运行起来?可以从 flashml.ai 下载 Windows 或 Linux 桌面应用,也可以用 `uv`(推荐)或 pip 安装命令行工具,或者从源码编译。
可以从 flashml.ai 下载 Windows 或 Linux 桌面应用,也可以用 `uv`(推荐)或 pip 安装命令行工具,或者从源码编译。安装这个需要 Python 吗?需要。命令行工具基于 Python,通过 `uv` 或 pip 安装;桌面应用则会替你完成引擎的配置。
需要。命令行工具基于 Python,通过 `uv` 或 pip 安装;桌面应用则会替你完成引擎的配置。在游戏电脑上运行 290B+ 模型有什么局限?无法把整个模型装进显存,而是采用随带宽自适应的 CPU-GPU 协同计算、预填充流式传输和 LRU 专家缓存。实际速度取决于你系统的 CPU-GPU 带宽,并且仅支持受支持的 RTX 显卡系列。
无法把整个模型装进显存,而是采用随带宽自适应的 CPU-GPU 协同计算、预填充流式传输和 LRU 专家缓存。实际速度取决于你系统的 CPU-GPU 带宽,并且仅支持受支持的 RTX 显卡系列。这个桌面应用支持哪些操作系统?桌面应用支持 Windows 和 Linux,没有提及 macOS 版本。
桌面应用支持 Windows 和 Linux,没有提及 macOS 版本。需要 NVIDIA 显卡吗?需要。原生支持面向 NVIDIA RTX 30、RTX 40 和 RTX 50 系列显卡,并结合 CPU 和主机内存来卸载专家模块。
需要。原生支持面向 NVIDIA RTX 30、RTX 40 和 RTX 50 系列显卡,并结合 CPU 和主机内存来卸载专家模块。FreeToken 支持哪些模型?它支持前沿的开放权重 MoE 模型,例如 DeepSeek-V4-Flash、Qwen3.6-35B-A3B 和 GLM-5.2,并支持 MXFP4、NVFP4、FP8 和 BF16 等量化格式。
它支持前沿的开放权重 MoE 模型,例如 DeepSeek-V4-Flash、Qwen3.6-35B-A3B 和 GLM-5.2,并支持 MXFP4、NVFP4、FP8 和 BF16 等量化格式。我能把 FreeToken 和 Claude Code 或 Codex 这类编程智能体一起用吗?可以。它提供与 Anthropic/OpenAI 兼容的 API,因此可以接入 Codex、Claude Code、OpenCode、OpenClaw 和 DeepSeek Harness 等编程及工具调用智能体。
可以。它提供与 Anthropic/OpenAI 兼容的 API,因此可以接入 Codex、Claude Code、OpenCode、OpenClaw 和 DeepSeek Harness 等编程及工具调用智能体。功能介绍里提到的 FTW 格式是什么?FTW 是 FreeToken 自有的快速权重格式,是其边缘原生运行时的一部分,专为高效加载和服务 MoE 模型而设计。
FTW 是 FreeToken 自有的快速权重格式,是其边缘原生运行时的一部分,专为高效加载和服务 MoE 模型而设计。FreeToken 的设计受到了什么启发?它深受 mini-sglang 启发,并复用了 SGLang、vLLM、FlashInfer、flash-linear-attention、LightLLM 和 llama.cpp 的设计与代码。
它深受 mini-sglang 启发,并复用了 SGLang、vLLM、FlashInfer、flash-linear-attention、LightLLM 和 llama.cpp 的设计与代码。What are similar projects?sglang, project-maya, TypeLLM, Strata, v100-skinny, vllm, airllm, jeeves
sglang, project-maya, TypeLLM, Strata, v100-skinny, vllm, airllm, jeevesWhich topics is it in?edge, minimax, glm, edge-ai, inference-engine, model-serving, moe, llm-inference, qwen, quantization, transformer, local-llm
edge, minimax, glm, edge-ai, inference-engine, model-serving, moe, llm-inference, qwen, quantization, transformer, local-llm