
DreamX-Creator README

The project's README from github.com/AMAP-ML/DreamX-Creator. As one markdown file: README.md.

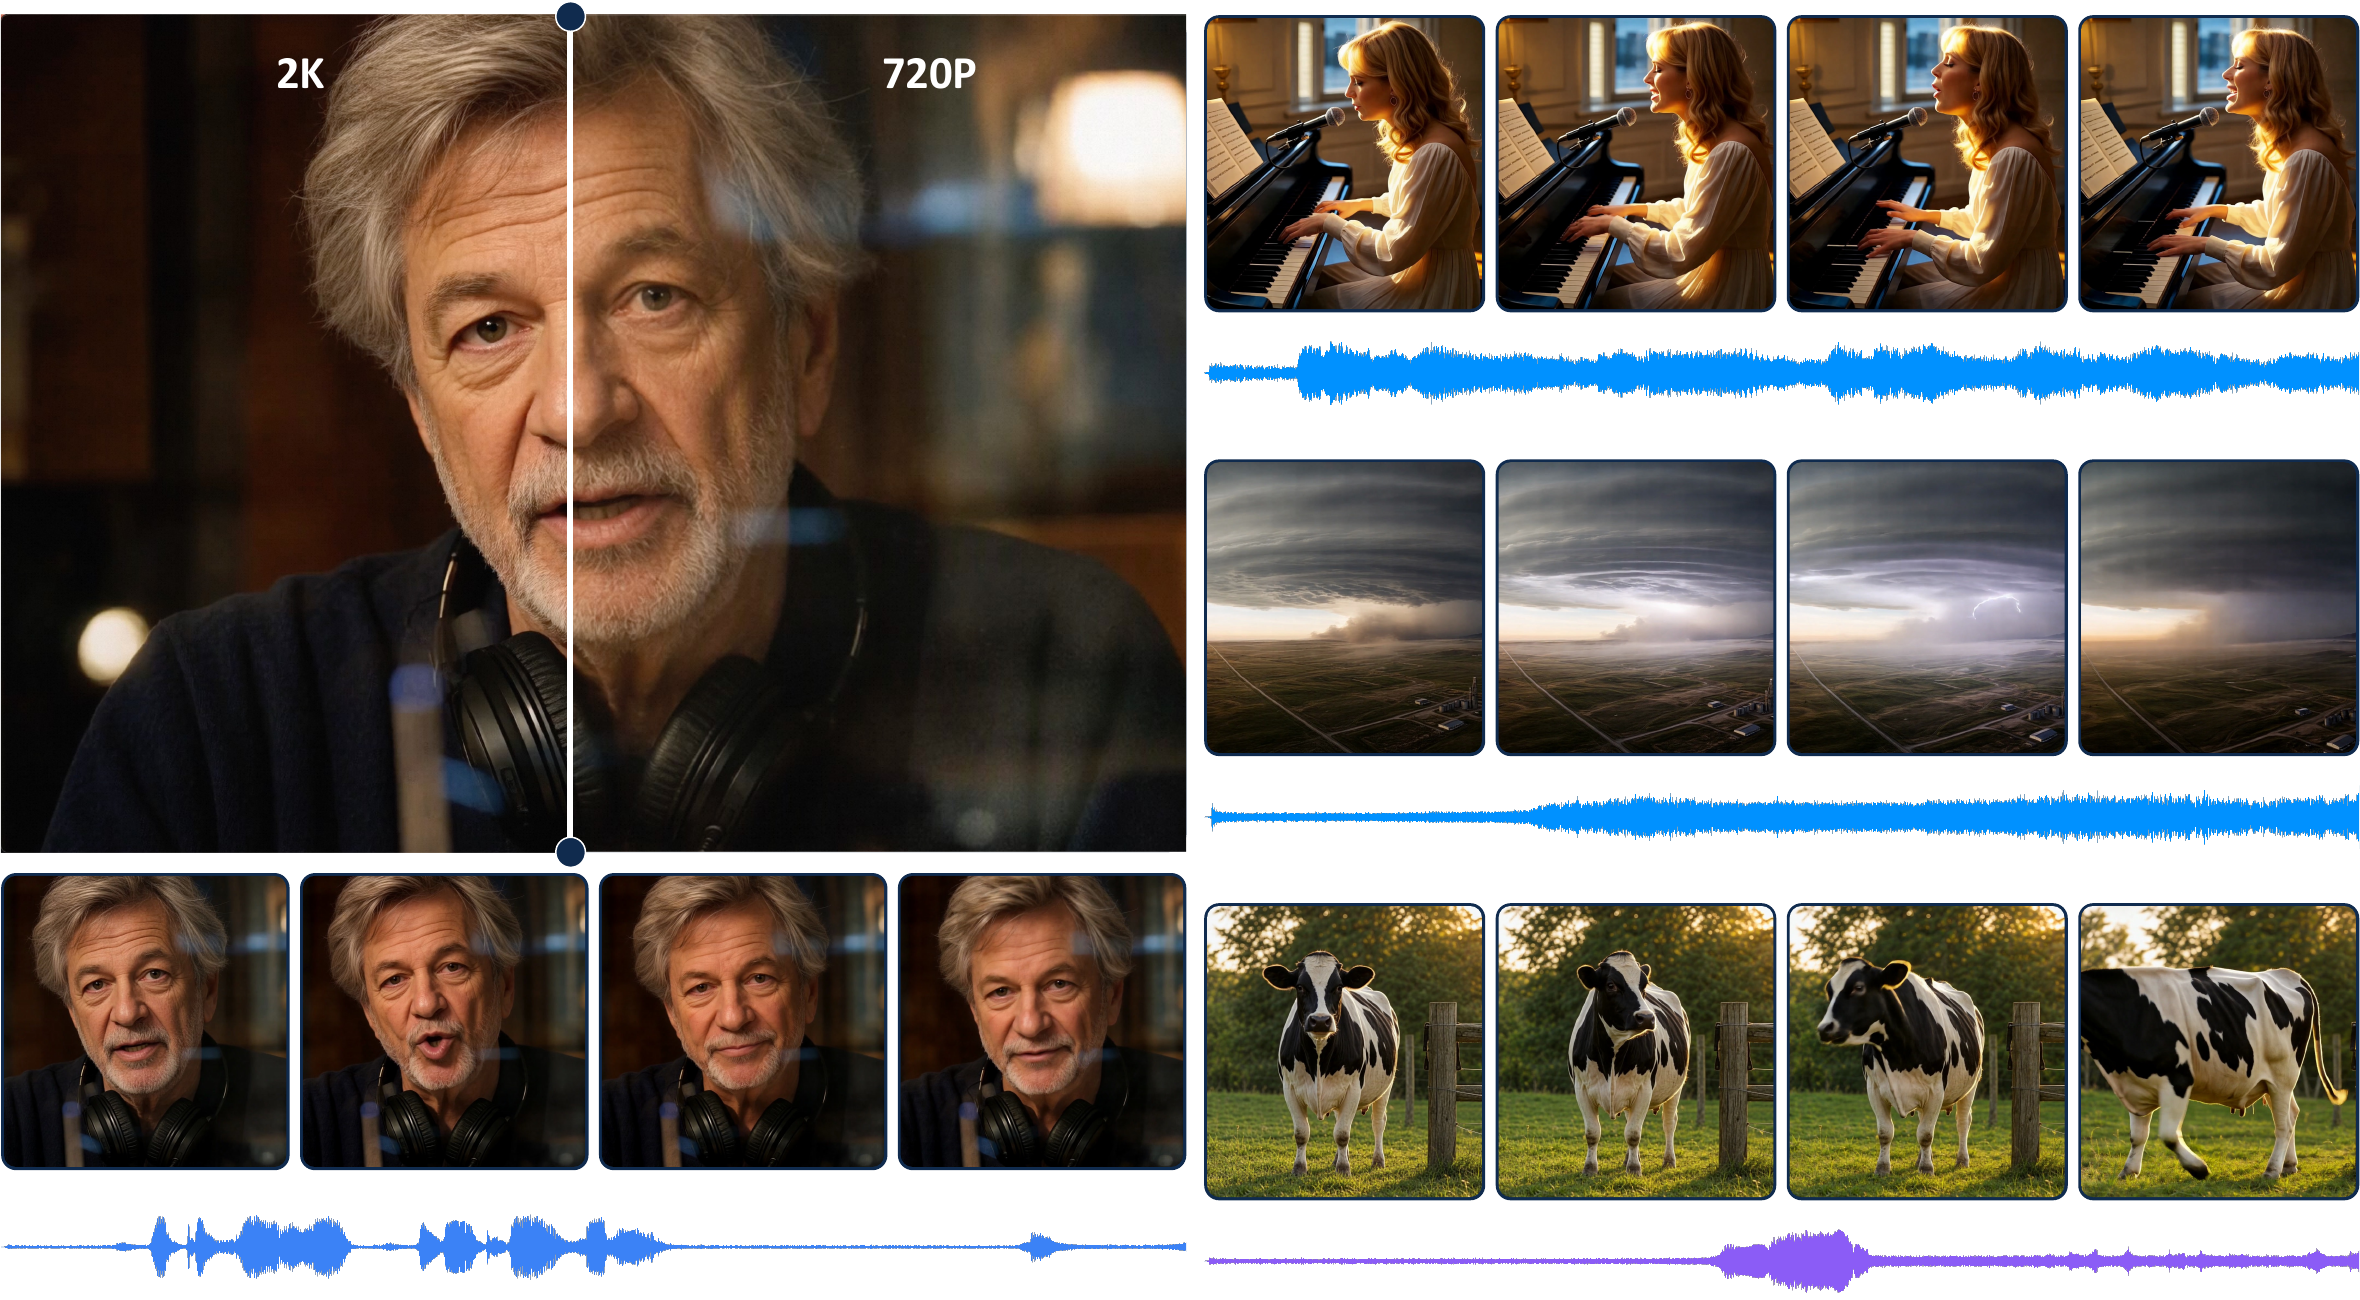
DreamX-Creator teaser

DreamX-Creator 1.0: Democratizing Native Audio-Video Generation at 2K Resolution

DreamX Team

arXiv HuggingFace ModelScope License


DreamX-Creator 1.0 is a research framework for native joint audio-video generation. Given a first frame and a text prompt, its implemented base generator jointly models modality-specialized video and audio streams, using Gated Cross-Modal Attention and Progressive Joint Training to enable bidirectional audio-video interaction.

The broader system combines Audio-Video Reinforcement Learning with Modality-Aware Multimodal Feedback to improve visual and audio quality, semantic consistency, and fine-grained audio-video synchronization. Autoregressive 1-Step 2K Refinement then upgrades the generated video to high-quality 2K output while preserving content, motion, and audio-aligned timing.

:clapper: Demo

:fire: News

:calendar: Plan

:open_file_folder: Repository Structure

:package: Model Weights

Model weights are distributed on HuggingFace and ModelScope and should be placed under checkpoints/ (details in checkpoints/README.md):

checkpoints/
├── creator/                     # DreamX-Creator 1.0 joint generator (7B, LoRA merged)
│   ├── video_model/             # video DiT shards + config
│   ├── audio_model/             # audio DiT + config
│   └── cross_attn_weights.safetensors  # gated A2V/V2A cross-modal attention
├── audio_vae/                   # CreatorDACVAE audio VAE
├── refiner/                     # 2K refiner
│   ├── sr_dit_5b.pt             # SR-DiT 5B refiner
│   ├── latent_upsampler_flash.pt       # FlashLatentUpsampler (default)
│   ├── latent_upsampler_2d_causal.pt   # causal 2D latent upsampler (optional)
│   └── lightvae_nu_scheme3.pt          # distilled fast decoder (optional, off by default)
└── wan2.2_ti2v_5b/              # shared Wan2.2-TI2V-5B dependencies
    ├── Wan2.2_VAE.pth           # video VAE
    ├── models_t5_umt5-xxl-enc-bf16.pth  # UMT5-xxl text encoder
    └── google/umt5-xxl/         # tokenizer

The wan2.2_ti2v_5b/ directory can also be downloaded directly from Wan-AI/Wan2.2-TI2V-5B; only the three entries above are needed.

:rocket: Quickstart

Each subdirectory is self-contained with its own requirements.txt and README.

1. Joint audio-video generation (first frame + prompt to synchronized video with audio):

cd audio_video_generation
pip install -r requirements.txt
./inference.sh                        # runs the default Verse-Bench case (case1)

See audio_video_generation/README.md for input overrides, CPU-offload options, output details, and multi-GPU sequence-parallel inference.

2. 2K refinement (super-resolve a generated or external video, audio unchanged):

cd ../video_refiner
pip install -r requirements.txt
INPUT=/path/to/video.mp4 bash run_inference.sh

See video_refiner/README.md for the full list of knobs (KV cache, window attention, speed/quality trade-offs).

:books: Citation

If you find DreamX-Creator useful in your research, please consider citing our technical report:

@misc{zhu2026dreamxcreatordemocratizingnativeaudiovideo,
  title={DreamX-Creator: Democratizing Native Audio-Video Generation at 2K Resolution},
  author={Jiashu Zhu and Yanhao Zheng and Ruitian Tian and Rujing Dang and Shen Zhang and Bingze Song and Jiachen Lei and Ruimin Lin and Jiahong Wu and Xiangxiang Chu},
  year={2026},
  eprint={2608.31106},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2608.31106},
}

:scroll: License

This project is licensed under the Apache License 2.0. See LICENSE for details.

:sparkles: Acknowledgement

We would like to thank the Wan Team, the OpenMOSS Team, and the VideoX-Fun Team for their outstanding open-source work on Wan, MOVA, and VideoX-Fun, respectively.

DreamX-Creator (AMAP-ML/DreamX-Creator)

Searching Database…

这是做什么的?DreamX-Creator 是一个开源研究框架,用于原生的音视频联合生成:它同时生成画面和与之同步的音频,经过精修后最高可达 2K 分辨率。
输入什么,输出什么?你提供一张首帧图加上一段文字描述;7B 生成器会生成带配套音频的视频,然后 SR-DiT 5B 精修器再把它提升到高质量的 2K 画质。
怎么把它跑起来?每个组件(audiovideogeneration/、videorefiner/)都是一个独立的文件夹,各自带有 requirements.txt 和 README:先装好对应环境,把权重下载到 checkpoints/,再运行它的推理脚本即可。
我需要哪些模型权重,从哪里下载?从 HuggingFace 或 ModelScope 获取:DreamX 7B 音视频生成器、SR-DiT 5B 精修器,以及 Wan-AI/Wan2.2-TI2V-5B —— 全部按照其 README 的说明放到 checkpoints/ 目录下。
技术报告里描述的东西都真的能用吗?目前只有推理部分:已发布的权重和代码覆盖 7B 生成器和单步 2K 精修器,而采样步数更少的蒸馏加速模型仍属于尚未落地的路线图内容。
我可以随便用吗,包括商业用途?可以 —— Apache 2.0 允许你使用、修改和再分发它,包括用于商业项目,只要保留许可声明即可。
普通电脑能跑吗,还是必须有很强的显卡?7B 生成器本身就是按单卡运行设计的,并为显存紧张的配置提供了 CPU offload 和内存相关选项,还可选多卡序列并行推理来加快生成速度。
它是怎么让音频和画面保持同步的?生成器采用带渐进式联合训练的门控跨模态注意力(Gated Cross-Modal Attention)实现音频与视频的双向交互,整个流程还加入了带模态感知的多模态反馈的音视频强化学习,来提升同步性、一致性和生成质量。
为什么必须给一张首帧图,而不是只给一段文字?已发布的基础生成器是以图片为条件的:首帧图确定场景,文字描述则驱动画面运动和声音。README 中没有提到只靠文字描述的纯提示模式。
它是基于其他开源项目做的吗?是的 —— 团队致谢了 Wan、OpenMOSS 和 VideoX-Fun 团队,并复用了 Wan2.2-TI2V-5B 的权重;此外还有一份技术报告,如果这个框架对你的研究有帮助,可以引用它。
Creator
AMAP-ML
Size
3.6 MB
Stars
312
Updated
CommitSep 03
Age
1mo
Commits · 90 Days