KISS — Knowledge Infrastructure for Scientific Simulation
An agent-actionable scaffold that externalizes operational expertise so AI agents can reliably run, check, and extend process-based scientific models.

Explore the live catalogue · Build KI with KDT · Read the paper
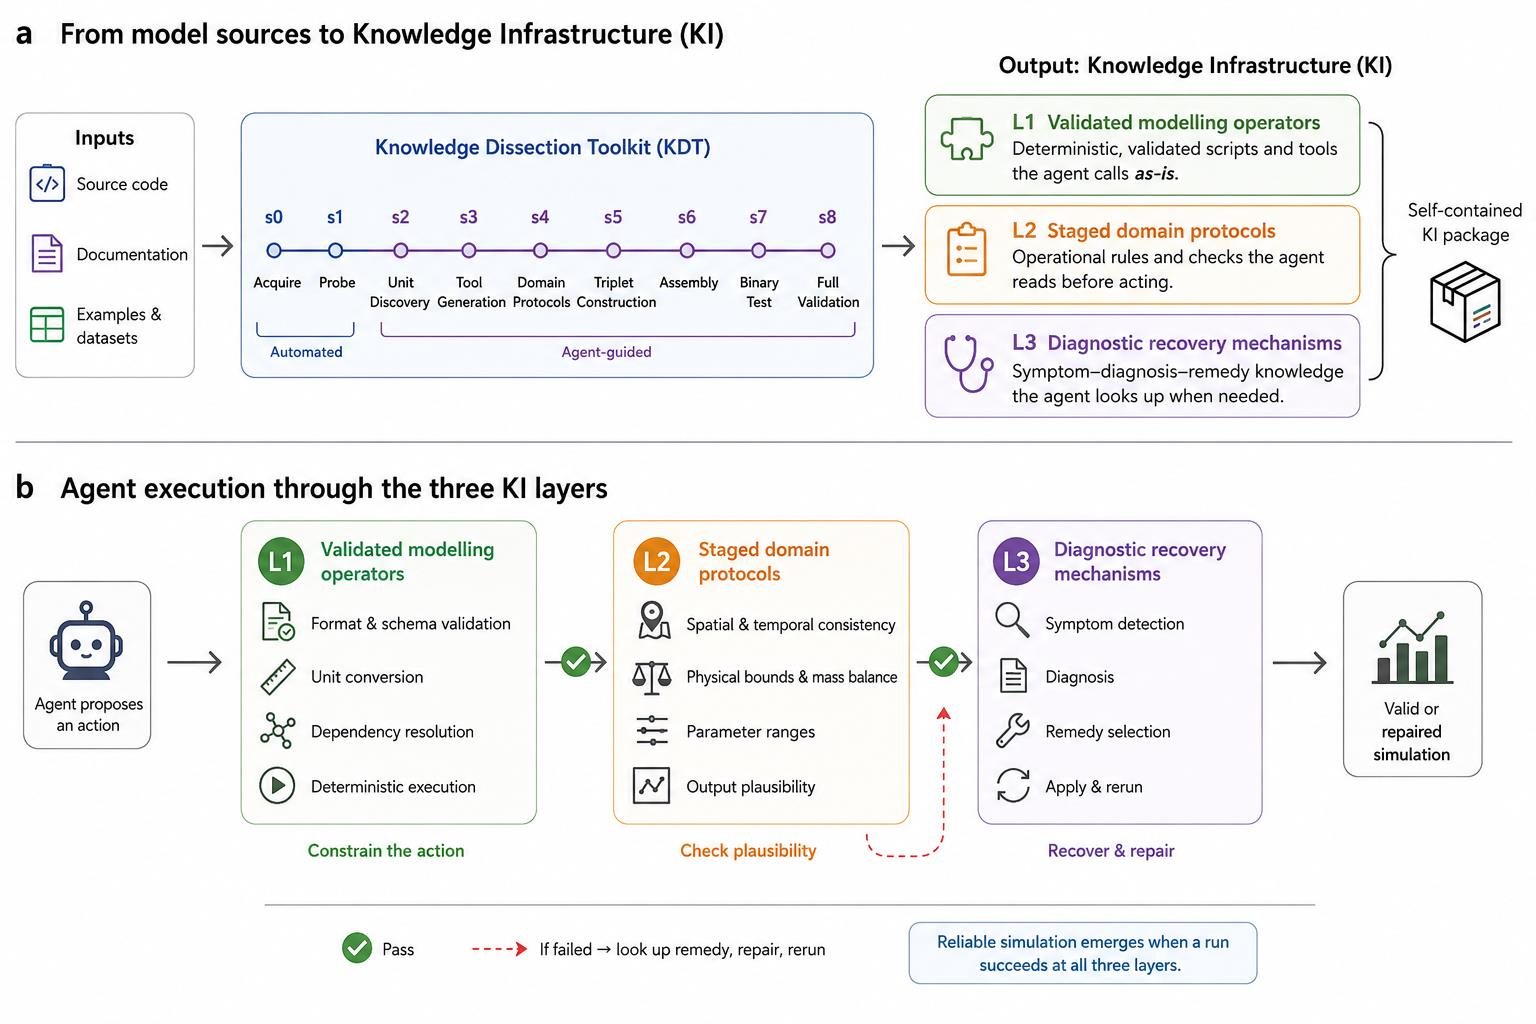
Knowledge dissection converts operational expertise into agent-usable Knowledge Infrastructure. Figure 2 from the KISS manuscript.
What is Knowledge Infrastructure?
Running a scientific model requires more than knowing its equations. Practitioners also know how to prepare model-specific inputs, how to decide whether each intermediate state is scientifically plausible, and how to recover when a run fails silently or indirectly. That operational expertise is often scattered across source code, documentation, example cases, and specialist practice.
Knowledge Infrastructure (KI) makes that expertise explicit and usable by a general-purpose coding agent. It separates operational knowledge into three complementary forms:
| Knowledge type |
The question it answers |
Representation in KI |
Role during execution |
| Procedural |
How should this operation be performed? |
Validated modelling operators |
Constrain actions through deterministic tools for format conversion, unit handling, dependency resolution, and execution |
| Evaluative |
Is the workflow still correct and scientifically plausible? |
Staged domain protocols |
Gate progress using spatial and temporal consistency, physical bounds, mass balance, parameter ranges, and output checks |
| Diagnostic |
Why did the run fail, and how should it recover? |
Diagnostic recovery mechanisms |
Map symptoms to diagnoses and validated remedies, then repair and rerun |
Reliable simulation emerges when an execution path satisfies all three constraints. Without procedural knowledge, agents perform invalid operations. Without evaluative knowledge, erroneous states propagate. Without diagnostic knowledge, agents cannot recover from silent or indirect failures.
From tacit expertise to an executable scaffold
The Knowledge Dissection Toolkit (KDT) extracts operational expertise from model source code, documentation, examples, datasets, and expert practice. It packages that expertise as a self-contained KI that an agent can:
- read to understand the model, its dependencies, and its operational sequence;
- call to execute validated, model-specific operations; and
- query to check intermediate results or recover from failures.
KISS leaves the governing equations untouched. The agent operates the original process-based model; KI changes the operational interface around it.
Model sources ── knowledge dissection ──► KI package ── agent execution ──► valid or repaired simulation
                                               │
                         ┌─────────────────────┼─────────────────────┐
                         │                     │                     │
                    Procedural            Evaluative            Diagnostic
                  constrain action      check plausibility      recover & repair
What this resource provides
The paper introduces four connected resources:
- The KI design — a three-layer scaffold for procedural, evaluative, and diagnostic knowledge.
- KDT — a knowledge-dissection toolkit for building KI packages for new models.
- An agent-driven simulation benchmark — a depth test of KI on a coupled VIC–Lohmann hydrological workflow.
- A public catalogue — 119 evaluated KI packages spanning 14 Earth-science domains, operated through a common interface.
This repository contains the model-level knowledge artifacts. The frozen cohort reported in the manuscript comprises:
| Construction mode |
KI packages |
Validation depth |
| Hand-built depth test |
2 |
VIC and Lohmann routing; evaluated in the 3,000-trial benchmark |
| Expert-supervised KDT transfer set |
25 |
Three sites per model and three independent agent sessions per site |
| Fully autonomous KDT scaling set |
92 |
59 observation-validated; 33 verified runnable on synthetic, example, or analytical inputs |
| Total evaluated in the paper |
119 |
14 Earth-science domains |
The repository may evolve beyond the frozen manuscript cohort. All study-scale numbers in this README refer to the 119-package evaluation reported in the paper.
What a KI package contains
Package layouts vary with the underlying model, but the artifacts serve the same three knowledge layers:
models/<MODEL>/
├── SKILL.md or SKILL_en.md          # operational entry point and staged guidance
├── tools/ and stage scripts         # validated modelling operators
├── dag.yaml                         # execution order, dependencies, and gates
├── knowledge_infrastructure.yaml    # machine-readable KI manifest
├── docs/
│   ├── format_spec.yaml             # input/output schemas and units
│   ├── validation_convention.yaml   # domain-appropriate acceptance rules, where available
│   └── REFERENCES.md                # provenance for operational claims
├── diagnostics/
│   └── triplets.yaml or triplets.md # symptom → diagnosis → remedy knowledge
└── preflight_check.py               # pre-execution consistency checks
| KI layer |
Typical repository artifacts |
| Validated modelling operators |
tools/*.py, preparation stages, run and scoring scripts |
| Staged domain protocols |
SKILL.md, dag.yaml, format_spec.yaml, validation conventions, preflight checks |
| Diagnostic recovery mechanisms |
diagnostics/triplets.yaml, error logs, symptom–diagnosis–remedy records |
Evidence from the paper
Depth: KI enables reliable agentic simulation
The depth benchmark tested a coupled VIC–Lohmann workflow with 14 milestones. Ten command-line coding agents from five independent platforms attempted the workflow across three Huai River basins in 3,000 independent trials.
- KI-equipped agents completed valid end-to-end simulations in up to 84% of trials.
- With KI removed, no agent exceeded 40% completion.
- A successful trial had to complete all 14 milestones and produce discharge with Nash–Sutcliffe efficiency ≥ 0.2.
- The ablation failures mapped directly to the missing layers: invalid operations without validated operators, implausible results without staged protocols, and unresolved error loops without diagnostic recovery.
Scale: KI construction transfers across models and domains
- KDT produced KI for 117 additional models, bringing the total evaluation to 119 models across 14 domains.
- In the 25-package expert-supervised set, 60 of 75 model–site combinations (80.0%) met domain-specific quantitative criteria; no execution failures occurred.
- The autonomous set contained 92 packages: 59 validated against observational data and 33 verified runnable using synthetic, example, or analytical inputs.
Structure: operational expertise converges
The cross-domain corpus supports the paper's central premise that operational expertise is structured and extractable rather than ad hoc:
- 835 tools were classified across seven conserved functional categories plus an
OTHER residual.
- Across 2,406 diagnostic recovery mechanisms, unit-conversion and input/output-format errors accounted for 55% of anticipated failures and appeared in every domain.
- Domain failure profiles were similar, with median pairwise Spearman's ρ = 0.75.
- 3,478 decision points clustered into 11 categories. Parameter selection, physics-option configuration, and unit-system specification appeared in every domain and accounted for 55% of all decisions.
Installation
Three ways in, depending on what you want to do.
1. The desktop application — no Python required
GeoForge Desktop runs these packages with an agent on your own machine. Download
it from releases: everything travels inside the download,
including all the model packages.
The manual walks one model from project creation to calibration, in
English,
简体中文 or
bilingual.
2. The library and harness — to drive a KI from your own code
For pointing your own agent at a package. Python 3.8 or newer; the clone is
about 145 MB.
git clone https://github.com/lzwei196/KISS---Knowledge-Infrastructure-for-Scientific-Simulation.git
cd KISS---Knowledge-Infrastructure-for-Scientific-Simulation

pip install -e ki_tools_common/     # the shared library, and the KI harness

# the interpreter the harness runs a package's operators and preflight with
export HC_PROJECT_PYTHON="$(which python)"
Set HC_PROJECT_PYTHON before importing, not after — the harness reads it once
at import time. Left unset, tool_command() emits an unresolved placeholder
and run_preflight() raises FileNotFoundError trying to execute it.
Or nothing at all. The harness imports only the standard library — the
numpy requirement comes from the rest of the shared library, which the
harness does not use. To skip the install, load the module directly:
import sys; sys.path.insert(0, "ki_tools_common/ki_tools_common/harness")
import ki_harness
Everything below works the same way; read ki_harness.contract for
harness.contract.
3. The command line — to inspect and install packages
Python 3.11 or newer.
pip install -e kiss/

kiss list                # the 127 packages
kiss info SWAT_Plus      # what one model needs
kiss papers WRF_Hydro    # the literature behind it
kiss verify              # what actually runs on this machine
Installing kiss/ does not give you the harness; the two are separate
installs. Run both lines if you want both.
Usage — driving a KI with an agent
from pathlib import Path
from ki_tools_common import harness

contract = harness.contract(Path("models/VIC").resolve(), execute=True)
Put contract in the agent's system prompt. That is the integration — the
same call works for every package in models/, and the agent receives the
model's staged protocol, its operators as absolute commands, its diagnostic
knowledge, and the obligations that govern how it may report a result.
Model binaries and large forcing or observational datasets are not bundled
uniformly with every package. harness.run_preflight(ki) reports what is
missing before a run rather than during one — it executes the package's own
preflight script with HC_PROJECT_PYTHON, so set that first.
Reading a package by hand
The same knowledge is plain files, if you would rather look first:
ls models/                                  # the available packages
sed -n '1,160p' models/VIC/SKILL_en.md      # the operational entry point
find models/VIC -maxdepth 2 -type f | sort  # operators, protocols, diagnostics
Driving a KI with your own agent — the KI harness
contract() is the whole entry point, shown above. The rest of this section
is what it puts in front of the agent, and the calls that surround it.
Why a shared contract
The instructions for using a KI were originally written twice — once in an
interactive application, once in an automated improvement loop — and the two
drifted. One kept its rules in a branch table, where 29 of them sat in a branch
that most runs never reached, and its per-package review gate covered 3 of 458
packages. The other embedded a single block that could not be partially
applied.
The design follows from that: a rule placed at a junction is skipped by
whoever takes the other road, so the harness is a single function every caller
passes through, with no branch on which caller is asking.
The obligations it carries
contract() renders a package's operational documentation as ten obligations,
held as a registry in ki_harness.py rather than as prose, so a parity test
fails if any driver stops emitting one:
|
|
| Run the real model |
no toy substitute, no literature value reported as a result |
| Follow the protocol in order |
the staged protocol is a sequence, not a menu |
| Absolute tool paths |
run operators with the project interpreter — do not search, do not disk-glob |
| Know the outputs |
establish what the model produces before running it |
| Units from the files |
read them from each file's own attributes, never from documentation |
| Preflight first |
check the environment, and obey the result |
| Failure ladder |
diagnostic triplets, then documentation, then reasoning — in that order |
| Never weaken |
do not relax a tool or a gate to obtain a pass |
| Not your own judge |
verdicts belong to the caller, not the agent under test |
| Evidence series |
write the simulated series to CSV so the result is reproducible |
The rest of the interface
ki = Path("models/MODFLOW6").resolve()

m = harness.manifest(ki)          # what this package actually ships
m["artifacts"]                    # {'SKILL.md': True, 'dag.yaml': True, ...}
m["missing"]                      # [] — stated up front, not discovered mid-run
m["tools"]                        # 30 operator scripts for MODFLOW 6

harness.tool_command(ki, "tools/calib_run.py")
# '/usr/bin/python3 /abs/path/models/MODFLOW6/tools/calib_run.py'

harness.run_preflight(ki, timeout=60)
# {'report': ..., 'returncode': 1, 'raw_tail': ...}

harness.assert_injected(prompt)   # raises unless the prompt carries the contract
Two of these refuse rather than guess. tool_command() raises KiHarnessError
for an operator that does not exist, because a fabricated path fails later and
less legibly. assert_injected() is the conformance hook: it raises unless the
prompt carries the [KI HARNESS v1] marker, so a spawn site that bypassed the
contract fails immediately rather than producing plausible unguided work. Wire
it into your own runner and the same guarantee holds there.
|
|
HC_PROJECT_PYTHON |
interpreter used by tool_command() and run_preflight(); set it to your project environment |
KI_HARNESS_FULL=1 |
adds the run-time attention digest: dependency-graph caveats, format specification, leading diagnostic triplets |
Resolving a package by model name
A directory name is not always the model identifier: 8 of the packages here
differ, with SWAT+ in SWAT_Plus, HEC-RAS in HEC_RAS, Noah-MP in
Noah_MP. resolve_ki_path() consults a database that this repository does
not distribute and refuses to guess without it, so resolve names against the
catalogue instead, which handles the same spellings and reports ambiguity
rather than selecting one:
from kiss_cli.catalog import Catalog
ki = Catalog.discover().get("SWAT+").root
Repository layout
.
├── README.md
├── models/                          # model-specific KI packages
├── ki_tools_common/                 # shared helper library + the KI harness
├── kiss/                            # the desktop application and its engine
├── docs/manual/                     # desktop application manual (EN / 中文 / bilingual)
├── CLAUDE_TEMPLATE.md               # reusable agent instruction template
├── AGENT_SERVICE_GUIDE.md           # agent-service deployment examples
├── DEPLOYMENT.md                    # infrastructure setup notes
└── revalidation_3x3_results.xlsx    # expert-supervised validation record
Citation
If you use KISS or its KI packages, please cite:
@article{li2026kiss,
  title         = {KISS - Knowledge Infrastructure for Scientific Simulation: A Scaffolding for Agentic Earth Science},
  author        = {Li, Ziwei and Zhu, Liujun and Liu, Yuchen and Zhao, Yichen and Li, Birk and Wu, Ruiqi and Jin, Junliang and Zhang, Jianyun},
  journal       = {arXiv preprint arXiv:2605.17856},
  year          = {2026},
  eprint        = {2605.17856},
  archivePrefix = {arXiv},
  url           = {https://arxiv.org/abs/2605.17856}
}
License
Released under the MIT License. Copyright © 2026 Jianyun Zhang Research Group, Hohai University.

 KISS — это фреймворк инфраструктуры знаний (KI), который упаковывает практический опыт, стоящий за запуском научных симуляционных моделей: как готовить входные данные, судить о физической правдоподобности результатов и восстанавливаться после сбоев, — чтобы ИИ-агенты для программирования могли надёжно запускать эти модели, а не просто знать их уравнения.