



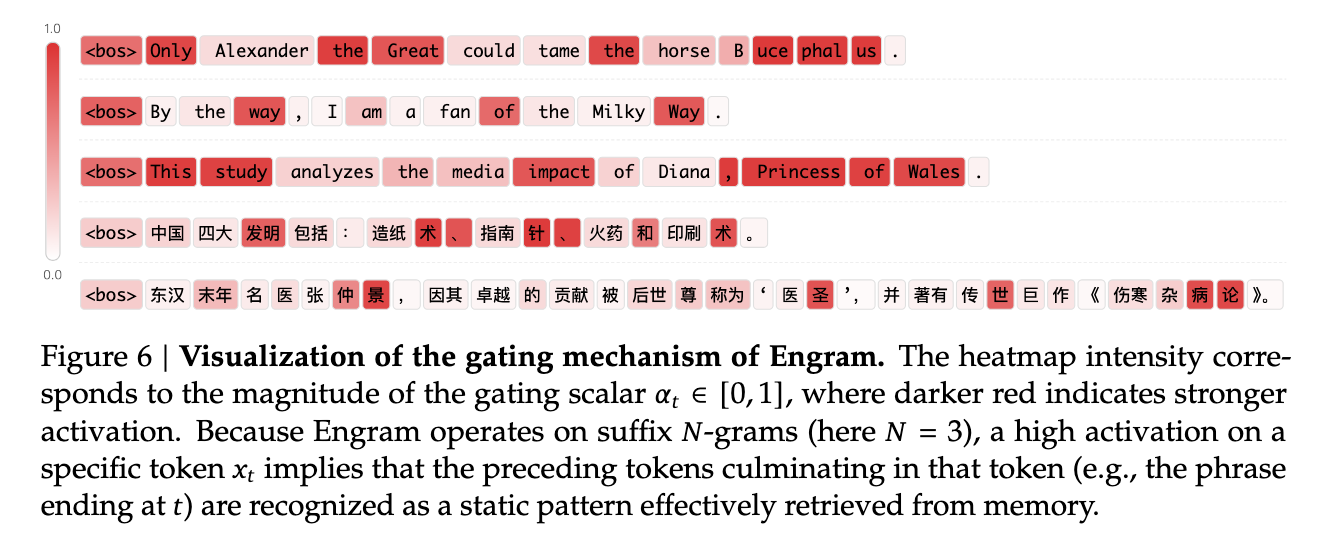
这是什么?
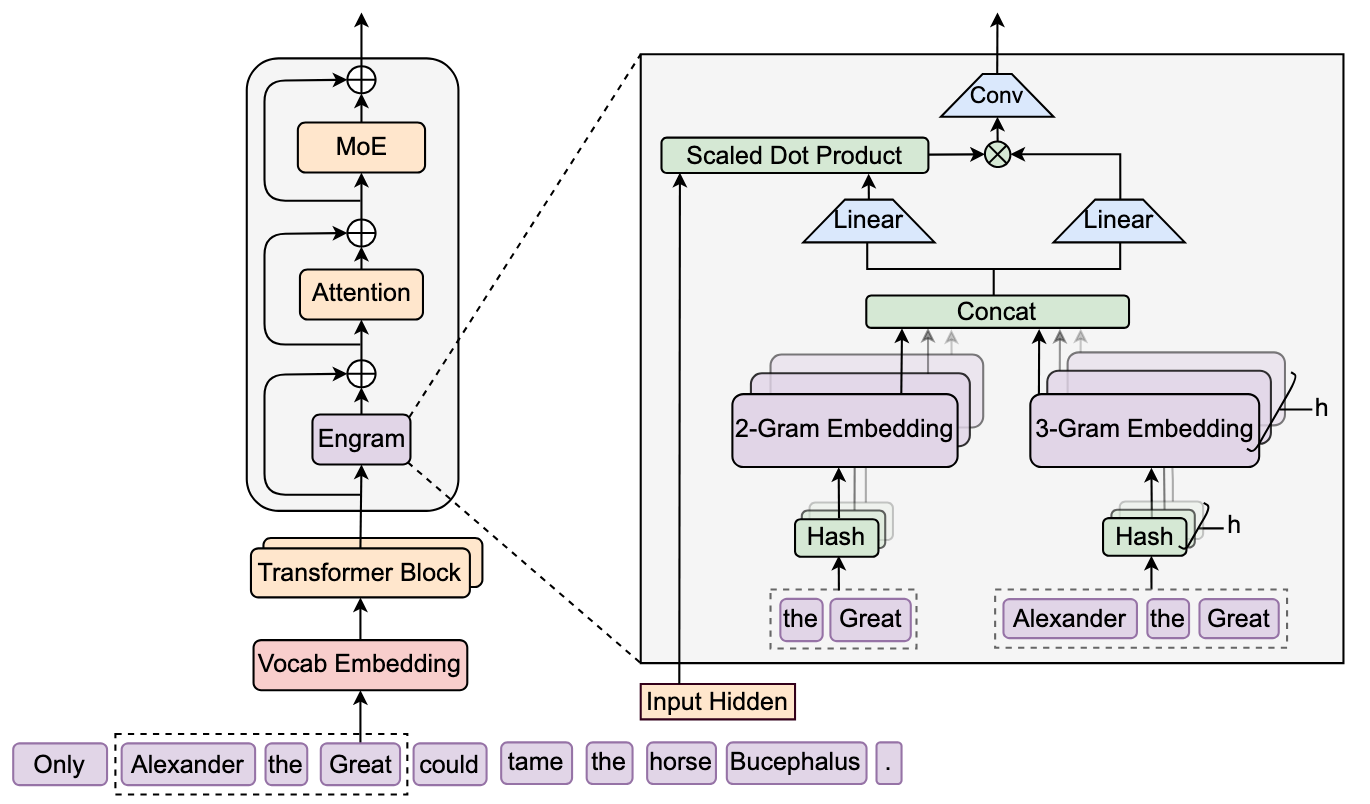
 这是 DeepSeek 论文《Conditional Memory via Scalable Lookup》的官方代码发布,介绍了 Engram——一个通过改造经典 N-gram 嵌入实现 O(1) 检索、赋予 Transformer 原生知识查找原语的模块,作为对 MoE 稀疏性的补充。
这是完整的可训练模型,还是只是演示代码?它是一个用于展示 Engram 模块数据流的独立演示实现;它对 Attention、MoE、mHC 等周围组件做了模拟,而不是提供完整的可训练模型。
它是一个用于展示 Engram 模块数据流的独立演示实现;它对 Attention、MoE、mHC 等周围组件做了模拟,而不是提供完整的可训练模型。怎么试用这份代码?安装 Python 3.8+ 和 PyTorch,然后运行仓库中的独立脚本,它会演示 Engram 模块的核心逻辑和数据流。
安装 Python 3.8+ 和 PyTorch,然后运行仓库中的独立脚本,它会演示 Engram 模块的核心逻辑和数据流。运行它需要装什么?只需要 Python 3.8 或更高版本和 PyTorch;这份演示代码没有描述其他任何配置。
只需要 Python 3.8 或更高版本和 PyTorch;这份演示代码没有描述其他任何配置。包含完整的 Engram-27B 模型或训练流程吗?不包含,只发布了 Engram 模块的简化独立演示;论文中 Engram-27B 的预训练配置、MoE 基线以及真实的 Attention/mHC 组件都没有提供。
不包含,只发布了 Engram 模块的简化独立演示;论文中 Engram-27B 的预训练配置、MoE 基线以及真实的 Attention/mHC 组件都没有提供。Engram 模块到底在做什么?它通过确定性查找检索基于 N-gram 的静态记忆,并将其与模型的动态隐藏状态融合,为 Transformer 提供了一种条件记忆机制,与 MoE 这类条件计算方法相辅相成。
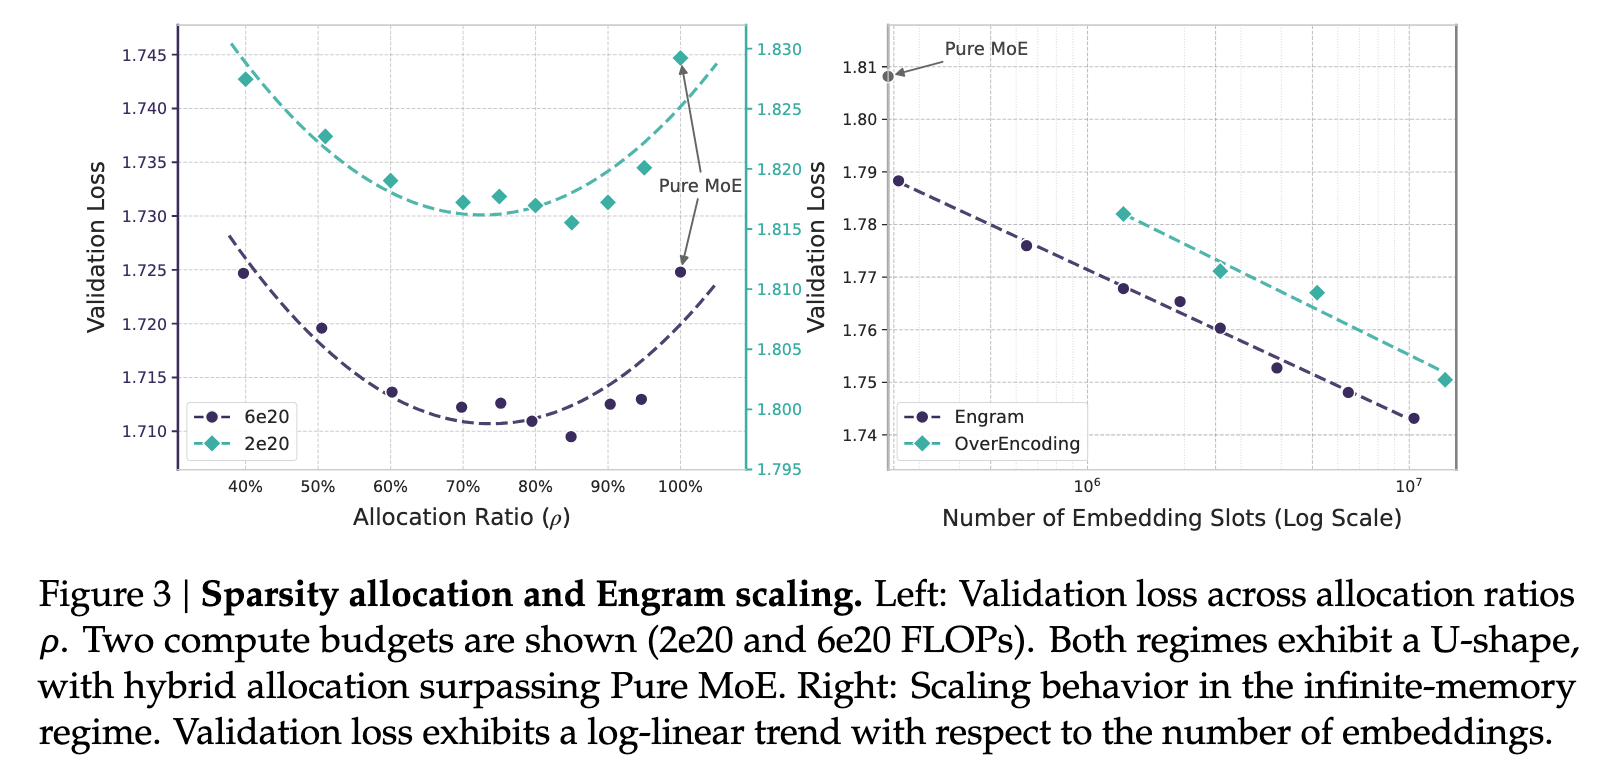
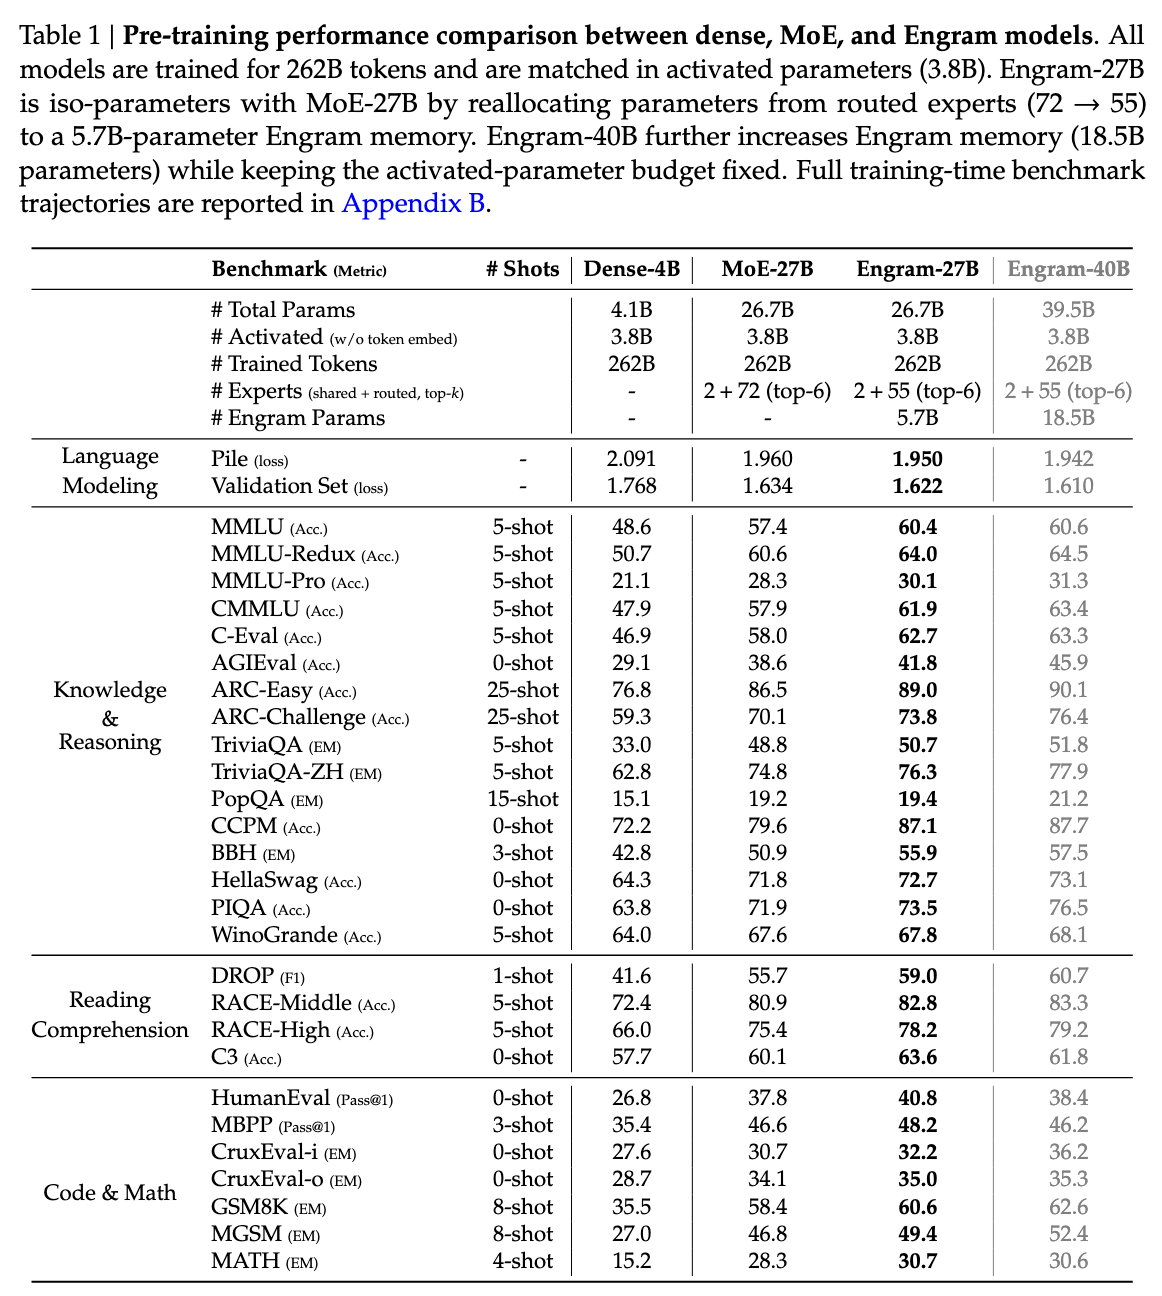
它通过确定性查找检索基于 N-gram 的静态记忆,并将其与模型的动态隐藏状态融合,为 Transformer 提供了一种条件记忆机制,与 MoE 这类条件计算方法相辅相成。与 MoE(专家混合)相比,Engram 表现如何?在参数量和 FLOPs 预算相当的情况下,Engram-27B 模型在知识、推理、代码和数学任务上持续优于 MoE 基线;论文还推导出一条 U 型缩放律,用于在 MoE 计算与 Engram 记忆之间分配容量。
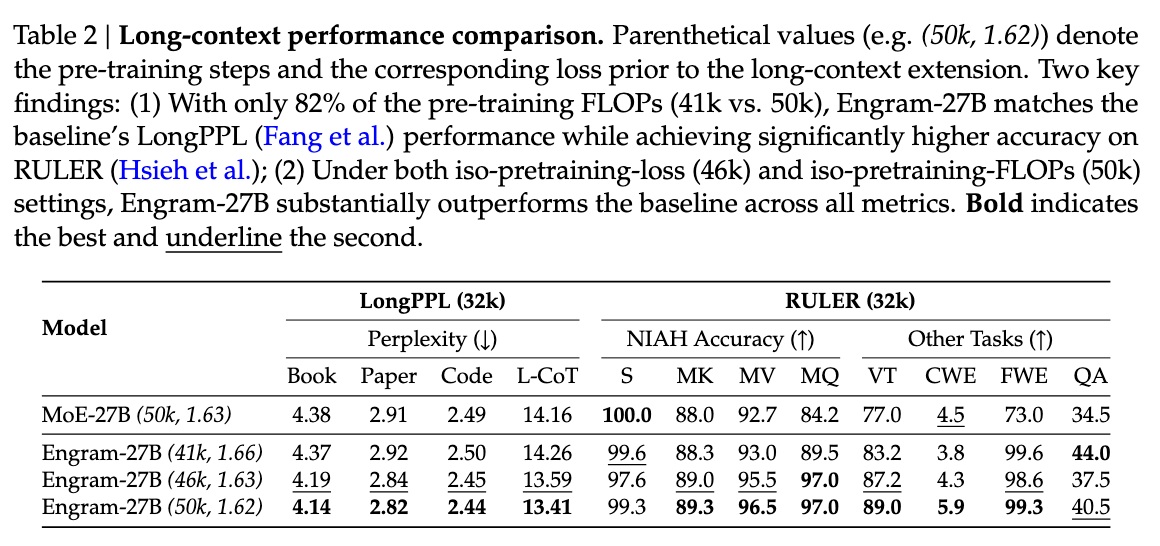
在参数量和 FLOPs 预算相当的情况下,Engram-27B 模型在知识、推理、代码和数学任务上持续优于 MoE 基线;论文还推导出一条 U 型缩放律,用于在 MoE 计算与 Engram 记忆之间分配容量。为什么 Engram 在推理时很高效?因为它的寻址是确定性的,它所依赖的大型嵌入表能以极小的推理开销卸载到主机内存;而且它让早期层不必记忆静态模式,为推理保留了有效深度。
因为它的寻址是确定性的,它所依赖的大型嵌入表能以极小的推理开销卸载到主机内存;而且它让早期层不必记忆静态模式,为推理保留了有效深度。What are similar projects?Attention-Residuals, bdh, llama3-from-scratch, MSA, DeepGEMM, llm-architecture-from-scratch, minGPT, Chinese-BERT-wwm
Attention-Residuals, bdh, llama3-from-scratch, MSA, DeepGEMM, llm-architecture-from-scratch, minGPT, Chinese-BERT-wwmWhich topics is it in?mixture-of-experts, attention-mechanism, papers, paper, embeddings, neural-network, transformer, nlp, large-language-models, academic-research, artificial-intelligence, deepseek
mixture-of-experts, attention-mechanism, papers, paper, embeddings, neural-network, transformer, nlp, large-language-models, academic-research, artificial-intelligence, deepseek