Example: embodied-model training on LoongForge — DreamZero at 4.38× baseline throughput, loss curves aligned
💡 Why LoongForge?
LoongForge is an open-source training framework developed by the Baidu AI Cloud Baige team, built to deliver faster training for mainstream LLMs, VLMs, diffusion, and embodied models, thereby significantly reducing costs.
High Performance — Built on multiple training backends (Megatron-LM and torch-native), with deep optimizations for each model family across parallelism strategy, memory footprint, communication overlap, and kernel efficiency, while keeping training loss curves aligned with the baseline.
Proven at Scale — Open-sourced from AIAK-Training-LLM, a training acceleration suite serving enterprise customers in Education, Computer Vision, and Embodied AI, with the largest production runs reaching 5,000+ XPUs.
🐉 LoongForge is named after the traditional Chinese loong boat (龙舟), a symbol of coordinated power and forward momentum.
🏗️ Architecture
Since optimal training strategies differ across model families and scales, LoongForge adopts a multi-backend architecture.
Megatron Stack — For LLMs, VLMs, and diffusion models. Powered by a patched Megatron-LM and extended with MoE parallelism, per-component heterogeneous parallelism, long-sequence optimizations, etc.
Torch-Native Stack — For embodied models (VLA and WAM). A standalone torch-native subsystem featuring DDP / ZeRO-1 / FSDP / HSDP, with deep optimizations for representative models across I/O, communication strategy, kernel efficiency, etc.
🔥 Latest News
[2026/09] ✨ Added training support for GLM-5.3-flash.
[2026/09] ✨ Added Kimi-K3 BF16 training support for both LLMs and VLMs.
[2026/09] ⚡ Added an optimized DreamZero Wan2.2-5B FSDP recipe with cache-aware data loading, compiled attention blocks, frozen-module handling, and FSDP2 Delta-FP8 Param AllGather.
[2026/08] 🤖 Added VLA training support for Wall-OSS-0.5, with custom fused operators for higher training throughput.
[2026/08] 📄 Released the TAOT paper — topology-aware dynamic expert replica placement that tackles expert-parallel (EP) load imbalance in MoE training, cutting overhead by up to 74% over industry solutions, with 1.43× speedup measured on a real training case. [blog]
[2026/08] ✨ Added training support for GLM-5.2, along with a GLM-5.2 + MoonViT custom-composition example for extending GLM with multimodal capabilities.
[2026/08] ✨ Added training support for MiniCPM-V-4.6 and Qwen3.8-27B.
[2026/08] 🧪 Introduced a unified evaluation module for the embodied stack, currently covering Pi0.5 / xVLA / GR00T, with more models on the way.
[2026/07] 🐳 Unified the prebuilt Docker images — all model families (LLM / VLM / VLA / Diffusion) now share a single image.
[2026/07] 🤖 Released LoongForge-Embodied, a torch-native DDP/FSDP training subsystem for embodied models (Pi0.5, GR00T-N1.6/N1.7, xVLA, LingBot-VA, FastWAM, DreamZero, and Cosmos3), with up to 4.38× speedup. [blog]
[2026/07] ✨ Added training support for Qwen-Image-Edit-2511.
[2026/07] ✨ Added training support for DeepSeek-V4-Flash / DeepSeek-V4-Pro.
📅 More
[2026/06] 🤖 Expanded VLA coverage with GR00T N1.6; 2.3× speedup on GR00T training. [blog]
[2026/05] ⚡ Accelerated Wan 2.2 training by 116%, and added CP and data packing support.
[2026/05] ✨ Added training support for Kimi K2.5 / K2.6, and introduced INT4 / NVFP4 PTQ.
[2026/05] 🎉 v0.1.0 — first official tagged release of LoongForge.
[2026/05] 🌟 Powered the training and public release of LLaVA-OneVision-2.0.
[2026/04] 🧩 Added training support for MiniMax-M2.7 on both NVIDIA GPU and Kunlun XPU.
[2026/04] 🚀 LoongForge source code publicly available on GitHub. [blog]
[2025/10] 🌟 Powered the training and public release of LLaVA-OneVision-1.5 under AIAK-Training-LLM, the predecessor of LoongForge. [blog]
✨ Key Features
🚀 Foundation Models
MoE EP Communication Optimization — Overlapped All2All / activation offload / compute, with further memory reduction beyond upstream Megatron-LM on DeepSeek-V3, Qwen3-MoE, etc.
MoE Expert Load Balancing — Topology-aware dynamic replication of hot experts to balance EP workloads, with up to 74% lower overhead than industry solutions. [TAOT Paper]
Adaptive FP8 Training — End-to-end FP8 for LLMs and VLMs with standard blockwise FP8; optional adaptive mode picks per-operator precision by GEMM shape and efficiency.
Custom Fused Operators — Fused kernels like FusedDSA for DSA-style models — TileLang version open-sourced, high-performance CUDA version available on Baidu Baige platform.
Long-Sequence Training — Context Parallel (CP) with chunked-pipeline scheduling scales LLM training to long sequence lengths.
🧩 Multi-Modal Models
Flexible Multi-Modal Composition — Assemble VLMs from interchangeable ViT and LLM components (e.g. GLM-5.2 + MoonViT) straight from config — no custom model code.
Heterogeneous Parallelism — Independent TP / DP / recompute / freeze per model component (e.g., ViT vs. LLM) for optimal throughput and memory. [blog]
Decoupled Encoder-Decoder Training — Separates ViT and LLM into independent tasks, eliminating encoder-induced pipeline bubbles.
VLA & WAM Training — A dedicated torch-native DDP/FSDP subsystem for VLA and world-action (WAM) models, decoupled from the Megatron core, with flexible DDP / ZeRO-1 / FSDP / HSDP strategies. [README]
FP8 Communication Optimization — Optional FP8 optimizations that cut cross-rank traffic on supported NVIDIA GPUs, covering both parallel strategies: blockwise FP8 delta AllGather for FSDP2 parameters, and FP8 grad all-reduce for DDP gradients. [Usage]
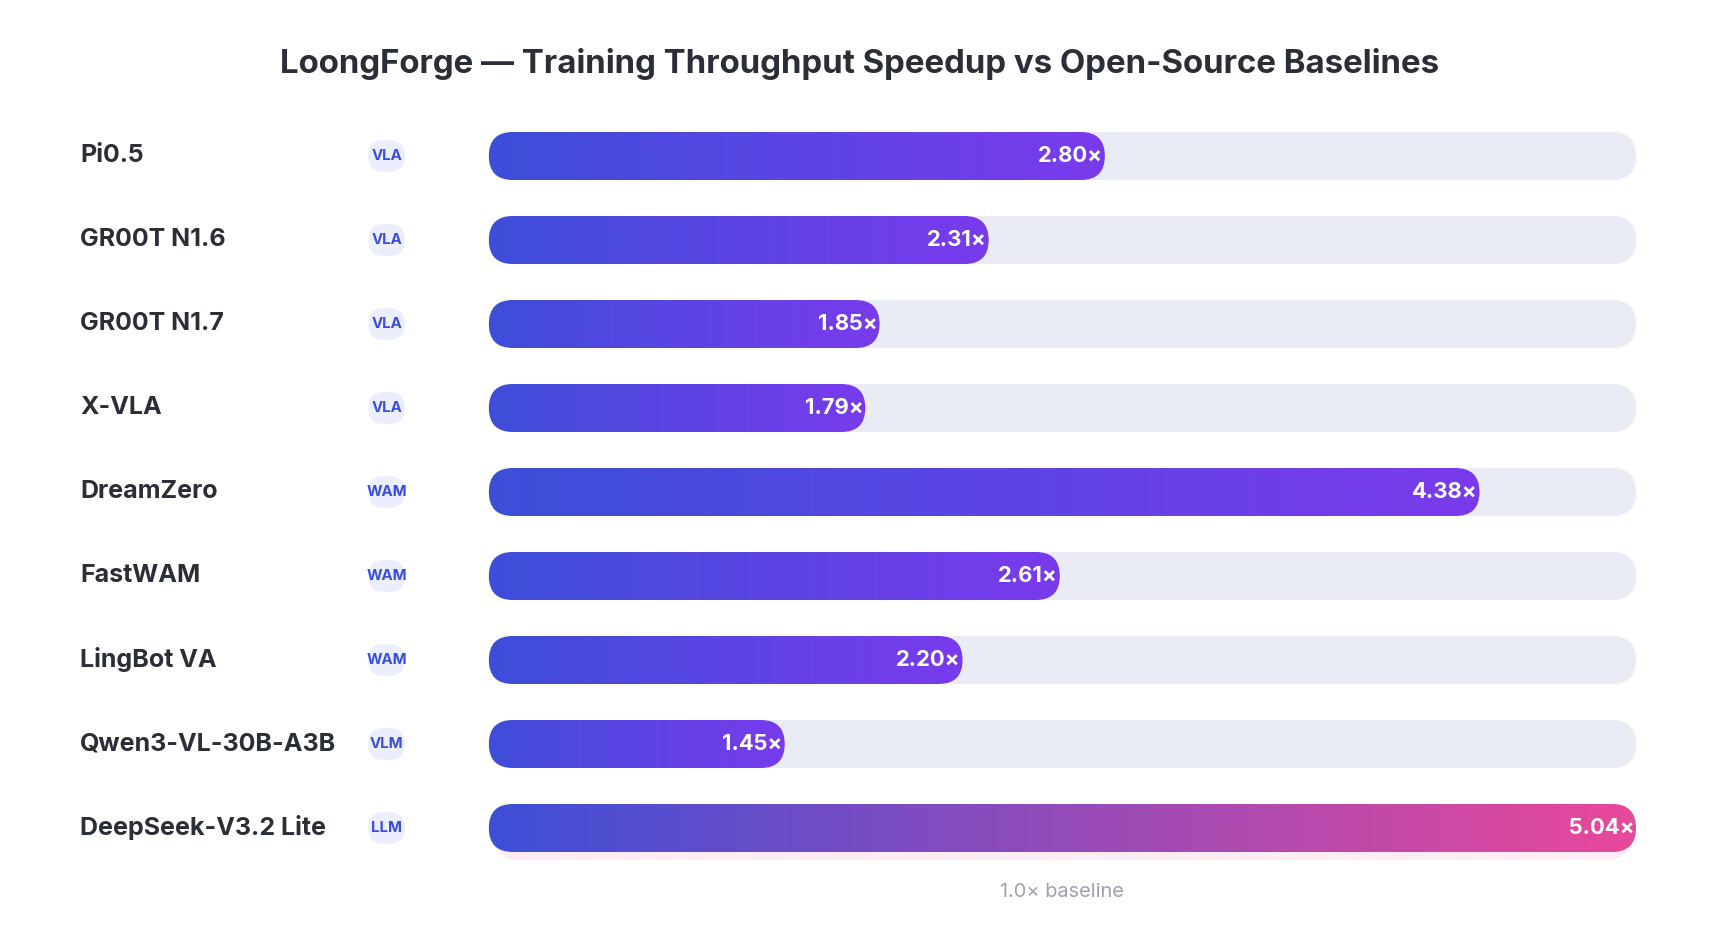
Per-Model Deep Optimization — Training code deeply customized for each supported model across I/O, communication strategy, and kernel efficiency — 1.79×–4.38× over official baselines in our benchmarks.
Unified Evaluation — Evaluate trained policies on LIBERO / CALVIN / SimplerEnv / RoboTwin, with coverage expanding continuously.
🧰 Workflow & Compatibility
Versatile Pipelines & Data Tools — Out-of-the-box Pretrain / MidTrain / SFT / LoRA, with built-in dataset format conversion and sequence packing.
Flexible Checkpointing — Offline bidirectional Megatron ↔ HuggingFace conversion plus native online HF load/save — no format barriers across your workflow.
Heterogeneous Hardware — Native support for NVIDIA GPUs and Kunlun XPUs via a minimally-intrusive plugin design.
Training throughput speedups over mainstream open-source baselines — each model and its baseline were benchmarked on the same machine type with the same training hyperparameters:
DeepSeek-V3.2 Lite reflects DSA operator-level optimizations and was validated on a reduced-layer configuration due to test-bed scale limits.
Numbers were measured at a point in time and may evolve as implementations change on both sides.
LoongForge supports a broad range of model families across LLM, VLM, diffusion, and embodied. Select a model below to open its training examples. For complete usage instructions, see the User Guide and the full model support matrix.
If you find LoongForge helpful, please cite this project:
@software{LoongForge2026,
  title  = {LoongForge: A high-performance framework for training LLMs, VLMs, diffusion, and embodied models},
  author = {{The LoongForge Authors}},
  year   = {2026},
  url    = {https://github.com/baidu-baige/LoongForge}
}
If you use TAOT for MoE training in LoongForge, you can cite our paper:
@article{zhang2026taot,
  title   = {{TAOT}: Topology-Aware Optimal Transport for Dynamic Expert Replica Placement in {MoE} Training},
  author  = {Zhang, Lingyun and Zhang, Henghua and Gu, Shilei and Mo, Kai and Han, Shuai and Li, Shiyong and Wang, Yanpeng and Shen, Dou},
  journal = {arXiv preprint arXiv:2608.03676},
  year    = {2026},
  url     = {https://arxiv.org/abs/2608.03676}
}
🤝 Contributing
We warmly welcome community contributions — bug reports, feature proposals, and PRs alike. Please read our Contributing Guidelines before submitting.
Thanks to all our contributors:
🙏 Acknowledgments
LoongForge builds on NVIDIA's Megatron-LM and draws inspiration from many excellent open-source projects, including HuggingFace Transformers, LLaMA-Factory, Megatron-Bridge, and LeRobot, as well as the official implementations of the models it supports (e.g. OpenPI, NVIDIA Isaac GR00T). We sincerely thank these communities for their outstanding contributions, and would also like to extend our gratitude to the LINUX DO community for its welcoming space for technical discussion and support for open-source sharing.
💬 Contact Us
GitHub Issues — Bug reports, usage questions, and feature requests. Open an issue.
Developer Communities — WeChat group, Xiaohongshu, and more. Join here.
Email — Enterprise adoption, large-scale deployment, partnership, or any other topic. [email protected].
📄 License
LoongForge is released under the Apache License 2.0. Some files are derived from third-party open-source projects; please refer to the specific file headers for their respective copyright and attribution.
What is this?An open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.
Is it a library I code against, or a set of ready-made training scripts?It's script-driven: you run ready-to-use launch scripts under examples/ (NVIDIA) or examplesxpu/ (Kunlun) with configs in configs/models/. Internally there are two backends — a patched Megatron-LM stack and a torch-native stack for embodied models.
How do I get it running?Pull the unified prebuilt Docker image (one image covers all model families) or build from source, then follow a tutorial for your hardware and modality and run your model's launch script from examples/.
Is the whole codebase Apache-2.0?Apache-2.0, but not uniformly: some files derive from third-party open-source projects, so check individual file headers for their copyright and attribution.
Do I need NVIDIA hardware, or does it run on anything else?NVIDIA GPUs or Baidu Kunlun XPUs — both are supported natively through a plugin design, each with its own install guide and tutorial set. No CPU-only mode is mentioned.
Why the name LoongForge?It's named after the traditional Chinese loong boat (龙舟), a symbol of coordinated power and forward momentum — fitting imagery for a distributed training framework.
What is TAOT?A Baidu technique for MoE training: topology-aware dynamic replica placement that balances expert-parallel load, cutting overhead by up to 74% over industry solutions, with a 1.43× speedup measured on a real training case.
Has anything real been trained with it?Yes — LLaVA-OneVision-1.5 and 2.0, Innovator-VL and the Qianfan-VL family (3B–70B parameters) were trained with LoongForge or its predecessor AIAK-Training-LLM, whose largest production runs reached 5,000+ XPUs.
Can I assemble a custom VLM from separate components?Yes — flexible multi-modal composition lets you pair interchangeable ViT and LLM components (the README shows GLM-5.2 + MoonViT) straight from config, with no custom model code, and tune parallelism per component.





 An open-source training framework from Baidu's Baige team for LLMs, VLMs, diffusion and embodied models, built for faster training and lower cost on NVIDIA GPUs and Kunlun XPUs.