210 ·GitHub
这是什么?
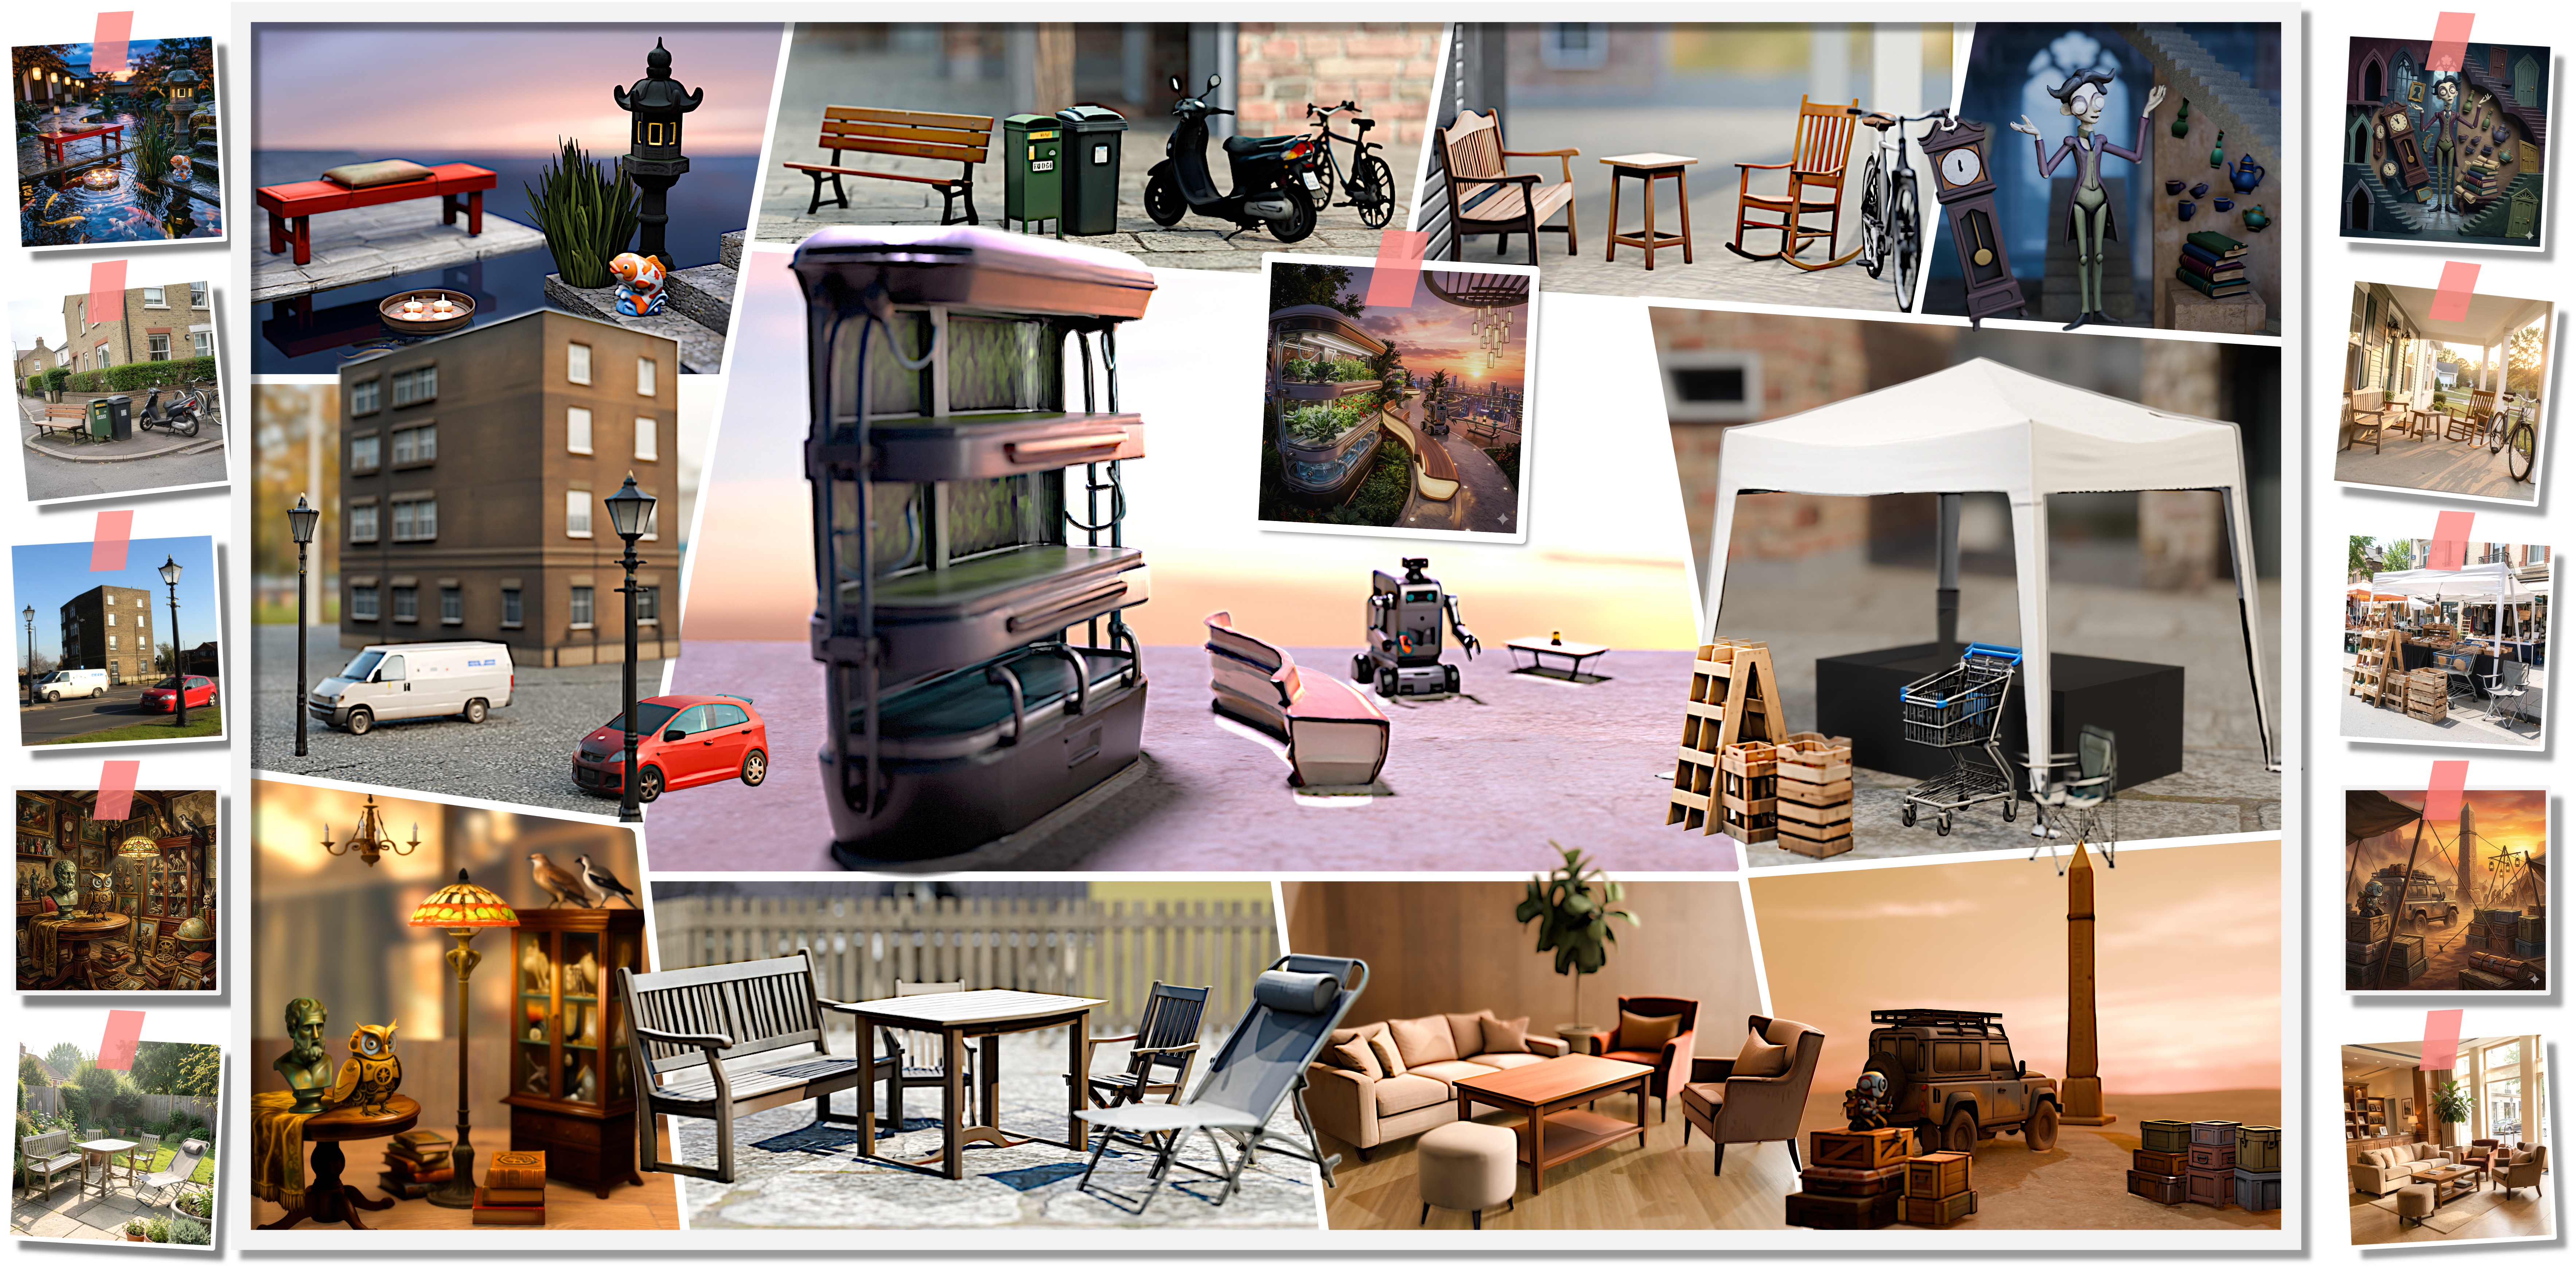
 Mira-Scene 是一个从单张图像重建可编辑 3D 场景的流水线,结合了交互式实例分割、深度估计、规范坐标与体素预测、物体网格生成、场景组装和环境贴图生成。
这是开箱即用的应用,还是需要我自己运行的研究流水线?它是一个开源研究流水线,不是打包好的应用:你拿到的是推理代码,以及 Mira-CCM 的 Stage 1 预训练检查点和 Stage 2 最终检查点,需要自己逐阶段运行。
它是一个开源研究流水线,不是打包好的应用:你拿到的是推理代码,以及 Mira-CCM 的 Stage 1 预训练检查点和 Stage 2 最终检查点,需要自己逐阶段运行。推理流水线怎么运行?按照推理指南运行分阶段流水线,它支持断点续跑、多种深度和网格后端,以及按案例的多 GPU 分片。
按照推理指南运行分阶段流水线,它支持断点续跑、多种深度和网格后端,以及按案例的多 GPU 分片。运行它需要预训练检查点和 GPU 吗?需要——你需要可从 Hugging Face 下载的 Stage 1 预训练检查点和 Stage 2 最终检查点,还需要 GPU 资源,因为流水线按案例在多块 GPU 上分片运行。
需要——你需要可从 Hugging Face 下载的 Stage 1 预训练检查点和 Stage 2 最终检查点,还需要 GPU 资源,因为流水线按案例在多块 GPU 上分片运行。发布的版本包含全部训练数据吗?发布的 Scene 数据和外扩绘制的 Objaverse 数据可用于微调,但预训练所用的海量 Objaverse 渲染数据并未包含在内,必须从源素材重新生成。
发布的 Scene 数据和外扩绘制的 Objaverse 数据可用于微调,但预训练所用的海量 Objaverse 渲染数据并未包含在内,必须从源素材重新生成。这是面向研究人员而非普通终端用户的吗?是的,它面向计算机视觉和生成式 3D 研究人员——这些人想在场景重建方法上做基准测试或在其上构建,项目附带论文、基准测试表和训练配置。
是的,它面向计算机视觉和生成式 3D 研究人员——这些人想在场景重建方法上做基准测试或在其上构建,项目附带论文、基准测试表和训练配置。MIT 许可证覆盖仓库里的所有内容吗?只有 Mira-Scene 代码本身采用 MIT 许可证;第三方组件、预训练模型和数据集各自保留独立的许可证和条款。
只有 Mira-Scene 代码本身采用 MIT 许可证;第三方组件、预训练模型和数据集各自保留独立的许可证和条款。Mira-CCM 是什么?Mira-CCM 是流水线 Stage 1 中预训练的规范坐标模型检查点;已在 Hugging Face 上发布,可直接用于启动 Stage 2 微调。
Mira-CCM 是流水线 Stage 1 中预训练的规范坐标模型检查点;已在 Hugging Face 上发布,可直接用于启动 Stage 2 微调。Mira-Scene 与 SAM3D 相比如何?在基准测试中,Mira-Scene 在 3D-IoU(0.727 对 0.520)、2D-IoU 和 ADD-S 上得分更高,且仅使用 8 万个开源 3D 样本和全自动数据流水线;而 SAM3D 依赖超过百万的闭源样本,需要大量人工布局标注。
在基准测试中,Mira-Scene 在 3D-IoU(0.727 对 0.520)、2D-IoU 和 ADD-S 上得分更高,且仅使用 8 万个开源 3D 样本和全自动数据流水线;而 SAM3D 依赖超过百万的闭源样本,需要大量人工布局标注。训练是怎么组织的?训练分两个阶段:用 exampletrain/configs/pretrainl1.yaml 预训练,用 exampletrain/configs/finetune.yaml 微调;有了 Hugging Face 上的预训练 Mira-CCM 检查点,可以直接跳到微调阶段。
训练分两个阶段:用 exampletrain/configs/pretrainl1.yaml 预训练,用 exampletrain/configs/finetune.yaml 微调;有了 Hugging Face 上的预训练 Mira-CCM 检查点,可以直接跳到微调阶段。数据集从哪里来?Scene 数据和外扩绘制的 Objaverse 数据单独发布在 Mira-Scene Dataset 仓库中;预训练所用的大规模原始 Objaverse 渲染数据不随项目再分发,必须从源素材重新生成。
Scene 数据和外扩绘制的 Objaverse 数据单独发布在 Mira-Scene Dataset 仓库中;预训练所用的大规模原始 Objaverse 渲染数据不随项目再分发,必须从源素材重新生成。What are similar projects?WorldSculpt, pointdit, tapnet, CodeVideoModel, InsertAny3D, UniMate, vggt, sam-3d-objects
WorldSculpt, pointdit, tapnet, CodeVideoModel, InsertAny3D, UniMate, vggt, sam-3d-objectsWhich topics is it in?3d-generation, 3d-reconstruction, segmentation, paper, training, dataset, evaluation, 3d, academic-research, artificial-intelligence, inference, generative-ai
3d-generation, 3d-reconstruction, segmentation, paper, training, dataset, evaluation, 3d, academic-research, artificial-intelligence, inference, generative-ai