NanoJev — A nano replica of Jev
English | 简体中文
A 0.6B parallel decision model: states and questions in, complete probability distributions out. Zero output-token decoding.
New project: JevHarness — Let an LLM build task-specific decision harnesses with Jev, with optional refinement using rewards and execution traces. Includes an interactive Pokémon demo.
Play ViZDoom · Maze & Snake · Model · Dataset
Now playing ViZDoom: one shared checkpoint handles Basic aiming and Predict Position's moving-target rocket shots, alongside Maze and Snake.
4 tasks · 18,760 decision questions per data variant · 896 Predict Position expert episodes
What's new
September 20, 2026 — One model, four games.
- ViZDoom Basic: 128/128 test successes, compared with 56/128 for Jev.
- ViZDoom Predict Position: 27/128 test successes, up from 11/128 before this round; the matched Jev run also scores 11/128. The policy learns when to turn, wait and fire at a moving target.
- 16,333 ViZDoom questions within an 18,760-question mixed-task dataset per target variant, spanning train, dev, calibration, test and OOD.
- One model, four games: the same step-400 checkpoint also completes the 50×50 maze in 225 attempts and collects 30 food items during a full 256-step Snake run.
Three models, side by side
Real browser replays of Jev, NanoJev and Untuned Qwen. These animations loop automatically; click either one to open its interactive player. All four demos use the same current NanoJev checkpoint. The interactive development site currently requires access; all recordings can also be played locally using the commands below.
ViZDoom Basic · Aim, then fire
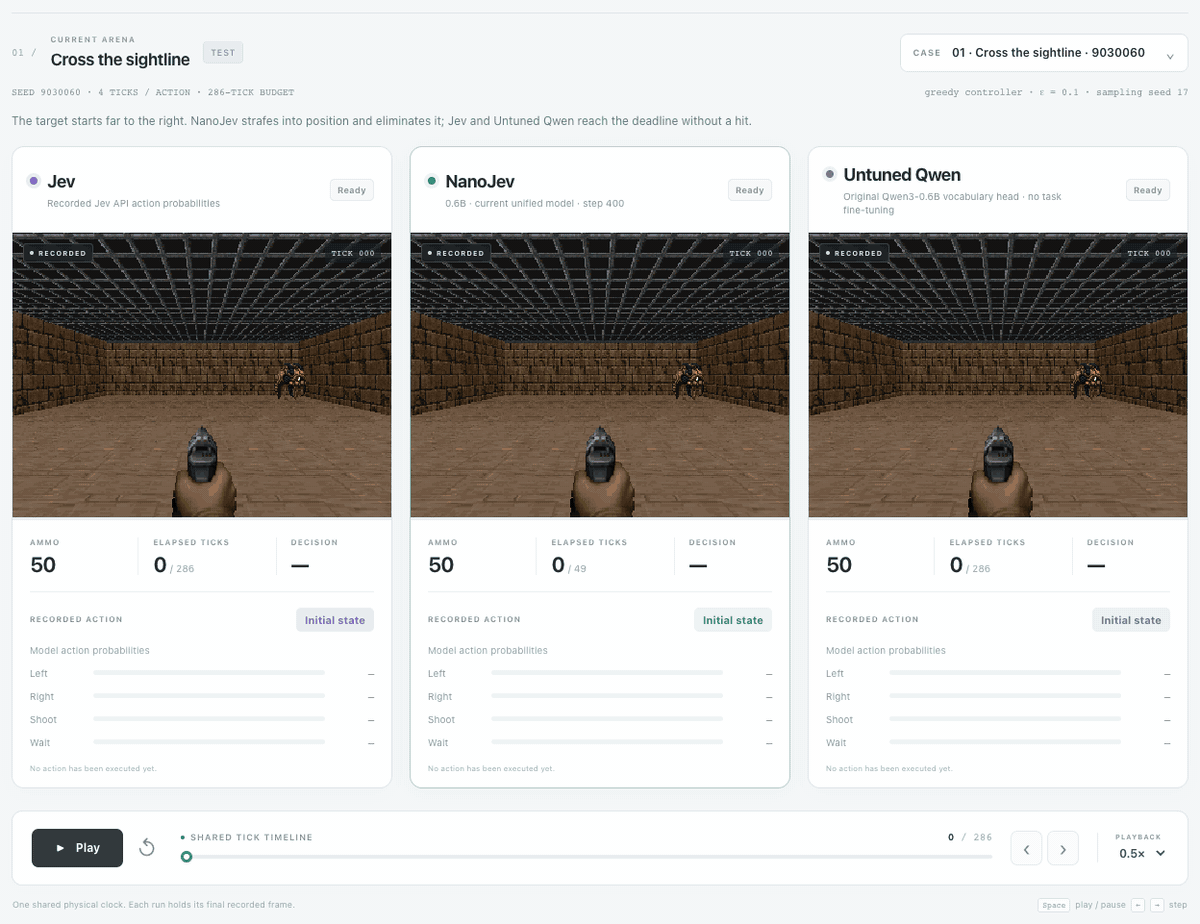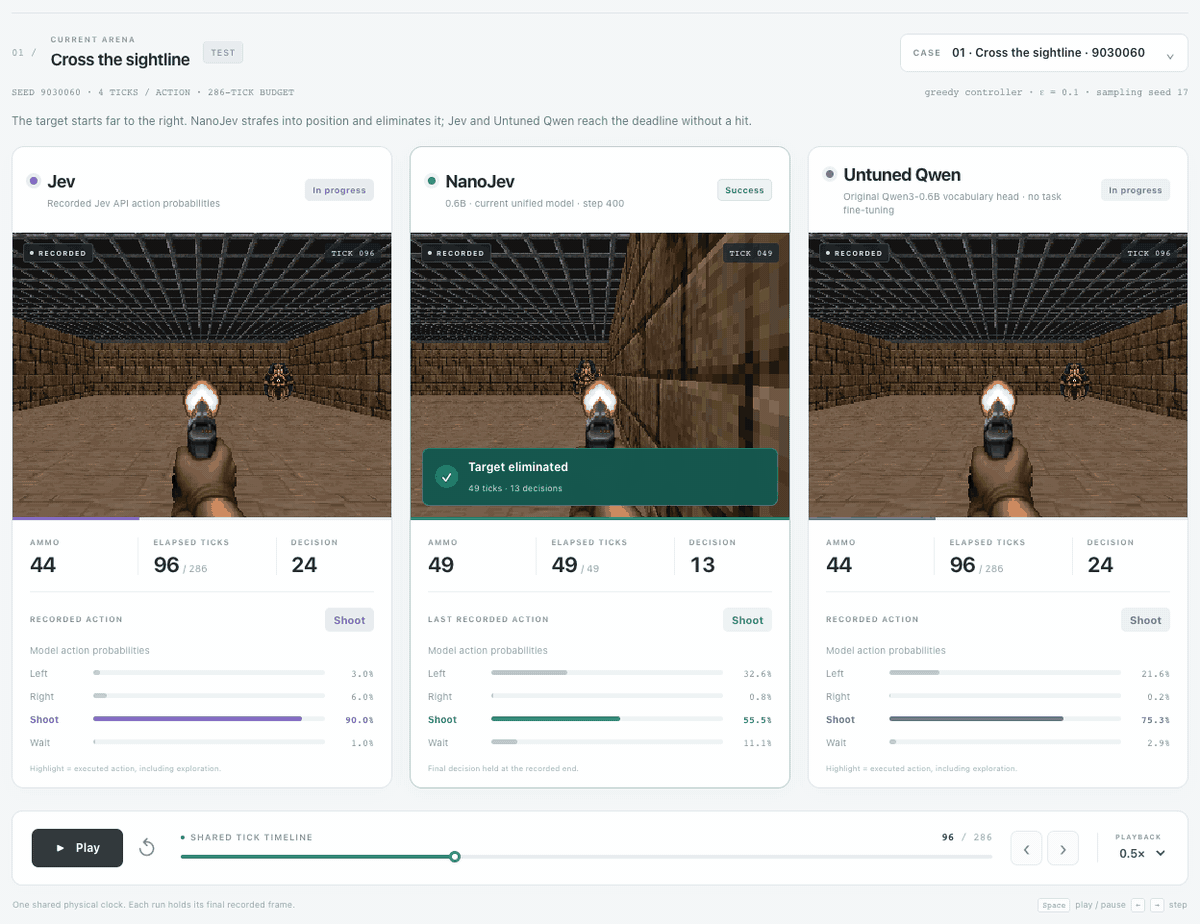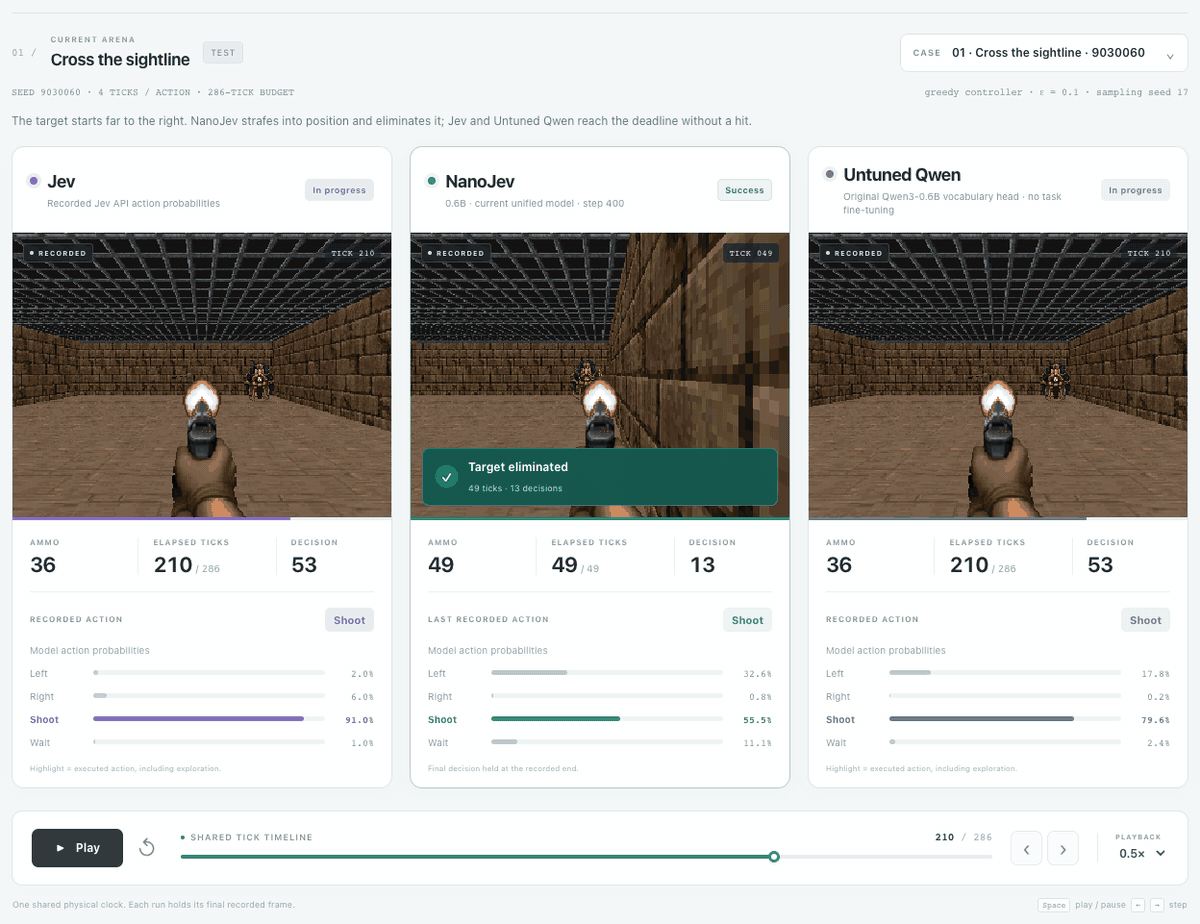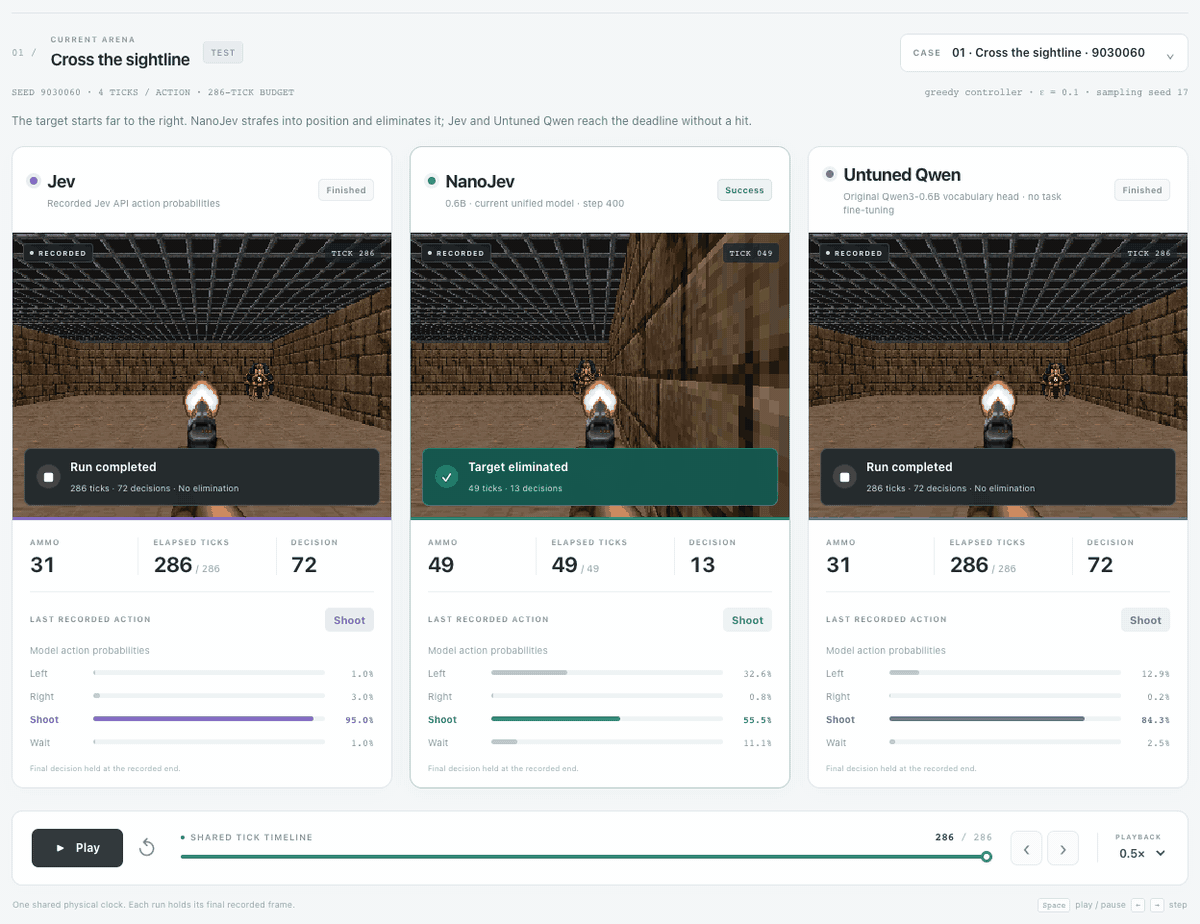
Move into position, line up the target, fire. NanoJev eliminates the target with one shot in 1.40 s; Jev and Untuned Qwen each fire 19 shots without an elimination before the deadline. The three panels share the same game clock and show original frames and action probabilities.
Find the exit · 50×50 Maze
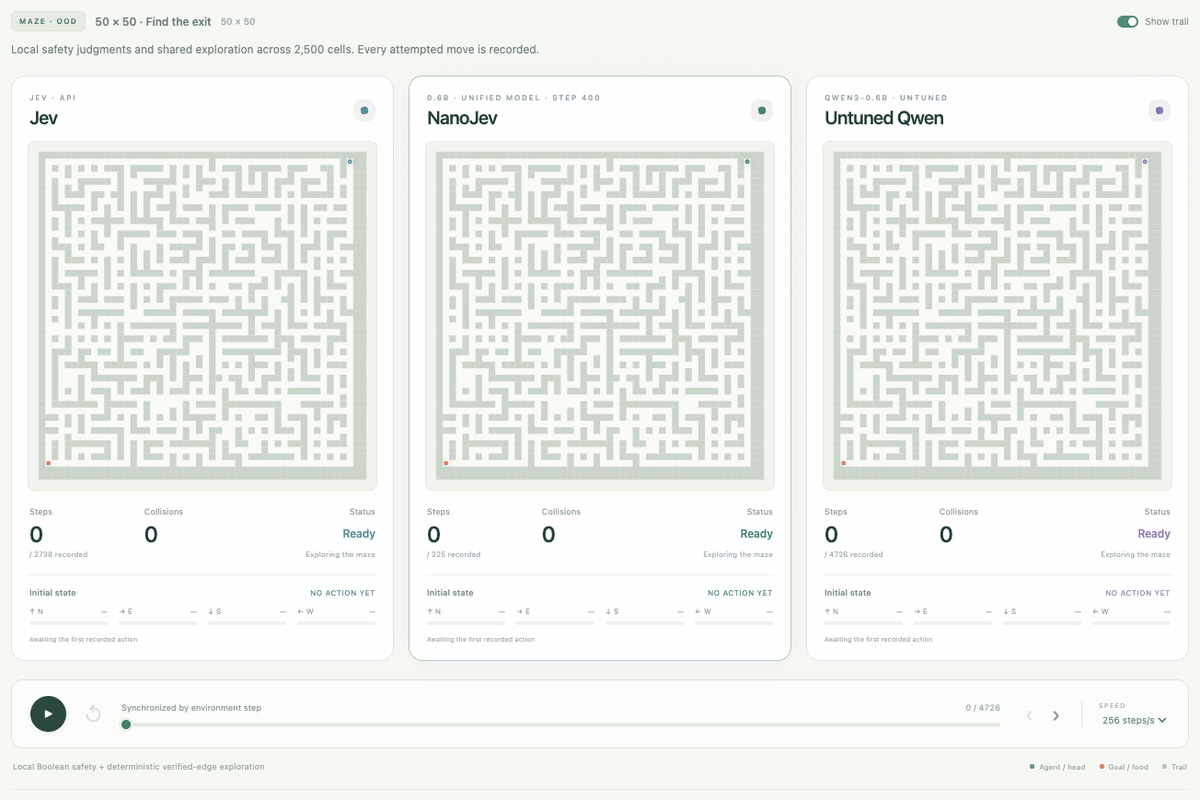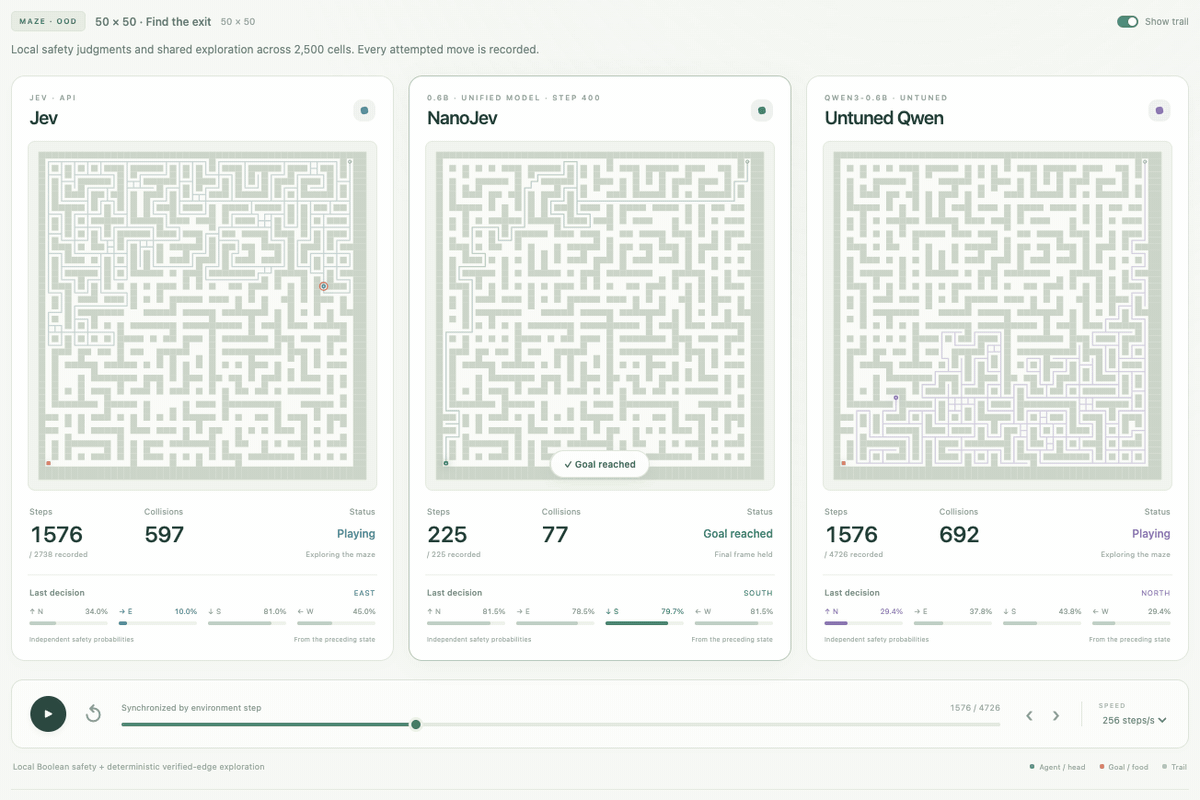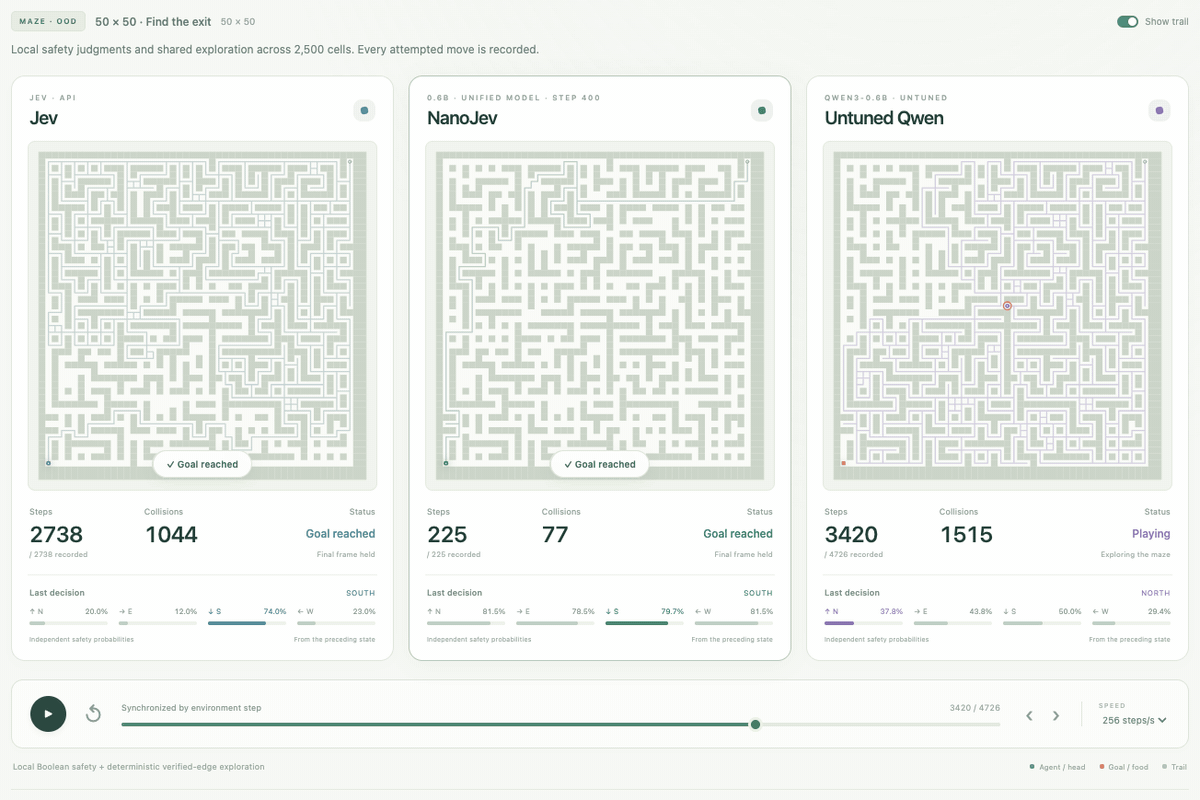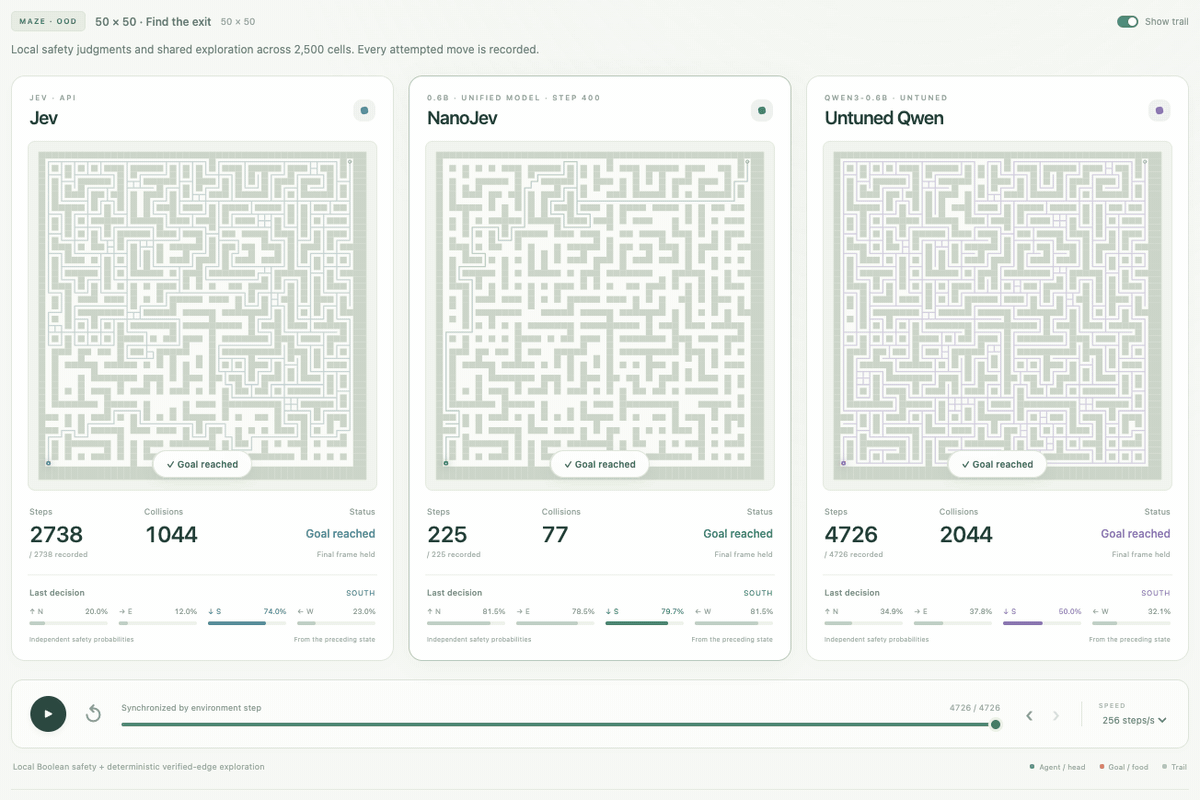
NanoJev reaches the exit in 225 attempts, versus 2,738 for Jev and 4,726 for Untuned Qwen. Each system combines local safety probabilities with the same exploration code and remembered open paths.
Play Snake · Play Predict Position
What NanoJev does
- Parallel decisions: batch independent states, questions and candidate paths in one backbone forward.
- Dynamic candidates: Choice returns a distribution over 2–255 supplied candidates using a shared scoring head.
- Boolean and ordered scores: predict a proposition's probability, or a distribution and expectation over 2–10 ordered levels.
- Direct probabilities: rank, select or sample actions without generating answer tokens.
- One small backbone: Qwen3-0.6B with decision heads, reused across all four game tasks and a persistent inference service.
Each request supplies a state, a question and its candidates. The backbone encodes candidate paths; shared heads produce the requested probabilities. Choice uses set attention and a softmax, Boolean uses a sigmoid, and Score returns a probability-weighted level.
Held-out gameplay
Successful episodes on the complete 274-case test set, using the same observation interface, candidate actions and seeded epsilon-greedy controller across systems:
| Model |
Maze |
Snake |
Basic |
Predict Position |
| NanoJev |
4/10 |
8/8 |
128/128 |
27/128 |
| Jev |
7/10 |
8/8 |
56/128 |
11/128 |
| Untuned Qwen3-0.6B |
2/10 |
0/8 |
56/128 |
11/128 |
Test and OOD together contain 548 cases per model. Every evaluated trajectory passes independent simulator replay. The large navigation showcases above use their displayed local-question and code-planning settings.
Complete test and OOD results · Training pipeline
Dataset scale and model
18,760 decision questions per target variant, including 16,333 ViZDoom questions. The matched hard-target and soft-target variants cover the same questions across train, dev, calibration, test and OOD.
| Task |
All five splits |
Training split |
| ViZDoom Predict Position |
11,173 |
6,788 |
| ViZDoom Basic |
5,160 |
3,054 |
| Maze |
1,469 |
653 |
| Snake |
958 |
403 |
| Total per variant |
18,760 |
10,898 |
Expert gameplay: the package includes 896 Predict Position episodes with 17,498 recorded decisions, including 512 episodes assigned to training. It also contains the original mixed-task inputs, hard/soft targets, evaluation trajectories and replay checks.
Of the 10,898 stored training questions, 10,893 pass the target-validity filter. Existing Maze, Snake and Basic splits are preserved.
Release version and training run
unified-games-v1 packages the step-400 checkpoint from the hard_lr1e5 training run. Both names refer to the same selected model used across the four demos.
| Name |
Meaning |
When to use it |
unified-games-v1 |
Hugging Face release tag identifying the matching model and dataset snapshots. |
Download with revision="unified-games-v1". |
hard_lr1e5 |
Training experiment: hard (one-hot) action targets for Predict Position, backbone learning rate 1e-5, decision-head learning rate 1e-4. |
Inspect training configs, logs and experiment comparisons. |
The shared model is trained with complete-question cross entropy. Updates mix Maze, Snake, Basic and Predict Position with weights 1/3, 1/3, 1/6, 1/6.
Hugging Face release complete: the model and complete dataset are uploaded and verified as unified-games-v1. Both release tags resolve to their recorded snapshots; every uploaded file passes remote identity checks.
The model and dataset are public and can be downloaded without signing in.
Quick start
git clone https://github.com/TianyuCodings/NanoJev.git
cd NanoJev
python -m pip install -r requirements-toy.txt huggingface_hub
Download the current checkpoint and data:
from huggingface_hub import snapshot_download

snapshot_download(
    repo_id="C-Tianyu/NanoJev",
    revision="unified-games-v1",
    local_dir="checkpoints/NanoJev-unified",
    allow_patterns=["best.safetensors", "config.json", "tokenizer/*", "backbone_config/*"],
)
snapshot_download(
    repo_id="C-Tianyu/NanoJev-Data",
    repo_type="dataset",
    revision="unified-games-v1",
    local_dir="data/NanoJev-unified",
)
Start inference in a CUDA environment:
python scripts/serve_decisions.py \
  --checkpoint-dir checkpoints/NanoJev-unified \
  --web-root web --port 8765 --disable-native-triton
The service loads the model once. Send state/question batches to POST http://127.0.0.1:8765/api/evaluate.
To explore the recorded games locally:
python3 -m http.server 8080 --bind 127.0.0.1 --directory web
Open http://127.0.0.1:8080/dev/?autoplay=1 for ViZDoom Basic or http://127.0.0.1:8080/dev/side-by-side.html?autoplay=1#maze for Maze.
Development notes
Release contents and reproduction · Input contract · Unified environments · Atomic planning · Predict Position replay · Shooting replay
Roadmap
- One unified checkpoint for Maze, Snake and both shooting tasks.
- 50×50 Maze, long Snake games and synchronized three-model browser replays.
- Mixed-task SFT, reproducible data splits and independently replayed evaluation.
- RLCD post-training for broader long-horizon tasks.
- Shared-prefix inference and larger candidate batches.
- Broader shooting scenarios and structured input support.

 Jev 的 nano 复刻版:一个 0.6B 参数的并行决策模型,输入状态和问题,直接输出完整的概率分布——全程不解码任何输出 token。