Update: Due to many automatically generated and irrelevant issues submitted to this repo (that have been deleted now) and our limited capacity to properly maintain this repo, we have to temporaliy archive (make read-only) this and several other repos.
Less is More: Recursive Reasoning with Tiny Networks
This is the codebase for the paper: "Less is More: Recursive Reasoning with Tiny Networks". TRM is a recursive reasoning approach that achieves amazing scores of 45% on ARC-AGI-1 and 8% on ARC-AGI-2 using a tiny 7M parameters neural network.
Paper
Motivation
Tiny Recursion Model (TRM) is a recursive reasoning model that achieves amazing scores of 45% on ARC-AGI-1 and 8% on ARC-AGI-2 with a tiny 7M parameters neural network. The idea that one must rely on massive foundational models trained for millions of dollars by some big corporation in order to achieve success on hard tasks is a trap. Currently, there is too much focus on exploiting LLMs rather than devising and expanding new lines of direction. With recursive reasoning, it turns out that “less is more”: you don’t always need to crank up model size in order for a model to reason and solve hard problems. A tiny model pretrained from scratch, recursing on itself and updating its answers over time, can achieve a lot without breaking the bank.
This work came to be after I learned about the recent innovative Hierarchical Reasoning Model (HRM). I was amazed that an approach using small models could do so well on hard tasks like the ARC-AGI competition (reaching 40% accuracy when normally only Large Language Models could compete). But I kept thinking that it is too complicated, relying too much on biological arguments about the human brain, and that this recursive reasoning process could be greatly simplified and improved. Tiny Recursion Model (TRM) simplifies recursive reasoning to its core essence, which ultimately has nothing to do with the human brain, does not require any mathematical (fixed-point) theorem, nor any hierarchy.
How TRM works
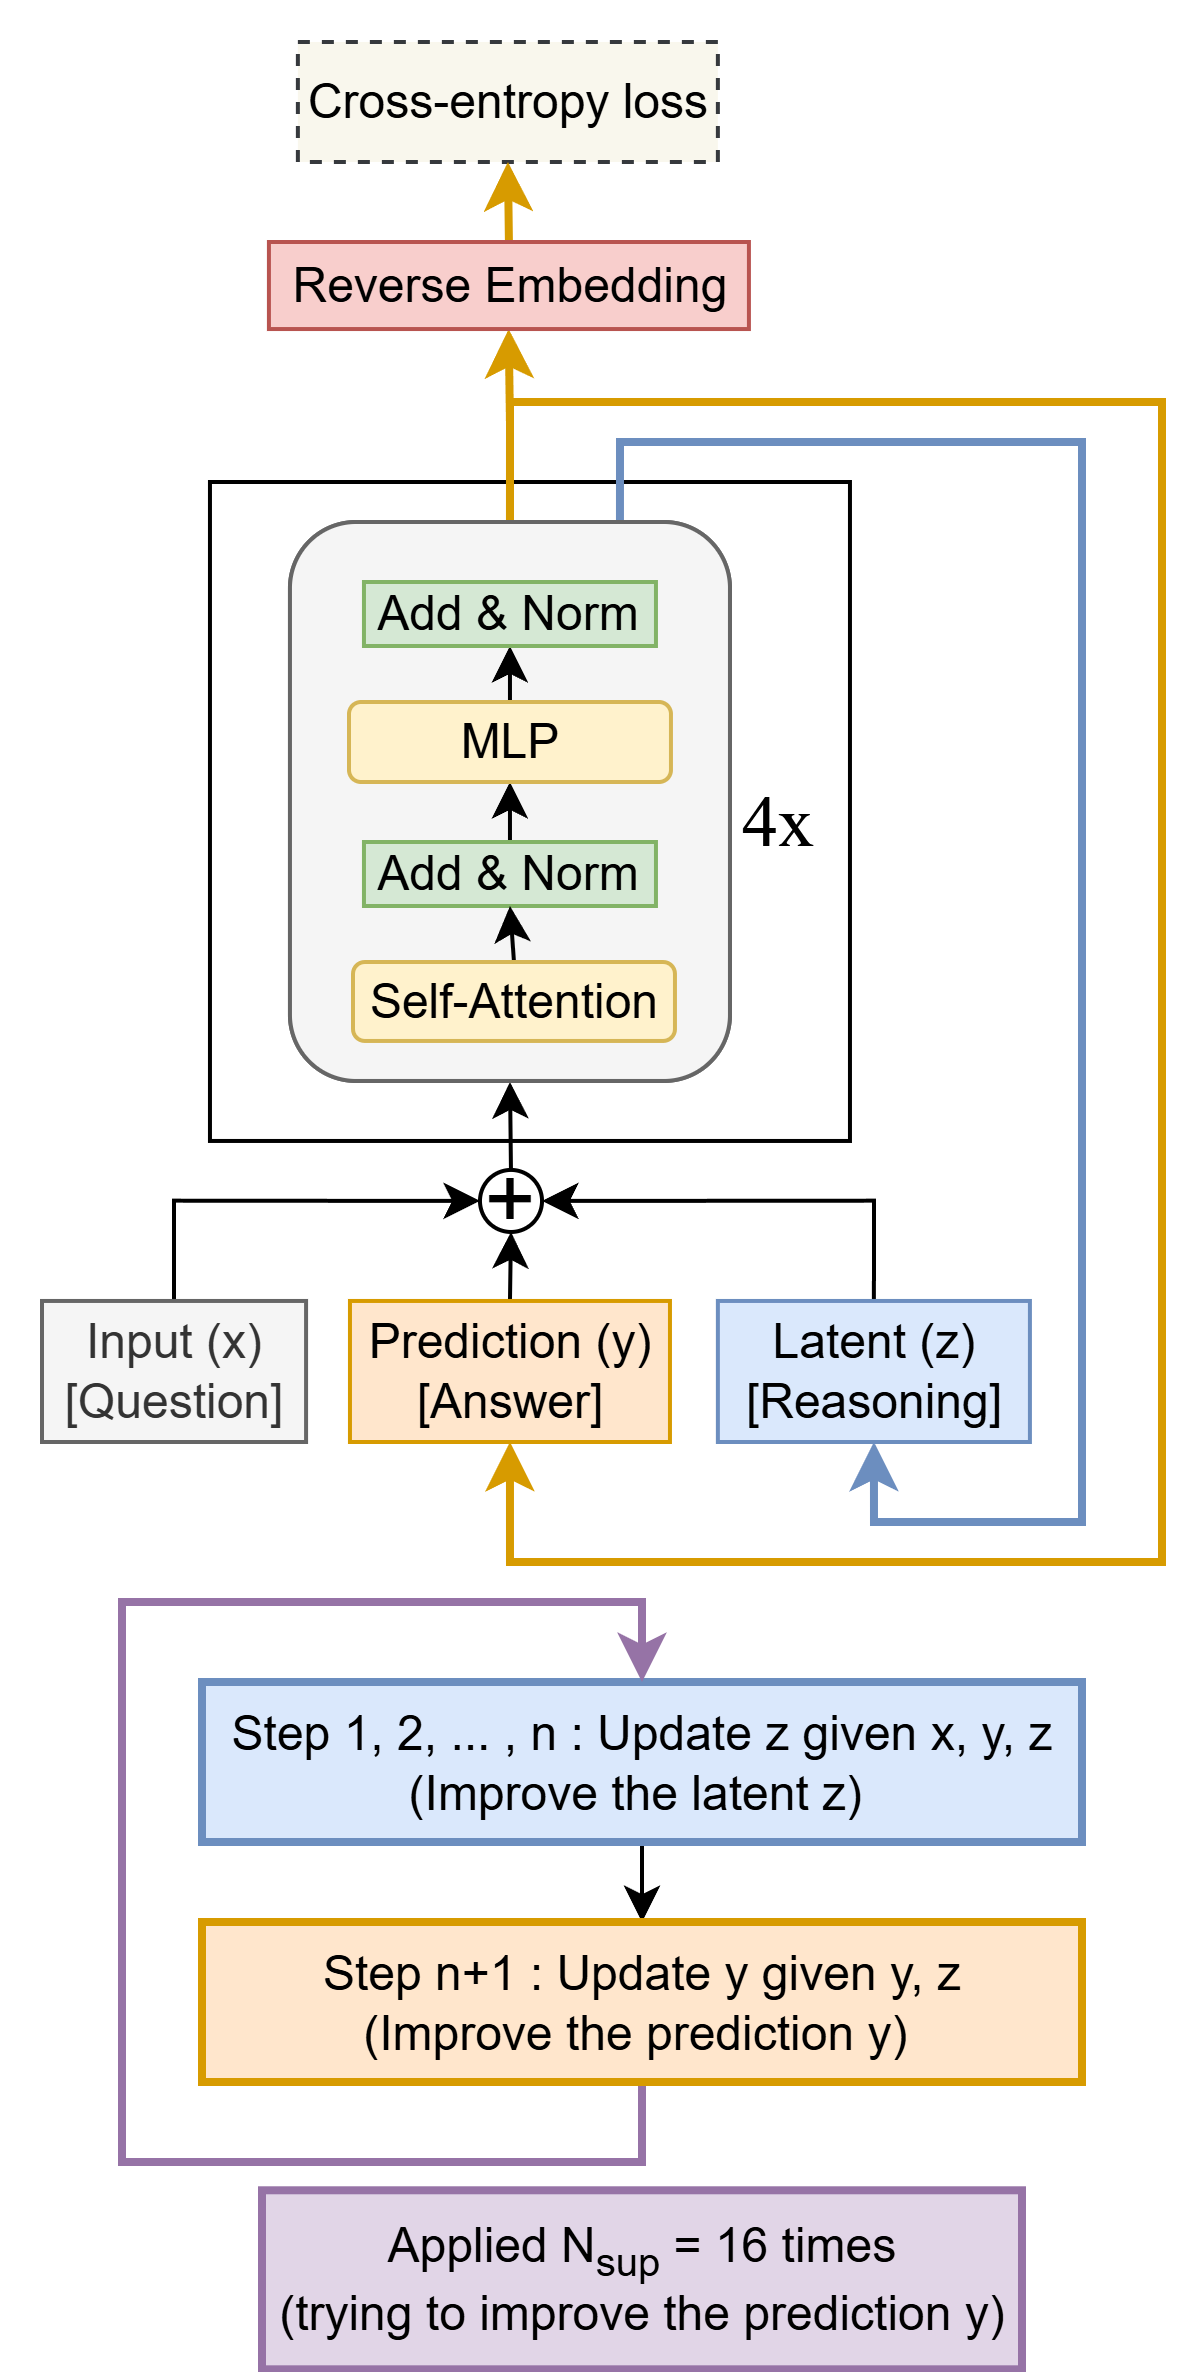
Tiny Recursion Model (TRM) recursively improves its predicted answer y with a tiny network. It starts with the embedded input question x and initial embedded answer y and latent z. For up to K improvements steps, it tries to improve its answer y. It does so by i) recursively updating n times its latent z given the question x, current answer y, and current latent z (recursive reasoning), and then ii) updating its answer y given the current answer y and current latent z. This recursive process allows the model to progressively improve its answer (potentially addressing any errors from its previous answer) in an extremely parameter-efficient manner while minimizing overfitting.
Requirements
Installation should take a few minutes. For the smallest experiments on Sudoku-Extreme (pretrain_mlp_t_sudoku), you need 1 GPU with enough memory. With 1 L40S (48Gb Ram), it takes around 18h to finish. In case that you run into issues due to library versions, here is the requirements with the exact versions used: specific_requirements.txt.
- Python 3.10 (or similar)
- Cuda 12.6.0 (or similar)
pip install --upgrade pip wheel setuptools
pip install --pre --upgrade torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/cu126 # install torch based on your cuda version
pip install -r requirements.txt # install requirements
pip install --no-cache-dir --no-build-isolation adam-atan2
wandb login YOUR-LOGIN # login if you want the logger to sync results to your Weights & Biases (https://wandb.ai/)
Dataset Preparation
# ARC-AGI-1
python -m dataset.build_arc_dataset \
  --input-file-prefix kaggle/combined/arc-agi \
  --output-dir data/arc1concept-aug-1000 \
  --subsets training evaluation concept \
  --test-set-name evaluation

# ARC-AGI-2
python -m dataset.build_arc_dataset \
  --input-file-prefix kaggle/combined/arc-agi \
  --output-dir data/arc2concept-aug-1000 \
  --subsets training2 evaluation2 concept \
  --test-set-name evaluation2

## Note: You cannot train on both ARC-AGI-1 and ARC-AGI-2 and evaluate them both because ARC-AGI-2 training data contains some ARC-AGI-1 eval data

# Sudoku-Extreme
python dataset/build_sudoku_dataset.py --output-dir data/sudoku-extreme-1k-aug-1000  --subsample-size 1000 --num-aug 1000  # 1000 examples, 1000 augments

# Maze-Hard
python dataset/build_maze_dataset.py # 1000 examples, 8 augments
Experiments
Sudoku-Extreme (assuming 1 L40S GPU):
run_name="pretrain_mlp_t_sudoku"
python pretrain.py \
arch=trm \
data_paths="[data/sudoku-extreme-1k-aug-1000]" \
evaluators="[]" \
epochs=50000 eval_interval=5000 \
lr=1e-4 puzzle_emb_lr=1e-4 weight_decay=1.0 puzzle_emb_weight_decay=1.0 \
arch.mlp_t=True arch.pos_encodings=none \
arch.L_layers=2 \
arch.H_cycles=3 arch.L_cycles=6 \
+run_name=${run_name} ema=True

Expected: Around 87% exact-accuracy (+- 2%)

run_name="pretrain_att_sudoku"
python pretrain.py \
arch=trm \
data_paths="[data/sudoku-extreme-1k-aug-1000]" \
evaluators="[]" \
epochs=50000 eval_interval=5000 \
lr=1e-4 puzzle_emb_lr=1e-4 weight_decay=1.0 puzzle_emb_weight_decay=1.0 \
arch.L_layers=2 \
arch.H_cycles=3 arch.L_cycles=6 \
+run_name=${run_name} ema=True
Expected: Around 75% exact-accuracy (+- 2%)
Runtime: < 20 hours
Maze-Hard (assuming 4 L40S GPUs):
run_name="pretrain_att_maze30x30"
torchrun --nproc-per-node 4 --rdzv_backend=c10d --rdzv_endpoint=localhost:0 --nnodes=1 pretrain.py \
arch=trm \
data_paths="[data/maze-30x30-hard-1k]" \
evaluators="[]" \
epochs=50000 eval_interval=5000 \
lr=1e-4 puzzle_emb_lr=1e-4 weight_decay=1.0 puzzle_emb_weight_decay=1.0 \
arch.L_layers=2 \
arch.H_cycles=3 arch.L_cycles=4 \
+run_name=${run_name} ema=True
Runtime: < 24 hours
Actually, you can run Maze-Hard with 1 L40S GPU by reducing the batch-size with no noticable loss in performance:
run_name="pretrain_att_maze30x30_1gpu"
python pretrain.py \
arch=trm \
data_paths="[data/maze-30x30-hard-1k]" \
evaluators="[]" \
epochs=50000 eval_interval=5000 \
lr=1e-4 puzzle_emb_lr=1e-4 weight_decay=1.0 puzzle_emb_weight_decay=1.0 global_batch_size=128 \
arch.L_layers=2 \
arch.H_cycles=3 arch.L_cycles=4 \
+run_name=${run_name} ema=True
Runtime: < 24 hours
ARC-AGI-1 (assuming 4 H-100 GPUs):
run_name="pretrain_att_arc1concept_4"
torchrun --nproc-per-node 4 --rdzv_backend=c10d --rdzv_endpoint=localhost:0 --nnodes=1 pretrain.py \
arch=trm \
data_paths="[data/arc1concept-aug-1000]" \
arch.L_layers=2 \
arch.H_cycles=3 arch.L_cycles=4 \
+run_name=${run_name} ema=True
Runtime: ~3 days
ARC-AGI-2 (assuming 4 H-100 GPUs):
run_name="pretrain_att_arc2concept_4"
torchrun --nproc-per-node 4 --rdzv_backend=c10d --rdzv_endpoint=localhost:0 --nnodes=1 pretrain.py \
arch=trm \
data_paths="[data/arc2concept-aug-1000]" \
arch.L_layers=2 \
arch.H_cycles=3 arch.L_cycles=4 \
+run_name=${run_name} ema=True
Runtime: ~3 days
Reference
If you find our work useful, please consider citing:
@misc{jolicoeurmartineau2025morerecursivereasoningtiny,
      title={Less is More: Recursive Reasoning with Tiny Networks},
      author={Alexia Jolicoeur-Martineau},
      year={2025},
      eprint={2510.04871},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2510.04871},
}
and the Hierarchical Reasoning Model (HRM):
@misc{wang2025hierarchicalreasoningmodel,
      title={Hierarchical Reasoning Model},
      author={Guan Wang and Jin Li and Yuhao Sun and Xing Chen and Changling Liu and Yue Wu and Meng Lu and Sen Song and Yasin Abbasi Yadkori},
      year={2025},
      eprint={2506.21734},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.21734},
}
This code is based on the Hierarchical Reasoning Model code and the Hierarchical Reasoning Model Analysis code.

 这是 TRM(Tiny Recursive Model,微型递归模型),论文《Less is More: Recursive Reasoning with Tiny Networks》的配套代码:一个只有 700 万参数的小型网络,通过递归推理在 ARC-AGI-1 上拿到 45%、在 ARC-AGI-2 上拿到 8% 的成绩。