📣 News
- [2026-10] 🤗 The ReSFT data (54,663 trajectories) and ORPO tasks (2,550 with skills) are now available on Hugging Face: SFT-54K · RL-2K.
- [2026-10] 🤗 The Agent-Reflex-8B checkpoint (Qwen3-8B, ReSFT + ORPO) is released.
- [2026-10] 🚀 Full codebase released: the RSD skill library (1,170 meta-skills), ReSFT and ORPO training recipes, and evaluation on six benchmarks.
- [2026-10] 📄 Our paper Agent-Reflex: Teaching Language Agents to Act Reflectively is now available on arXiv and Hugging Face Papers.
🎬 Demo
Agent-Reflex in One Minute
https://github.com/user-attachments/assets/281af1d3-843e-4496-b232-58fee951cefd
🎥 Download the 1080p video (60 seconds) · 💻 original task interactive replay (open locally in a browser)
💡 Overview
Agents are trained in idealized environments but deployed into noisy ones. Two gaps follow:
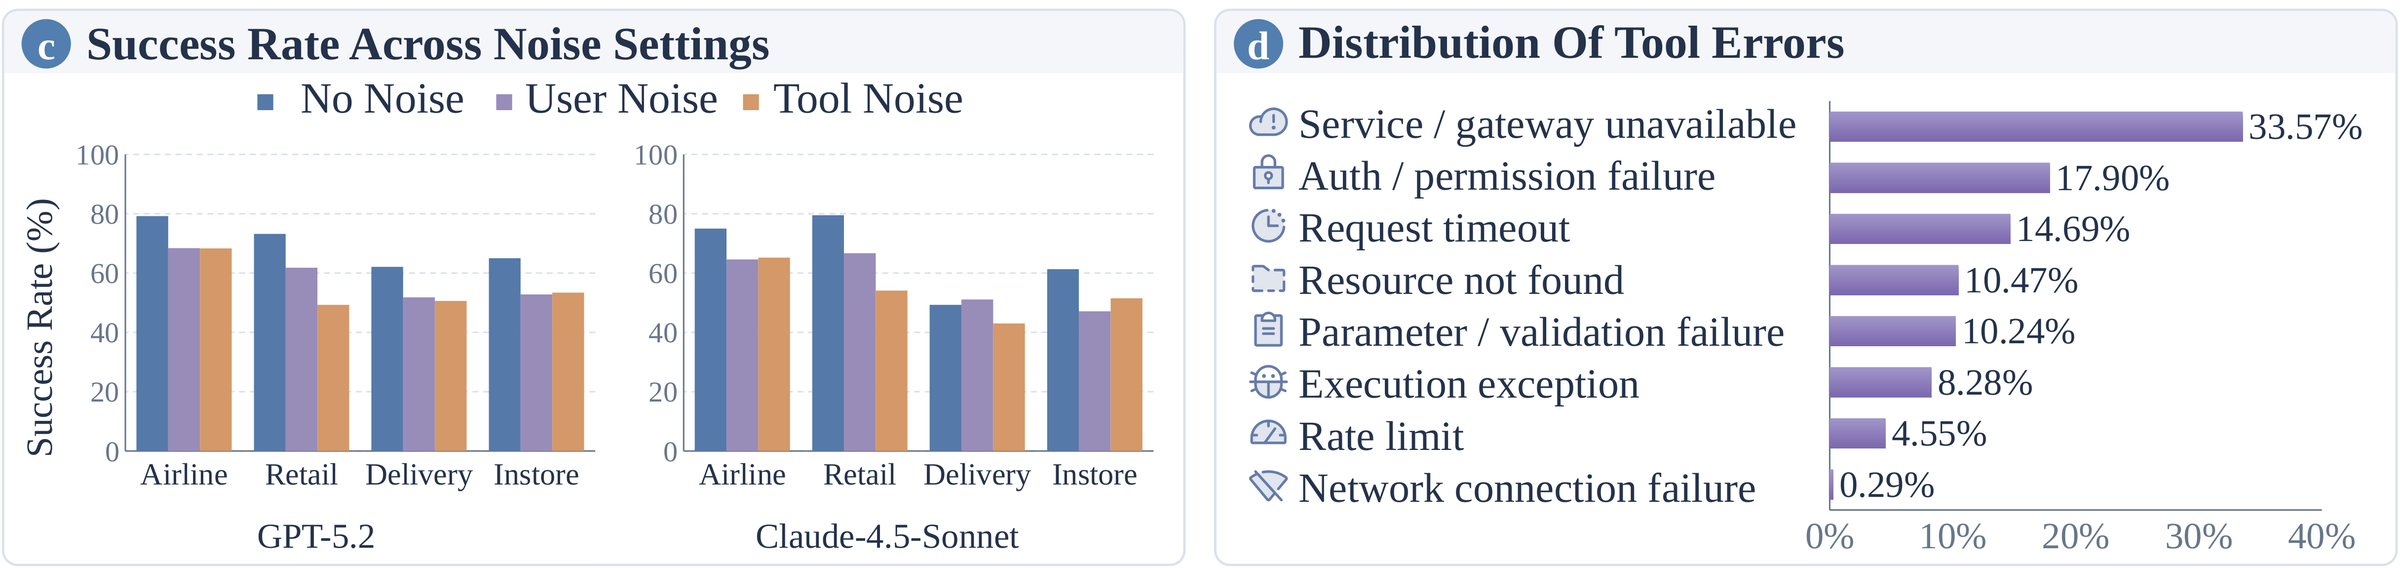
- (1) No noisy feedback. Real MCP tools time out, reject permissions or return malformed results, yet training environments return clean feedback, so agents never learn to detect and recover from failures.
- (2) No user correction. Real users interrupt and correct the agent mid-task, yet user simulators rarely issue such corrections.
Figure 1 (a, b) · The two gaps. Idealized interaction (a) vs. real-world interaction with user corrections and noisy feedback (b).
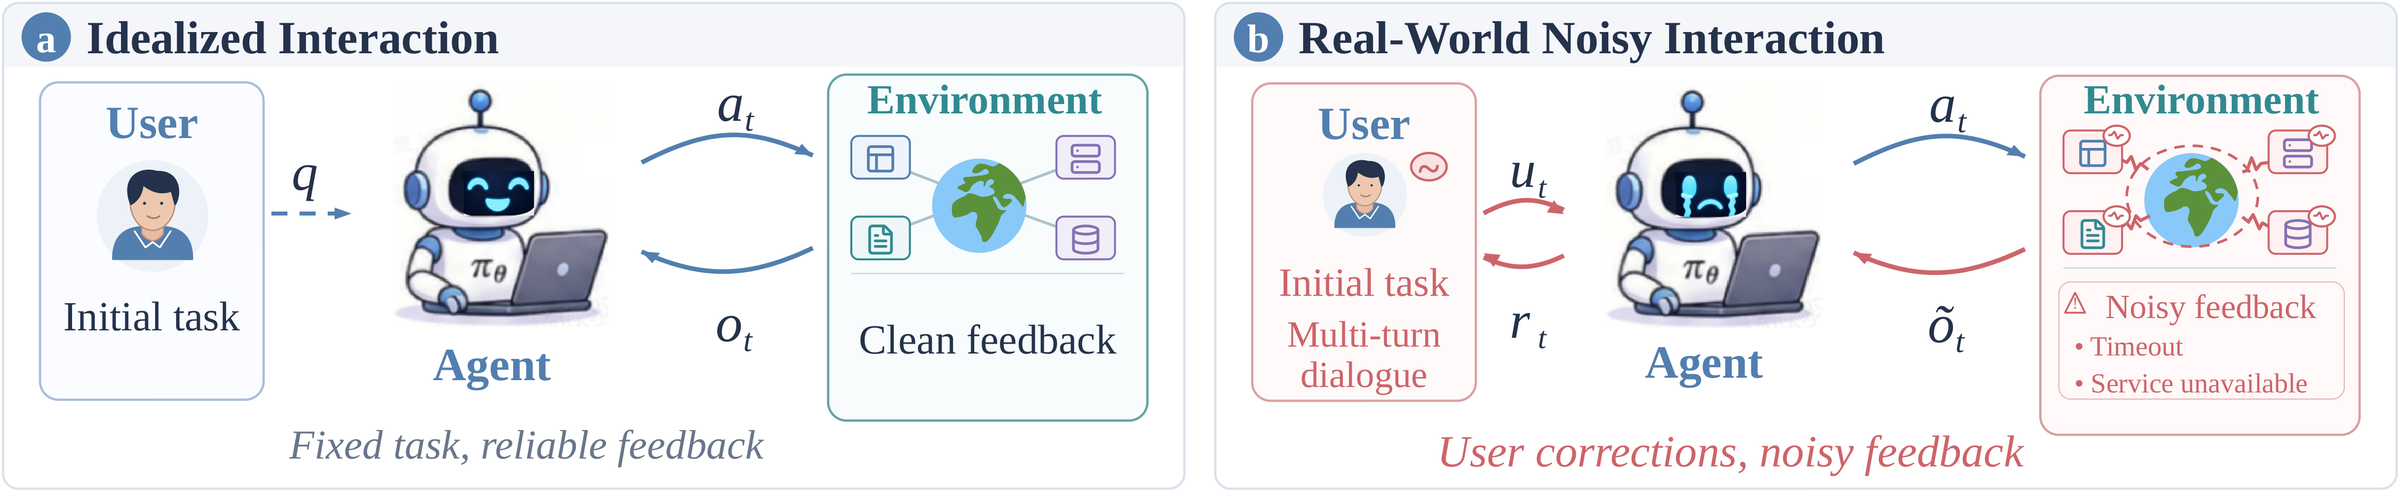
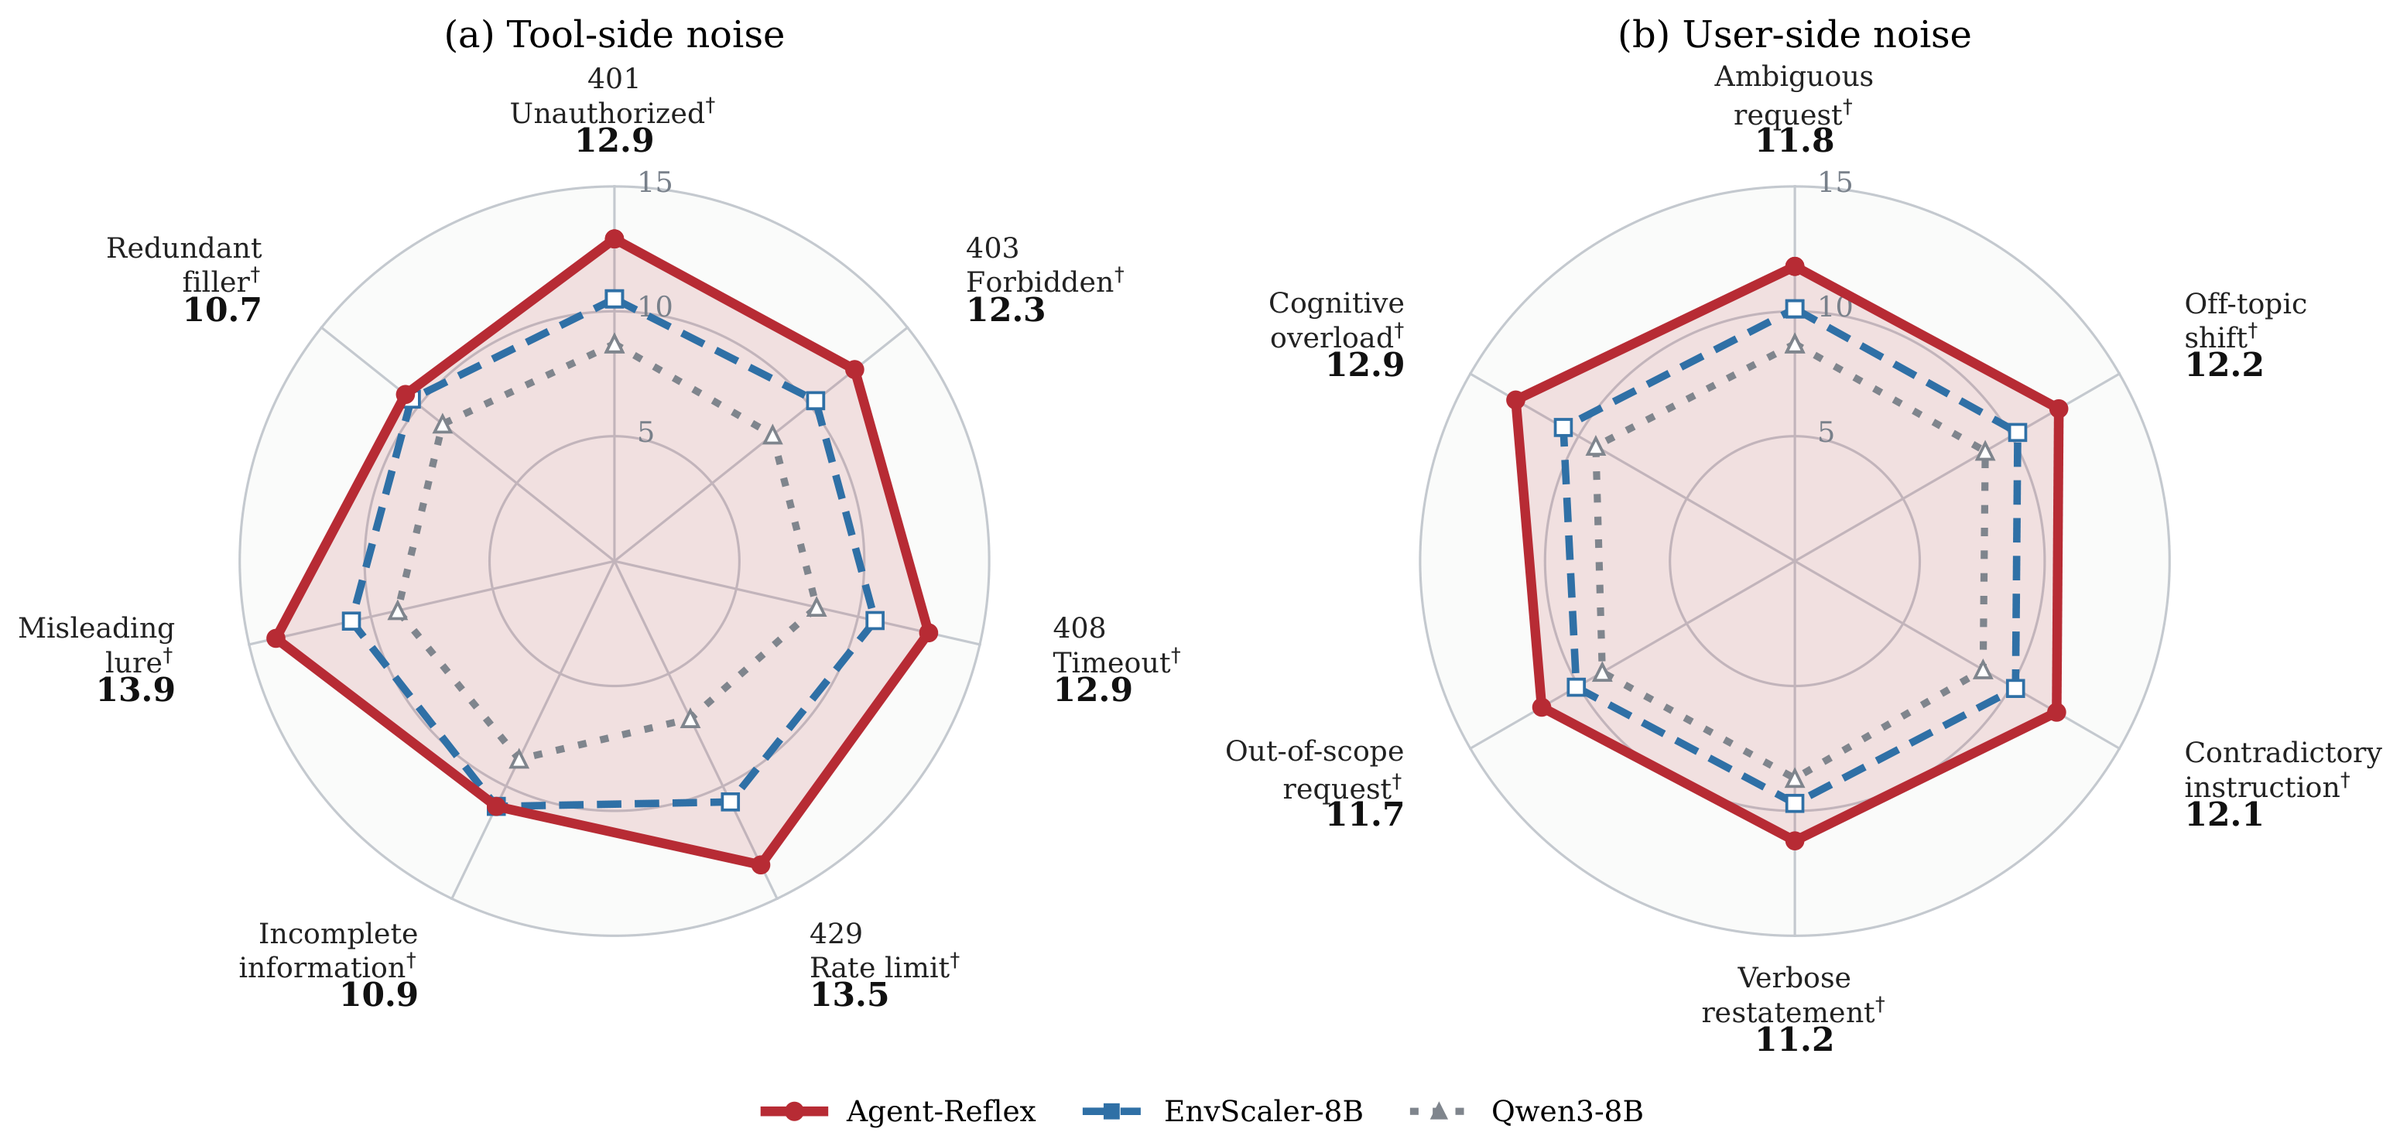
Figure 1 (c, d) · The cost of noise. Strong agents lose success rate under user or tool noise (c); tool errors fall into eight recurring families (d).
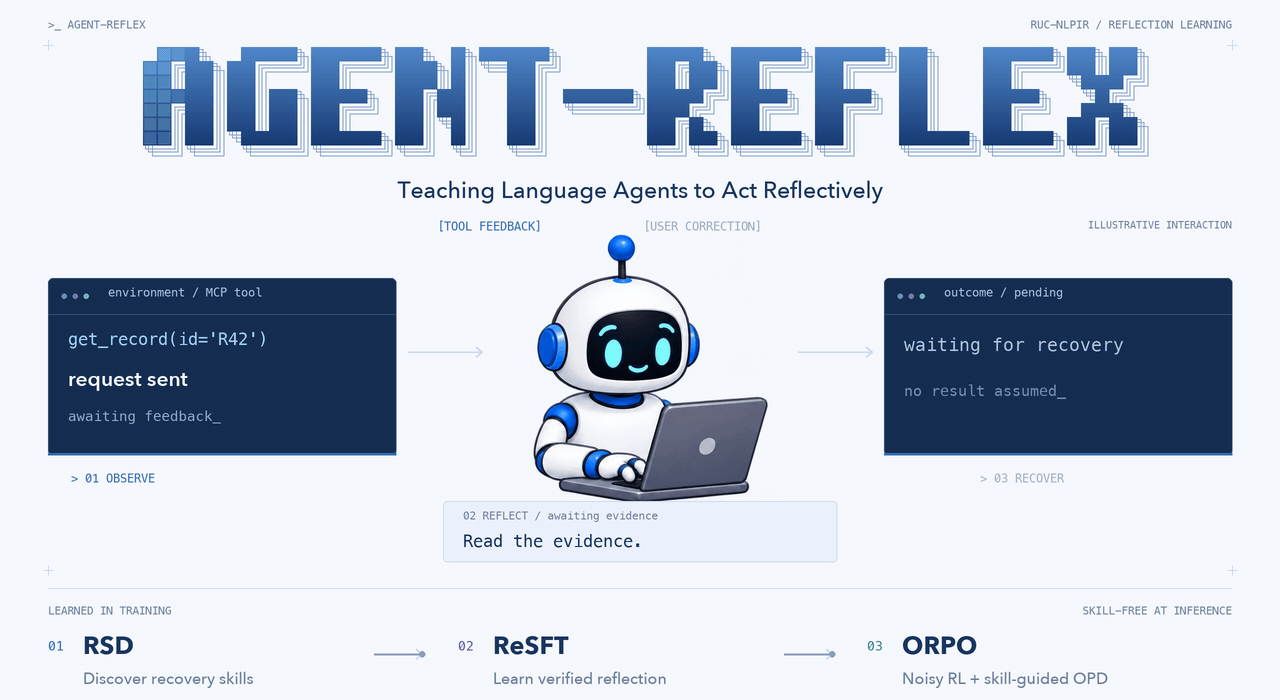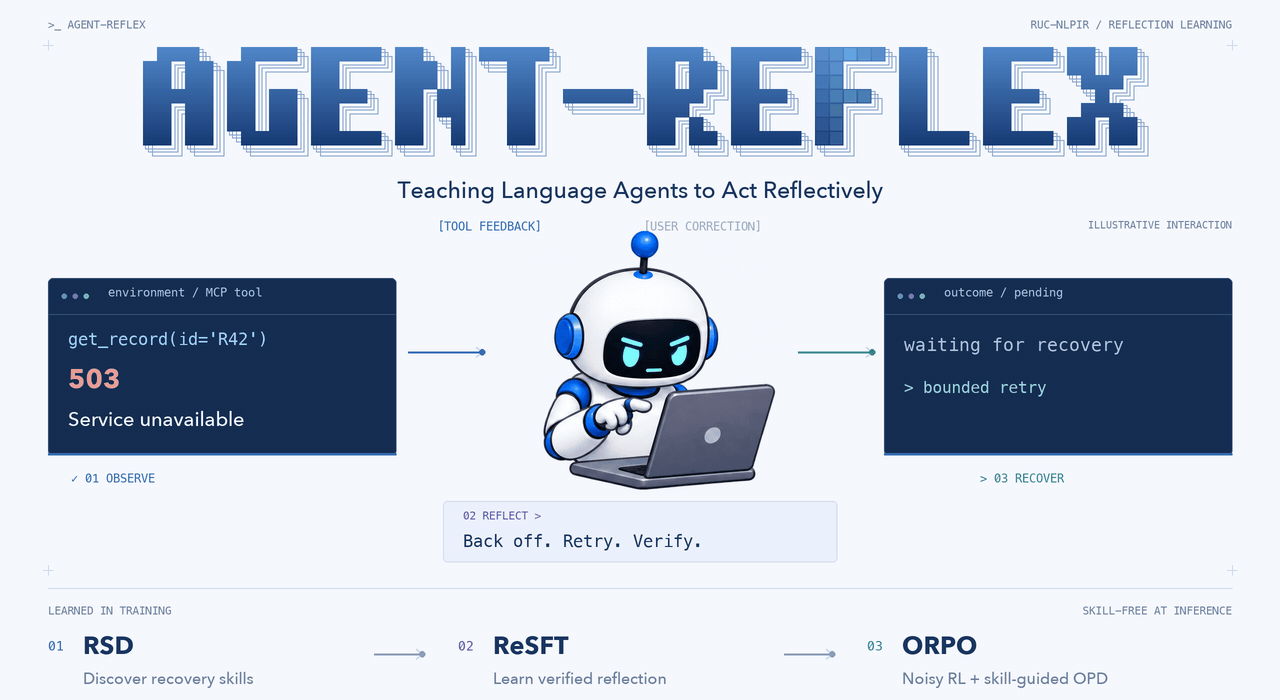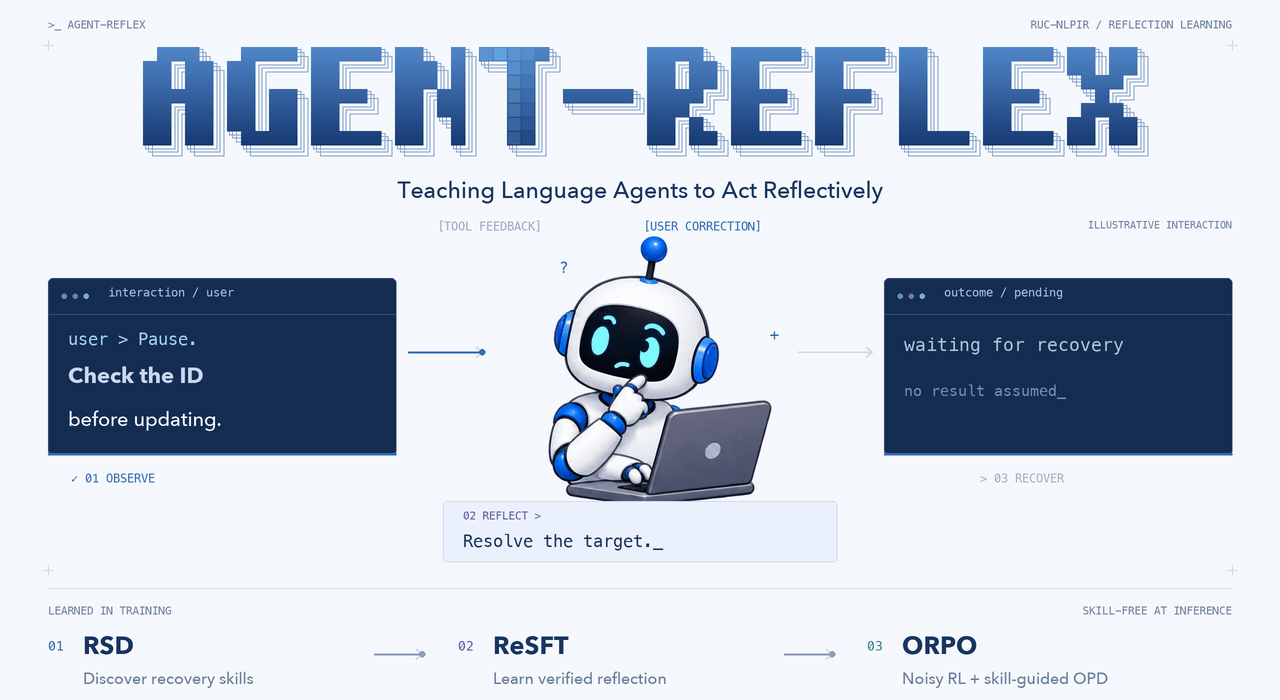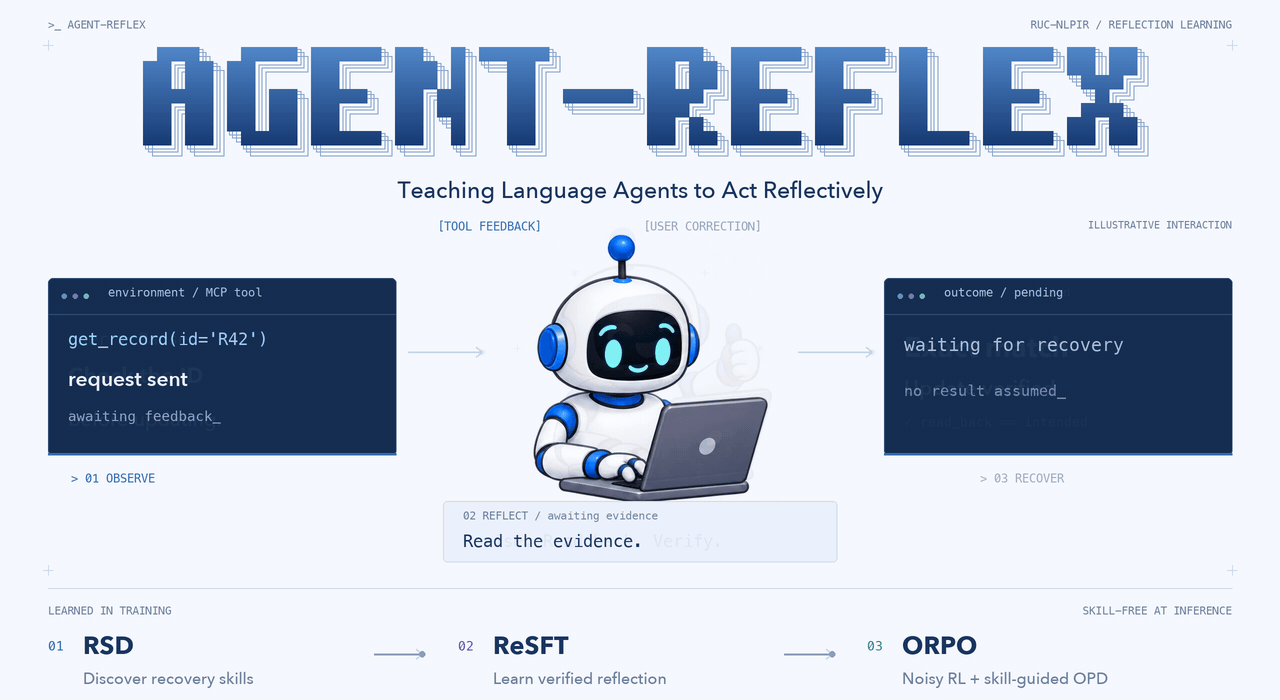
Agent-Reflex treats reflection as a learnable meta-skill: it mines skills from failures in noisy environments, distills them into supervised data and reinforces them with noisy agentic RL. On Qwen3-8B it improves six agent benchmarks and stays robust under noise.
✨ Agent-Reflex Framework
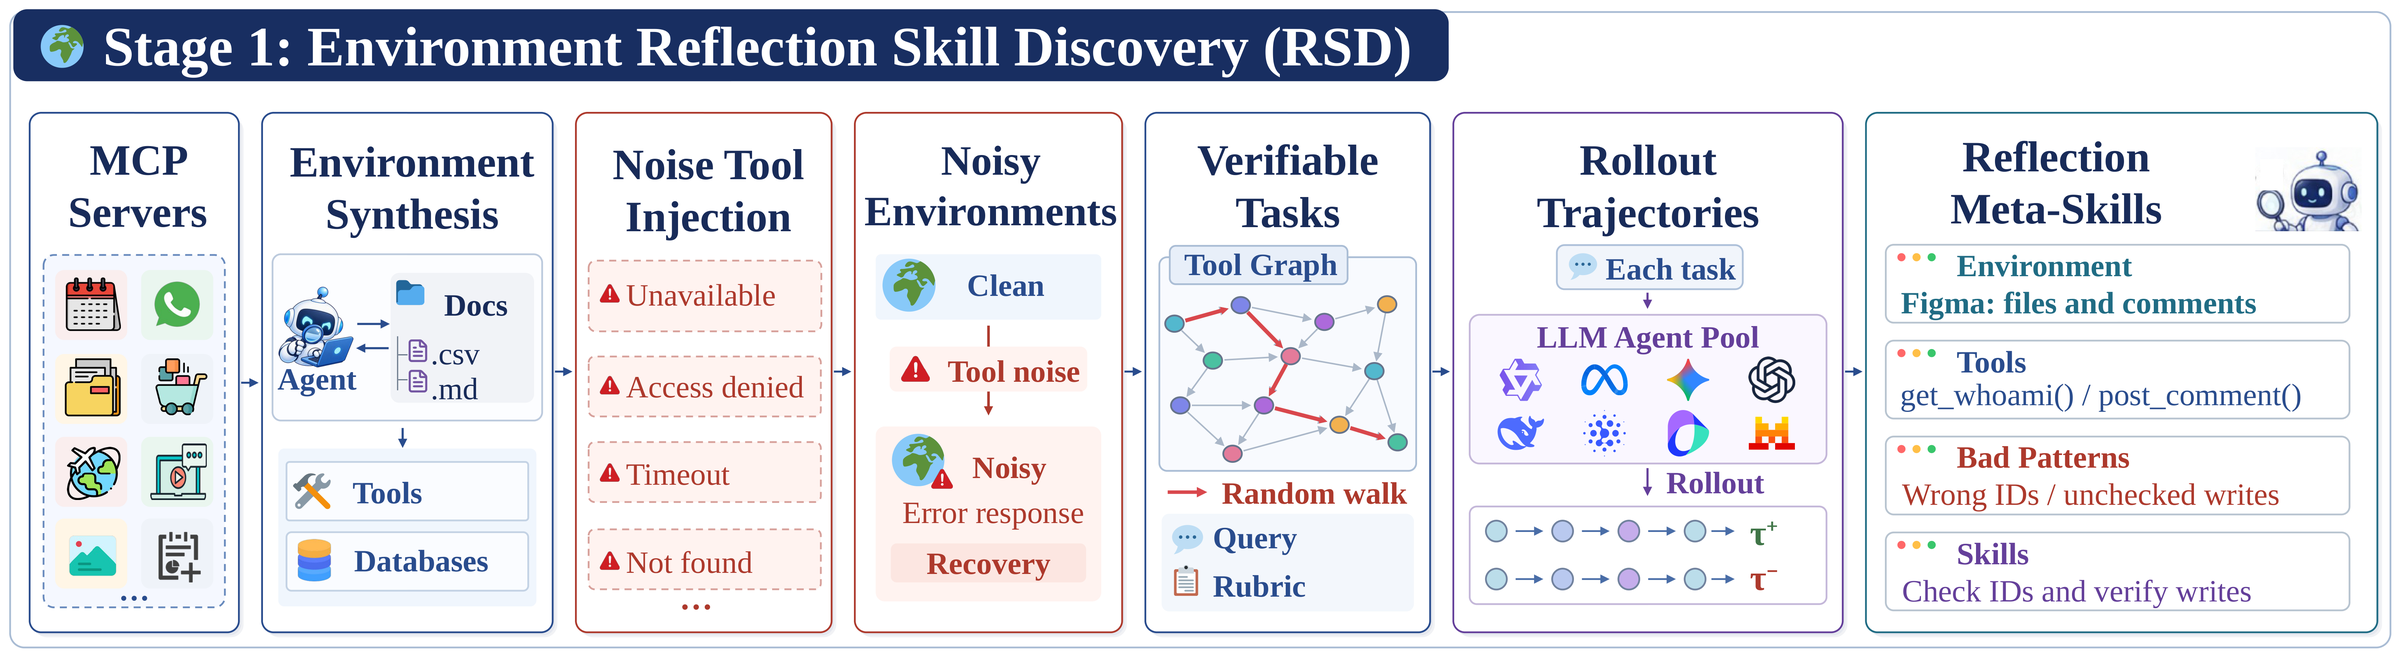
Stage 1 · Environment Reflection Skill Discovery (RSD)
Build failure-aware executable environments by perturbing tool returns with real-world failure families, and mine verifier-matched success / failure pairs into an offline library of 1,170 reflection meta-skills over 557 environments. Environment synthesis and the environment infrastructure follow Agent-World.
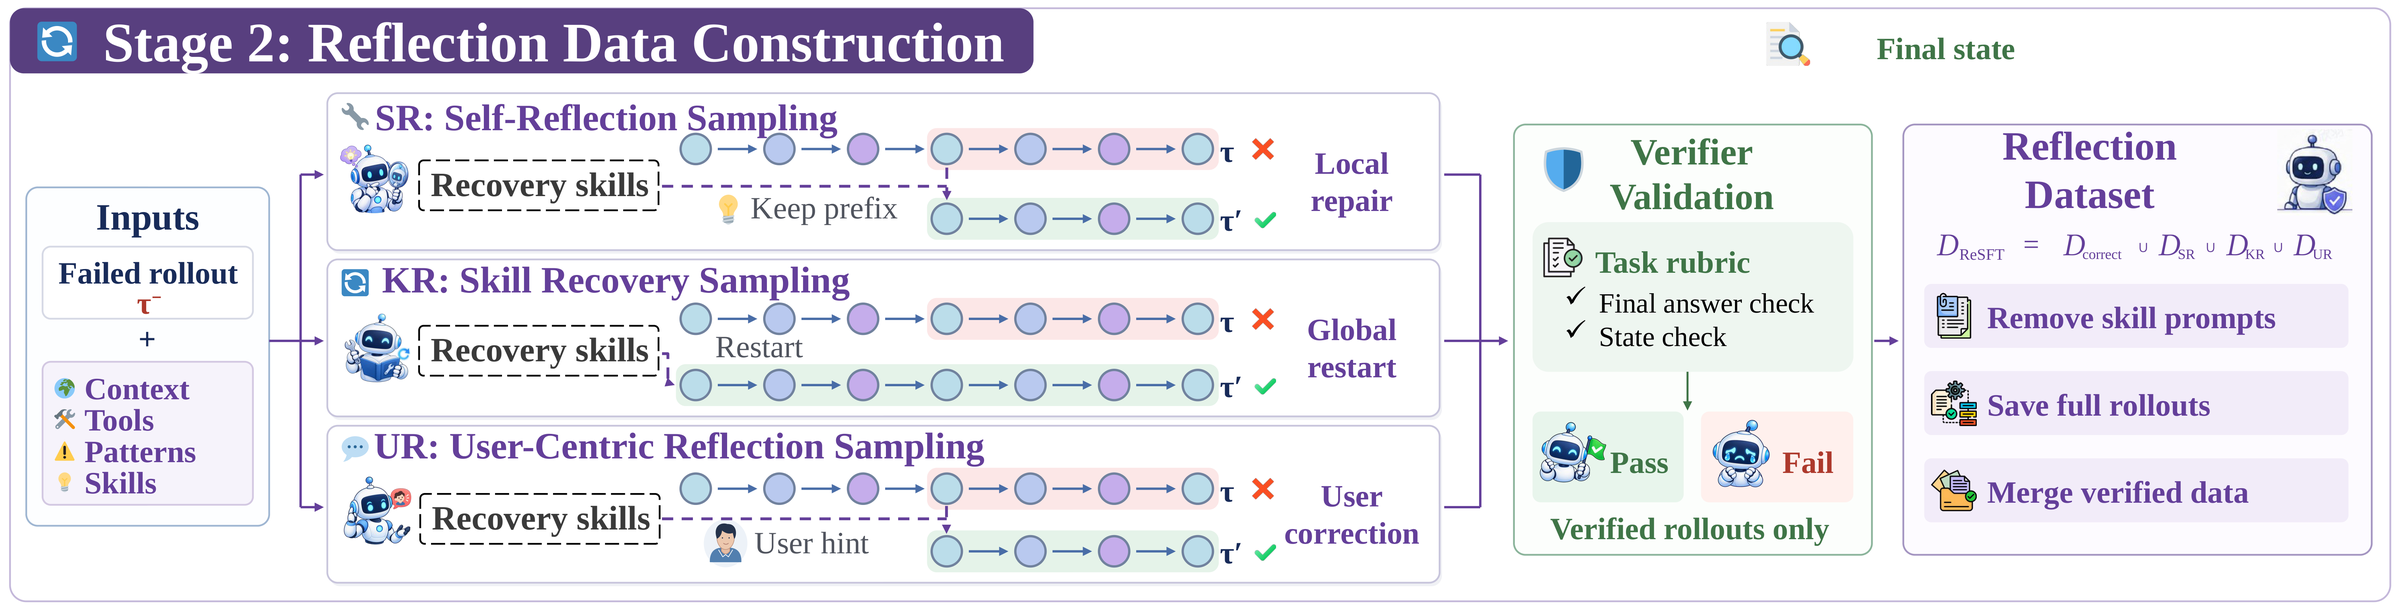
Stage 2 · Reflective Supervised Fine-Tuning (ReSFT)
Convert each skill into verifier-validated self-reflection (SR), skill recovery (KR) and user-correction (UR) data, with skill prompts stripped, and internalize them by supervised fine-tuning.
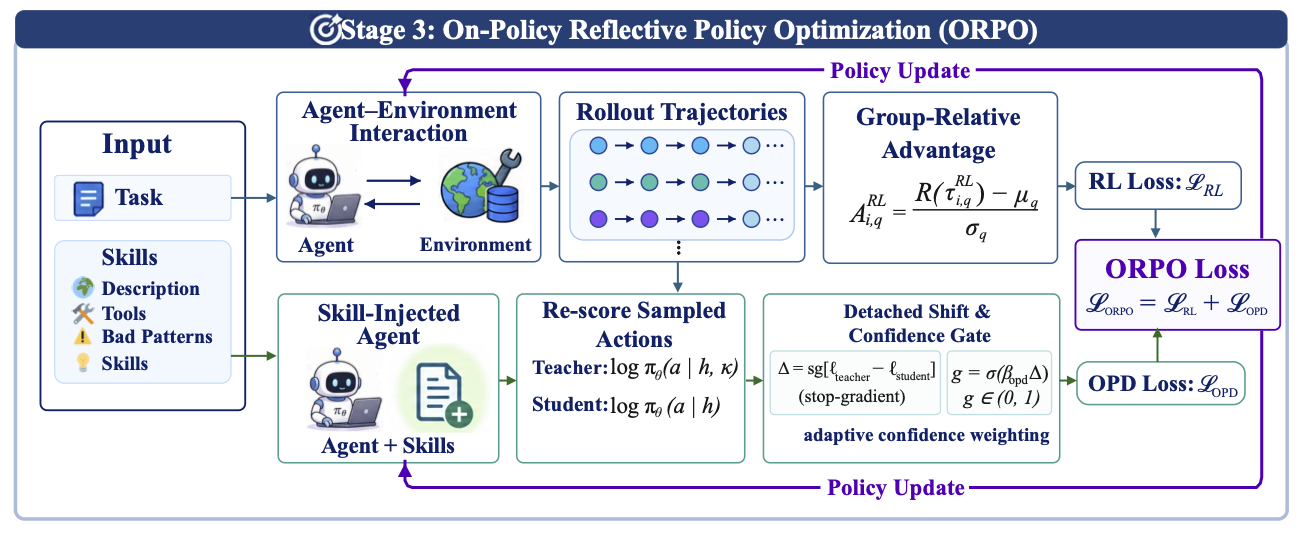
Stage 3 · On-Policy Reflective Policy Optimization (ORPO)
Combine Noisy Agent RL with same-token, skill-guided on-policy distillation (OPD) to provide dense reflection supervision. Skills are used only in training; the deployed agent is skill-free.
📊 Benchmarks & Results
We evaluate on six agent benchmarks under each benchmark's official metric:
- General Function Calling:
- BFCL V4 (paper): the Berkeley Function Calling Leaderboard extended to agentic evaluation (web search, memory, multi-turn, live / non-live, irrelevance); 5,217 tasks.
- ACEBench: normal, special and agentic tool use, emphasizing when to call a tool and how to handle underspecified requests.
- ToolSandbox: stateful, conversational tool use with implicit state dependencies, an LLM user simulator and deliberately unsolvable tasks; 200 offline scenarios.
- Long-Horizon Interactive Workflows:
- τ²-Bench: dual-control airline, retail and telecom domains where agent and user both act on shared state under a policy document.
- VitaBench: delivery, in-store and OTA domains plus cross-scenario tasks spanning domains within one episode.
- Noisy Interaction:
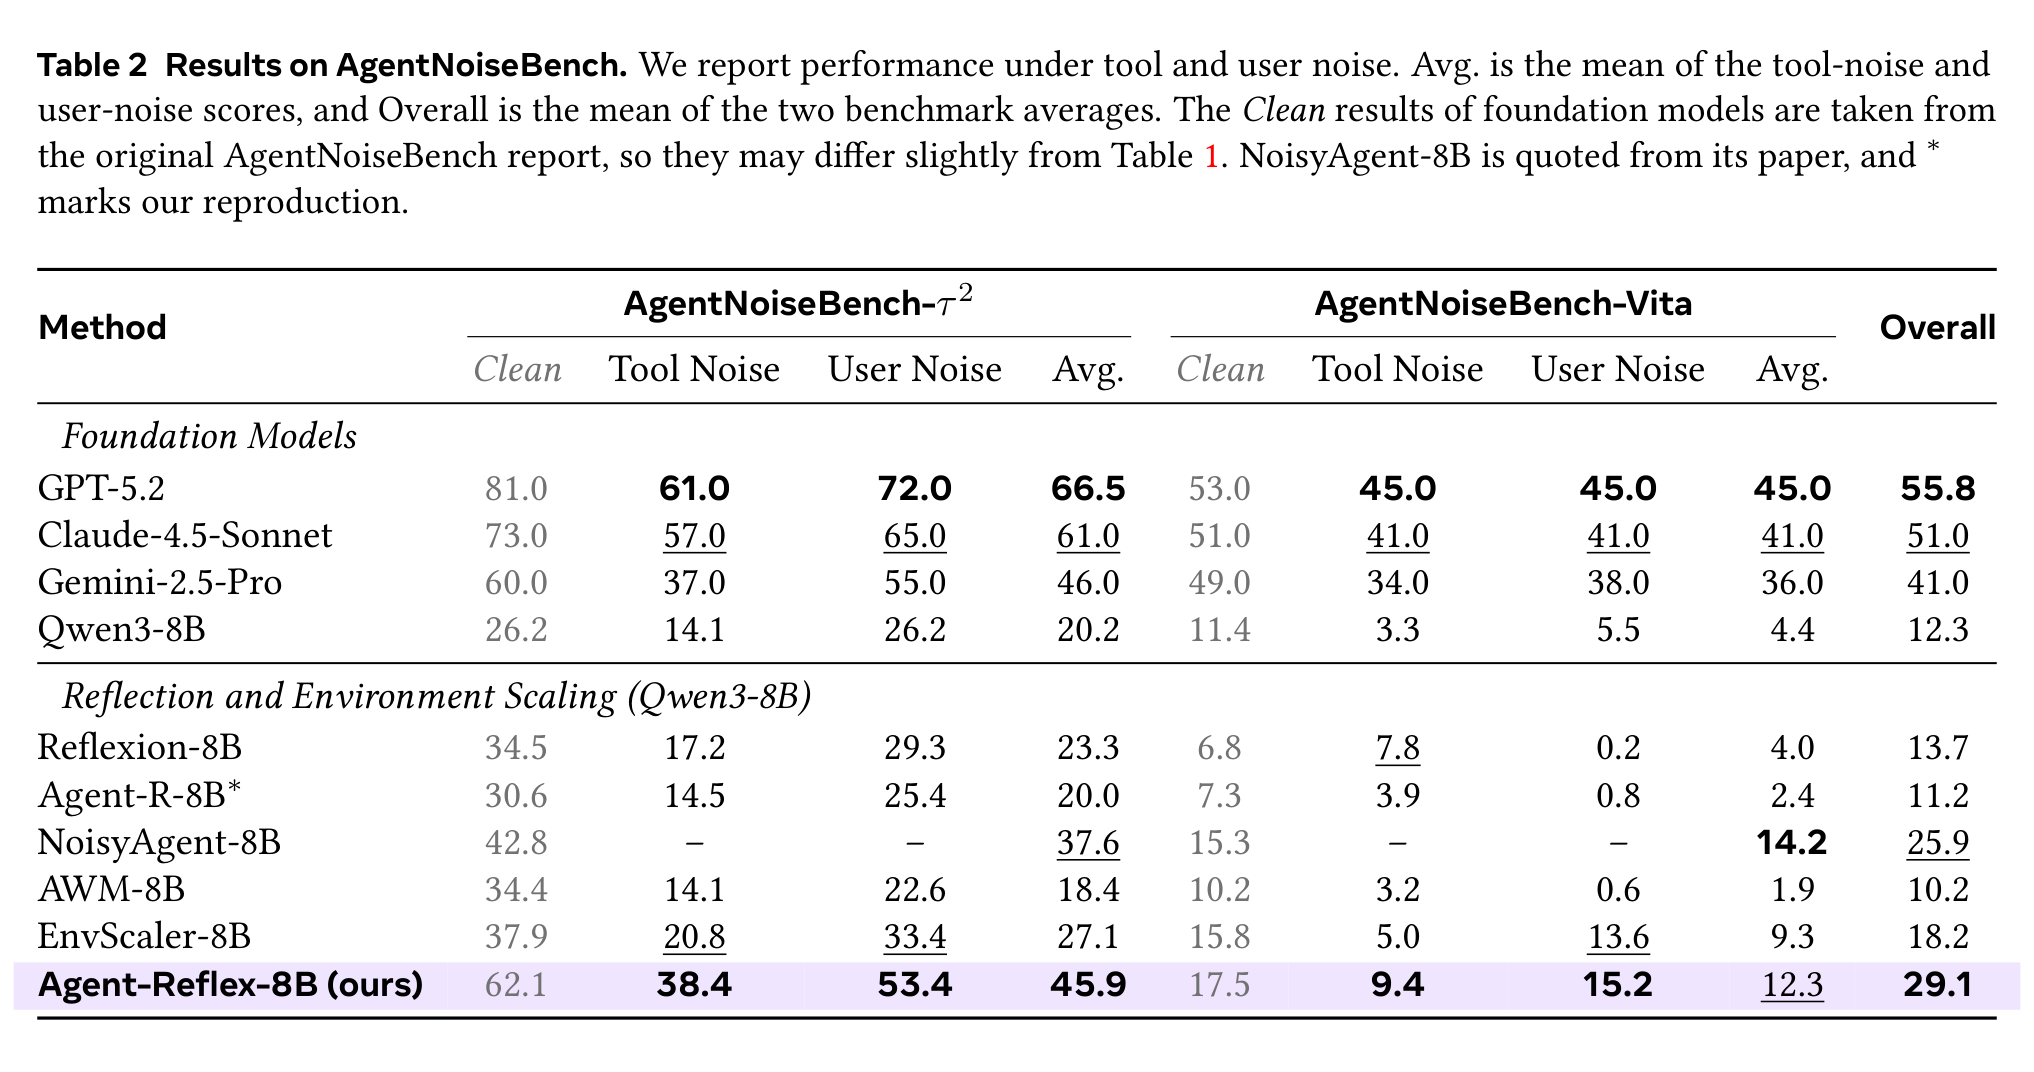
- AgentNoiseBench: tool-side and user-side perturbations injected into τ²-Bench and VitaBench environments.
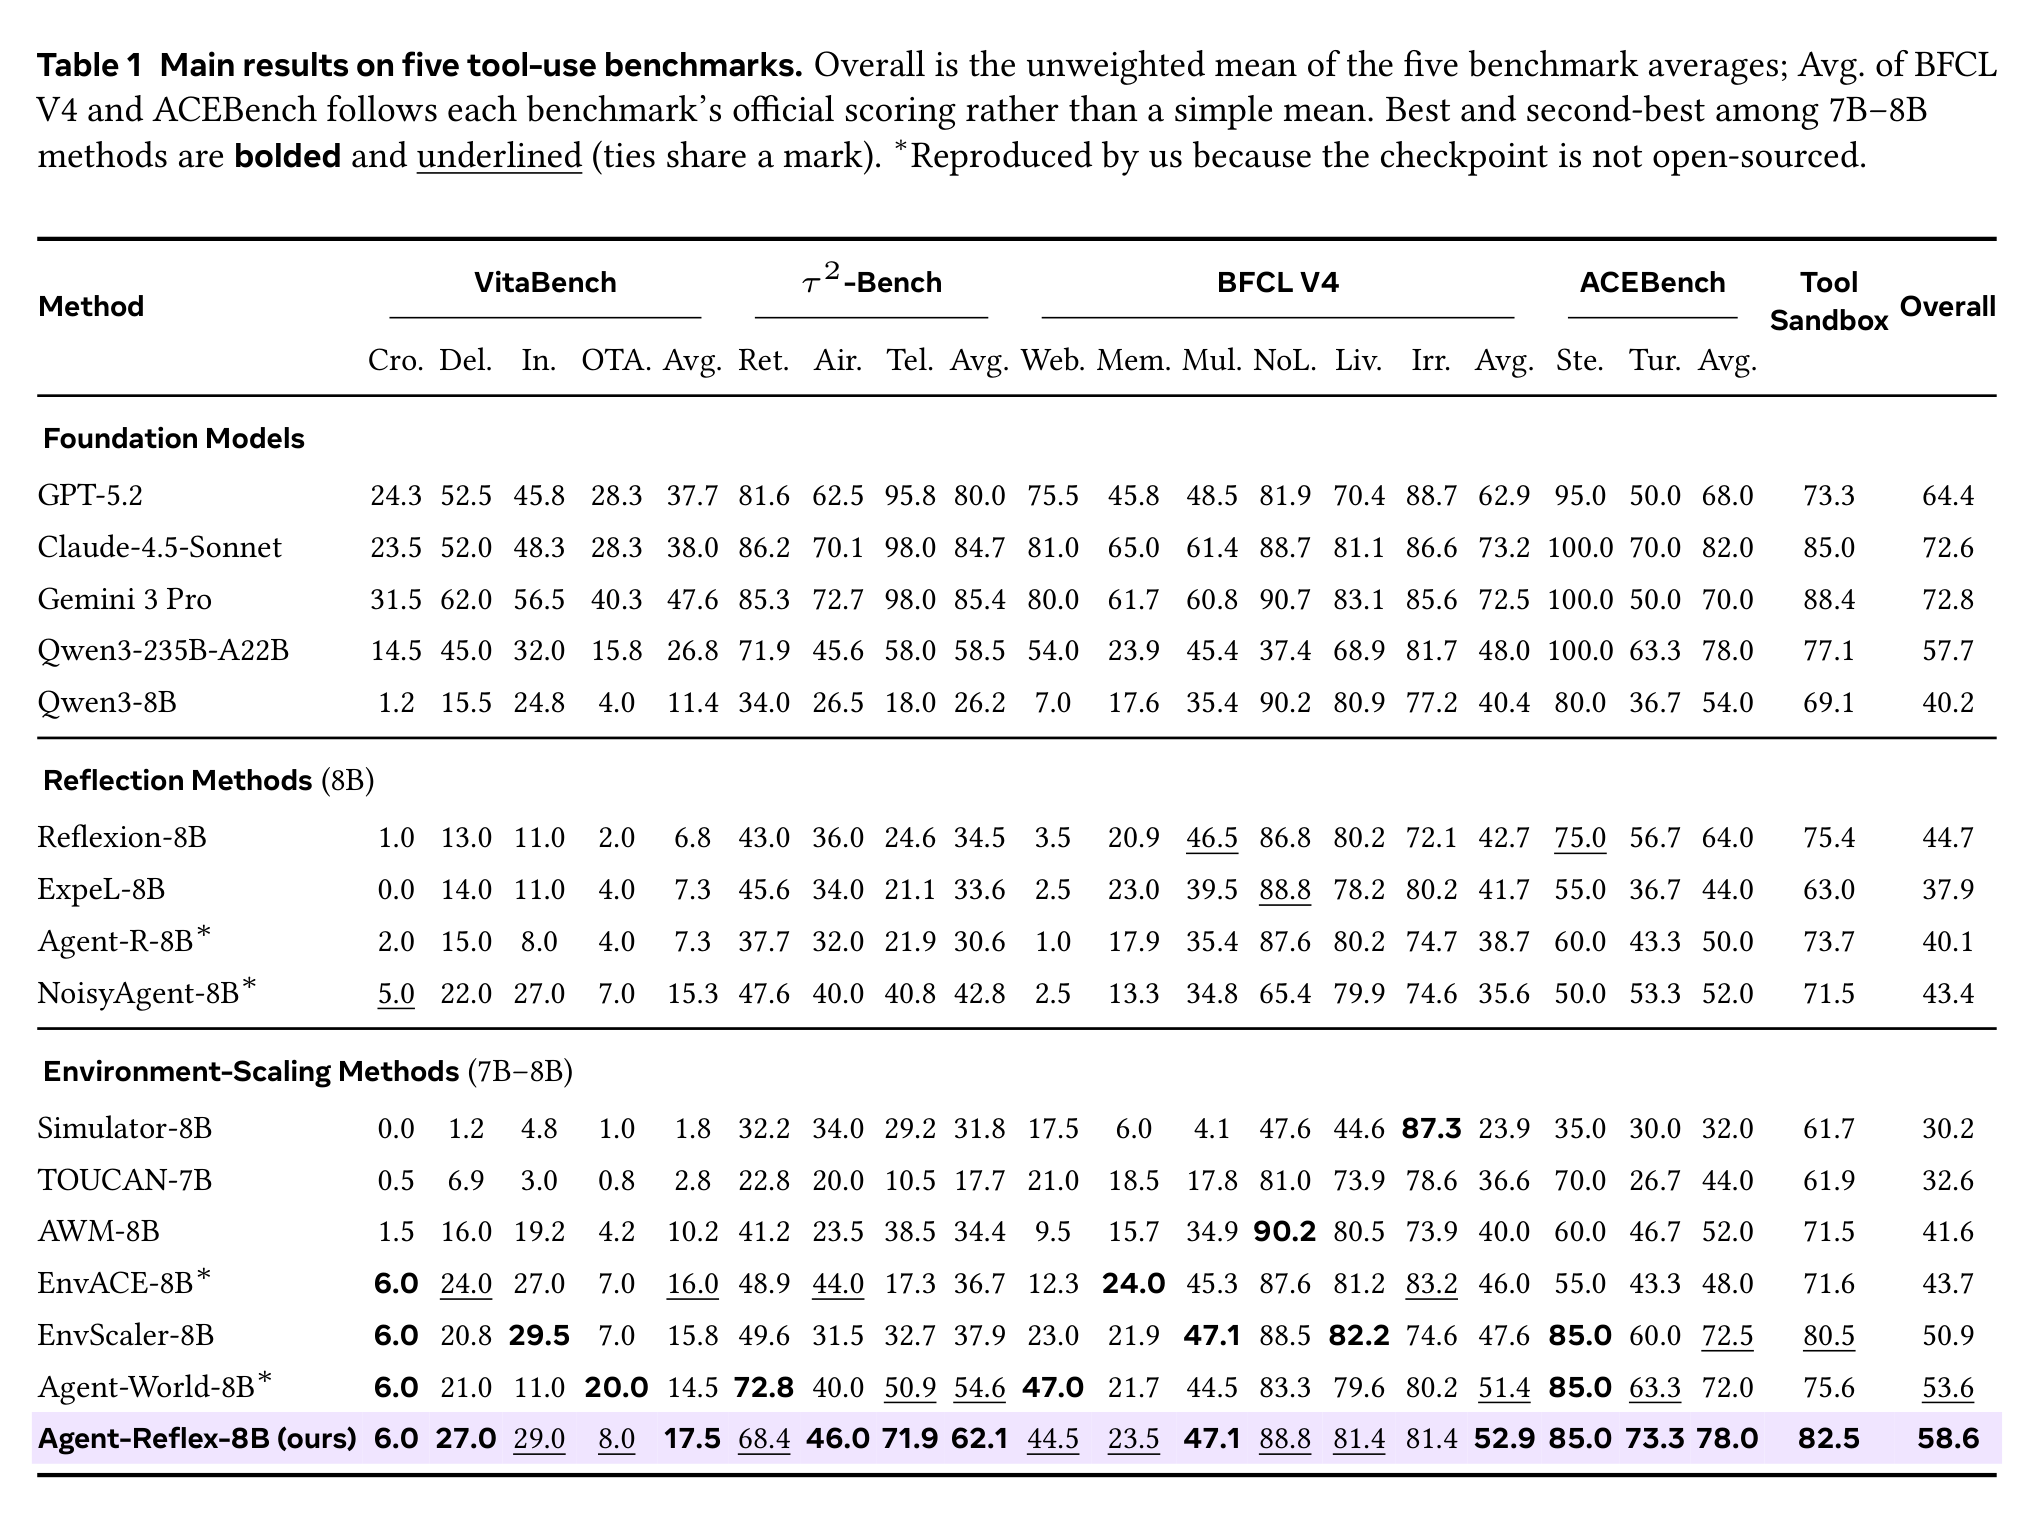
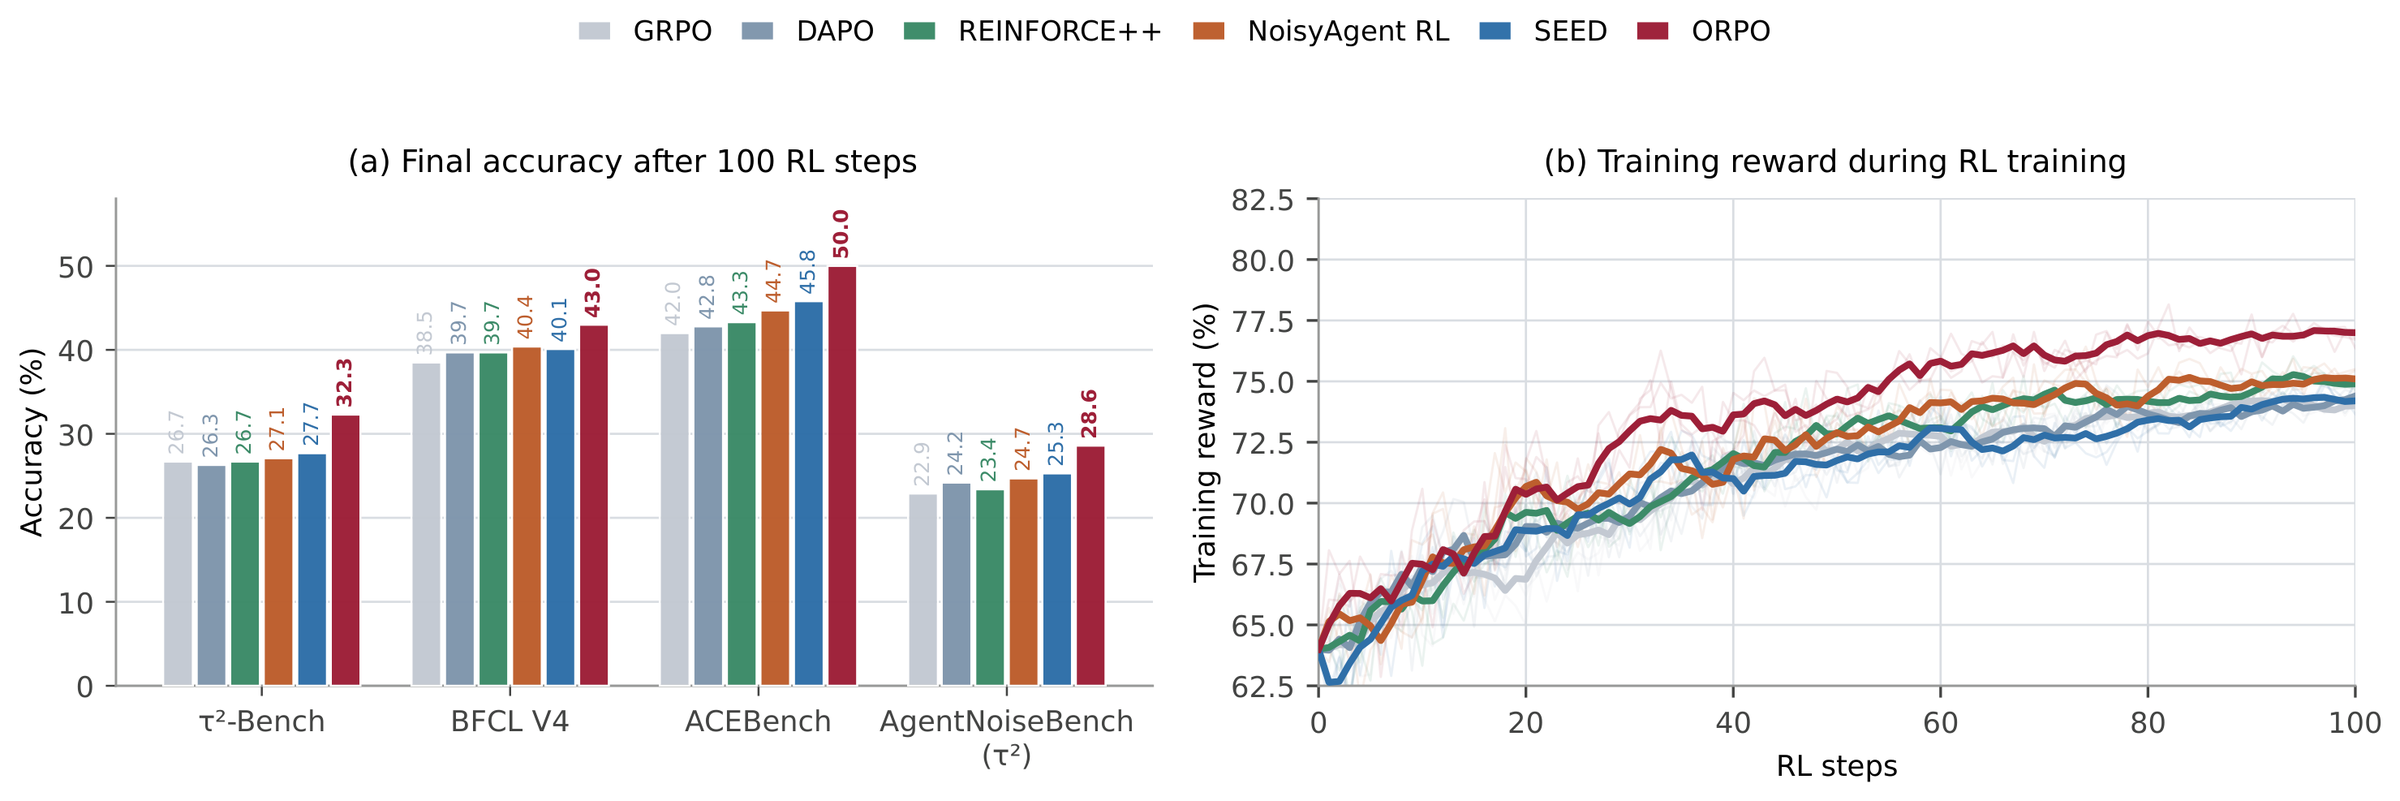
On Qwen3-8B, Agent-Reflex reaches 58.6 Overall on the five long-horizon tool-use benchmarks (+18.4 over the backbone, +7.7 over EnvScaler-8B) and 29.1 on AgentNoiseBench, the best among all 8B methods:
| Method |
VitaBench |
τ²-Bench |
BFCL V4 |
ACEBench |
ToolSandbox |
Overall |
AgentNoiseBench |
| Qwen3-8B |
11.4 |
26.2 |
40.4 |
54.0 |
69.1 |
40.2 |
12.3 |
| Reflexion |
6.8 |
34.5 |
42.7 |
64.0 |
75.4 |
44.7 |
13.7 |
| EnvScaler-8B |
15.8 |
37.9 |
47.6 |
72.5 |
80.5 |
50.9 |
18.2 |
| Agent-World-8B |
14.5 |
54.6 |
51.4 |
72.0 |
75.6 |
53.6 |
– |
| Agent-Reflex |
17.5 |
62.1 |
52.9 |
78.0 |
82.5 |
58.6 |
29.1 |
Full tables, noise robustness and the RL algorithm comparison
🔧 Installation
Environment Setup
Each part has its own environment, built by one script with uv (pip install uv) from a pinned requirements.txt:
| Part |
Python |
Core packages |
Setup |
| ReSFT |
3.12 |
torch 2.6.0 (cu124), transformers 5.8, DeepSpeed 0.19, flash-attn 2.7.4, Liger 0.8 |
bash LLaMA-Factory/setup_env.sh |
| ORPO |
3.10 |
torch 2.7.1 (cu128), verl 0.5, SGLang 0.4.10.post2, transformers 4.54.1, Ray 2.57, flash-attn 2.8.3 |
bash ORPO/setup_env.sh |
| Model serving |
3.12 |
vLLM 0.27.1 |
bash evaluation/shared/setup_vllm.sh |
| Benchmarks |
3.10 / 3.12 |
one venv per benchmark; upstream code cloned at pinned commits |
bash evaluation/<Bench>/setup.sh |
- Hardware: NVIDIA 80 GB GPUs with a driver supporting CUDA 12.8. ReSFT uses 2 × 8 GPUs; ORPO and evaluation use 1 × 8.
- Network: the setup scripts need GitHub, PyPI and Hugging Face. Behind a proxy, export
HTTP_PROXY / HTTPS_PROXY first.
API Configuration
Training needs no API keys. Evaluation reads them from evaluation/.env (git-ignored):
cp evaluation/.env.example evaluation/.env
# then edit evaluation/.env:
BOYUE_API_KEY=sk-xxxxxxxx
BOYUE_API_BASE_URL=http://35.220.164.252:3888/v1   # outside CN/HK: https://api.boyuerichdata.opensphereai.com/v1
SERPER_API_KEY=xxxxxxxx
BOYUE_API_KEY: the user simulator (gpt-4.1) and judge (claude-sonnet-4-6) for every benchmark except BFCL. Register at Boyue API (docs), open the API令牌 (API tokens) page and create a token in the auto group; the key starts with sk-.
[!NOTE]
By default our evaluation calls these models through Boyue, a third-party OpenAI-compatible API service. Any OpenAI-compatible endpoint works: to use the official OpenAI / Anthropic APIs or your own gateway, point the base URL and key in evaluation/.env (and the client setup in each benchmark's run.sh / config) to your provider. A coding agent can make this change in a few minutes.
SERPER_API_KEY: BFCL V4 web search only, from serper.dev.
🗂️ Repository
Agent-Reflex/
├── RSD/             🪞 Stage 1 · the reflection meta-skill library (1,170 skills)
├── LLaMA-Factory/   📘 Stage 2 · ReSFT recipe and launch scripts
├── ORPO/            🎯 Stage 3 · verl-based ORPO: noisy rollouts + skill-guided OPD
├── evaluation/      📊 τ²-Bench, BFCL V4, ACEBench, VitaBench, AgentNoiseBench, ToolSandbox
└── assets/          🖼️ figures used in this README; demo/ holds the demo video and replay page
📦 Data
pip install -U huggingface_hub
hf download dongguanting/Agent-Reflex-SFT-54K --repo-type dataset --include "train/*" \
  --local-dir LLaMA-Factory/data/agent_reflex_resft
hf download dongguanting/Agent-Reflex-RL-2K train_envscaler_2550_with_skills.jsonl \
  --repo-type dataset --local-dir ORPO/data
hf download dongguanting/Agent-Reflex-8B --local-dir /path/to/Agent-Reflex-8B
🚀 Quick Start
1. ReSFT
cd LLaMA-Factory
NNODES=2 NODE_RANK=<0|1> MASTER_ADDR=<node0> MODEL_PATH=/path/to/Qwen3-8B \
  bash scripts/run_resft_qwen3_8b.sh
2. ORPO
Start from the ReSFT model checkpoint:
cd ORPO
python scripts/prepare_init_checkpoint.py /path/to/resft_checkpoint --apply
MODEL_PATH=/path/to/resft_checkpoint bash scripts/run_orpo_qwen3_8b.sh
3. Evaluation
Full task sets under the official settings (fill in evaluation/.env first):
cd evaluation
MODEL_PATH=/path/to/Agent-Reflex-8B RUN_NAME=agent-reflex bash run_all.sh
run_all.sh serves the model with vLLM and runs all six benchmarks; set BENCHES="Tau2 BFCL-v4" to run a subset. Per-benchmark details are in evaluation/README.md.
🙏 Acknowledgements
Agent-Reflex builds on verl, LLaMA-Factory, EnvScaler, Agent-World, tau2-bench, BFCL, VitaBench, ToolSandbox and AgentNoiseBench. Thanks to their authors.
📄 License
Agent-Reflex code and the RSD skill library are released under the MIT License. Vendored components keep their own licenses:
| Component |
License |
ORPO/ (verl), LLaMA-Factory/ |
Apache-2.0 |
evaluation/BFCL-v4/ (BFCL data, from gorilla) |
Apache-2.0 |
evaluation/Tau2/data/, evaluation/AgentNoiseBench/repo/tau2-bench-main/ (tau2-bench) |
MIT |
evaluation/VitaBench/data/, evaluation/AgentNoiseBench/repo/vitabench/ (VitaBench) |
MIT |
evaluation/ACEBench/interact_with_env/ (EnvScaler, tau-bench) |
MIT |
ToolSandbox is cloned from apple/ToolSandbox at setup time and is not redistributed here. The AgentNoiseBench noise injection and data follow AgentNoiseBench; please refer to its authors for terms of use.
📚 Citation
@misc{dong2026agentreflex,
  title={Agent-Reflex: Teaching Language Agents to Act Reflectively},
  author={Guanting Dong and Xinyu Yang and Jiajie Jin and Yuyang Hu and Xiaoshuai Song and Yifei Chen and Xiaoxi Li and Jiejun Tan and Yutao Zhu and Tat-Seng Chua and Ji-Rong Wen and Zhicheng Dou},
  year={2026},
  eprint={2610.17953},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2610.17953},
}

@article{song2026envscaler,
  title={EnvScaler: Scaling Tool-Interactive Environments for LLM Agent via Programmatic Synthesis},
  author={Song, Xiaoshuai and Chang, Haofei and Dong, Guanting and Zhu, Yutao and Dou, Zhicheng and Wen, Ji-Rong},
  journal={arXiv preprint arXiv:2601.05808},
  year={2026}
}

@article{dong2026agent,
  title   = {Agent-World: Scaling Real-World Environment Synthesis for Evolving General Agent Intelligence},
  author  = {Dong, Guanting and Lu, Junting and Huang, Junjie and Zhong, Wanjun and
             Liu, Longxiang and Huang, Shijue and Li, Zhenyu and Zhao, Yang and
             Song, Xiaoshuai and Li, Xiaoxi and Jin, Jiajie and Zhu, Yutao and
             Wang, Hanbin and Lei, Fangyu and Luo, Qinyu and Chen, Mingyang and
             Chen, Zehui and Feng, Jiazhan and Wen, Ji-Rong and Dou, Zhicheng},
  journal = {CoRR},
  volume  = {abs/2604.18292},
  year    = {2026},
  url     = {https://arxiv.org/abs/2604.18292}
}
 Agent-Reflex: Teaching Language Agents to Act Reflectively




 Agent-Reflex 是一个训练框架,用来教会调用工具的大模型智能体学会反思:注意到工具返回的嘈杂反馈和用户的纠正,并从中恢复,而不是悄无声息地失败。