Download
Take the latest build from Releases.
Some antivirus engines flag unsigned NSIS installers that download other binaries, which is a false positive. The installer is built by GitHub Actions from the public source on master, and the update channel is signed against a public minisign key, so you can verify both: see SECURITY.md.
Code signing for the Windows installers: free code signing provided by SignPath.io, certificate by SignPath Foundation. The application is in review, and until it is approved the installers ship unsigned.
Current release: v3.0.5 (October 2026). Every change since 1.0.0 is in CHANGELOG.md.
3.0.5 is about Create: LTX 2.5, FastH3 and YuE2 run on your own machine, Qwen-Image 2.1 gets a transparent background and its prompt enhancer, Edit, Remove Background and Enhance Image take up to 50 images in one go, and LU Cloud adds Qwen Image 2.1, LTX 2.5, MiniMax H3 and Wan 3.0 Reference. Chat takes any file, each model in a group chat can have its own persona, dropdowns stay inside the window (issue 149), and the speech install works again on Ubuntu 24.04.
3.0.4 fixed the Code agent and the agent in chat on LU Cloud: writing a long file no longer ends the run, "continue" picks up where a run stopped instead of starting over, the agent keeps a plan only when you ask for one, and cloud context is 32K by default and can be set per model. It also fixed the bugs reported on GitHub and Discord since 3.0.3 (issues 144 to 147): MiniMax H3 runs as a video model with sound, Edit takes up to three extra images with Qwen-Image 2.1, a missing encoder or VAE is named and offered as a download instead of ending in "Value not in list", the LoRA stack follows the loras folder, and group chat works with every LU Engine model.
3.0.3 was a hotfix: chats with many images no longer run the app out of memory, Create reads a model's family from the file instead of its name, and the five bugs reported on GitHub since 3.0.2 are fixed (issues 139 to 143).
3.0.2 was a hotfix: the Code tab lost its scrollbar and its input box once a conversation grew taller than the window (issue 138, a regression in 3.0.1) and is held to the window height again, and the count of open cloud models now takes the Create Studio endpoints in, which makes it fourteen video models and seven image models.
What is new in 3.0.1
- Qwen-Image 2.1 runs locally on Windows and Linux. One model generates a picture from a prompt and edits one from a reference image, with no mask to paint. About 16 GB of files, ComfyUI 0.37.0 or newer, and a research license that does not allow commercial use.
- Models has a LoRAs tab of its own. Search CivitAI, download into ComfyUI's
models/loras folder, see what is installed with its size and trigger word, and delete what you no longer want.
- A GPU whose free memory could not be measured is planned more carefully, and the log now says total capacity instead of calling it free.
- The Linux AppImage stops handing its own runtime to every program LU starts, so a healthy system Python, pip, git or ffmpeg keeps working, and a distribution that blocks pip in the system Python keeps the isolated environment LU built.
- The local model runs one conversation at a time and says so, with a line showing how many chats are ahead. Stop works while a chat is still waiting.
- Temperature, Top P and Max tokens belong to the conversation you moved them in, instead of every open chat sharing one value.
- Cloud video renders offer the clip lengths the picked model really supports, read from the live catalog.
Three steps
- Install. Run the installer like any other program. On first launch a wizard looks for an AI engine that is already running on your machine, and installs one for you with a single click if there is none. It does the same for ComfyUI, which draws the images and video.
- Pick a model. The model manager marks which models fit your hardware and downloads them in one click. It works with the engine you already have (Ollama, LM Studio and others) and can link models those tools already store, without copying them.
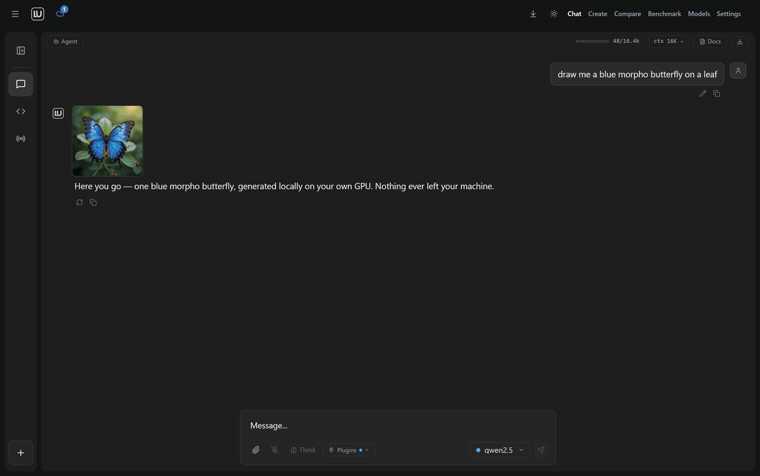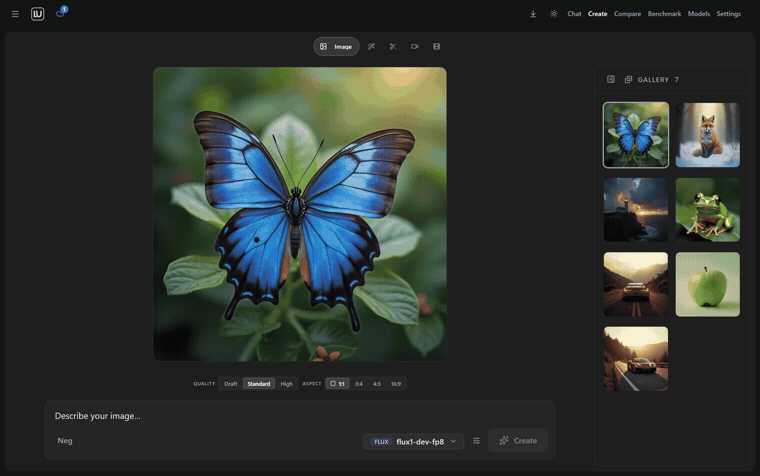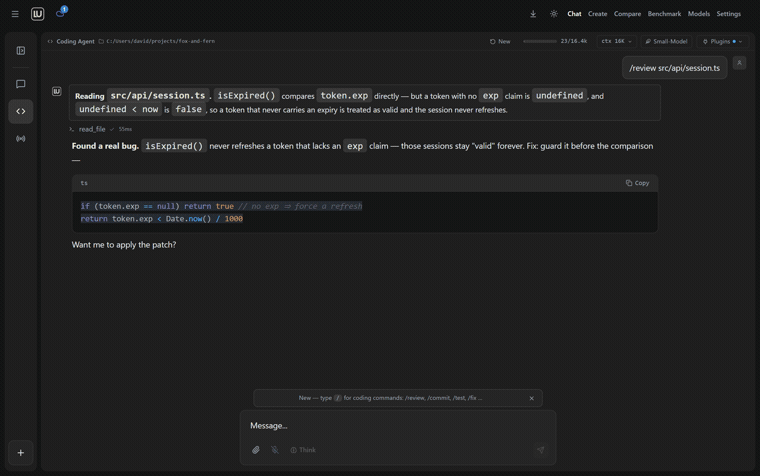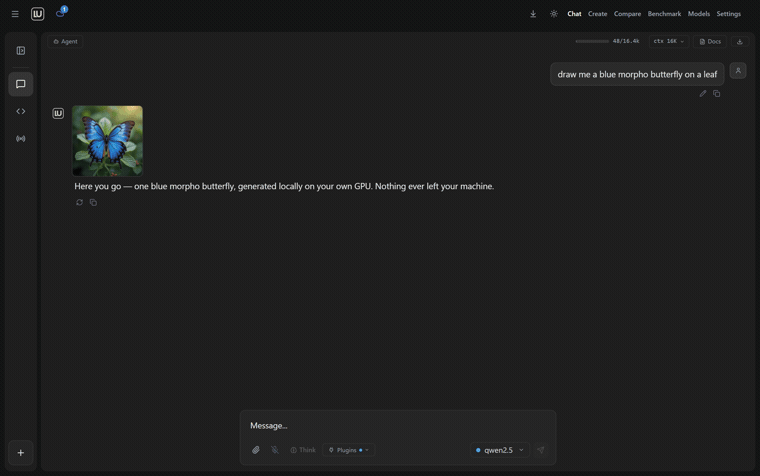
- Create. Chat, Create, Code and Agent are tabs in one window. Type in one, switch to the next, keep the same models.
Walkthrough with screenshots: Getting started guide. New to local AI: the five minute beginner guide.
Build from source, or contribute
git clone https://github.com/PurpleDoubleD/locally-uncensored.git
cd locally-uncensored
npm install
npm run dev          # browser dev mode
npm run tauri build  # desktop binary
setup.bat on Windows and setup.sh on Linux and macOS bootstrap Node, Git and Ollama for dev mode. See the contributing guide.
What is in the box
Chat. Models that answer directly, without refusals, next to the mainstream ones in the same menu. Thinking is shown as it happens, with an effort control on the models that offer one. Upload an image and ask about it, chat with your own documents through a local index, talk instead of typing and have answers read back, keep a memory across conversations, switch personas, and import your ChatGPT, Claude or Gemini export so the old threads come with you. A long conversation folds its older turns into a summary instead of running out of room.
Create. Images and video on your own GPU through a ComfyUI the app installs, starts, repairs and updates for you. No node graphs. The lanes are text to image, edit and image to image with a mask for inpainting, remove background, video, animate an image, extend a clip, motion control, talking character, music, and Character Studio, which trains a character on your own card and drops it into your local LoRA folder. A LoRA picker with a stack and strength sliders reads the folder live, and everything you make lands in the gallery. Upscale and Erase Object are the two lanes that run in the cloud only. How it works.
Code. A coding agent that builds a map of the repo, edits only the lines you asked for, shows the diff before it applies anything, runs your tests and reads the failures, and carries typed git tools and per project rules in a .lurules file. Ask, Plan and Bypass modes per conversation, a file explorer with preview, and a workspace per project. A Local API in Settings puts every local model on one OpenAI compatible address behind a token, so your other coding tools can use the same machine.
Agent. Web search and fetch, reading and writing files, a shell, code execution, screenshots, image and video generation, and your own MCP servers on top. Long jobs go to background agents that work while you carry on, and a panel shows what is running. Every tool call passes a permission gate you control, and a read only run stays read only.
Everywhere. Reach the app from your phone over your LAN or through a Cloudflare tunnel, paired by QR code and a passcode, off until you turn it on, with connected devices listed. Compare two models side by side, benchmark them on your own hardware for speed, cost and correctness, and take updates over a signed channel. Phone details.
Optional: LU Labs Cloud
Some models are larger than any desktop card. Flip the Cloud switch in the same app and those run on hosted GPUs instead, with the heavy Create lanes alongside them. The same account works in the browser at lu-labs.ai, on a plan or on credit packs that do not expire. The local app stays free either way, and switching back to local costs nothing: plans and prices.
Since 3.0.0 the catalogue says what it can back up. Every cloud chat model was asked the same two questions twice and judged on the answer, and a longer three-round test on 2026-10-05 took the mark from five more: 19 of the 46 we measured answer in full, and only those carry a No refusals mark in the picker. Across all measured answers, 5% were refusals. 12 models cost no credits at all in chat on an active plan, up to 500,000 input and output tokens per day. For images and video, 14 video and 7 image models run without a built-in content restriction, most of them with Uncensored in the name, and your account decides what they may produce.
How it compares
|
Locally Uncensored |
Open WebUI |
LM Studio |
Jan |
SillyTavern |
| Chat |
Yes |
Yes |
Yes |
Yes |
Yes |
| Image generation |
Yes |
No |
No |
No |
Partial |
| Video generation |
Yes |
No |
No |
No |
No |
| Image to image and image to video |
Yes |
No |
No |
No |
No |
| Coding agent |
Yes |
No |
No |
No |
No |
| Agent with tools and MCP |
Yes |
No |
No |
No |
No |
| Works out of the box |
Yes |
No |
Yes |
Yes |
No |
| Remote access from your phone |
Yes |
Partial |
No |
No |
Partial |
| Compare and benchmark |
Yes |
No |
No |
No |
No |
| Answers directly, without refusals |
Yes |
No |
No |
No |
Partial |
| Voice in and out |
Yes |
Partial |
No |
No |
Partial |
| Document chat |
Yes |
Yes |
No |
No |
No |
| Runs without Docker |
Yes |
No |
Yes |
Yes |
Yes |
| Open source |
Yes |
Yes |
No |
Yes |
Yes |
Deep dives: vs LM Studio · vs Jan · vs Open WebUI · vs GPT4All · vs Msty · vs KoboldCpp · vs SillyTavern · LM Studio alternatives · Best local AI apps 2026
Models that run well
The model manager holds the full catalog and marks what fits your machine. These are the ones worth starting with.
Text
| Model |
Download |
Notes |
| Qwen 3.8 27B Uncensored |
18 GB |
Vision, tools and switchable thinking, 262K context. The IQ2_M build is 11 GB and fits a 12 GB card. |
| Gemma 4 12B Heretic |
7.4 GB |
Vision, a different voice from the Qwen line. The IQ4_XS build is for 8 GB cards. |
| Qwen3-VL 8B Abliterated |
5 GB |
Image understanding on an 8 GB card. |
| Hermes 3 Llama 3.1 8B |
5 GB |
Native tool calling. The small model to give the agent. |
| Llama 3.1 8B Abliterated |
5 GB |
Fast and reliable, the usual first download. |
| GLM 4.7 Flash Heretic |
10 GB |
30B class in an IQ2_M build that fits 12 GB. |
| Qwen 3.6 35B MoE Abliterated |
24 GB |
35B total with 3B active, vision and agentic coding. |
GLM 5.3 is in the catalog too, but its smallest local quant is 217 GB, so on a desktop it is cloud territory. Kimi K3 is further out still.
Image
| Model |
VRAM |
Notes |
| Juggernaut XL V9 |
6-8 GB |
Photoreal SDXL, the friendliest entry point. |
| DreamShaper XL Turbo V2 |
6-8 GB |
Anime and stylized. |
| FLUX.1 schnell or dev |
8-10 GB |
Fast, or slower and better. |
| FLUX 2 Klein 4B |
8-10 GB |
The newest FLUX, and the quickest of them. |
| Z-Image Turbo |
10-16 GB |
Unfiltered. Loads slowly below 16 GB. |
| Qwen-Image 2.1 |
16-24 GB |
Generates and edits in one model. Needs ComfyUI 0.37.0. Research license, non-commercial. |
| Qwen-Image 2.1 (No Refusals) |
16-24 GB |
The same model with a community text encoder that has its refusals removed (Heretic). |
| Noct Q (Qwen-Image 2.1, Unfiltered) |
16-24 GB |
A community finetune of Qwen-Image 2.1 with modified image model weights. Research license, non-commercial. |
| ERNIE-Image Turbo |
24 GB |
Baidu DiT, eight steps. |
Video
| Model |
VRAM |
Notes |
| AnimateDiff Lightning |
6-8 GB |
Four step animation, the cheapest way in. |
| FramePack F1 |
6-8 GB |
Image to video on a small card. |
| Wan 2.1 1.3B |
8-10 GB |
Light text to video. |
| Wan 2.1 14B FP8 |
12+ GB |
The quality step up. |
| Wan 2.2 TI2V 5B |
12+ GB |
Image and text to video in one model. |
| HunyuanVideo 1.5 FP8 |
12+ GB |
Strong frame to frame consistency. |
| LTX Video 2.3 22B FP8 |
16+ GB |
The newest LTX. |
Music runs on ACE Step 1.5 Turbo at 6-8 GB, and Talking Character on Wan 2.2 S2V from 10-12 GB.
Bring your own engine
If you already run a local engine, the app finds it and lists it instead of installing a second one. It detects Ollama, LM Studio, vLLM, KoboldCpp, llama.cpp, LocalAI, Jan, TabbyAPI, GPT4All, Aphrodite, SGLang, TGI, LiteLLM and text-generation-webui, and it ships its own LU Engine for people who have none. Cloud providers are optional and use your own keys: OpenAI, Anthropic, OpenRouter, Groq, Together, DeepSeek, Mistral, or any OpenAI compatible address you paste in.
FAQ
Is it really free and offline?
Yes. AGPL-3.0, no account, no usage limits. In local mode chat, agent runs and image and video generation all happen on your machine, with no telemetry and no analytics. The app checks GitHub for updates, and pressing the Cloud switch sends one anonymous daily count, which Settings names.
What does "uncensored" mean?
Abliterated models have the trained in refusal behaviour removed from the weights, so it is not a jailbreak that can be patched or break. They answer directly, without refusals. Full guide.
What hardware do I need?
Chat runs a 3B model on 8 GB of system RAM with no GPU at all, and an 8B model comfortably on a 6 GB card. Image generation starts at 6 to 8 GB of VRAM, and so does video on AnimateDiff Lightning or FramePack F1; the Wan and Hunyuan models want 12 GB or more. The model manager marks what fits before you download.
Can it replace ChatGPT or Claude?
For most chat, writing and coding, yes, with a good 8B to 14B local model, and it stays private and unlimited. Frontier cloud models are still stronger on the hardest reasoning. You can add them with your own API keys, or use the Cloud switch.
Does remote access leak data?
No. It is off until you turn it on, gated by a passcode, and it lists the devices that are connected. On your LAN nothing leaves the network; away from home an encrypted Cloudflare tunnel joins phone and PC. No third party AI server is involved.
What about macOS?
There is no macOS desktop build. Every release builds Windows and Linux only. On a Mac, use LU Cloud in the browser at lu-labs.ai, which runs chat, images and video on hosted GPUs.
Roadmap
- Voice mode, a live spoken conversation rather than push to talk in and read aloud out
- Face ID and PuLID in Create, so a character keeps one face across images
- Upscale and Erase Object as local lanes; both run in the cloud today
Everything else listed here has shipped. See Releases for the history.
Tech stack
Tauri v2 with a Rust backend, React 19, TypeScript, Tailwind CSS 4, Vite 8, ComfyUI for images and video, faster-whisper for speech to text and Piper for speech.
Discord: https://locallyuncensored.com/discord, with help channels for chat, images, video and the coding agent. Bugs and ideas: Issues and Discussions.
License
AGPL-3.0-only. See LICENSE.


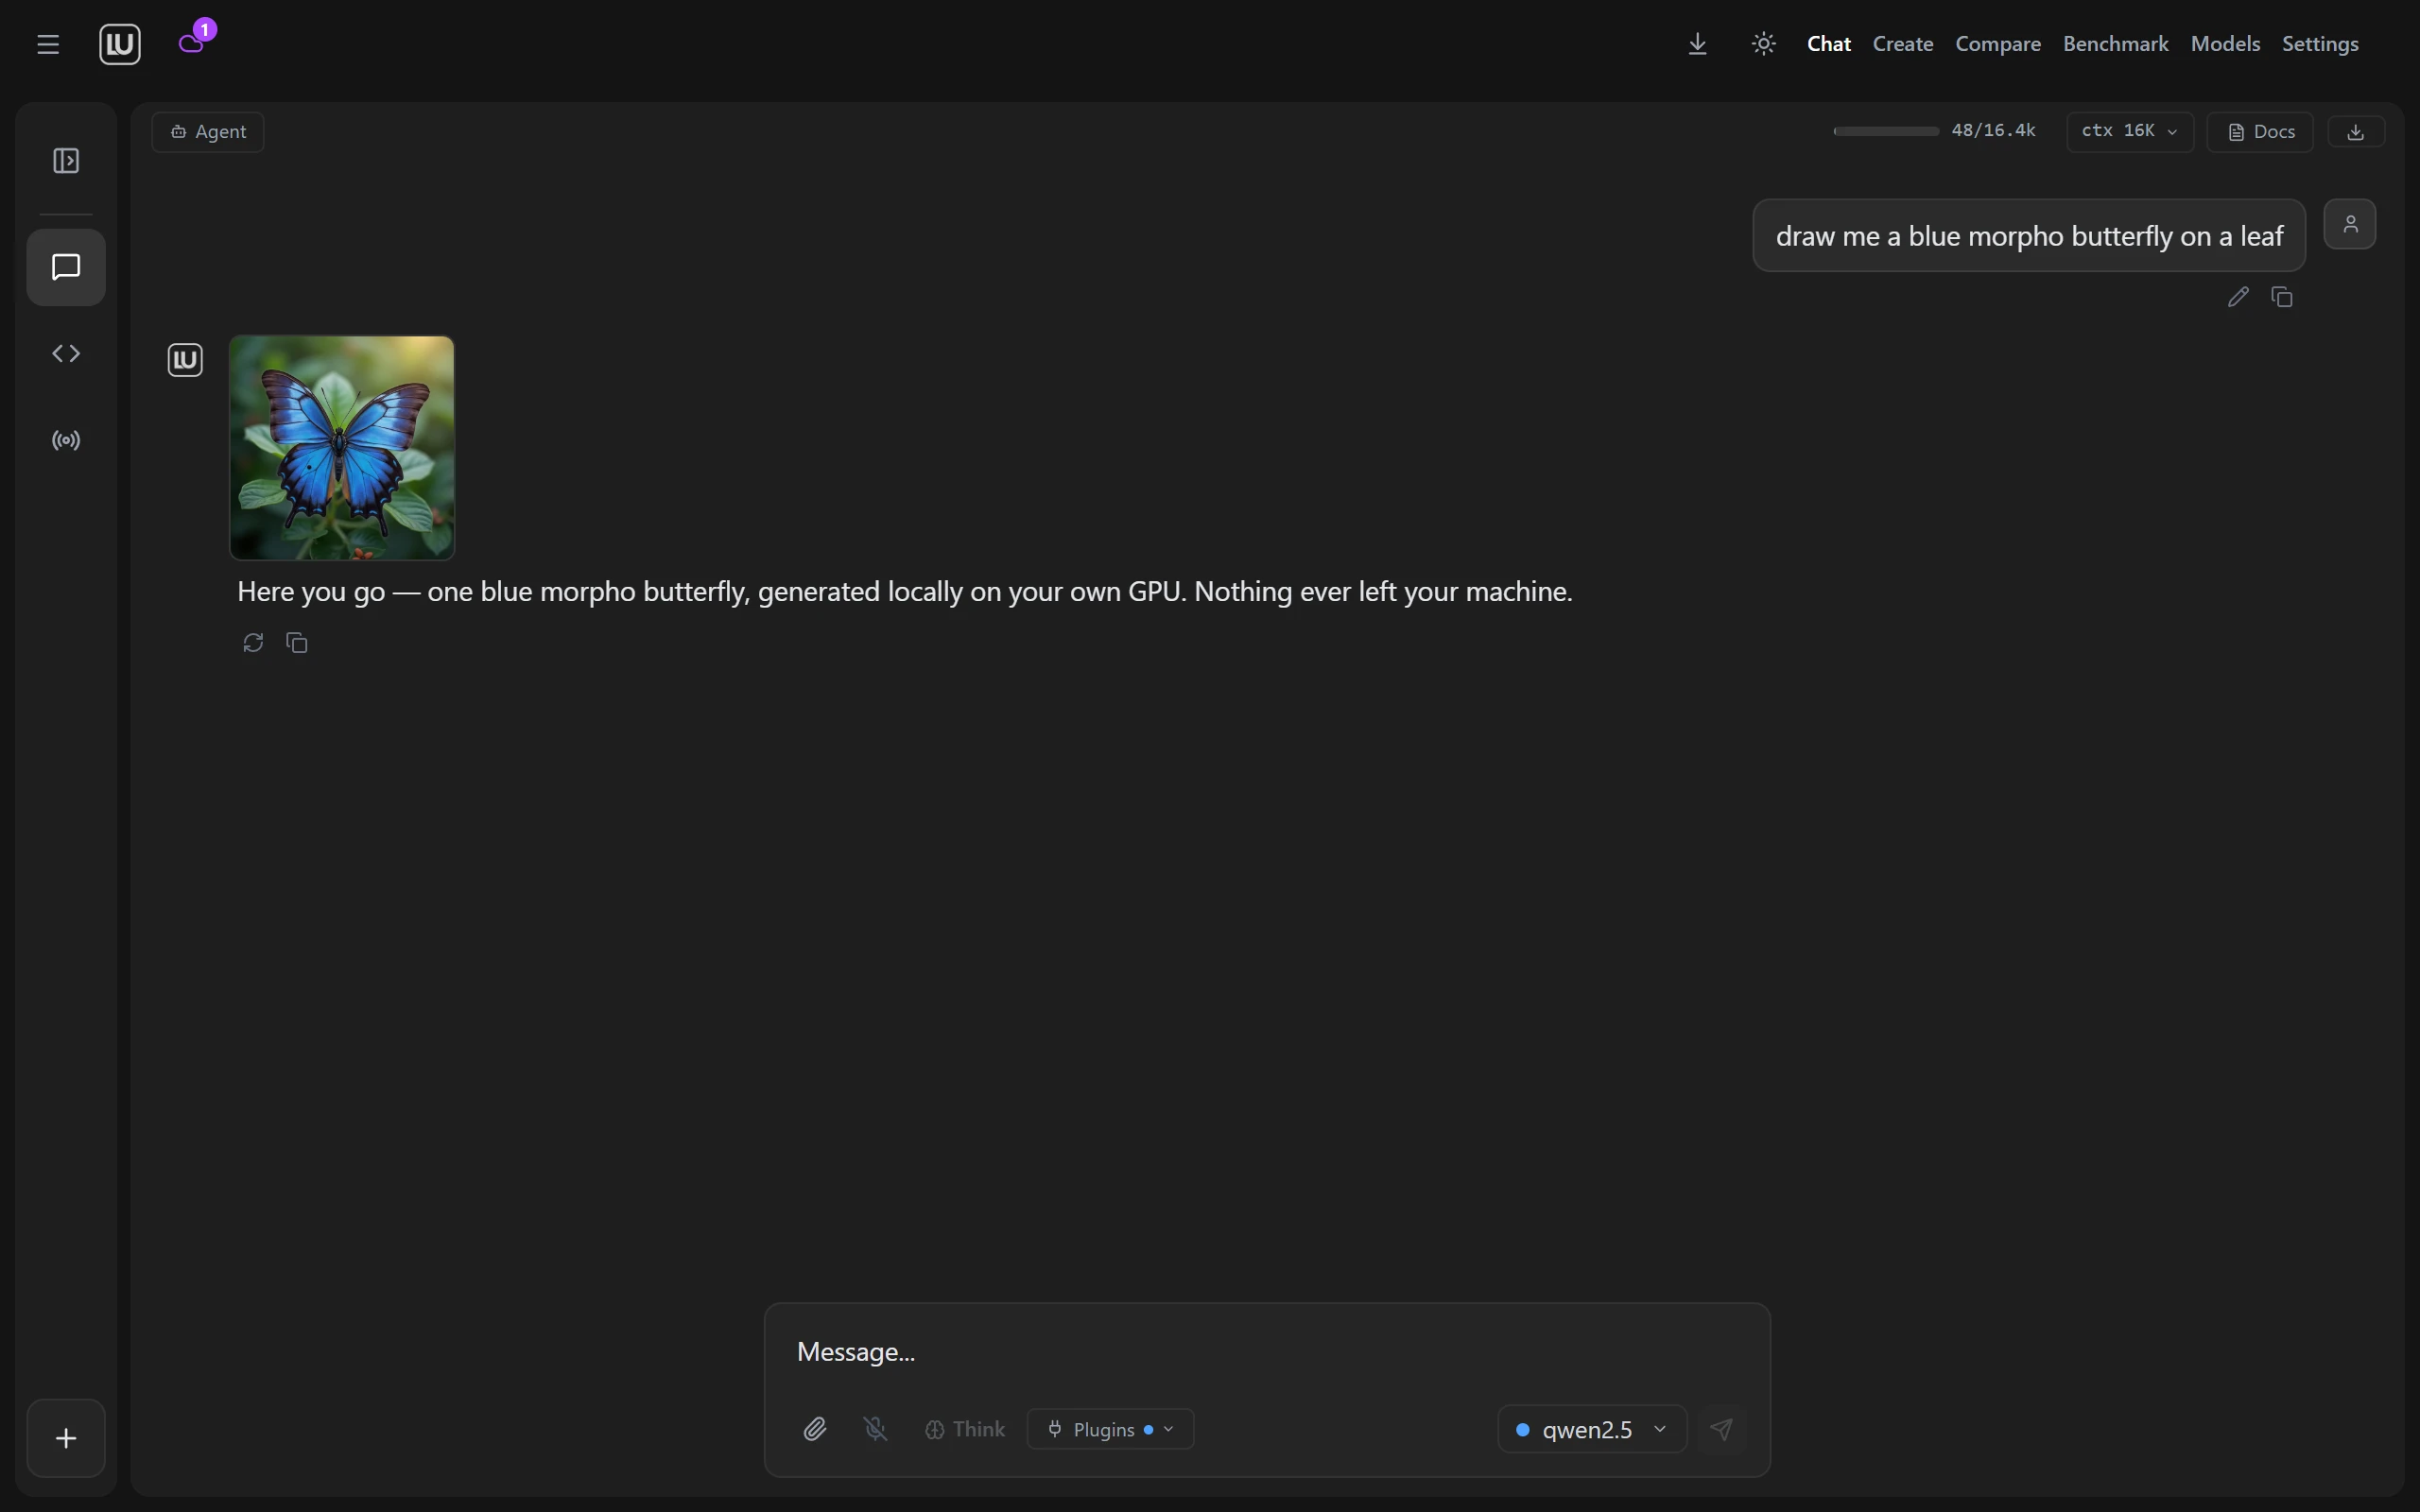
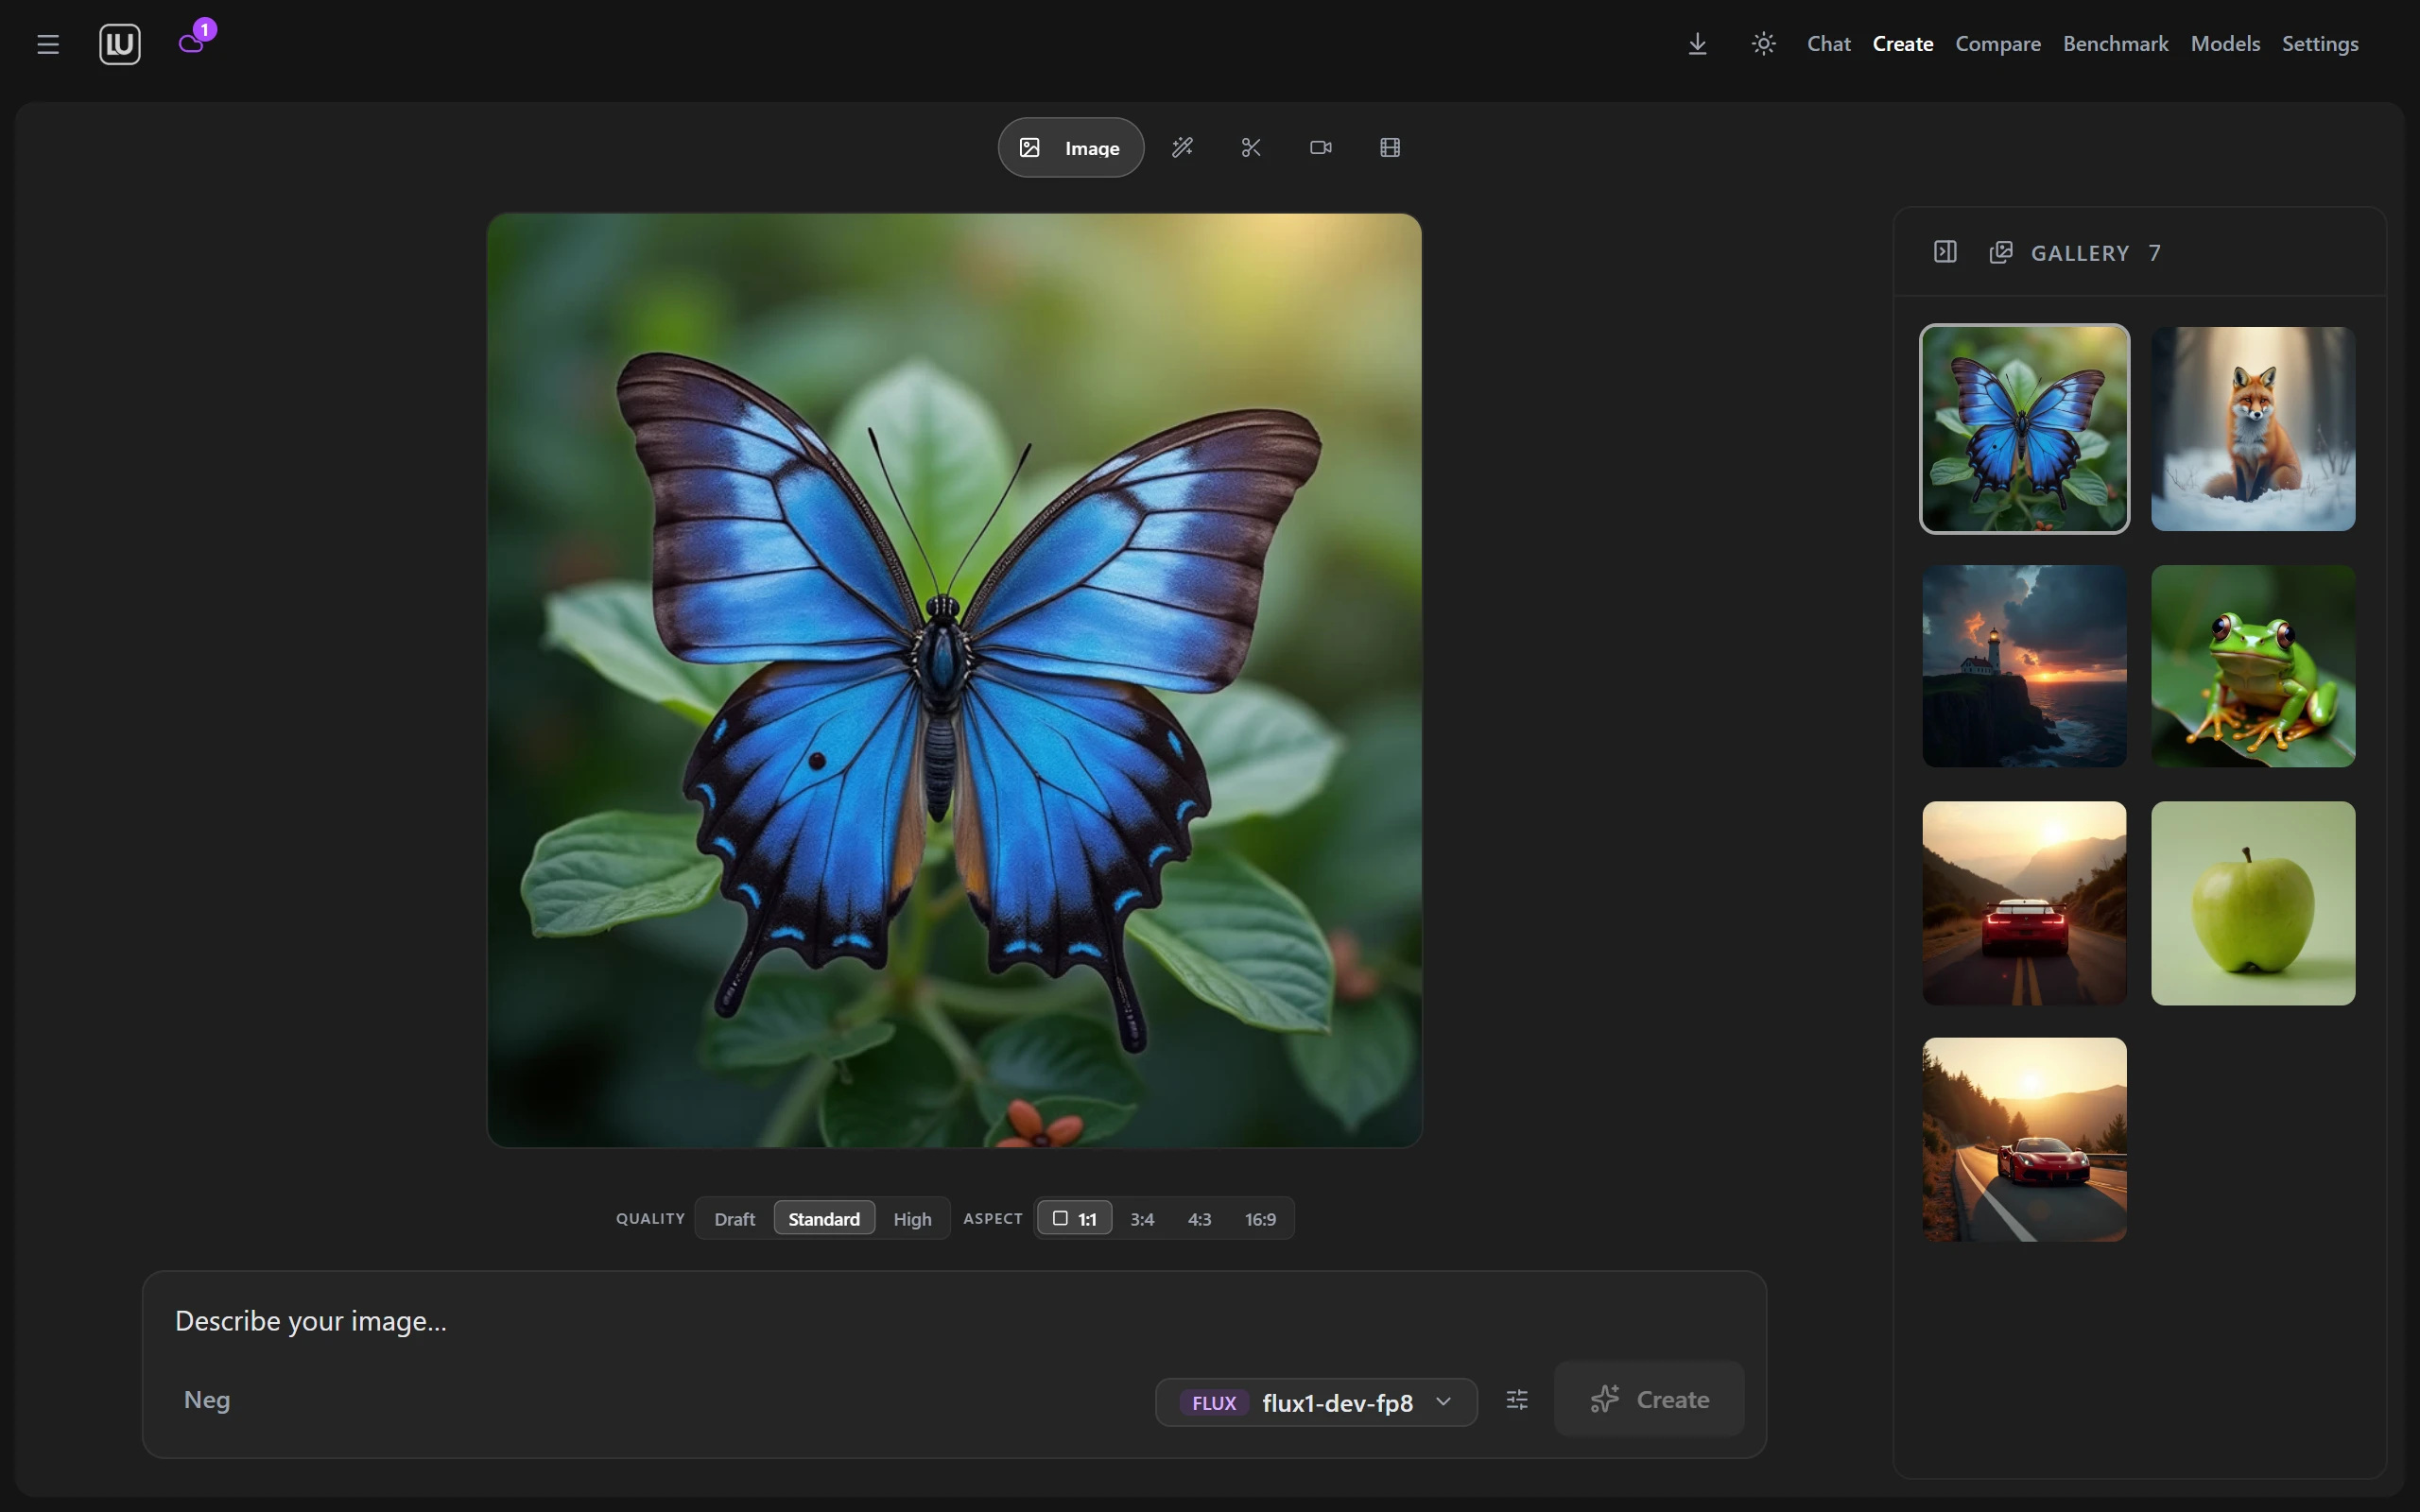
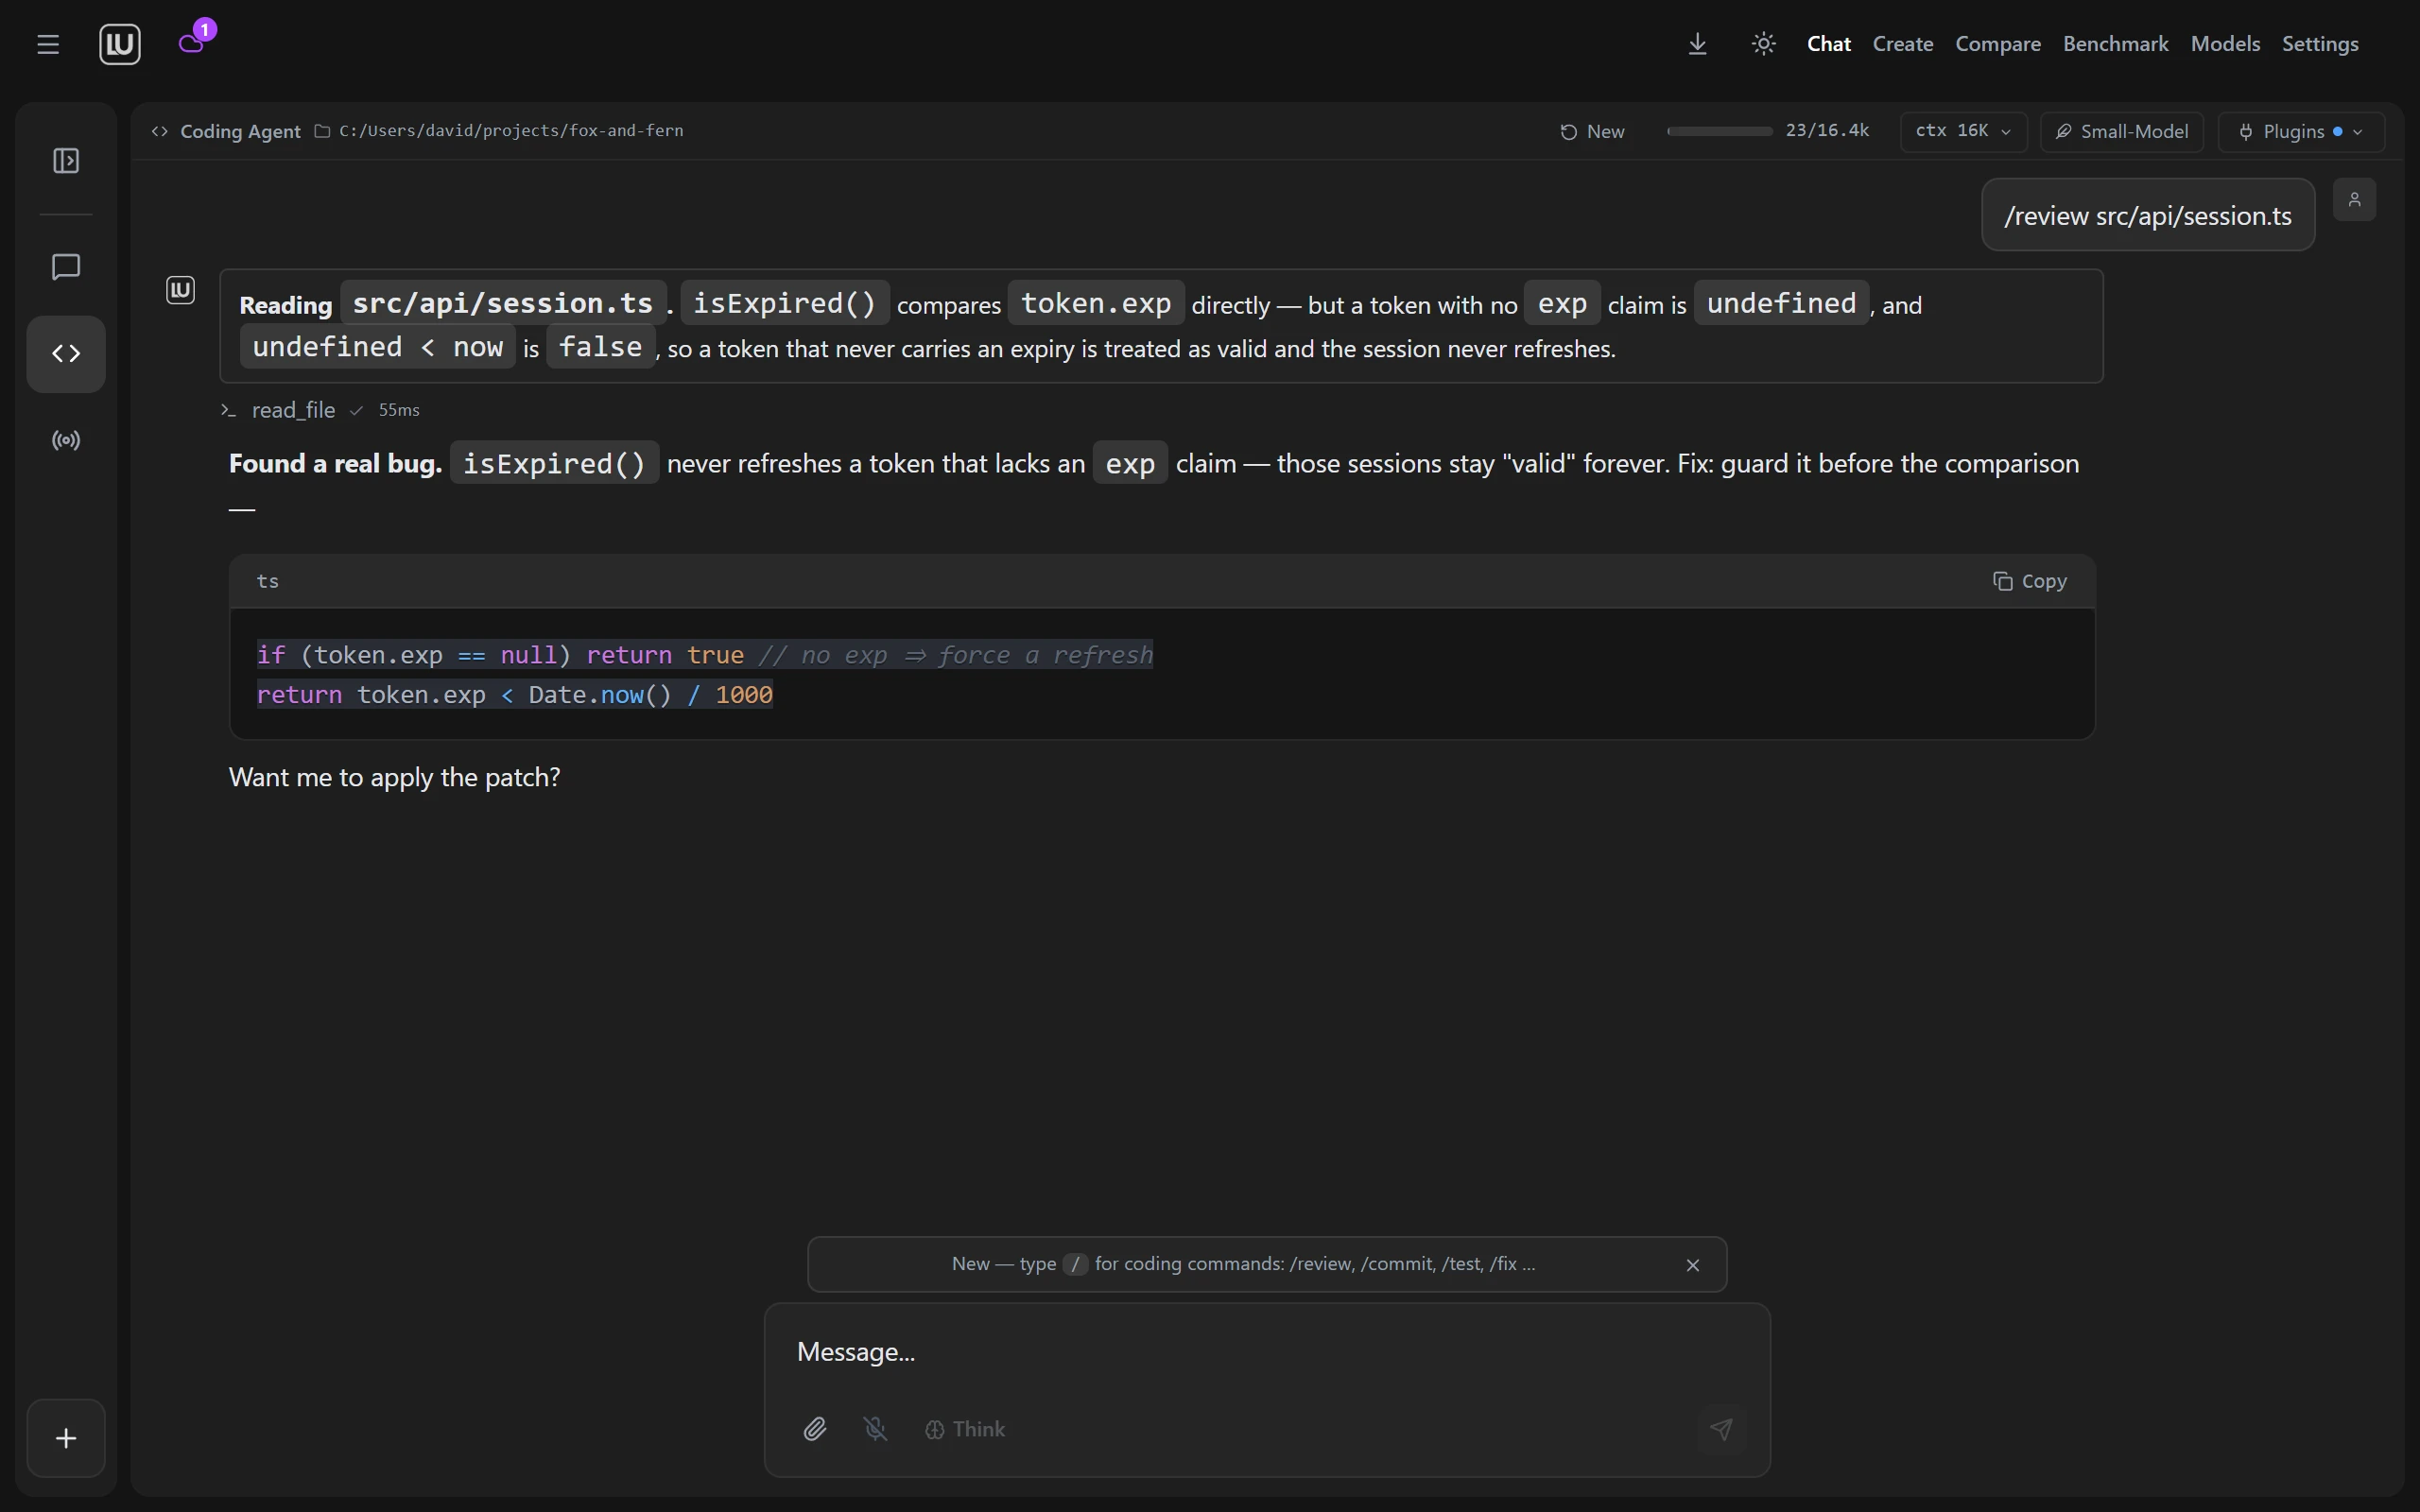
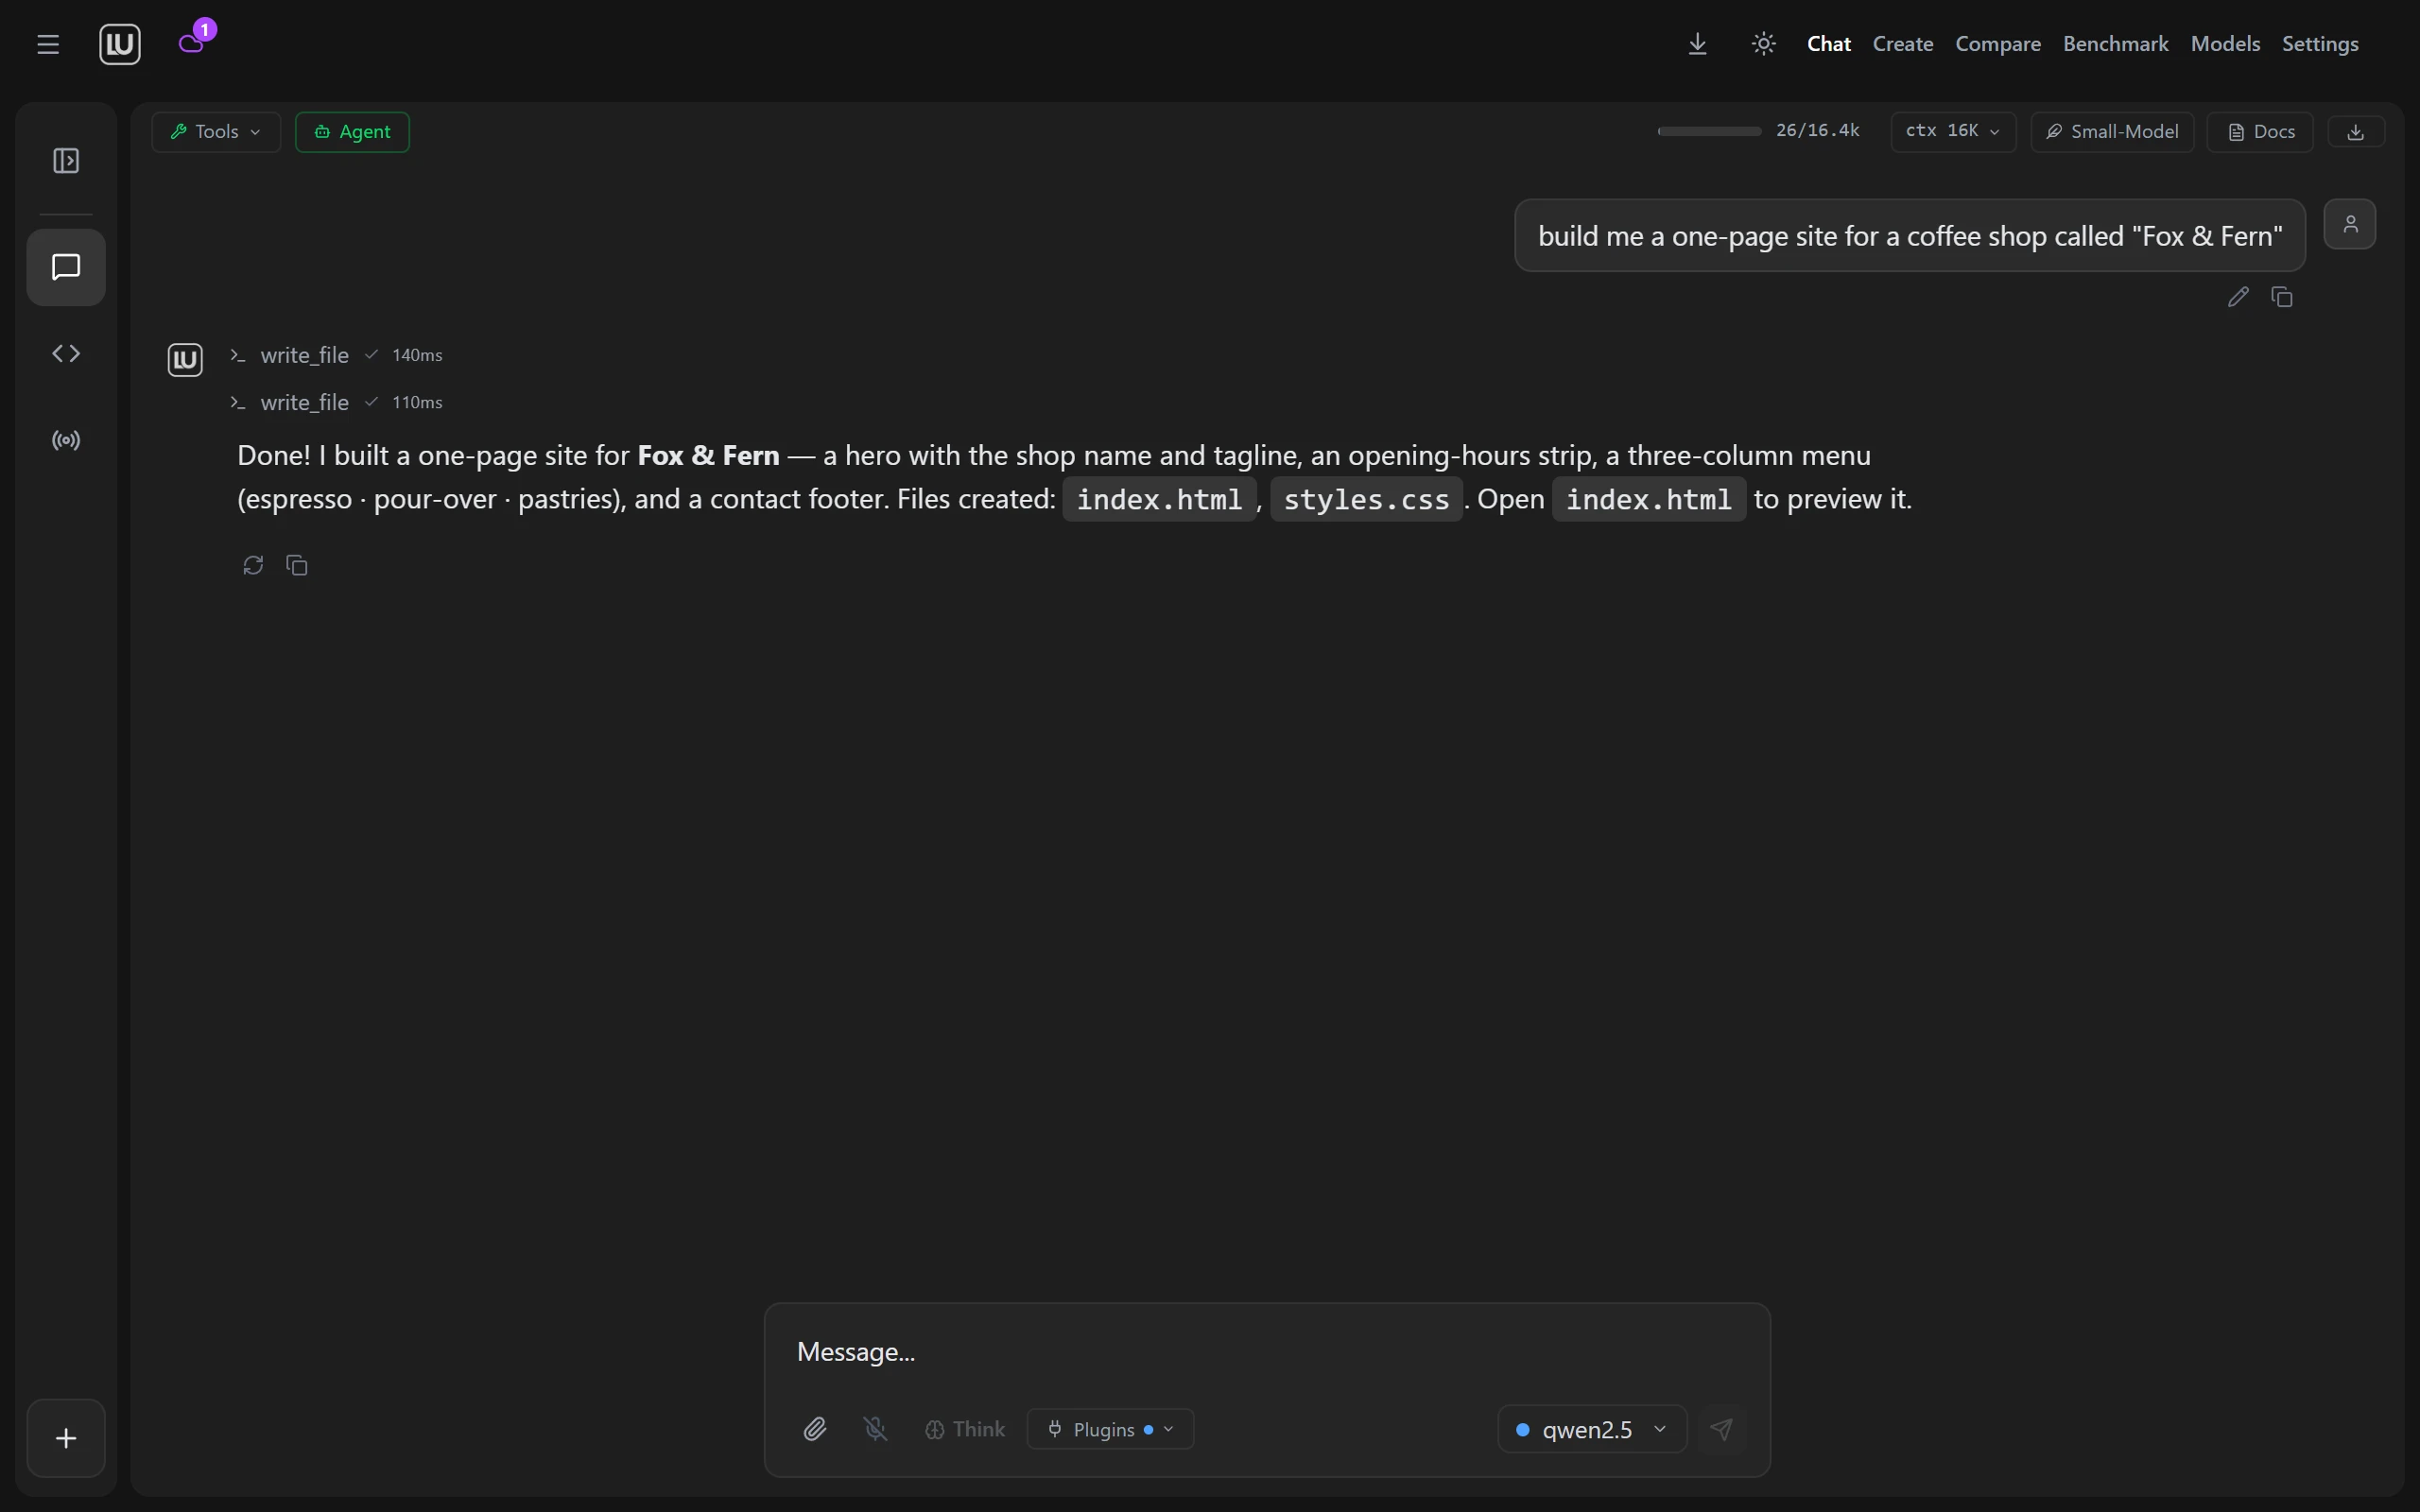

 这是一个面向桌面的本地一体化 AI 工作室,把聊天、图像和视频生成以及编程智能体打包进一个免费开源应用,支持 Windows 和 Linux。