This project aims to create a simple and scalable repo, to reproduce Sora (OpenAI, but we prefer to call it "ClosedAI" ).
本项目希望通过开源社区的力量复现Sora,由北大-兔展AIGC联合实验室共同发起,来自兔展、华为、鹏城实验室和开源社区伙伴均有深度贡献力量。
当前V1.5版本完全基于华为昇腾训练(昇腾纯血版),欢迎Pull Request和使用!
我们正在快速迭代新版本,欢迎更多合作者或算法工程师加入,算法工程师招聘-兔展智能.pdf






If you like our project, please give us a star ⭐ on GitHub for latest update.
📣 News
- [2026.03.08] 👋👋👋 We introduce Helios, a breakthrough video generation model that achieves minute-scale, high-quality video synthesis at 19.5 FPS on a single H100 GPU — without relying on conventional long video anti-drifting strategies or standard video acceleration techniques. Welcome to check Technical Report!
- [2025.06.05] 🔥🔥🔥 We release version 1.5.0, our most powerful model! By introducing a higher-compression WFVAE and an improved sparse DiT architecture, SUV, we achieve performance comparable to HunyuanVideo (Open-Source) using an 8B-scale model and 40 million video samples. Version 1.5.0 is fully trained and inferred on Ascend 910-series accelerators; Please check the mindspeed_mmdit branch for our new code and Report-v1.5.0.md for our report. The GPU version is coming soon.
- [2024.12.03] ⚡️ We released our arxiv paper and WF-VAE paper for v1.3. The next more powerful version is coming soon.
- [2024.10.16] 🎉 We released version 1.3.0, featuring: WFVAE, prompt refiner, data filtering strategy, sparse attention, and bucket training strategy. We also support 93x480p within 24G VRAM. More details can be found at our latest report.
- [2024.08.13] 🎉 We are launching Open-Sora Plan v1.2.0 I2V model, which is based on Open-Sora Plan v1.2.0. The current version supports image-to-video generation and transition generation (the starting and ending frames conditions for video generation). Check out the Image-to-Video section in this report.
- [2024.07.24] 🔥🔥🔥 v1.2.0 is here! Utilizing a 3D full attention architecture instead of 2+1D. We released a true 3D video diffusion model trained on 4s 720p. Check out our latest report.
- [2024.05.27] 🎉 We are launching Open-Sora Plan v1.1.0, which significantly improves video quality and length, and is fully open source! Please check out our latest report. Thanks to ShareGPT4Video's capability to annotate long videos.
- [2024.04.09] 🤝 Excited to share our latest exploration on metamorphic time-lapse video generation: MagicTime, which learns real-world physics knowledge from time-lapse videos.
- [2024.04.07] 🎉🎉🎉 Today, we are thrilled to present Open-Sora-Plan v1.0.0, which significantly enhances video generation quality and text control capabilities. See our report. Thanks to HUAWEI NPU for supporting us.
- [2024.03.27] 🚀🚀🚀 We release the report of VideoCausalVAE, which supports both images and videos. We present our reconstructed video in this demonstration as follows. The text-to-video model is on the way.
- [2024.03.01] 🤗 We launched a plan to reproduce Sora, called Open-Sora Plan! Welcome to watch 👀 this repository for the latest updates.
😍 Gallery
Text-to-Video Generation of Open-Sora Plan v1.5.0.
Youtube:

Bilibili:
😮 Highlights
Open-Sora Plan shows excellent performance in video generation.
- With an 8×8×8 downsampling rate, but achieves higher PSNR than the VAE used in Wan2.1. Lowers the training cost for the DiT built upon it.
🚀 More powerful sparse dit
- The more powerful sparse attention architecture, SUV, achieves performance close to dense DiT while providing over a 35% speedup.

🐳 Resource
| Version |
Architecture |
Diffusion Model |
CausalVideoVAE |
Data |
Prompt Refiner |
| v1.5.0 |
SUV (Skiparse 3D) |
121x576x1024[5] |
Anysize_8x8x8_32dim |
- |
- |
| v1.3.0 [4] |
Skiparse 3D |
Anysize in 93x640x640[3], Anysize in 93x640x640_i2v[3] |
Anysize |
prompt_refiner |
checkpoint |
| v1.2.0 |
Dense 3D |
93x720p, 29x720p[1], 93x480p[1,2], 29x480p, 1x480p, 93x480p_i2v |
Anysize |
Annotations |
- |
| v1.1.0 |
2+1D |
221x512x512, 65x512x512 |
Anysize |
Data and Annotations |
- |
| v1.0.0 |
2+1D |
65x512x512, 65x256x256, 17x256x256 |
Anysize |
Data and Annotations |
- |
[1] Please note that the weights for v1.2.0 29×720p and 93×480p were trained on Panda70M and have not undergone final high-quality data fine-tuning, so they may produce watermarks.
[2] We fine-tuned 3.5k steps from 93×720p to get 93×480p for community research use.
[3] The model is trained arbitrarily on stride=32. So keep the resolution of the inference a multiple of 32. Frames need to be 4n+1, e.g. 93, 77, 61, 45, 29, 1 (image).
[4] Model weights are also available at OpenMind and WiseModel.
[5] The current model weights are only compatible with the NPU + MindSpeed-MM framework. Model weights are also available at and modelers.
[!Warning]
🚨 For version 1.2.0, we no longer support 2+1D models.
⚙️ How to start
GPU
coming soon...
NPU
Please check out the mindspeed_mmdit branch and follow the README.md for configuration.
📖 Technical report
Please check Report-v1.5.0.md.
💡 How to Contribute
We greatly appreciate your contributions to the Open-Sora Plan open-source community and helping us make it even better than it is now!
For more details, please refer to the Contribution Guidelines
- Allegro: Allegro is a powerful text-to-video model that generates high-quality videos up to 6 seconds at 15 FPS and 720p resolution from simple text input based on our Open-Sora Plan. The significance of open-source is becoming increasingly tangible.
- Latte: It is a wonderful 2+1D video generation model.
- PixArt-alpha: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis.
- ShareGPT4Video: Improving Video Understanding and Generation with Better Captions.
- VideoGPT: Video Generation using VQ-VAE and Transformers.
- DiT: Scalable Diffusion Models with Transformers.
- FiT: Flexible Vision Transformer for Diffusion Model.
- Positional Interpolation: Extending Context Window of Large Language Models via Positional Interpolation.
🔒 License
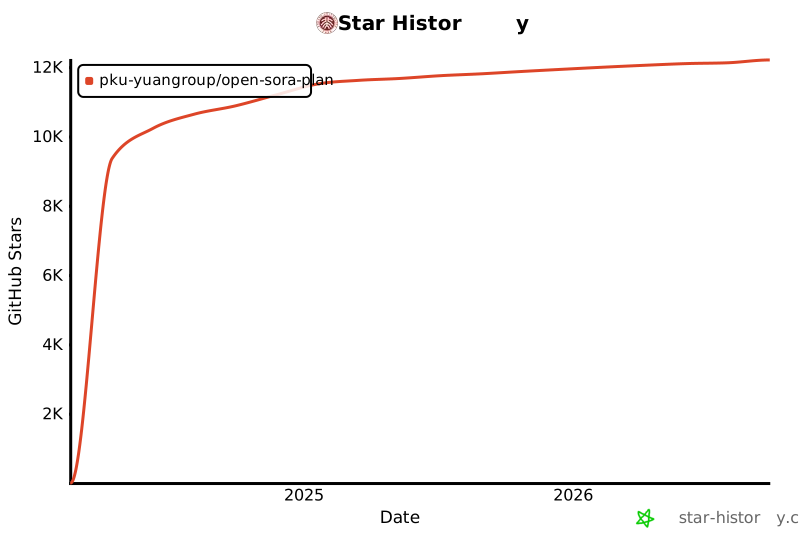
✨ Star History
✏️ Citing
@article{lin2024open,
  title={Open-Sora Plan: Open-Source Large Video Generation Model},
  author={Lin, Bin and Ge, Yunyang and Cheng, Xinhua and Li, Zongjian and Zhu, Bin and Wang, Shaodong and He, Xianyi and Ye, Yang and Yuan, Shenghai and Chen, Liuhan and others},
  journal={arXiv preprint arXiv:2412.00131},
  year={2024}
}
@article{helios,
  title={Helios: Real Real-Time Long Video Generation Model},
  author={Yuan, Shenghai and Yin, Yuanyang and Li, Zongjian and Huang, Xinwei and Yang, Xiao and Yuan, Li},
  journal={arXiv preprint arXiv:2603.04379},
  year={2026}
}
@article{li2024wf,
  title={WF-VAE: Enhancing Video VAE by Wavelet-Driven Energy Flow for Latent Video Diffusion Model},
  author={Li, Zongjian and Lin, Bin and Ye, Yang and Chen, Liuhan and Cheng, Xinhua and Yuan, Shenghai and Yuan, Li},
  journal={arXiv preprint arXiv:2411.17459},
  year={2024}
}


 Open-Sora Plan 是一个开源社区项目,旨在复现 OpenAI 的 Sora 文生视频模型,由北京大学相关的 AIGC 实验室牵头,华为和鹏城实验室也参与了贡献。