MiniCPM-OCR is a family of models for efficient document parsing and text recognition. MiniCPM-OCR 1.0 parses Chinese and English documents and PDFs, balancing quality and efficiency across challenging inputs such as scans, photographs, curved pages, and recaptured documents. MiniCPM-OCR Jev evaluates OCR results at the region level, distinguishing problematic regions from reliable ones. It works with different parsing models to help users locate content that needs review.
📢 News
- [2026.11.05] The official MiniCPM-OCR 1.0 Docker image is now available, bundling model weights, the SDK, and vLLM for end-to-end image and PDF parsing. See Docker deployment to get started.
- 🔥🔥🔥 [2026.11.02] MiniCPM-OCR 1.0 now runs on iOS! Parse documents entirely on your device, even offline. Try it now.
- [2026.11.09] pip SDK 1.0.5: Parse several inputs in one run, with one result per file.
--split-images makes each standalone image its own document.
- [2026.11.02] pip SDK 1.0.4: JSON output now uses the same format as the online document parsing API. Page orientation is corrected automatically by default, and GIF images are now supported.
- [2026.10.30] The Web Demo is now open source, with support for self-hosting and switching between Chinese and English. See the Web Demo deployment tutorial.
- [2026.10.29] SDK 1.0.3: Markdown output preserves text recognized in image regions and includes links to the corresponding cropped images. The Skill now includes an Ollama deployment guide.
- 🚀🚀🚀 [2026.10.27] MiniCPM-OCR 1.0 and MiniCPM-OCR Jev are now open source! Get started with the model weights, the pip SDK, the Skill, and a free API.
MiniCPM-OCR 1.0
MiniCPM-OCR 1.0 (1.3B) is the first OCR-specific model in the MiniCPM-V/o family. It focuses on text-centric document understanding, covering text, tables, formulas, charts, seals, and structured information extraction. Its key features include:
- 🏆 SOTA document parsing: MiniCPM-OCR 1.0 achieves a SOTA score of 93.68 on Real5-OmniDocBench, a benchmark for real-world document parsing, and demonstrates leading parsing capabilities on OmniDocBench v1.6, Wild-OmniDocBench, and olmOCR-Bench. It supports Chinese and English documents and PDFs, handling both standard documents and challenging capture conditions, including scans, curved pages, photographs, skewed pages, and recaptured documents.
- ⚡ Efficient inference. With DSpark decoding acceleration (DSpark-BF16, DSpark-GGUF), MiniCPM-OCR 1.0 improves end-to-end processing efficiency by 55%. Its throughput is approximately 1.49× that of PaddleOCR-VL-1.6 and 3.62× that of MinerU2.5 Pro, reducing the time needed for large-scale document parsing.
- 🔍 General recognition and information extraction: MiniCPM-OCR 1.0 achieves a SOTA score of 54.7 on OCRBench v2, demonstrating strong general OCR capabilities. It also supports key information extraction (KIE), extracting relevant document content for downstream information management and automated processing.
- 🛠️ Easy deployment and development: MiniCPM-OCR 1.0 supports vLLM, SGLang, llama.cpp, and Ollama from day one, with multiple chip platforms and quantized versions available at release. It supports further fine-tuning and provides a pip SDK and a full-featured API for application integration and customization. You can also get started quickly with SKILL.md. Explore parsing results with the online Demo (CN / Global).
Among the open-source OCR models shown below, MiniCPM-OCR 1.0 achieves 1.2 pages/s and the highest overall performance on OmniDocBench v1.6, Real5-OmniDocBench, Wild-OmniDocBench, and olmOCR-Bench.
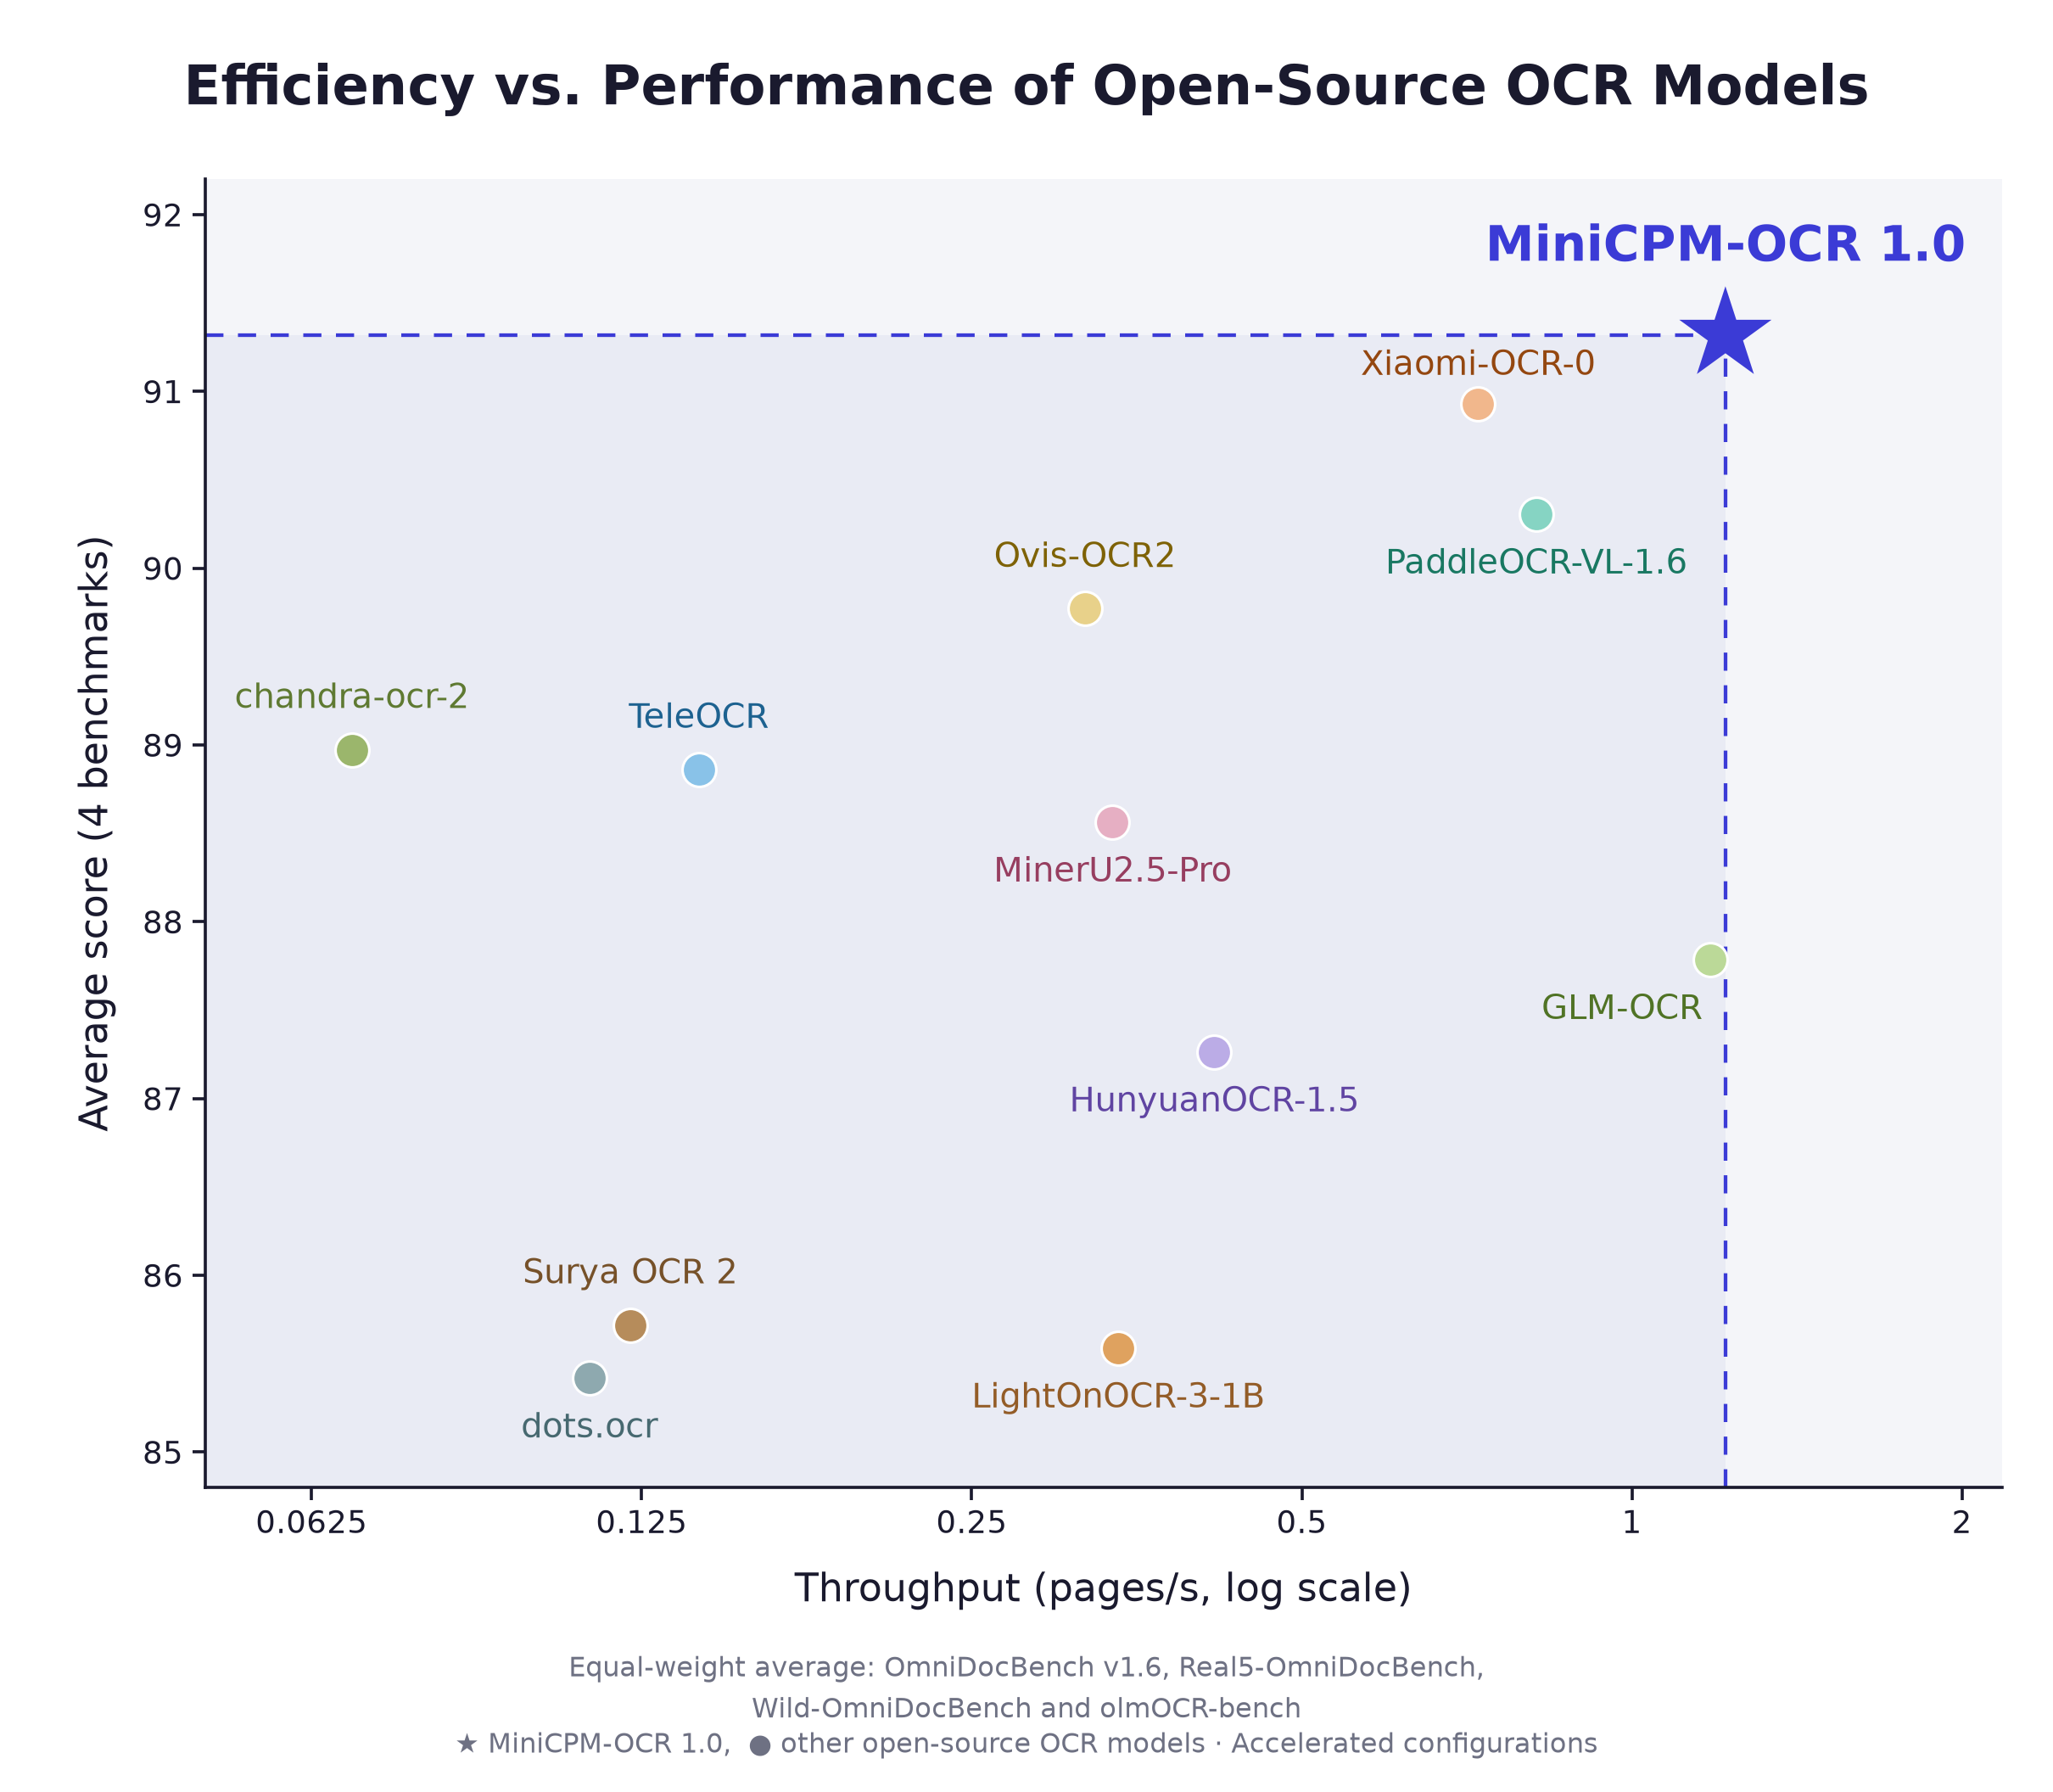
See the reproduction guide for test settings and reproduction details, and the model guide throughput evaluation for each model's throughput.
Benchmark Comparisons
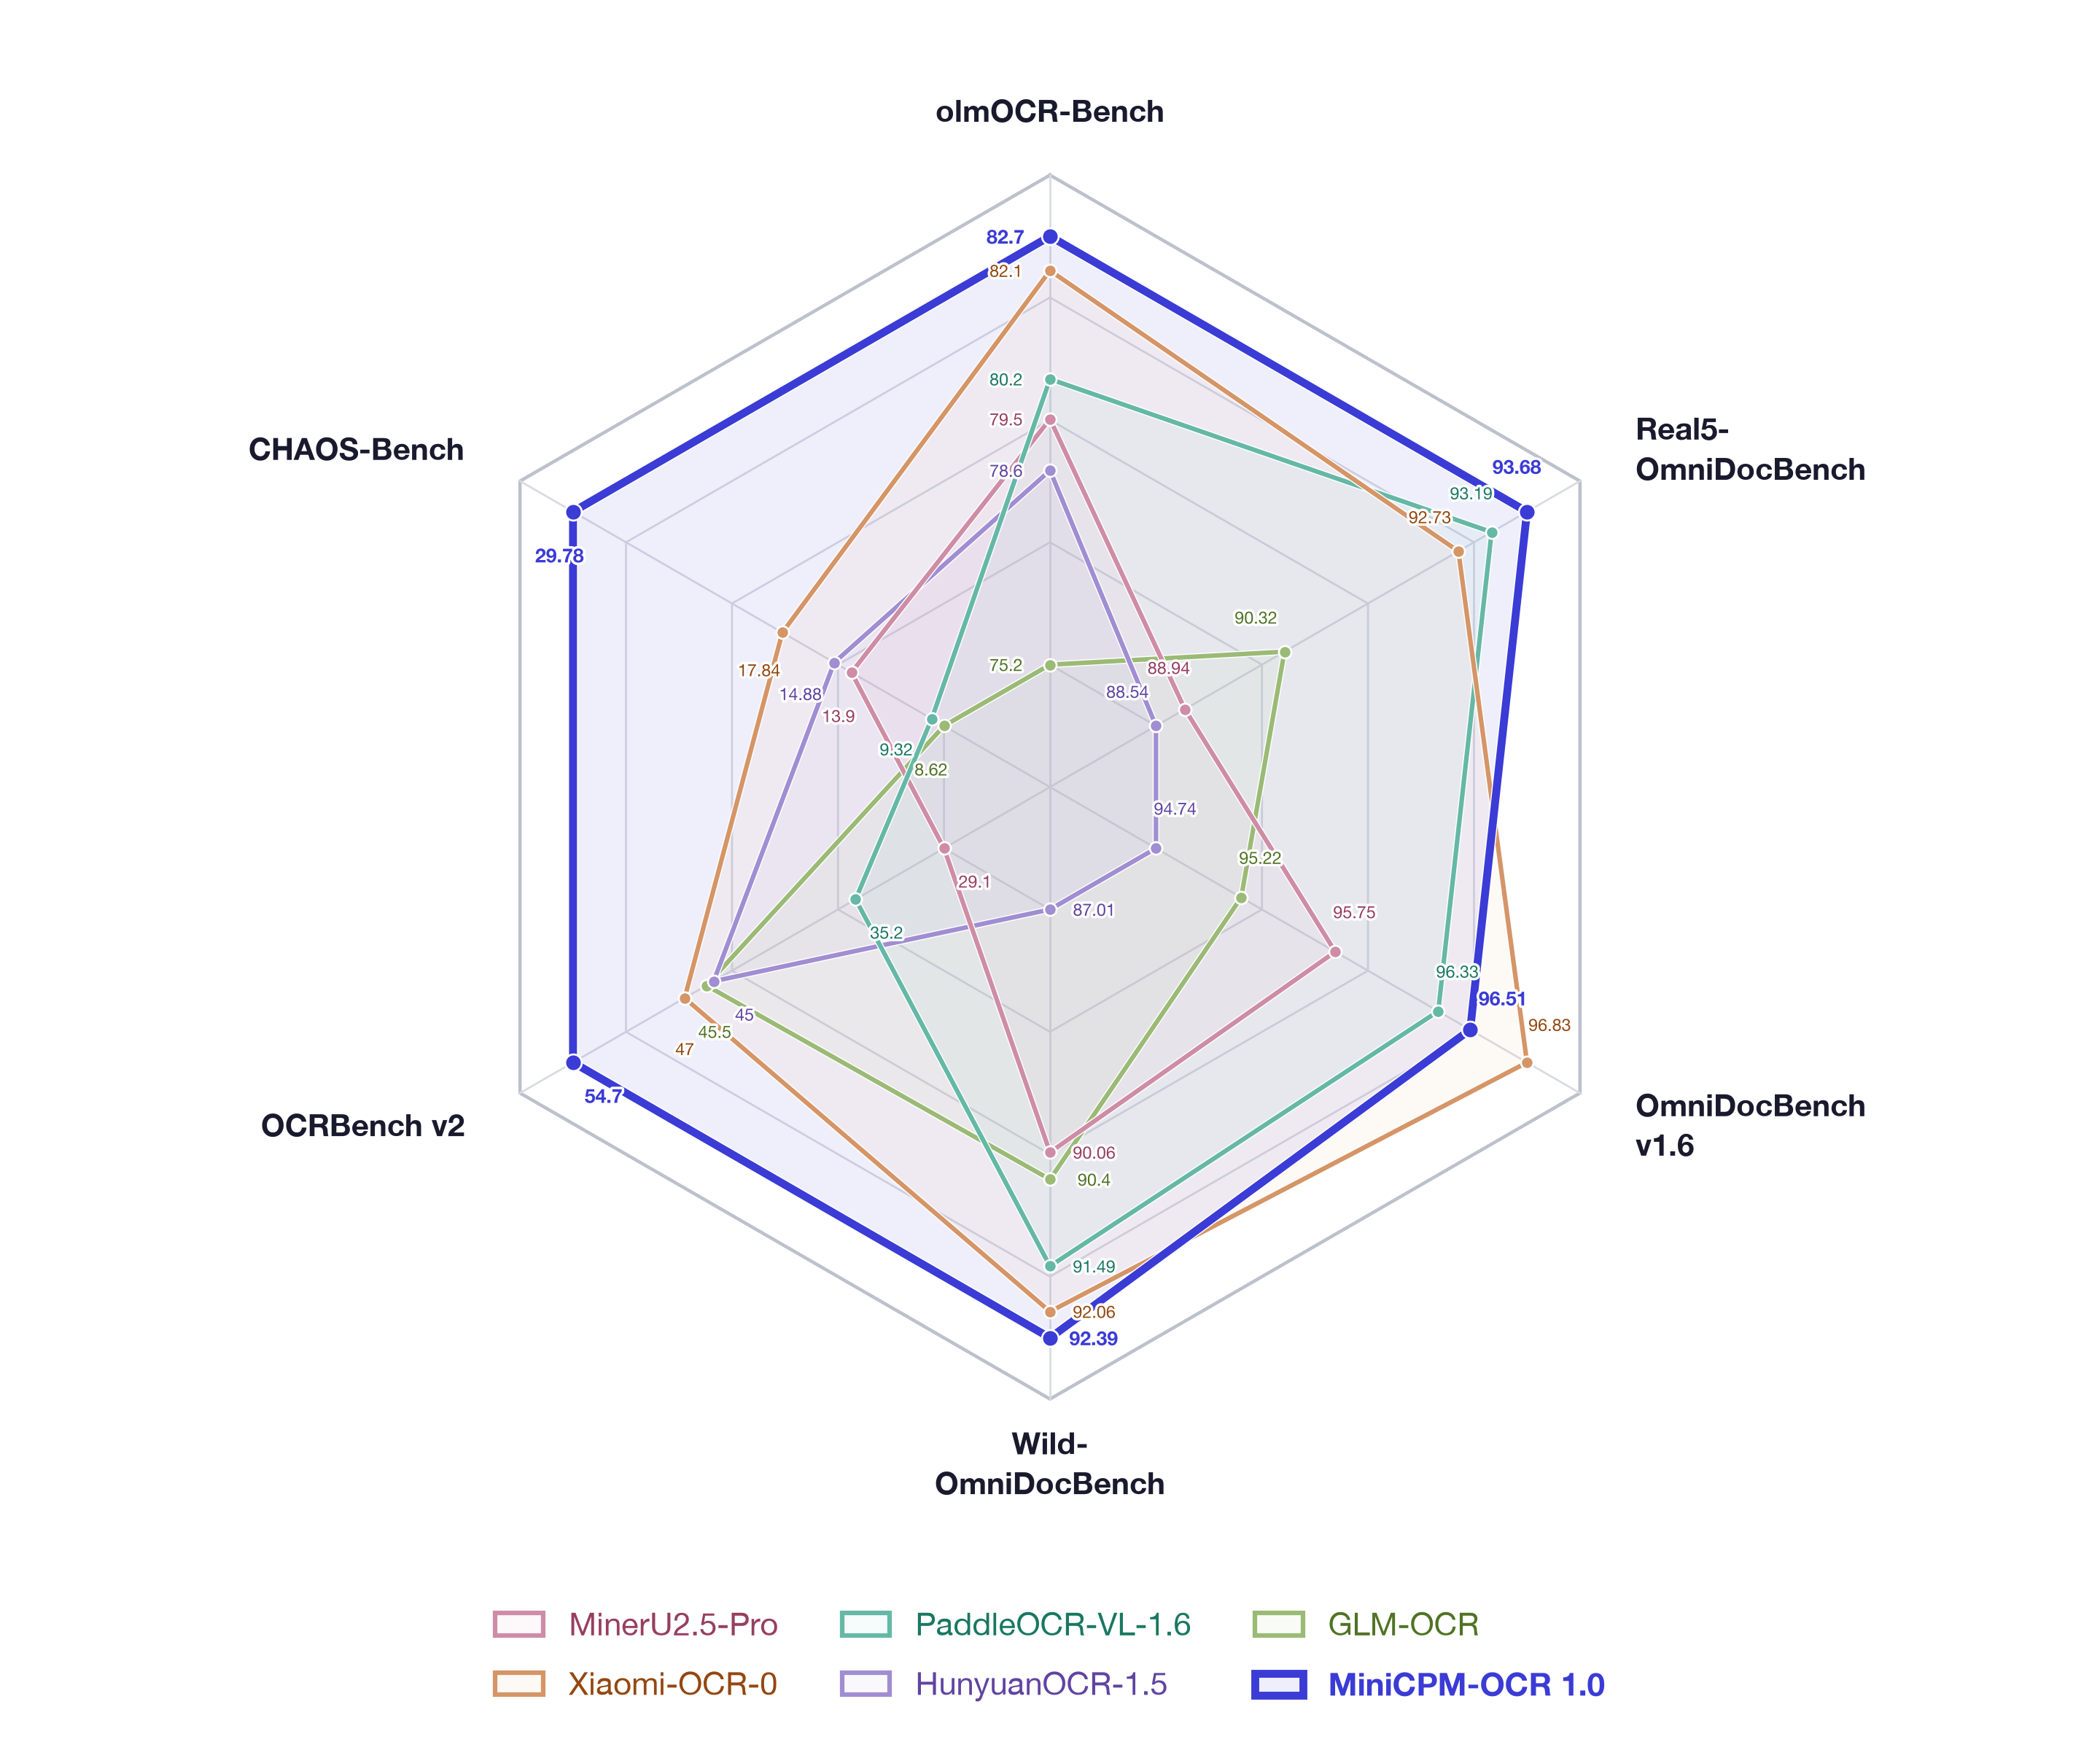
View complete MiniCPM-OCR 1.0 evaluation results
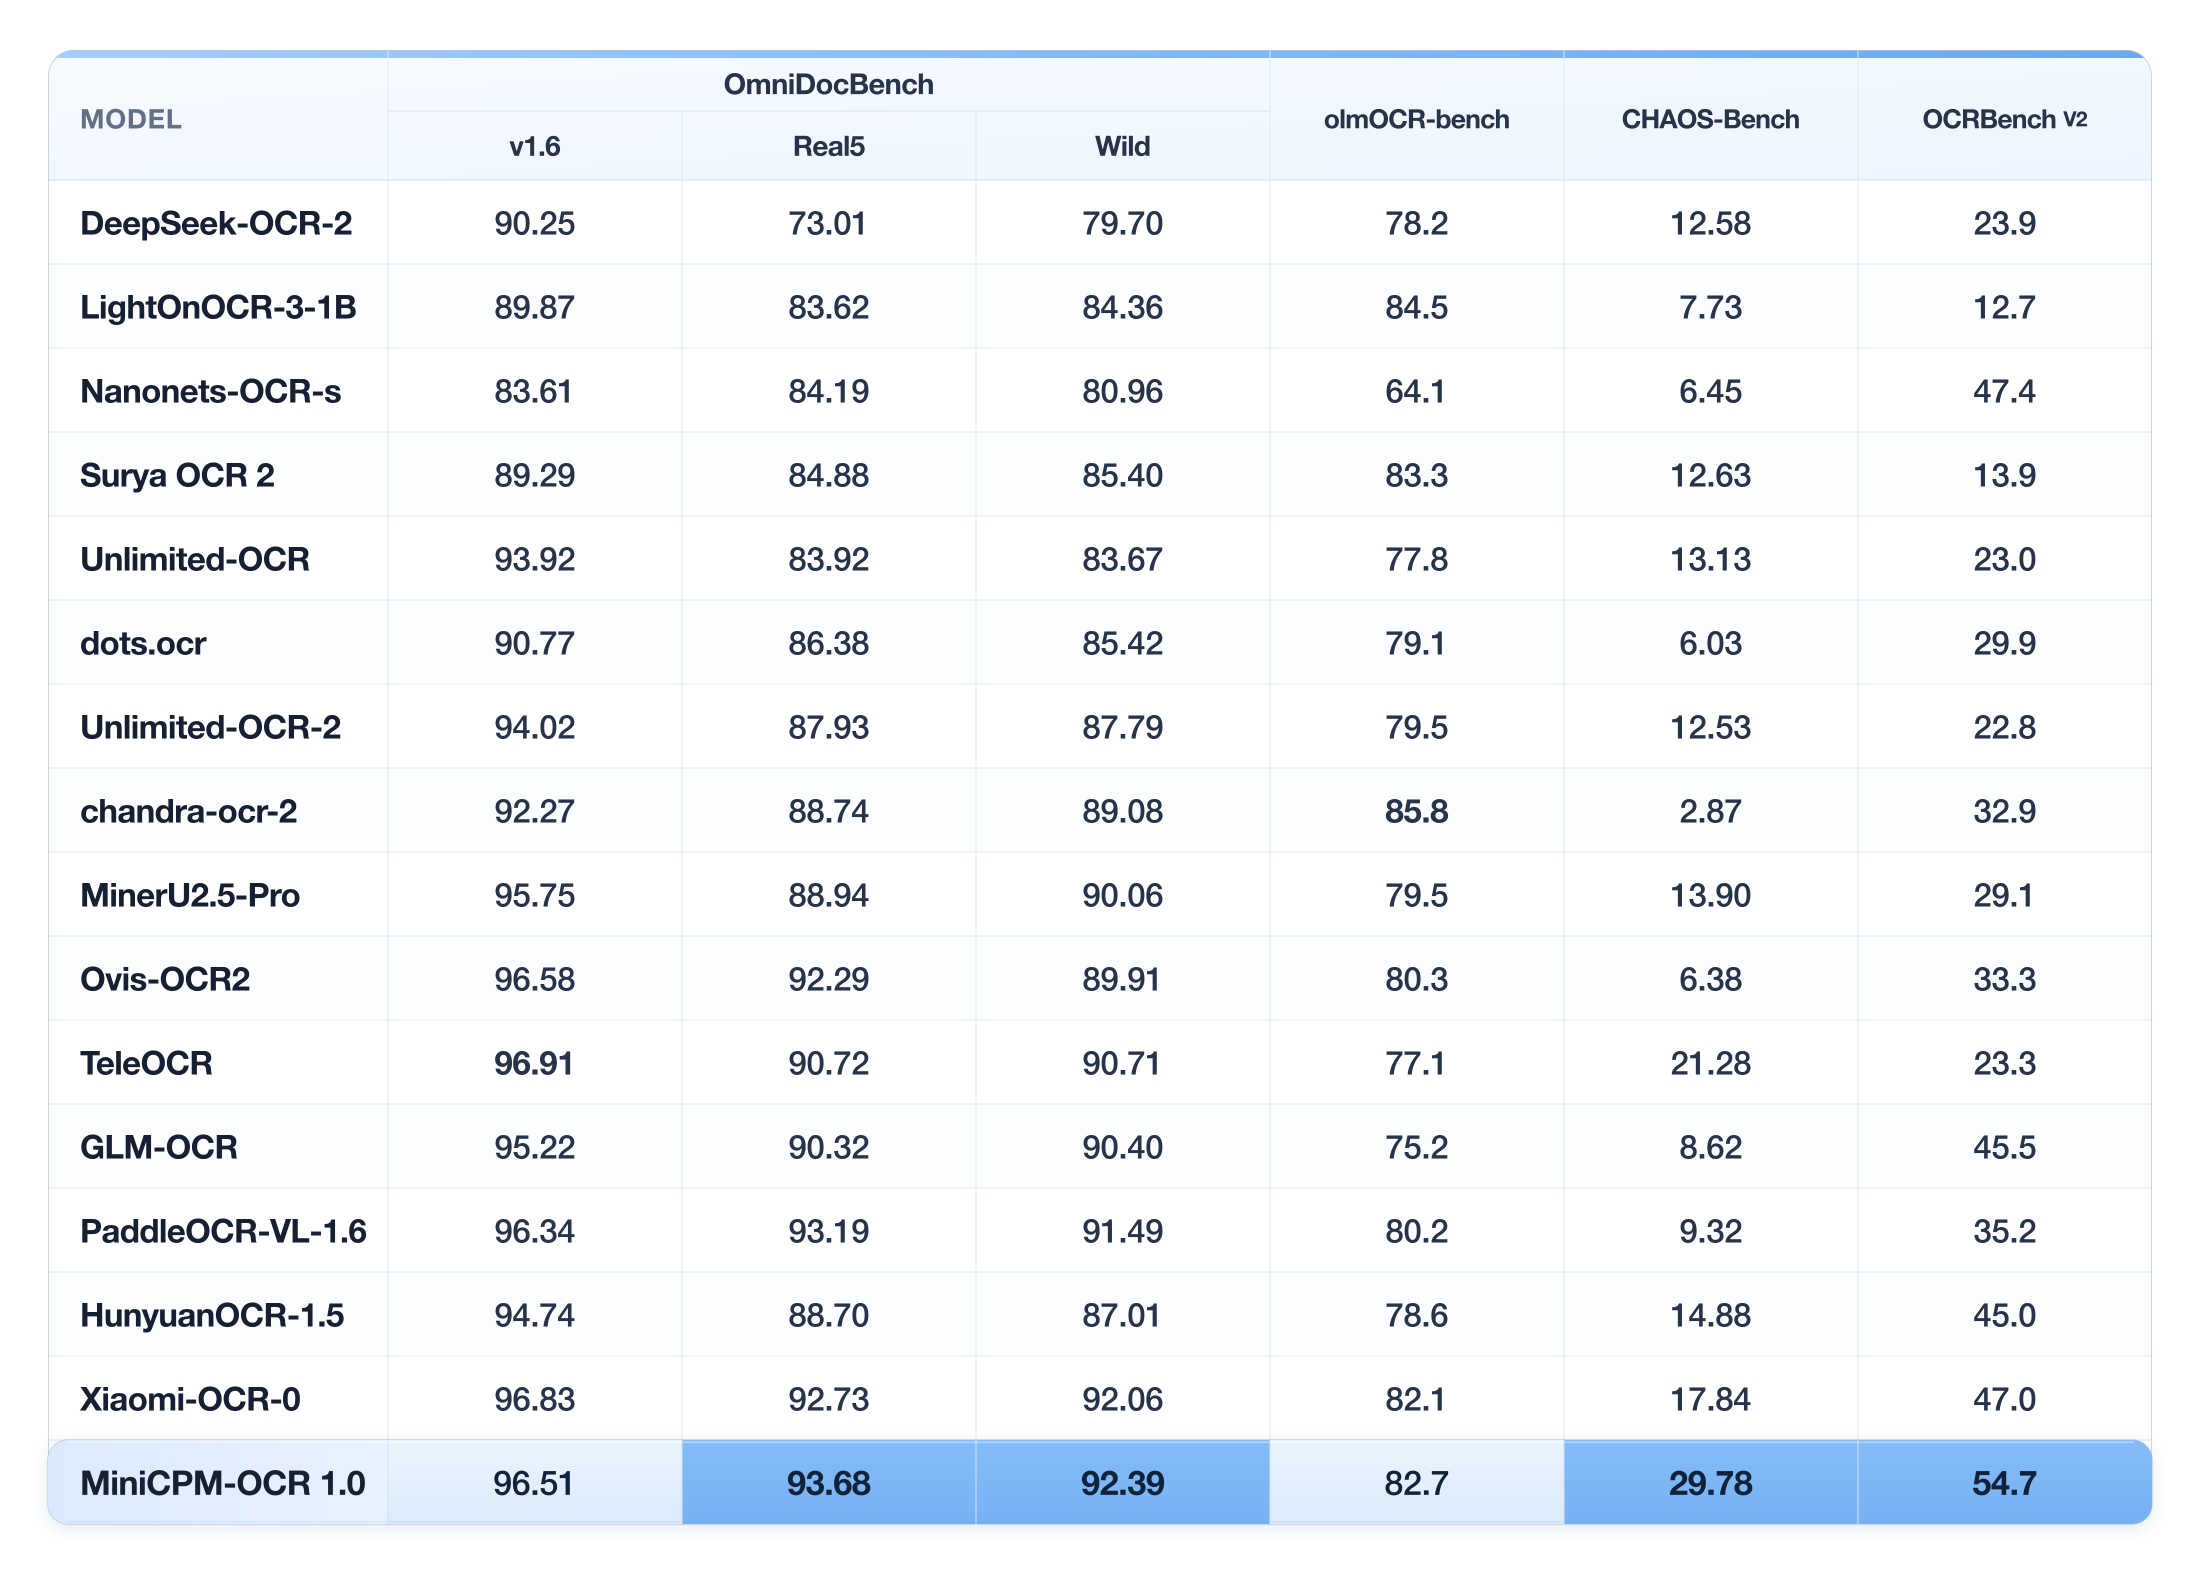
See the MiniCPM-OCR 1.0 guide for per-benchmark bar charts and throughput details.
Examples
Left to right: original document, detected layout, and rendered Markdown.
English Documents
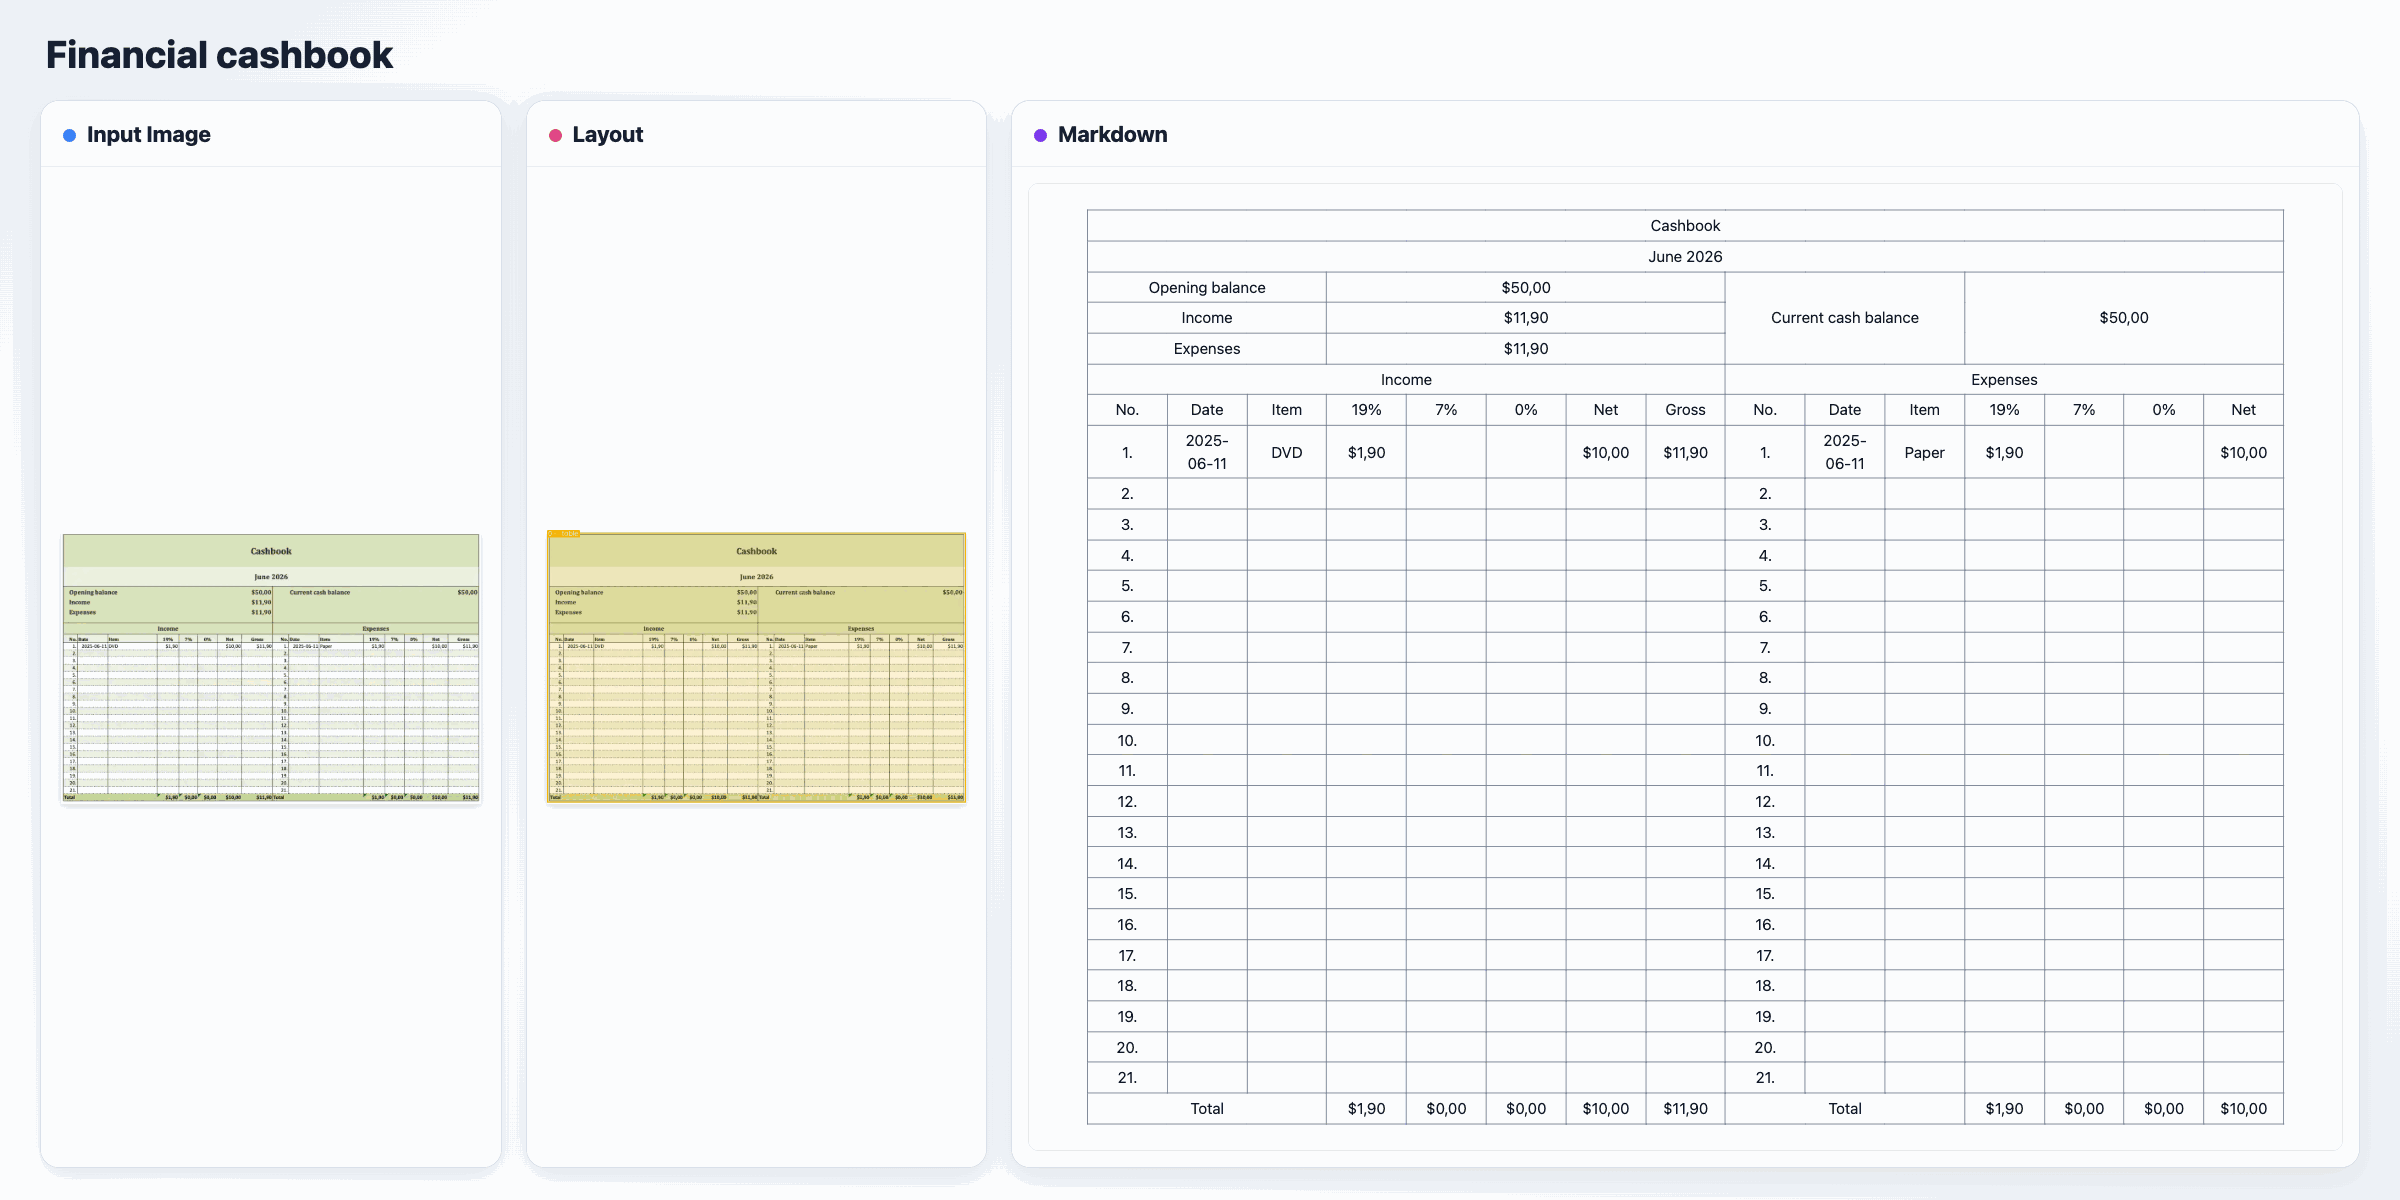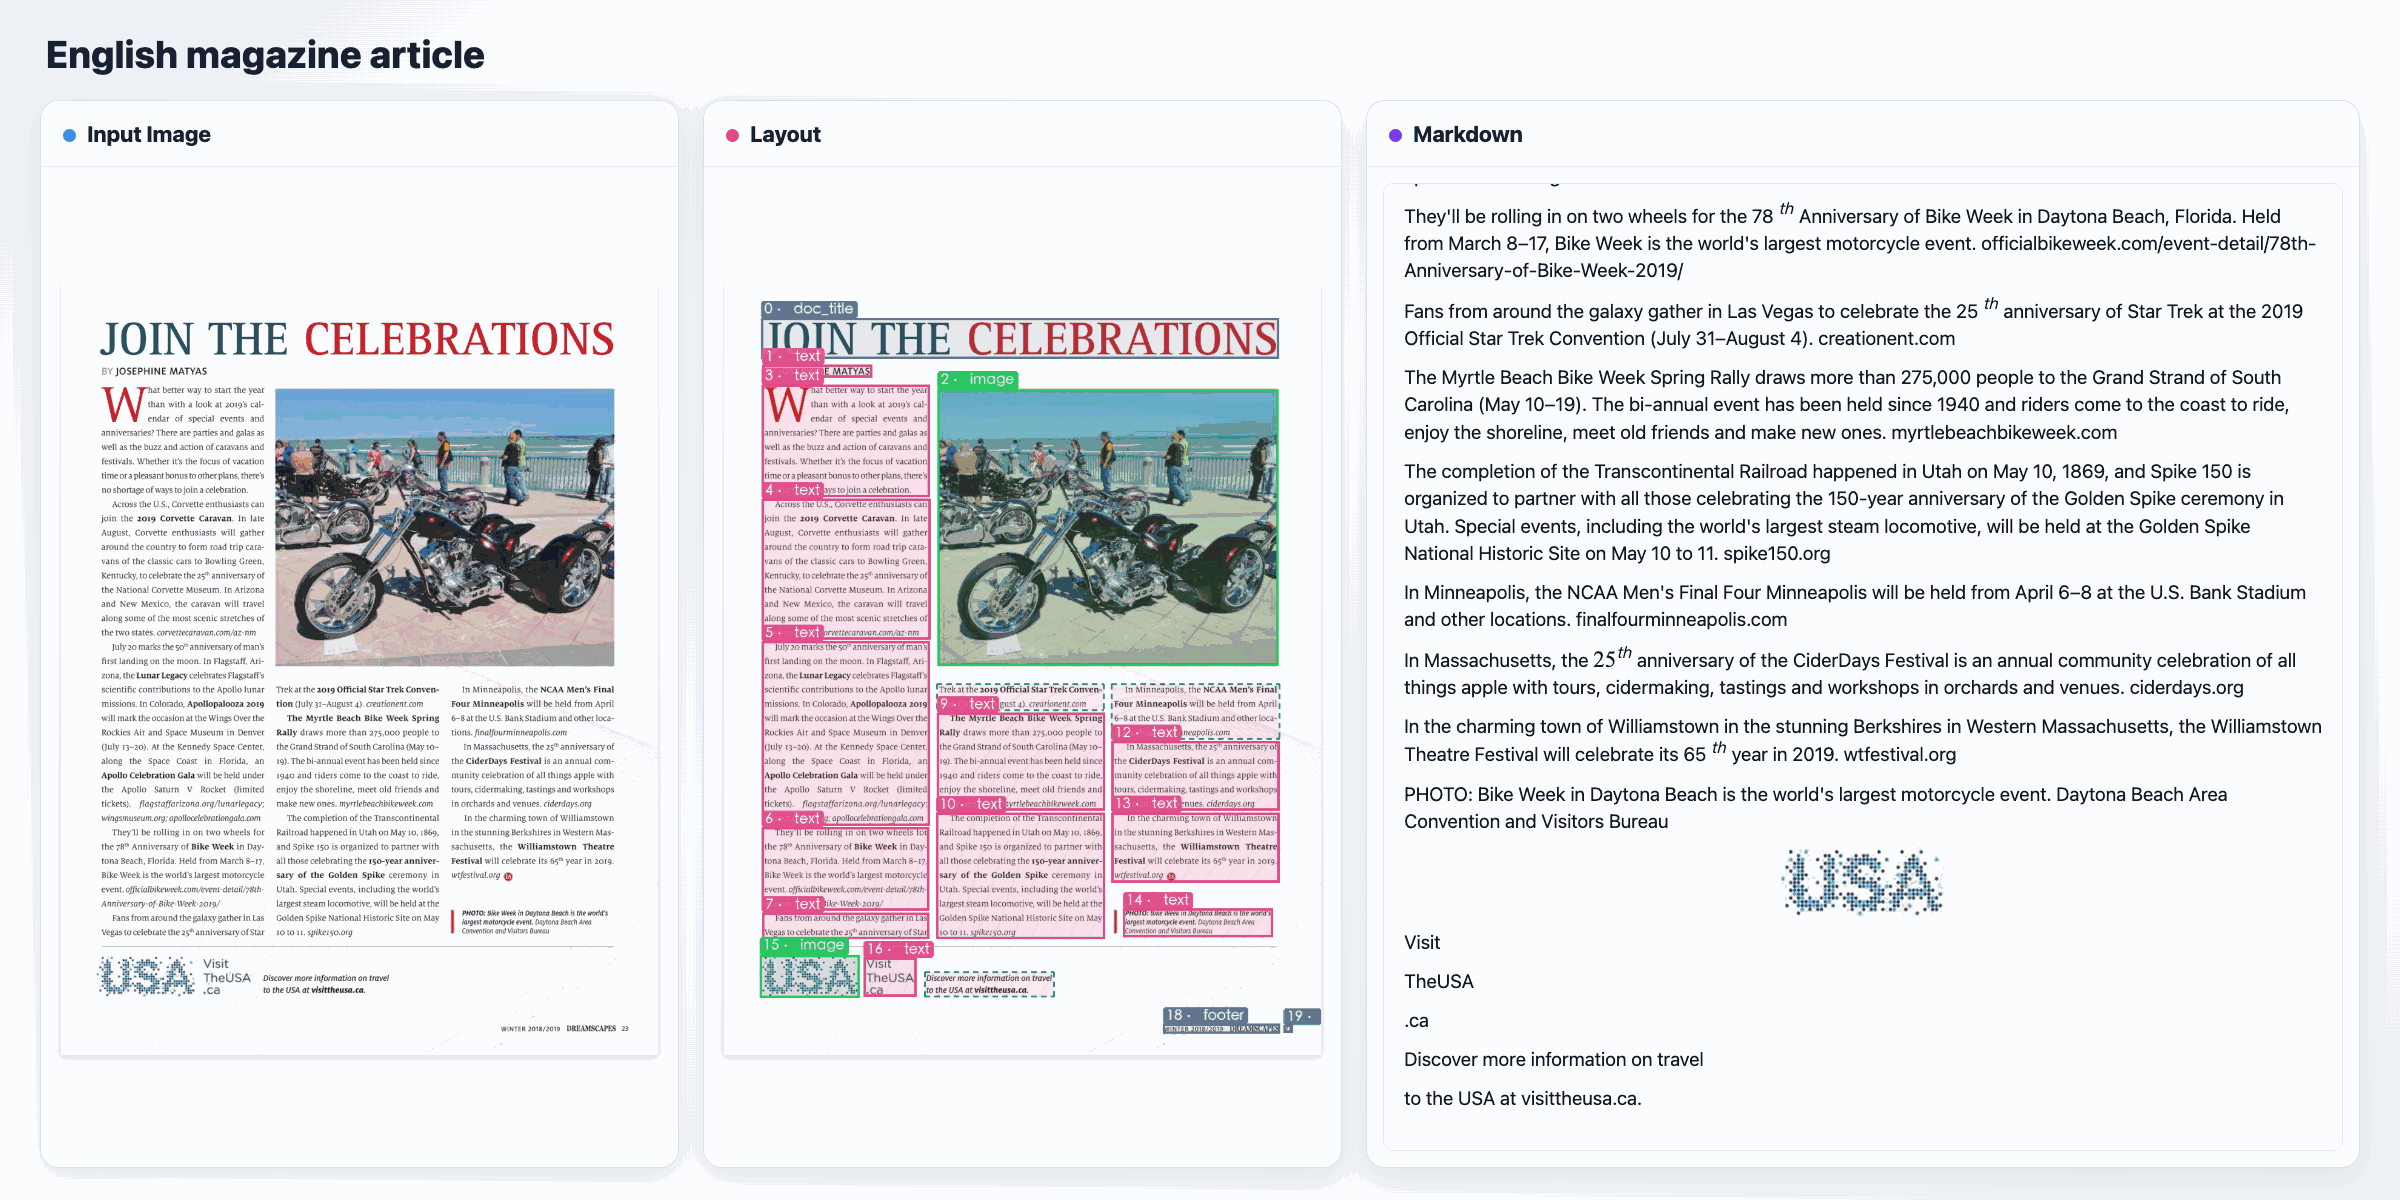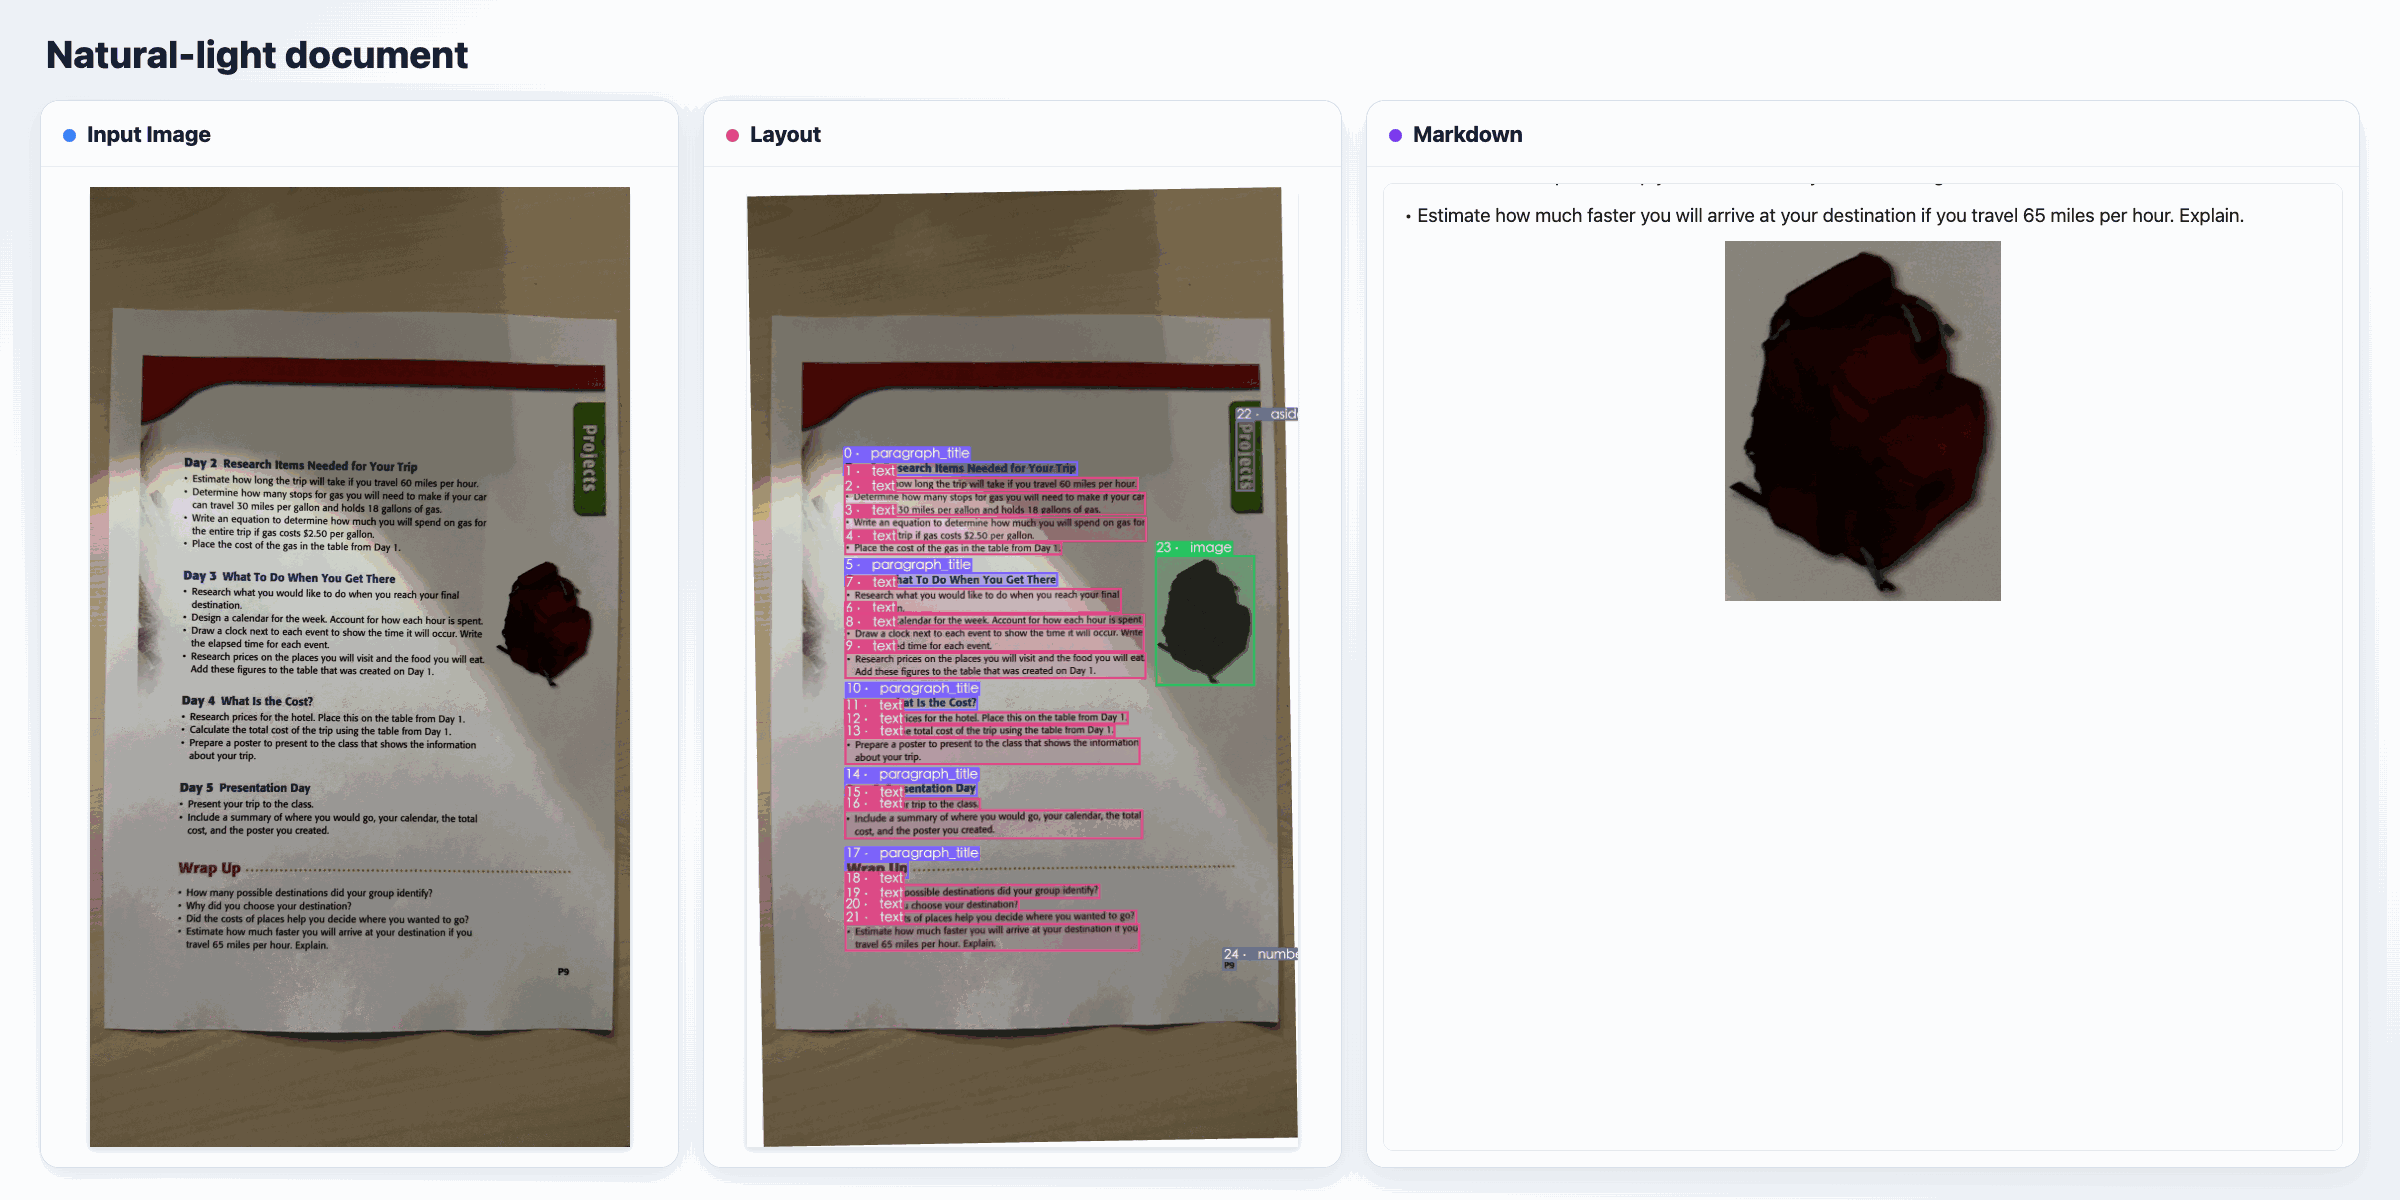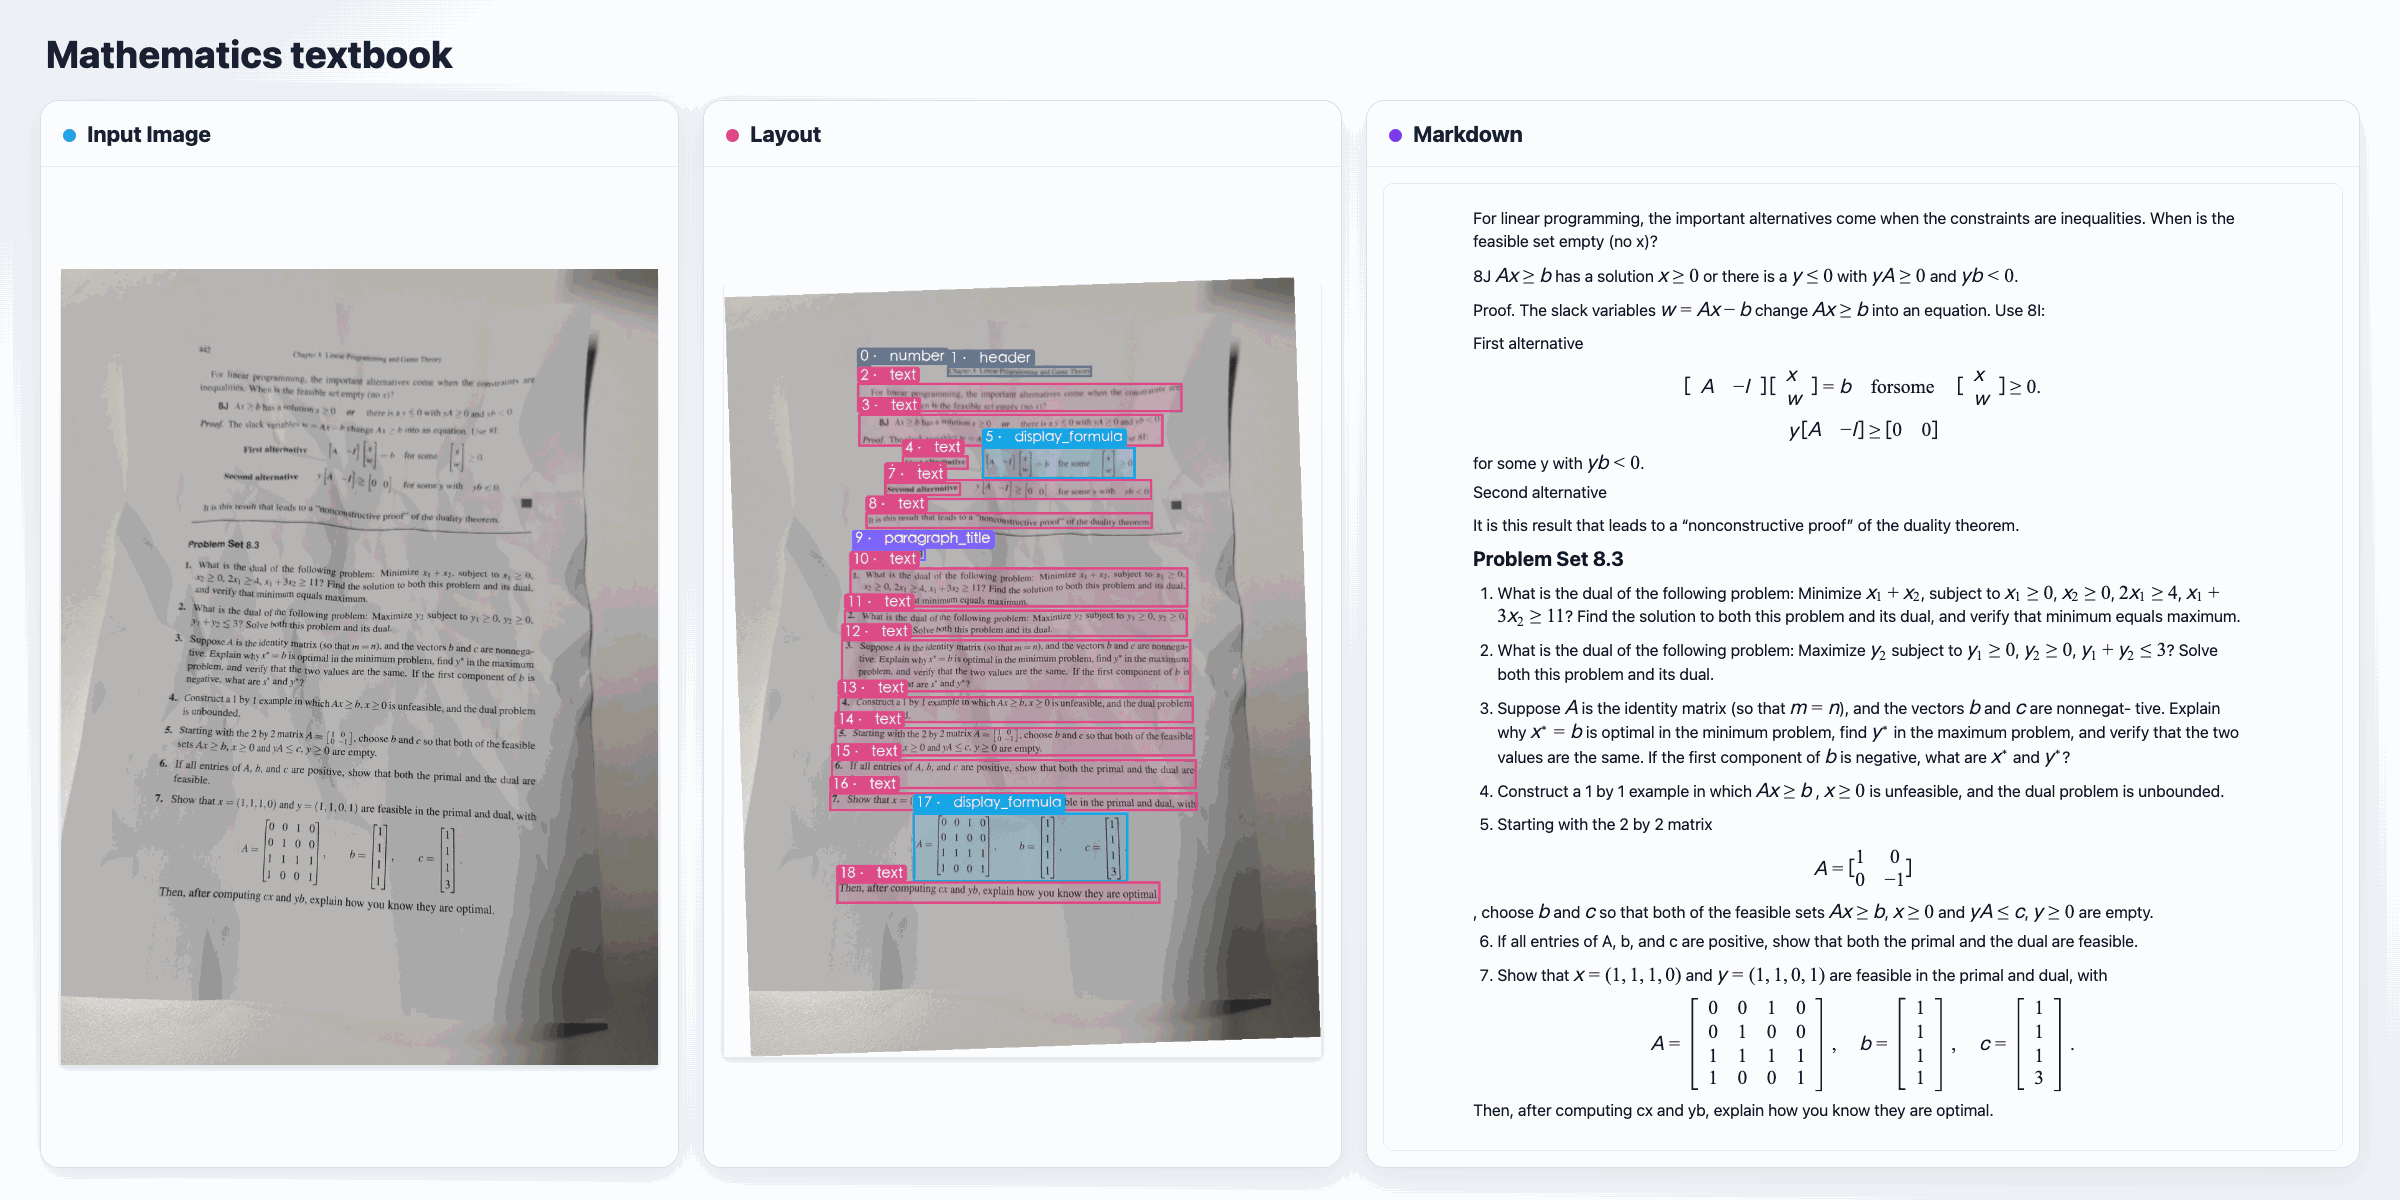
More English Examples
Original documents and parsed results, side by side.
Chinese Documents
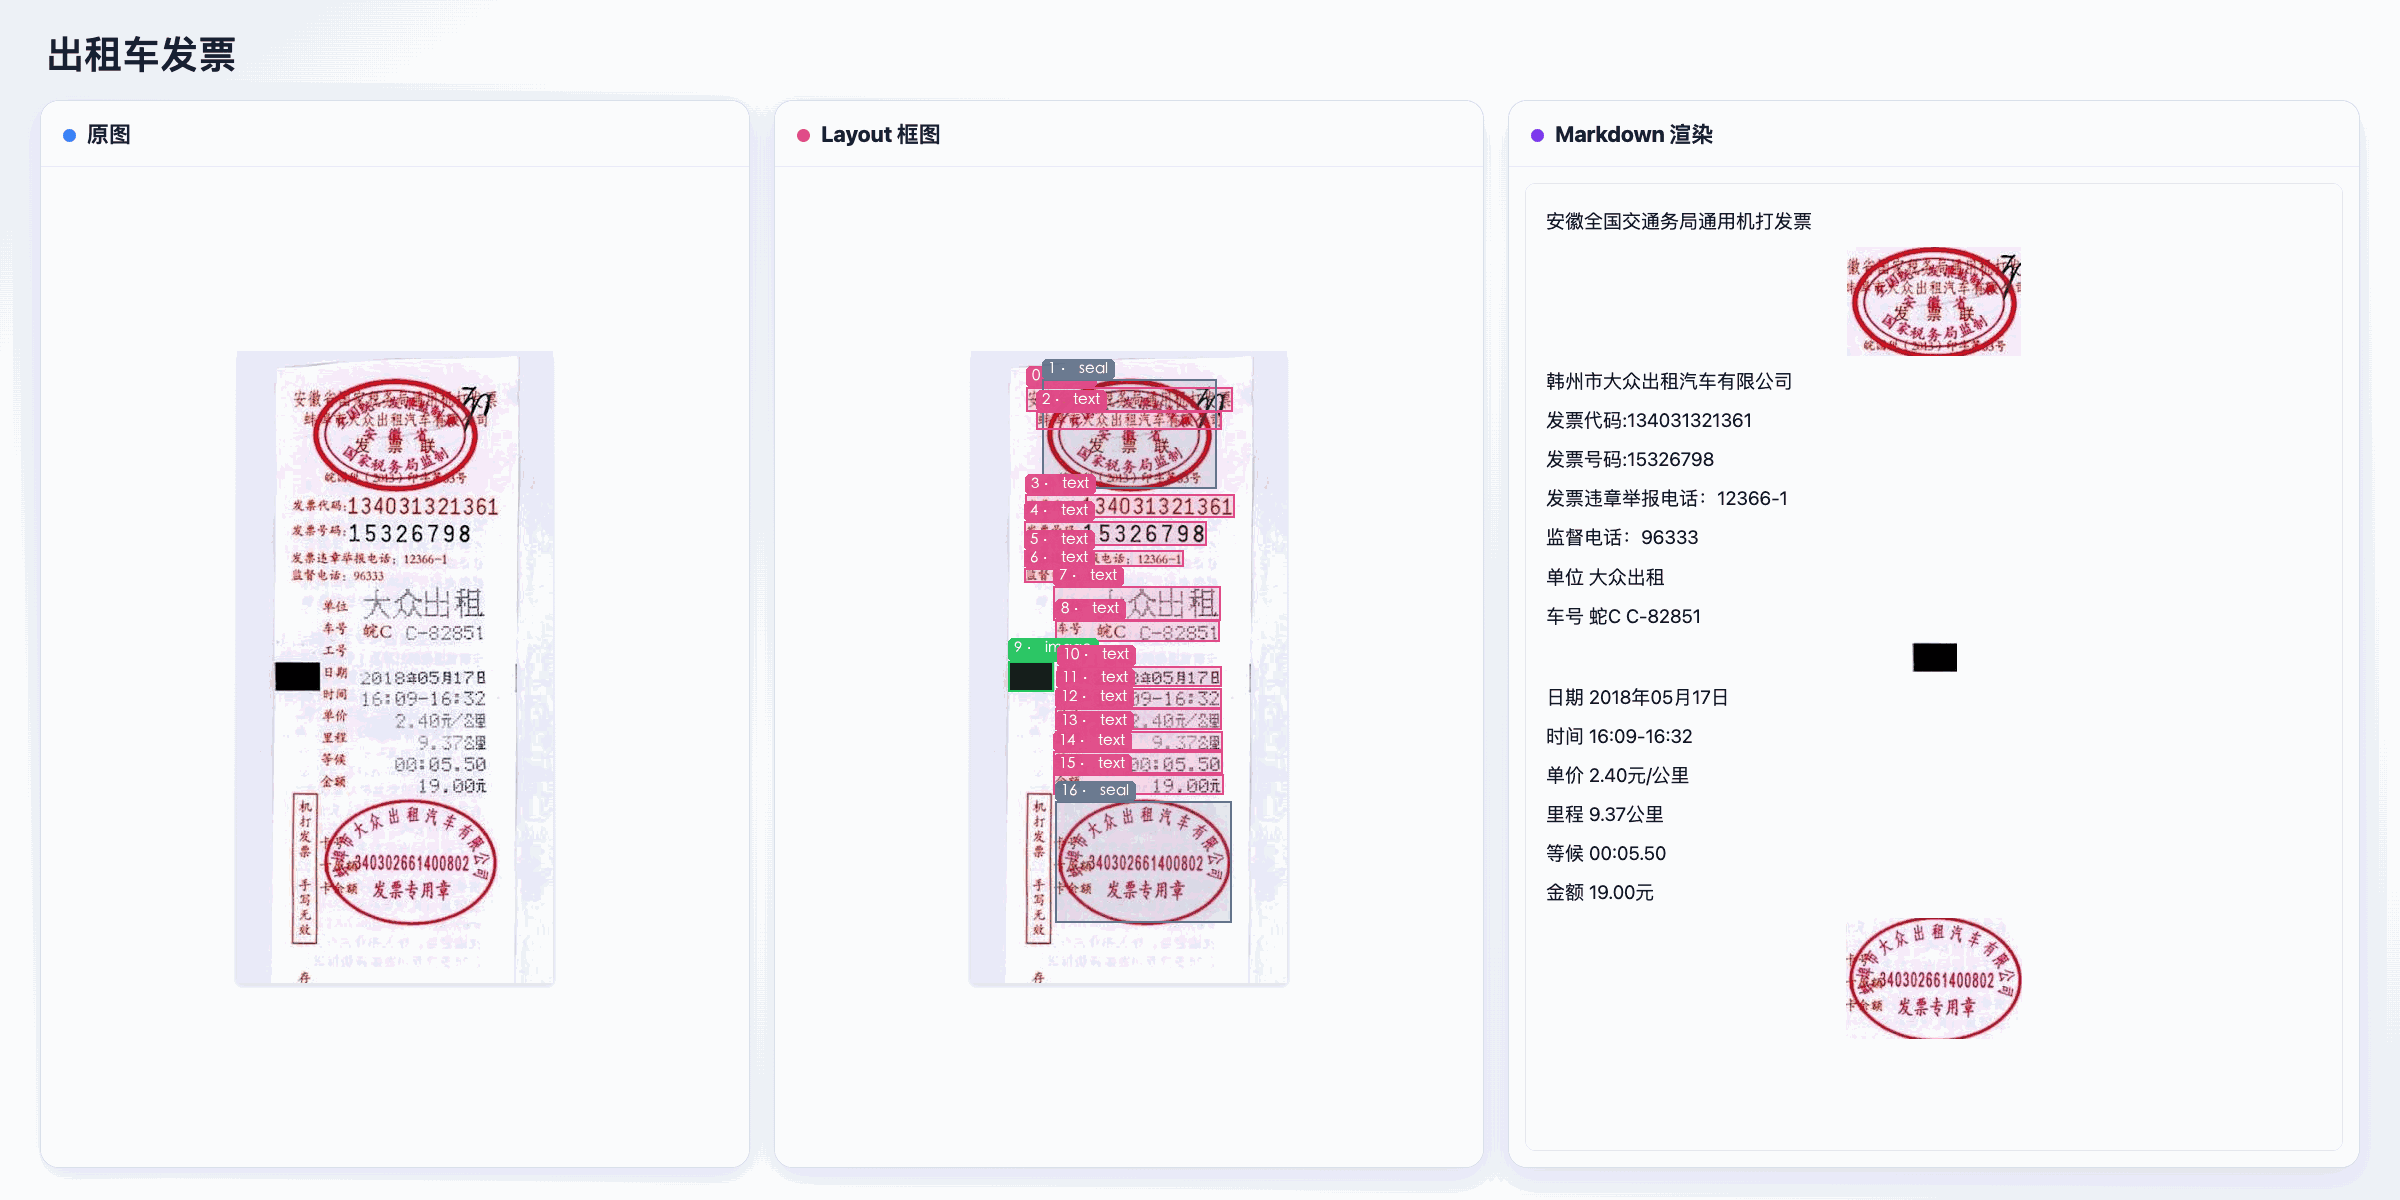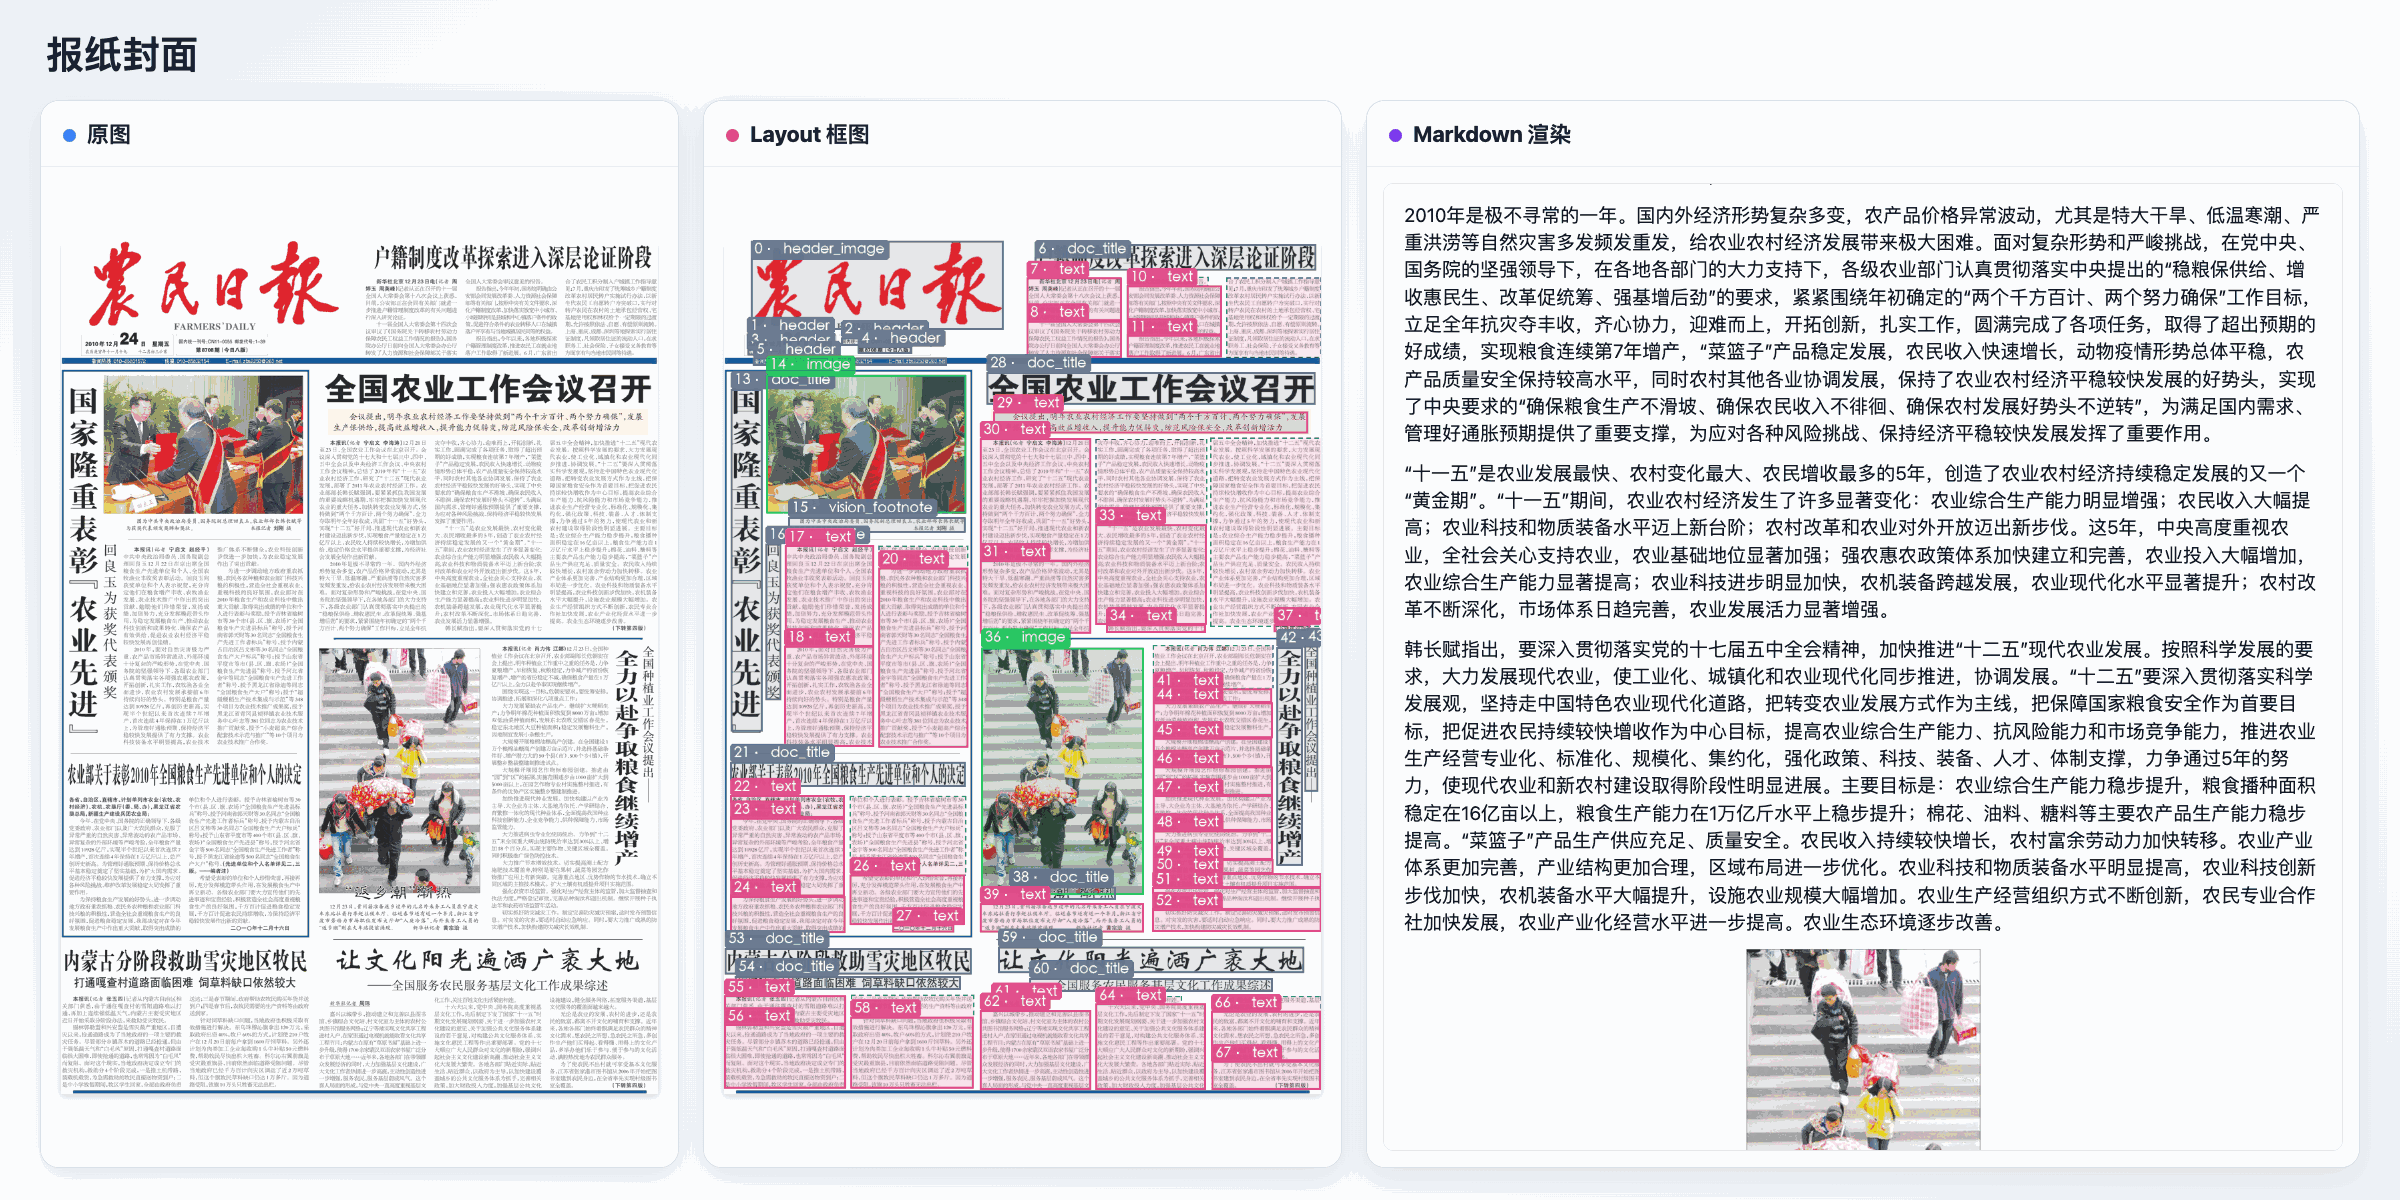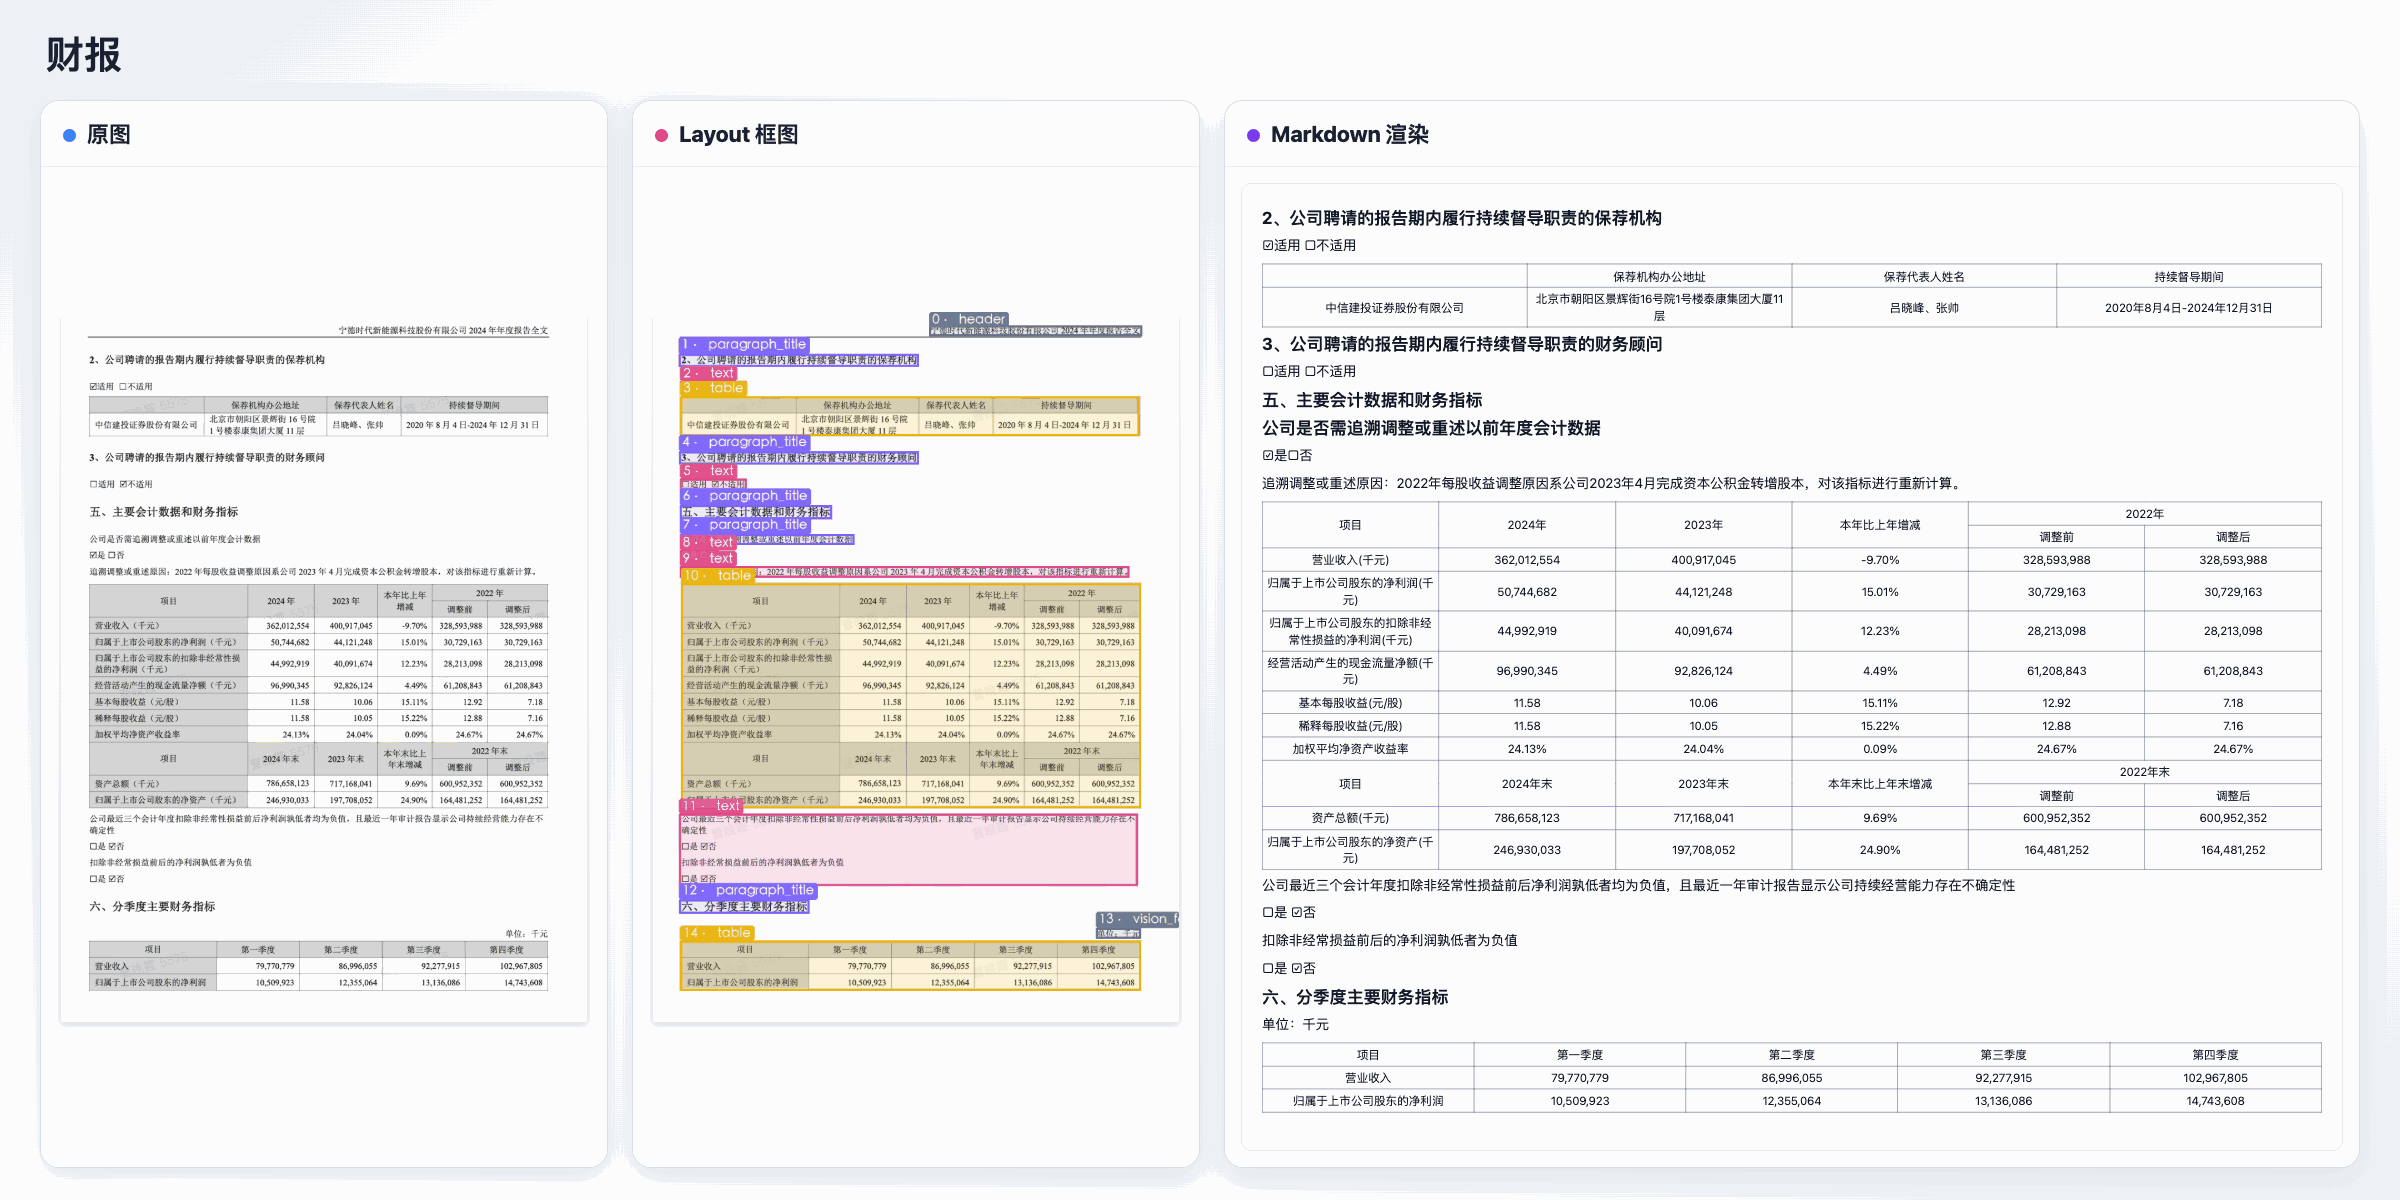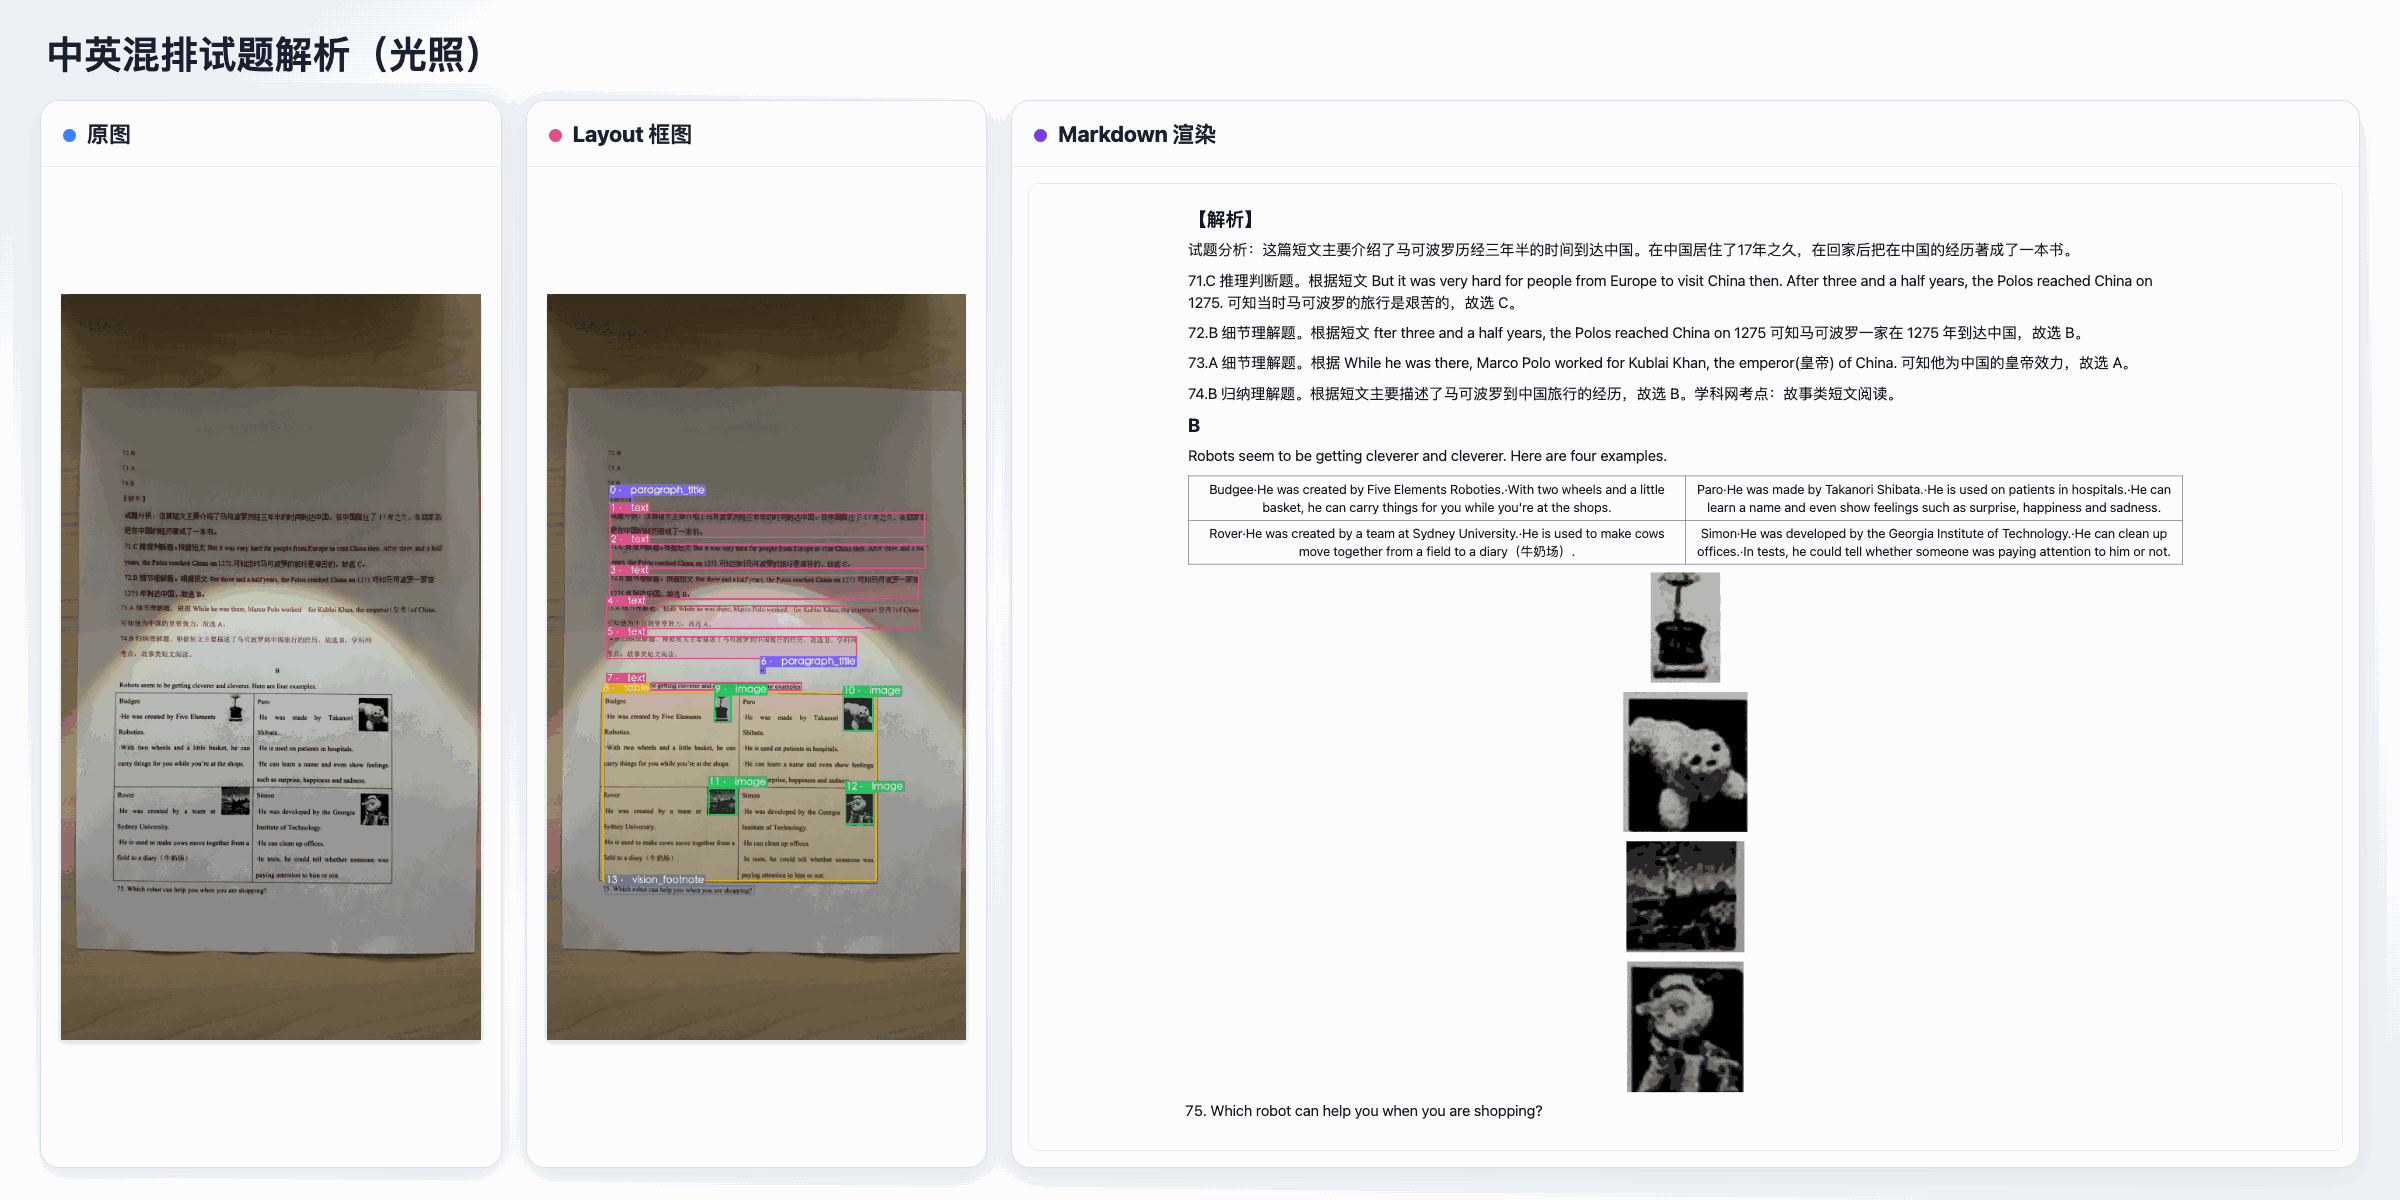
More Chinese Examples
Original documents and parsed results, side by side.
MiniCPM-OCR Jev
MiniCPM-OCR Jev is an OCR correctness decision model for text, formulas, and tables. Given an image and its corresponding OCR result, it returns a quality score from 0 to 1 to help select reliable results and locate content that needs review.
- 🛡️ Strong performance in a small model: With only 2B parameters, MiniCPM-OCR Jev achieves an AUROC (×100) of 93.6 on JevOCRBench, outperforming JEV-35B-A3B (90.1) and approaching Qwen3.5-397B-A17B (93.8).
- 🧩 Consistent generalization: Across parsing results from MiniCPM-OCR 1.0, GLM-OCR, PaddleOCR-VL-1.6, and Xiaomi-OCR-0, its AUROC (×100) ranges from 91.9 to 93.4.
Evaluation Results
The table below reports overall and per-category AUROC (×100) on JevOCRBench. Higher values indicate better discrimination between correct and incorrect parsing results.
Review-Free Accuracy
Accuracy at different review-free rates across three document types.
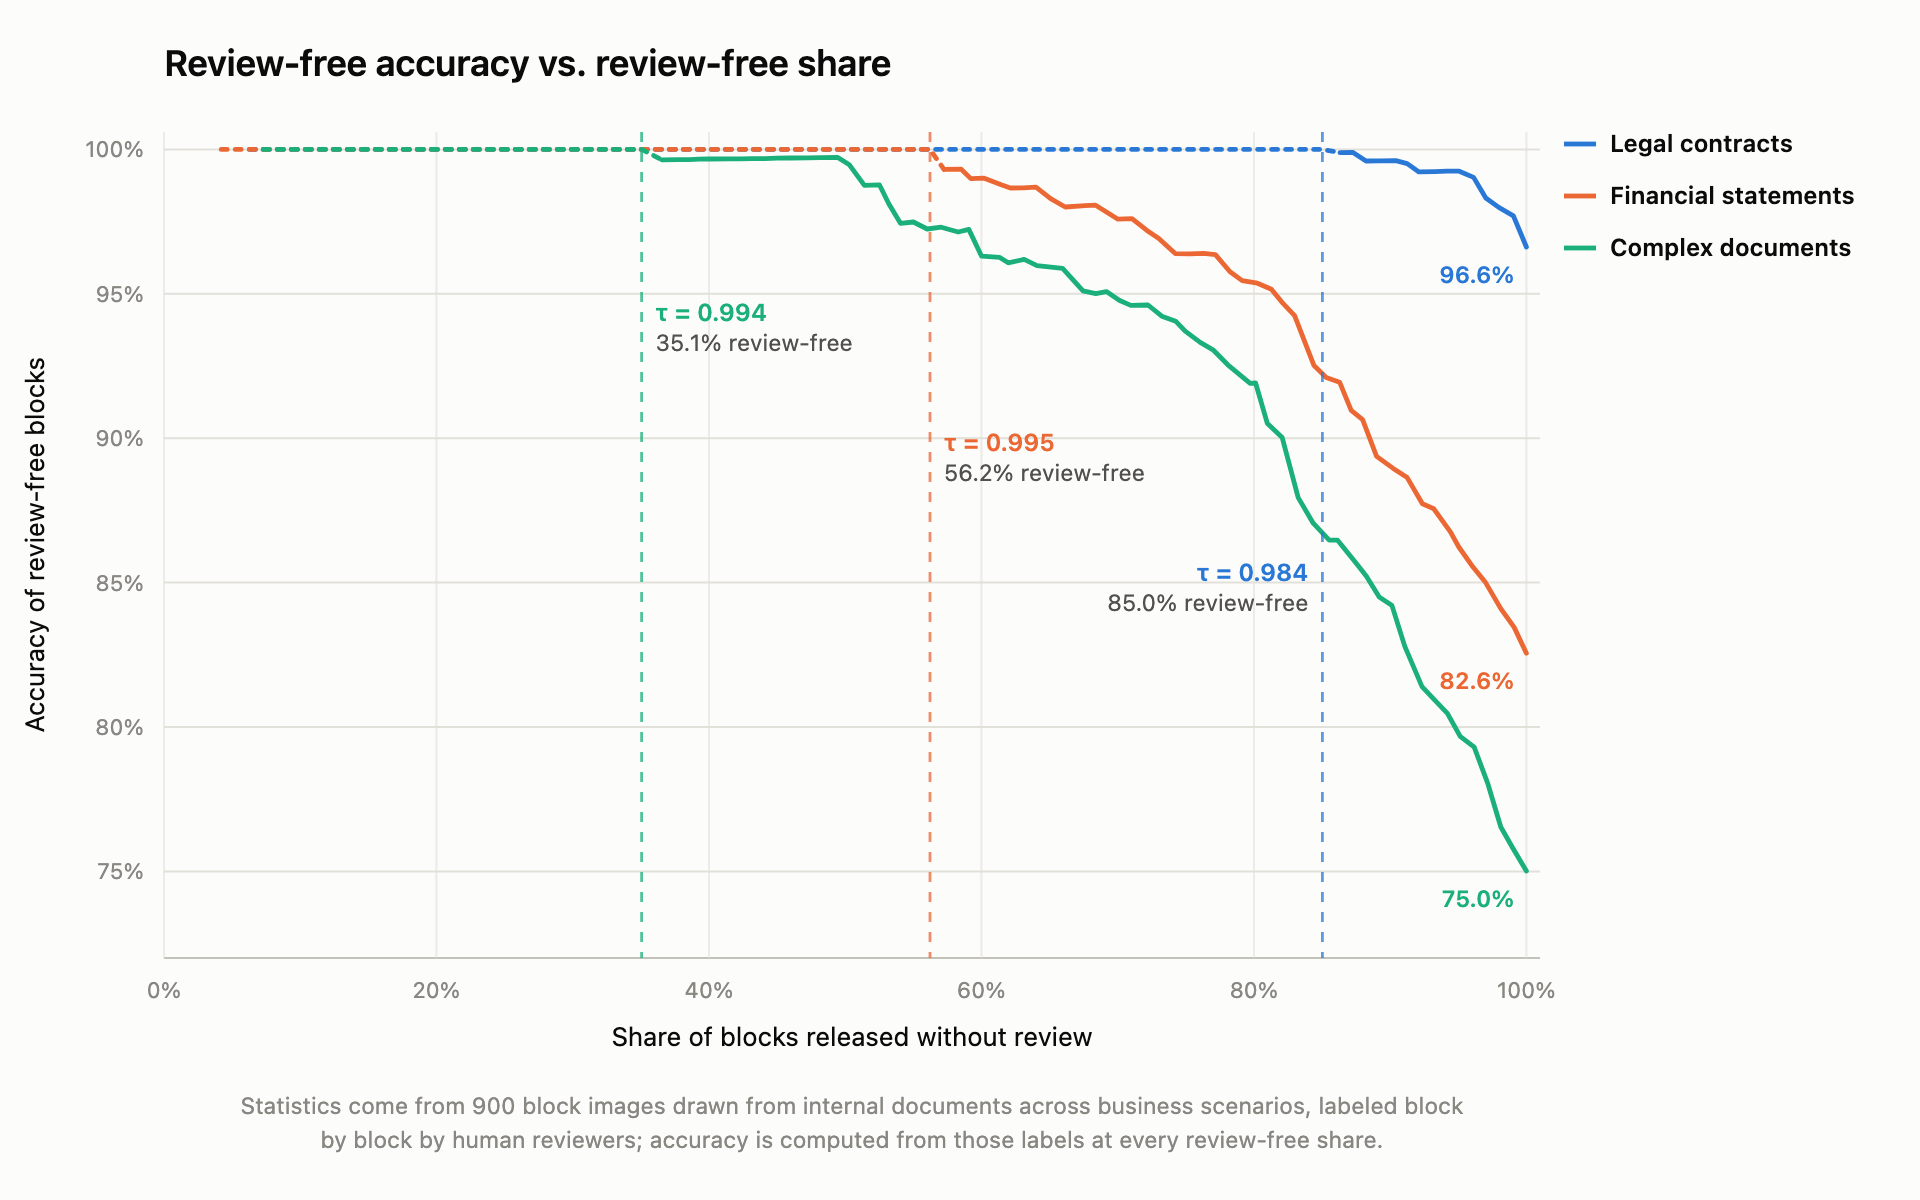
Set the threshold only after checking it on a small batch from the real application.
Decision Examples
Jev scores for text, formula, and table recognition.
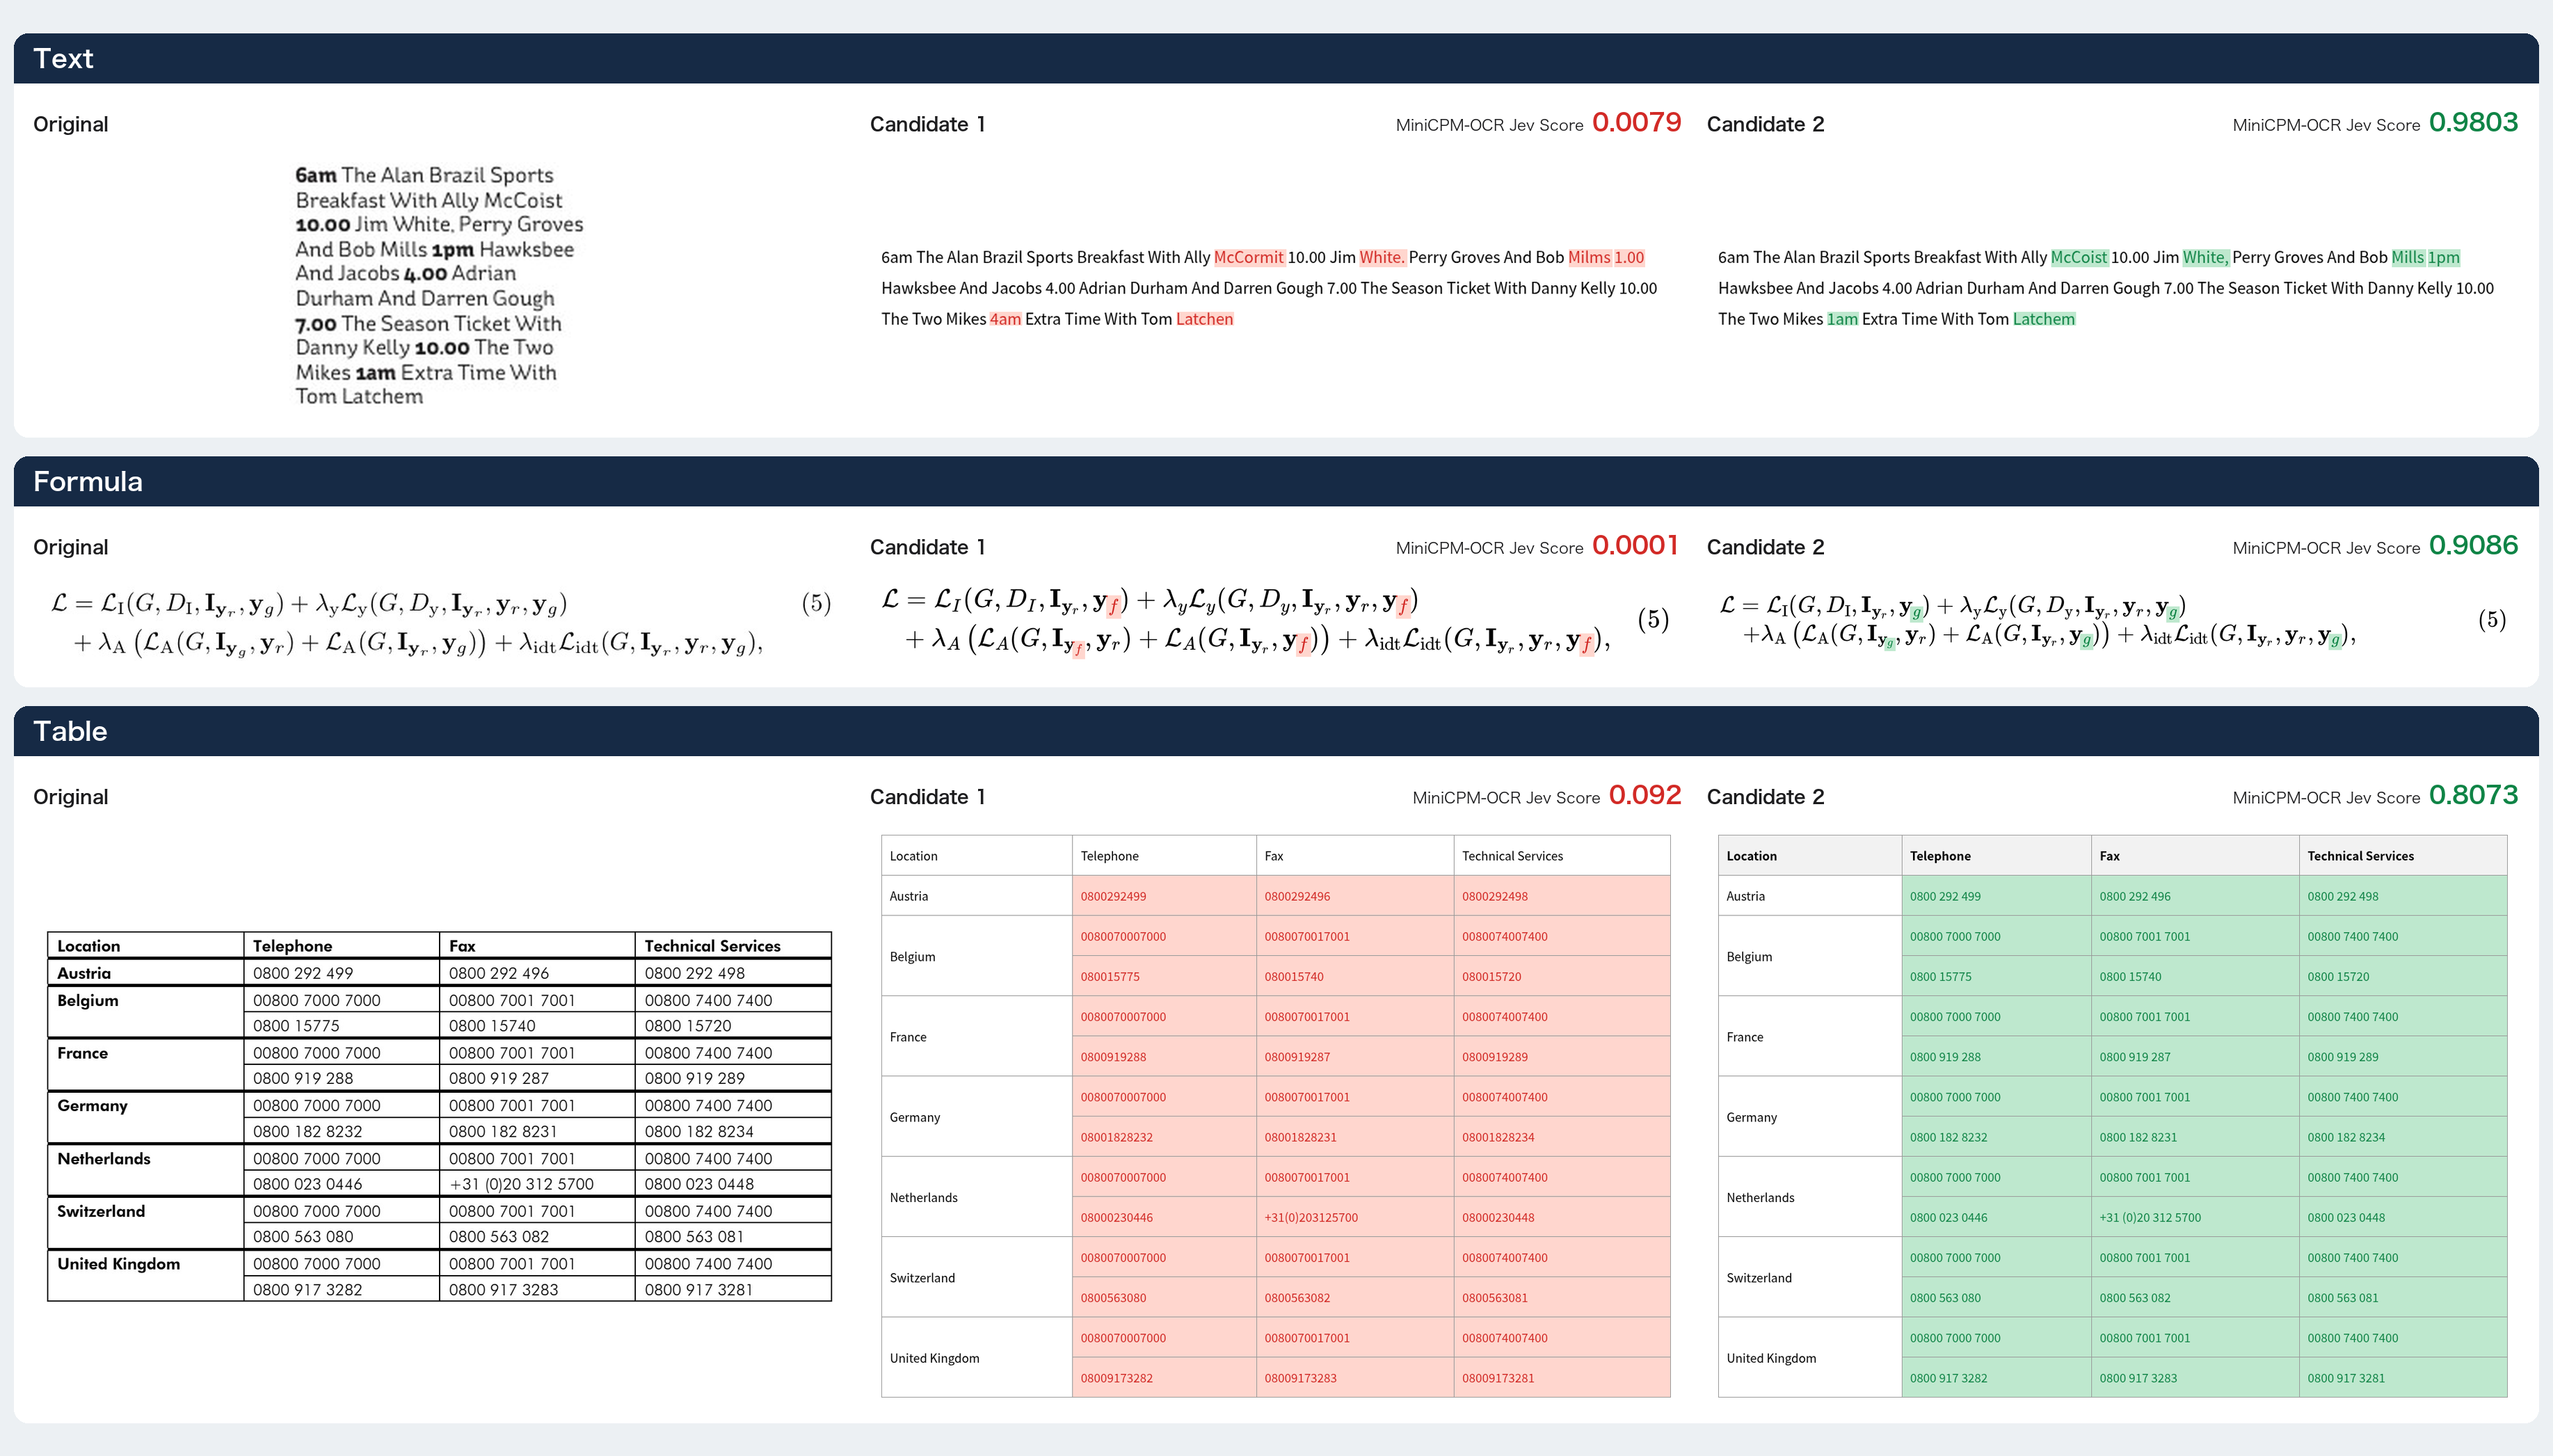
See the MiniCPM-OCR Jev model guide for more on usage, technical specifications, evaluation results, and efficiency results.
Using MiniCPM-OCR
Choose how to integrate MiniCPM-OCR 1.0 and MiniCPM-OCR Jev:
How Document Parsing Works
Full-page parsing runs as a two-stage pipeline orchestrated by the minicpm-ocr SDK. The two stages use separate models, run in separate environments, and may run on different machines:
flowchart LR
    DOC["PDF / image"] --> S1

    subgraph SDKENV ["minicpm-ocr SDK (its own environment)"]
        S1["Stage 1 · Layout detection<br>PP-DocLayoutV3 layout model (PaddlePaddle / PaddleX)<br>regions, reading order, cropping"]
        ASM["Assemble output<br>Markdown / JSON in reading order"]
    end

    subgraph SRVENV ["Recognition service (separate environment)"]
        S2["Stage 2 · Region recognition<br>MiniCPM-OCR 1.0<br>vLLM / SGLang / llama.cpp / Ollama"]
    end

    S1 -- "each cropped region, over HTTP,<br>with a prompt for its region type" --> S2
    S2 -- "text, tables, formulas, charts, seals" --> ASM
- Stage 1 — Layout detection (run locally by the SDK). The PP-DocLayoutV3 layout model detects document regions — text, tables, formulas, charts, seals — and analyzes reading order; the SDK then crops the regions. It runs inside the SDK environment and requires PaddlePaddle / PaddleX.
- Stage 2 — Region recognition (inference service). The SDK sends each cropped region over HTTP to a MiniCPM-OCR 1.0 inference service — served by vLLM, SGLang, llama.cpp, or Ollama — with a prompt matching the region type (
Text Recognition:, Table Recognition:, Formula Recognition:, …). The SDK assembles the recognized content into the final Markdown / JSON in reading order.
A full local deployment therefore prepares two environments side by side: the SDK environment (pip package minicpm-ocr, plus PaddlePaddle / PaddleX for the layout model) and the inference-service environment of the chosen backend. The Skill walks through the complete setup — backend choice, environment installation, model downloads, and verification — and the SDK tutorial covers the same steps for manual deployment. For region prompts and per-stage details, see the document parsing workflow.
Skill
Ask a coding agent to follow the MiniCPM-OCR 1.0 skill to set up the environment, download models, and parse your first document. Send the following instruction to the agent:
Read and execute https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md
Ask a coding agent to follow the MiniCPM-OCR Jev skill to deploy, start, and verify the scoring service locally — either from the Docker image or with the SDK, using vLLM, SGLang, llama.cpp, or Ollama as the inference backend. Send the following instruction to the agent:
Read and execute https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_jev_en.md
If you have already cloned this repository, you can use ./docs/SKILL_en.md and ./docs/SKILL_jev_en.md directly.
Docker Deployment
Deploy MiniCPM-OCR 1.0 with the official Docker image, which bundles model weights, the SDK, vLLM, and the document parsing backend. The Docker Hub page provides startup instructions for both the OCR model API and the end-to-end document parsing API, supporting image and PDF parsing into Markdown / JSON.
Requires Linux x86-64, an NVIDIA GPU, a driver compatible with CUDA 12.9, and Docker configured with NVIDIA Container Toolkit. Follow the image documentation to select and start the service you need.
Free API
Use the Free API to access MiniCPM-OCR 1.0 recognition and MiniCPM-OCR Jev quality scoring.
MiniCPM-OCR 1.0 API docs · MiniCPM-OCR Jev API docs
MiniCPM-V Demo — iOS, Android & HarmonyOS
MiniCPM-OCR 1.0 parses documents entirely on your device, even offline. This document recognition feature is currently available on iOS only.
On-device demo tutorial
Local Deployment
Run the models on your own hardware: MiniCPM-OCR 1.0 parses PDFs and images into Markdown or JSON, while MiniCPM-OCR Jev scores the parsing results.
MiniCPM-OCR 1.0 deployment tutorial · MiniCPM-OCR Jev deployment tutorial · Web demo deployment tutorial
Fine-Tuning
Model Weights
| Model |
Description |
Main Model Weights |
DSpark Heads |
| MiniCPM‑OCR 1.0 |
Efficient document parsing and text recognition for Chinese and English documents and PDFs, balancing quality and speed across scans, photographs, curved pages, and recaptured documents. |
🤗  BF16
🤗 GGUF
🤗 AWQ
🤗 GPTQ |
🤗 BF16
🤗 GGUF |
| MiniCPM‑OCR Jev |
An OCR correctness decision model for text, formulas, and tables. Given an image and its OCR result, it returns a quality score from 0 to 1. |
🤗 BF16 🤗 GGUF
🤗 AWQ 🤗 GPTQ |
💡 FAQ and Troubleshooting
See the FAQ for common questions about installation, model downloads, GPU memory, input formats, and unexpected outputs.
📄 License
The entire project is released under the Apache License 2.0, including code, documentation, and model weights for MiniCPM-OCR 1.0 and MiniCPM-OCR Jev.


 MiniCPM-OCR 是一组用于文档理解的模型:MiniCPM-OCR 1.0 可将中英文文档和 PDF 解析为结构化文本(包括表格、公式、图表和印章),而 MiniCPM-OCR Jev 是一个独立模型,用于为这些解析结果打 0 到 1 的分,标记出需要人工复核的区域。