

Что это?
 Kimi K2 — серия больших языковых моделей от Moonshot AI: модель mixture-of-experts с 1 триллионом общих параметров (32B активируется на токен), обученная для передовых знаний, рассуждений, кодинга и особенно агентских задач с использованием инструментов.
Это одна модель или есть варианты?Есть два варианта: Kimi-K2-Base — сырая предобученная базовая модель для исследователей, желающих её дообучать, и Kimi-K2-Instruct — дообученная чат/агентская модель для использования сразу, без долгого размышления.
Есть два варианта: Kimi-K2-Base — сырая предобученная базовая модель для исследователей, желающих её дообучать, и Kimi-K2-Instruct — дообученная чат/агентская модель для использования сразу, без долгого размышления.Kimi-K2-Instruct — «думающая» модель, как рассуждающие конкуренты?Нет, она описывается как рефлексная модель без долгого размышления, в отличие от режимов расширенного рассуждения в некоторых моделях конкурентов.
Нет, она описывается как рефлексная модель без долгого размышления, в отличие от режимов расширенного рассуждения в некоторых моделях конкурентов.На кого нацелена эта модель?На исследователей и разработчиков, которым нужна либо базовая модель для дообучения, либо готовая чат/агентская модель для задач с инструментами и кодингом.
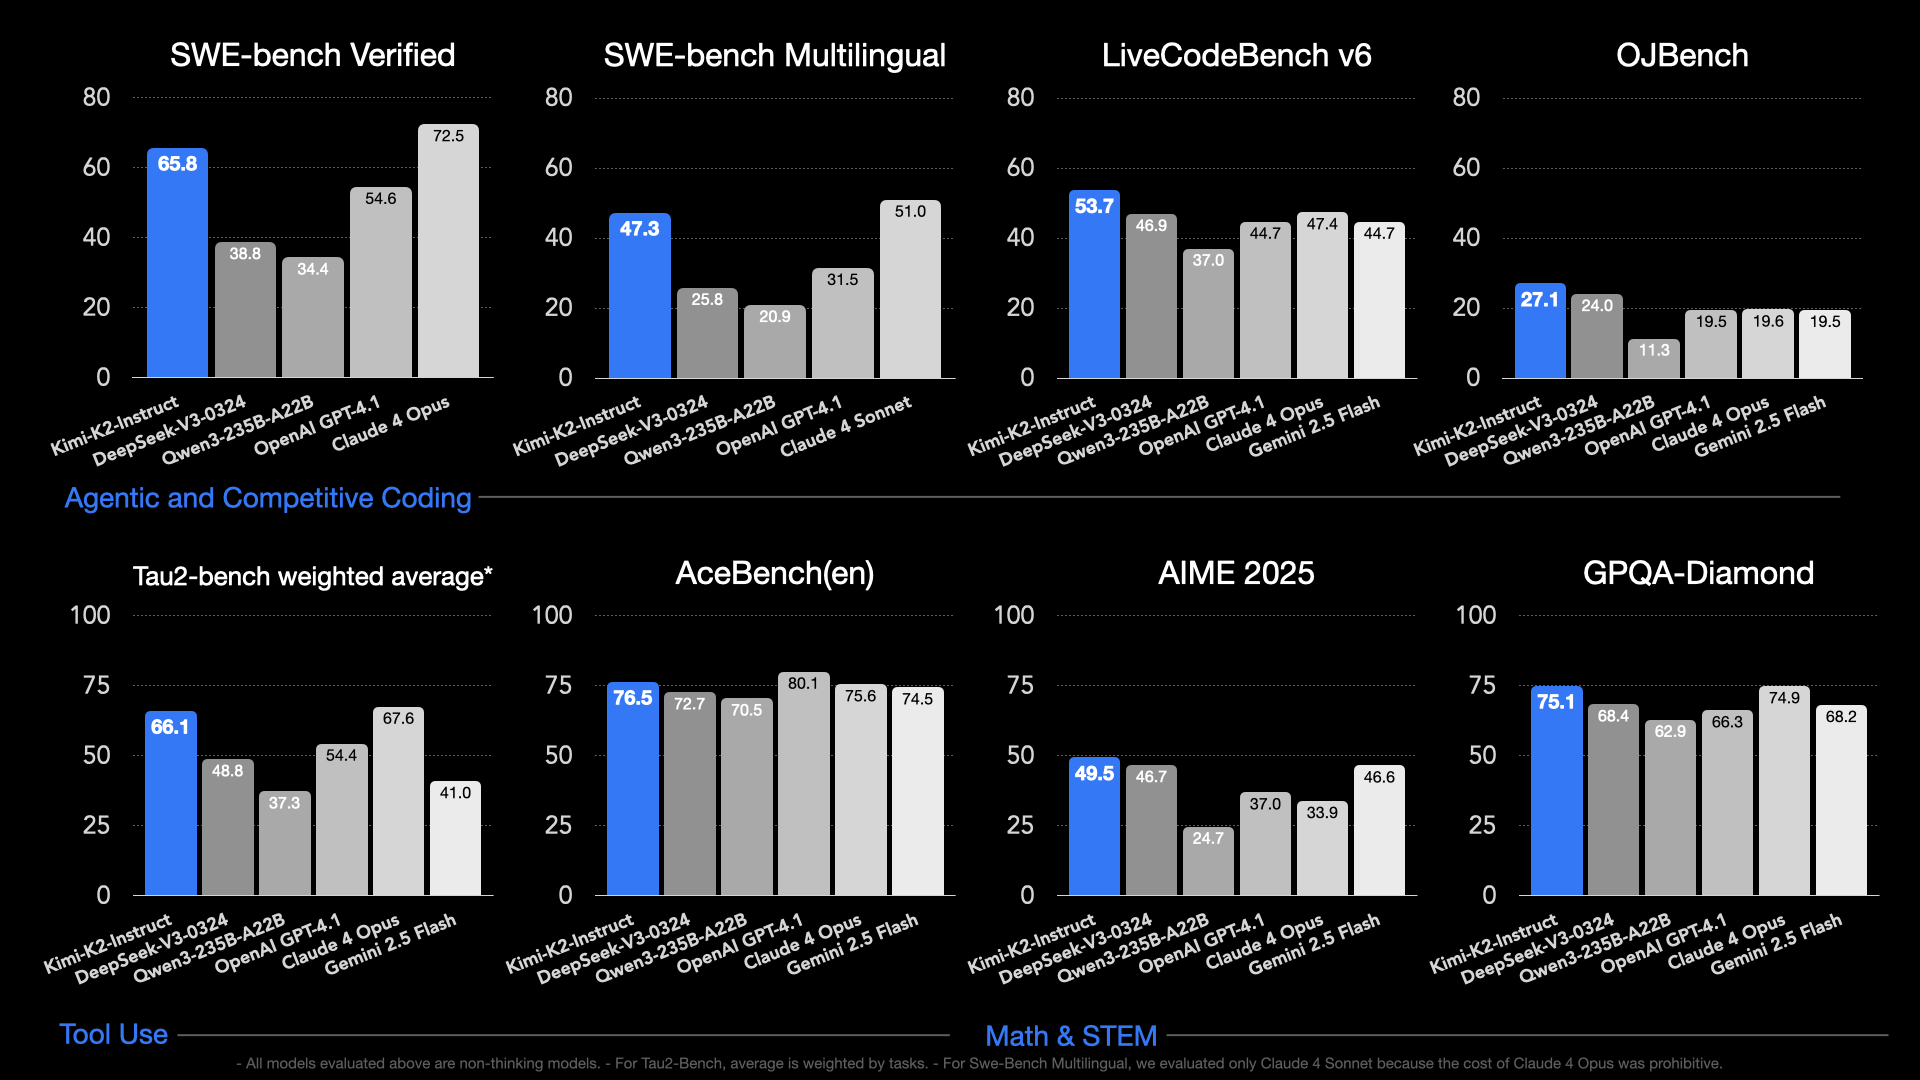
На исследователей и разработчиков, которым нужна либо базовая модель для дообучения, либо готовая чат/агентская модель для задач с инструментами и кодингом.Как Kimi K2 сравнивается с моделями вроде DeepSeek-V3 или Claude в кодинговых бенчмарках?В агентском кодинге на SWE-bench Verified Kimi K2 Instruct набирает 65.8% pass@1 (с одной попытки), заметно выше 38.8% у DeepSeek-V3-0324 и 34.4% у Qwen3-235B, хотя ниже 72.5% у Claude Opus 4.
В агентском кодинге на SWE-bench Verified Kimi K2 Instruct набирает 65.8% pass@1 (с одной попытки), заметно выше 38.8% у DeepSeek-V3-0324 и 34.4% у Qwen3-235B, хотя ниже 72.5% у Claude Opus 4.Какой оптимизатор использовался, чтобы стабильно обучить такую огромную модель?Moonshot AI использовала оптимизатор Muon в беспрецедентном масштабе, разработав новую технику «MuonClip» для устранения нестабильностей обучения при масштабировании до 1T параметров.
Moonshot AI использовала оптимизатор Muon в беспрецедентном масштабе, разработав новую технику «MuonClip» для устранения нестабильностей обучения при масштабировании до 1T параметров.Насколько велики обучающие данные и контекстное окно?Kimi K2 была предобучена на 15.5 триллиона токенов без единого сбоя обучения и поддерживает длину контекста 128K токенов.
Kimi K2 была предобучена на 15.5 триллиона токенов без единого сбоя обучения и поддерживает длину контекста 128K токенов.Сколько экспертов использует архитектура MoE?Всего 384 эксперта, из которых на каждый токен выбирается 8 плюс 1 общий эксперт, в 61 слое с вниманием MLA и активациями SwiGLU.
Всего 384 эксперта, из которых на каждый токен выбирается 8 плюс 1 общий эксперт, в 61 слое с вниманием MLA и активациями SwiGLU.What are similar projects?DeepSeek-V3, Kimi-K3, MiniCPM, Qwen3.8, DeepSeek-R1, Hy4-preview, minimind, StartLux-Decision
DeepSeek-V3, Kimi-K3, MiniCPM, Qwen3.8, DeepSeek-R1, Hy4-preview, minimind, StartLux-DecisionWhich topics is it in?open-weights, tool-calling, mixture-of-experts, reasoning, coding, language-model, moe, agentic, fine-tuning, transformer, large-language-models, artificial-intelligence
open-weights, tool-calling, mixture-of-experts, reasoning, coding, language-model, moe, agentic, fine-tuning, transformer, large-language-models, artificial-intelligence