




10.1K ·GitHub
Что это такое?
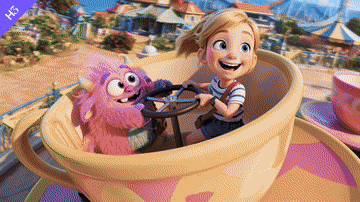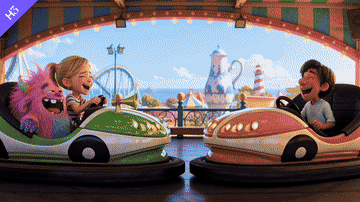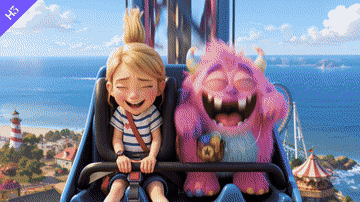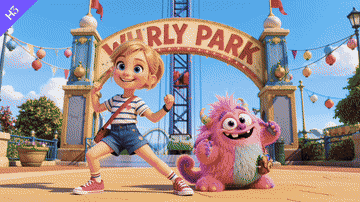
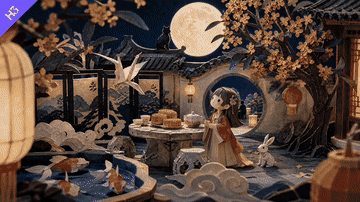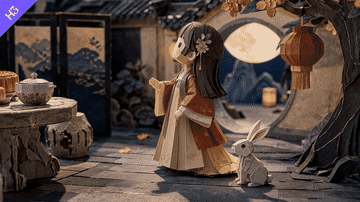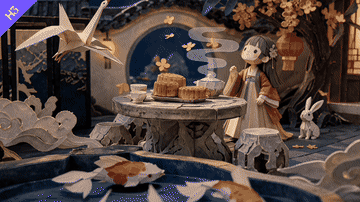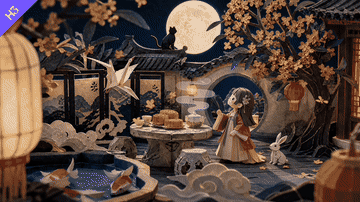
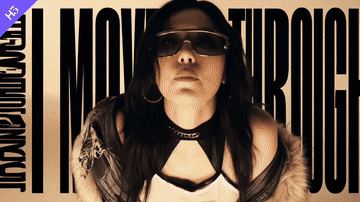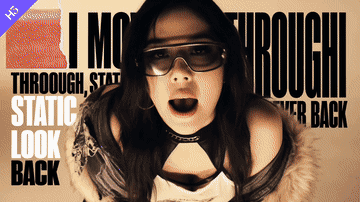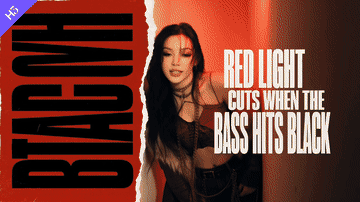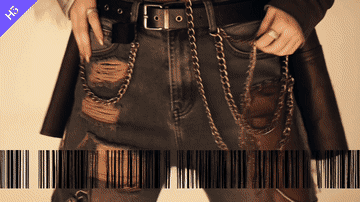
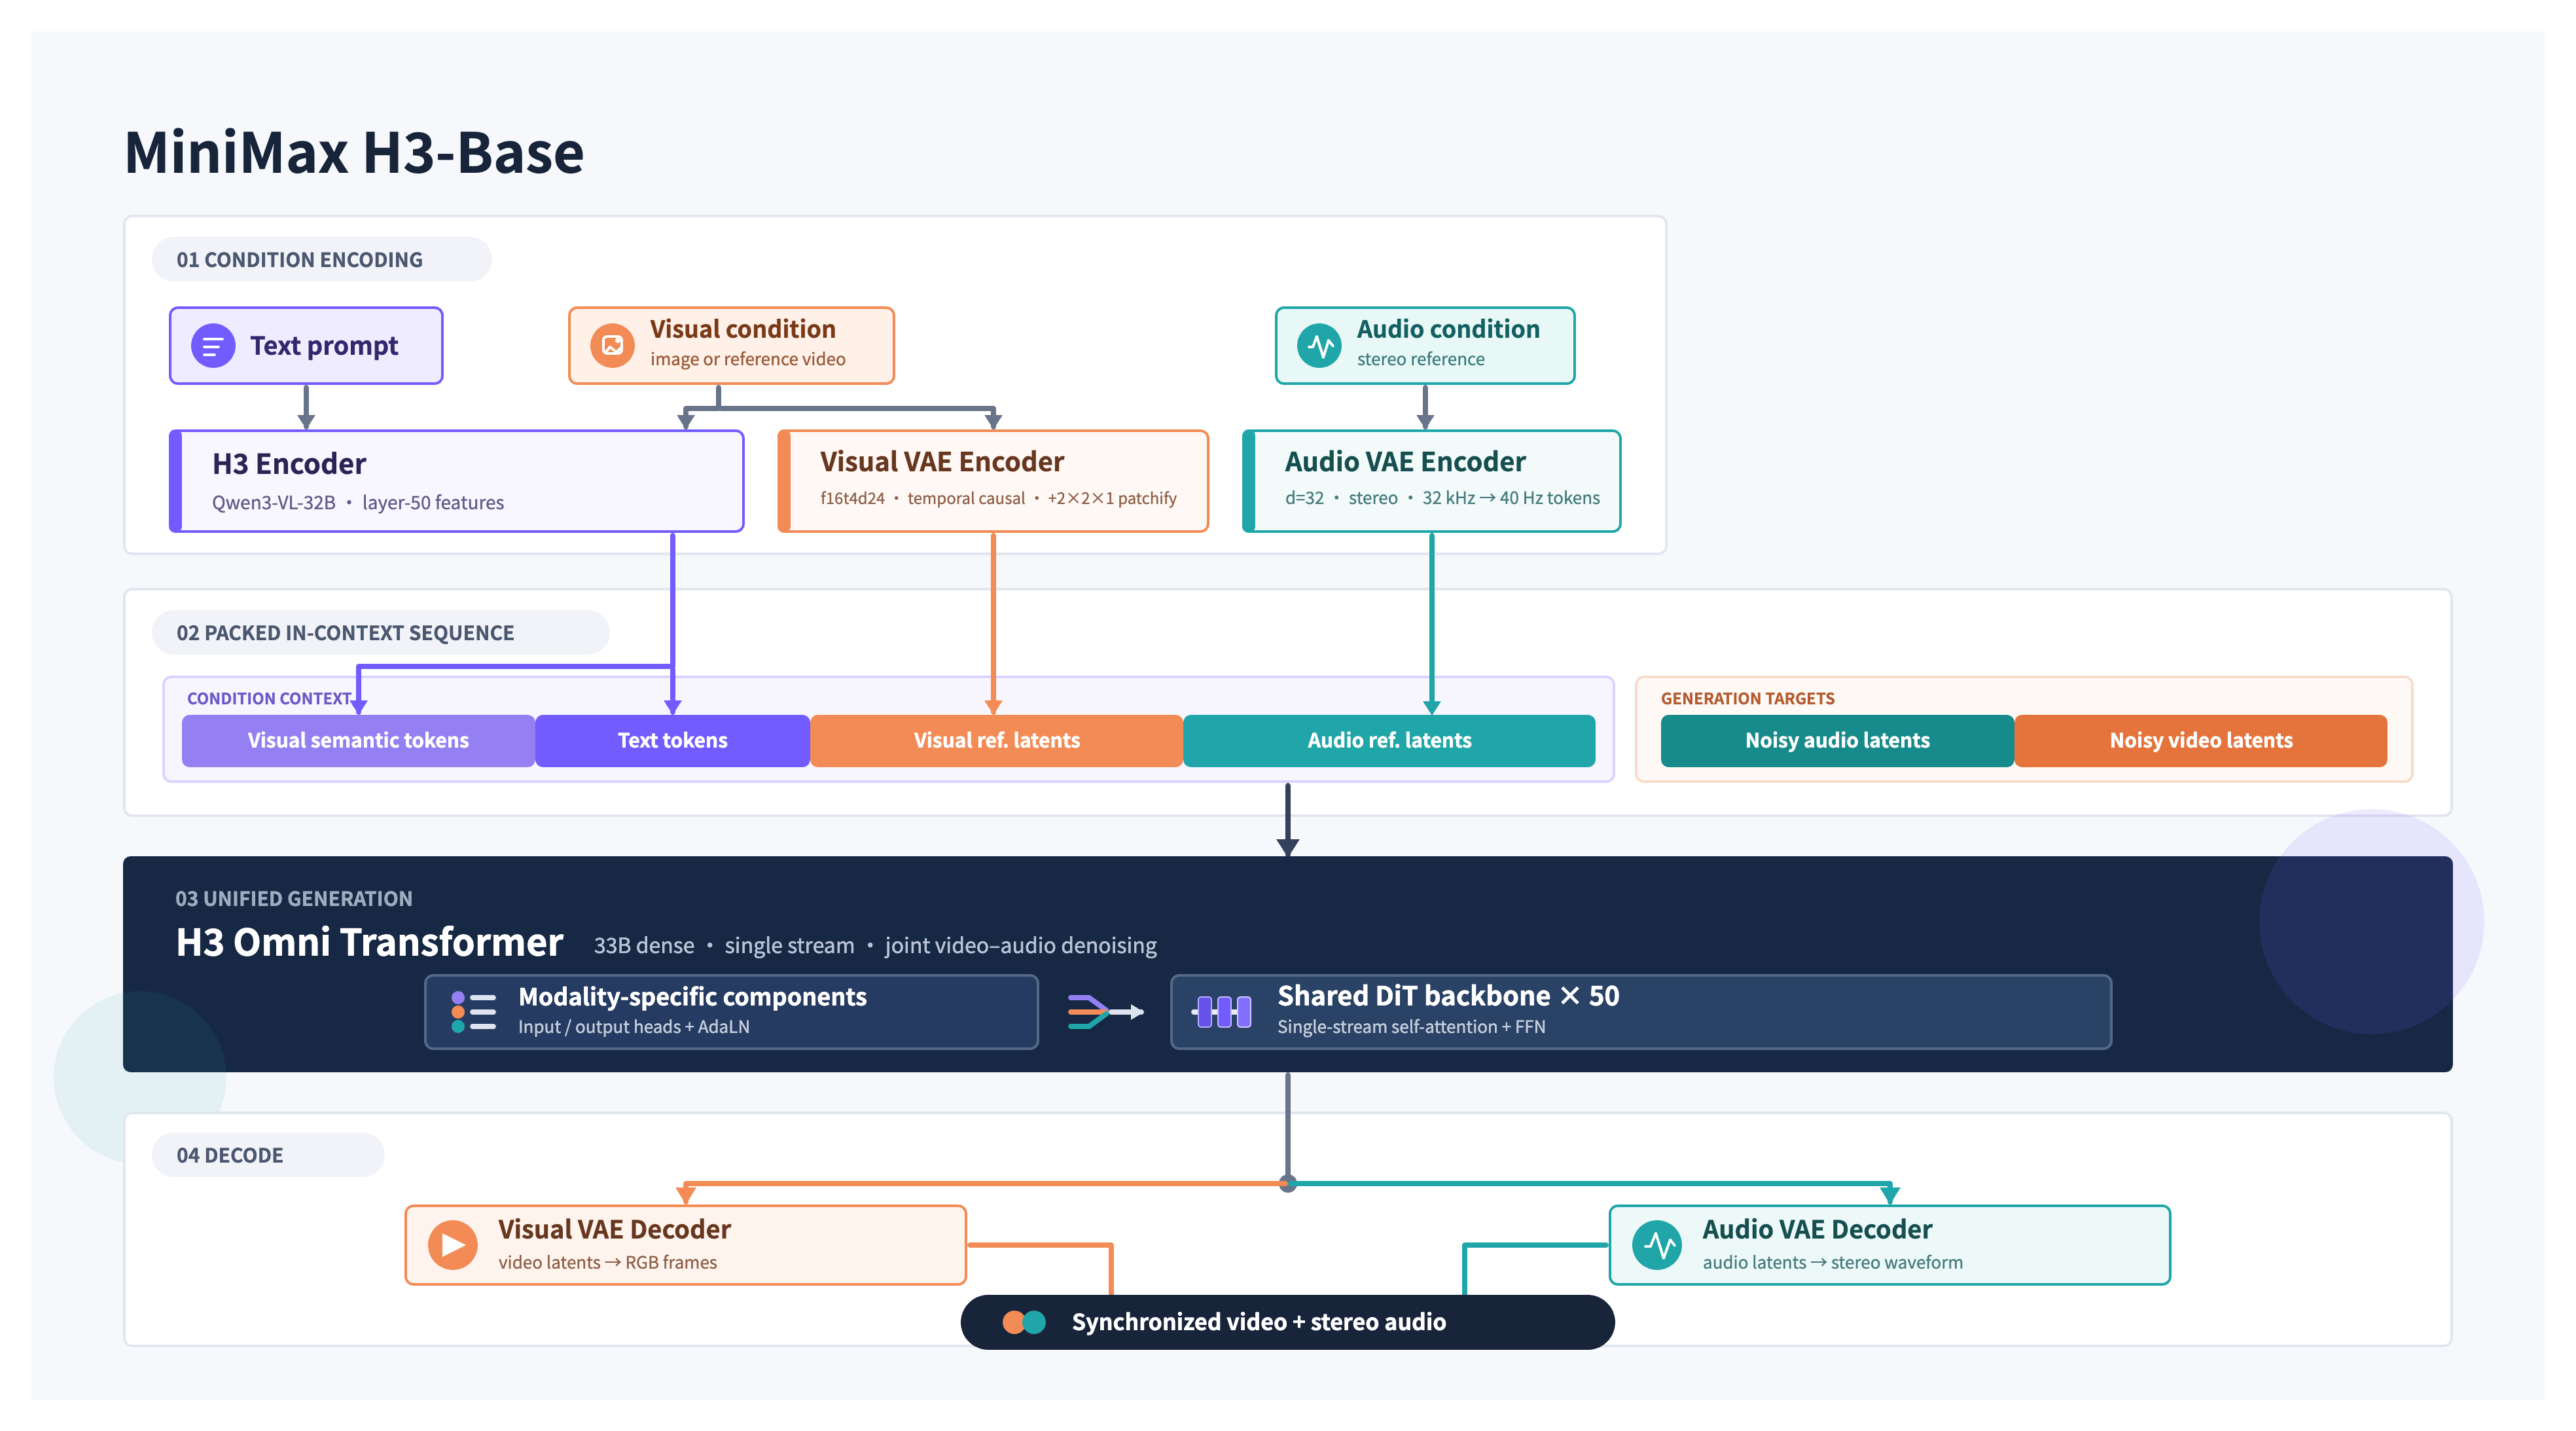
 MiniMax H3 — универсальная омнимодальная генеративная система: она принимает смешанный ввод из текста, изображений, видео и аудио и генерирует видео с нативным стереозвуком, с разрешением до 2K и длительностью до 15 секунд на клип.
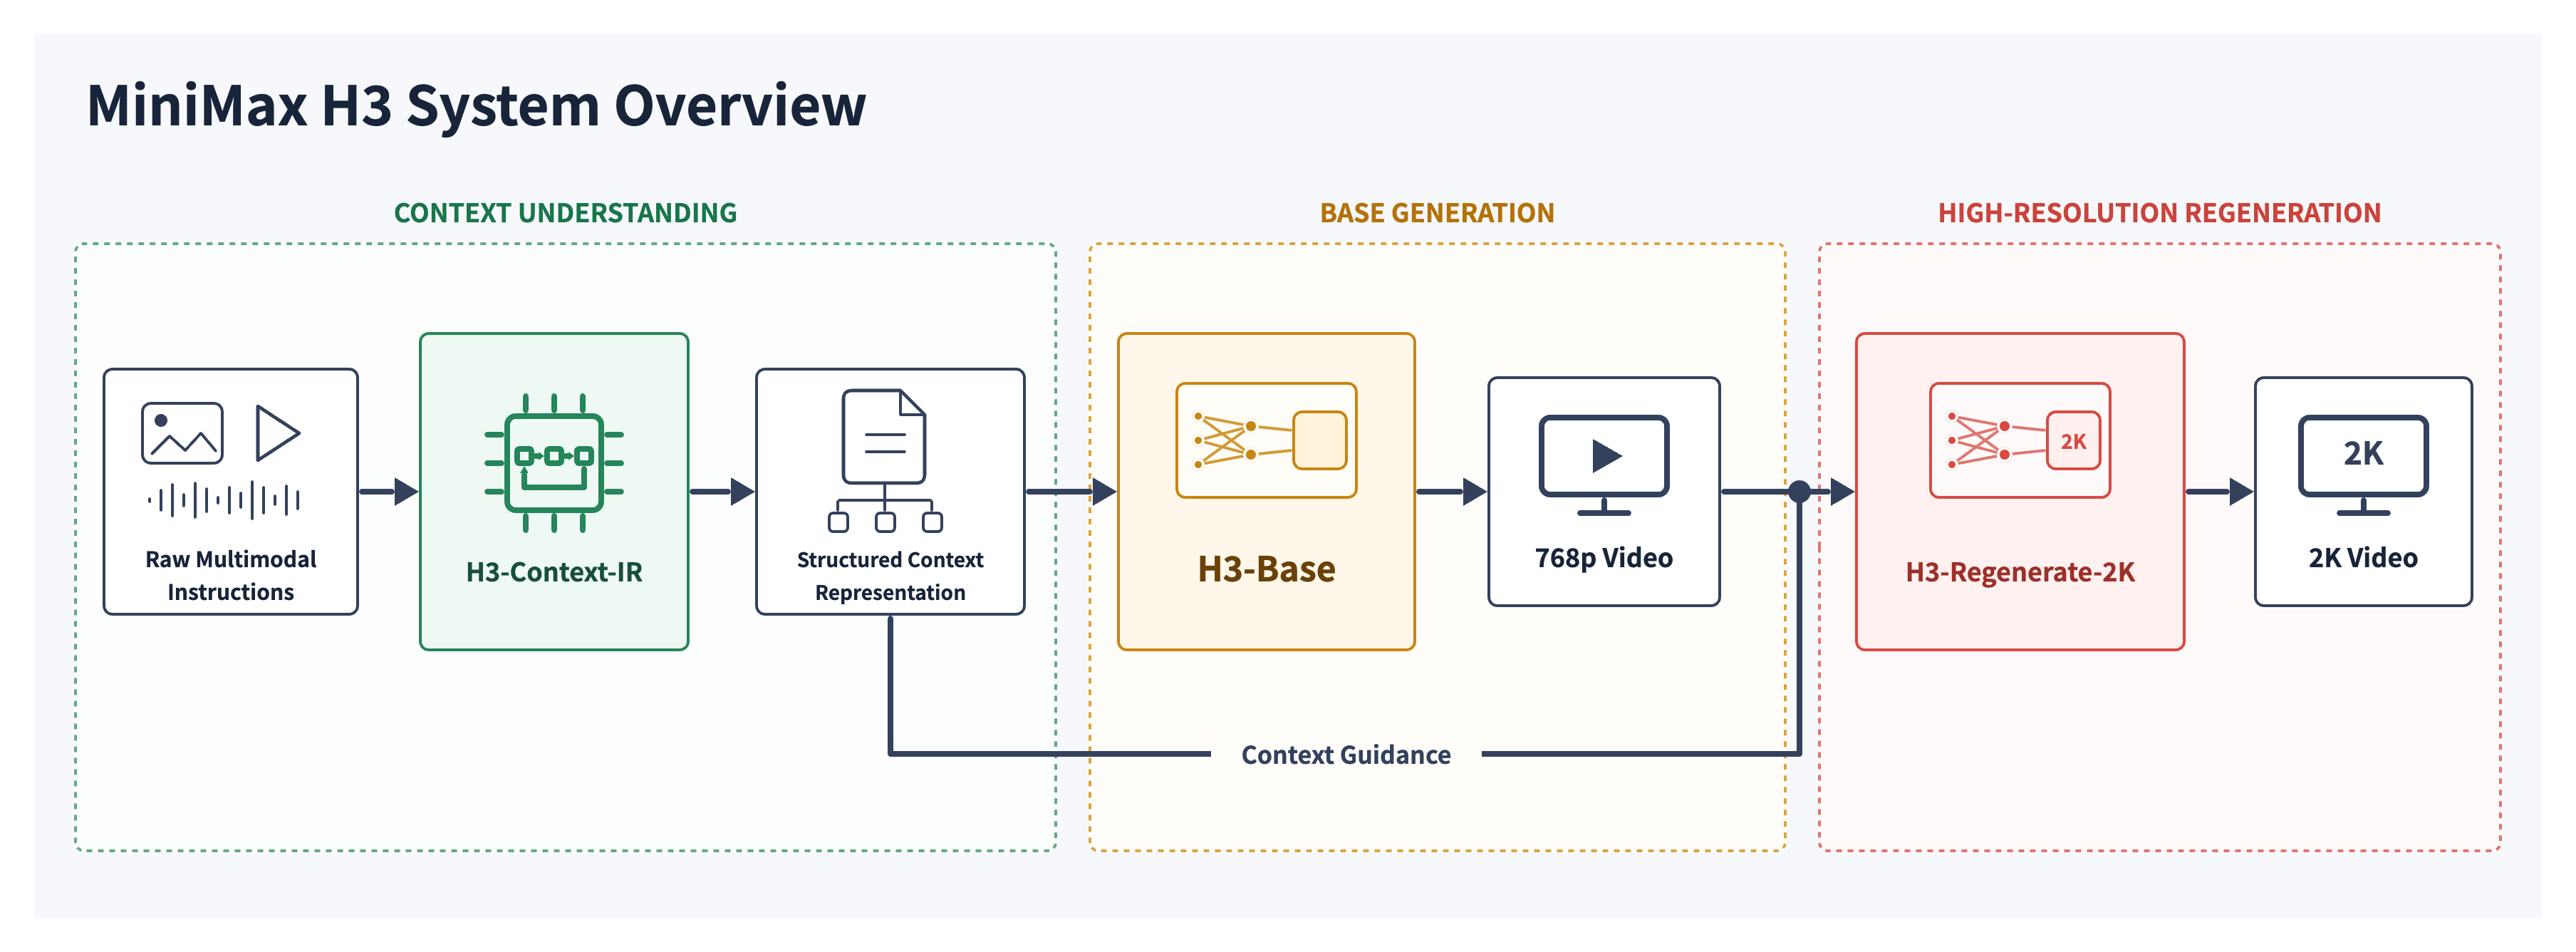
То есть что я на самом деле получу, когда склонирую репозиторий — всю систему целиком?Только основной генератор: в репозитории H3-Base поставляется в виде двух чекпоинтов под конкретные задачи плюс девять агентских навыков (skills). Стадия предобработки Context-IR и модуль регенерации в 2K закрыты — их поведение покрыто API.
Только основной генератор: в репозитории H3-Base поставляется в виде двух чекпоинтов под конкретные задачи плюс девять агентских навыков (skills). Стадия предобработки Context-IR и модуль регенерации в 2K закрыты — их поведение покрыто API.Где мне вообще его запустить — в облачном приложении, через API или на своей машине?Быстрее всего в облаке: веб-приложение hailuoai.video, десктопный hub.minimax.io или API на platform.minimax.io (для всех трёх есть китайские зеркала). Для локального запуска разверните открытые чекпоинты H3-Base по разделу Local Deployment в README.
Быстрее всего в облаке: веб-приложение hailuoai.video, десктопный hub.minimax.io или API на platform.minimax.io (для всех трёх есть китайские зеркала). Для локального запуска разверните открытые чекпоинты H3-Base по разделу Local Deployment в README.Какие ограничения у клипов, которые она создаёт?Клипы идут от 4 до 15 секунд при 24 FPS со стереозвуком 32 кГц; вывод по умолчанию — 768p (по короткой стороне), с возможностью апгрейда до 2K через отдельный проход H3-Regenerate-2K. Соотношения сторон — от 21:9 и 16:9 до 1:1 и 9:16.
Клипы идут от 4 до 15 секунд при 24 FPS со стереозвуком 32 кГц; вывод по умолчанию — 768p (по короткой стороне), с возможностью апгрейда до 2K через отдельный проход H3-Regenerate-2K. Соотношения сторон — от 21:9 и 16:9 до 1:1 и 9:16.Есть ли модерация того, что я отправляю?Да — отправляемый текст, изображения, видео и улучшенные промпты проходят автоматическую модерацию; контент, распознанный как противоправный, порнографический или нарушающий чужие права, может быть заблокирован, причём ложные срабатывания возможны.
Да — отправляемый текст, изображения, видео и улучшенные промпты проходят автоматическую модерацию; контент, распознанный как противоправный, порнографический или нарушающий чужие права, может быть заблокирован, причём ложные срабатывания возможны.Могу ли я свободно использовать веса — что говорит лицензия?Действует MiniMax H3 Community License — это специальная лицензия, а не стандартная open-source (в метаданных GitHub никакая не указана). В README подчёркивается, что модерация не снимает с вас обязанностей использовать модель на законных основаниях согласно этой лицензии.
Действует MiniMax H3 Community License — это специальная лицензия, а не стандартная open-source (в метаданных GitHub никакая не указана). В README подчёркивается, что модерация не снимает с вас обязанностей использовать модель на законных основаниях согласно этой лицензии.Могу ли я запустить открытые чекпоинты на своём железе?Требования к оборудованию не указаны, но H3-Base — это плотный трансформер на 33 млрд параметров, причём около 13 млрд из них (ветки AdaLN) можно пропустить на инференсе. Всё равно это не модель для ноутбука — рассчитывайте на серьёзный объём видеопамяти.
Требования к оборудованию не указаны, но H3-Base — это плотный трансформер на 33 млрд параметров, причём около 13 млрд из них (ветки AdaLN) можно пропустить на инференсе. Всё равно это не модель для ноутбука — рассчитывайте на серьёзный объём видеопамяти.Что можно подать на вход, кроме текстового промпта?Два режима ввода: H3-Base-FL2VA принимает ноль, одну или две картинки (чистый text-to-video, по первому или последнему кадру, либо по первому и последнему кадру). H3-Base-Ref2VA принимает смешанные референсы: до 9 изображений, 3 видеоклипов и 3 аудиоклипов — всего 12 файлов.
Два режима ввода: H3-Base-FL2VA принимает ноль, одну или две картинки (чистый text-to-video, по первому или последнему кадру, либо по первому и последнему кадру). H3-Base-Ref2VA принимает смешанные референсы: до 9 изображений, 3 видеоклипов и 3 аудиоклипов — всего 12 файлов.Что такое H3-Context-IR?Это облачный сервис предобработки: он разбирает ваш промпт и референс-медиа, рассуждает между модальностями и переписывает всё в структурированное Context Intermediate Representation, из которого генерирует H3-Base. Он с закрытым исходным кодом — либо вызывайте его API, либо следуйте Prompting Guidance, чтобы собрать своё.
Это облачный сервис предобработки: он разбирает ваш промпт и референс-медиа, рассуждает между модальностями и переписывает всё в структурированное Context Intermediate Representation, из которого генерирует H3-Base. Он с закрытым исходным кодом — либо вызывайте его API, либо следуйте Prompting Guidance, чтобы собрать своё.Как работает вывод в 2K?Это не классическое super-resolution: H3-Regenerate-2K подаёт результат в 768p вместе с исходным контекстом обратно в модель и регенерирует уже в 2K, восстанавливая мелкие детали, а не угадывая их. Модуль пока не открыт — API валидирует официальный сценарий работы.
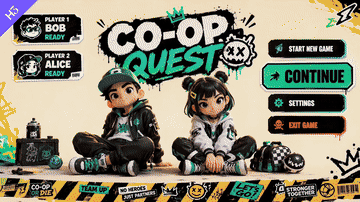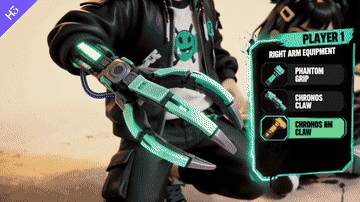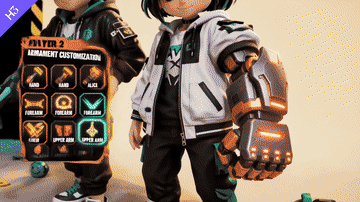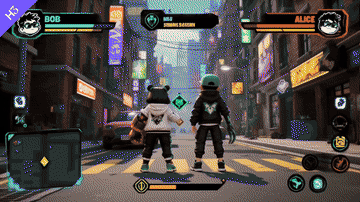
Это не классическое super-resolution: H3-Regenerate-2K подаёт результат в 768p вместе с исходным контекстом обратно в модель и регенерирует уже в 2K, восстанавливая мелкие детали, а не угадывая их. Модуль пока не открыт — API валидирует официальный сценарий работы.Что за девять встроенных навыков?Один — h3-prompt-writing, переносимый Markdown-навык с двумя гайдами по промптам, который работает в Claude Code, Claude Agent SDK, Cursor, Windsurf, Codex и LangChain. Остальные восемь — генераторы под конкретные стили для канваса MiniMax Hub — реклама товаров, короткие 3D-мультфильмы, покерфт-объяснялки, музыкальные клипы и другое; они не переносимые.
Один — h3-prompt-writing, переносимый Markdown-навык с двумя гайдами по промптам, который работает в Claude Code, Claude Agent SDK, Cursor, Windsurf, Codex и LangChain. Остальные восемь — генераторы под конкретные стили для канваса MiniMax Hub — реклама товаров, короткие 3D-мультфильмы, покерфт-объяснялки, музыкальные клипы и другое; они не переносимые.What are similar projects?infinite-livestream, LTX-Video, CodeVideoModel, awesome-minimax-h3-integration, hyperflow, DreamX-Creator, CogVideo, FreeVideo
infinite-livestream, LTX-Video, CodeVideoModel, awesome-minimax-h3-integration, hyperflow, DreamX-Creator, CogVideo, FreeVideoWhich topics is it in?minimax-h3, minimax, open-weights, vlm, image-to-video, audio-generation, text-to-video, multimodal, video-generation, transformer, multilingual, prompt-engineering
minimax-h3, minimax, open-weights, vlm, image-to-video, audio-generation, text-to-video, multimodal, video-generation, transformer, multilingual, prompt-engineering