Soup turns the pain of LLM fine-tuning into a simple workflow. One config, one command, done.
pip install "soup-cli[train]"   # add [train] to fine-tune; bare `soup-cli` is the light CLI
soup init --template chat
soup train
Fine-tune an 8B model on a 4 GB laptop GPU. Layer streaming keeps the frozen base out of
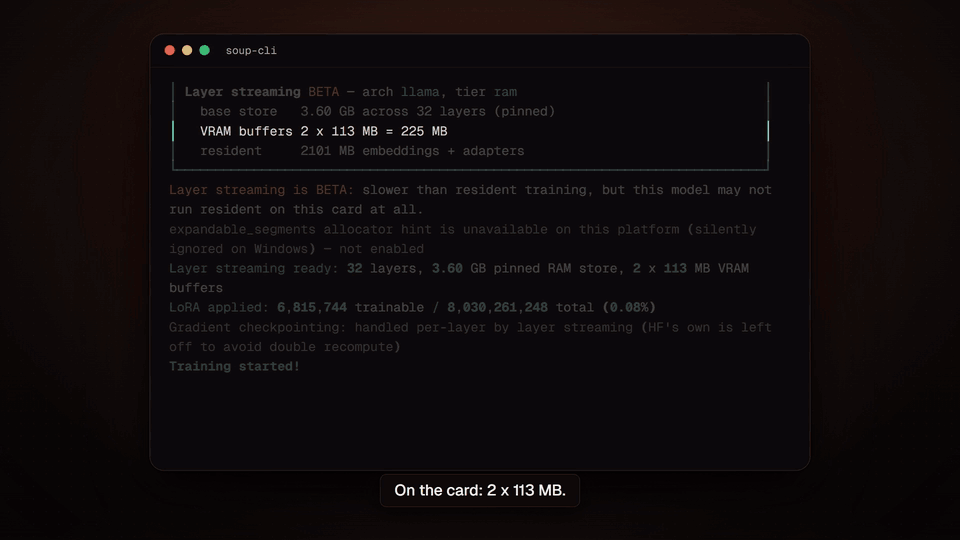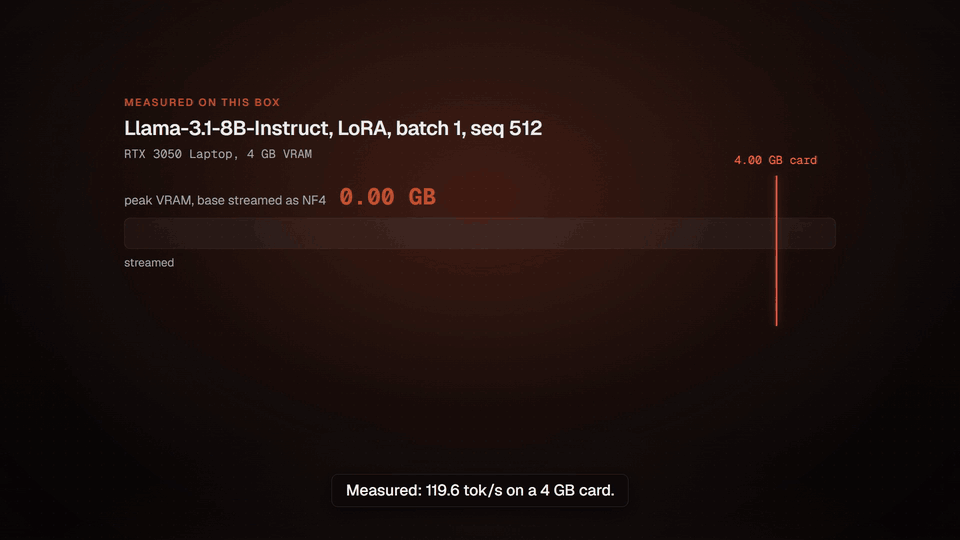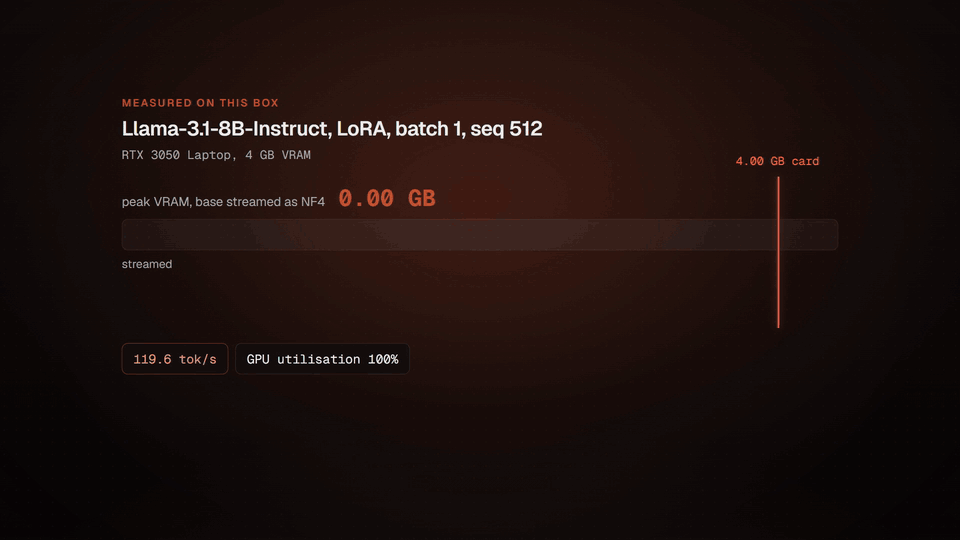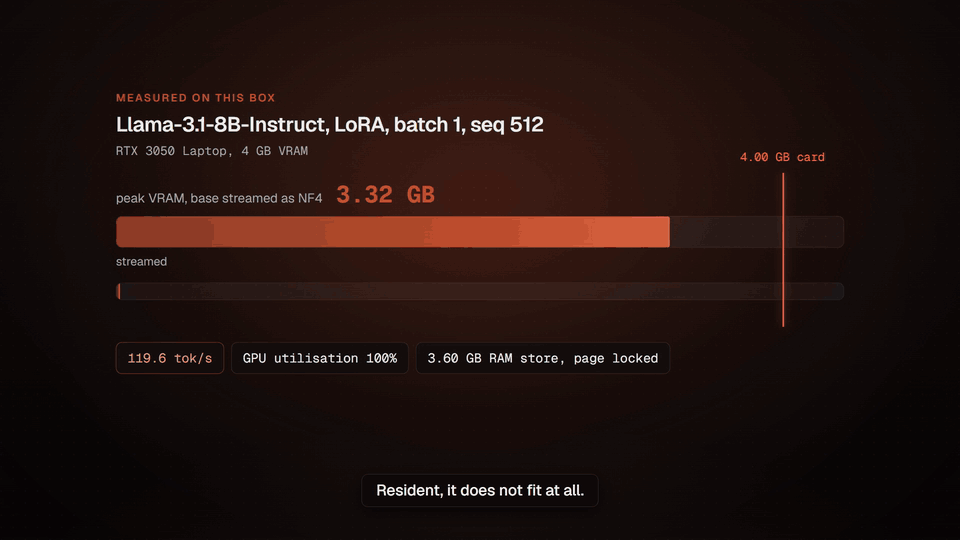
VRAM and feeds it to the GPU one decoder layer at a time. Measured on an RTX 3050 Laptop 4 GB:
Llama-3.1-8B-Instruct + NF4 at 119.6 tok/s, 3.32 GB peak — bit-exact against a normal
resident run, and reproduced independently on an H100 at 113.00 tok/s in the same 3.32 GB.
(The tok/s figure was measured on v0.72.2, before the v0.73.0 correctness repair that cost
−4.8% at 32B; it has not been re-run on a 4 GB card since.) Opt-in (stream_layers: true)
and still BETA —
how it works ·
all measurements · paper ·
check it yourself on a free Colab T4 (caps the process to
4 GB, then asserts a streamed model is bit-identical to a normal one)
Llama-3.1-8B-Instruct + NF4, LoRA, batch 1, seq 512 on an RTX 3050 Laptop 4 GB — 3.32 GB peak, 119.6 tok/s. Full video (90s)
Why Soup?
Training LLMs is still painful. Even experienced teams spend 30-50% of their time fighting
infrastructure instead of improving models. Soup fixes that.
Zero SSH. Never SSH into a broken GPU box again.
One config. A simple YAML file is all you need.
Auto everything. Batch size, GPU detection, quantization — handled.
Works locally. Train on your own GPU with QLoRA. No cloud required.
What's New
v0.74.0 — the frozen base was being loaded in fp32 the whole time. Fixing that
alone cuts peak VRAM 2.59x on an unchanged config. 116 of the 120 merged pull
requests in this release came from outside the maintainer, by 25 people.
Every SFT load silently upcast the frozen base to fp32. A base that never
receives an optimizer step was materialised at twice its checkpoint precision, on
all three load paths. Measured on an H100 with Llama-3.1-8B + LoRA: 48,241 MiB →
18,658 MiB peak — 2.59x, 28.9 GB, byte-identical across three repeats. A trainable
base still loads fp32, deliberately.
Transformers 5.x, TRL 0.29, PEFT 0.20. Qwen3.5-family text decoders train on the
Transformers path, and pip install "soup-cli[train,mlx]" resolves again — the two
extras previously declared ranges that could not be satisfied together.
The free Colab/Kaggle tier could not stream at all. T4 / P100 / V100 / GTX 16xx
crashed layer streaming, because peft creates LoRA adapters in the checkpoint's dtype
while the fp16 GradScaler needs fp32 gradients.
Four SSRF bypasses of the same shape. Abbreviated, decimal, hex and octal IPv4
spellings (127.1, 2130706433, 0x7f000001, 0177.0.0.1) reached the telemetry
and webhook guard — and, through a path the first fix never touched, the OTLP
tracing validator.
Breaking: soup serve now exits 2 when bound to a non-loopback host without
--tool-auth-token, instead of printing a warning. /v1/tools/bash is re-enabled
behind real OS-level isolation, so the endpoint it protects now actually executes.
soup train --cloud lambda, plan-only by default, with termination in a
finally that also polls to confirm it happened.
Known limitation: the declared torch>=2.5.0 floor does not work with trl>=0.29 —
at torch 2.5.1 trl cannot import. A fresh install resolves a newer torch and is
unaffected; a pinned 2.5.x environment is not. See
#651.
Python 3.10–3.12 only. On 3.13+, pip used to resolve untested PyTorch wheels that
crash in the native extension before Soup runs at all.
Previous release — v0.73.3, every pull request came from outside the maintainer
v0.73.3 — every pull request in this release came from someone other than the
maintainer. All 24 of them, from eight people, five of whom appear here for the first
time. What they found is the interesting part: four separate flags that were validated,
documented, and then read by nothing.
Assistant-only masking trained on zero tokens, with a normal loss curve. A
tokenizer returning BatchEncoding — which is not a dict — slipped past the guard,
so the label mask was built from the mapping's key strings. No exception, no
warning, a loss curve that looks like training. Found by reading the type, not by
hitting the bug.
On Apple Silicon, quantization: 4bit was silently rewritten to none.
Previous release — v0.72.4, align on a laptop (DPO / ORPO / SimPO / KTO over layer streaming)
Layer streaming used to support supervised fine-tuning only; v0.72.4 opened it to the
preference losses. The risk was one thing: DPO needs a reference model, and a second copy
would double memory and defeat the point. Soup uses the same streamed base with its
adapters switched off — measured at 0.914× the SFT peak, where forcing a real second
instance cost +730 MB, exactly one copy of the weights. Bit-exact against a normal
non-streamed run for all four. Honest cost: free in memory, not in time — DPO reads the
layer stack 1.52× as often per step. grpo / ppo stay excluded on purpose.
Trained with stream_layers: true on v0.72.0? That adapter is inert — its tensors were
saved under keys with an extra .inner. segment, so every loader returned the untuned base.
Fixed in v0.72.1; re-run or re-save. Check with:
python -c "from safetensors.torch import load_file; print([k for k in load_file('adapter_model.safetensors') if '.inner.' in k][:3])"
Previous release — v0.71.40, soup reward synth (generate a reward verifier from your data)
Point soup reward synth at a JSONL of reference outputs and it infers a deterministic verifier,
writes a readable / committable .py reward function, and — the part nobody else does — refuses to
emit one that can't tell your references from bad answers (four families: numeric / json_schema /
regex / tool_call; a mandatory calibration report is the moat). Reward ensembles
(reward_fn: "accuracy,format") also train now. (#311)
Use pip rather than pipx if you also want to import soup_cli from your own
code, since pipx deliberately isolates the application from everything else.
The full extras table (fast, mlx, serve, eval, ui, vision, audio, …) lives in
docs/models.md.
error: externally-managed-environment? That is
PEP 668, not a Soup problem. Debian 12,
Ubuntu 23.04 and later stop pip from writing into the system Python, because
apt manages those files too. pipx and uv tool sidestep it by giving Soup
its own environment, which is why they are listed first above. python3 -m venv .venv && source .venv/bin/activate then plain pip works just as well.
Double quotes, not single."soup-cli[train]" is the only spelling that works in every
shell — cmd.exe, PowerShell, bash and zsh. If you copied 'soup-cli[train]' from an older
tutorial and pip rejected it, that is the reason:
why, and the exact error.
soup init, soup data …, and the other data/inspection commands work on the light install.
Fine-tuning (soup train) needs the [train] extra.
2. Create a config
soup init                       # interactive wizard
soup init --template chat       # or start from a template
config/schema.py is the single source of truth for every field. Advanced data, training,
and PEFT options are documented under Documentation.
Unknown config keys warn today and will be rejected in v0.75. A key no model
declares — a typo like quantizaton, or a field that only exists on a newer Soup —
used to validate clean and be discarded, so the run proceeded with the setting simply
not applied. It is now reported at load with the field you probably meant. From
v0.75 the same config will fail to load instead of warning, so fix or remove the
key rather than relying on it being ignored. See
Unknown config keys.
Documentation
The full feature reference lives in docs/. Start here:
Recommended model families, the VRAM size guide, the pip extras matrix
Data Formats
Alpaca, ShareGPT, ChatML, preference pairs (DPO / ORPO / SimPO / IPO / KTO), vision, audio,
ASR, plaintext, embedding, RAFT and more — all auto-detected from JSONL, JSON, CSV, Parquet or
TXT, so in most cases you point data.train at a file and nothing else changes. Schemas with a
worked example per format, plus the data pipeline (remote URIs, streaming, sharding,
interleaving, vocab expansion, document ingestion), are in
docs/data.md.
Common Commands
soup train  --config soup.yaml        # train (SFT/DPO/GRPO/PPO/KTO/ORPO/SimPO/IPO/...)
soup infer  --model ./output --input prompts.jsonl   # batch inference
soup chat   --model ./output          # interactive chat
soup serve  --model ./output          # OpenAI-compatible API server
soup ui                               # local browser dashboard
soup merge  --adapter ./output        # merge LoRA into the base model
soup export --model ./output --format gguf           # export for deployment
soup eval   benchmark --model ./output               # evaluate
soup data   inspect ./data/train.jsonl               # dataset stats
soup recipes list                     # 100+ ready-made model recipes
soup autopilot --model <id> --data d.jsonl --goal chat  # zero-config
soup doctor                           # check GPU / deps / environment
Soup works with any text-generation model on the
HuggingFace Hub — if it loads with
AutoModelForCausalLM, it works, zero config changes. Llama 3.x/4, Qwen 2.5/3, Gemma 3, Mistral,
Mixtral, DeepSeek R1/V3, Phi-4, and 100+ others ship as ready-made recipes (soup recipes list).
VRAM
Max model (QLoRA 4-bit)
Example
8 GB
~7B
Llama-3.1-8B, Mistral-7B
16 GB
~14B
Phi-4-14B, Qwen2.5-14B
24 GB
~34B
CodeLlama-34B, Yi-1.5-34B
48 GB
~70B
Llama-3.3-70B
80 GB+
70B+ (full) or MoE
Mixtral-8x22B, DeepSeek-V3
Full model + vision tables and the optional-extras matrix are in docs/models.md.
Docker
Run Soup without installing CUDA or PyTorch locally (image published to GHCR on every release):
docker pull ghcr.io/makazhanalpamys/soup:latest
docker run --gpus all -v $(pwd):/workspace ghcr.io/makazhanalpamys/soup train --config soup.yaml
docker compose up   # or build locally
Requirements
Python 3.10, 3.11 or 3.12 (those are the versions CI tests; 3.13+ is not supported yet
because the PyTorch stack has not been validated there)
GPU with CUDA (recommended), Apple Silicon (MPS), or CPU (experimental — very slow)
8 GB+ VRAM for 7B models with QLoRA
All training tasks run on CPU for testing (quantization auto-disabled). Optional extras
(train, all, fast, vision, qat, serve, serve-fast, ui, eval, deepspeed,
liger, mlx, onnx, tensorrt, …) are listed in
docs/models.md.
What is this?Soup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.
Is this a CLI tool, or does it need a separate training server?It is a Python CLI application (soup-cli) installed via pip/pipx that runs training locally; it also ships an optional local Web UI dashboard for monitoring runs.
How do I install it and start a training run?Install with pipx install soup-cli[train] (or pip install for virtualenvs/Docker), create a soup.yaml from a built-in template like chat, dpo, kto or vision, then run soup train.
What do I need on my machine before running it?Python 3.10-3.12 and a GPU with CUDA are recommended; Apple Silicon (MPS) and CPU-only also work, though CPU training is described as experimental and very slow.
Is layer streaming reliable enough to rely on?Layer streaming is opt-in and still marked BETA; it previously could not run at all on free Colab/Kaggle T4, P100, V100 or GTX 16xx tiers, and GRPO/PPO are intentionally excluded from it.
Does it run on Windows and Mac, or only Linux?Being a Python CLI it works cross-platform (Linux, macOS, Windows) via pip/pipx, and a prebuilt Docker image is published on every release if you don't want to install CUDA/PyTorch locally.
How little VRAM do I actually need to fine-tune an 8B model?Soup's layer streaming feeds the frozen base model into the GPU one decoder layer at a time, letting an 8B model train in about 3.32 GB peak VRAM at 119.6 tok/s on a 4 GB RTX 3050 Laptop GPU.
What models can I fine-tune with Soup?Any text-generation model on the HuggingFace Hub that loads with AutoModelForCausalLM, with 100+ ready-made recipes including Llama 3.x/4, Qwen 2.5/3, Gemma 3, Mistral, DeepSeek R1/V3 and Phi-4.
What training methods does it support beyond plain SFT?Preference-tuning methods like DPO, GRPO, PPO, KTO, ORPO, SimPO, IPO and BCO, plus pre-training, distillation, classification and vision/audio/TTS tasks, all runnable over the same layer-streamed base.
What is soup reward synth?Point it at a JSONL of reference outputs and it infers a deterministic reward-verifier function (numeric, jsonschema, regex or toolcall), refusing to emit one that can't distinguish your references from bad answers.
Why did the author build Soup instead of using existing scripts?Because teams spend 30-50% of their time fighting training infrastructure instead of improving models, so Soup automates GPU detection, batch sizing and quantization behind a single YAML config with zero SSH.






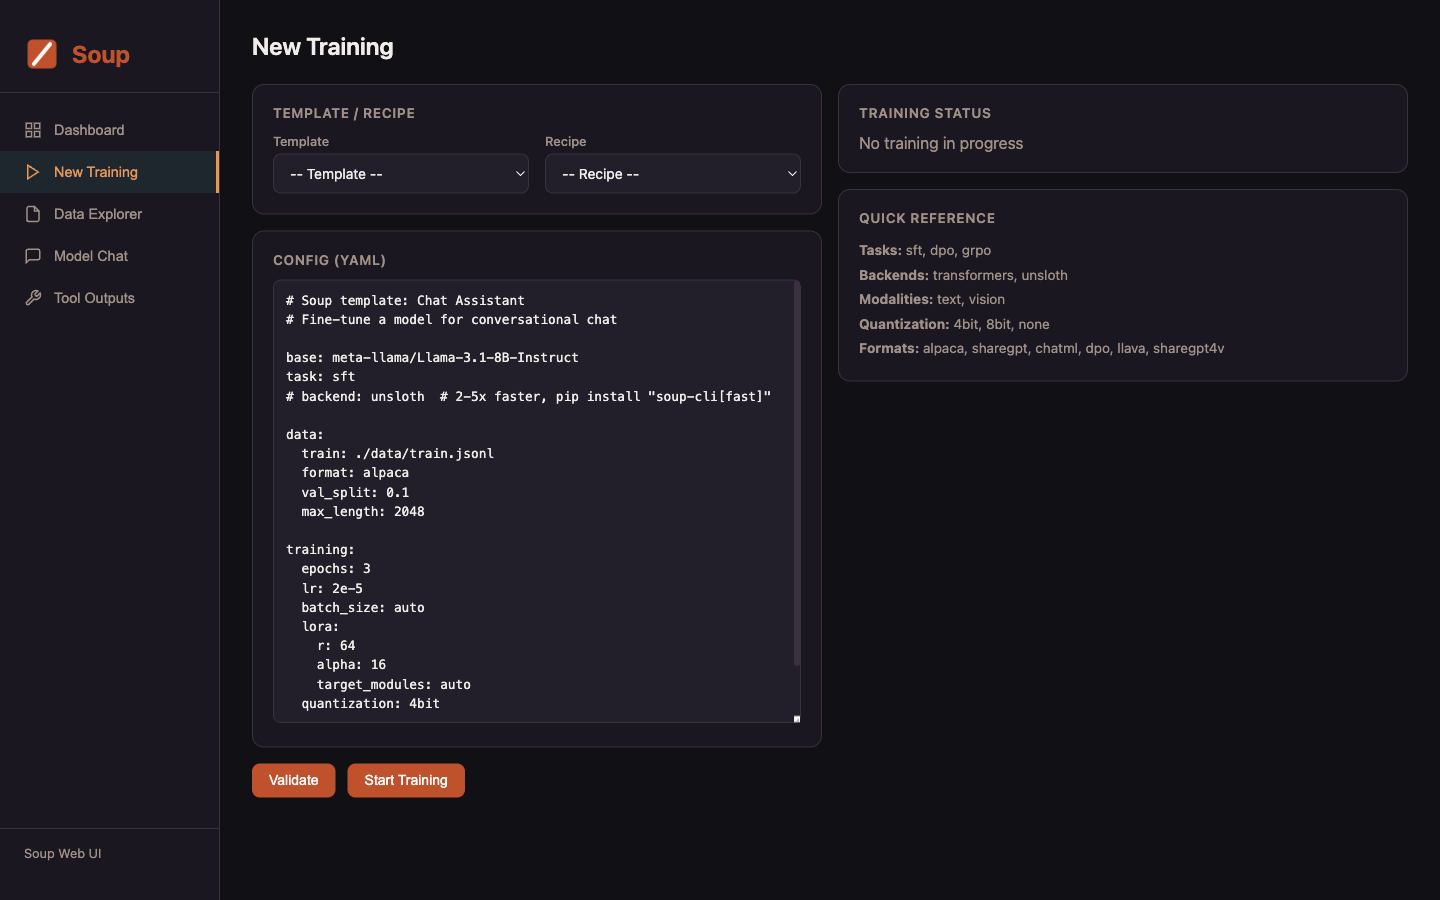

 Soup is a command-line tool for fine-tuning and post-training LLMs from a single YAML config file, automating GPU detection, batching and quantization so you just write a config and run one command.