🚀 LightRAG: Simple and Fast Retrieval-Augmented Generation
🎉 News
- [2026.07]🎯[New Feature]: Add Smart Heading recognition feature for word documents.
- [2026.05]🎯[New Feature]: Merge RagAnything into LightRAG🎉. Multimodal content parsing and extraction via MinerU / Docling services.
- [2026.05]🎯[New Feature]: Introducing four selectable text chunking strategies:
Fix, Recursive, Vector, and Paragraph.
- [2026.05]🎯[New Feature]: Role-specific LLM configuration support, 4 distinct roles: EXTRACT, QUERY, KEYWORDS, and VLM, with independent LLM settings.
- [2026.03]🎯[New Feature]: Integrated OpenSearch as a unified storage backend, providing comprehensive support for all four LightRAG storage.
- [2026.03]🎯[New Feature]: Introduced a setup wizard. Support for local deployment of embedding, reranking, and storage backends via Docker.
- [2025.11]🎯[New Feature]: Integrated RAGAS for Evaluation and Langfuse for Tracing. Updated the API to return retrieved contexts alongside query results to support context precision metrics.
- [2025.10]🎯[Scalability Enhancement]: Eliminated processing bottlenecks to support Large-Scale Datasets Efficiently.
- [2025.09]🎯[New Feature] Enhances knowledge graph extraction accuracy for Open-Sourced LLMs such as Qwen3-30B-A3B.
- [2025.08]🎯[New Feature] Reranker is now supported, significantly boosting performance for mixed queries (set as default query mode).
- [2025.08]🎯[New Feature] Added Document Deletion with automatic KG regeneration to ensure optimal query performance.
- [2025.06]🎯[New Release] Our team has released RAG-Anything — an All-in-One Multimodal RAG system for seamless processing of text, images, tables, and equations.
- [2025.06]🎯[New Feature] LightRAG now supports comprehensive multimodal data handling through RAG-Anything integration, enabling seamless document parsing and RAG capabilities across diverse formats including PDFs, images, Office documents, tables, and formulas. Please refer to the new multimodal section for details.
- [2025.03]🎯[New Feature] LightRAG now supports citation functionality, enabling proper source attribution and enhanced document traceability.
- [2025.02]🎯[New Feature] You can now use MongoDB as an all-in-one storage solution for unified data management.
- [2025.02]🎯[New Release] Our team has released VideoRAG-a RAG system for understanding extremely long-context videos
- [2025.01]🎯[New Release] Our team has released MiniRAG making RAG simpler with small models.
- [2025.01]🎯You can now use PostgreSQL as an all-in-one storage solution for data management.
- [2024.11]🎯[New Resource] A comprehensive guide to LightRAG is now available on LearnOpenCV. — explore in-depth tutorials and best practices. Many thanks to the blog author for this excellent contribution!
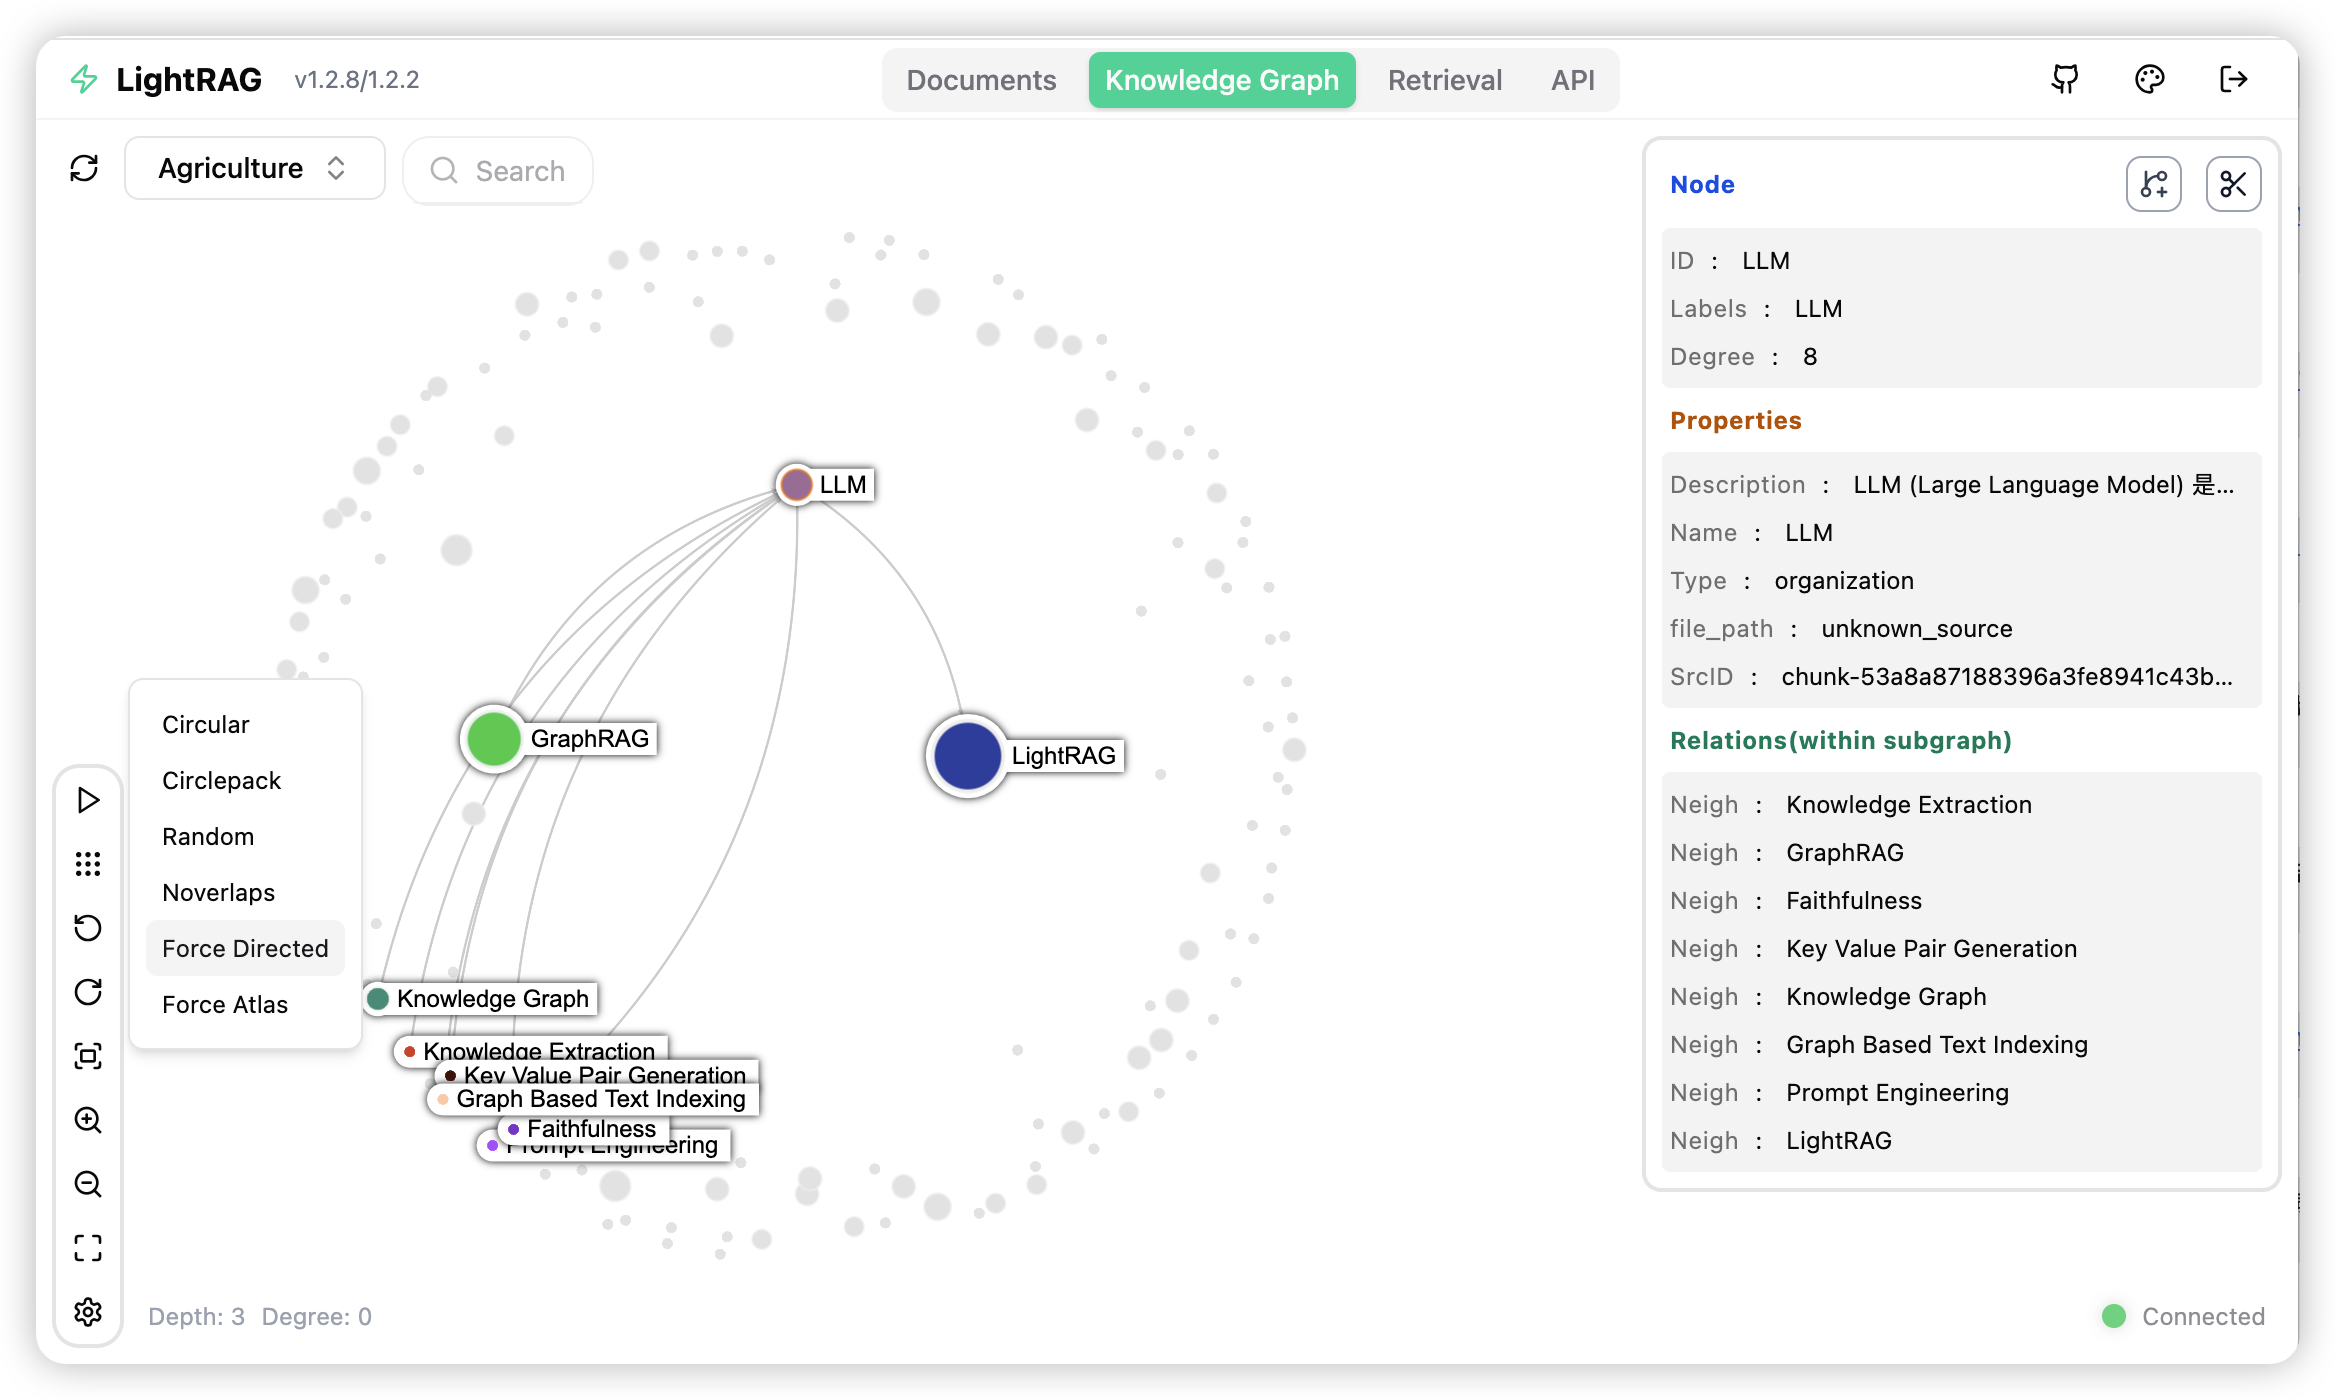
- [2024.11]🎯[New Feature] Introducing the LightRAG WebUI — an interface that allows you to insert, query, and visualize LightRAG knowledge through an intuitive web-based dashboard.
- [2024.11]🎯[New Feature] You can now use Neo4J for Storage-enabling graph database support.
- [2024.10]🎯[New Feature] We've added a link to a LightRAG Introduction Video. — a walkthrough of LightRAG's capabilities. Thanks to the author for this excellent contribution!
- [2024.10]🎯[New Channel] We have created a Discord channel!💬 Welcome to join our community for sharing, discussions, and collaboration! 🎉🎉
Algorithm Flowchart
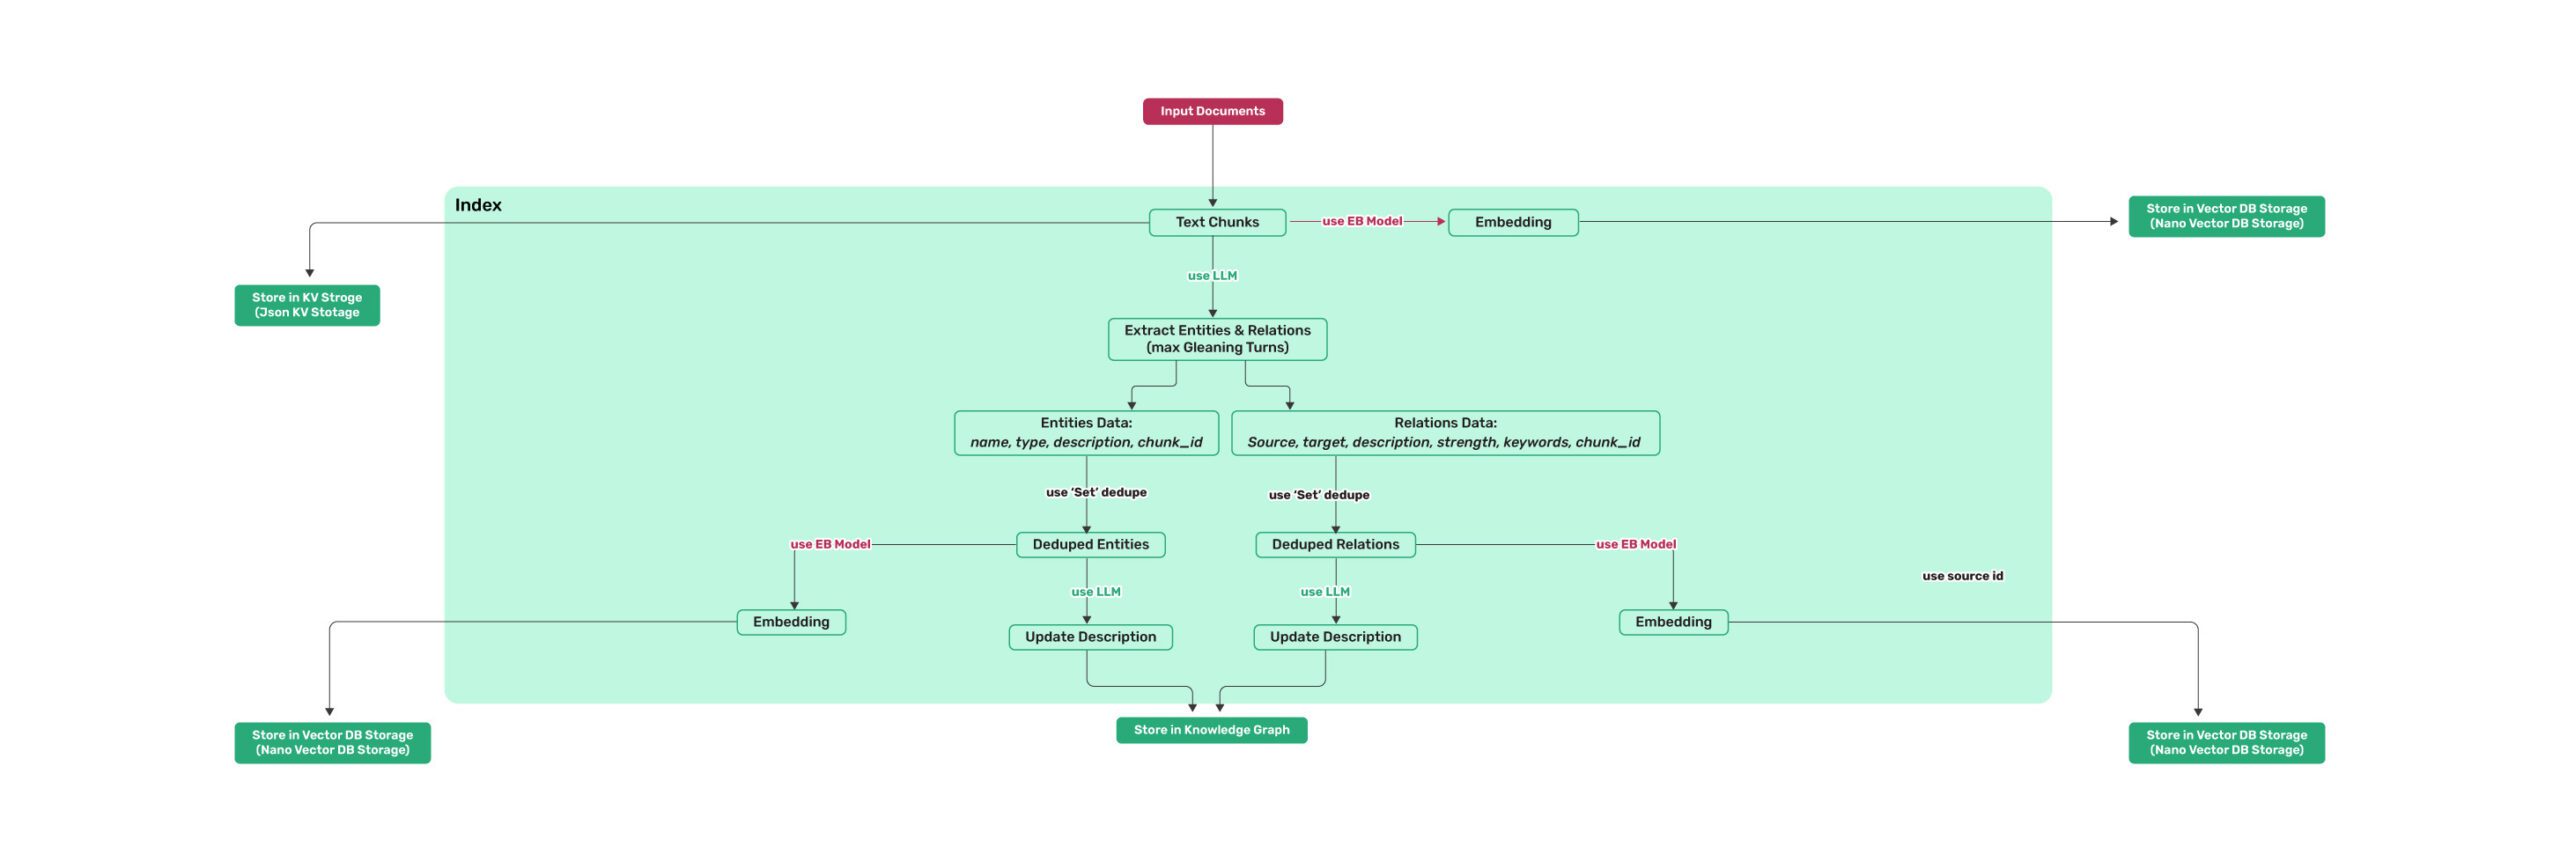 Figure 1: LightRAG Indexing Flowchart - Img Caption : Source
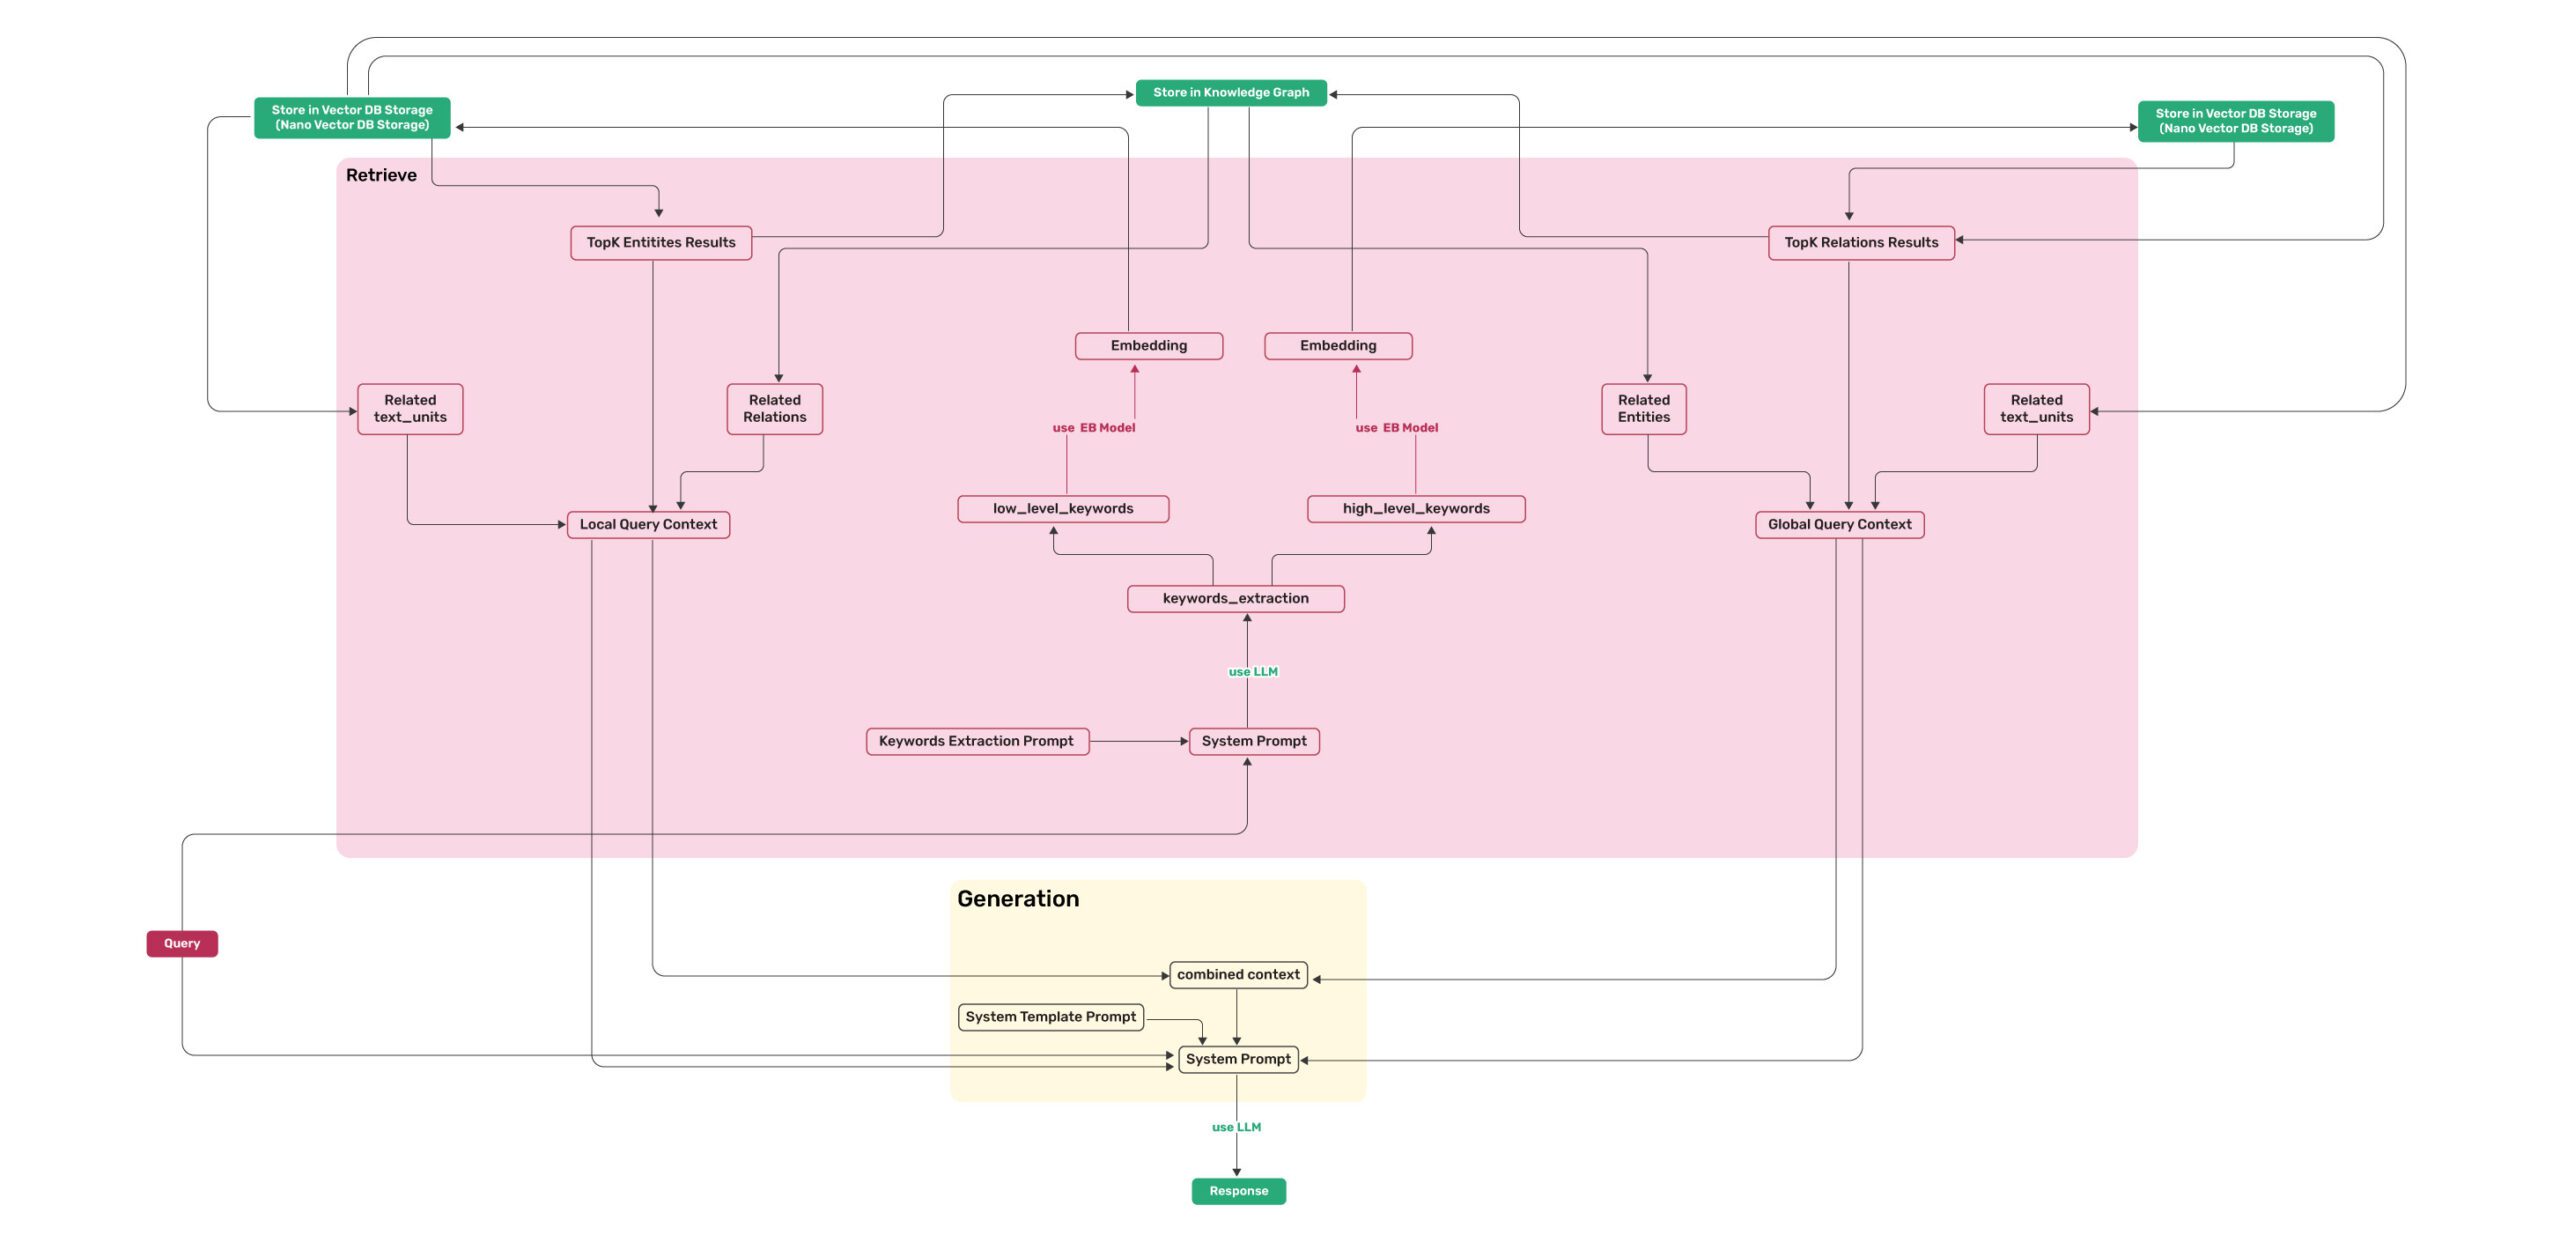 Figure 2: LightRAG Retrieval and Querying Flowchart - Img Caption : Source
Installation
💡 Using uv for Package Management: This project uses uv for fast and reliable Python package management. Install uv first: curl -LsSf https://astral.sh/uv/install.sh | sh (Unix/macOS) or powershell -c "irm https://astral.sh/uv/install.ps1 | iex" (Windows)
Note: You can also use pip if you prefer, but uv is recommended for better performance and more reliable dependency management.
📦 Offline Deployment: For offline or air-gapped environments, see the Offline Deployment Guide for instructions on pre-installing all dependencies and cache files.
Install LightRAG Server
### Install LightRAG Server as tool using uv (recommended)
uv tool install "lightrag-hku[api]"

### Or using pip
# python -m venv .venv
# source .venv/bin/activate  # Windows: .venv\Scripts\activate
# pip install "lightrag-hku[api]"

# Setup env file
# Obtain the env.example file by downloading it from the GitHub repository root
# or by copying it from a local source checkout.
cp env.example .env  # Update the .env with your LLM and embedding configurations
# Launch the server. It binds to all interfaces (0.0.0.0) by default.
# SECURITY: before exposing it on a network, configure authentication in .env
# (LIGHTRAG_API_KEY, or AUTH_ACCOUNTS together with TOKEN_SECRET), or bind to
# 127.0.0.1 for local-only access; without auth every endpoint is public.
# Note: the Ollama-compatible /api/* routes stay open by default for client
# compatibility; set WHITELIST_PATHS=/health to require auth on them too.
lightrag-server
git clone https://github.com/HKUDS/LightRAG.git
cd LightRAG

# Bootstrap the development environment (recommended)
make dev
source .venv/bin/activate  # Activate the virtual environment (Linux/macOS)
# Or on Windows: .venv\Scripts\activate

# make dev installs the test toolchain plus the full offline stack
# (API, storage backends, and provider integrations), then builds the frontend.
# Run make env-base or copy env.example to .env before starting the server.

# Equivalent manual steps with uv
# Note: uv sync automatically creates a virtual environment in .venv/
uv sync --extra test --extra offline
source .venv/bin/activate  # Activate the virtual environment (Linux/macOS)
# Or on Windows: .venv\Scripts\activate

### Or using pip with virtual environment
# python -m venv .venv
# source .venv/bin/activate  # Windows: .venv\Scripts\activate
# pip install -e ".[test,offline]"

# Build front-end artifacts
cd lightrag_webui
bun install --frozen-lockfile
bun run build
cd ..

# setup env file
make env-base  # Or: cp env.example .env and update it manually
# Launch API-WebUI server
lightrag-server
- Launching the LightRAG Server with Docker Compose
git clone https://github.com/HKUDS/LightRAG.git
cd LightRAG
cp env.example .env  # Update the .env with your LLM and embedding configurations
# modify LLM and Embedding settings in .env
docker compose up
Historical versions of LightRAG docker images can be found here: LightRAG Docker Images
Official GHCR images published by GitHub Actions are signed with Sigstore Cosign using GitHub OIDC. See docs/DockerDeployment.md for verification commands.
On Apple Silicon (macOS 26) without Docker Desktop, you can run the same Postgres/Neo4j/Milvus storage stack on Apple's native container runtime — see docs/AppleContainerSetup.md.
Instead of editing env.example by hand, use the interactive setup wizard to generate a configured .env and, when needed, docker-compose.final.yml:
make env-base           # Required first step: LLM, embedding, reranker
make env-storage        # Optional: storage backends and database services
make env-server         # Optional: server port, auth, and SSL
make env-base-rewrite   # Optional: force-regenerate wizard-managed compose services
make env-storage-rewrite # Optional: force-regenerate wizard-managed compose services
make env-security-check # Optional: audit the current .env for security risks
For full description of every target see docs/InteractiveSetup.md.
Optional: spaCy Models for docx smart_heading
The native docx parser's opt-in smart_heading engine parameter uses spaCy for sentence/NER heuristics. The spaCy runtime is already included in the api extra — only the two pinned language models (zh_core_web_sm / en_core_web_sm 3.8.0, GitHub release wheels not published on PyPI) need one extra step:
lightrag-download-cache --spacy-install
Enable smart_heading per file/rule (e.g. LIGHTRAG_PARSER=docx:native(smart_heading=true)), or globally in .env:
# .docx files routed to the native engine get smart_heading by default;
# opt a file back out with an explicit native(smart_heading=false) rule/hint.
DOCX_SMART_HEADING=true
When the global switch is on (or a LIGHTRAG_PARSER rule carries native(smart_heading=true)), the server verifies the models at startup and fails fast with install guidance if they are missing. Deployments that never enable smart_heading need no models. The main Docker image ships the models pre-installed (the lite image does not); for air-gapped hosts see the Offline Deployment Guide.
Optional: libcairo for SVG Rasterization (native md/textpack)
The native markdown/textpack parser rasterizes embedded SVG images to PNG via cairosvg. cairosvg is a cffi binding: pip install cairosvg (pulled in by the api extra) always succeeds, but rendering only works if the native libcairo shared library is also present on the host — pip/uv cannot install system libraries. Without it, rasterization fails at runtime and the affected SVG is skipped (the rest of the document is unaffected); the server logs a warning at startup so the gap is visible before it shows up as a per-document warning later.
Install the system package for your platform:
# Debian / Ubuntu (the official Docker image already includes this)
sudo apt-get install -y libcairo2

# RHEL / Fedora
sudo dnf install -y cairo

# macOS (Homebrew)
brew install cairo

# Windows: install the GTK3 runtime, which bundles libcairo-2.dll
Deployments that never process markdown/textpack documents with embedded SVGs can ignore the startup warning.
About LightRAG
A Lightweight, Graph-Based RAG Framework
LightRAG is a lightweight knowledge-graph RAG framework and an efficient alternative to Microsoft GraphRAG. It adopts a dual-layer architecture to manage both knowledge graphs (KGs) and vector embeddings, effectively bridging the gap between traditional vector-based RAG and graph-based RAG approaches. Designed for high scalability, LightRAG addresses key challenges in large-scale graph indexing and retrieval, including heavy computational overhead, slow response times, and the high cost of incremental updates. While supporting large datasets, LightRAG can still deliver exceptionally high RAG quality, even when paired with a 30B open-source large language model (LLM).
Features & Advantages
- Deep Contextual Understanding: Through graph-structured indexing, LightRAG captures complex semantic dependencies between entities, overcoming the fragmented context limitations typical of traditional chunk-based retrieval methods. Its generation quality and context awareness are particularly outstanding in vertical domains (e.g., legal, financial) that require global comprehension or logical reasoning.
- Exceptional Comprehensiveness & Diversity: LightRAG’s dual-level retrieval mechanism allows it to integrate detailed facts and abstract concepts concurrently. This enables the system to achieve remarkable performance in query result comprehensiveness and diversity, making it highly effective at handling complex, cross-document queries.
- Extreme Retrieval Efficiency & Low Cost: LightRAG does not rely on inefficient community reports or multi-hop reasoning for complex queries. This drastically reduces the number of LLM calls required during both the indexing and querying phases, significantly lowering response latency and LLM computational costs.
- Incremental Updates & Selective Deletion: LightRAG addresses the challenges of incrementally updating and selectively deleting content from graph-based knowledge bases, keeping them current in dynamic data environments. When a document is deleted, the system can use the LLM cache created during indexing to quickly rebuild the affected entities and relationships, substantially improving update efficiency.
- Multiple Document Parsing Engines: LightRAG's document processing pipeline supports MinerU, Docling, and Native and can be extended with third-party parsers. LightRAG's Native engine efficiently parses images, tables, and formulas in Word and Markdown documents, making it especially suitable for documents rich in multimodal content. The Native engine also automatically detects and corrects section headings in Word documents, improving content extraction from documents with inconsistent outlines and laying the foundation for section-aware text chunking.
- Multiple Text Chunking Strategies: LightRAG supports four text chunking strategies:
Fixed-length (F), Recursive character (R), Vector semantic (V), and Paragraph semantic (P). The LightRAG-native Paragraph semantic (P) strategy aligns chunk boundaries with the document's native semantic boundaries—headings, paragraphs, and tables—as closely as possible. This reduces problems such as mismatched headings and content or missing header rows when long tables are split.
- Multiple Storage Backends: LightRAG's default KV, vector, and graph stores are in-memory databases with local file persistence — suitable only for small-scale testing and evaluation, not for production. LightRAG also supports a wide range of commonly used storage backends (PostgreSQL recommended) for production deployments with large datasets.
Multimodal Capability Upgrades
Traditional RAG systems lack an effective way to process multimodal content such as images, formulas, and tables in documents. Starting with v1.5, LightRAG seamlessly integrates multimodal processing into its document pipeline and query flow. Through the knowledge graph, LightRAG connects multimodal content with the body text and can use that information when answering queries to produce more accurate and reliable responses. This capability can substantially improve RAG quality for documents rich in multimodal content, such as operation manuals and academic papers.
LightRAG API Server
The LightRAG server offers not only a web-based UI for exploring LightRAG functionalities but also a comprehensive REST API. For more information about the LightRAG server, please refer to LightRAG Server.
Key Configuration Guide
Selecting LLM Models
LightRAG requires LLM/VLMs of four different roles during its workflow





 LightRAG 是 HKUDS 开发的开源图结构 RAG 框架(发表于 EMNLP 2025)。它把你的文档索引成知识图谱加上向量嵌入,方便你进行查询——是 Microsoft GraphRAG 之外一个更轻量、更快速的选择。