

6.5K ·GitHub
Что это такое?
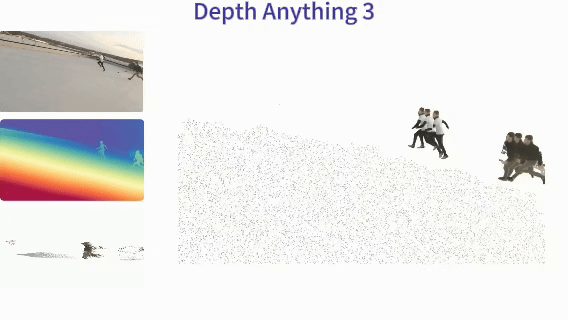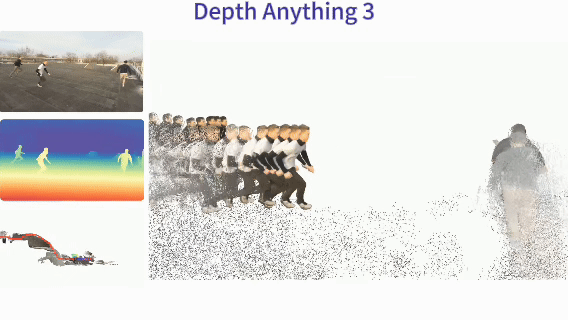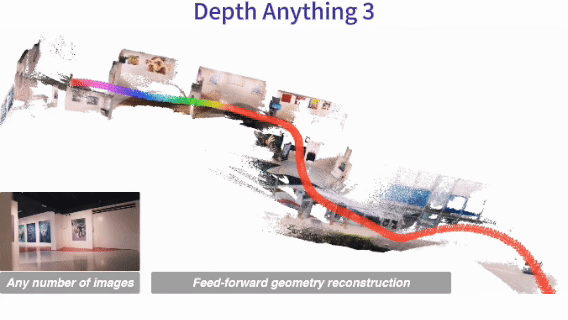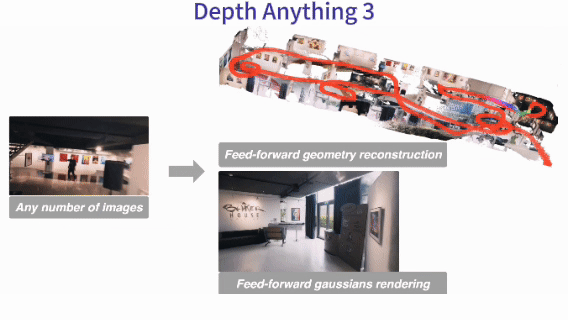
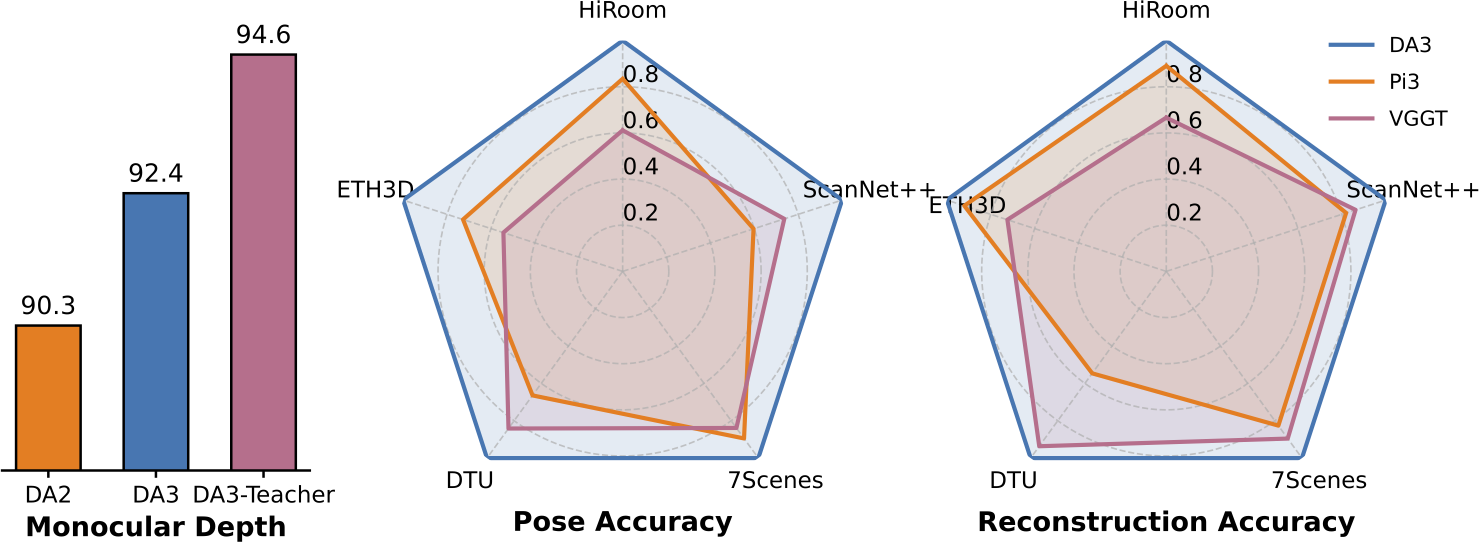
 Depth Anything 3 (DA3) — это фундаментальная модель от ByteDance Seed, которая предсказывает пространственно согласованную геометрию — глубину, положения камер, даже 3D-гауссианы — по произвольным визуальным входным данным, с известными положениями камер или без них.
Это модель, которую я скачиваю, Python-библиотека или готовое приложение?И то и другое, в одном репозитории: предобученные чекпоинты плюс Python-инструментарий, который оборачивает их в веб-интерфейс на Gradio, CLI со скриптами и Python API. Архитектура задана в DepthAnything3Net и настраивается через Yaml-файлы.
И то и другое, в одном репозитории: предобученные чекпоинты плюс Python-инструментарий, который оборачивает их в веб-интерфейс на Gradio, CLI со скриптами и Python API. Архитектура задана в DepthAnything3Net и настраивается через Yaml-файлы.Как это запустить?Это Python-проект: установите зависимости, скачайте чекпоинт из Model Zoo, а затем запускайте через веб-интерфейс Gradio для интерактивной работы, через CLI для пакетной обработки или через Python API.
Это Python-проект: установите зависимости, скачайте чекпоинт из Model Zoo, а затем запускайте через веб-интерфейс Gradio для интерактивной работы, через CLI для пакетной обработки или через Python API.Есть ли подводные камни при скачивании весов модели?Да: модели с суффиксом -1.1 были переобучены после исправления бага в обучении и работают лучше, особенно на уличных сценах — лучше брать их; оригинальные чекпоинты Giant, Large и Nested устарели.
Да: модели с суффиксом -1.1 были переобучены после исправления бага в обучении и работают лучше, особенно на уличных сценах — лучше брать их; оригинальные чекпоинты Giant, Large и Nested устарели.Можно ли бесплатно использовать это в коммерческих проектах?Код распространяется под Apache-2.0, как и небольшие чекпоинты (DA3-BASE, DA3-SMALL, DA3METRIC-LARGE, DA3MONO-LARGE), но флагманские веса GIANT, LARGE и NESTED — под CC BY-NC 4.0, то есть только для некоммерческого использования.
Код распространяется под Apache-2.0, как и небольшие чекпоинты (DA3-BASE, DA3-SMALL, DA3METRIC-LARGE, DA3MONO-LARGE), но флагманские веса GIANT, LARGE и NESTED — под CC BY-NC 4.0, то есть только для некоммерческого использования.Мне нужна мощная видеокарта для этого?GPU нужен, а размер модели — ваш рычаг: от DA3-Small (0.08B) до Giant (1.15B). DA3-Streaming обрабатывает сверхдлинные видеопоследовательности менее чем на 12 ГБ видеопамяти за счёт инференса скользящим окном.
GPU нужен, а размер модели — ваш рычаг: от DA3-Small (0.08B) до Giant (1.15B). DA3-Streaming обрабатывает сверхдлинные видеопоследовательности менее чем на 12 ГБ видеопамяти за счёт инференса скользящим окном.Как получить глубину в реальных метрах?Используйте DA3METRIC-LARGE и вычислите metricdepth = focal * netoutput / 300, где focal — фокусное расстояние в пикселях (среднее fx и fy из матрицы внутренних параметров камеры K). Серия Nested и так выдаёт глубину в метрах.
Используйте DA3METRIC-LARGE и вычислите metricdepth = focal * netoutput / 300, где focal — фокусное расстояние в пикселях (среднее fx и fy из матрицы внутренних параметров камеры K). Серия Nested и так выдаёт глубину в метрах.Что меняет флаг useraypose?Он заставляет модель вычислять положение камеры через ray head — в целом чуть медленнее, но точнее. По умолчанию стоит False для более быстрого инференса.
Он заставляет модель вычислять положение камеры через ray head — в целом чуть медленнее, но точнее. По умолчанию стоит False для более быстрого инференса.На каких данных обучали модели?Все модели обучены исключительно на публичных академических датасетах, как сказано в README.
Все модели обучены исключительно на публичных академических датасетах, как сказано в README.Он подключается к таким инструментам, как Blender или ComfyUI?Да — в составляемом сообществом списке Awesome DA3 есть аддон для Blender для реконструкции по наборам изображений, ноды ComfyUI для глубины по одному/нескольким видам и согласованной по видео глубины, обёртки ROS2 для робототехники и просмотрщик видео на Three.js/WebXR.
Да — в составляемом сообществом списке Awesome DA3 есть аддон для Blender для реконструкции по наборам изображений, ноды ComfyUI для глубины по одному/нескольким видам и согласованной по видео глубины, обёртки ROS2 для робототехники и просмотрщик видео на Three.js/WebXR.What are similar projects?nerfstudio, vggt, lingbot-map, ml-sharp, vggt-omega, InsertAny3D, pointdit, ABot-Recon
nerfstudio, vggt, lingbot-map, ml-sharp, vggt-omega, InsertAny3D, pointdit, ABot-ReconWhich topics is it in?point-cloud, gaussian-splatting, vision-transformer, neural-rendering, pose-estimation, 3d-reconstruction, gradio, webui, transformer, inference, computer-vision, pytorch
point-cloud, gaussian-splatting, vision-transformer, neural-rendering, pose-estimation, 3d-reconstruction, gradio, webui, transformer, inference, computer-vision, pytorch