Alaya-EVOKE: From Linear-Scaling Supervision to Endless World
A three-step, CFG-free world model that remembers where it has been, takes direction mid-flight,
and keeps going — 1.5 s of video every 2.11 s on a single H200.
✨ Highlights
🏆 State of the art on WBench — as a three-step world model, while staying competitive in
visual quality on VBench-Long and VBench-2.0.
⚡ 3 steps, zero CFG. 1.5 s of 384×640 video every 2.11 s on one H200 — one forward per
step, not two. Few-step speed without few-step ceilings.
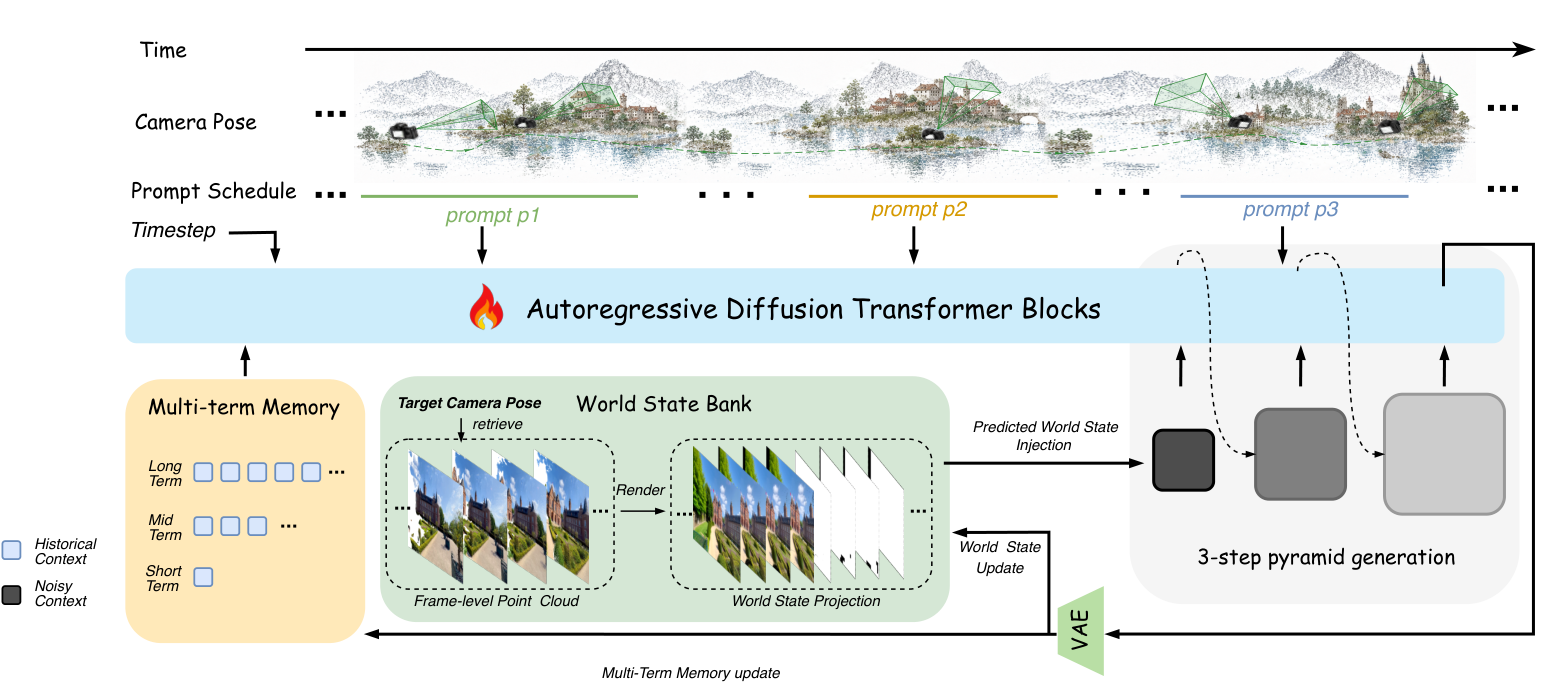
🌍 Endless, not windowed. Scene geometry lives in an external, camera-indexed world state
bank instead of the denoiser's context. Only what the current view needs is retrieved, so the
context stays bounded however long the session runs — no trading session length for memory.
🎛️ Re-promptable mid-flight. Per-chunk conditioning lets you change the prompt while the
rollout is running: the sky ignites, the storm rolls in, no cut and no restart.
🧑🏫 A teacher rebuilt for the long horizon. Chunk-wise grouping, distant-frame retrieval and a
linear-attention global state make its memory and compute grow linearly — which is what makes
30 s self-forced supervision affordable.
📰 Latest News
2026-08-30 — Director Web UI. EVOKE now ships with a local Web UI for per-chunk prompting,
dual-stick camera control, streaming previews, continuation, and revision branching. See the
UI guide and interface preview.
2026-08-14 — Day 0. Alaya-EVOKE entered the official
WBench table and achieved state of the art in its
release snapshot, one day after the first arXiv submission.
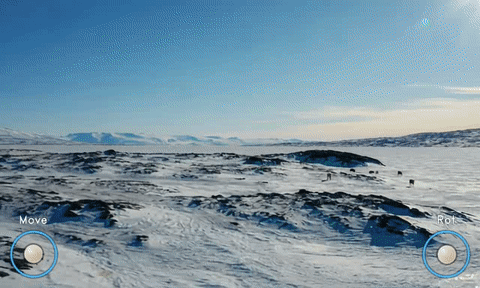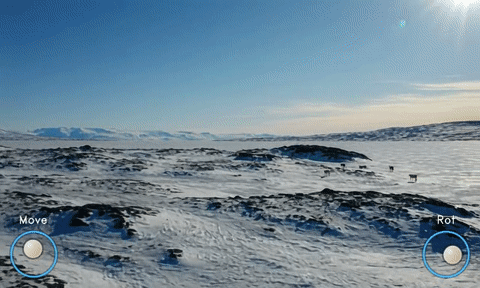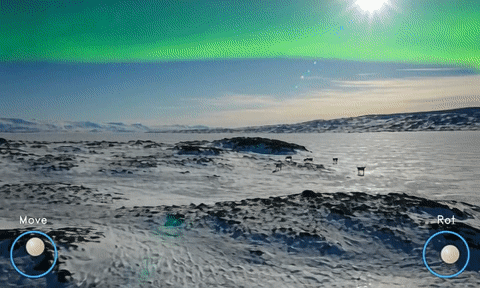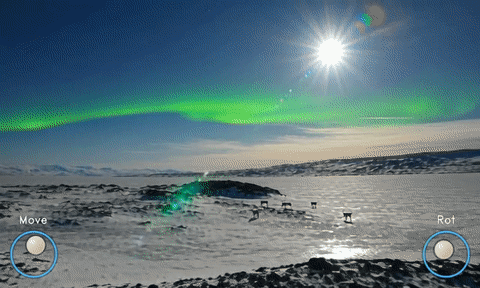
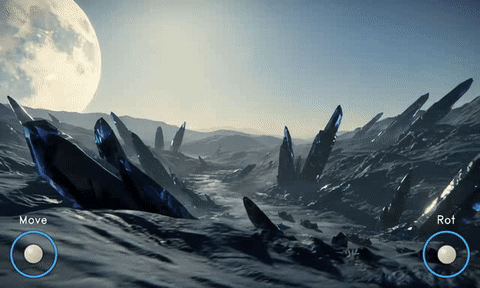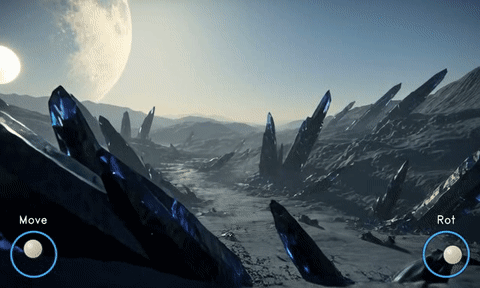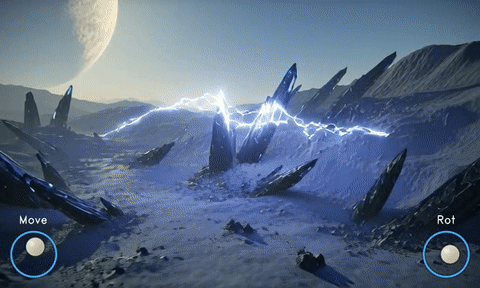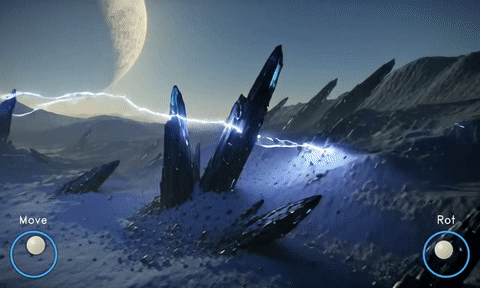
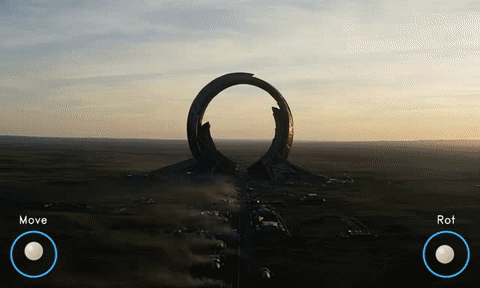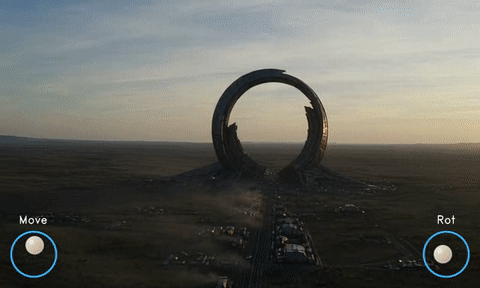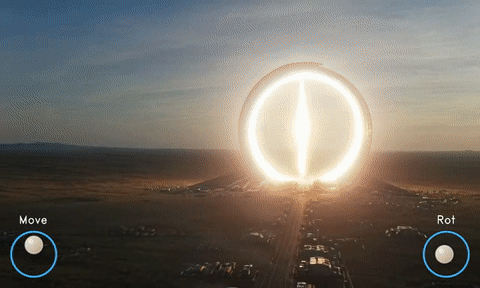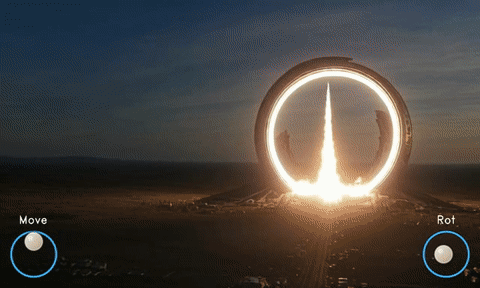
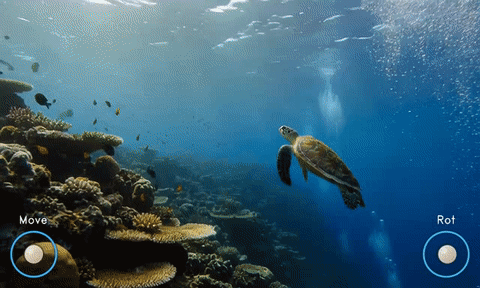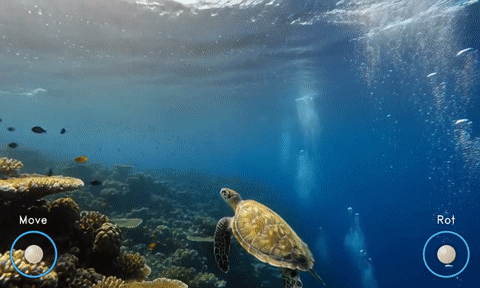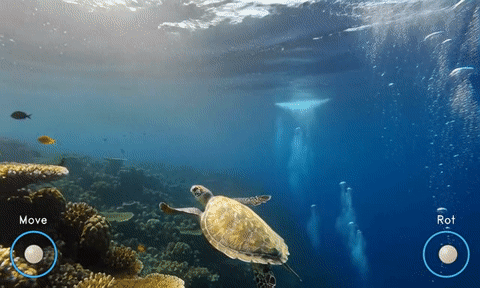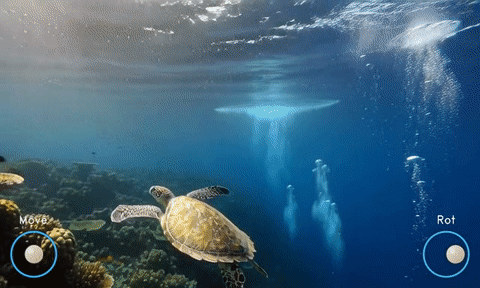
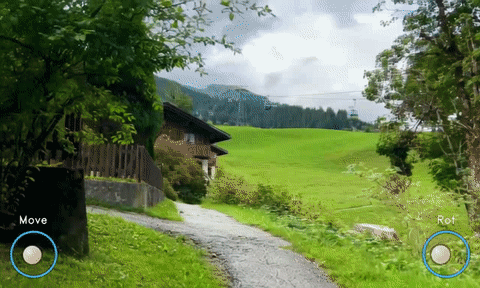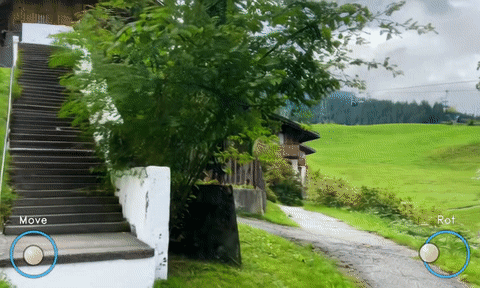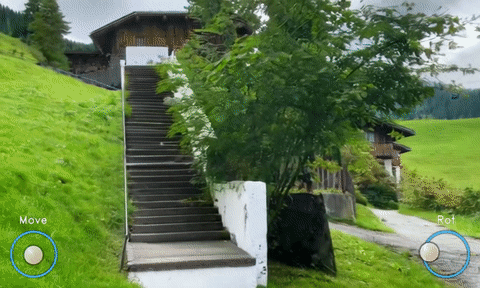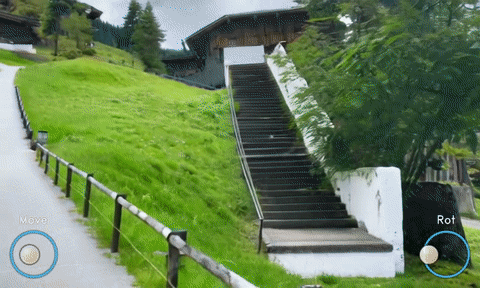
Every clip was produced by the launchers in this repo, on the data bundled in examples/ — no external
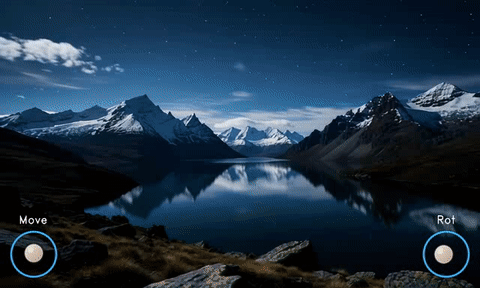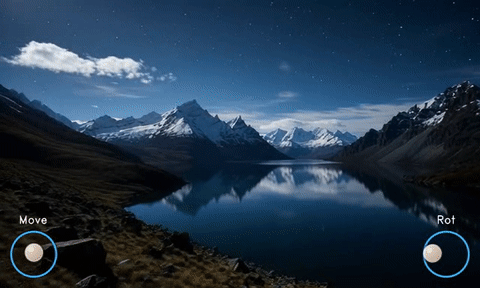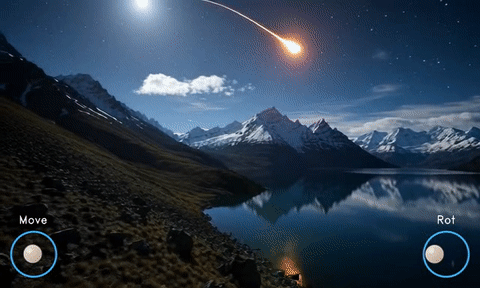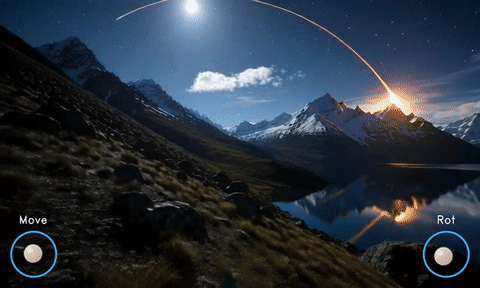
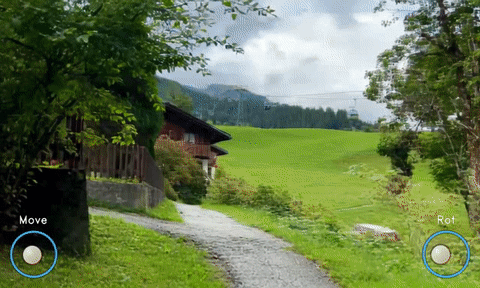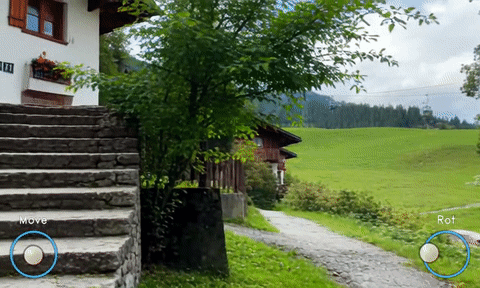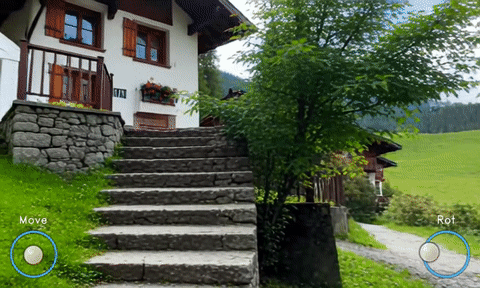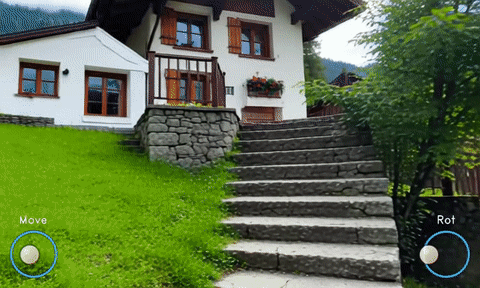
dataset, no cherry-picking across seeds. The Move / Rot joystick is the camera-control HUD burned
into geo_pred.mp4.
Re-prompting mid-rollout
Per-chunk conditioning lets the prompt change while the rollout is running — no cut, no restart.
Each schedule below switches at chunk 3 of 6 (213 frames, 8.9 s).
the frame-0 global anchor (i2v: the input image; v2v: the first latent of the reference video)
long / mid
multi-term parametric memory (history_sizes = [16, 2, 1]) with coarser patch kernels — long (4,8,8), mid (2,4,4), everything else (1,2,2)
warp
the world state bank rendered into this view; its RoPE overlaps the noise window
prev_short
the last latent of the previous chunk, the continuity anchor closest to the noise
Every tier lives at the same latent resolution (res/8); compression comes only from the patchify
convolution kernel, and no low-resolution latents are stored. In the short tier
[prefix | warp | prev_short] the residual MLP and the per-stage compression act only on the warp
frames in the middle.
The world state bank itself has three operations: write — a monocular depth model estimates depth
for the emitted chunk under its known poses, unprojected into a persistent point cloud; read — the
current camera pose addresses the bank directly, with sources ranked by co-visibility, up to eight
fused, and a batched z-buffered scatter returning a warped image plus a per-pixel visibility mask; and
evict — an optional retention window, which hour-scale runs enable explicitly.
⚙️ Environment
Python 3.10 + CUDA 12.4. The pins in requirements.txt are the environment actually in use —
torch 2.4 / deepspeed 0.14.5 / flash-attn are load-bearing, not aspirational.
Two things pip will not do: diffusers is pinned to a development fork that is not on PyPI
(install it first or nothing imports), and postprocess_viz.py needs the ffmpeg binary on
PATH. Both depth backends (ViGeo, Depth-Anything-3) are vendored under
evoke/third_party/, so only their weights are downloaded — see Weights.
📦 Weights
Everything goes under models/ (gitignored). Every released EVOKE directory is the parent of a
transformer/, because it loads as from_pretrained(path, subfolder="transformer").
models/
├── model_index.json                              a map of this layout -- not a loadable pipeline
├── evoke-base/                                   vae / text_encoder / tokenizer / scheduler only
├── ViGeo1.1/vigeo.pt                             depth backend -- REQUIRED
├── DA3/{config.json,model.safetensors}           depth backend -- OPTIONAL
└── evoke/
    ├── stage1_camera_control/transformer/        multi-step camera-controllable model
    ├── stage2_few_step_training/transformer/     few-step distillation (3-step pyramid)
    ├── stage3_long_distillation/transformer/     30s long-video distillation (post-distill init)
    ├── stage3_post_distillation/transformer/     the shipped model
    └── evoke_teacher/{high,low}_noise/           the two DMD teacher experts -- training only
# EVOKE -- the four released models, the teacher, and the base components
hf download AlayaLab/Evoke --local-dir models

# ViGeo -- REQUIRED. The depth backend behind the world state bank; every shipped
# recipe uses it (DEPTH_BACKEND=vigeo, cloud_warp.backend: vigeo).
hf download pkqbajng/ViGeo --local-dir models/ViGeo1.1
Depth-Anything-3 is optional — nothing in the default path touches it, and you only need it if you
set DEPTH_BACKEND=da3. Get the da3-giant weights from
depth-anything-3 and drop
config.json + model.safetensors into models/DA3/. Switching backend is a recipe change, not a
speed knob — training and inference must agree on it.
Both depth backends ship under CC-BY-NC-4.0, which is more restrictive than this repo's
Apache-2.0. Check their licences before any commercial use.
🖥️ Director Web UI
The repository includes a local, single-GPU Director UI for the released post-distill model. It
supports a reference image, per-chunk prompts, independent movement/look camera controls, streaming
chunk previews, lazy full-video download, continuation, and non-destructive revision branching. The
bundled default is the six-chunk Meteor case.
Complete the Environment and Weights sections above first, make sure ffmpeg is on PATH, then run
from the repository root:
Open http://127.0.0.1:7860 and wait for the status to become READY. Generated projects, jobs,
videos, logs, and caches are excluded from source releases by ui/.gitignore.
The server binds to localhost by default and does not provide authentication or rate limiting. Do
not expose it directly to the public internet. Configuration, model-path overrides, data layout,
and the deliberately exposed reverse-proxy form are documented in ui/README.md.
🚀 Inference
384 × 640 @ 24 fps. One chunk = 36 frames = 1.5 s, so NUM_CHUNKS=20 is a 30 s clip. All four
commands run on the data bundled in examples/ — one case each, four for segment — no external
dataset:
Results land in <OUT_ROOT>/<case>/geo_pred.mp4. Every distilled model was trained on v2v
conditioning alone (geo_condition_{i2v,t2v}_ratio: 0.0), so MODE=i2v|t2v on them is zero-shot
and the launchers say so at startup. Only stage1_camera_control has all three modes in distribution
(ratios 0.1 / 0.2).
Everything else — the mode × model matrix, hour-scale rollouts, per-chunk log format, and how to point
the launchers at your own data — is in scripts/inference/README.md.
Every launcher also has -h.
🗝️ Training
One launcher per released model. Each initialises from its own released checkpoint, so you
continue from where we left off — nobody reproduces a stage from scratch, and the pretraining data is
not part of this release:
Post-distillation goes back to the stage-1 teacher on purpose: it is a short run that firms up camera
control, not another long-horizon distillation.
Each writes to models/train/<same-name>/; move or symlink it into models/evoke/ to serve it.
All four start with no external dataset — they point at the single 60 s clip in examples/data/,
so they run as a pipeline check, not a real training run (one clip overfits immediately). For a real
run swap data_yaml_path to the production mix named beside it in the config.
Scale is set by ACCELERATE_CONFIG — the topology is baked into the accelerate yaml, so do not
override it with --num_machines. To merge a LoRA checkpoint into a full transformer, see
tools/merge_lora_ckpt.py (use --dtype fp32: the delta is ~5e-4 of the weight magnitude and bf16
swallows it).
📝 Notes
The warp / attention recipe must match between training and inference. A mismatch silently
degrades quality rather than failing — every knob in the launchers is annotated with the config
field it mirrors.
Resolution is data driven, but keep the width a multiple of 64 so the long tier and the
quarter-resolution pyramid stage both divide evenly.
👍 Acknowledgement
The EVOKE teacher is built on LingBot-World. The
vae / text encoder / tokenizer / scheduler in models/evoke-base come from the released
Helios base, which traces them to Wan. The optional
Director UI LightTAE decoder adapter is adapted from
ModelTC/LightX2V under Apache-2.0.
🔒 License
Apache-2.0, see LICENSE. Vendored third-party code keeps its own license and provenance under
evoke/third_party/*.
✏️ Citation
@misc{evoke2026,
  title         = {Alaya-EVOKE: From Linear-Scaling Supervision to Endless World},
  author        = {Yuanyang Yin and Gongxuan Wang and Yifan Zhan and Chuanhao Li and Kaipeng Zhang and Feng Zhao},
  year          = {2026},
  eprint        = {2608.13546},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CV},
  url           = {https://arxiv.org/abs/2608.13546},
}
Evoke (AlayaLab/Evoke)
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.
Searching Database…
Choose a tag and it will appear here. With no tags selected, all catalog projects are shown.
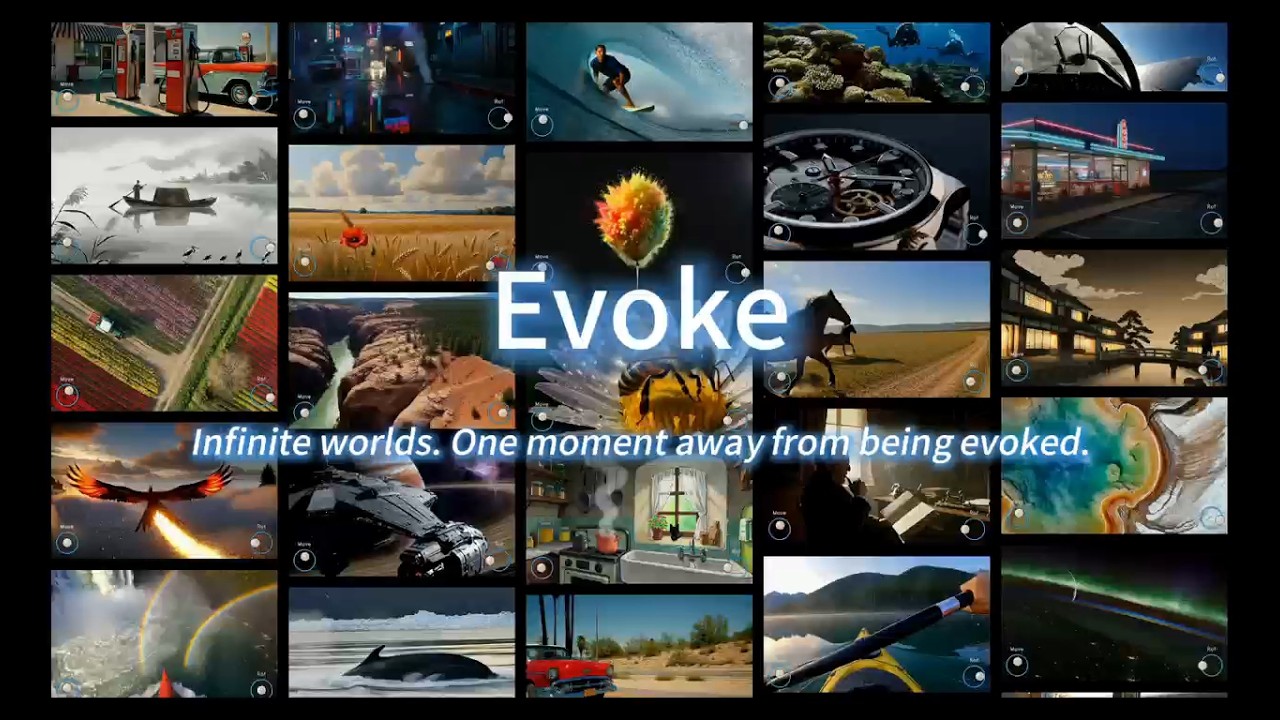
Что это?EVOKE — исследовательская реализация интерактивной «модели мира», генерирующей бесконечное управляемое видео: трёхшаговая система без CFG, которая помнит, где уже побывала, позволяет менять направление прямо во время генерации и показывает лучший в классе результат на долгосрочном бенчмарке WBench.
Это готовое приложение или исследовательская кодовая база, которую нужно запускать самому?Это исследовательская кодовая база со скриптами обучения и инференса, плюс локальный веб-интерфейс Director для одной GPU, который вы запускаете сами после настройки весов и окружения — хостируемой/онлайн-версии нет.
Как запустить веб-интерфейс Director?После установки зафиксированного окружения и скачивания релизных весов модели в models/ убедитесь, что ffmpeg доступен в PATH, затем запустите лаунчер интерфейса из корня репозитория; по умолчанию открывается демо «Meteor» из шести чанков.
Что должно быть установлено перед попыткой?Python 3.10 с CUDA 12.4, зафиксированные torch 2.4 / deepspeed 0.14.5 / flash-attn, dev-форк diffusers, которого нет на PyPI (нужно сначала установить вручную), и бинарник ffmpeg в PATH для скрипта визуализации.
Есть ли подводные камни установки, о которых стоит знать?Да: diffusers нужно установить из зафиксированного dev-форка до любых импортов, а два опциональных бэкенда глубины (ViGeo, Depth-Anything-3) распространяются под более строгой лицензией CC-BY-NC-4.0, несмотря на лицензию Apache-2.0 у репозитория, — проверьте это перед коммерческим использованием.
Нужна ли конкретная GPU для запуска?Оно собрано и протестировано на одной H200, выдавая 1.5 с видео 384x640 каждые 2.11 с; интерфейс Director работает на одной GPU, но минимальные требования или поддержка меньших GPU не заявлены.
Что такое WBench?WBench — бенчмарк долгосрочных интерактивных моделей мира, на котором EVOKE заявляет лучшие результаты, оставаясь при этом конкурентоспособным на VBench-Long и VBench-2.0.
Что такое «банк состояния мира», который всё упоминается?Это внешнее индексированное по камере облако точек, хранящее геометрию сцены вне контекста модели: записи поступают от монокулярной модели глубины, разворачивающей каждый новый чанк, а при чтениях извлекаются только совместно видимые точки, нужные для текущего вида, поэтому память растёт вместе со сценой, а не с длиной сессии.
Можно менять промпт, пока видео генерируется?Да — кондиционирование по чанкам позволяет задать новый промпт прямо посреди генерации, например переключившись со спокойной тундры на вспыхивающее над головой северное сияние, без обрыва или перезапуска генерации.
Почему она отказывается от classifier-free guidance (CFG)?Дистиллированная студенческая модель работает всего за 3 шага и без CFG, делая один прямой проход за шаг вместо двух, что даёт скорость малошаговой генерации без обычного для такого режима потолка качества.






 EVOKE — исследовательская реализация интерактивной «модели мира», генерирующей бесконечное управляемое видео: трёхшаговая система без CFG, которая помнит, где уже побывала, позволяет менять направление прямо во время генерации и показывает лучший в классе результат на долгосрочном бенчмарке WBench.