
UniForge3D README

项目的 README,来自 github.com/xibushu/UniForge3D。合并为一个 markdown 文件:README.md。

UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space

Wenjue Chen1,*, Wenyue Chen1,2,*, Heliang Zheng2, Rongfei Jia2, Yuan Liu3,†, Meng Li1,†

1 Peking University   2 Math Magic   3 The Hong Kong University of Science and Technology

* Equal contribution. † Corresponding authors.

Project Page Hugging Face Paper

UniForge3D teaser

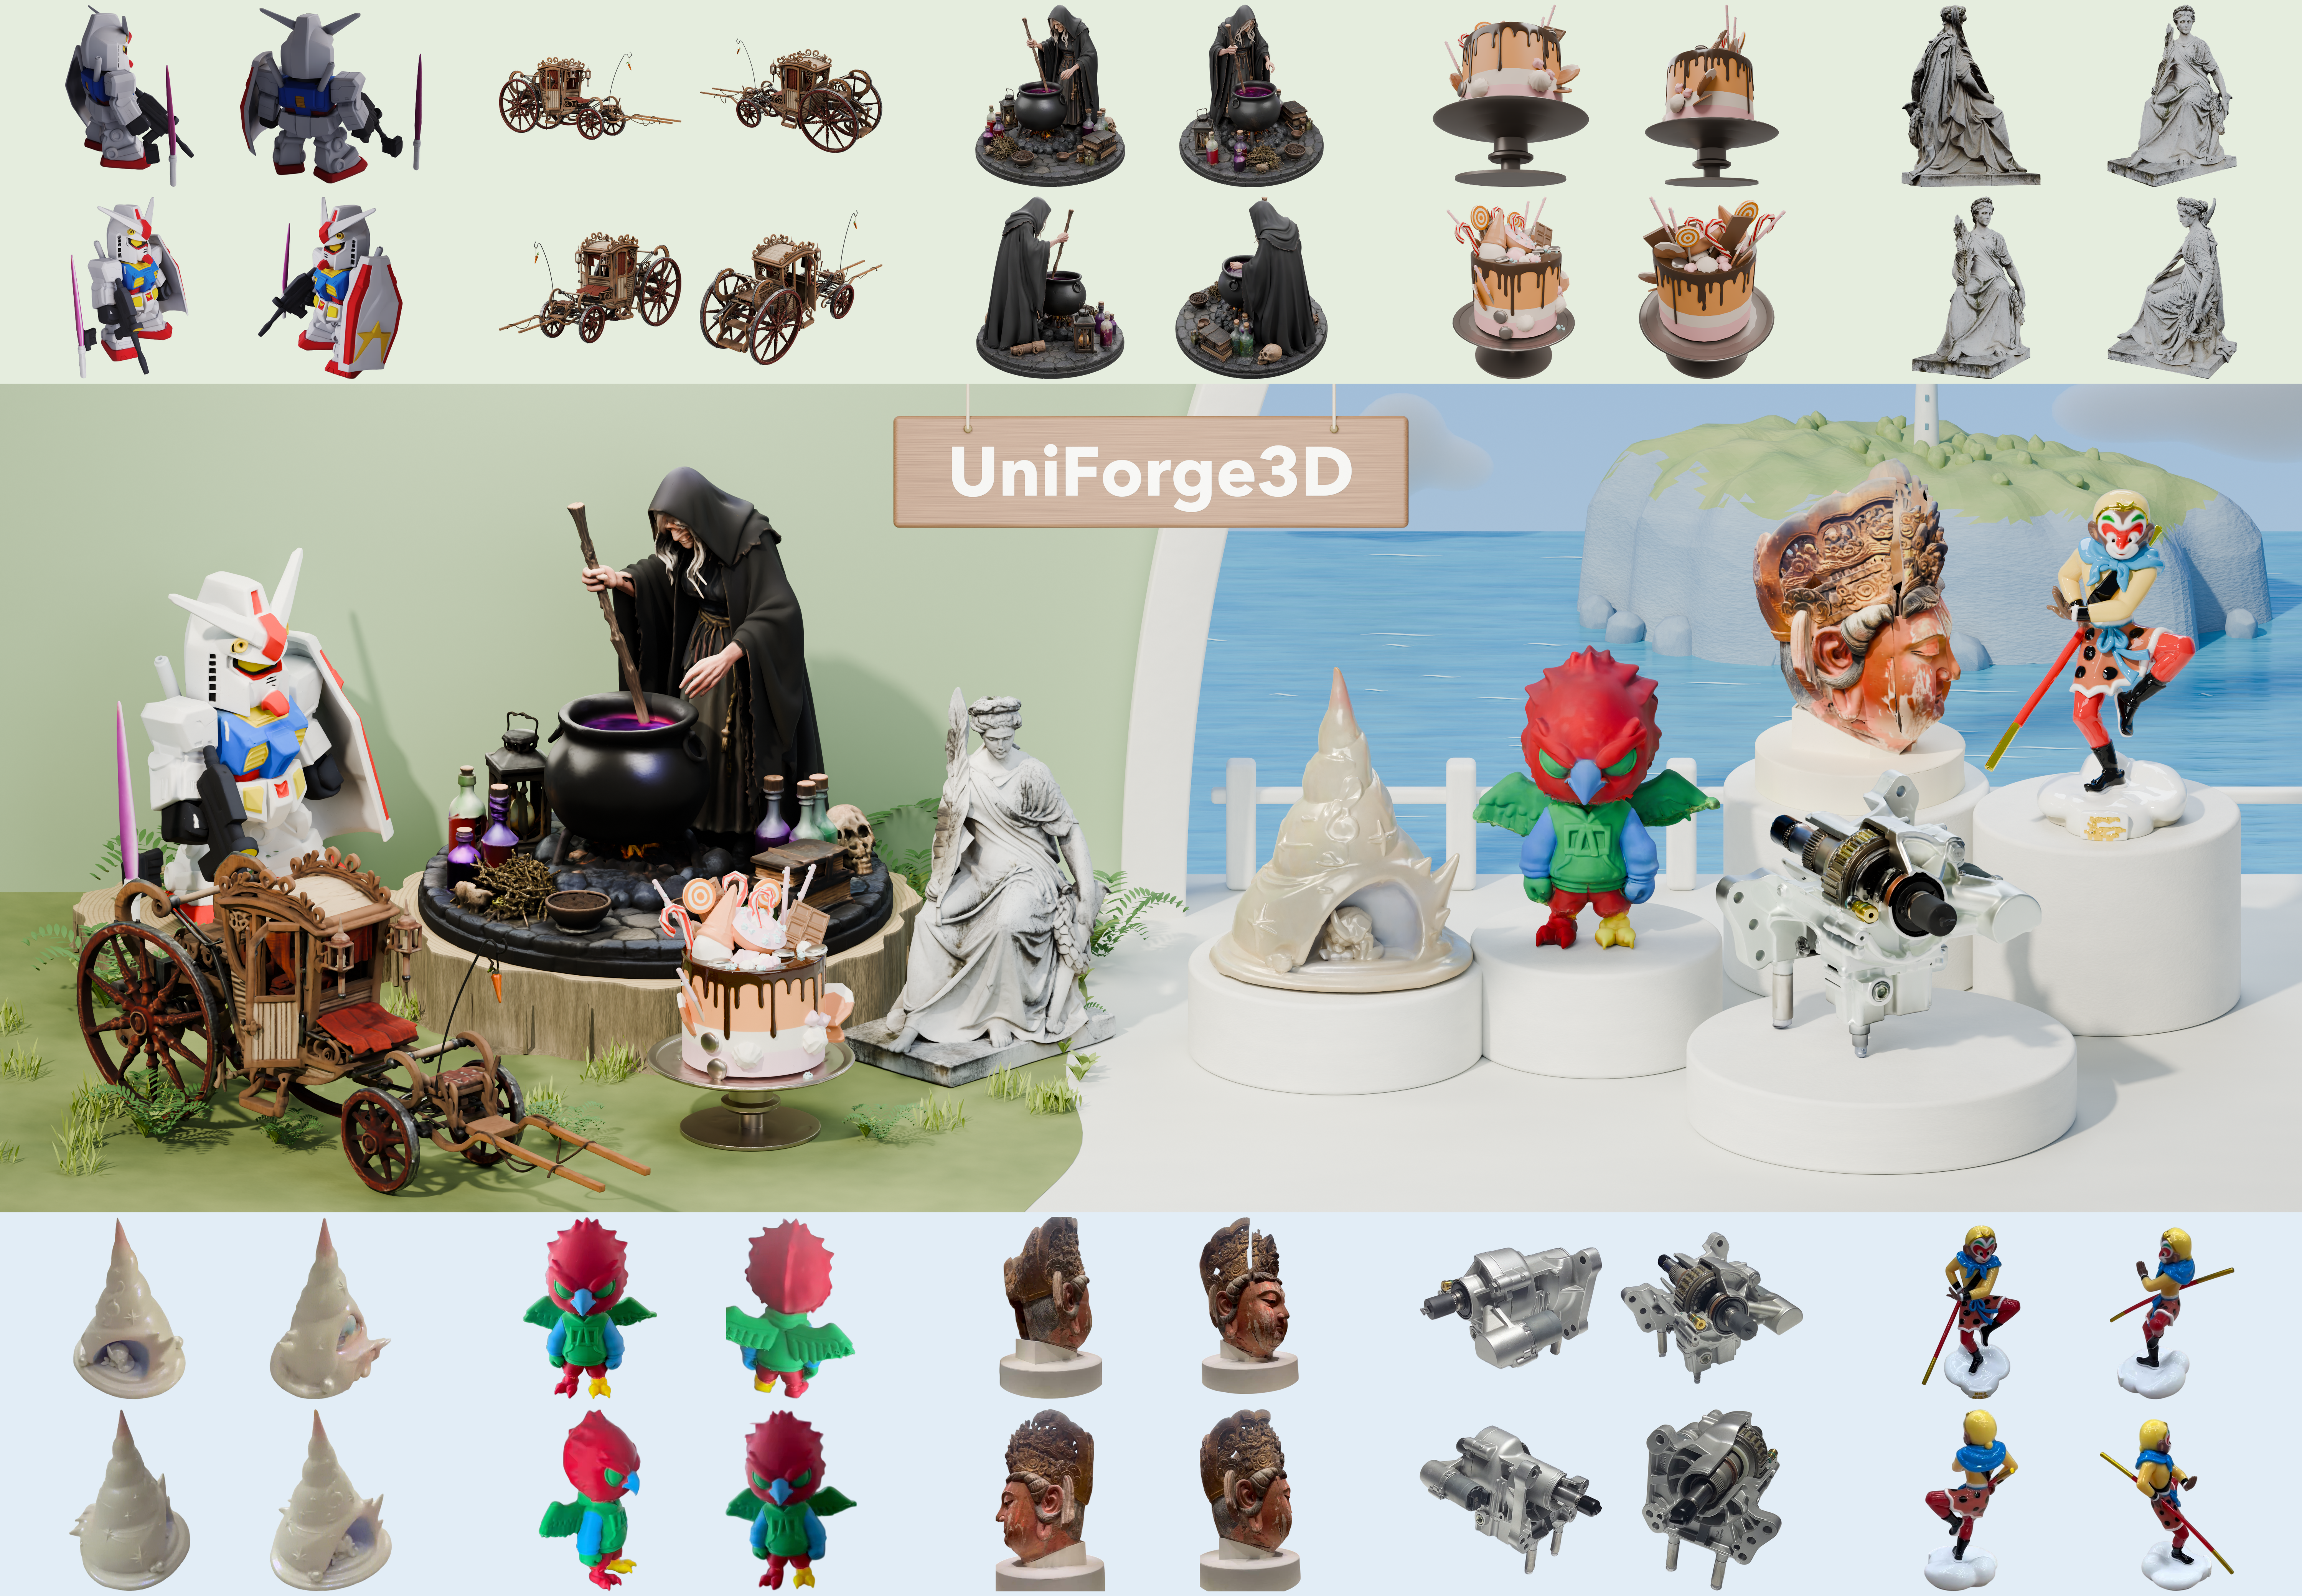
UniForge3D generates complete 3D assets from sparse, unposed multi-view images. It jointly models reconstruction and generation in a shared anchor-guided space, then uses structure-guided view selection to preserve observed details.

Installation

git clone https://github.com/xibushu/UniForge3D.git
cd UniForge3D
bash setup.sh
conda activate uniforge3d

Inference

Place the views of each object directly in a separate folder under assets/:

assets/
├── case01/
│   ├── 001.png
│   ├── 002.png
│   ├── 003.png
│   └── 004.png
└── case02/
    └── ...

Run all cases using the pretrained model:

python infer.py

Acknowledgements

Our code is based on these wonderful works:

License

Original UniForge3D source code is released under the MIT License. Third-party code, dependencies, and model weights retain their respective licenses and are not relicensed under this project's MIT License. Please refer to their original license files and notices for applicable terms.

The MIT License for our source code does not apply to the released model weights. In particular, our VGGT-derived checkpoints were initialized from facebook/VGGT-1B and remain subject to CC BY-NC 4.0. The default background remover, BRIA RMBG-2.0, requires separate authorization for commercial use.

Citation

If you find UniForge3D useful in your research, please cite our paper:

@article{chen2026uniforge3d,
  title   = {UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space},
  author  = {Chen, Wenjue and Chen, Wenyue and Zheng, Heliang and Jia, Rongfei and Liu, Yuan and Li, Meng},
  journal = {arXiv preprint arXiv:2610.15357},
  year    = {2026}
}

UniForge3D (xibushu/UniForge3D)

正在搜索数据库…

这是什么?UniForge3D 是一篇研究论文的官方代码发布版本,它能够从稀疏、无位姿的多视角图片生成完整的 3D 资产,并在共享的锚点引导空间中同时对重建和生成进行建模。
这是可以直接使用的应用程序还是研究代码库?这是一个配合学术论文发布的研究代码库,你需要通过运行推理脚本来调用预训练模型,它并不是打包好的应用程序或图形界面。
我该如何用自己的图片运行推理?将每个物体的多视角图片直接放入 assets/ 目录下的独立文件夹中,然后使用提供的预训练模型运行所有案例。
它的运行需要依赖其他模型吗?需要。该实现基于 TRELLIS.2 和 VGGT 构建,因此这两个组件是底层流程的一部分,尽管文档中没有列出确切的软件包依赖。
我需要同一物体的多张照片吗,还是一张图片就够了?它需要同一物体的多个(稀疏)视角,而不是单张照片;不过这些视角无需预先标定位姿,因为模型就是为处理无位姿的多视角输入而设计的。
“结构引导的视角选择”具体是做什么的?这是一种机制,用于选择信任哪些生成的视角,使最终的 3D 资产能够保留输入图片中真正观察到的精细细节,而不是仅仅依靠锚点空间凭空臆造这些细节。
这项研究是谁完成的?论文列出的作者来自北京大学、Math Magic 以及香港科技大学。
它与常见的多视角三维重建工具有什么不同?UniForge3D 并不把重建和生成当作两个独立的阶段,而是将二者统一在同一个共享的锚点引导表示中,因此它既能重建已观察到的几何结构,也能在同一空间中生成 3D 资产缺失的部分。
作者
xibushu
大小
71.6 MB
星标
481
更新
提交Oct 17
时长
1个月
提交 · 90 天