🤲 Meet MINT — making world-space egocentric motion data more accessible
Egocentric motion reconstruction estimates how a camera moves and how both hands are positioned, oriented, and moving in the surrounding space. Producing this data often requires capture hardware with built-in tracking or a pipeline that combines calibration, monocular depth, SLAM, hand reconstruction, and trajectory cleanup. Deploying multiple models, managing errors between stages, and working with different licenses add to the cost of producing data at scale.
MINT takes ordinary egocentric RGB video and uses a unified model to predict camera and two-hand motion, then composes them into world-space outputs. The Web Viewer supports inference and inspection on an NVIDIA GPU with at least 24 GB of VRAM. Long videos are processed in windows, with camera trajectories joined across windows.
- Unified camera and hand modeling. A shared spatiotemporal representation feeds four prediction heads: camera extrinsics, field of view, camera-frame MANO, and per-frame hand presence. Explicit rigid composition produces world-space hand motion without depth maps or point clouds at inference.
- Structured pipeline amortization. EgoPipeline generates structured camera and hand supervision offline. MINT learns from these labels, reducing the need to deploy multiple independent models when processing new videos.
- Open models and research resources. The release provides model weights, training and inference code, structured non-video annotations covering 1,021 hours of egocentric footage, and reference code for EgoPipeline orchestration, cleaning, and export. Source videos and separately licensed assets must be obtained under their own access terms.
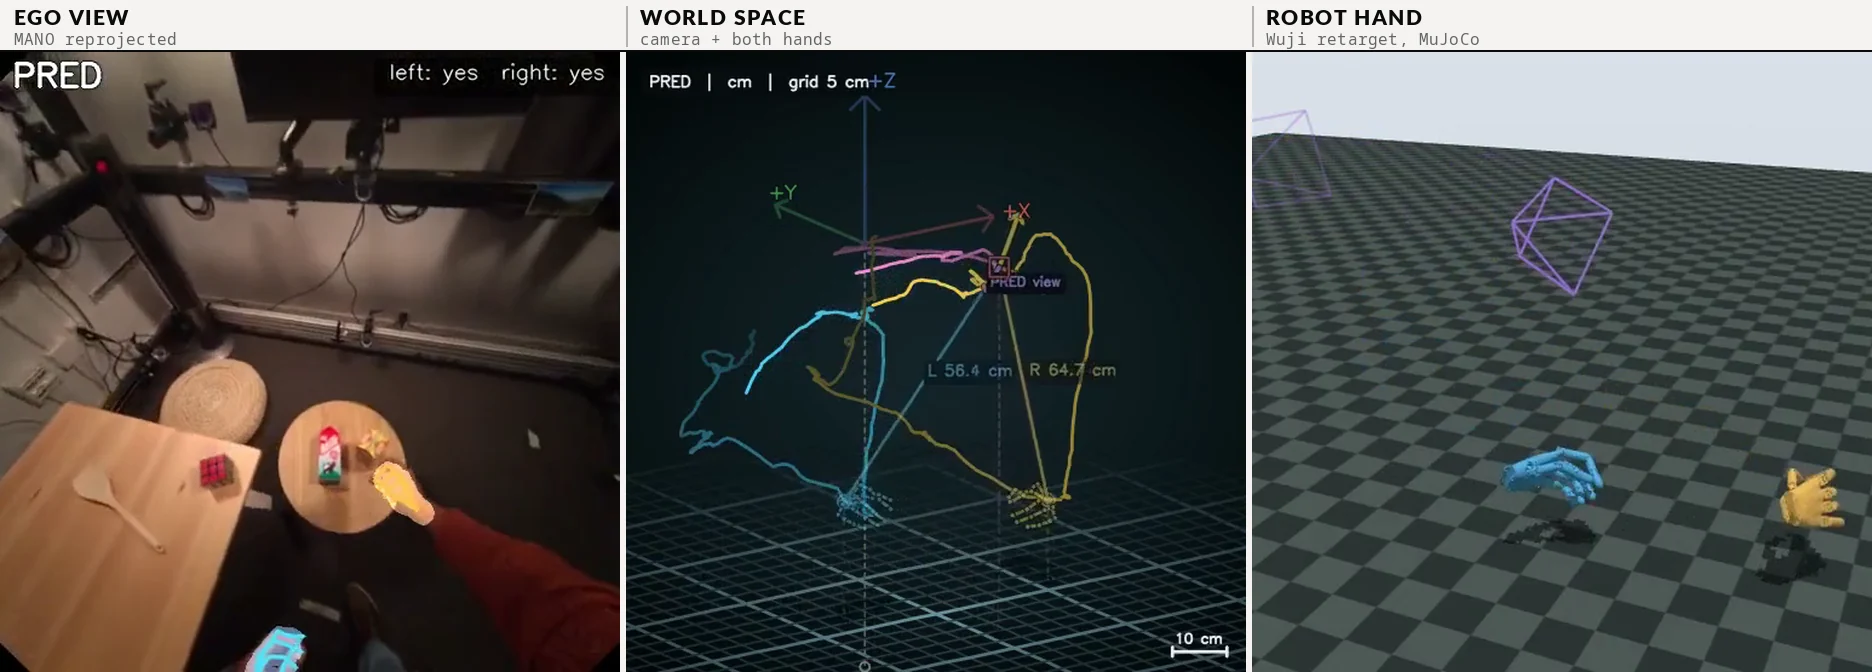
Same frames, same overlay renderer. Left: the input. Middle: the conventional ego pipeline, whose output is pseudo-label, not ground truth. Right: MINT predictions.
📑 Table of Contents
Collapse
📋 Release status
|
Item |
Where |
| ✅ |
MINT checkpoint, 1.139B total parameters |
Hugging Face · ModelScope |
| ✅ |
Inference, Web Viewer, training code |
this repository |
| ✅ |
1,021-hour structured egocentric dataset (non-video portion) |
Hugging Face · ModelScope |
| ✅ |
Benchmark implementation and CLI, integrated into the Viewer |
eval/model_effect/benchmark/ |
| ✅ |
EgoPipeline orchestration, cleaning and LeRobot export reference |
ego_pipeline/ |
| ✅ |
Video normalisation and hand-filtering scripts |
ego_pipeline/preprocessing/ |
| ✅ |
Wuji hand URDF/MJCF/STL and retargeting |
eval/simulate/wuji-retargeting/ |
| ✅ |
Zero-shot HOT3D / ARCTIC result table (paper Table 1) |
Camera-frame bimanual reconstruction |
| ⏳ |
Scale-corrected camera trajectories — the released dataset's trajectories are scale-enlarged |
The current ones are usable for pretraining, not for metric evaluation. Cause in Public Ego pretraining data |
| ❌ |
License-restricted pipeline adaptations (adapted HaWoR source, weights, MANO) |
cannot be redistributed; see THIRD_PARTY_NOTICES.md |
🚀 Quick Start: Web Viewer
The Web Viewer is the primary MINT entry point. It lets you select a checkpoint, load the MINT model, run inference on a LeRobot episode or an egocentric MP4 video, and inspect GT/prediction overlays, camera trajectories, hand motion, frame metrics, and benchmark results in one interface.
Hardware requirement: MINT model inference requires an NVIDIA GPU with at least 24 GB of VRAM.
Install the inference environment and download the public MINT model. The Viewer also requires the separately licensed MANO hand models. Create an account on the official MANO website, accept the MANO license, and download the MANO release before running the asset check below.
git clone https://github.com/wuji-technology/wuji-ego-mint.git
cd wuji-ego-mint
bash scripts/create_env.sh inference
conda activate mint-inference
bash scripts/download_assets.sh

# Copy the MANO files from the downloaded release into the project.
mkdir -p assets/mano/mano_right assets/mano/mano_left
cp /path/to/MANO_RIGHT.pkl assets/mano/mano_right/MANO_RIGHT.pkl
cp /path/to/MANO_LEFT.pkl assets/mano/mano_left/MANO_LEFT.pkl

python -m mint doctor --profile inference
python -m mint viewer
Model and asset locations
Place the models and assets used by Quick Start at the paths below. scripts/download_assets.sh downloads the public MINT checkpoint automatically; MANO must be downloaded from its official website and copied manually.
| Model or asset |
Download source |
Path in this repository |
Notes |
| MINT checkpoint |
ModelScope or Hugging Face |
checkpoints/model.safetensors |
The download script places and verifies it automatically; use the same path for a manual download. |
| MANO left- and right-hand models |
MANO website |
assets/mano/mano_right/MANO_RIGHT.pkl
assets/mano/mano_left/MANO_LEFT.pkl |
Registration and acceptance of the MANO License are required. |
| LingBot-Map pretrained backbone |
LingBot-Map |
assets/models/lingbot-map.pt |
Optional; download only when required by the selected configuration. |
| Wuji Hand URDF, MJCF, and STL |
Included in this repository |
eval/simulate/wuji-retargeting/wuji_retargeting/wuji-description/hand/body/ |
No additional download is required. |
Using the Viewer
The Viewer automatically opens http://127.0.0.1:8011 in the default browser. Then:
- In Model and Sample, keep
checkpoints/model.safetensors or select another compatible checkpoint.
- Click Load Model and wait until the model status is ready.
- Select a LeRobot episode or an egocentric MP4 video, then choose the camera-inference, hand-window, and geometry settings.
- Click Start Inference.
- Inspect the synchronized GT/Pred 2D view, fixed-world and camera-frame 3D panels, per-frame values, losses, exports, and optional benchmark tools. The export menu can either compose the selected views into one grid MP4 or download 2D, fixed-world 3D, MuJoCo, and Wuji Hand GT/Pred renders as eight individual MP4 files in a ZIP.
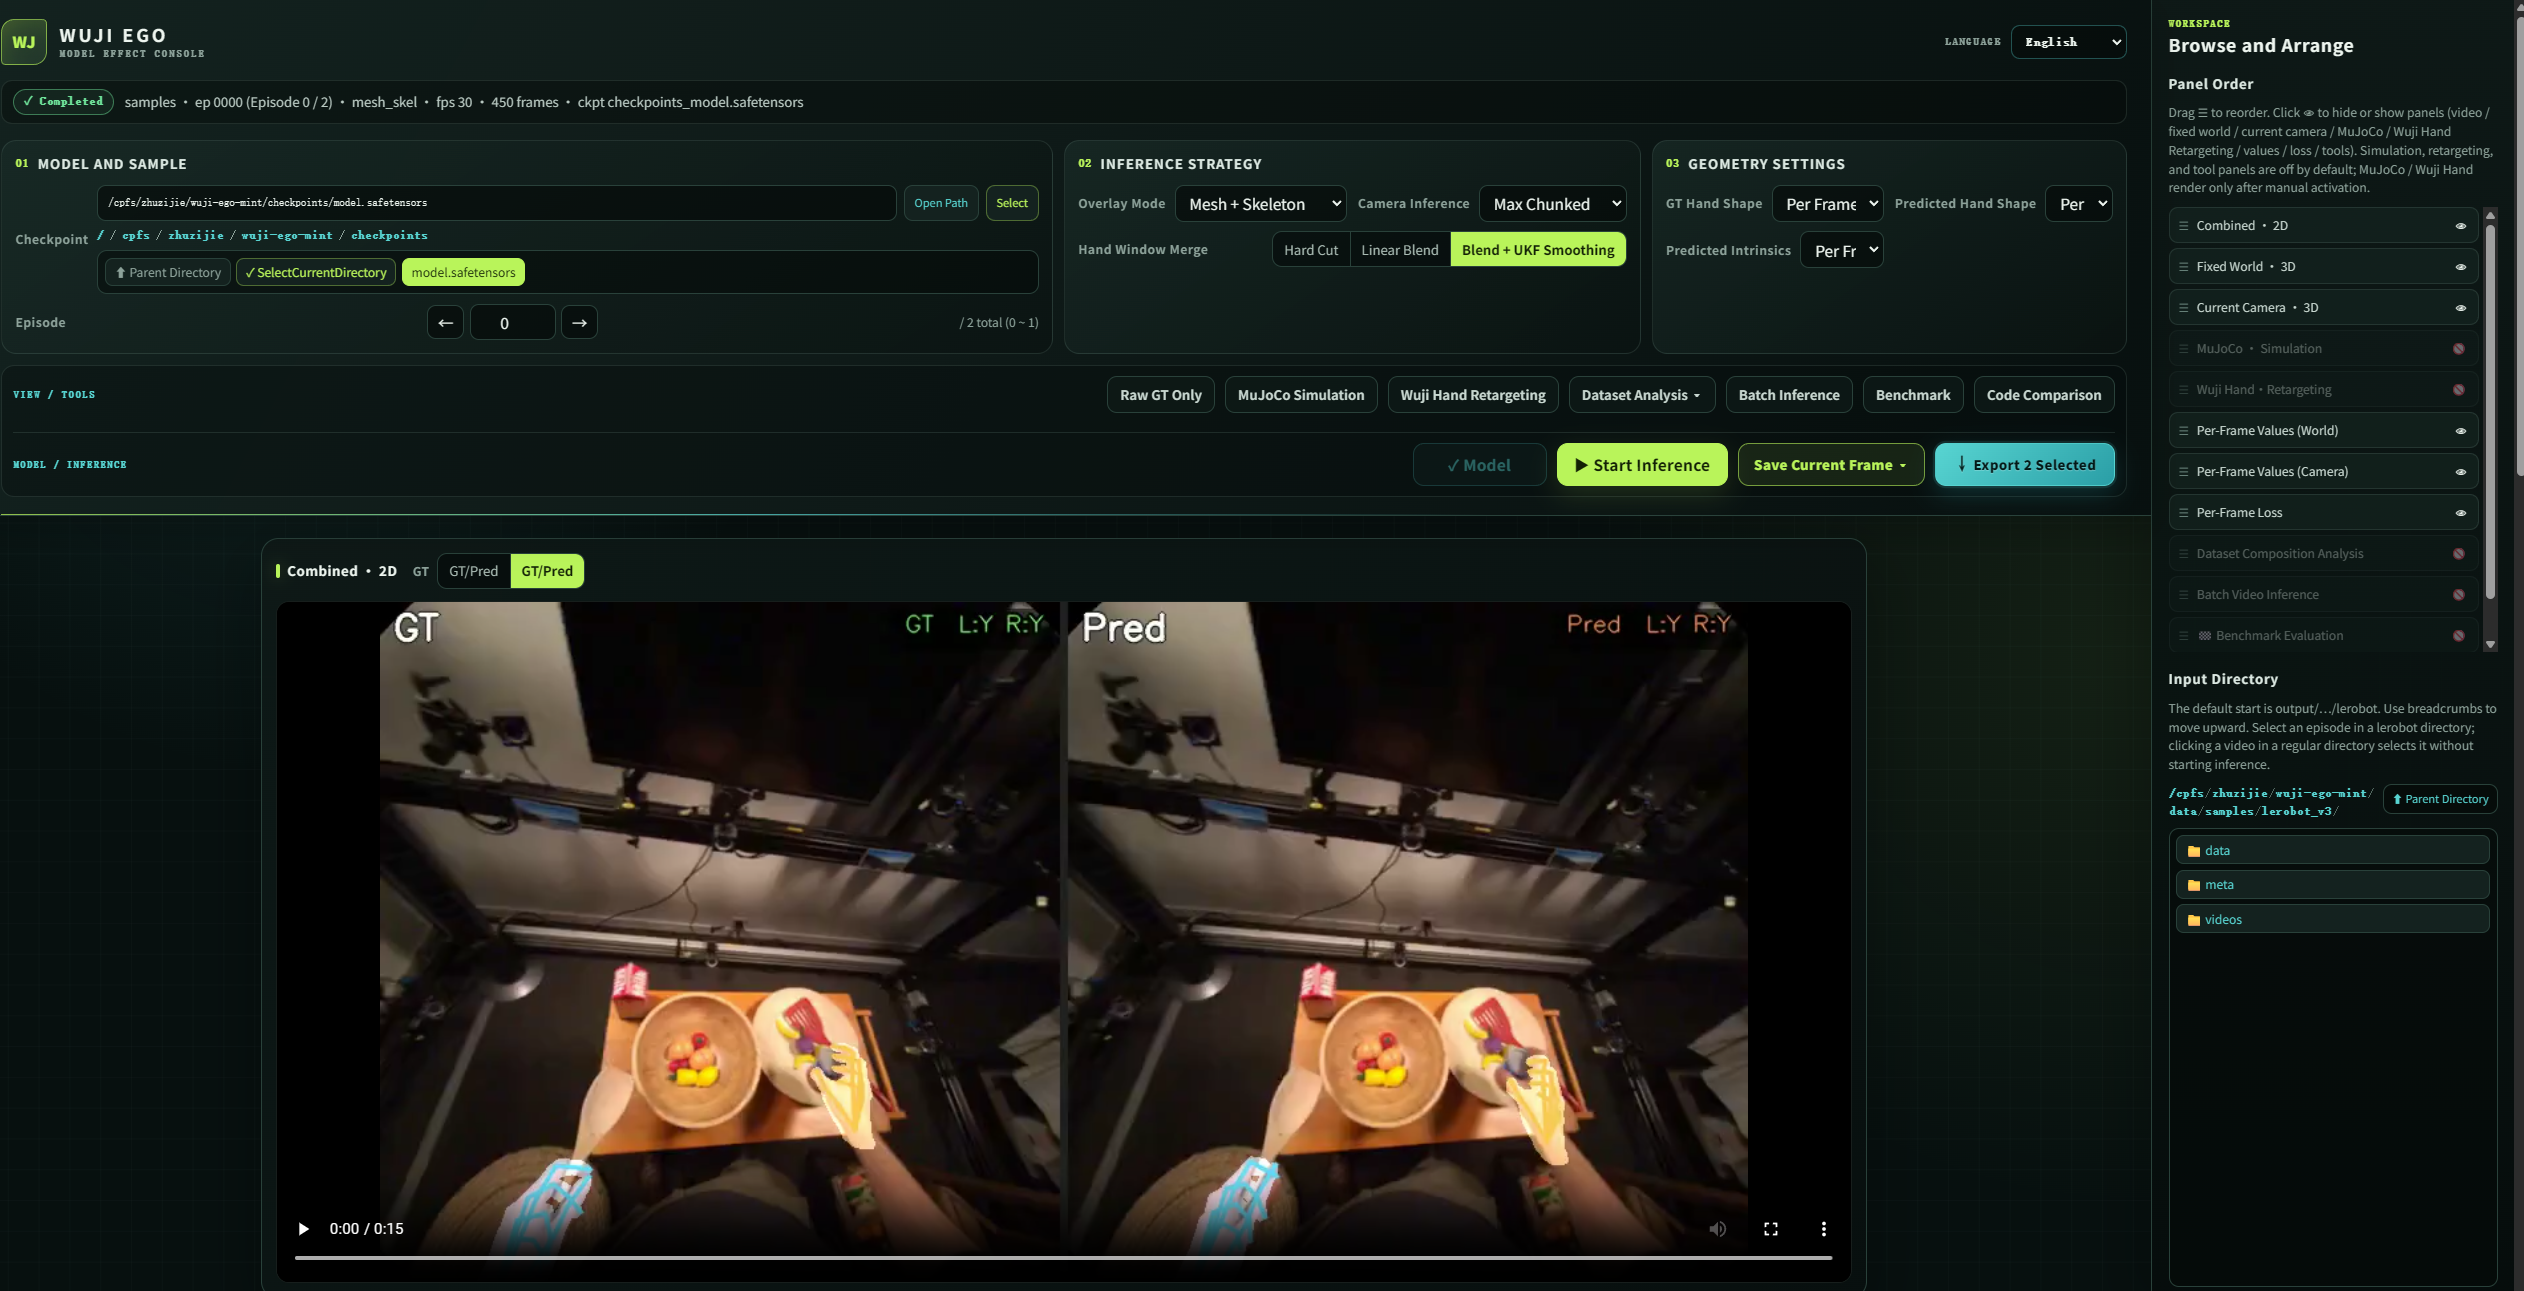
Testing your own video needs no configuration change and no command line: browse to the video in the input-directory picker at the bottom right of the Viewer and click it. Supported formats are .mp4, .mov, .avi, .mkv and .webm. A plain video carries no ground truth, so the Viewer runs in prediction-only mode — GT panels, the GT/Pred side-by-side layout and the loss readout are hidden, and everything shown is prediction.
All visualization operations live in the Viewer panel — there is no separate command-line visualization step. See Installation for installation, CUDA, MANO, and offline deployment details.
🧠 How MINT works
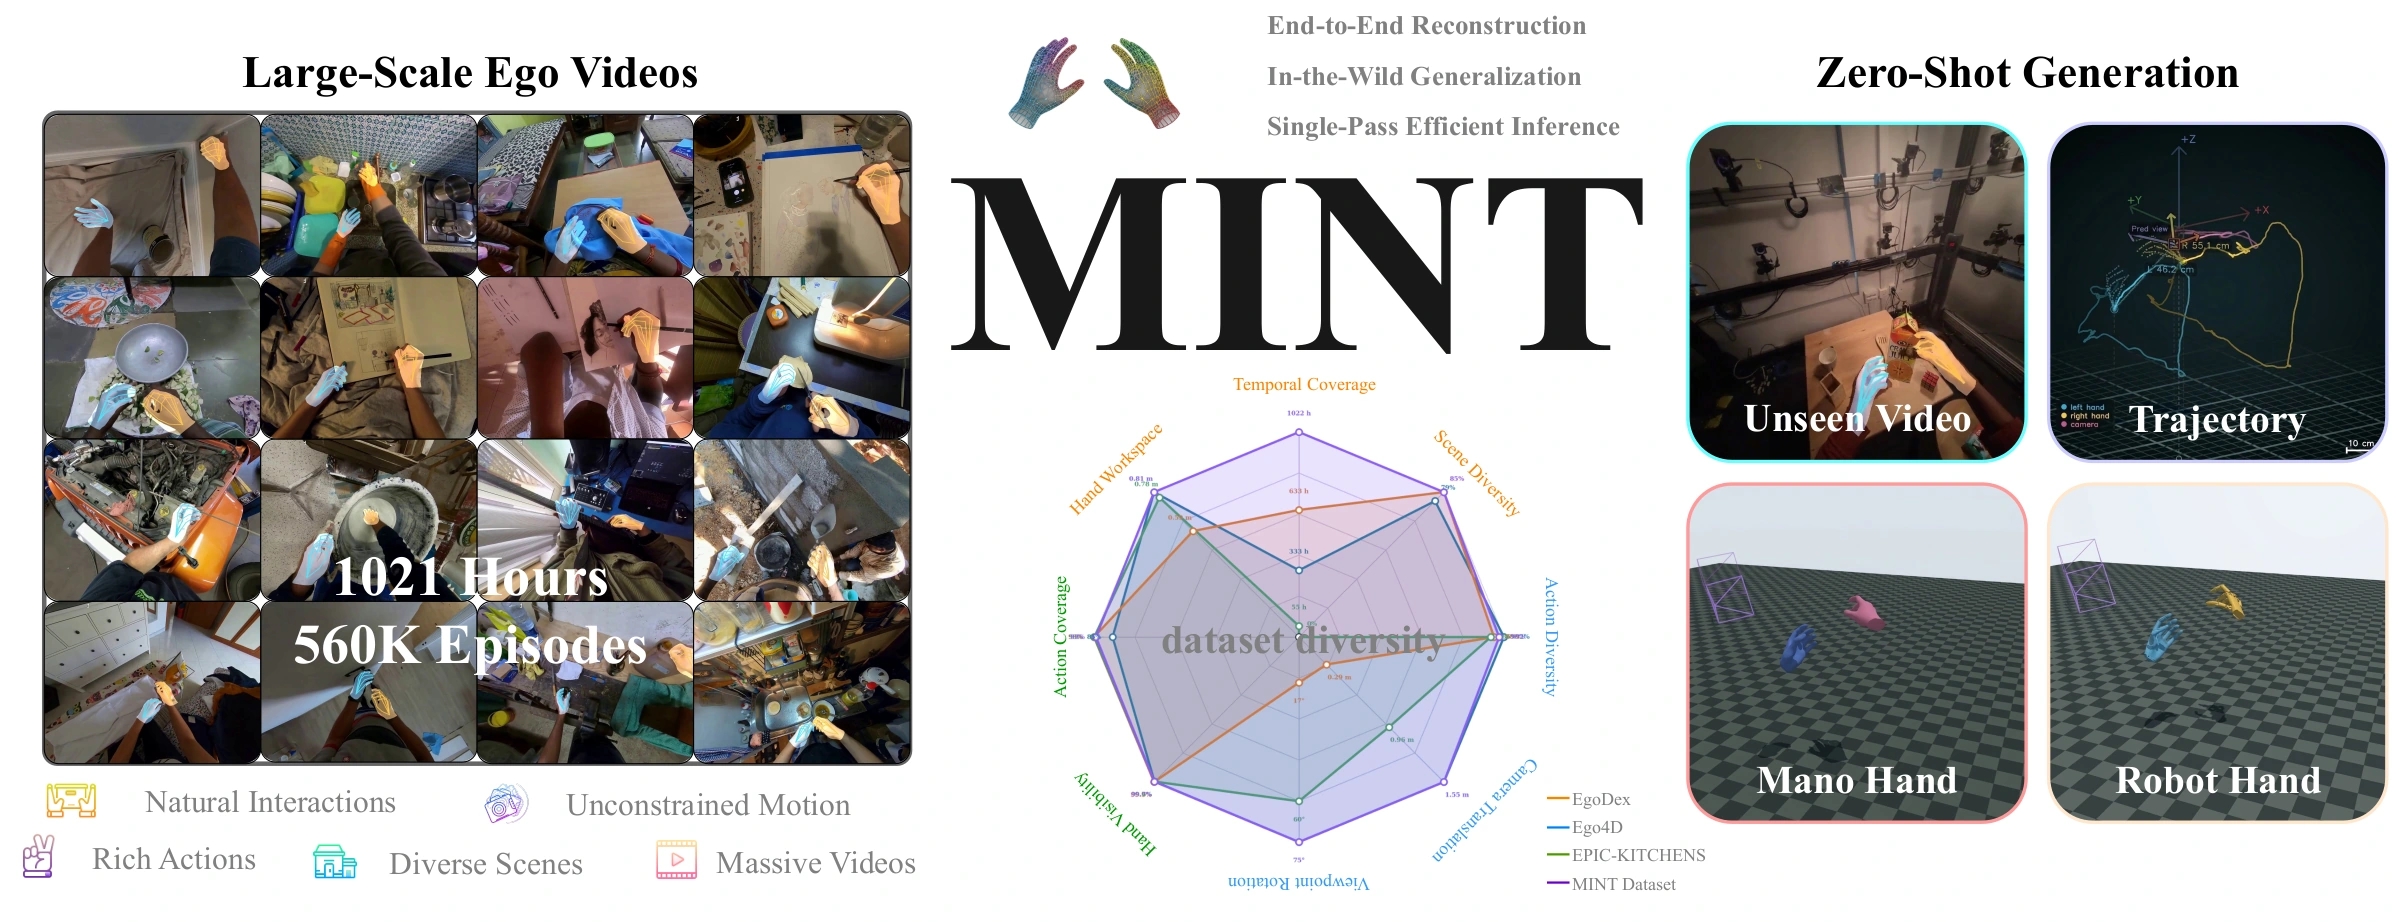
Left: the released supervision — 1,021 h, 560 K episodes of egocentric video, and how its diversity compares with EgoDex, Ego4D and EPIC-KITCHENS. Right: MINT predictions for an unseen video — world-space camera and hand trajectory, MANO hands, and the same motion retargeted to a robot hand.
Within each window, four prediction heads share a spatiotemporal representation. Explicit rigid transforms compose the predicted camera and hand states into world-space motion.
Model at a glance
|
|
| Input |
monocular egocentric RGB, 378 × 518 frames, patch 14, 999 tokens per frame |
| Backbone |
LingBot-Map / GCT — 24 alternating frame-wise / global attention pairs |
| Clip |
T = 32 frames, re-anchored to the window's own first frame |
| Total parameters |
1.139B |
| Head 01 |
camera extrinsics, 7-D [t, q], iterative causal refinement, 4 steps |
| Head 02 |
field of view, f_h, f_w, independent temporal branch, Softplus |
| Head 03 |
camera-frame hand MANO, 218-D, left + right, component queries, 2 refinements |
| Head 04 |
per-frame hand presence, logits L / R, patch cross-attention |
| Composition |
x_c = R x_w + t, p_w = Rᵀ(p_c − t), Q_w = Rᵀ Q_c — explicit and differentiable |
| At inference |
no depth map, no point cloud, no dense 3D intermediate |
| Training |
Stage 1 pretrain on 1,021 h of pipeline supervision → Stage 2 correct the camera trajectory on a small high-precision trajectory set, with the geometric encoder and the hand, presence and field-of-view modules frozen |
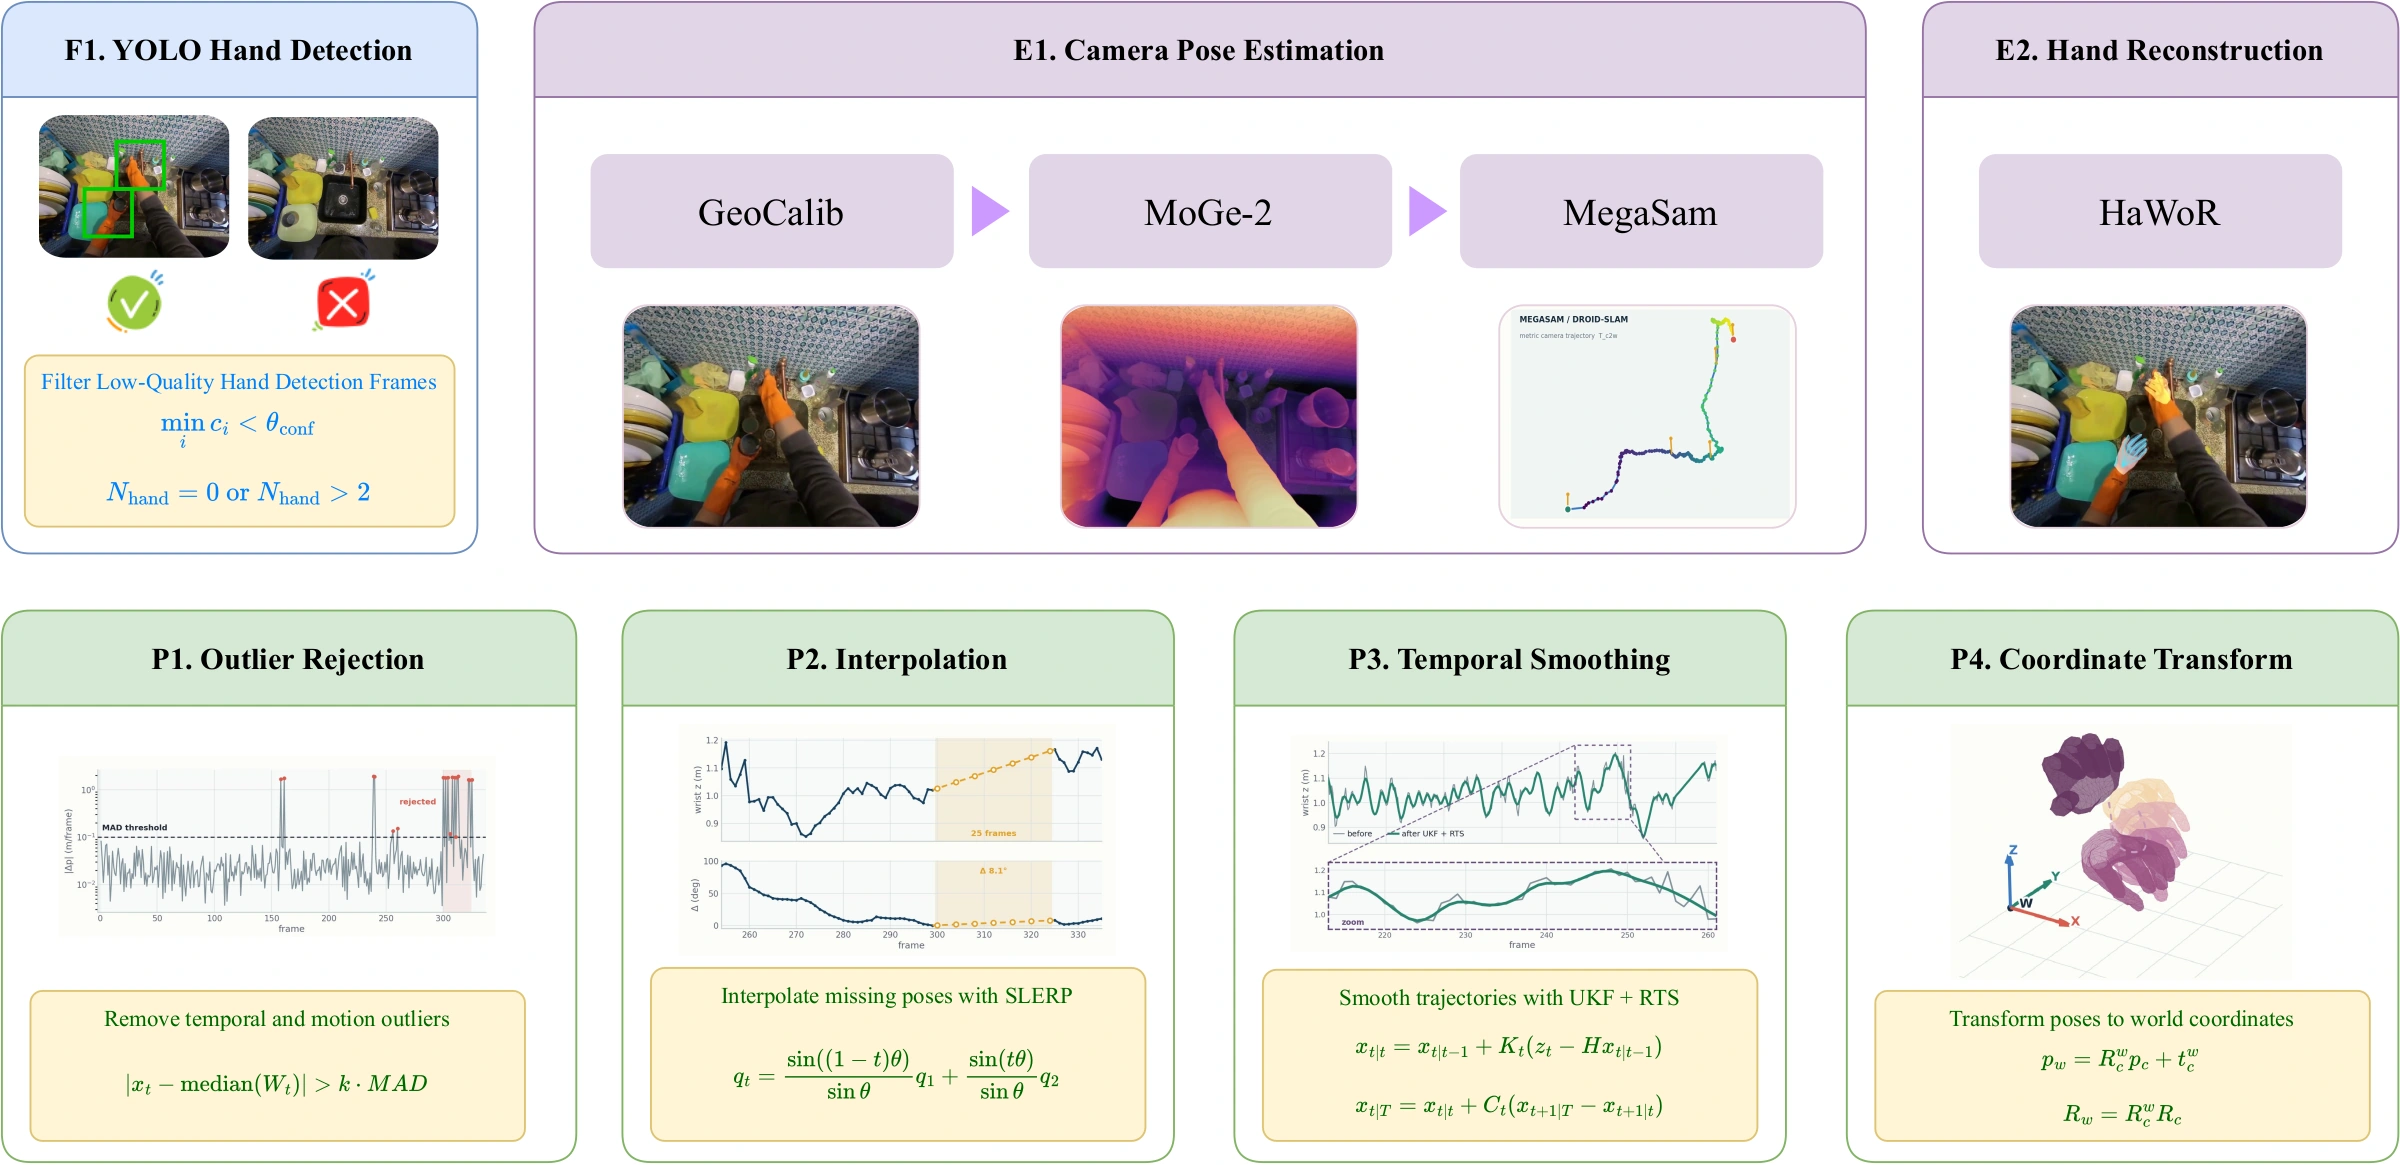
EgoPipeline stages.
Where the supervision comes from
EgoPipeline is our open-source implementation of the conventional multi-stage route, and it stays in the project as the supervision generator, not as the deployment path:
| Stage |
Component |
Produces |
| 00 |
preprocessing and filtering |
normalise fps/resolution/duration; cut out stretches with no hands or more than two; validate metadata, split overlapping clips |
| 01 |
GeoCalib |
camera intrinsics |
| 02 |
MoGe-2 |
monocular depth |
| 03 |
MegaSaM / DROID-SLAM |
metric camera track |
| 04 |
HaWoR |
camera-frame MANO |
| 05 |
cleanup |
outlier rejection, gap interpolation, temporal filters |
Its output is pseudo-label, not ground truth — that distinction is load-bearing everywhere in this repository.
Why one model instead of the chain
A multi-stage pipeline typically combines several visual models and post-processing components. Different models may extract features from the same video independently, intermediate estimates can propagate errors across stages, and deployment requires coordinating multiple dependencies and interfaces. MINT shares a spatiotemporal representation across camera and hand prediction, reducing repeated feature extraction and integration work when processing new videos.
Inference throughput measured on RTX 4090D, at 512 × 384 and 30 fps under identical conditions; time is the marginal cost per frame in steady state. Speedups are against VITRA, which EgoPipeline, this project's data pipeline, was built by optimising. The three methods are points on one line of work: VITRA to start, EgoPipeline as the pipeline-level optimisation, MINT replacing the chain with a single model.
| Method |
One GPU |
Four GPUs |
Time ↓
ms/frame |
fps ↑ |
Speedup ↑
vs VITRA |
Time ↓
ms/frame |
fps ↑ |
Speedup ↑
vs VITRA |
| VITRA | 1260.0 | 0.8 | — | 283.3 | 3.5 | — |
| EgoPipeline | — | — | — | 83.4 | 12.0 | 3.4× |
| MINT | 72.4 | 13.8 | 17.4× | 22.7 | 44.1 | 12.5× |
Against the conventional pipeline, MINT is 17.4× faster on one GPU (VITRA 1260.0 → 72.4 ms/frame) and 12.5× on four (283.3 → 22.7 ms/frame). The four-GPU columns show where that comes from: optimising the conventional pipeline itself (EgoPipeline) accounts for 3.4× (283.3 → 83.4), and the unified model takes it to 22.7.
EgoPipeline is itself distributed-optimised (Ray multi-GPU operators, persistent workers, asynchronous CPU stages): rewriting its serial single-GPU execution as a scheduled 4-GPU worker pool took 179.0 s down to 63.9 s per 270 frames, 2.8× internal to the pipeline. That is whole-clip wall-clock including decode and write-out, a different accounting from the steady-state cost above; the two do not multiply.
📊 What MINT is measured on
Camera-frame bimanual reconstruction
Result sources: MINT and MINT + UKF use the latest coverage-aware evaluation; all other results are taken from the ViDiHand evaluation.
Following the coverage-aware protocol in Sec. V-A of the paper, missed hands receive the error of a canonical MANO placeholder instead of being excluded from pose evaluation. FAcc, recall, and F1 measure detection; MPJPE-p and PA-MPJPE-p measure articulated pose; GO-p and CT-p measure wrist orientation and hand placement; Jitter measures temporal smoothness.
MINT is evaluated on HOT3D and ARCTIC in a zero-shot setting; neither dataset is used in either of its two training stages. MINT + UKF uses the same model weights as MINT and applies an unscented Kalman filter (UKF) at inference time, with all other evaluation settings held constant. Bold marks the best displayed value in each column; ties are all bolded.
| Method |
Detection |
3D pose |
Orient. & pos. |
Temporal |
| FAcc ↑ |
Recall ↑ |
F1 ↑ |
MPJPE-p ↓
mm |
PA-MPJPE-p ↓
mm |
GO-p ↓
deg |
CT-p ↓
m |
Jitter ↓
mm/frame² |
| ARCTIC |
|---|
| InterWild | 0.878 | 0.943 | 0.959 | 30.82 | 15.95 | 25.39 | 0.097 | 46.58 |
| HaMeR | 0.875 | 0.943 | 0.957 | 29.20 | 14.60 | 24.91 | 0.095 | 18.28 |
| Hamba | 0.833 | 0.912 | 0.941 | 31.23 | 17.17 | 27.82 | 0.110 | 15.36 |
| WildHands | 0.879 | 0.946 | 0.960 | 25.70 | 13.94 |



 MINT is a unified deep learning model that takes ordinary egocentric RGB video and directly predicts world-space camera motion and two-hand (MANO) motion, replacing the usual calibration + depth + SLAM + hand-reconstruction pipeline with a single pass.