


Что это такое?
 VibeVoice — это семейство открытых голосовых ИИ-моделей от Microsoft, охватывающее синтез речи и распознавание речи: длинный многоголосый TTS, потоковый TTS в реальном времени и ASR, созданный для записей длиной в час.
Так это приложение, которое я устанавливаю, или набор моделей?Это исследовательский фреймворк плюс веса моделей на Hugging Face, а не готовое приложение: VibeVoice-ASR-7B, ASR-Streaming, ASR-BitNet (CPU), TTS-1.5B и Realtime-0.5B — у каждого есть документация и быстрый способ попробовать.
Это исследовательский фреймворк плюс веса моделей на Hugging Face, а не готовое приложение: VibeVoice-ASR-7B, ASR-Streaming, ASR-BitNet (CPU), TTS-1.5B и Realtime-0.5B — у каждого есть документация и быстрый способ попробовать.Где я могу реально попробовать эти модели?У ASR-7B есть браузерный Playground, а у Realtime-0.5B — демо на Colab; в своём коде модель ASR загружается напрямую через библиотеку Hugging Face Transformers.
У ASR-7B есть браузерный Playground, а у Realtime-0.5B — демо на Colab; в своём коде модель ASR загружается напрямую через библиотеку Hugging Face Transformers.Насколько надёжный звук она выдаёт?В README предупреждают, что результаты всё ещё могут быть неожиданными, предвзятыми или неточными, и что модели наследуют ошибки своей базовой модели — Qwen2.5 1.5b в этом релизе.
В README предупреждают, что результаты всё ещё могут быть неожиданными, предвзятыми или неточными, и что модели наследуют ошибки своей базовой модели — Qwen2.5 1.5b в этом релизе.Могу ли я раздавать модели со своего сервера?Да, поддерживается инференс через vLLM для скорости, включая рецепт для раздачи потокового распознавания, но в репозитории нет Dockerfile, так что развёртывание — на вашей совести.
Да, поддерживается инференс через vLLM для скорости, включая рецепт для раздачи потокового распознавания, но в репозитории нет Dockerfile, так что развёртывание — на вашей совести.Могу ли я использовать это в своём продукте?Вот в чём подвох: репозиторий на GitHub распространяется по лицензии MIT, но в README сказано, что модели предназначены только для исследований и разработки, и коммерческое использование без дополнительного тестирования не рекомендуется.
Вот в чём подвох: репозиторий на GitHub распространяется по лицензии MIT, но в README сказано, что модели предназначены только для исследований и разработки, и коммерческое использование без дополнительного тестирования не рекомендуется.Заработает ли это на моей машине без GPU?Требования к железу нигде не расписаны, но есть отдельный чекпоинт, ориентированный на CPU, — VibeVoice-ASR-BitNet, а его быстрый способ попробовать — проект VibeASR.cpp, так что для распознавания речи GPU строго не обязателен.
Требования к железу нигде не расписаны, но есть отдельный чекпоинт, ориентированный на CPU, — VibeVoice-ASR-BitNet, а его быстрый способ попробовать — проект VibeASR.cpp, так что для распознавания речи GPU строго не обязателен.Почему часть с синтезом речи отключена?Microsoft удалила код VibeVoice-TTS из репозитория в сентябре 2025 года, обнаружив злоупотребления, противоречащие её принципам ответственного ИИ. Веса TTS-1.5B всё ещё перечислены, но вариант быстрого пробования помечен как Disabled.
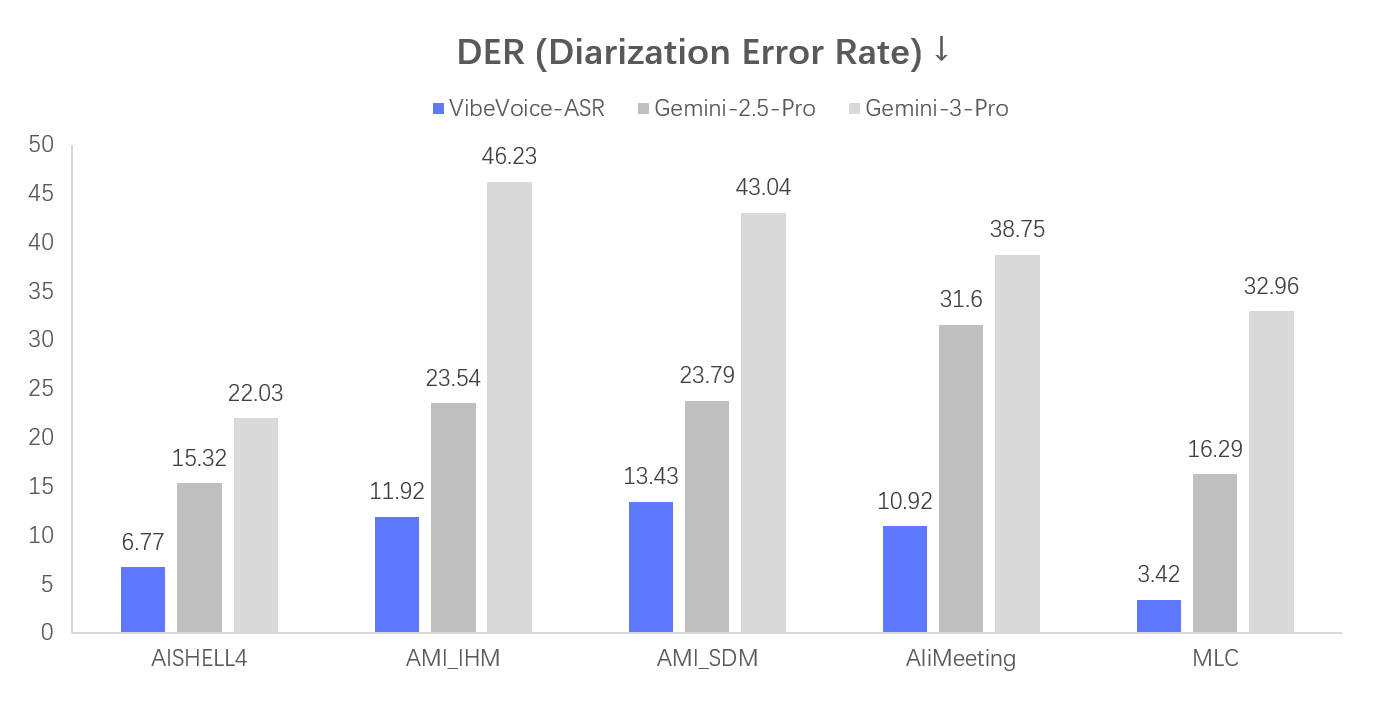
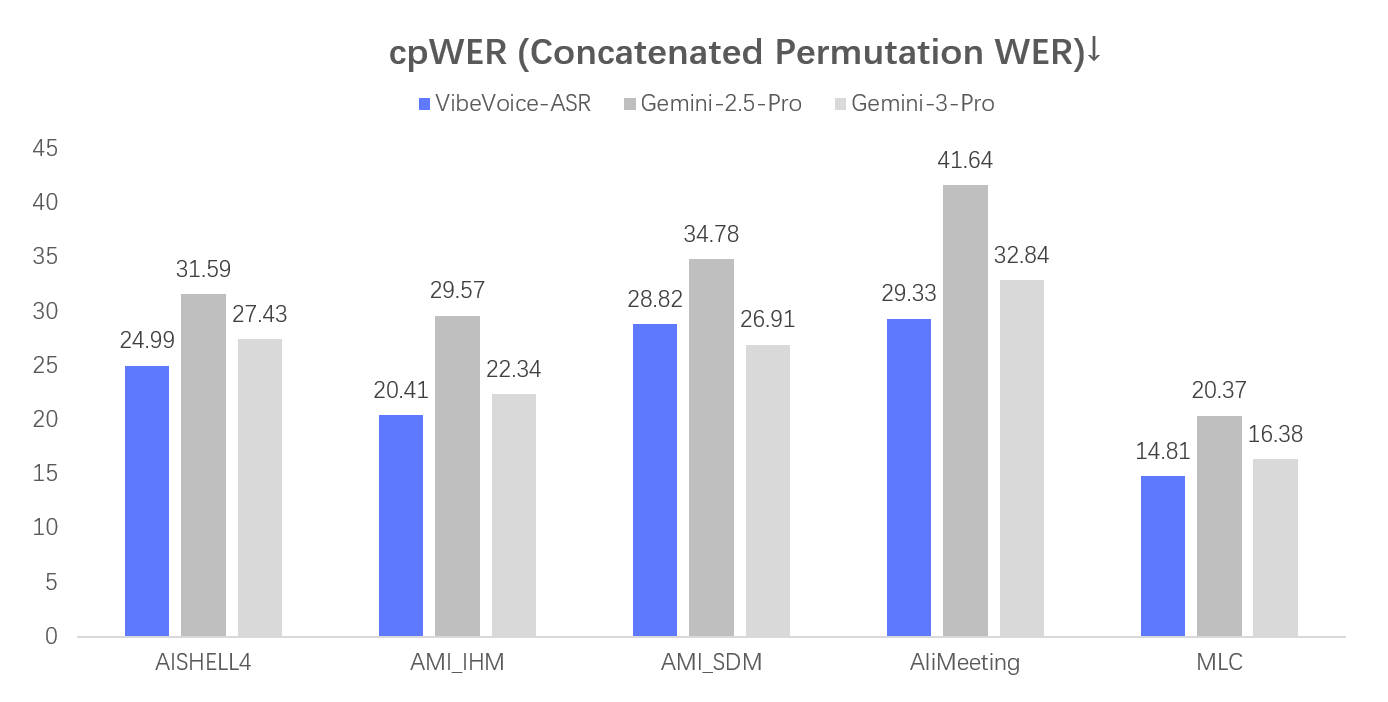
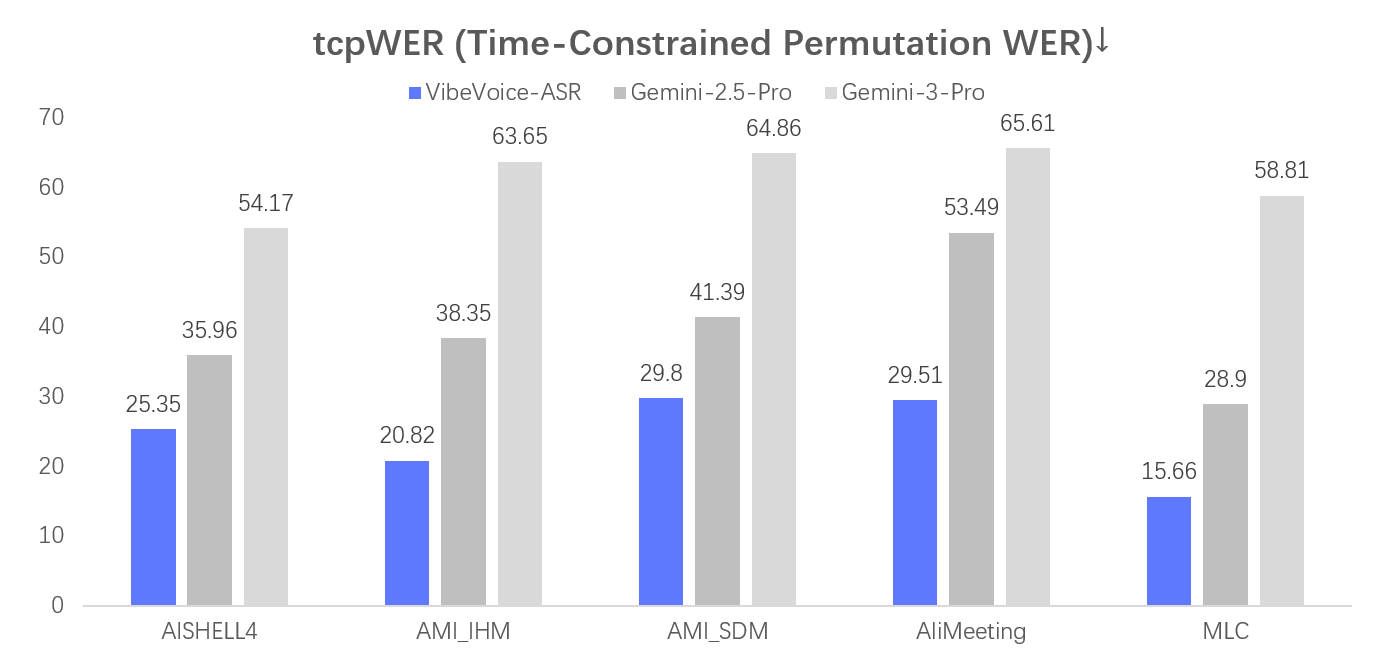
Microsoft удалила код VibeVoice-TTS из репозитория в сентябре 2025 года, обнаружив злоупотребления, противоречащие её принципам ответственного ИИ. Веса TTS-1.5B всё ещё перечислены, но вариант быстрого пробования помечен как Disabled.Что модель ASR умеет делать с длинной записью?Она обрабатывает до 60 минут непрерывного аудио за один проход и одновременно выполняет распознавание, диаризацию и проставление меток времени — то есть возвращает, кто, что и когда сказал. Пользовательские хотворды помогают повысить точность на именах и отраслевых терминах.
Она обрабатывает до 60 минут непрерывного аудио за один проход и одновременно выполняет распознавание, диаризацию и проставление меток времени — то есть возвращает, кто, что и когда сказал. Пользовательские хотворды помогают повысить точность на именах и отраслевых терминах.Какие языки она поддерживает?VibeVoice-ASR изначально многоязычна — более 50 языков. Экспериментальные дикторы Realtime-0.5B добавляют девять языков (DE, FR, IT, JP, KR, NL, PL, PT, ES) плюс 11 различных стилей английских голосов.
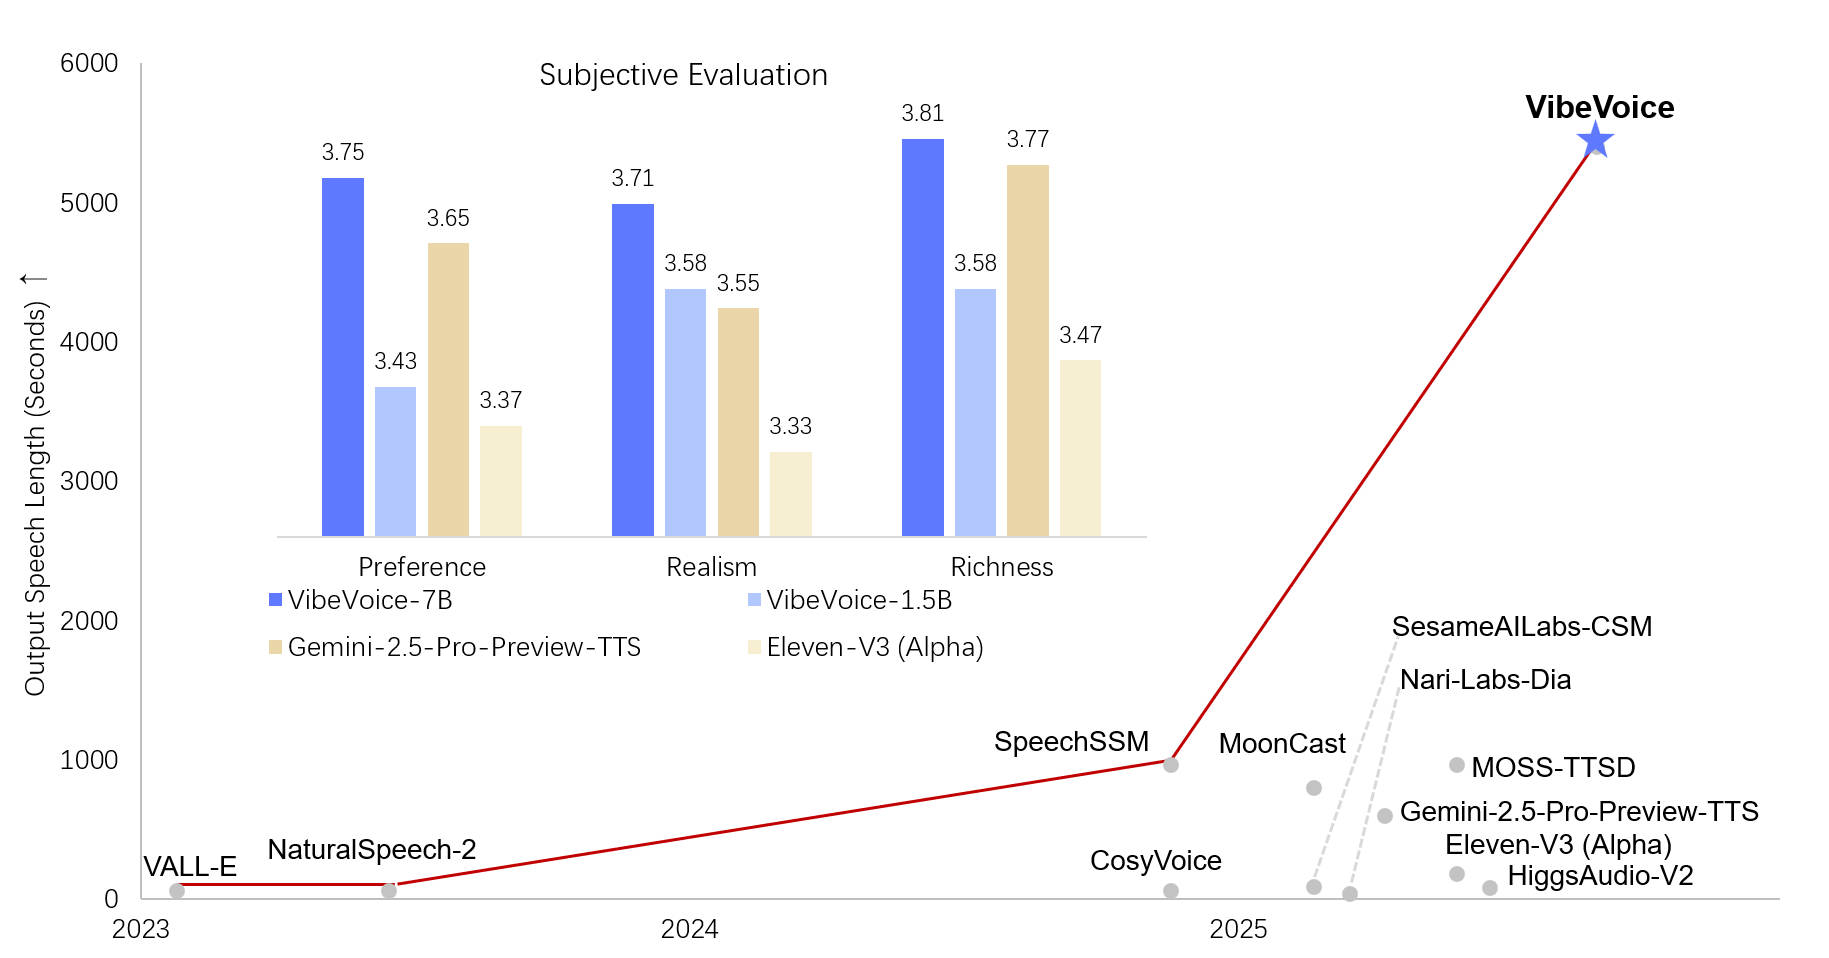
VibeVoice-ASR изначально многоязычна — более 50 языков. Экспериментальные дикторы Realtime-0.5B добавляют девять языков (DE, FR, IT, JP, KR, NL, PL, PT, ES) плюс 11 различных стилей английских голосов.Что такое VibeVoice-Realtime-0.5B?Это лёгкая модель TTS реального времени на 0,5 млрд параметров: примерно 300 миллисекунд до первого слышимого звука, потоковый текстовый ввод и генерация длинных записей около 10 минут. Есть демо на Colab в один клик.
Это лёгкая модель TTS реального времени на 0,5 млрд параметров: примерно 300 миллисекунд до первого слышимого звука, потоковый текстовый ввод и генерация длинных записей около 10 минут. Есть демо на Colab в один клик.What are similar projects?Speech, MOSS-TTS, FunASR, WhisperLiveKit, speechbrain, ChatTTS, faster-whisper, seamless_communication
Speech, MOSS-TTS, FunASR, WhisperLiveKit, speechbrain, ChatTTS, faster-whisper, seamless_communicationWhich topics is it in?diarization, voice-ai, asr, mit-license, diffusion, transcription, speech-to-text, transformers, speech-recognition, tts, vllm, text-to-speech
diarization, voice-ai, asr, mit-license, diffusion, transcription, speech-to-text, transformers, speech-recognition, tts, vllm, text-to-speech