Colossal-AI
Instantly Run Colossal-AI on Enterprise-Grade GPUs
Skip the setup. Access a powerful, pre-configured Colossal-AI environment on HPC-AI Cloud.
Train your models and scale your AI workload in one click!
- NVIDIA Blackwell B200s: Experience the next generation of AI performance (See Benchmarks). Now available on cloud from $2.47/hr.
- Cost-Effective H200 Cluster: Get premier performance with on-demand rental from just $1.99/hr.
Get Started Now & Claim Your Free Credits →
Instant Access Top Open Models at Half the Cost
Skip the hassle. Access powerful, long-context LLMs seamlessly through HPC-AI Model APIs.
Build your AI agents, chatbots, and RAG applications with HPC-AI Model APIs!
Latest & Greatest Models: Experience state-of-the-art performance with Kimi 2.5, MiniMax 2.5, and GLM 5.1. Perfect for massive 2M+ context windows and complex coding tasks.
Unbeatable Pricing: Stop overpaying for API endpoints. Get premier inference speed at up to 50% cheaper than OpenRouter.
Get Started Now & Claim Your $4 Free Credits →
Colossal-AI Benchmark
To see how these performance gains translate to real-world applications, we conducted a large language model training benchmark using Colossal-AI on Llama-like models. The tests were run on both 8-card and 16-card configurations for 7B and 70B models, respectively.
| GPU |
GPUs |
Model Size |
Parallelism |
Batch Size per DP |
Seqlen |
Throughput |
TFLOPS/GPU |
Peak Mem(MiB) |
| H200 |
8 |
7B |
zero2(dp8) |
36 |
4096 |
17.13 samp/s |
534.18 |
119040.02 |
| H200 |
16 |
70B |
zero2 |
48 |
4096 |
3.27 samp/s |
469.1 |
150032.23 |
| B200 |
8 |
7B |
zero1(dp2)+tp2+pp4 |
128 |
4096 |
25.83 samp/s |
805.69 |
100119.77 |
| H200 |
16 |
70B |
zero1(dp2)+tp2+pp4 |
128 |
4096 |
5.66 samp/s |
811.79 |
100072.02 |
The results from the Colossal-AI benchmark provide the most practical insight. For the 7B model on 8 cards, the B200 achieved a 50% higher throughput and a significant increase in TFLOPS per GPU. For the 70B model on 16 cards, the B200 again demonstrated a clear advantage, with over 70% higher throughput and TFLOPS per GPU. These numbers show that the B200's performance gains translate directly to faster training times for large-scale models.
Latest News
Table of Contents
Why Colossal-AI
Prof. James Demmel (UC Berkeley): Colossal-AI makes training AI models efficient, easy, and scalable.
(back to top)
Features
Colossal-AI provides a collection of parallel components for you. We aim to support you to write your
distributed deep learning models just like how you write your model on your laptop. We provide user-friendly tools to kickstart
distributed training and inference in a few lines.
(back to top)
Colossal-AI in the Real World
Open-Sora
Open-Sora:Revealing Complete Model Parameters, Training Details, and Everything for Sora-like Video Generation Models
[code]
[blog]
[Model weights]
[Demo]
[GPU Cloud Playground]
[OpenSora Image]
(back to top)
Colossal-LLaMA-2
[GPU Cloud Playground]
[LLaMA3 Image]
| Model |
Backbone |
Tokens Consumed |
MMLU (5-shot) |
CMMLU (5-shot) |
AGIEval (5-shot) |
GAOKAO (0-shot) |
CEval (5-shot) |
| Baichuan-7B |
- |
1.2T |
42.32 (42.30) |
44.53 (44.02) |
38.72 |
36.74 |
42.80 |
| Baichuan-13B-Base |
- |
1.4T |
50.51 (51.60) |
55.73 (55.30) |
47.20 |
51.41 |
53.60 |
| Baichuan2-7B-Base |
- |
2.6T |
46.97 (54.16) |
57.67 (57.07) |
45.76 |
52.60 |
54.00 |
| Baichuan2-13B-Base |
- |
2.6T |
54.84 (59.17) |
62.62 (61.97) |
52.08 |
58.25 |
58.10 |
| ChatGLM-6B |
- |
1.0T |
39.67 (40.63) |
41.17 (-) |
40.10 |
36.53 |
38.90 |
| ChatGLM2-6B |
- |
1.4T |
44.74 (45.46) |
49.40 (-) |
46.36 |
45.49 |
51.70 |
| InternLM-7B |
- |
1.6T |
46.70 (51.00) |
52.00 (-) |
44.77 |
61.64 |
52.80 |
| Qwen-7B |
- |
2.2T |
54.29 (56.70) |
56.03 (58.80) |
52.47 |
56.42 |
59.60 |
| Llama-2-7B |
- |
2.0T |
44.47 (45.30) |
32.97 (-) |
32.60 |
25.46 |
- |
| Linly-AI/Chinese-LLaMA-2-7B-hf |
Llama-2-7B |
1.0T |
37.43 |
29.92 |
32.00 |
27.57 |
- |
| wenge-research/yayi-7b-llama2 |
Llama-2-7B |
- |
38.56 |
31.52 |
30.99 |
25.95 |
- |
| ziqingyang/chinese-llama-2-7b |
Llama-2-7B |
- |
33.86 |
34.69 |
34.52 |
25.18 |
34.2 |
| TigerResearch/tigerbot-7b-base |
Llama-2-7B |
0.3T |
43.73 |
42.04 |
37.64 |
30.61 |
- |
| LinkSoul/Chinese-Llama-2-7b |
Llama-2-7B |
- |
48.41 |
38.31 |
38.45 |
27.72 |
- |
| FlagAlpha/Atom-7B |
Llama-2-7B |
0.1T |
49.96 |
41.10 |
39.83 |
33.00 |
- |
| IDEA-CCNL/Ziya-LLaMA-13B-v1.1 |
Llama-13B |
0.11T |
50.25 |
40.99 |
40.04 |
30.54 |
- |
| Colossal-LLaMA-2-7b-base |
Llama-2-7B |
0.0085T |
53.06 |
49.89 |
51.48 |
58.82 |
50.2 |
| Colossal-LLaMA-2-13b-base |
Llama-2-13B |
0.025T |
56.42 |
61.80 |
54.69 |
69.53 |
60.3 |
ColossalChat
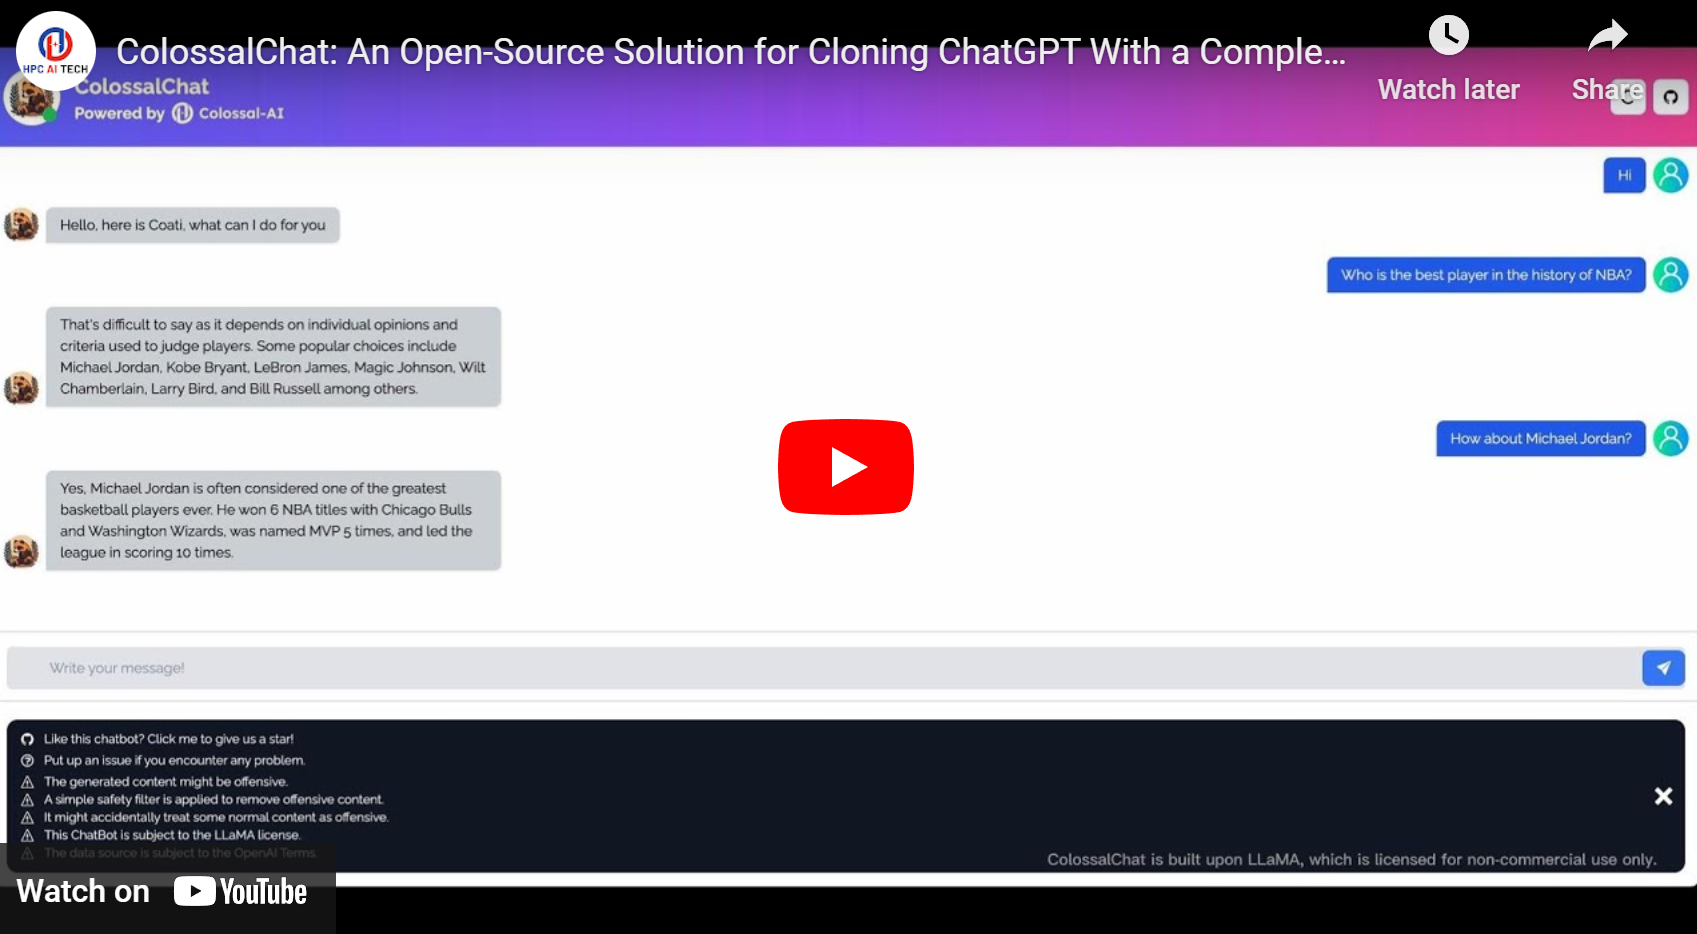
ColossalChat: An open-source solution for cloning ChatGPT with a complete RLHF pipeline.
[code]
[blog]
[demo]
[tutorial]
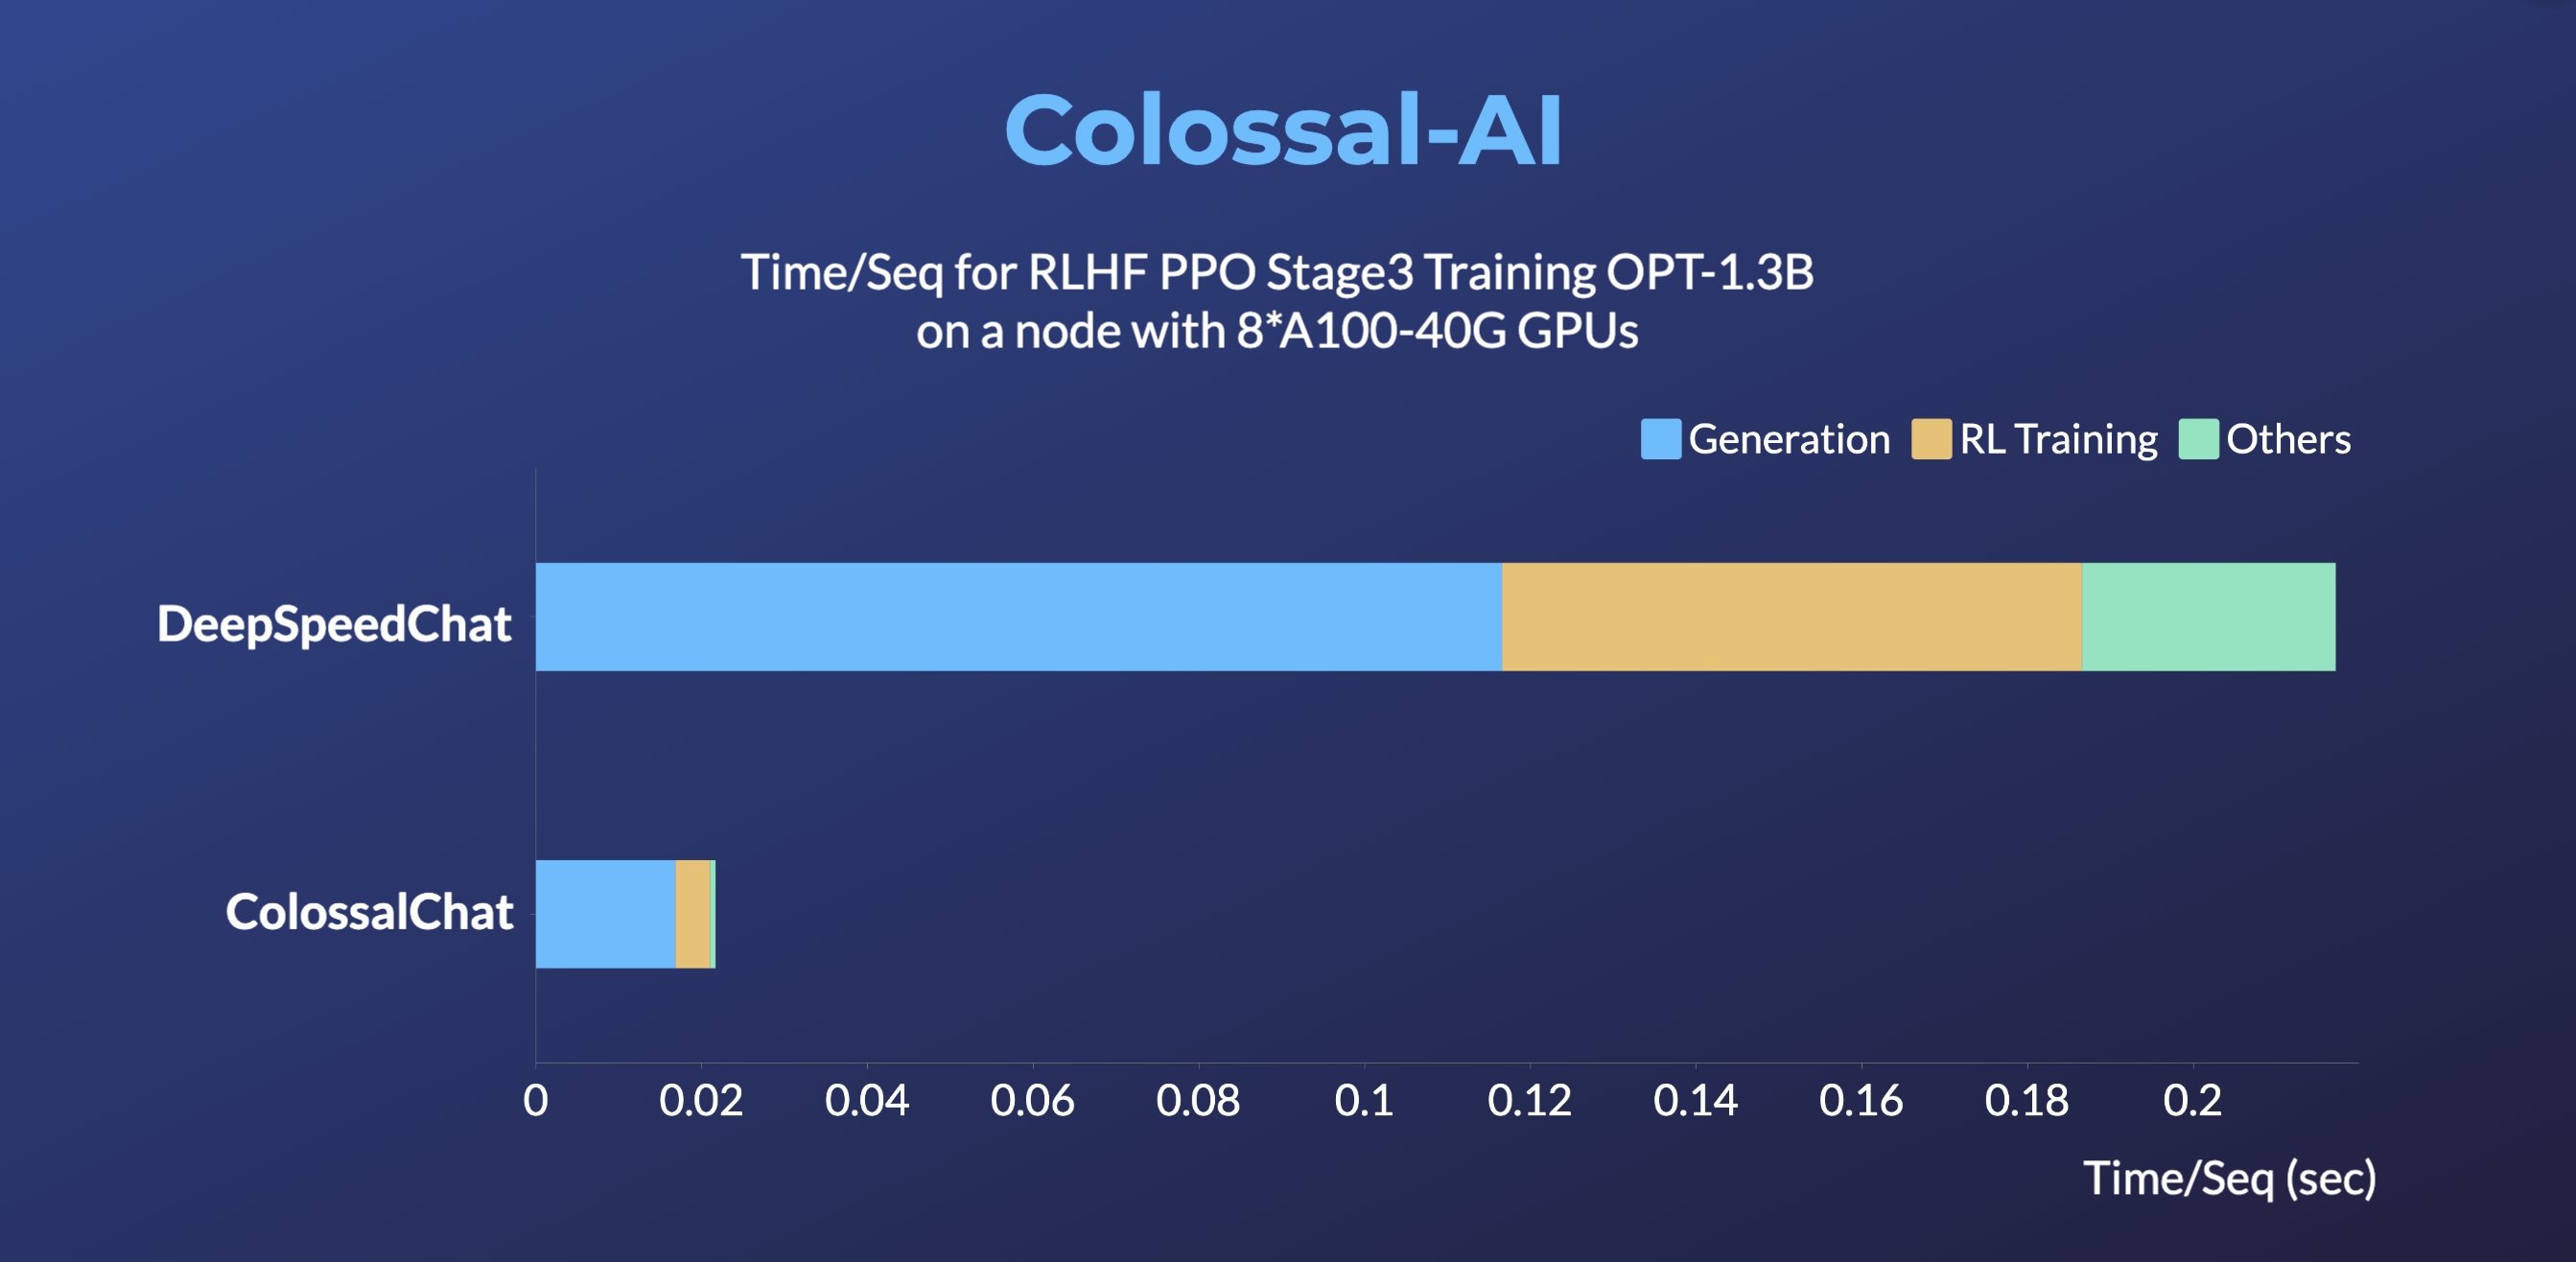
- Up to 10 times faster for RLHF PPO Stage3 Training
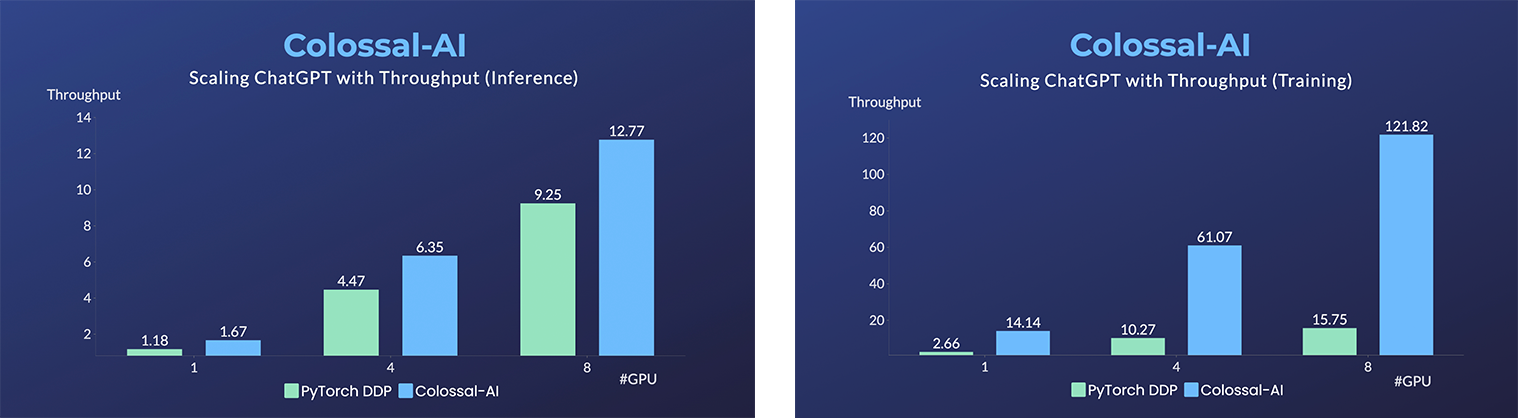
- Up to 7.73 times faster for single server training and 1.42 times faster for single-GPU inference
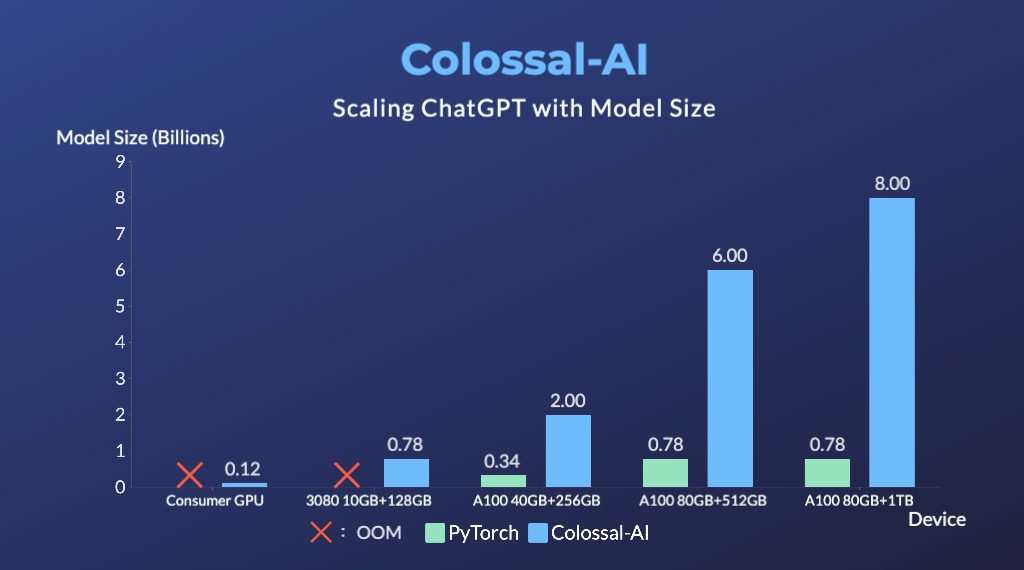
- Up to 10.3x growth in model capacity on one GPU
- A mini demo training process requires only 1.62GB of GPU memory (any consumer-grade GPU)
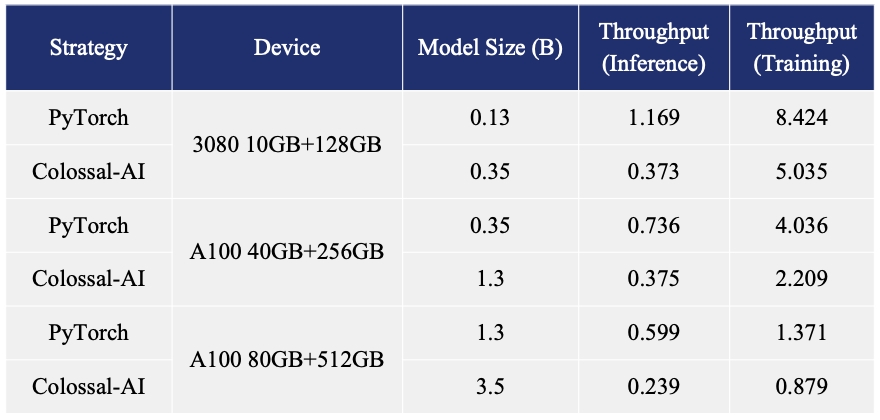
- Increase the capacity of the fine-tuning model by up to 3.7 times on a single GPU
- Keep at a sufficiently high running speed
(back to top)
AIGC
Acceleration of AIGC (AI-Generated Content) models such as Stable Diffusion v1 and Stable Diffusion v2.
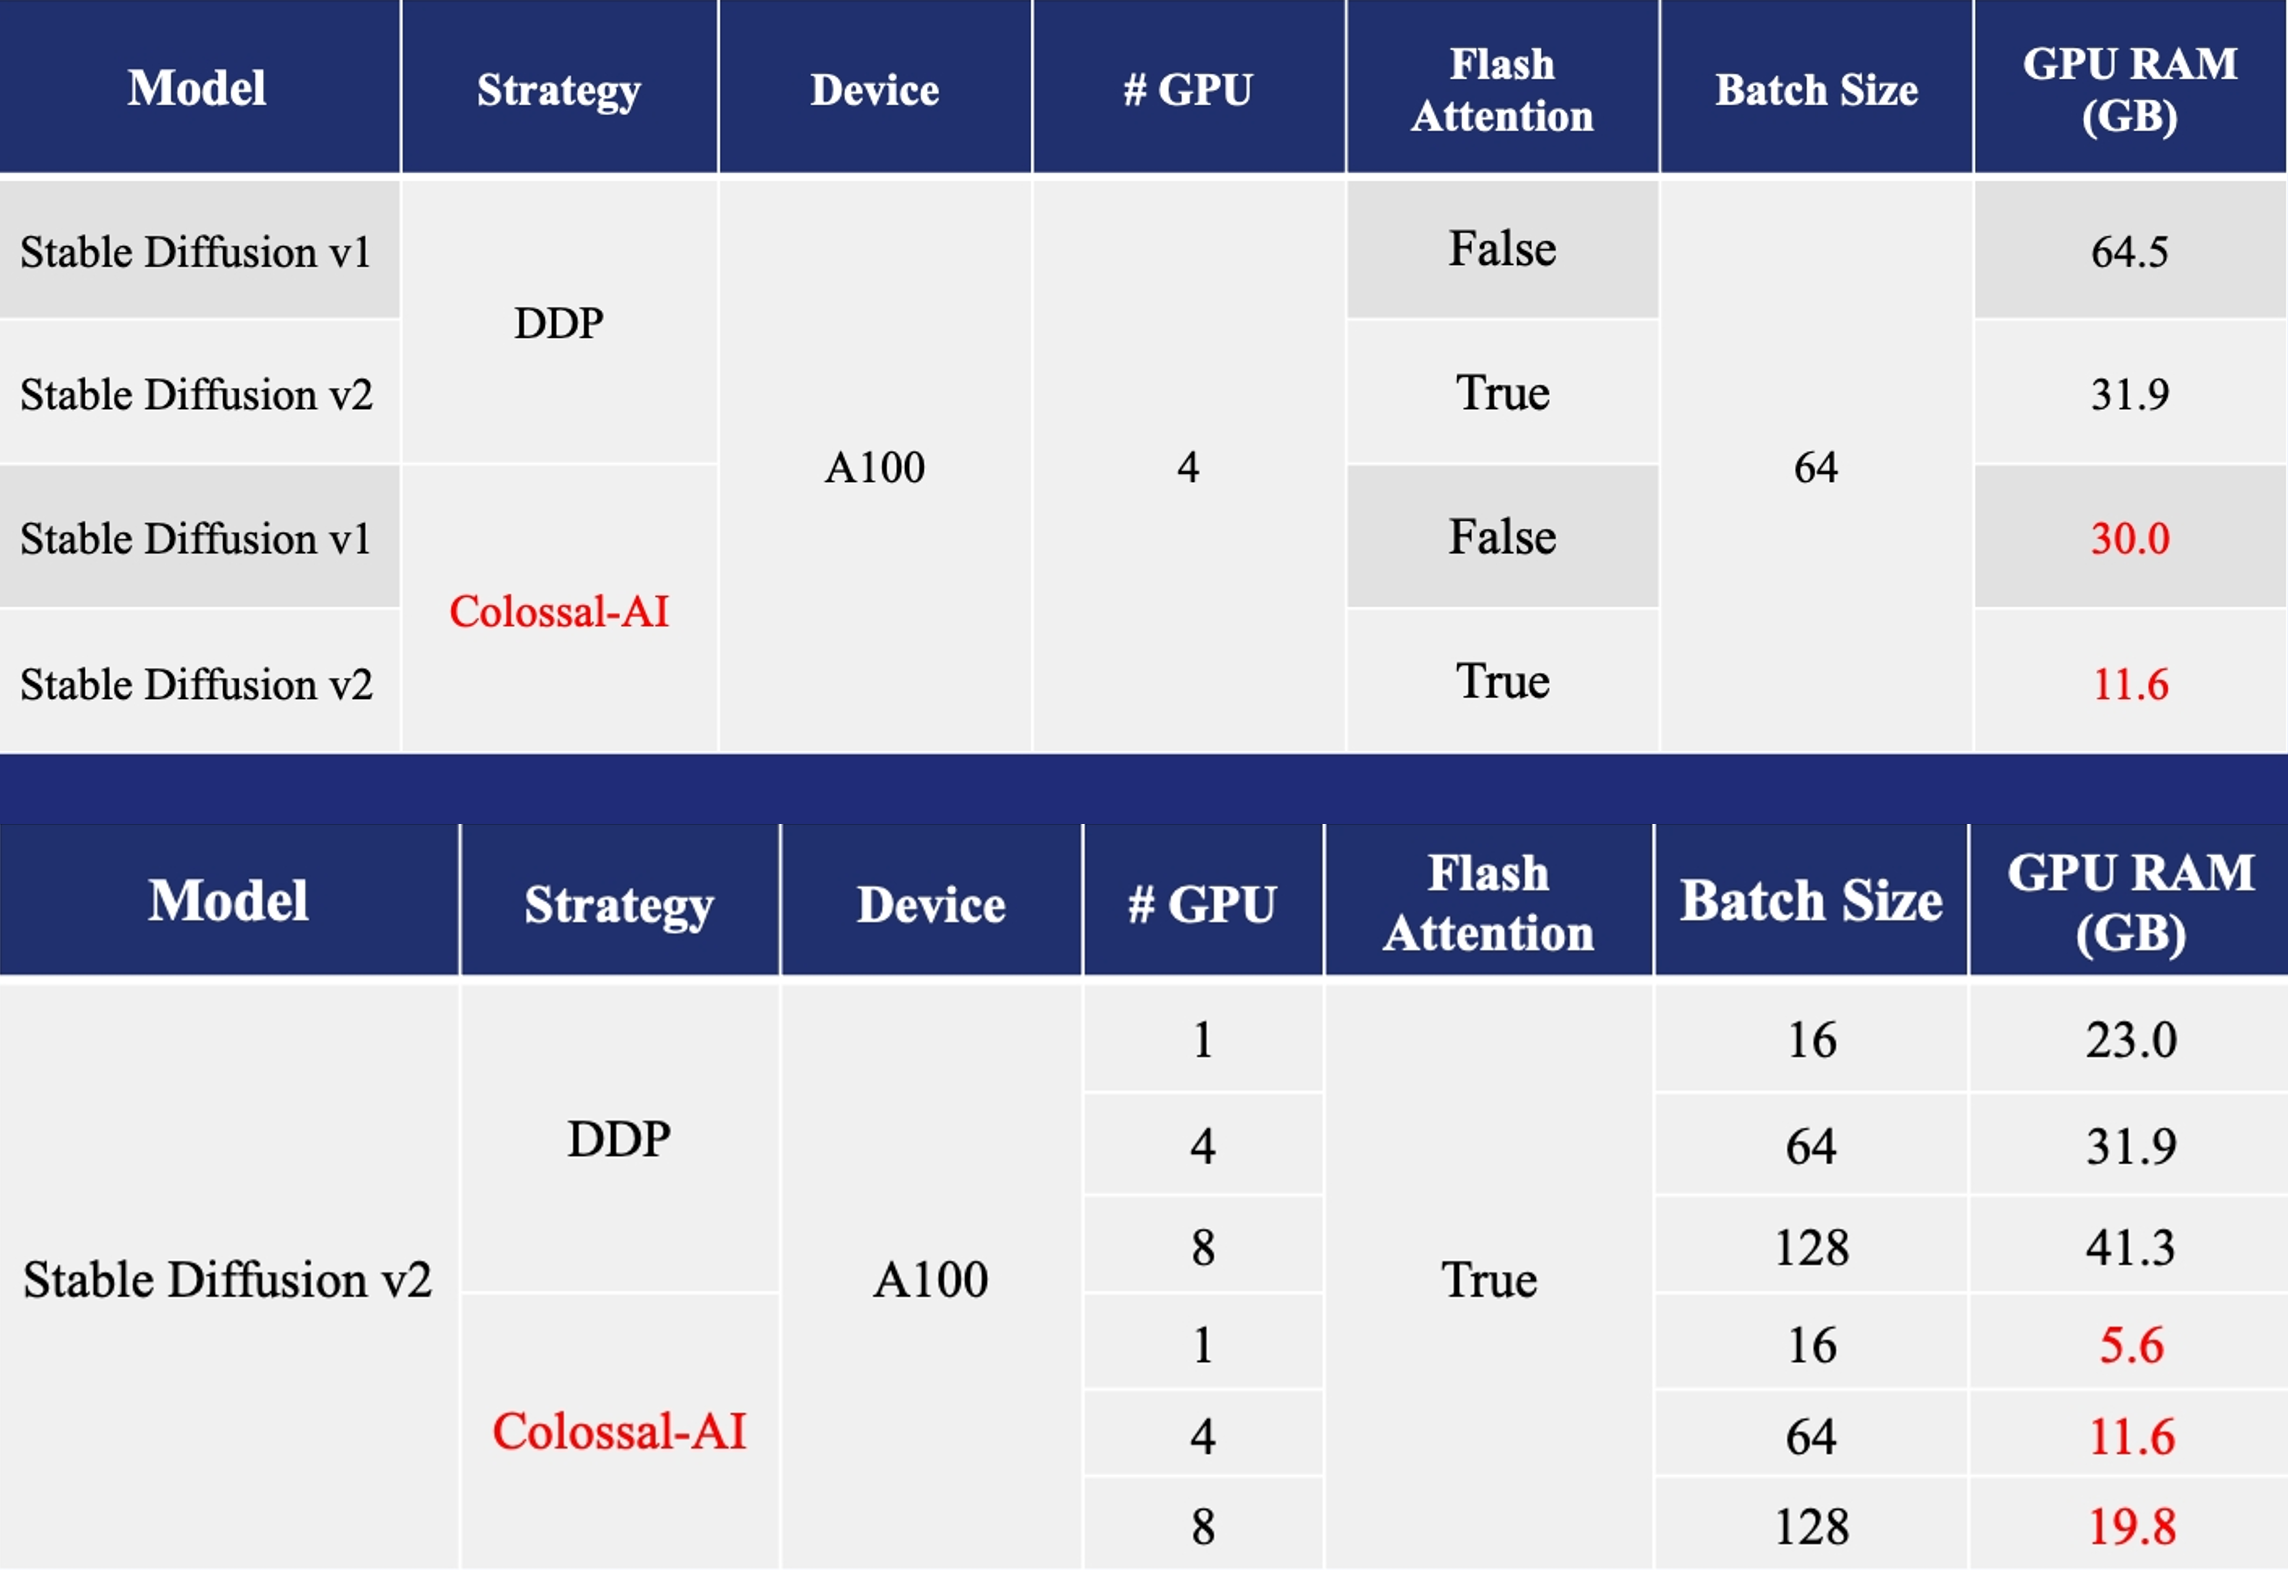
- Training: Reduce Stable Diffusion memory consumption by up to 5.6x and hardware cost by up to 46x (from A100 to RTX3060).






 Colossal-AI 是一个开源系统,通过提供一套并行训练和内存优化技术的工具箱,帮助人们更省钱、更快速、用更少的硬件训练和运行大型 AI 模型。