[!IMPORTANT]
License Notice
This codebase and its associated model weights are released under FISH AUDIO RESEARCH LICENSE. Please refer to LICENSE for more details. We will take action against any violation of the license.
[!WARNING]
Legal Disclaimer
We do not hold any responsibility for any illegal usage of the codebase. Please refer to your local laws about DMCA and other related laws.
Quick Start
For Human
Here are the official documents for Fish Audio S2, follow the instructions to get started easily.
[!IMPORTANT]
For SGLang server, please read SGLang-Omni README.
For vLLM Omni server, please read vLLM-Omni Fish Speech S2 Pro Recipe and the User Guide.
For LLM Agent
Install and configure Fish-Audio S2 by following the instructions here: https://speech.fish.audio/install/
Fish Audio S2 Pro
State-of-the-art multilingual text-to-speech (TTS) system, redefining the boundaries of voice generation.
Fish Audio S2 Pro is the most advanced multimodal model developed by Fish Audio. Trained on over 10 million hours of audio data covering more than 80 languages, S2 Pro combines a Dual-Autoregressive (Dual-AR) architecture with reinforcement learning (RL) alignment to generate speech that is exceptionally natural, realistic, and emotionally rich, leading the competition among both open-source and closed-source systems.
The core strength of S2 Pro lies in its support for sub-word level fine-grained control of prosody and emotion using natural language tags (e.g., [whisper], [excited], [angry]), while natively supporting multi-speaker and multi-turn conversation generation.
Visit the Fish Audio website for a live playground, or read our technical report and blog post for more details.
Model Variants
| Model |
Size |
Availability |
Description |
| S2-Pro |
4B parameters |
HuggingFace |
Full-featured flagship model with maximum quality and stability |
More details of the model can be found in the technical report.
Benchmark Results
| Benchmark |
Fish Audio S2 |
| Seed-TTS Eval — WER (Chinese) |
0.54% (best overall) |
| Seed-TTS Eval — WER (English) |
0.99% (best overall) |
| Audio Turing Test (with instruction) |
0.515 posterior mean |
| EmergentTTS-Eval — Win Rate |
81.88% (highest overall) |
| Fish Instruction Benchmark — TAR |
93.3% |
| Fish Instruction Benchmark — Quality |
4.51 / 5.0 |
| Multilingual (MiniMax Testset) — Best WER |
11 of 24 languages |
| Multilingual (MiniMax Testset) — Best SIM |
17 of 24 languages |
On Seed-TTS Eval, S2 achieves the lowest WER among all evaluated models including closed-source systems: Qwen3-TTS (0.77/1.24), MiniMax Speech-02 (0.99/1.90), Seed-TTS (1.12/2.25). On the Audio Turing Test, 0.515 surpasses Seed-TTS (0.417) by 24% and MiniMax-Speech (0.387) by 33%. On EmergentTTS-Eval, S2 achieves particularly strong results in paralinguistics (91.61% win rate), questions (84.41%), and syntactic complexity (83.39%).
Highlights

Fine-Grained Inline Control via Natural Language
S2 Pro brings unprecedented "soul" to speech. Using simple [tag] syntax, you can precisely embed emotional instructions at any position in the text.
- 15,000+ Unique Tags Supported: Not limited to fixed presets; S2 supports free-form text descriptions. Try
[whisper in small voice], [professional broadcast tone], or [pitch up].
- Rich Emotion Library:
[pause] [emphasis] [laughing] [inhale] [chuckle] [tsk] [singing] [excited] [laughing tone] [interrupting] [chuckling] [excited tone] [volume up] [echo] [angry] [low volume] [sigh] [low voice] [whisper] [screaming] [shouting] [loud] [surprised] [short pause] [exhale] [delight] [panting] [audience laughter] [with strong accent] [volume down] [clearing throat] [sad] [moaning] [shocked]
Innovative Dual-Autoregressive (Dual-AR) Architecture
S2 Pro adopts a master-slave Dual-AR architecture consisting of a decoder-only transformer and an RVQ audio codec (10 codebooks, ~21 Hz):
- Slow AR (4B parameters): Operates along the time axis, predicting the primary semantic codebook.
- Fast AR (400M parameters): Generates the remaining 9 residual codebooks at each time step, reconstructing exquisite acoustic details.
This asymmetric design achieves peak audio fidelity while significantly boosting inference speed.
Reinforcement Learning (RL) Alignment
S2 Pro utilizes Group Relative Policy Optimization (GRPO) for post-training alignment. We use the same model suite for data cleaning and annotation directly as Reward Models, perfectly resolving the distribution mismatch between pre-training data and post-training objectives.
- Multi-Dimensional Reward Signals: Comprehensively evaluates semantic accuracy, instruction adherence, acoustic preference scoring, and timbre similarity to ensure every second of generated speech feels intuitive to humans.
As the Dual-AR architecture is structurally isomorphic to standard LLMs, S2 Pro natively supports all SGLang inference acceleration features, including Continuous Batching, Paged KV Cache, CUDA Graph, and RadixAttention-based Prefix Caching.
Performance on a single NVIDIA H200 GPU:
- Real-Time Factor (RTF): 0.195
- Time-to-First-Audio (TTFA): ~100 ms
- Extreme Throughput: 3,000+ acoustic tokens/s while maintaining RTF < 0.5
Robust Multilingual Support
S2 Pro supports over 80 languages without requiring phonemes or language-specific preprocessing:
- Tier 1: Japanese (ja), English (en), Chinese (zh)
- Tier 2: Korean (ko), Spanish (es), Portuguese (pt), Arabic (ar), Russian (ru), French (fr), German (de)
- Global Coverage: sv, it, tr, no, nl, cy, eu, ca, da, gl, ta, hu, fi, pl, et, hi, la, ur, th, vi, jw, bn, yo, xsl, cs, sw, nn, he, ms, uk, id, kk, bg, lv, my, tl, sk, ne, fa, af, el, bo, hr, ro, sn, mi, yi, am, be, km, is, az, sd, br, sq, ps, mn, ht, ml, sr, sa, te, ka, bs, pa, lt, kn, si, hy, mr, as, gu, fo, etc.
Native Multi-Speaker Generation
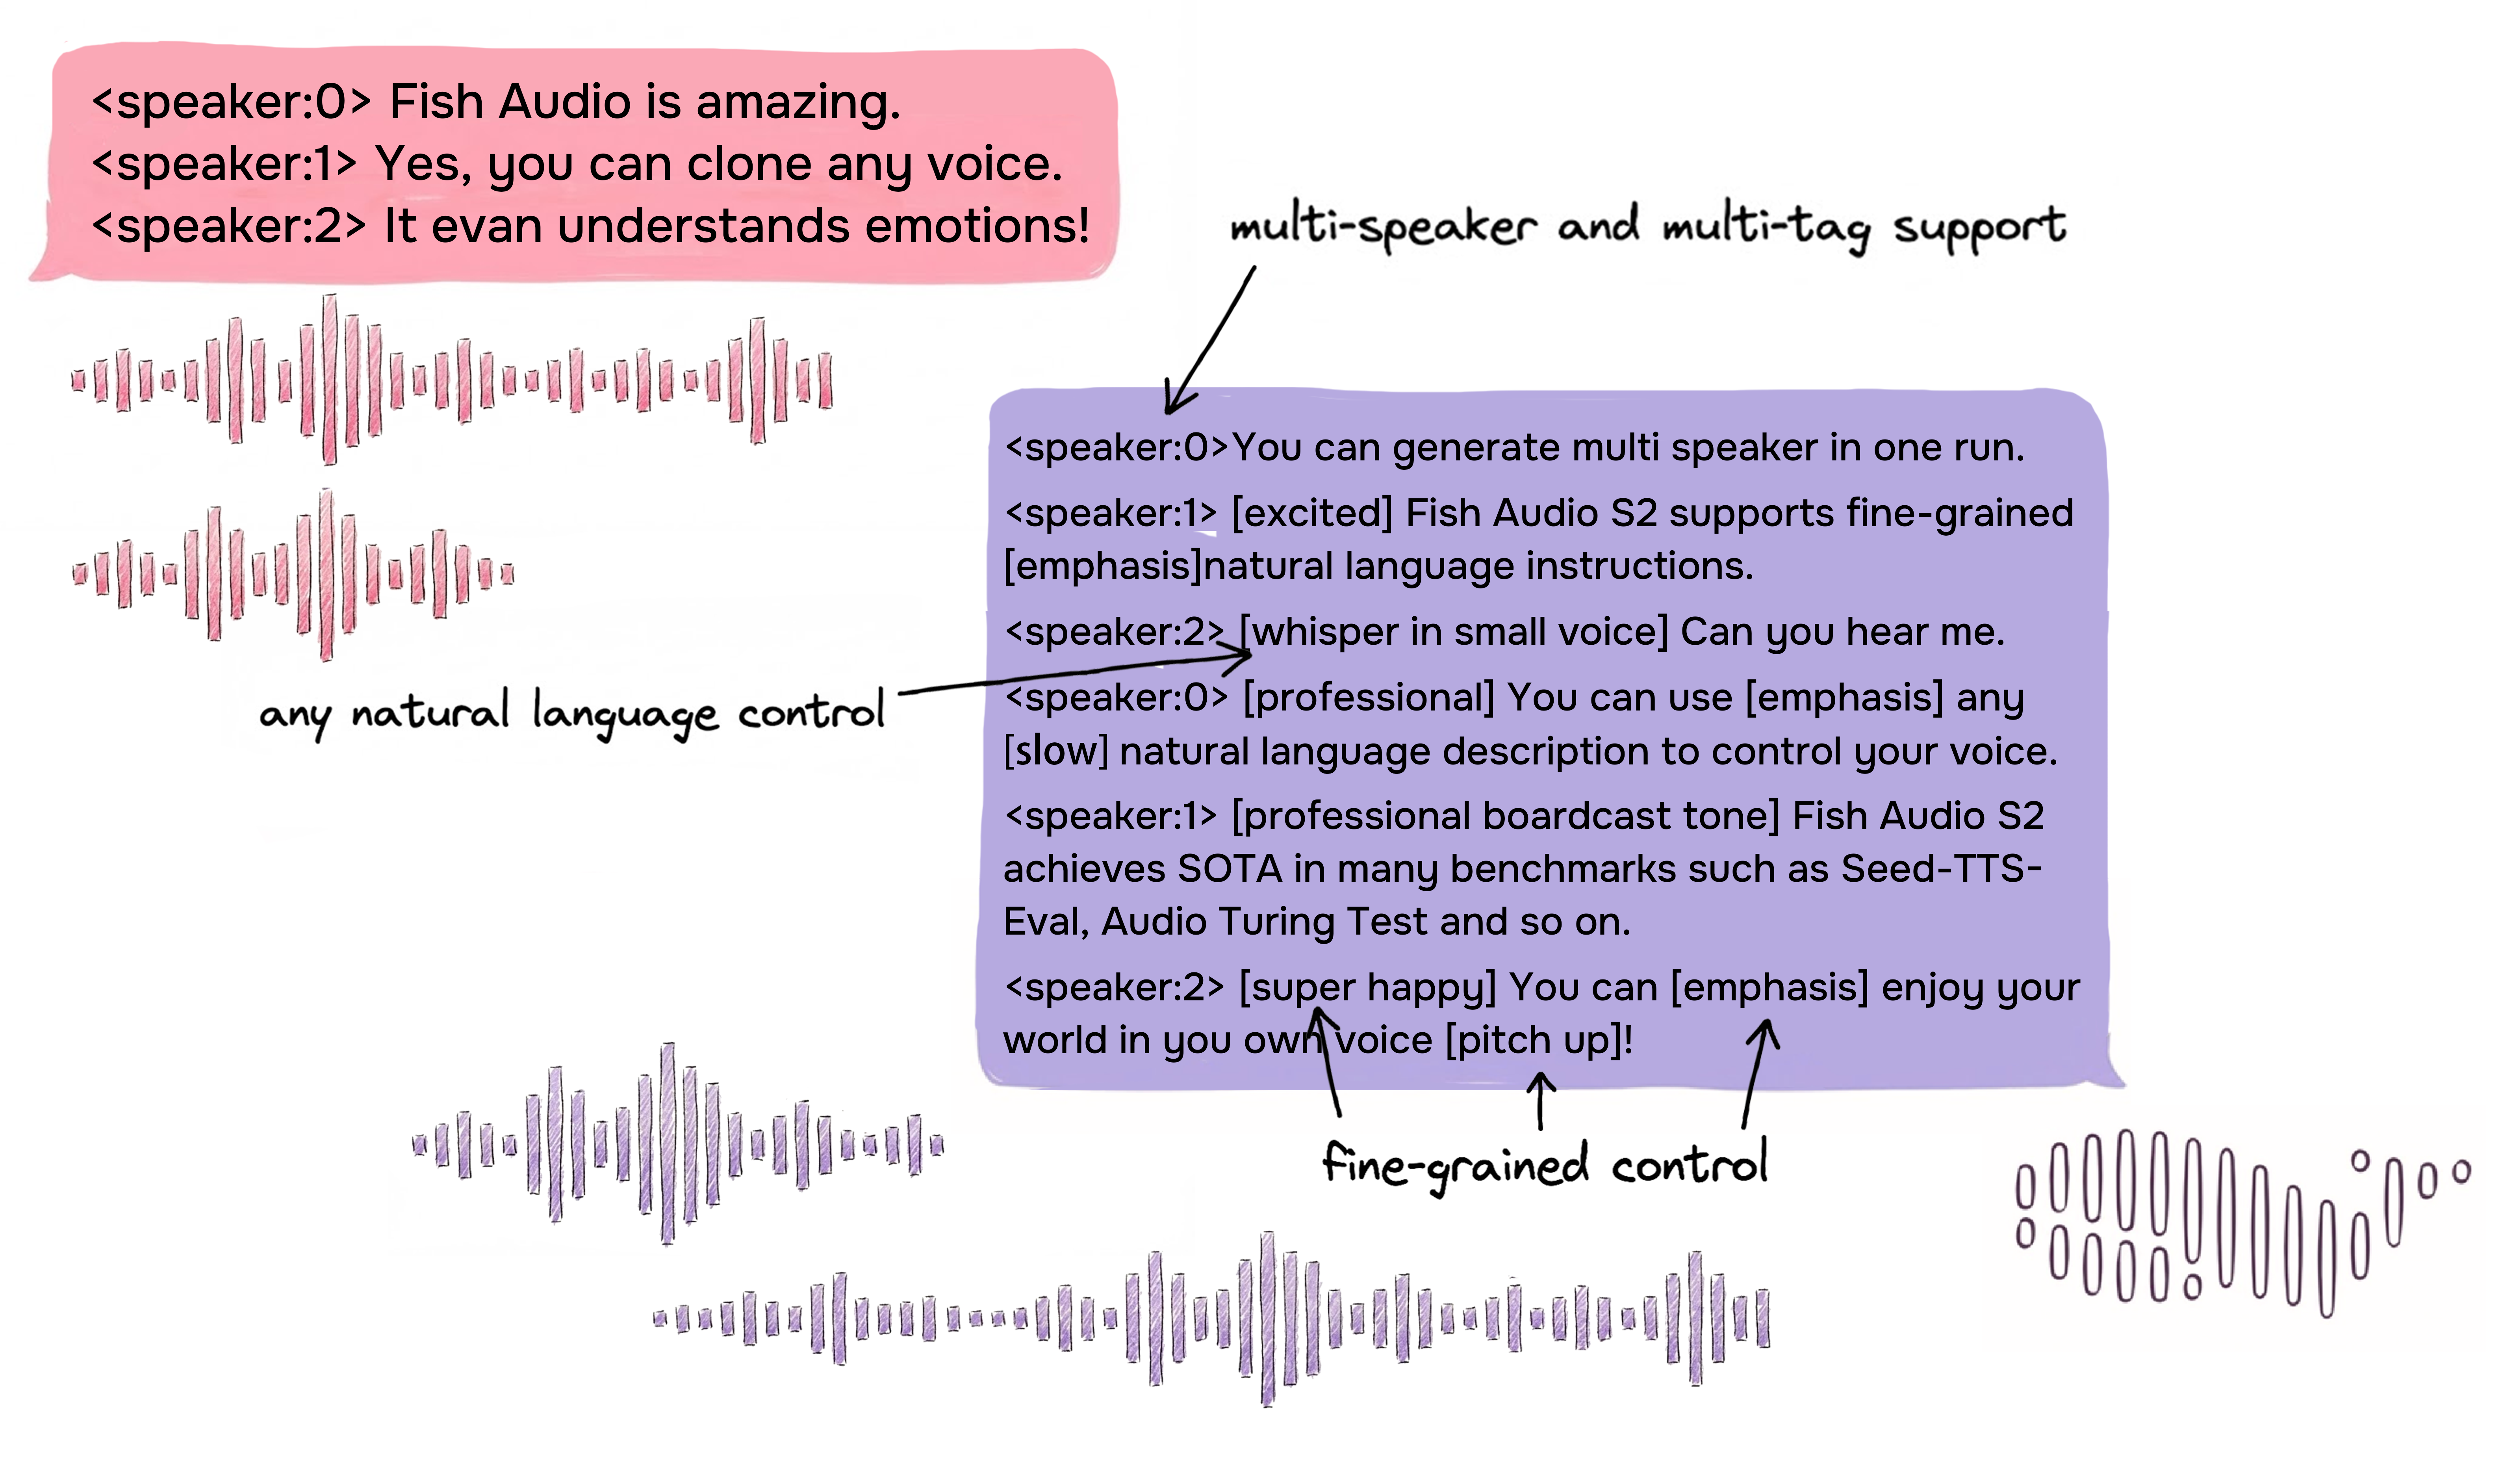
Fish Audio S2 allows users to upload reference audio containing multiple speakers, and the model processes each speaker's features via the <|speaker:i|> token. You can then control the model's performance via speaker ID tokens, enabling a single generation to include multiple speakers. There is no longer a need to upload separate reference audio for each individual speaker.
Multi-Turn Generation
Thanks to the expansion of the model context, our model can now leverage previous information to improve the expressiveness of subsequent generated content, thereby increasing the naturalness of the dialogue.
Rapid Voice Cloning
Fish Audio S2 supports accurate voice cloning using short reference samples (typically 10-30 seconds). The model captures timbre, speaking style, and emotional tendencies, producing realistic and consistent cloned voices without additional fine-tuning.
For SGLang Server usage, please refer to the SGLang-Omni README.
Credits
Tech Report
@misc{fish-speech-v1.4,
      title={Fish-Speech: Leveraging Large Language Models for Advanced Multilingual Text-to-Speech Synthesis},
      author={Shijia Liao and Yuxuan Wang and Tianyu Li and Yifan Cheng and Ruoyi Zhang and Rongzhi Zhou and Yijin Xing},
      year={2024},
      eprint={2411.01156},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2411.01156},
}

@misc{liao2026fishaudios2technical,
      title={Fish Audio S2 Technical Report},
      author={Shijia Liao and Yuxuan Wang and Songting Liu and Yifan Cheng and Ruoyi Zhang and Tianyu Li and Shidong Li and Yisheng Zheng and Xingwei Liu and Qingzheng Wang and Zhizhuo Zhou and Jiahua Liu and Xin Chen and Dawei Han},
      year={2026},
      eprint={2603.08823},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2603.08823},
}




 Fish Speech(Fish Audio S2)是一款领先的开源文本转语音系统,可以生成自然、富有情感的语音,支持 80 多种语言。其旗舰模型 S2-Pro 结合了 Dual-AR 架构与强化学习对齐技术。