



33.2K ·GitHub
Что это такое?
 Fish Speech (Fish Audio S2) — современная система синтеза речи с открытым исходным кодом, которая генерирует естественную, эмоционально выразительную речь на более чем 80 языках. Флагманская модель S2-Pro сочетает архитектуру Dual-AR с выравниванием на основе обучения с подкреплением.
Это отдельный файл модели или полноценная система со своим интерфейсом?Это полноценная система синтеза речи: её можно запустить через инструмент командной строки, WebUI, выделенный сервер инференса или внутри Docker-контейнера.
Это полноценная система синтеза речи: её можно запустить через инструмент командной строки, WebUI, выделенный сервер инференса или внутри Docker-контейнера.Как это запустить?Сначала следуйте инструкции по установке, затем выберите Command Line Inference, WebUI Inference или Server Inference; для запуска в контейнере также есть руководство по Docker Setup.
Сначала следуйте инструкции по установке, затем выберите Command Line Inference, WebUI Inference или Server Inference; для запуска в контейнере также есть руководство по Docker Setup.Нужна ли мощная видеокарта, чтобы это запустить?Да — это модель с 4 млрд параметров, рассчитанная на видеокарты NVIDIA с поддержкой CUDA. Опубликованные показатели измерялись на одной NVIDIA H200, а для высокопроизводительной работы сервера используется ускорение через SGLang.
Да — это модель с 4 млрд параметров, рассчитанная на видеокарты NVIDIA с поддержкой CUDA. Опубликованные показатели измерялись на одной NVIDIA H200, а для высокопроизводительной работы сервера используется ускорение через SGLang.Есть ли подвох, прежде чем внедрять это в продукт?Проект прямо снимает с себя ответственность за незаконное использование и предупреждает, что будет применять свою лицензию против нарушений, поэтому перед коммерческим использованием внимательно проверьте условия лицензии.
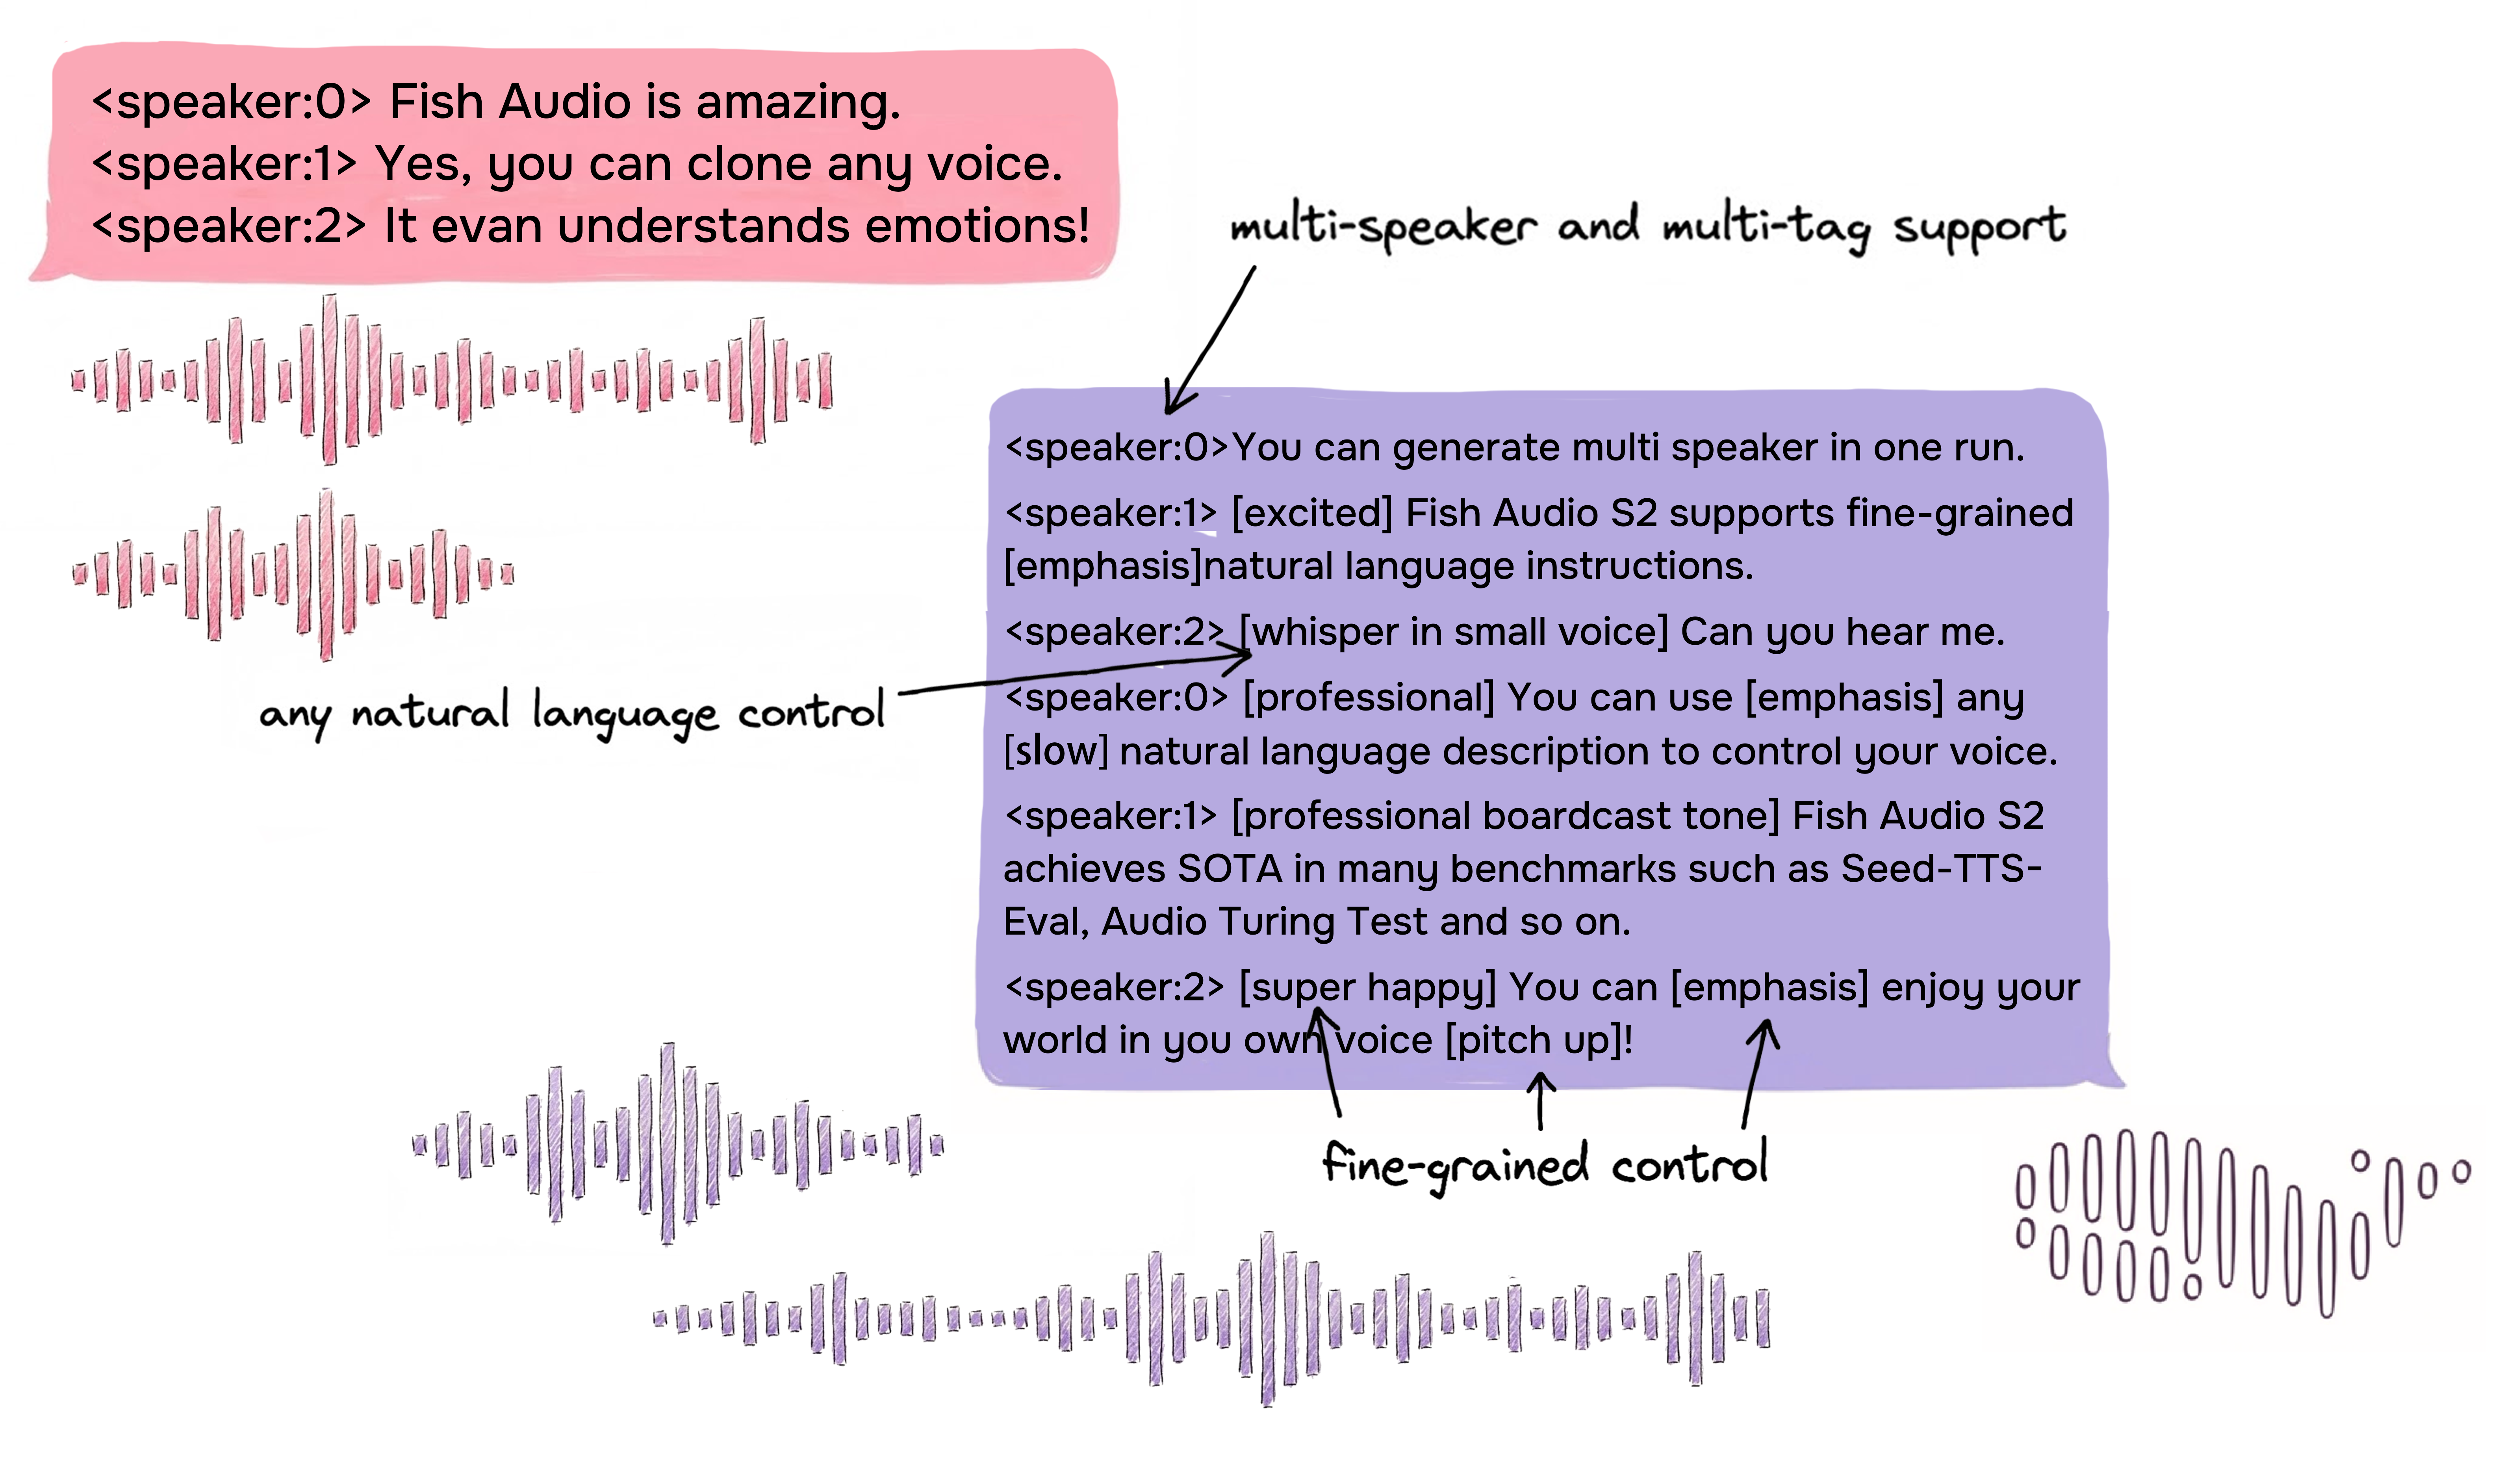
Проект прямо снимает с себя ответственность за незаконное использование и предупреждает, что будет применять свою лицензию против нарушений, поэтому перед коммерческим использованием внимательно проверьте условия лицензии.Что особенного в системе эмоциональных тегов?Вы вставляете в текст теги на естественном языке, например [whisper], [angry] или [professional broadcast tone], и они напрямую управляют интонацией и эмоциями. Помимо фиксированных пресетов поддерживаются более 15 000 свободных тегов.
Вы вставляете в текст теги на естественном языке, например [whisper], [angry] или [professional broadcast tone], и они напрямую управляют интонацией и эмоциями. Помимо фиксированных пресетов поддерживаются более 15 000 свободных тегов.Сколько эталонного аудио нужно для клонирования голоса?Достаточно 10–30 секунд эталонного аудио, чтобы модель смогла перенять тембр, манеру речи и эмоциональные особенности без дополнительного дообучения.
Достаточно 10–30 секунд эталонного аудио, чтобы модель смогла перенять тембр, манеру речи и эмоциональные особенности без дополнительного дообучения.Может ли она сгенерировать диалог нескольких говорящих за один проход?Да — вы можете загрузить эталонное аудио с несколькими говорящими и управлять выводом для каждого из них с помощью токенов идентификаторов говорящих, так что одна генерация может включать несколько голосов.
Да — вы можете загрузить эталонное аудио с несколькими говорящими и управлять выводом для каждого из них с помощью токенов идентификаторов говорящих, так что одна генерация может включать несколько голосов.Почему она так быстра для модели с 4 млрд параметров?Она использует асимметричную архитектуру Dual-AR (медленный AR на 4 млрд параметров и быстрый AR на 400 млн) вместе с ускорением SGLang (непрерывный батчинг, paged KV cache, RadixAttention). Это даёт около 100 мс до первого звука и более 3 000 акустических токенов в секунду на H200.
Она использует асимметричную архитектуру Dual-AR (медленный AR на 4 млрд параметров и быстрый AR на 400 млн) вместе с ускорением SGLang (непрерывный батчинг, paged KV cache, RadixAttention). Это даёт около 100 мс до первого звука и более 3 000 акустических токенов в секунду на H200.What are similar projects?Speech, csm, FireRedAudio, breeze-tts, MOSS-TTS, bark, VoxCPM, Retrieval-based-Voice-Conversion-WebUI
Speech, csm, FireRedAudio, breeze-tts, MOSS-TTS, bark, VoxCPM, Retrieval-based-Voice-Conversion-WebUIWhich topics is it in?vits, voice-cloning, speech-synthesis, llama, webui, tts, text-to-speech, reinforcement-learning, multimodal, transformer, multilingual, real-time
vits, voice-cloning, speech-synthesis, llama, webui, tts, text-to-speech, reinforcement-learning, multimodal, transformer, multilingual, real-time