
Что это?
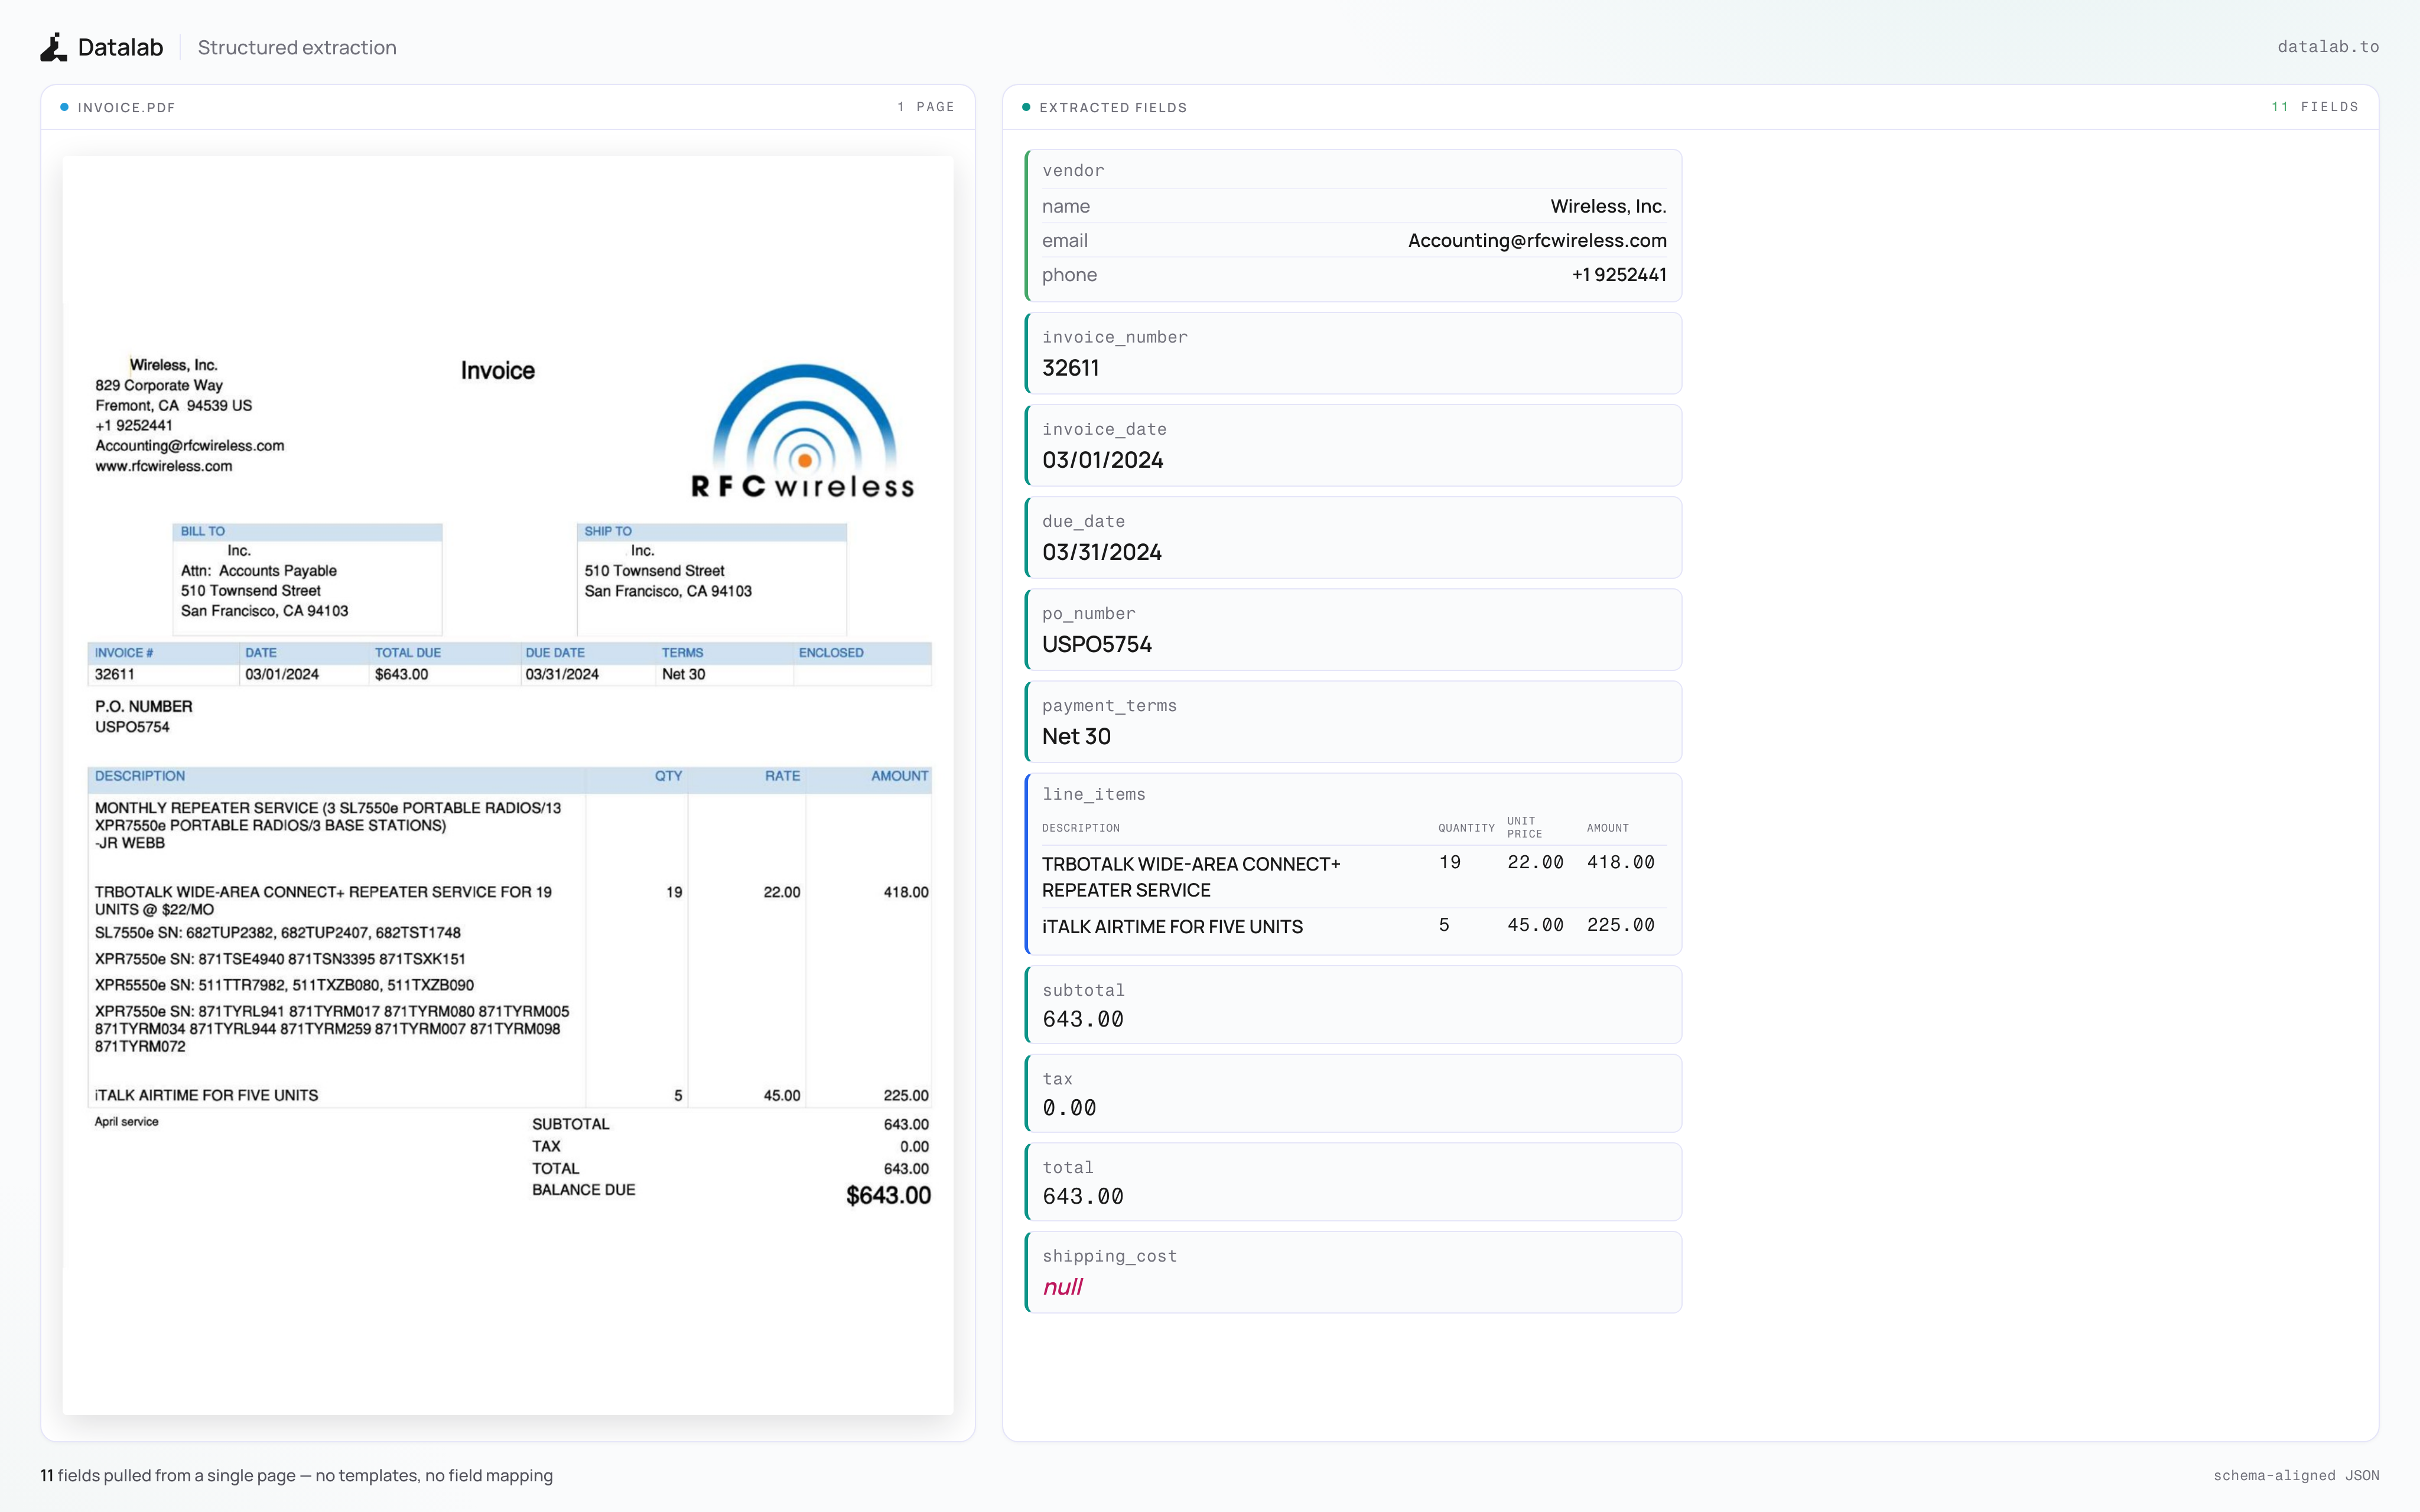
 lift — открытая визуально-языковая модель 9B и набор инструментов, извлекающие структурированные JSON-данные из PDF и изображений по заданной вами схеме, с ограничивающим схемой декодированием, гарантирующим корректный вывод.
Это модель, CLI-инструмент или Python-библиотека?И то, и другое, и третье: визуально-языковая модель 9B, которую можно запускать локально или через vLLM, с CLI для отдельных файлов или каталогов, Python-библиотекой (InferenceManager) для использования в своём процессе и приложением на Streamlit под названием Schema Studio для построения схем.
И то, и другое, и третье: визуально-языковая модель 9B, которую можно запускать локально или через vLLM, с CLI для отдельных файлов или каталогов, Python-библиотекой (InferenceManager) для использования в своём процессе и приложением на Streamlit под названием Schema Studio для построения схем.Как это запустить?Установите пакет через pip (pip install lift-pdf или lift-pdf[app] для Schema Studio) или соберите из исходников, затем запускайте CLI с --schema, указывающим на JSON-файл схемы, и выберите --method hf или vllm для инференса.
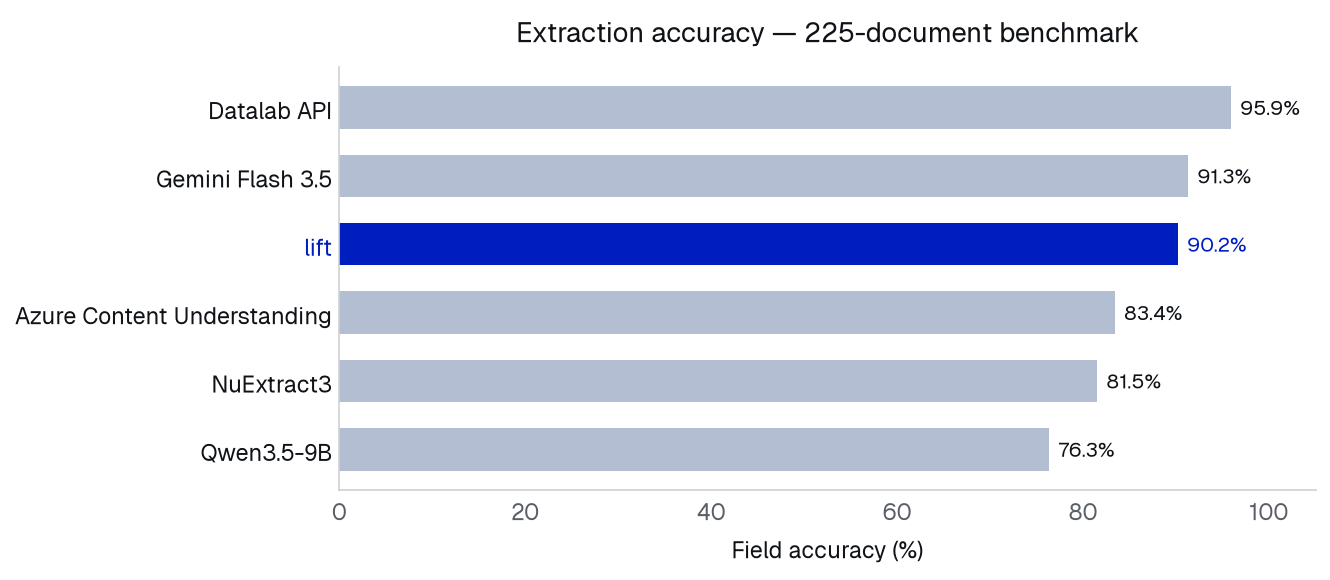
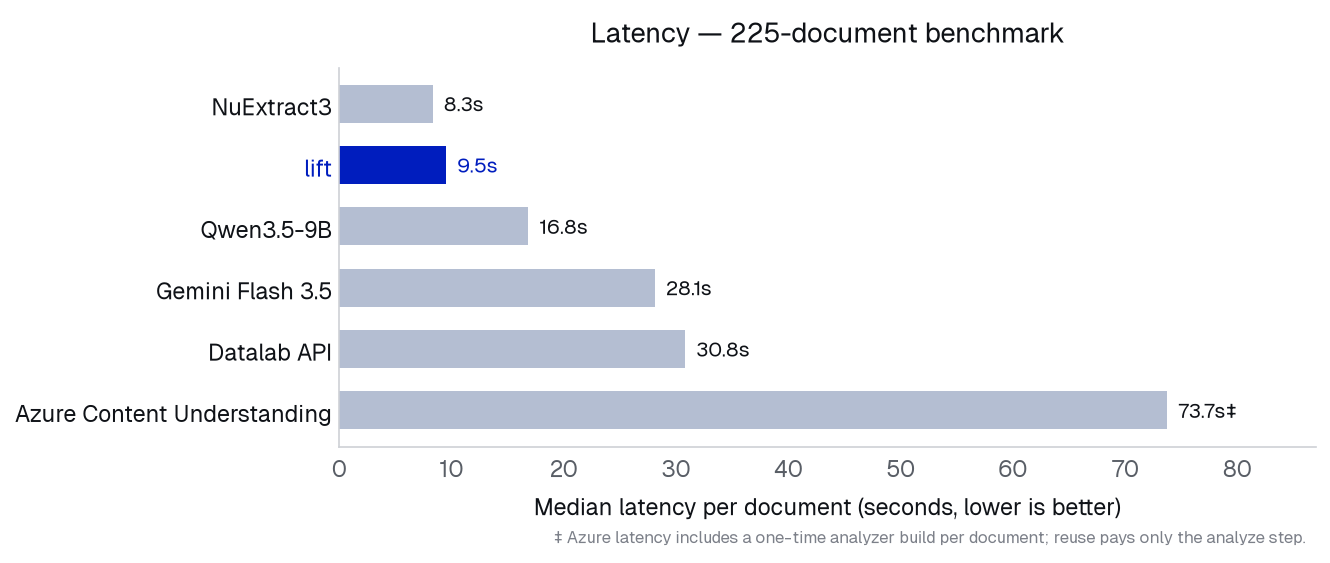
Установите пакет через pip (pip install lift-pdf или lift-pdf[app] для Schema Studio) или соберите из исходников, затем запускайте CLI с --schema, указывающим на JSON-файл схемы, и выберите --method hf или vllm для инференса.Насколько точное извлечение?На бенчмарке авторов из 225 документов lift (9B) показывает точность полей 90,2%, но лишь 20,9% точности по документу целиком (все поля верны) при медианной задержке 9,5 с — быстрее, но менее стабильно идеально, чем хостинговый API Datalab.
На бенчмарке авторов из 225 документов lift (9B) показывает точность полей 90,2%, но лишь 20,9% точности по документу целиком (все поля верны) при медианной задержке 9,5 с — быстрее, но менее стабильно идеально, чем хостинговый API Datalab.Каковы условия лицензии?Код — под Apache 2.0, но веса модели используют изменённую лицензию OpenRAIL-M: бесплатно для исследований, личного использования и стартапов с финансированием/выручкой до 5 млн долларов, но нельзя использовать конкурентно по отношению к собственному API Datalab, а более широкое коммерческое использование на своём хостинге требует отдельной лицензии.
Код — под Apache 2.0, но веса модели используют изменённую лицензию OpenRAIL-M: бесплатно для исследований, личного использования и стартапов с финансированием/выручкой до 5 млн долларов, но нельзя использовать конкурентно по отношению к собственному API Datalab, а более широкое коммерческое использование на своём хостинге требует отдельной лицензии.Что такое Schema Studio?Это приложение на Streamlit в комплекте с lift для интерактивного построения, сохранения и тестирования JSON-схем извлечения на собственных документах перед запуском в большом масштабе.
Это приложение на Streamlit в комплекте с lift для интерактивного построения, сохранения и тестирования JSON-схем извлечения на собственных документах перед запуском в большом масштабе.Какая альтернатива самостоятельному хостингу lift?Datalab предлагает управляемый API с более высокой точностью, чем открытые веса, с проверкой по каждому полю, цитатами и оценками уверенности, плюс 20 долларов бесплатных кредитов ежемесячно и публичную песочницу, чтобы попробовать без установки чего-либо.
Datalab предлагает управляемый API с более высокой точностью, чем открытые веса, с проверкой по каждому полю, цитатами и оценками уверенности, плюс 20 долларов бесплатных кредитов ежемесячно и публичную песочницу, чтобы попробовать без установки чего-либо.Какие JSON-схемы поддерживаются?Поддерживается стандартный JSON Schema со строками, числами, булевыми значениями, массивами и вложенными объектами, но enum, anyOf/oneOf, $ref и additionalProperties лучше избегать, так как декодер с ограничением по схеме пропускает схемы, которые не может скомпилировать.
Поддерживается стандартный JSON Schema со строками, числами, булевыми значениями, массивами и вложенными объектами, но enum, anyOf/oneOf, $ref и additionalProperties лучше избегать, так как декодер с ограничением по схеме пропускает схемы, которые не может скомпилировать.What are similar projects?surya, ZDTaichu5.0-9B, Unlimited-OCR, marker, olmocr, StartLux-Decision, chandra, EvoVLM
surya, ZDTaichu5.0-9B, Unlimited-OCR, marker, olmocr, StartLux-Decision, chandra, EvoVLMWhich topics is it in?document-intelligence, vision-language, json-schema, schema, data-extraction, vlm, llm-inference, vllm, ocr, document-processing, evaluation, multimodal
document-intelligence, vision-language, json-schema, schema, data-extraction, vlm, llm-inference, vllm, ocr, document-processing, evaluation, multimodal