
webmagic README

The project's README from github.com/code4craft/webmagic. As one markdown file: README.md.

logo

Readme in Chinese

Maven Central License Build Status

A scalable crawler framework. It covers the whole lifecycle of crawler: downloading, url management, content extraction and persistent. It can simplify the development of a specific crawler.

Features:

Install:

Add dependencies to your pom.xml:

<dependency>
    <groupId>us.codecraft</groupId>
    <artifactId>webmagic-core</artifactId>
    <version>${webmagic.version}</version>
</dependency>
<dependency>
    <groupId>us.codecraft</groupId>
    <artifactId>webmagic-extension</artifactId>
    <version>${webmagic.version}</version>
</dependency>

WebMagic use slf4j with slf4j-log4j12 implementation. If you customized your slf4j implementation, please exclude slf4j-log4j12.

<exclusions>
    <exclusion>
        <groupId>org.slf4j</groupId>
        <artifactId>slf4j-log4j12</artifactId>
    </exclusion>
</exclusions>

Get Started:

First crawler:

Write a class implements PageProcessor. For example, I wrote a crawler of github repository information.

public class GithubRepoPageProcessor implements PageProcessor {

    private Site site = Site.me().setRetryTimes(3).setSleepTime(1000);

    @Override
    public void process(Page page) {
        page.addTargetRequests(page.getHtml().links().regex("(https://github\\.com/\\w+/\\w+)").all());
        page.putField("author", page.getUrl().regex("https://github\\.com/(\\w+)/.*").toString());
        page.putField("name", page.getHtml().xpath("//h1[@class='public']/strong/a/text()").toString());
        if (page.getResultItems().get("name")==null){
            //skip this page
            page.setSkip(true);
        }
        page.putField("readme", page.getHtml().xpath("//div[@id='readme']/tidyText()"));
    }

    @Override
    public Site getSite() {
        return site;
    }

    public static void main(String[] args) {
        Spider.create(new GithubRepoPageProcessor()).addUrl("https://github.com/code4craft").thread(5).run();
    }
}

You can also use annotation way:

@TargetUrl("https://github.com/\\w+/\\w+")
@HelpUrl("https://github.com/\\w+")
public class GithubRepo {

    @ExtractBy(value = "//h1[@class='public']/strong/a/text()", notNull = true)
    private String name;

    @ExtractByUrl("https://github\\.com/(\\w+)/.*")
    private String author;

    @ExtractBy("//div[@id='readme']/tidyText()")
    private String readme;

    public static void main(String[] args) {
        OOSpider.create(Site.me().setSleepTime(1000)
                , new ConsolePageModelPipeline(), GithubRepo.class)
                .addUrl("https://github.com/code4craft").thread(5).run();
    }
}

Docs and samples:

Documents: http://webmagic.io/docs/

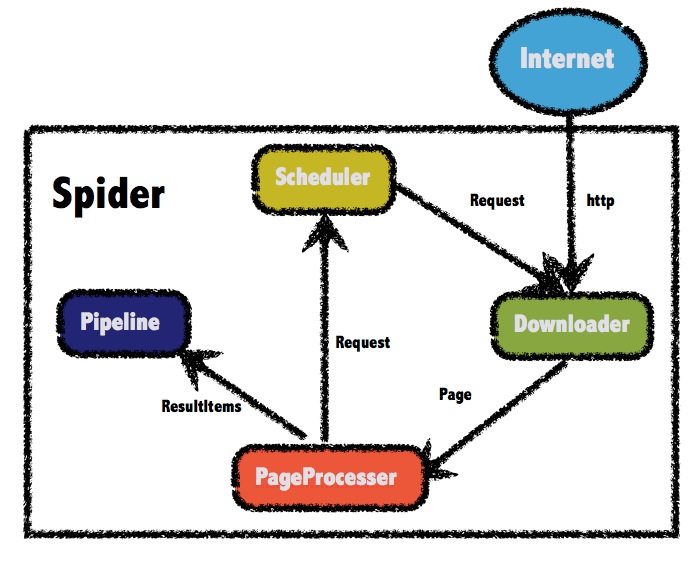
The architecture of webmagic (referred to Scrapy)

image

There are more examples in webmagic-samples package.

License:

Licensed under Apache 2.0 license

Thanks:

To write webmagic, I refered to the projects below :

Mail-list:

https://groups.google.com/forum/#!forum/webmagic-java

http://list.qq.com/cgi-bin/qf_invite?id=023a01f505246785f77c5a5a9aff4e57ab20fcdde871e988

QQ Group: 373225642 542327088

webmagic (code4craft/webmagic)

Searching Database…

11.7K ·GitHub
这是什么?WebMagic 是一个可扩展的 Java 爬虫框架。它覆盖了爬虫的完整生命周期——下载、URL 管理、内容提取和数据持久化——让开发特定爬虫变得更简单。
这是一个拿来就能跑的现成爬虫,还是用来自己写爬虫的框架?它是一个框架,不是做好的爬虫:你只需写一个简单的 Java 类,说明要抓取和提取什么内容,WebMagic 会负责运行周边的整套流程。
怎么把它加到我的项目里,并让第一个爬虫跑起来?先在 pom.xml 中添加 WebMagic 依赖,然后写一个实现 PageProcessor 接口的类——README 里的示例就是一个抓取 GitHub 仓库信息的爬虫。
依赖方面有什么需要留意的坑吗?WebMagic 通过 slf4j 输出日志,并且自带 slf4j-log4j12 绑定;如果你要用自己的 slf4j 实现,需要排除 slf4j-log4j12 以免冲突。
这东西是不是就像 Java 版的 Scrapy?基本上是的——它的架构明确参考了 Python 爬虫框架 Scrapy;README 也提到早先的 Java 爬虫框架 Spiderman 是其参考之一。
是不是必须实现 PageProcessor,有没有更省事的方式?不是必须的——你也可以在一个普通的 Java POJO 上用注解来定义爬虫,完全不需要任何配置。
怎么告诉爬虫接下来要跟进哪些链接?在你的 processor 里调用 page.addTargetRequests(links),把页面上发现的 URL 加入待抓取队列。
Creator
code4craft
Size
17 MB
Stars
11.7K
Age
13y
Commits · 90 Days