pd-bridge — heterogeneous prefill/decode for DeepSeek-V4-Flash

Prefill a 284B model on NVIDIA. Decode it on Apple Silicon. Over plain 10GbE.
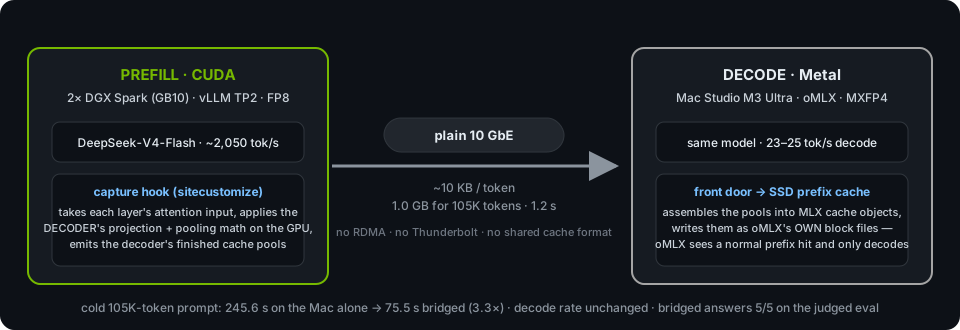
Two production inference engines that share no cache format, no framework, no vendor and no
quantization, serving one request together. DeepSeek-V4-Flash is 284B total / 13B active,
256 routed experts, MLA + sparse attention, 149 GB resident on the prefill side and 156 GB on
the decode side:
- Prefill: 2× NVIDIA DGX Spark (GB10), vLLM TP2, official
deepseek-ai/DeepSeek-V4-Flash FP8
- Decode: 1× Mac Studio M3 Ultra, oMLX,
DV4-Flash-MXFP4-MLX (MXFP4)
- Link: ordinary 10 gigabit Ethernet. No RDMA, no Thunderbolt.
cold prompt        Mac Studio alone    Sparks prefill -> Mac decode
   ~25K tokens          42.6 s               28.2 s     1.5x
   ~82K tokens         205.8 s               72.9 s     2.8x
  ~105K tokens         245.6 s               75.5 s     3.3x
  ~241K tokens         732.3 s              200.3 s     3.7x
decode rate unchanged (23-25 tok/s both ways); warm turns bypass the bridge (4.9 s / 19.3 s at 241K)
Every row verdict-checked, 2026-09-06. The bridged leg scores 5/5 on the judged quality eval,
same as native.
Since then the served window went 262,144 -> 2,097,152 and the ceiling moved with it.
A 700,630-token cold prompt now bridges end to end in 11 minutes 26 seconds — verdict complete,
342 blocks, 1,117 tok/s of prefill. That is 2.9x past the largest prompt in the table above, and
the pair has accepted over a million.
cold prompt     engine   tok/s    end-to-end   blocks   verdict
   192,099      119.2 s   1,611      143.1 s      93    complete
   385,838      288.7 s   1,337      466.6 s     188    complete
   677,069      596.8 s   1,134      655.9 s     330    complete
   700,630      627.0 s   1,117      685.5 s     342    complete
   709,055      635.4 s   1,116      694.6 s     345    partial 706,560/709,055 (99.6%)
   988,487    1,037.8 s     952    1,142.5 s     376    partial 770,048/988,487 (78%)
 1,006,172    1,070.5 s     940    1,171.7 s     346    partial 708,608/1,006,172 (70%)
All 2026-09-08, one prefill pair, same 10GbE. partial is not a failure: past roughly 772K tokens the
capture crosses the prefill box's free-memory floor and seals a valid contiguous prefix instead of
dying; the decoder mounts what arrived and natively prefills the remainder. See Known limits.
We have not run a Mac-alone control at these sizes, so those rows carry no ratio — they are what
the bridge does, not a claimed speedup. The measured ratios stop at 241K and are shown above.
Full numbers and methodology: RESULTS.md · bench/BENCHMARK-PROTOCOL.md
2026-09-17 — the link is no longer plain 10GbE. A Mac Studio joined the Sparks' RoCE fabric through a MikroTik switch
(ConnectX-4 Lx in a Thunderbolt enclosure, driven by Ash Hart's MCDMA), and a second
Studio receives the same blocks over Apple's Thunderbolt RDMA. The cache now moves Spark → door Studio → library Studio → back
as RDMA on every hop, and a four-turn conversation answered from the library in 7–10 s vs 30 s on one Studio and 18 s on the
Sparks alone. That layer, its tools and its numbers live in fabric/. None of it exists without MCDMA;
Ben's MelonDMA told us what the Gen3 tunnel would do before we had one.
The idea
Prefill/decode disaggregation is well established, and so is the hardware argument for it: prefill is
compute-bound, decode is memory-bandwidth-bound, so run each phase where it is cheapest. Existing
systems do this by transferring the KV cache from the prefill worker to the decode worker.
That requires both ends to agree on a cache format. Ours never can. One side is CUDA/vLLM with an
FP8 paged cache; the other is Metal/MLX with its own block layout. Worse, DeepSeek-V4-Flash does not
have "a KV cache" — each layer carries a rotating 128-token window, a compressor pool (ratio 4 with
overlap carry, and ratio 128), and an indexer pool, all with layer-dependent RoPE.
So we don't transfer a cache. We compute the decoder's finished cache on the prefill machine,
using the decoder's own weights, and write it straight into the decoder's prefix-cache store.
The prefill engine already computes the exact tensor those pools are a pure function of — the
attention input. A hook takes it there, applies the Mac's projection and pooling math on the GPU,
and emits the finished pools. The decode side assembles them into MLX cache objects and hands them
to oMLX's own block writer. oMLX then sees a normal prefix-cache hit and only decodes. Neither
engine is modified in its hot path; the decoder does not know a bridge exists.
Payload: ~10 KB per token — 0.80 GB for an 81K-token prompt, pulled in 1.08 s. The network
stopped being the bottleneck; the prefill engine is now 65% of wall time, which is where you want it.
Why the reconstruction is trustworthy
The whole design rests on the pooled tensors being the same tensors the decoder would have
computed. That is tested, not assumed:
| check |
result |
| Cache arrays rebuilt on the Mac vs. a full native forward |
313/313 bit-exact |
| Blocks written by the bridge vs. blocks oMLX writes itself |
11/11 identical (only the created_at stamp differs) |
| Torch pooling port vs. MLX ground truth (T=23,217) |
projections, window, carries bit-exact; pooled tensors 99.95–99.96% identical, worst delta one bf16 ulp |
| In-container hook selftest (chunked == one-shot) |
52/52 |
| Needle retrieval through a fully reconstructed 81K cache |
correct on every benchmark run |
studio/verify_blocks.py, studio/pd_diff_state.py, spark/pd_pool_validate.py and
spark/pd_pool_selftest.py reproduce these. Compare tensors, never file hashes — created_at means
a bridge-written block can never be byte-identical as a file.
Known limits — read this before you run it
The memory floor, and why big prompts come back partial (2026-09-08)
The capture lives in the prefill box's memory for the whole request and costs about 11.8 KB of
unified memory per token on rank 0 only (rank 1 stays flat — it does its half of the attention and
holds no capture). A GB10 has ONE 121 GB pool shared by weights, the vLLM KV arena and everything
else, so steady-state free memory with the model up is ~22 GB.
Measured: the capture crosses a 5.0 GB free-memory floor at roughly 772,000 tokens. Past that the
hook seals a valid contiguous prefix [0,T) and reports it rather than dying — the decoder mounts
what arrived and natively prefills the tail. That is the partial verdict in the table above. A
700,630-token wake cleared the floor with 100 MB to spare; a 1,006,172-token wake sealed at 70%.
This replaced a real failure. Before the fix, _finish() copied every layer to the host without
freeing the layers it had already written, so the full device capture and the growing host copies
were alive at once. At 1,021,199 tokens it died after 11 of 43 layers and drove the box into swap
thrash — no sshd even over a 200G fabric. It needed a physical power button. The hook now releases
each layer as its file lands and checks MemAvailable every 64 layer-chunks.
If you are memory-tight, this is your limit, not the window. The window is a config number; the
floor is physics on your box. Measure MemAvailable during a long prefill before trusting either.
The ~82K-token ceiling was a real bug. It is fixed. (History kept because the failure mode is
instructive and the arithmetic still matters on smaller machines.)
omlx_block_writer used to hold one materialised cumulative cache snapshot per 2048-token
boundary until finalize(): peak memory grew quadratically with prompt length (~`N(N+1)/2`
blocks' worth of arrays — ~16 GB at 39 boundaries, ~23 GB at 47, which exhausted a 256 GB M3 Ultra
holding a 156 GB model and wrote zero blocks at 97,848 tokens).
The writer now streams: each boundary is stored through oMLX's own pipeline and released the
moment it is snapshotted (begin_stream/store_boundary; finalize drains and verifies). Peak
memory is ONE boundary snapshot (~20 MB × boundary index / N — tens of MB, not tens of GB). It is
validated against a real oMLX reference block (synthetic layout match) and live at 52 boundaries /
109,085 tokens — see RESULTS.md. PD_STREAM_BOUNDARIES=0 restores the batched path for comparison.
PD_MAX_BRIDGE_TOKENS remains as a configurable envelope guard, not a bug workaround: raise it to
your machine's measured headroom.
Two related behaviours worth knowing:
- The fallback works, and it can no longer lie. When a bridge fails the reply still comes back
correct — the decoder serves natively. Since the bench4 autopsy (docs/FINDING-bench4-cold-fallback.md),
every response carries an
X-PD-Bridge verdict (complete / partial B/T / declined with reason),
and bench_cold.py records it — a silent native fallback can never again enter a results table
as a bridged number.
- The "cold-start variance" at 20K was not variance. The 25.5 s vs 55.4 s spread was the capture
hook flushing mid-request during chunked prefill (see the FINDING): the 55 s runs were native
fallbacks wearing a bridge label. The hook now guards its idle flush with a CUDA-event query and a
chunk-alignment check, and the front validates every capture manifest before trusting it.
Status, honestly
This is a reference implementation, not a library. It is pinned hard and it is young.
- One model. DeepSeek-V4-Flash. The pooling math is specific to its sparse attention.
- Pinned stacks. oMLX 0.6.4; vLLM 0.21.1rc1 with the DeepSeek-V4 plugin (sparkrun image).
- It monkey-patches private internals of both engines — a
sitecustomize hook onto
DeepseekV4MultiHeadLatentAttentionWrapper.attention_impl on the vLLM side, and a
filesystem-fallback patch to oMLX's PagedSSDCacheIndex on the MLX side (oMLX indexes SSD blocks
at model load only, so externally written blocks are otherwise invisible). Expect this to break
when either project moves.
- The judged quality eval is five questions on one document. The bridged leg scores 5/5 on it,
twice (once from a fresh cold v3 bridge), same as native. Prefill runs FP8 weights and decode runs
MXFP4, so bridged output is not token-identical to native; it is factually faithful on what we
checked, which is a smaller claim than "equivalent".
- The flush signal was unreliable until 2026-09-06 17:52 — fixed. The hook's watcher ran in three
processes and two of them deleted the signal before the capturing worker saw it (~1 in 3 hit rate). Hook v5
fixes it; captures now close 0.6–0.9 s after the engine returns (4.8 s at 236K, which is the block write).
Autopsy:
docs/FINDING-flush-signal-three-watchers.md. Unit test: spark/test_flush_decision.py.
- The front door is threaded, with one caveat. HTTP handlers run in threads (health, model list and
oMLX passthrough answer immediately, and concurrent decodes overlap because the decoder batches them),
but every
bridge() call — the MLX cache assembly — is marshalled to the main thread and runs one at a
time, because MLX streams are thread-local and the model lives there. Measured 2026-09-06: a short
request completed in 47 s while an 86K-token cold bridge was in flight, instead of waiting it out.
Two clients do slow each other down; they no longer block each other.
- Only cold, long prompts benefit. Warm turns bypass the bridge by design and are served natively.
The transferable idea is bigger than this code: when two engines cannot share a cache format,
compute the consumer's finished cache on the producer, using the consumer's weights. That
generalizes past this model and this hardware, and it is the part worth stealing.
Layout
spark/    prefill side (NVIDIA / vLLM)
  capture_sitecustomize_v3.py   the hook: projections + pooling on the GPU, per-layer safetensors
  pd_pool_torch.py              torch port of the decoder's pooling math (RoPE, compress, rmsnorm)
  pd_pool_selftest.py           in-container selftest (chunked == one-shot)
  pd_pool_validate.py           validate the port against MLX ground truth
  pd-launch-v3.sh               launch vLLM with the hook (PD_HOOK=off for a control run)
  pd_capture_http.py            Range-capable server so the decoder can stream captures
  pd_share.py                   the threaded share the pooled path actually runs (SimpleHTTP drops connections under poll+fetch)
  pd-hf-layout.sh               lay the checkpoint out as an HF hub dir inside the container mount
  POOL-VALIDATION.md            what the validation numbers mean

studio/   decode side (Apple Silicon / oMLX)
  pd_front.py                   OpenAI-compatible front door; orchestrates a request end to end
  omlx_block_writer.py          drive oMLX's own store pipeline to emit prefix-cache blocks
  pd_assemble_blocks.py         build MLX cache objects from a pooled capture, snapshot per boundary
  pd_export_proj_weights.py     export the MLX projection weights the prefill hook needs
  pd_export_pool_truth.py       MLX-computed ground truth for validating the torch port
  pd_make_v3_from_mlx.py        build a v3 capture entirely in MLX (acceptance harness)
  pd_capture_mlx.py             capture attention inputs natively (test fixture)
  pd_rebuild_mlx.py             attention-only replay (the v1 path, kept for comparison)
  verify_blocks.py              directory-vs-directory block comparison
  pd_diff_state.py              cache-array diff against a full forward
  test_block_writer_synthetic.py
  pd_omlx_hooks.py              kv/RDMA path: staged restore, tail install, restore timing (PD_OMLX_HOOKS=1)
  pd-front-kv.sh / pd-rdma-recvd.sh   front door in kv mode / the RDMA receiver
  pd_assemble_kv.py, pd_verify_kv.py, test_omlx_block.py   kv-path assembly, bridged-vs-native check, block header gate

spark/ (kv/RDMA path)
  pd_kv_connector.py            vLLM v1 KV connector: oMLX-native blocks built on the GPU, pushed over RDMA during prefill
  pd_omlx_block.py              oMLX chain hashes + block file header
  pd-launch-kv.sh, pd_memguard.sh, pd-rdma-serve.sh, test_kv_gather.py

rdma/     pd_rdma (receiver, R1 pull server/client) + libpd_rdma_tx.so (the connector's sender); docs/RDMA.md

bench/    bench_cold.py (records the X-PD-Bridge verdict), hetero (the one-command demo client),
          BENCHMARK-PROTOCOL.md
docs/     DESIGN-v3-pooled.md — the pooling math and the hook points, derived from oMLX's own code
          FINDING-bench4-cold-fallback.md — the mid-request-flush autopsy; what broke and what it taught
          FINDING-flush-signal-three-watchers.md — why the flush signal was consumed by the wrong worker
          FINDING-stale-limits-after-a-window-change.md — READ THIS BEFORE RAISING YOUR WINDOW.
              Five numbers sized against the old window that break silently after you raise it,
              including the one that clamps every long-context answer to a single token.
Don't have this hardware? Start on the rung you can reach
Everything in this repo is written against the exact machines we ran, on purpose: if you have the same
gear you get an exact replica and the numbers in RESULTS.md. If you don't, the idea is the same and the
recipe scales down. Three rungs, honestly labeled:
| rung |
prefill side |
decode side |
model |
status |
| A · exact replica |
2× DGX Spark, TP2 over their direct 200G cable |
Mac Studio M3 Ultra 256 GB |
DeepSeek-V4-Flash (284B / 13B active) |
measured — everything in RESULTS.md |
| B · one Spark + any Apple Silicon Mac |
1× DGX Spark (128 GB) |
Mac Studio / Mac mini / iMac with ≥32 GB unified memory |
a model that fits both boxes: the FP8 V4-Flash does not fit one Spark, so pick an MLA-latent model that does — DeepSeek-V2-Lite (16B) is the obvious first |
recipe only, unmeasured |
| C · the kid's stack |
one used CUDA gaming card (8–24 GB) in a beat PC, vLLM or sglang |
an M-series iMac / MacBook with 16 GB |
the smallest MLA-latent model that fits both |
recipe only, unmeasured |
What is identical across all three rungs: the front door, the verdict header, the cold/warm decision, the
block writer path, the benchmark protocol, the wire (ordinary Ethernet — ~10 KB/token means even 1 GbE
moves a 30K-token prompt in ~0.3 s). What changes when you move down: the model, and therefore the pooling
math in the capture hook (DeepSeek-V4-Flash's hook is specific to its sparse attention; a plain-MLA model
like V2-Lite is simpler — its per-layer cache is the K/V rows themselves). docs/PORTING.md names the
four seams you touch and has a two-question feasibility test that takes ten minutes.
What to expect at the bottom rung, honestly: the win is the ratio of prefill speeds. A used 3090 prefills a
16B MLA model far faster than a 16 GB Mac does, so the shape of the result should hold; the absolute
numbers will be smaller because the prompts and models are smaller. We have not run rungs B or C
ourselves. They are the first ports we want to see, a negative result is a result, and we will feature
whoever lands one. Open an issue.
The point of this repo is that the privilege travels down. Take it apart.
Running it
Prerequisites
| side |
hardware |
software |
model |
| prefill |
2× NVIDIA DGX Spark (GB10, 128 GB each) on a 200G RoCE link (TP2) |
Docker + the sparkrun vLLM image with the DeepSeek-V4 plugin (aidendle94/sparkrun-vllm-ds4-gb10:production-ready, vLLM 0.21.1rc1) |
deepseek-ai/DeepSeek-V4-Flash (official FP8 checkpoint, ~149 GB) |
| decode |
1× Mac Studio M3 Ultra, 256 GB |
oMLX 0.6.4 in a venv + the one-file patch in studio/ |
an MLX MXFP4-experts / MXFP8-attention conversion of deepseek-ai/DeepSeek-V4-Flash-0731 (~156 GB; any bit-exact conversion works — ours keeps the DSpark MTP heads) |
| link |
any Ethernet ≥10 GbE between the two |
SSH key from the Mac to the prefill head; Python 3.10+ on both |
— |
The official FP8 checkpoint is ~149 GB, so it does not fit one 128 GB Spark: prefill is tensor-parallel
across two Sparks over their direct ConnectX-7 link (the standard two-Spark cable — box to box, no switch
involved). The only traffic that crosses to the Mac is HTTP over ordinary Ethernet, through whatever switch
you have. The numbers in RESULTS.md are TP2 over a 10 GbE LAN.
The Mac-side model. We run a local, bit-exact MLX conversion of deepseek-ai/DeepSeek-V4-Flash-0731
(MXFP4 experts, MXFP8 attention, DSpark MTP heads kept). There is no single published id to point at, so
produce your own; the closest one-liner is
mlx_lm.convert --hf-path deepseek-ai/DeepSeek-V4-Flash-0731 --mlx-path ~/models/DV4-Flash-MXFP4-MLX \
  -q --q-mode mxfp4 --q-bits 4 --q-group-size 32
(unverified by us end to end — our build was a mixed conversion). What matters for the bridge is
self-consistency, not which conversion: make weights exports the attention-projection weights from
your MLX model, and the prefill hook uses exactly those, so the pooled tensors match whatever the decoder
actually runs.
cp config.example.env config.env && $EDITOR config.env   # nothing has a working default
source config.env
1. Export the decoder's projection weights (on the Mac, in the oMLX venv). These are what the
prefill hook uses, so that the pooled tensors match the decoder's arithmetic rather than the
prefill engine's:
$OMLX_PYTHON studio/pd_export_proj_weights.py --model "$PD_MODEL" --out "$PD_V3"
Copy $PD_V3 (pd_pool_torch.py, dv4_proj_weights.*, capture_sitecustomize_v3.py) to both
prefill nodes.
2. Start the prefill pair (rank 0 = TP head, rank 1 = worker):
./spark/pd-launch-v3.sh 1     # worker first
./spark/pd-launch-v3.sh 0     # then head
python3 spark/pd_share.py "$PD_CAPTURE_DIR" 8010        # pooled mode (the one the numbers use)
# or: python3 spark/pd_capture_http.py --root "$PD_CAPTURE_DIR" --port 8010   # Range-capable; needed by the older 'hidden' pipelined mode
3. Patch and start oMLX, then the front door (on the Mac):
# oMLX must notice blocks written after model load — one small patch, applied once, in the oMLX venv:
OMLX_PKG=$($OMLX_PYTHON -c 'import omlx,os;print(os.path.dirname(omlx.__file__))')   # .../site-packages/omlx
patch -p0 -d "$OMLX_PKG/cache" < "$OLDPWD/studio/omlx-0.6.4-paged_ssd_cache-disk-index-fallback.patch"
# then (re)start oMLX serving $PD_MODEL on :8011, and start the front door:
$OMLX_PYTHON studio/pd_front.py          # listens on $PD_PORT (8012), OpenAI-compatible
curl -s localhost:8012/health             # {"ok": true, "front": "pd", ...}
Point any OpenAI-compatible client at :8012. Prompts under PD_MIN_TOKENS or with fewer than
PD_MIN_TAIL uncached tokens go straight to oMLX; longer cold prompts are prefilled on the Sparks. The
X-PD-Bridge response header says which happened. make doctor checks every link in the chain.
4. Benchmark:
python3 bench/bench_cold.py --chars 330000 --seed 301 --url http://<decoder>:8012   # bridged
python3 bench/bench_cold.py --chars 330000 --seed 302 --url http://<decoder>:8011   # native
Plain-attention models over RDMA
A dense GQA model (Qwen3, Llama, Mistral, …) needs no pooling port: its decoder cache is the prefill engine's own
K/V rows. PD_MODE=kv uses an official vLLM KV connector to cut those rows into oMLX-native block files on the GPU,
pushes them over RoCEv2 while the prefill runs, and hands oMLX a staged cache plus the tail rows, so the decoder
prefills one token. Reference: Qwen3-32B bf16, one DGX Spark → Mac Studio M2 Ultra (Mac NIC via
MelonDMA) — TTFT 43.9 s at 33K tokens with the engine at 42.6 s,
~4.4× the native oMLX rate measured at ~32K. Setup, porting checklist and verification: docs/RDMA.md.
Gotchas that cost us hours
The bridge was fluent and WRONG above the native window for days (2026-09-08)
This is the most important thing in this file if you are raising the context window.
The capture hook builds the decoder's rope table from its own projection sidecar
(pd_v3/dv4_proj_weights.json). When we grew the served window 1M -> 2M we updated the engine flags
and the per-node model config.json, but not the sidecar. It kept YaRN factor 16 /
max_position 1,048,576 while the decoder ran factor 32 / 2,097,152.
YaRN is numerically identical below original_max_position_embeddings (65,536) and diverges
above it. So every test at or under ~65K passed, and everything above it was quietly corrupt —
verdict complete, position_gaps False, manifest T matching the request, and the model unable to
retrieve a midpoint needle. Measured before the fix: MISS at 98,779 / 148,134 / 189,031 / 287,842 /
385,838 — five for five. After correcting the factor: PASS at 189K, at 200K on a cold cache, and
at 386K.
The window lives in FOUR places. All of them must agree:
- the launch parameters (
PD_MAX_MODEL_LEN, PD_ROPE_FACTOR)
- each prefill node's model
config.json rope_scaling
pd_v3/dv4_proj_weights.json rope_scaling + max_position_embeddings — the one we missed- the decoder's
config.json
LAW: a window change is not done until a needle is retrieved THROUGH THE BRIDGE above the native
window. Our previously published "verified ceiling" had been measured on the native fallback path
(the capture share happened to be down that day), so the bridged path's correctness at depth had
never actually been tested.
Two traps that produce false verdicts:
- A reused seed reintroduces the bug you just fixed. Our first post-fix retest MISSED and meant
nothing: the document shared its first ~100K tokens with an earlier run, so the decoder served
88,064 tokens of cached blocks built under the old rope. After any change to rope, projection
weights or capture format, verify with a FRESH SEED.
- The decoder's block cache has no notion of rope config. It is keyed by token prefix only.
Fixing the config does not repair what is already cached — move the cache aside (rename, do not
delete) or you will keep serving the old geometry.
And one in the harness itself: needle.py --max-tokens defaulted to 48. When the model spends
that budget reasoning, content comes back empty and the harness scores a MISS. A 120K run
"failed" at 48 and passed at 300 on the same document. Default raised to 300.
- Prefix caching must be OFF on the prefill engine. With it on, vLLM skips a repeated document
prefix, the hook sees
43 layers x 0 tokens, and the decoder waits forever for rows that will
never arrive. The decoder owns the caches; the prefill engine must compute every token it pools.
--enforce-eager. Prefill-only engine: CUDA graphs buy nothing and cost ~13 min of boot. The
first async version of the hook also invalidated vLLM's graph capture at startup
(cudaErrorStreamCaptureInvalidated); guard any hook with torch.cuda.is_current_stream_capturing().- Keep exactly one model build resident on the decoder. Two builds in oMLX's pool exceeded the
admission target and cost a ~33 s evict-and-reload on every request that targeted the other one.
It looks exactly like a bridge regression and is not.
- Restart order matters. Stop the old oMLX server and wait for its shutdown line before
starting a new one, or the new server's first load hits a memory settle barrier and aborts.
NCCL_IB_GID_INDEX is fabric-specific. Ours is 5; the common recipe says 3. Check show_gids.- Same math is not the same bits. Computing the 128-row window on a 128-row slice differs by one
bf16 ulp from taking those rows out of the 2048-row chunk matmul — MXFP4 kernel tiling. Slice from
the chunk computation. Relatedly, MLX's bf16
sum is serial for 8 rows and 32 strided bf16
partials combined in f32 for 128 rows; plain f32 accumulation matched only ~50% of elements.
- An idle-flush capture hook and chunked prefill are a dangerous pair. With
--max-num-batched-tokens 8192 the engine grinds ~4 s per chunk; a 2 s idle watcher fires
between chunks (or inside a chunk's enqueue burst) and ships a DONE manifest for a request that
is still running. Guard the flush with a CUDA-event query (GPU busy = mid-request) and a
chunk-alignment check (calls % n_layers == 0), and make the consumer validate manifest T == request T before trusting any DONE. This cost us a whole benchmark round: docs/FINDING-bench4-cold-fallback.md.
- Benchmark with a real token budget. A 64-token cap truncated answers mid-reasoning and read as
a retrieval failure on both paths.
Contributing
The most useful things anyone could add, roughly in order:
Kill the quadratic snapshot memory — done 2026-09-06 (streaming boundary store; see
Known limits and RESULTS.md). The bridge is validated to 109K tokens on a 256 GB machine.- A second model. The bridge shape should generalize to any MLA/sparse-attention model whose
caches are a pure function of the attention input. Porting the pooling math is the work.
- Stream the capture over a socket instead of staging it on the prefill node's NVMe.
- Ship the decoder's carry state to the prefill engine so warm-but-extended prompts can prefill
only the tail instead of the whole thing.
- Finish the judged quality eval on the bridged leg (
bench/BENCHMARK-PROTOCOL.md).
- Make the engine patches survive upstream. Both would be better as small upstream hooks than
as monkey patches — a cache-rescan API on the oMLX side especially.
Benchmark numbers in a PR must follow bench/BENCHMARK-PROTOCOL.md, including a native baseline on
the same hardware and a warm engine on both legs.
Credits
oMLX for the decoder and its cache format; the vLLM DeepSeek-V4 plugin and the sparkrun GB10 image;
EXO Labs, whose DGX Spark + Mac Studio prefill/decode result set the reference point this builds on;
and the Spark↔Mac USB4/RDMA work that made joining the two silicon families look worth trying.
Apache-2.0.

 pd-bridge 把一个 DeepSeek-V4-Flash 请求拆到两台机器上处理:prefill(预填充)跑在 NVIDIA DGX Spark 上(CUDA/vLLM),decode(解码)跑在 Mac Studio 上(Metal/oMLX),两者之间用普通的 10GbE 以太网连接。