dalle-mini README

The project's README from github.com/borisdayma/dalle-mini. As one markdown file: README.md.

DALL·E Mini

How to use it?

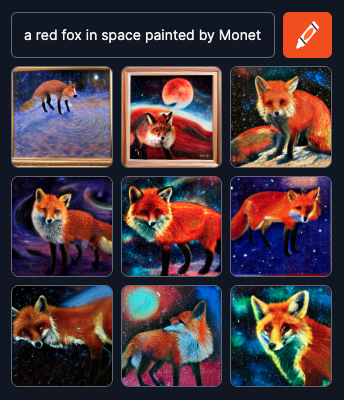
You can use the model on 🖍️ craiyon

How does it work?

Refer to our reports:

Development

Dependencies Installation

For inference only, use pip install dalle-mini.

For development, clone the repo and use pip install -e ".[dev]". Before making a PR, check style with make style.

You can experiment with the pipeline step by step through our inference pipeline notebook

Open In Colab

Training of DALL·E mini

Use tools/train/train.py.

You can also adjust the sweep configuration file if you need to perform a hyperparameter search.

FAQ

Where to find the latest models?

Trained models are on 🤗 Model Hub:

Where does the logo come from?

The "armchair in the shape of an avocado" was used by OpenAI when releasing DALL·E to illustrate the model's capabilities. Having successful predictions on this prompt represents a big milestone for us.

Contributing

Join the community on the LAION Discord. Any contribution is welcome, from reporting issues to proposing fixes/improvements or testing the model with cool prompts!

You can also use these great projects from the community:

Acknowledgements

Authors & Contributors

DALL·E mini was initially developed by:

Many thanks to the people who helped make it better:

Citing DALL·E mini

If you find DALL·E mini useful in your research or wish to refer, please use the following BibTeX entry.

@misc{Dayma_DALL·E_Mini_2021,
      author = {Dayma, Boris and Patil, Suraj and Cuenca, Pedro and Saifullah, Khalid and Abraham, Tanishq and Lê Khắc, Phúc and Melas, Luke and Ghosh, Ritobrata},
      doi = {10.5281/zenodo.5146400},
      month = {7},
      title = {DALL·E Mini},
      url = {https://github.com/borisdayma/dalle-mini},
      year = {2021}
}

References

Original DALL·E from "Zero-Shot Text-to-Image Generation" with image quantization from "Learning Transferable Visual Models From Natural Language Supervision".

Image encoder from "Taming Transformers for High-Resolution Image Synthesis".

Sequence to sequence model based on "BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension" with implementation of a few variants:

Main optimizer (Distributed Shampoo) from "Scalable Second Order Optimization for Deep Learning".

Citations

@misc{
  title={Zero-Shot Text-to-Image Generation}, 
  author={Aditya Ramesh and Mikhail Pavlov and Gabriel Goh and Scott Gray and Chelsea Voss and Alec Radford and Mark Chen and Ilya Sutskever},
  year={2021},
  eprint={2102.12092},
  archivePrefix={arXiv},
  primaryClass={cs.CV}
}
@misc{
  title={Learning Transferable Visual Models From Natural Language Supervision}, 
  author={Alec Radford and Jong Wook Kim and Chris Hallacy and Aditya Ramesh and Gabriel Goh and Sandhini Agarwal and Girish Sastry and Amanda Askell and Pamela Mishkin and Jack Clark and Gretchen Krueger and Ilya Sutskever},
  year={2021},
  eprint={2103.00020},
  archivePrefix={arXiv},
  primaryClass={cs.CV}
}
@misc{
  title={Taming Transformers for High-Resolution Image Synthesis}, 
  author={Patrick Esser and Robin Rombach and Björn Ommer},
  year={2021},
  eprint={2012.09841},
  archivePrefix={arXiv},
  primaryClass={cs.CV}
}
@misc{
  title={BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension}, 
  author={Mike Lewis and Yinhan Liu and Naman Goyal and Marjan Ghazvininejad and Abdelrahman Mohamed and Omer Levy and Ves Stoyanov and Luke Zettlemoyer},
  year={2019},
  eprint={1910.13461},
  archivePrefix={arXiv},
  primaryClass={cs.CL}
}
@misc{
  title={Scalable Second Order Optimization for Deep Learning},
  author={Rohan Anil and Vineet Gupta and Tomer Koren and Kevin Regan and Yoram Singer},
  year={2021},
  eprint={2002.09018},
  archivePrefix={arXiv},
  primaryClass={cs.LG}
}
@misc{
  title={GLU Variants Improve Transformer},
  author={Noam Shazeer},
  year={2020},
  url={https://arxiv.org/abs/2002.05202}    
}
 @misc{
  title={DeepNet: Scaling transformers to 1,000 layers},
  author={Wang, Hongyu and Ma, Shuming and Dong, Li and Huang, Shaohan and Zhang, Dongdong and Wei, Furu},
  year={2022},
  eprint={2203.00555}
  archivePrefix={arXiv},
  primaryClass={cs.LG}
} 
@misc{
  title={NormFormer: Improved Transformer Pretraining with Extra Normalization},
  author={Sam Shleifer and Jason Weston and Myle Ott},
  year={2021},
  eprint={2110.09456},
  archivePrefix={arXiv},
  primaryClass={cs.CL}
}
@inproceedings{
  title={Swin Transformer V2: Scaling Up Capacity and Resolution}, 
  author={Ze Liu and Han Hu and Yutong Lin and Zhuliang Yao and Zhenda Xie and Yixuan Wei and Jia Ning and Yue Cao and Zheng Zhang and Li Dong and Furu Wei and Baining Guo},
  booktitle={International Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2022}
}
@misc{
  title = {CogView: Mastering Text-to-Image Generation via Transformers},
  author = {Ming Ding and Zhuoyi Yang and Wenyi Hong and Wendi Zheng and Chang Zhou and Da Yin and Junyang Lin and Xu Zou and Zhou Shao and Hongxia Yang and Jie Tang},
  year = {2021},
  eprint = {2105.13290},
  archivePrefix = {arXiv},
  primaryClass = {cs.CV}
}
@misc{
  title = {Root Mean Square Layer Normalization},
  author = {Biao Zhang and Rico Sennrich},
  year = {2019},
  eprint = {1910.07467},
  archivePrefix = {arXiv},
  primaryClass = {cs.LG}
}
@misc{
  title = {Sinkformers: Transformers with Doubly Stochastic Attention},
  url = {https://arxiv.org/abs/2110.11773},
  author = {Sander, Michael E. and Ablin, Pierre and Blondel, Mathieu and Peyré, Gabriel},
  publisher = {arXiv},
  year = {2021},
}
@misc{
  title = {Smooth activations and reproducibility in deep networks},
  url = {https://arxiv.org/abs/2010.09931},
  author = {Shamir, Gil I. and Lin, Dong and Coviello, Lorenzo},
  publisher = {arXiv},
  year = {2020},
}
@misc{
  title = {Foundation Transformers},
  url = {https://arxiv.org/abs/2210.06423},
  author = {Wang, Hongyu and Ma, Shuming and Huang, Shaohan and Dong, Li and Wang, Wenhui and Peng, Zhiliang and Wu, Yu and Bajaj, Payal and Singhal, Saksham and Benhaim, Alon and Patra, Barun and Liu, Zhun and Chaudhary, Vishrav and Song, Xia and Wei, Furu},
  publisher = {arXiv},
  year = {2022},
}

dalle-mini (borisdayma/dalle-mini)

Searching Database…

What is this?DALL·E Mini is an open-source model that generates images from a text prompt, built as a smaller, reproducible version of OpenAI's DALL·E.
Is this a ready-made app or a model I run myself?It's a Python library and training codebase for a text-to-image model; you either pip install it for inference or clone the repo to train/develop it.
How do I try generating images without setting anything up?The easiest way is to use the hosted demo at craiyon, no installation needed.
Where do I get the pretrained models from?Trained models (VQGAN for encoding/decoding images, and DALL·E mini/mega for text-to-image) are hosted on the Hugging Face Model Hub.
Is this the same quality as the real DALL·E?Not stated directly, but the name 'mini' and its community origin (built during a Hugging Face FLAX/JAX hackathon) imply a much smaller, less capable model than OpenAI's original DALL·E.
Why is the logo an avocado armchair?It references OpenAI's original DALL·E demo, where 'an armchair in the shape of an avocado' was the showcase prompt; successfully generating it was treated as a milestone.
Are there alternative apps built on this project?Yes, the community built related projects like DALL-E Playground and DALL·E Flow (which adds diffusion and upscaling in a human-in-the-loop workflow), and it can also run on Replicate via browser or API.
What research is the model based on?It combines ideas from OpenAI's original DALL·E (zero-shot text-to-image), CLIP-style image quantization, VQGAN image encoding, and a BART-based sequence-to-sequence architecture with several transformer variant improvements.
Creator
borisdayma
Size
18.3 MB
Stars
14.7K
Age
5y
Commits · 90 Days
