

这是什么?
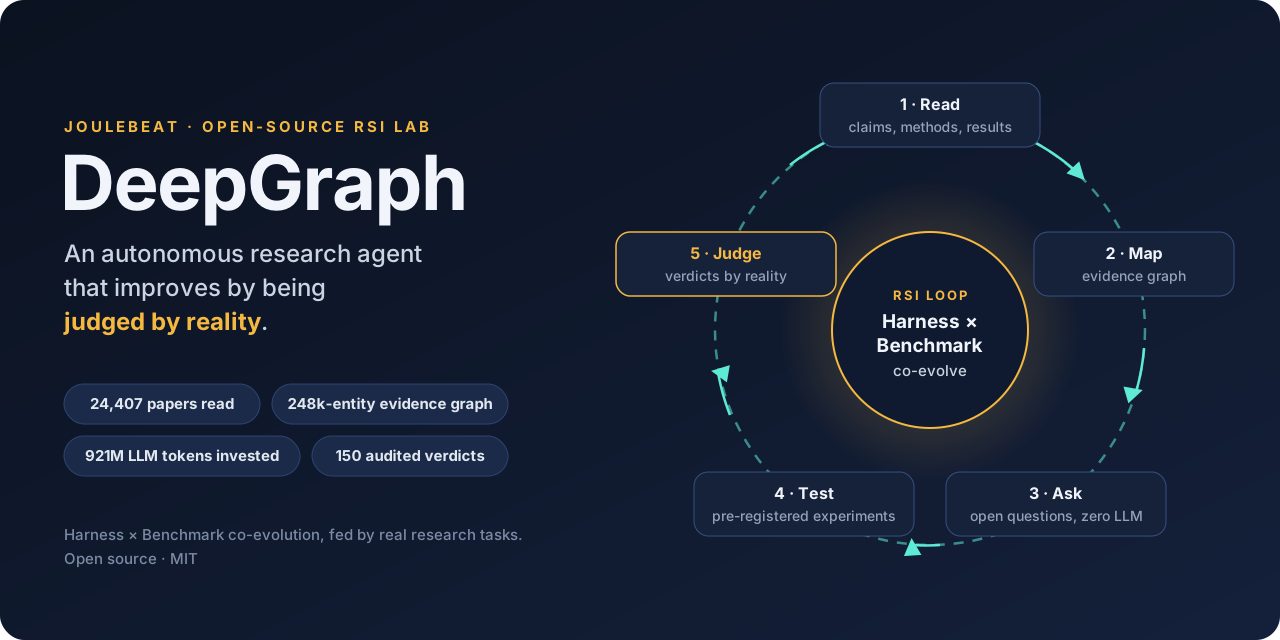
 DeepGraph 是开源 AI 自我改进(RSI)实验室 JouleBeat 的自主研究智能体。它阅读科学文献、寻找未解问题、运行真实实验,让结果来判定什么才是真的。
这是独立应用,还是更像一条流水线?它是一条端到端的研究流水线:把 arXiv 论文采集进证据知识图谱,用纯 SQL(不靠 LLM)检测未解问题,再把问题转化为有预算约束的实验,由证据阶梯来评判。
它是一条端到端的研究流水线:把 arXiv 论文采集进证据知识图谱,用纯 SQL(不靠 LLM)检测未解问题,再把问题转化为有预算约束的实验,由证据阶梯来评判。怎么把它跑起来?快速上手需要 Python 3.12+ 和一个 LLM API 密钥;若要搭建带 PostgreSQL、systemd 和远程 GPU 后端的完整控制平面,请参照 docs/DEPLOY.md 中的部署指南。
快速上手需要 Python 3.12+ 和一个 LLM API 密钥;若要搭建带 PostgreSQL、systemd 和远程 GPU 后端的完整控制平面,请参照 docs/DEPLOY.md 中的部署指南。需要先建好数据库吗,还是可选的?最小化快速上手时 PostgreSQL 是可选的,但要解锁完整控制平面、systemd 部署和远程 GPU 后端就必须有它。
最小化快速上手时 PostgreSQL 是可选的,但要解锁完整控制平面、systemd 部署和远程 GPU 后端就必须有它。它产出的每个结论都可信吗?这套系统靠自我审计而非保证每次运行都正确:2026 年 8 月,它发现并撤回了 11 条基于空模型输出的自身结论。
这套系统靠自我审计而非保证每次运行都正确:2026 年 8 月,它发现并撤回了 11 条基于空模型输出的自身结论。它究竟面向谁?它为想要可验证计算结论的研究人员而构建,同时也充当 JouleBeat 自身研发智能体框架和基准的迭代闭环。
它为想要可验证计算结论的研究人员而构建,同时也充当 JouleBeat 自身研发智能体框架和基准的迭代闭环。Evolution Kernel 是什么?它是 JouleBeat 技术栈背后的开源引擎,负责提出、评估、接受或回滚对框架和基准的更改。可通过 pip install evolution-kernel 单独安装。
它是 JouleBeat 技术栈背后的开源引擎,负责提出、评估、接受或回滚对框架和基准的更改。可通过 pip install evolution-kernel 单独安装。它在没有 LLM 参与的情况下如何发现未解的研究问题?十个结构检测器用纯 SQL 查询证据图谱来挖掘未解问题,这一步刻意不引入 LLM,以保证确定性和可审计性。
十个结构检测器用纯 SQL 查询证据图谱来挖掘未解问题,这一步刻意不引入 LLM,以保证确定性和可审计性。到目前为止 DeepGraph 实际产出了什么?根据其 2026 年 8 月的生产数据,它已采集 24,407 篇论文(7,005 篇完成全流程处理),构建了包含 248,441 个实体和 735,913 条关系的图谱,并在六大研究议程下给出 150 份经审计的实验裁定。
根据其 2026 年 8 月的生产数据,它已采集 24,407 篇论文(7,005 篇完成全流程处理),构建了包含 248,441 个实体和 735,913 条关系的图谱,并在六大研究议程下给出 150 份经审计的实验裁定。JouleBeat 为什么构建这个,而不直接给模型做基准测试?JouleBeat 需要源源不断的真实、可核验的任务来评判新的智能体框架和基准;计算研究恰好提供了这一点,因为结论可以通过重新运行代码或数据来证实或证伪。
JouleBeat 需要源源不断的真实、可核验的任务来评判新的智能体框架和基准;计算研究恰好提供了这一点,因为结论可以通过重新运行代码或数据来证实或证伪。What are similar projects?Raven, awesome-rsi, rrsi, Proteus, wikiskill, AI-Scientist, KISS-Knowledge-Infrastructure-for-Scientific-Simulation, EvoScientist
Raven, awesome-rsi, rrsi, Proteus, wikiskill, AI-Scientist, KISS-Knowledge-Infrastructure-for-Scientific-Simulation, EvoScientistWhich topics is it in?recursive-self-improvement, reproducible-research, self-evolving-agents, ai-research, deep-research, science, arxiv, scientific-computing, llm-agents, papers, knowledge-graph, harness
recursive-self-improvement, reproducible-research, self-evolving-agents, ai-research, deep-research, science, arxiv, scientific-computing, llm-agents, papers, knowledge-graph, harness