12.6K ·GitHub
What is this?
 This is a collection of shell scripts that scrapes and aggregates tens of thousands of images across 5 categories (porn, hentai, sexy, neutral, drawings) to build a labeled dataset for training an NSFW image classifier.
Is this a trained model or just scripts?It is not an app or a ready model — it is a set of numbered shell scripts (1_get_urls.sh through 6_create_test.sh) you run in sequence to scrape, download, and organize the raw image dataset yourself.
It is not an app or a ready model — it is a set of numbered shell scripts (1_get_urls.sh through 6_create_test.sh) you run in sequence to scrape, download, and organize the raw image dataset yourself.How do I collect the dataset?Run the scripts under scripts/ in order: the first script grabs image URLs per category using the bundled Ripme app, the second downloads the actual images, and later scripts split everything into train/test folders.
Run the scripts under scripts/ in order: the first script grabs image URLs per category using the bundled Ripme app, the second downloads the actual images, and later scripts split everything into train/test folders.Do I need Docker or Python installed first?You need Docker to run the scraping pipeline, and fastai (installed via conda) if you also want to train the CNN classifier on the resulting dataset.
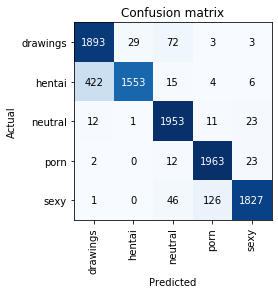
You need Docker to run the scraping pipeline, and fastai (installed via conda) if you also want to train the CNN classifier on the resulting dataset.Is the resulting dataset clean and ready to use?No, the author explicitly warns it's noisy, and in their own tests the drawings/hentai and porn/sexy categories were frequently confused with each other.
No, the author explicitly warns it's noisy, and in their own tests the drawings/hentai and porn/sexy categories were frequently confused with each other.What are the 5 image categories?Porn, hentai, sexy, neutral, and drawings — covering explicit content, suggestive-but-not-explicit images, and two safe-for-work categories used for contrast during training.
Porn, hentai, sexy, neutral, and drawings — covering explicit content, suggestive-but-not-explicit images, and two safe-for-work categories used for contrast during training.Where do the safe-for-work comparison images come from?Optional scripts pull SFW anime drawings from the Danbooru2018 database and SFW neutral photos from the Caltech256 dataset.
Optional scripts pull SFW anime drawings from the Danbooru2018 database and SFW neutral photos from the Caltech256 dataset.What is Ripme and why does the project need it?Ripme is a third-party downloader application the scripts call to actually scrape images from the source URLs, most of which point to various subreddits.
Ripme is a third-party downloader application the scripts call to actually scrape images from the source URLs, most of which point to various subreddits.Do I have to re-scrape the URLs myself?No — the author already ran the URL-collection script and committed its output under the rawdata directory, so you only need to rerun it if you edit the source URL lists.
No — the author already ran the URL-collection script and committed its output under the rawdata directory, so you only need to rerun it if you edit the source URL lists.What are similar projects?gallery-dl, waifu2x, X-AnyLabeling, fiftyone, label-studio, fashion-mnist, instaloader, FreePEP
gallery-dl, waifu2x, X-AnyLabeling, fiftyone, label-studio, fashion-mnist, instaloader, FreePEPWhich topics is it in?reddit, anime, scraper, image-classification, jupyter-notebook, image, dataset, web-scraping, data-science, shell, computer-vision, command-line-tool
reddit, anime, scraper, image-classification, jupyter-notebook, image, dataset, web-scraping, data-science, shell, computer-vision, command-line-tool