Fast and Accurate Code Search for Agents
Uses ~99% fewer tokens than grep+read
Semble is a code search library built for agents. It returns the exact code snippets they need instantly, using ~99% fewer tokens than grep+read. Indexing and searching a full codebase end-to-end takes under a second, matching the retrieval quality of a code-specialized transformer while indexing ~340x faster and querying ~17x faster (see benchmarks). Everything runs on CPU with no API keys, GPU, or external services. Use it as an MCP server, a CLI tool via AGENTS.md, or a dedicated sub-agent, and any coding agent (Claude Code, Cursor, Codex, OpenCode, etc.) gets instant access to any repo.
Quickstart
Your agent queries Semble in natural language (e.g. "How is authentication handled?") and gets back only the relevant code snippets, without grepping or reading full files.
The fastest way to get started is the interactive installer. Install uv, then run:
uv tool install semble
semble install
semble install detects installed coding agents such as Claude Code, Codex, and OpenCode, and then lets you choose which integrations to enable:
- MCP server: lets the agent call Semble directly as a tool.
- Instructions: adds CLI usage guidance to AGENTS.md / CLAUDE.md.
- Sub-agent: installs a dedicated
semble-search sub-agent.
To undo the setup, run semble uninstall.
For manual setup instructions (MCP config per agent, AGENTS.md snippet, sub-agent files), see the installation docs.
Updating Semble
uv tool upgrade semble   # upgrade
uv cache clean semble    # for MCP users (restart your MCP client after)
Unattended install
For sandboxed or scripted environments, skip the prompts with --agent and, optionally, --type:
semble install --agent claude --type mcp subagent --yes
--agent accepts one or more agent ids (e.g. claude, codex, pi); --type accepts mcp, instructions, subagent, or all (default: all); --yes skips the confirmation prompt (requires --agent for a fully non-interactive run).
Main Features
- Fast: indexes an average repo in ~500 ms and answers queries in ~1 ms, all on CPU.
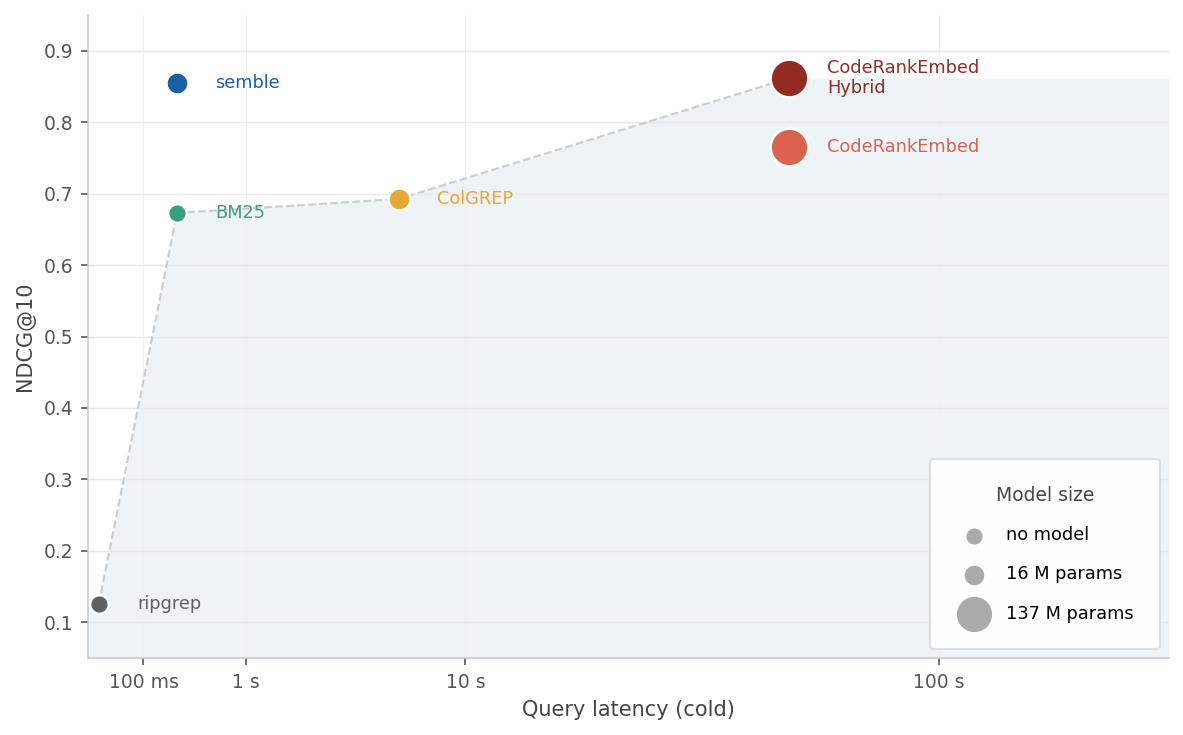
- Accurate: NDCG@10 of 0.854 on our benchmarks, on par with code-specialized transformer models, at a fraction of the size and cost.
- Token-efficient: returns only the relevant chunks, using ~99% fewer tokens than grep+read.
- Zero setup: runs on CPU with no API keys, GPU, or external services required.
- MCP server: works with Claude Code, Cursor, Codex, OpenCode, VS Code, and any other MCP-compatible agent.
- Local and remote: pass a local path or a git URL.
CLI
Semble also ships as a standalone CLI. This is useful in scripts or anywhere you want search results without an MCP session. Indexes are built and cached on first run, and invalidated automatically when files change.
# Search a local repo (index is built and cached automatically)
semble search "authentication flow" ./my-project

# Search a remote repo (cloned on demand)
semble search "save model to disk" https://github.com/MinishLab/model2vec

# Limit results
semble search "save model to disk" ./my-project --top-k 10

# Search docs/config/everything instead of just code
semble search "deployment guide" ./my-project --content docs   # or: config, all

# Find code similar to a known location
semble find-related src/auth.py 42 ./my-project

# Show only the first N lines of each result's snippet (0 = path/line range only)
semble search "authentication flow" ./my-project --max-snippet-lines 10
--content accepts code (default), docs, config, or all. path defaults to the current directory when omitted; git URLs are accepted. If semble is not on $PATH, use uvx --from "semble[mcp]" semble in its place. semble --version (or -V) prints the installed version.
Controlling which files are indexed
Semble reads .gitignore and .sembleignore files to determine which files to index. Both files use standard gitignore syntax and their patterns are merged. .sembleignore lets you add semble-specific rules without touching .gitignore. Rules are applied recursively, so a .sembleignore in a subdirectory applies to that subtree.
Excluding files: add patterns the same way you would in .gitignore:
# .sembleignore
generated/     # exclude generated dir
*.pb.go.       # exclude Go protobuf files
Including non-default extensions: prefix the extension pattern with ! to force-include files that semble wouldn't index by default:
# .sembleignore
!*.proto       # include Protobuf files
!*.cob         # include COBOL files
Semble also always skips a set of well-known non-source directories regardless of ignore files (e.g. node_modules/, .venv/, dist/, build/, __pycache__/, and similar).
Savings
semble savings shows how many tokens semble has saved across all your searches:
semble savings
  Semble Token Savings
  ════════════════════════════════════════════════════════════════════════

  Total saved:  ~714.2M tokens  (94%)
  Total calls:  14.3k
  Efficiency:  ███████████████████████░  94%

  By Period
  ────────────────────────────────────────────────────────────────────────
  Period             Calls           Saved  Ratio
  ────────────────────────────────────────────────────────────────────────
  Today                198    ~1.4M tokens  ███████████████████████░  95%
  Last 7 days        13.1k  ~707.2M tokens  ███████████████████████░  94%
  All time           14.3k  ~714.2M tokens  ███████████████████████░  94%

  By Call Type
  ────────────────────────────────────────────────────────────────────────
  #     Call type            Calls  Share
  ────────────────────────────────────────────────────────────────────────
  1.    search               14.1k  ████████████████    99%
  2.    find_related           205  █░░░░░░░░░░░░░░░     1%
  ════════════════════════════════════════════════════════════════════════
Savings are calculated as follows: for each call, semble records the total character count of the unique files containing returned chunks and the character count of the snippets returned. Estimated tokens saved is (file chars − snippet chars) / 4 (4 chars per token). This is a conservative estimate: the baseline is reading matched files in full, which is how coding agents often explore unfamiliar code.
Storage
By default, your Semble savings statistics and any saved indexes are stored in the OS cache folder (~/Library/Caches/semble/ on macOS, ~/.cache/semble/ on Linux, %LOCALAPPDATA%\semble\Cache\ on Windows). To override this location you can supply an environment variable SEMBLE_CACHE_LOCATION which should be the full path to the target cache location e.g. ~/my-folder/my-caches/semble.
Files larger than 1 MB are skipped during indexing to keep index builds lean. Skipped files are reported as a warning at index time. If you work with large generated or ingested documents, you can raise (or lower) this limit with the SEMBLE_MAX_FILE_BYTES environment variable (in bytes).
On first use, Semble also downloads the embedding model from Hugging Face and caches it in the standard Hugging Face cache (~/.cache/huggingface/ by default, or $HF_HOME if set); this only happens once and requires network access.
Use semble clear to remove cached data: semble clear index (saved indexes), semble clear savings (usage stats), semble clear orphans (indexes for repos no longer present on disk), or semble clear all (everything).
Library usage
Semble can also be used as a Python library for programmatic access, useful when building custom tooling or integrating search directly into your own code.
from semble import ContentType, SembleIndex

# Index a local directory (code only, the default)
index = SembleIndex.from_path("./my-project")

# Index docs and prose (markdown, rst, etc.)
index = SembleIndex.from_path("./my-project", content=ContentType.DOCS)

# Index everything (code, docs, and config)
index = SembleIndex.from_path("./my-project", content=[ContentType.CODE, ContentType.DOCS, ContentType.CONFIG])

# Index code and docs together
index = SembleIndex.from_path("./my-project", content=[ContentType.CODE, ContentType.DOCS])

# Index a remote git repository
index = SembleIndex.from_git("https://github.com/MinishLab/model2vec")

# Search the index with a natural-language or code query
results = index.search("save model to disk", top_k=3)

# Find code similar to a specific result
related = index.find_related(results[0], top_k=3)

# Each result exposes the matched chunk
result = results[0]
result.chunk.file_path   # "model2vec/model.py"
result.chunk.start_line  # 127
result.chunk.end_line    # 150
result.chunk.content     # "def save_pretrained(self, path: PathLike, ..."
MCP Server
Semble runs as an MCP server so agents can search any codebase directly as a native tool call. Repos are indexed on demand and cached; local paths are re-indexed automatically on file changes.
| Tool |
Description |
search |
Search a codebase with a natural-language or code query. Pass repo as a local path or an https:// git URL and content as code, docs, config, or all (default: code). |
find_related |
Given a file path and line number, return chunks semantically similar to the code at that location. |
For per-agent setup instructions, see the installation docs.
Benchmarks
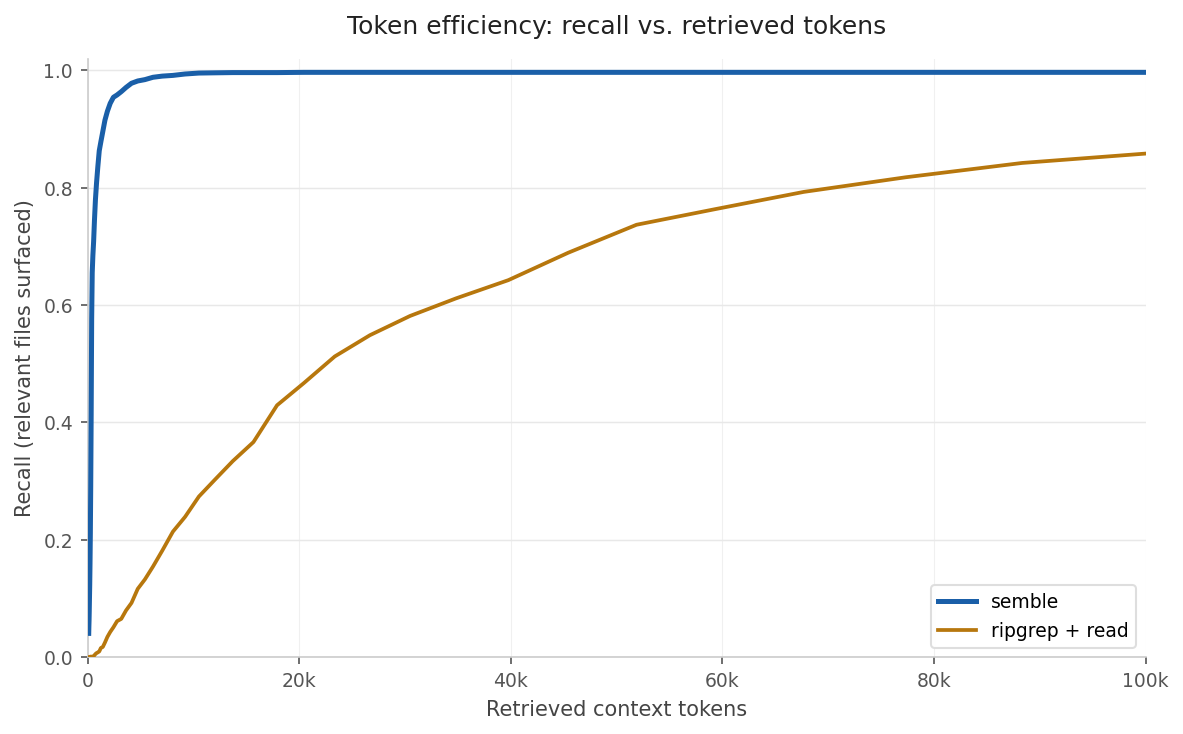
We benchmark quality and speed across ~1,250 queries over 63 repositories in 19 languages (left), and token efficiency against grep+read at equivalent recall levels (right).
The quality benchmark (left) scores retrieval quality (NDCG@10) against total latency; semble matches the quality of the 137M-parameter CodeRankEmbed while indexing 340x faster. The token efficiency benchmark (right) measures how many tokens each method needs to reach a given recall level; semble uses 99% fewer tokens on average and hits 97% recall at only 2k tokens, while grep+read needs a full 100k context window to reach 85%. See benchmarks for per-language results, ablations, and full methodology.
How it works
Semble splits each file into code-aware chunks using tree-sitter, then scores every query against the chunks with two complementary retrievers: static Model2Vec embeddings using the code-specialized potion-code-16M-v2 model for semantic similarity, and BM25 for lexical matches on identifiers and API names. The two score lists are fused with Reciprocal Rank Fusion (RRF).
After fusing, results are reranked with a set of code-aware signals:
Ranking signals
- Adaptive weighting. Symbol-like queries (
Foo::bar, _private, getUserById) get more lexical weight, while natural-language queries stay balanced between semantic and lexical retrievers.
- Definition boosts. A chunk that defines the queried symbol (a
class, def, func, etc.) is ranked above chunks that merely reference it.
- Identifier stems. Query tokens are stemmed and matched against identifier stems in a chunk, giving an additional weight to chunks that contain them. For example, querying
parse config boosts chunks containing parseConfig, ConfigParser, or config_parser.
- File coherence. When multiple chunks from the same file match the query, the file is boosted so the top result reflects broad file-level relevance rather than a single out-of-context chunk.
- Noise penalties. Test files,
compat//legacy/ shims, example code, and .d.ts declaration stubs are down-ranked so canonical implementations surface first.
Because the embedding model is static with no transformer forward pass at query time, all of this runs in milliseconds on CPU.
Indexes are cached to disk automatically on the first search. On subsequent runs, Semble walks the file tree and compares modification times; added, removed, or changed files are reindexed incrementally, without rebuilding the rest of the index. A full rebuild only happens if the indexing settings change (e.g., after a semble upgrade that changes the model, chunking, or cache format). In MCP mode, the index is checked and refreshed automatically as files change, so results stay current across the session.
Using a custom model
If you would like to use another model, you can set your SEMBLE_MODEL_NAME environment variable to a local path or Hugging Face repository. This path is read verbatim, and should contain a Model2Vec compatible model. This is particularly useful if you can't access Hugging Face at runtime.
Acknowledgements
Thanks to Greptile for providing free access to their AI code review platform.
License
MIT
Citing
If you use Semble in your research, please cite the following:
@software{minishlab2026semble,
  author       = {{van Dongen}, Thomas and Stephan Tulkens},
  title        = {Semble: Fast and Accurate Code Search for Agents},
  year         = {2026},
  publisher    = {Zenodo},
  doi          = {10.5281/zenodo.19785932},
  url          = {https://github.com/MinishLab/semble},
  license      = {MIT}
}



 Semble 是一个为编程智能体打造的代码搜索库。它会针对查询直接返回准确相关的代码片段,不需要智能体用 grep 查找再逐个读取完整文件,相比 grep+read 大约能少用 99% 的 token。