Google Maps Scraper Kit





Quick start ·
Use with an AI agent ·
Features ·
Compare ·
Recipes ·
FAQ
Last verified working: 2026-11-01, fresh install of v2.1.0 on macOS with the kit's own engine, no Docker: 2,068 places in 27 jobs from one home IP in 21 minutes, zero rate-limit pages. Also runs on Linux (amd64 and arm64), Windows and Docker.
A free, open-source Google Maps scraper for lead generation that runs on your own machine.
Name a business type and a city. Get back an outreach-ready CSV with name, phone, email, website,
category, address, rating and review count, plus Instagram, Facebook, LinkedIn, TikTok, YouTube and X
links when the site shows them. Add --no-socials to skip those, or --no-website for the businesses
that still need a site.
No Google Maps API key, no SaaS credits, no data leaving your computer. One command starts the
engine, with or without Docker. Then run it from the terminal, or let Claude Code, Codex or Cursor
drive it for you in plain English.
⚡
100 leads + emails
in 44 seconds, measured |
📧
Emails + 6 socials
on by default, zero AI tokens |
🗺️
Past Google's 120 cap
--grid and --deep-scan |
🔒
100% local
no API key, no credits, no Docker |
Sponsored by Swiftproxy and SerpApi. Paid placements; details below.
Quick start
Requires Python 3.9 or newer and Google Chrome (or Chromium, Edge or Brave). The engine and the
scripts use the Python standard library by default. Optional website rendering adds Playwright
(setup); the basic crawl needs no pip install. No browser
installed? The first start downloads Chrome for Testing once, about 100 MB, checked against a pinned
SHA-256.
Open a terminal (macOS: Terminal; Windows: PowerShell) and run these four lines:
git clone https://github.com/Mahanaicoach/google-maps-scraper-kit.git
cd google-maps-scraper-kit
python3 scripts/engine.py start
python3 scripts/scrape.py "coffee shops in Austin TX" 30.2672 -97.7431 --depth 2
Port 8080 taken? Run cp .env.example .env, set SCRAPER_PORT=8081 (any free port) in it, and start again.
Then use that port wherever these docs say 8080.
On Windows, type py in place of python3. Stop the engine with python3 scripts/engine.py stop.
Prefer Docker? Replace the third line with docker compose up -d, with
Docker Desktop installed and open. If the native
engine is running, stop it first (python3 scripts/engine.py stop). The two keep separate job lists,
so jobs started in one do not show in the other. The first run builds the engine image, about a
minute. It is the same engine on the same port, so every other command stays the same.
Prefer clicking? http://localhost:8080 has a form; each job gives a Leads CSV (the 8 lead fields and
socials, junk emails dropped), the full raw CSV or JSON.
Already running another copy of the kit on this machine? Set SCRAPER_PORT in .env first
(SETUP §6, "second copy").
No coordinates handy? Let the Python CLI geocode the city:
python3 scripts/scrape.py "dentists in Denver CO" --city "Denver, CO" --depth 5
Each --depth step loads one more batch of about 20 places: --depth 2 returns about 40, --depth 5
up to about 100, near Google's cap of about 120 per search. Need the whole city? Add --grid 3:
python3 scripts/scrape.py "dentists in Denver CO" --city "Denver, CO" --grid 3
Want every listing, not just a grid's worth? --deep-scan (the ! option: slower) runs the grid, then
splits every tile that came back at Google's cap into four sub-tiles one zoom level in, deduped:
python3 scripts/scrape.py "restaurants in Denver CO" --city "Denver, CO" --deep-scan
Example output
results-<short job id>.csv from the first command above (pass --out to name it yourself).
Illustrative rows. The file also has six social columns after these eight (see below):
| title |
phone |
emails |
website |
category |
address |
review_rating |
review_count |
| Example Roasters |
+1 512-555-0101 |
[email protected] |
example.com |
Coffee shop |
100 Congress Ave, Austin, TX |
4.7 |
312 |
| Sample Espresso Bar |
+1 512-555-0102 |
[email protected] |
example.org |
Cafe |
200 S Lamar Blvd, Austin, TX |
4.5 |
128 |
review_count works in headless mode; see Honest limits.
--browser-sites enables optional Playwright retries when HTTP finds no emails or social profile
links. It renders JavaScript and shares the rendered homepage between both passes. Output adds
website_fetch_status: http, rendered, blocked, timeout, budget_exhausted or error.
See optional setup.
The social columns instagram, facebook, linkedin, tiktok, youtube and x come after the eight
lead fields by default. --no-socials drops them. --tech adds
fb_pixel, google_ads_tag, analytics, bing_ads, linkedin_insight, tiktok_pixel, cms,
mobile_friendly and intent_score, and sorts the hottest leads first. --verify-emails adds
email_host. --full keeps every raw column, including coordinates, place IDs, all categories, the
week's opening hours and whether the place is open now.
Full walkthrough, platform notes and troubleshooting: SETUP.md.
Swiftproxy - Residential proxies for Google Maps scraping
90M+ residential IPs across 220+ locations, rotating or static, over HTTP(S) and SOCKS5, so big
Google Maps and multi-city jobs keep running. Use code PROXY90 for 10% off.
Try Swiftproxy →
SerpApi - Google Maps API in JSON and Markdown
Access Google Maps listings, reviews, directions, and other public search data with SerpApi's Google
Maps API, delivered as clean, structured JSON and Markdown.
Try SerpApi →
Become a sponsor · Sponsors also appear in the sponsor box of every installed copy's web UI, read from assets/sponsors/sponsors.json.
Use it with Claude Code or any agent
The kit ships a Claude Code skill that teaches the
agent to run scripts/scrape.py for every scrape, what the output holds, and the rate-limit and
data-handling guardrails.
It also works with Codex, Cursor and any other Agent Skills-compatible tool.
Option A: open the folder in Claude Code. The skill and four slash commands load automatically.
cd google-maps-scraper-kit
claude
Option B: install the skill into an agent you already use.
npx skills add mahanaicoach/google-maps-scraper-kit
This installs the skill file only. The engine and scripts/scrape.py ship with the kit, so the
agent first asks you to install it (the Quick start) and then works from its folder.
The slash commands come with Option A.
Then ask in plain language:
Scrape gyms in Miami and give me phones, emails and websites.
The agent checks the engine is up and starts it if not, runs scripts/scrape.py in the background
(it creates, waits for and saves the job), and hands you a clean table of the 8 lead fields plus the file.
| Slash command (Claude Code) |
Action |
/scrape <business> in <city, ST> [depth] |
Run one scrape, return a clean table and CSV |
/scrape-batch <keywords-file> [--city "City, ST"] |
Run many queries as one job |
/scrape-setup |
Start the engine and run a health check |
/scrape-jobs [list | delete <id>] |
List or delete jobs |
Plain requests trigger the skill too: "build me a lead list of plumbers in Phoenix". The skill
scrapes Google Maps business listings only. It does not scrape social platforms directly.
What you get
|
|
| 📇 8 lead fields by default |
name, phone, email, website, category, address, rating, review count, then the six social columns (--no-socials drops them). The engine writes 36 raw columns plus categories; --full keeps them all. |
| 📧 Email extraction, on by default |
After the Maps job, the script crawls every business website, 16 at a time: the homepage, then its contact and about pages if the homepage shows no email. It prints your found rate. |
| 🗺️ Beyond the 120 cap |
--grid 3 splits the city into 3 x 3 map tiles, runs them one at a time and dedupes on place_id. --deep-scan (! slower) goes further: any tile that comes back at the cap is split into 4 sub-tiles one zoom level in, so dense districts are searched block by block. |
| 🔗 Social enrichment, on by default |
Finds Instagram, Facebook, LinkedIn, TikTok, YouTube and X profiles in code (HTTP + regex), reusing the homepage the email crawl already fetched. Zero AI tokens. --no-socials skips it. |
| 🎯 Who already advertises |
--tech spots a Meta Pixel, Google Ads tag, analytics, Bing Ads, LinkedIn Insight and TikTok pixels on each website, plus its platform (WordPress, Shopify, Wix…) and mobile support, then ranks leads by an intent_score from 0 to 100. Zero AI tokens. |
| 🧹 Filters |
--no-website (businesses that still need a site), --min-rating, --min-reviews, --has-phone, --has-email, --limit. --exclude earlier.csv skips the places you already have, so a weekly re-run returns only new leads. |
| ✅ Email checks |
--verify-emails looks up each domain's MX record over DNS (no key), drops dead domains and labels the mail host (google_workspace, microsoft_365, other, none; blank when the row has no email). |
| 📍 Auto-geocoding |
Type a city name. Coordinates are resolved for you via OpenStreetMap. Repeat --city to run several cities into one file. |
| 📦 Batch jobs |
Many keywords, one job, one CSV. The engine lists a place found by several keywords once. |
| 🌐 Proxies |
For large or repeated runs: --proxy URL with http, https, socks5 or socks5h, and user:pass@ on http and https. Repeat it and the keywords take turns; a keyword Google refuses is retried through the next proxy. |
| 🤖 Agent-native |
A skill plus four slash commands. The agent runs the script and presents the lead fields; it never hand-builds API calls. |
| 🔒 Safe defaults |
API bound to 127.0.0.1, and the engine refuses requests from other websites in your browser (DNS rebinding, cross-site posts); an optional API key. No telemetry: the engine talks to Google Maps, and to the businesses' websites and dns.google only for jobs that ask. The web UI and engine.py status ask GitHub once a day whether a newer release is out, with nothing about you in the request (SCRAPER_NO_UPDATE_CHECK=1 in .env turns it off); nothing updates itself. Proxy passwords show as ***. A cell that a spreadsheet would run as a formula gets a leading ' in the engine's CSV download and in the script's file. Results git-ignored; website fetches skip private addresses; rate-limit and data-law guardrails built into the skill. |
Measured, not estimated
Fresh install of v2.1.0 on 2026-11-01: a MacBook, the installed Chrome, no Docker, no proxies, home internet. Every number below is one run, reproducible with the command shown.
| Command |
Result |
Wall time |
scrape.py "coffee shops in Austin TX" 30.2672 -97.7431 --depth 2 |
40 places, 11 emails, 16 with a social profile |
21 s |
scrape.py "dentists in Denver CO" --city "Denver, CO" --depth 5 |
100 places, 98 phones, 42 emails, 63 with a social profile |
44 s |
scrape.py "restaurants in Manhattan NY" 40.7580 -73.9855 --depth 20 --no-email --no-socials |
119 places (Google's cap) |
34 s |
scrape.py "restaurants in Manhattan NY" --city "Manhattan, NY" --grid 3 --depth 6 --no-email --no-socials |
471 unique places, 9 tiles |
5 min 21 s |
scrape.py "roofing contractors in Phoenix AZ" --city "Phoenix, AZ" --depth 3 --tech --verify-emails --min-rating 4.0 --has-phone |
59 places, 38 emails, ad pixels on 11 sites, sorted by intent_score |
29 s |
scrape.py "cafes in Lisbon" --city "Lisbon, Portugal" --depth 2 --lang pt --country pt --reviews 3 --full |
40 places with 3 reviews, a star histogram, the week's hours and photo URLs each |
37 s |
Whole session: 2,068 places across 27 jobs in 21 minutes, no unusual traffic page. Your results depend on the city, the hour and your IP. Open-source alternatives, with sources: docs/best-google-maps-scrapers.md.
Batch jobs and the Python CLI
scripts/scrape.py is a standalone, dependency-free Python CLI: single queries, batches, geocoding,
socials and CSV output. It works on macOS, Linux and Windows.
python3 scripts/scrape.py --keywords-file examples/queries.example.txt --city "Denver, CO"
One keyword per line. One job. One CSV.
Honest limits
- About 120 listings per search. Google Maps stops scrolling at roughly 120 results per search.
That is Google's cap, not the kit's.
--grid is the fix: it splits the city into N x N map tiles,
runs one job per tile, and dedupes the results on place_id. Tiles run one at a
time, so a grid is slower and more likely to trip rate limits than a single search. Each depth step
adds a batch of about 20 places.
- Review counts come with a changed user agent. Google gives a browser whose user agent says
HeadlessChrome its "limited view": no review counts, today's hours only, no reviews. So the
engine's headless Chrome sends its own user agent with HeadlessChrome replaced by Chrome (same
OS, same version, nothing else changed), and Google returns review_count, the week's
open_hours and reviews_link. Google can still leave a field out; if every count is missing,
--min-reviews warns and skips that filter. Review texts and the star histogram come with
--reviews N (up to 5 per place, one page load each). Business photo URLs come in images
(--full), with no extra page loads. Rather run a real window, with the agent unchanged? SETUP §3.
- Emails only when a business publishes one. The script reads the business homepage, then its
contact and about pages. Listings with no site, or a site with no visible
email, return an empty
emails cell. Social links come from the homepage, or from the contact
and about pages when the homepage has none. Instagram bios are not read. Expect emails on a fraction of
rows, not all of them.
- A wrong website on the listing gives no emails or socials. Some listings point at another
business's site (a plumber listed with a bank's homepage). A homepage that shows neither the
listing's phone number nor a word of its category is skipped for emails, social links and tech
flags, and the run says how many were skipped. Report, abuse and phishing inboxes are dropped too.
- Rate limits are real. Heavy use without proxies can get your IP temporarily rate-limited by
Google for minutes to hours. When Google answers with its unusual-traffic page, the engine waits
and retries the keyword up to 2 times, then stops the job and keeps the rows found before that.
Your Google account is not affected. See Responsible use.
- The web UI is a simple form for beginners. Up front are "What" (a business type) and "Where"
(a city), and two options that are on by default: "Emails" and "Social profiles", under "Collect".
Both boxes take only picks from their lists, and each pick becomes a tag you can remove: type a
few letters, then pick. Text that is not in a list is refused, and Enter never starts a search.
Three collapsed sections hold the rest: "Location
and language", "Advanced options" and "Proxies". The job list shows each job's status with a
progress bar (a review stage reads "reading reviews 7 of 20"), its times in your local time, and
Leads CSV, Full CSV, JSON and Delete buttons. Downloads are named after the search, for example
bakery-in-portland-or-c063a815-leads.csv. Leads CSV has the script's 8 lead fields and the social
columns, with the same junk-email rules; Full CSV and JSON have every raw column. Its email and
social options read homepages only, so the scripts, which also crawl contact pages, find more
emails. Its What and Where boxes take only picks from their lists: about 4,100 business types
(the kit's 201 popular ones in engine/presets/business-types.json, add a niche there, then
Google's own category names) and about 168,000 cities from GeoNames, so a search never names a
place or a type that does not exist. Each type is searched in each city, one job per city, with
the map centred on that city. The page loads two static files from GitHub
(raw.githubusercontent.com), with no tracking: the sponsor box's
assets/sponsors/sponsors.json from this repo (cached for a day), and Google's category names
for the What box (cached for 30 days). Scraped data stays on your machine.
- Service-area businesses often have no address. Plumbers, cleaners and other mobile services
often hide their street address on Google, so
address is empty for them. The city and the phone
usually remain.
- No SOCKS5 login. Chrome cannot log in to a SOCKS5 proxy, so the engine refuses a SOCKS5 proxy
with a username and password (422). Use the provider's
http://user:pass@host:port address, or a
SOCKS5 proxy that allows your IP address.
How it compares
14 of 14 green. No other Google Maps scraper we compared scores more than 5. The kit is the only
one that finds emails, social profiles and ad pixels by default, for free, without the data leaving your machine.
✅ built in and free · 🟡 partial, manual or paid · ❌ no · ➖ not applicable or not stated
|
This kit |
gosom |
omkarcloud |
zohaibbashir |
gaspa93 |
conor |
Apify, Outscraper |
| Price |
✅ Free |
✅ Free |
🟡 Freemium |
✅ Free |
✅ Free |
✅ Free |
❌ Per result |
| Data stays local |
✅ |
✅ |
🟡 Cloud enrichment |
✅ |
✅ |
✅ |
❌ |
| Setup |
✅ Python, Chrome |
🟡 Docker or binary |
🟡 App, account |
🟡 pip, Playwright |
🟡 pip, Chromedriver |
🟡 Docker |
🟡 Account, key |
| Past Google's 120 cap |
✅ --grid, --deep-scan |
🟡 Manual bbox |
✅ |
❌ |
❌ |
❌ |
✅ |
| Emails |
✅ On by default |
🟡 Flag, off by default |
🟡 Paid |
❌ |
❌ |
❌ |
🟡 Paid add-on |
| Email check (MX) |
✅ --verify-emails |
❌ |
🟡 Paid |
❌ |
❌ |
❌ |
🟡 Paid add-on |
| Social profiles |
✅ 6 networks, on by default |
❌ |
🟡 Paid |
❌ |
❌ |
❌ |
🟡 Paid add-on |
| Ad pixels and lead score |
✅ --tech ranks leads |
❌ |
🟡 Yes/no ads field |
❌ |
❌ |
❌ |
❌ |
| Lead filters |
✅ 6 filters and --exclude |
🟡 -resume only |
✅ |
❌ |
❌ |
❌ |
🟡 Varies |
| Proxy rotation |
✅ Rotates on block |
✅ |
➖ |
❌ |
❌ |
❌ |
✅ |
| Web UI |
✅ |
✅ |
✅ App |
❌ |
❌ |
❌ |
✅ |
| REST API |
✅ Localhost only |
✅ |
✅ |
❌ |
❌ |
✅ |
✅ |
| AI agent |
✅ Skill and 4 commands |
🟡 Needs Docker and Node |
❌ |
❌ |
❌ |
❌ |
🟡 Apify MCP |
| Published speed |
✅ 100 leads with emails in 44 s |
🟡 ~120 a minute, emails off |
❌ |
❌ |
❌ |
❌ |
➖ |
| ✅ count |
14 / 14 |
5 |
4 |
2 |
2 |
3 |
4 |
Facts about other tools come from their own README on 2026-11-02. The kit's numbers are measured, with
the commands to reproduce them, in Measured, not estimated. The full
comparison is in docs/best-google-maps-scrapers.md.
Ask a chat AI to "scrape Google Maps" and it hits a consent wall and JavaScript-rendered pages, so
you get close to zero structured rows: on the table above it would score 1, for its free tier. This kit runs a real headless scraping engine locally and gives
the agent a precise operating manual for it.
Guides and recipes
One page per job, with the exact commands. Index: docs/README.md.
FAQ
What is the best free Google Maps scraper on GitHub?
For lead lists with contact data, this kit: it is the only open-source scraper that returns emails and social profiles by default, needs no Docker, API key or pip install, and gets past Google's 120-result cap with --grid and --deep-scan. The comparison, with sources and dates: docs/best-google-maps-scrapers.md.
How fast is it?
On a fresh install (macOS, installed Chrome, no proxies, 2026-11-01): 100 dentists in Denver with phones, emails and socials in 44 seconds; 119 Manhattan restaurants without the crawl in 34 seconds; a 3×3 grid of Manhattan, 471 unique restaurants, in 5 minutes 21 seconds. Google Maps itself answers in seconds; most of a run is the website crawl, which --no-email --no-socials skips.
Is this Google Maps scraper free?
Yes. The kit and its engine are MIT licensed. There are no credits, subscriptions or API keys. You
need Python and Chrome on your own machine, or Docker.
Do I need a Google Maps API key or the Google Places API?
No. The kit drives a headless browser against Google Maps directly, so there is no API quota or billing.
How is this different from kit 1.x?
Kit 1.x ran another open-source scraper's engine in Docker. Kit 2.0 has its own engine, written
from scratch in standard-library Python around a headless Chrome. It runs without Docker, works on
Windows and on arm64 Linux, needs no workarounds for jobs that never finish, and sends no telemetry.
It keeps the same job API and column names, so scripts and files made for 1.x still work, and an
update from 1.x brings the old jobs along. A few columns hold their data differently (reviews come
on request, without reviewer names): SETUP, Upgrading from kit 1.x. On top sits the lead-focused layer: a dependency-free
Python CLI with geocoding and batching, email and social enrichment to a clean CSV, and a
Claude Code skill with slash commands and safety guardrails. See CREDITS.md.
Do I need Claude Code to use it?
No. Claude Code makes it hands-free through a skill and slash commands, but scripts/scrape.py and
scripts/scrape.sh run on their own from any terminal.
Can ChatGPT or Claude scrape Google Maps?
Not by chatting alone. A chat AI hits Google's consent wall and pages built by JavaScript, so it
returns few or no structured rows. An agent that can run commands, such as Claude Code, Codex or
Cursor, can drive this kit: ask "scrape gyms in Miami" and it runs the script, then returns a table
and a CSV. See Use it with Claude Code or any agent.
Does it work with Codex, Cursor or other agents?
Yes. npx skills add mahanaicoach/google-maps-scraper-kit installs the skill into any Agent
Skills-compatible tool. The /scrape slash commands are Claude Code only. After a scrape, Claude Code,
Codex and Gemini CLI show you the first 10 rows in the chat through the kit's hook, which the model
never receives. In other agents, python3 scripts/leads.py <file> --open opens the file in your
spreadsheet app.
What data do I get for each business?
Name, phone, email, website, category, address, rating and review count, then Instagram, Facebook,
LinkedIn, TikTok, YouTube and X links by default. Add --no-socials to drop the social columns, or
--full for every raw column.
How many leads can I scrape?
Up to about 120 per search. Add --grid 3 to split the city into 9 map tiles and get past that cap, or
--deep-scan to also split every tile that hits the cap into 4 sub-tiles (slower, marked !),
with duplicates removed. Batch as many keywords as you like in one job. For large or repeated runs,
add proxies (see Responsible use).
Does it work on Windows, Linux and Apple Silicon Macs?
Yes, natively on all three with Python and Chrome, Apple Silicon and Linux arm64 included, or anywhere
Docker runs. On Windows, use py scripts/scrape.py, or run scrape.sh under WSL2 or Git Bash.
SETUP.md has the platform notes.
Is scraping Google Maps legal?
It is against Google's Terms of Service, and phones and emails are personal data. Read
Responsible use and follow the law where the data is used: GDPR and CCPA
abroad, and LGPD in Brazil. This is not legal advice.
Responsible use
This drives a real scraper against Google Maps. Light use is fine. Heavy use without proxies can get
your IP temporarily rate-limited (minutes to hours). Your Google account is not affected.
For large requests, the agent flags the risk and suggests proxies, then proceeds. It refuses only
clearly abusive use.
Featured in
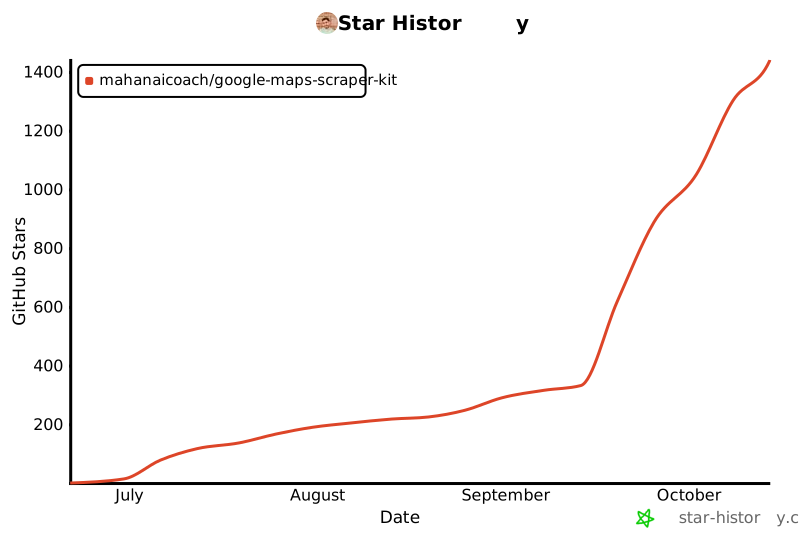
Star history
If this kit saved you an afternoon of copy-pasting, a star helps the next person find it.
Project layout
google-maps-scraper-kit/
├── engine/                 the kit's own engine: Google Maps over Chrome DevTools, HTTP API, web UI
│   ├── serve.py            the engine server on 127.0.0.1:8080
│   └── test_engine.py      offline tests, no network, no Chrome
├── Dockerfile              the engine image: Python + Debian's Chromium, non-root
├── docker-compose.yml      runs that image on 127.0.0.1:8080
├── .env.example            config template
├── scripts/
│   ├── engine.py           start, stop, status or restart the engine without Docker; list or delete jobs
│   ├── scrape.py           Python CLI: single, batch, geocoding, socials, CSV
│   ├── scrape.sh           bash CLI: single query
│   ├── update.sh           one-command update of a clone or fork
│   ├── test_scrape.py      offline tests, no network: python3 scripts/test_scrape.py
│   └── test_update.sh      checks update.sh, no network: bash scripts/test_update.sh
├── docs/                   guides and recipes
├── examples/               sample job body and batch keyword list
├── .claude/
│   ├── settings.json       pre-approved local commands for hands-free runs
│   ├── commands/           /scrape, /scrape-batch, /scrape-setup, /scrape-jobs
│   └── skills/google-maps-scraper/SKILL.md
├── AGENTS.md               points Codex, Cursor and other agents to CLAUDE.md
├── CLAUDE.md               project instructions for Claude Code
├── CREDITS.md              attribution and licenses
└── SETUP.md                full setup guide
Updating
The web UI shows a line under its title when a newer release is out, and python3 scripts/engine.py status
prints one (both check GitHub's releases once a day; SCRAPER_NO_UPDATE_CHECK=1 in .env turns it off).
Nothing updates by itself. Pull the latest fixes with one command. It works in a clone of this repo or of your fork, and it
keeps your own commits:
bash scripts/update.sh
If the engine runs in Docker, the script rebuilds and restarts it so the new version takes effect.
Without Docker, restart it yourself: python3 scripts/engine.py restart. Forked it on GitHub? Run git push afterwards, or click Sync fork on your fork's
page.
On Windows without Git Bash, run the same update by hand:
git pull https://github.com/Mahanaicoach/google-maps-scraper-kit.git master
py scripts/engine.py restart
With Docker, run docker compose up -d --build --remove-orphans in place of the second line.
Coming from kit 1.x? The same command moves you to the own engine, and your old jobs and their CSVs
appear in the new web UI. Details: SETUP.md, upgrading from 1.x.
Support
Found a bug? Open an issue with
the command you ran and the error. Issues are for problems with the kit. Run your own scrapes with the
quick start above; requests like "find me hotels in Hamburg" are closed without action.
Contributions: CONTRIBUTING.md. Security reports: SECURITY.md.
License
Built by Mahan. MIT licensed. Third-party components: CREDITS.md.

 一款免费的开源工具,可以在本地抓取 Google 地图上的商家信息,生成可直接用于外联的潜在客户名单,并将名称、电话、邮箱、网站、类别、地址、评分和评价数量导出为 CSV 文件。