
ESP32s3-LLM-Cluster README

The project's README from github.com/Low-Zi-Hong/ESP32s3-LLM-Cluster. As one markdown file: README.md.

ESP32s3-LLM-Cluster

A distributed pipeline inference engine on multiple ESP32S3 running 1.58-bit (BitNet) Language model.

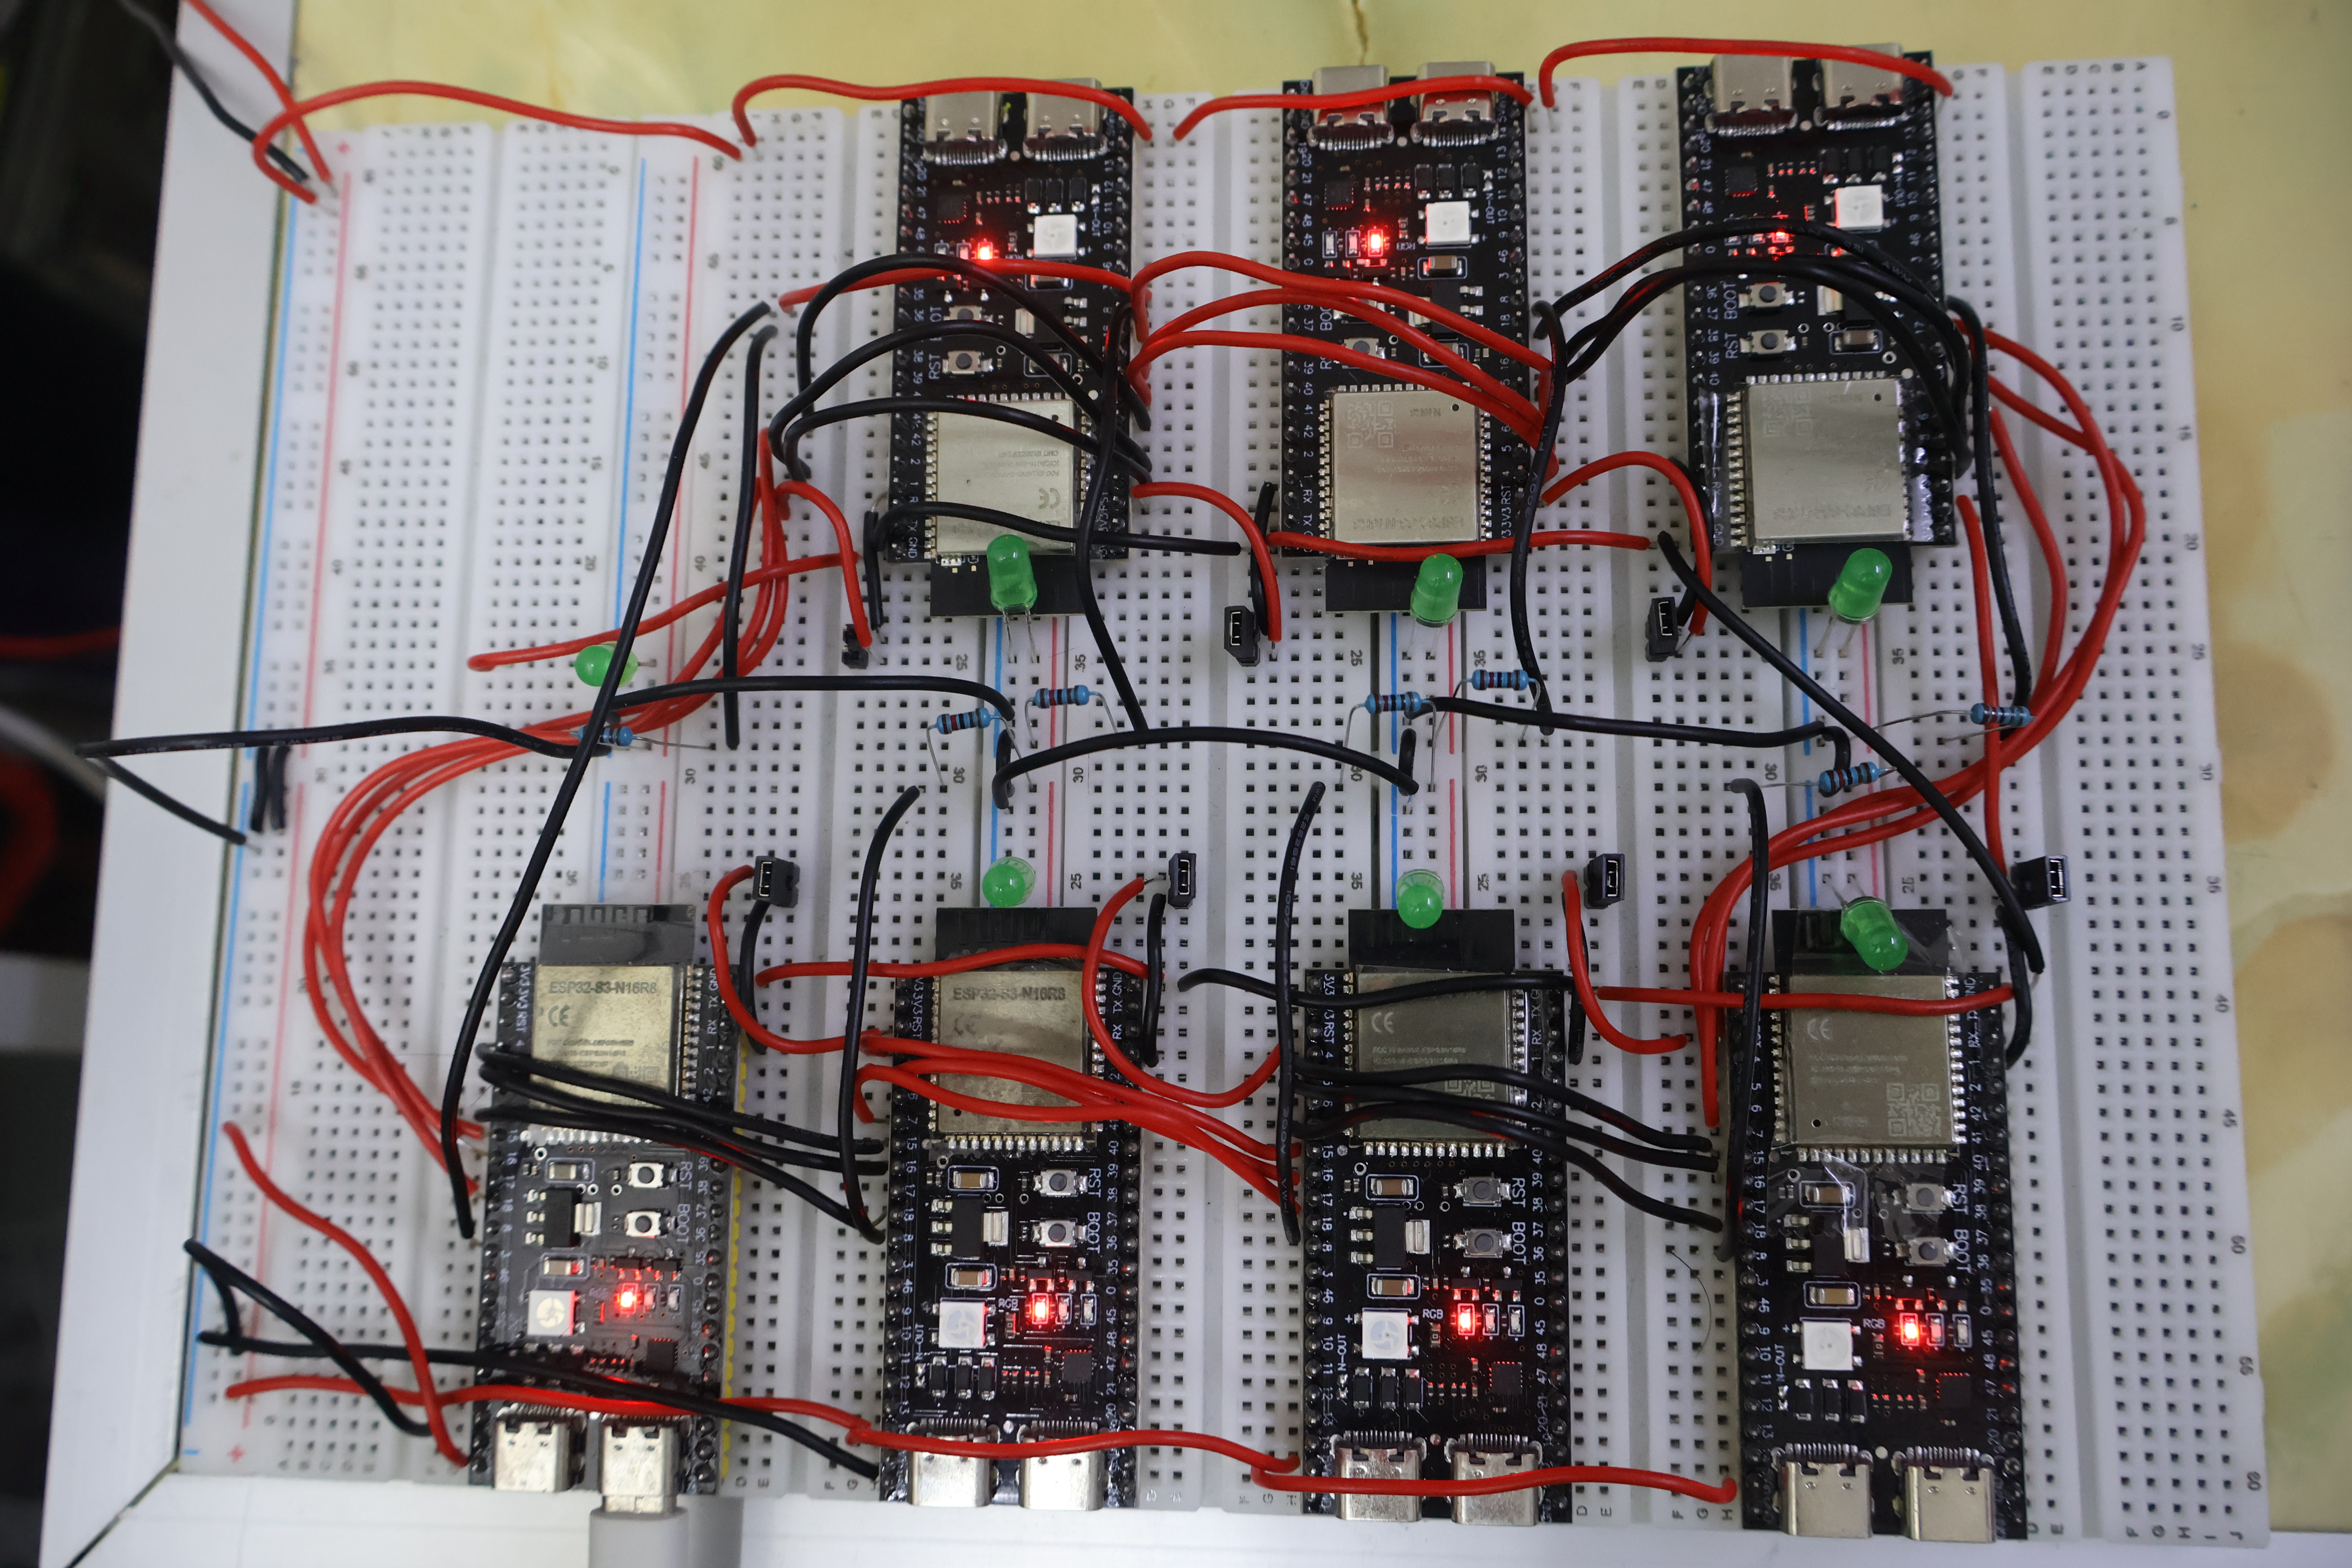
ESP32S3 boards

Architecture

This project runs a sliced 0.5B LLM across a cluster of 7 ESP32s3. One act as master and others are node. The master node runs the tokenizer and embeding and the other attention layer and MLP ran on the nodes. The master and node communicate through high speed SPI Daisy-Chain.

┌─────────────────────────────────────────────────────────┐
│                     MASTER NODE                         │
│                                                         │
│  [ Prompt ] ---> BPE Tokenizer                          │
│                       │                                 │
│                 Token Embedding                         │
│             (INT4, ~14MB in Flash)                      │
│                       │                                 │
│             (SPI CH A - TX to Node 1)                   │
└───────────────────────┬─────────────────────────────────┘
                        │ Hidden State Vector (FP32)
                        ▼
┌─────────────────────────────────────────────────────────┐
│                    COMPUTE NODE 1                       │
│             (SPI CH B - RX from Master)                 │
│                                                         │
│  ► Layer 0 to 3 (4x Transformer Blocks)                 │
│    • RMSNorm (FP16 scaled to FP32)                      │
│    • 1.58-bit Attention (Q, K, V, O proj) + RoPE        │
│    • KV Cache (PSRAM)                                   │
│    • 1.58-bit MLP (Gate, Up, Down proj)                 │
│                                                         │
│             (SPI CH A - TX to Node 2)                   │
└───────────────────────┬─────────────────────────────────┘
                        │
                       ... (Nodes 2 to 5)
                        │
                        ▼
┌─────────────────────────────────────────────────────────┐
│                    COMPUTE NODE 6                       │
│             (SPI CH B - RX from Node 5)                 │
│                                                         │
│  ► Layer 20 to 23 (4x Transformer Blocks)               │
│    • Same 1.58-bit Architecture                         │
│                                                         │
│             (SPI CH A - TX back to Master)              │
└───────────────────────┬─────────────────────────────────┘
                        │
                        ▼
┌─────────────────────────────────────────────────────────┐
│                     MASTER NODE                         │
│             (SPI CH B - RX from Node 6)                 │
│                                                         │
│                 Final RMS Norm                          │
│             (FP16, 64KB in 'fnorm' partition)           │
│                       │                                 │
│         LM Head (Tied to INT4 Embeddings)               │
│                       │                                 │
│               Greedy Sampling                           │
│                       │                                 │
│  [ Output ] <--- Next Token ID                          │
└─────────────────────────────────────────────────────────┘

Getting Started

pls refer workflow guide to start with the project.

Project Structure

.
├── README.md                   # Project documentation
├── workflow.md                 # Step-by-step flashing, model prep & wiring guide
├── .gitignore                  # Git ignore rules for build files & binaries
│
├── docs/                       
│   └── images/                 # Architecture diagrams and hardware photos
│
├── master_board/               # Firmware for the Master Node (ESP-IDF)
│   ├── main/
│   │   ├── main.cpp            # Master orchestrator, user I/O & BPE tokenizer
│   │   ├── embedding.cpp       # INT4 embedding lookup logic
│   │   ├── lm_head.cpp         # LM Head mapping and greedy sampling
│   │   └── spi_bus.cpp         # Master dual-channel SPI driver
│   ├── partitions.csv          # Custom partition table (token, model, fnorm)
│   └── CMakeLists.txt
│
├── node_firmware/              # Firmware for the Compute Nodes (ESP-IDF)
│   ├── main/
│   │   ├── main.cpp            # Node worker entry point & inference loop
│   │   ├── bitlinear.cpp       # 1.58-bit ternary linear layer implementation
│   │   ├── bitlinear_forward.S # Assembly optimized MAC ops for 1.58-bit
│   │   ├── qwen_attention.cpp  # Qwen Attention, RoPE & KV-Cache runtime
│   │   ├── lut_table.cpp       # Look-up tables for extreme optimization
│   │   └── spi_bus.cpp         # Daisy-chain SPI DMA receiver/transmitter
│   ├── partitions.csv          # Layer partition layout for Node
│   └── CMakeLists.txt
│
├── python_tools/               # PC-side quantization & preprocessing suite
    ├── crop_token.py           # Vocabulary pruning (scales down to 32K tokens)
    ├── crop_model_weight.py    # Embedding matrix slicing
    ├── qat_158.py              # BitNet QAT (Quantization-Aware Training) fine-tuning
    ├── bit4_embedding.py       # INT4 weight packer for embeddings
    ├── pack_tokenizer_bin.py   # Serializes tokenizer rules into ESP32 .bin
    ├── pack_model_bin.py       # Packs 1.58-bit layer chunks for physical alignment
    ├── look_model_structure.py # Debug tool for inspecting .safetensors
    └── flash_*.bat             # Multi-threaded fast flashing scripts

License

This project is licensed under the MIT License - see the LICENSE file for details.

Acknowledgments

Inspiration, related works, and references:

ESP32s3-LLM-Cluster (Low-Zi-Hong/ESP32s3-LLM-Cluster)

Searching Database…

这是什么?该项目是一个分布式推理引擎,运行经 1.58 比特(BitNet)三值权重量化的 0.5B 参数大语言模型,并将其拆分到通过 SPI 连接的 7 片 ESP32-S3 微控制器集群上。
这是单个 ESP32-S3 设备,还是多板集群?它是一个 7 块板的硬件集群,不是单颗芯片:一片 ESP32-S3 作为主控,运行分词器和嵌入步骤,另外六片运行模型的注意力和 MLP 层。
怎么让它跑起来?README 只是指向一份单独的工作流指南来进行设置,本身并没有包含逐步的构建或烧录说明。
搭建它需要什么硬件?你需要 7 块实体 ESP32-S3 开发板,以 SPI 菊花链方式接线连在一起,外加一个预先量化的 BitNet(1.58 比特三值)模型,用于加载到主控板和节点板上。
这个项目成熟度如何——有经过测试的构建指南吗?README 本身很简略,“Project Structure”一节是空的,实际设置则交由外部工作流指南处理,所以你要有亲自动手组装接线的心理准备,而不是跟着一份打磨好的快速上手指南走。
为什么把模型拆到 7 块板上,而不是只用一片 ESP32-S3?把分词器/嵌入(主控)与注意力和 MLP 层(节点)分开,可以让集群运行内存和算力需求超出单片 ESP32-S3 承载能力的模型。
什么是 BitNet 1.58 比特量化?BitNet 把模型权重限制为三值(-1、0、1),大幅缩小内存占用,使大语言模型能够切实装进 ESP32-S3 这类微控制器级硬件。
这个项目的灵感来自哪里?作者致谢“ESP-32-s3-Story-maker-LLM”(ESP32-S3 上的单节点量化大模型部署)和“esp32s3-distributed-ai”(多节点分布式 AI 架构),并把这两个思路与 BitNet 量化结合起来。
Size
8.6 MB
Stars
246
Updated
CommitOct 08
Age
2mo
Commits · 90 Days