LivePortrait: Efficient Portrait Animation with Stitching and Retargeting Control
1 Kuaishou Technology 2 University of Science and Technology of China 3 Fudan University
* Equal contributions
† Project lead
🔥 Updates
2025/06/01: 🌍 Over the past year, LivePortrait has 🚀 become an efficient portrait-animation (humans, cats and dogs) solution adopted by major video platforms—Kuaishou, Douyin, Jianying, WeChat Channels—as well as numerous startups and creators. 🎉2025/01/01: 🐶 We updated a new version of the Animals model with more data, see here.2024/10/18: ❗ We have updated the versions of the transformers and gradio libraries to avoid security vulnerabilities. Details here.2024/08/29: 📦 We update the Windows one-click installer and support auto-updates, see changelog.2024/08/19: 🖼️ We support image driven mode and regional control. For details, see here.2024/08/06: 🎨 We support precise portrait editing in the Gradio interface, inspired by ComfyUI-AdvancedLivePortrait. See here.2024/08/05: 📦 Windows users can now download the one-click installer for Humans mode and Animals mode now! For details, see here.2024/08/02: 😸 We released a version of the Animals model, along with several other updates and improvements. Check out the details here!2024/07/25: 📦 Windows users can now download the package from HuggingFace. Simply unzip and double-click run_windows.bat to enjoy!2024/07/24: 🎨 We support pose editing for source portraits in the Gradio interface. We’ve also lowered the default detection threshold to increase recall. Have fun!2024/07/19: ✨ We support 🎞️ portrait video editing (aka v2v)! More to see here.2024/07/17: 🍎 We support macOS with Apple Silicon, modified from jeethu's PR #143.2024/07/10: 💪 We support audio and video concatenating, driving video auto-cropping, and template making to protect privacy. More to see here.2024/07/09: 🤗 We released the HuggingFace Space, thanks to the HF team and Gradio!2024/07/04: 😊 We released the initial version of the inference code and models. Continuous updates, stay tuned!2024/07/04: 🔥 We released the homepage and technical report on arXiv.
Introduction 📖
This repo, named LivePortrait, contains the official PyTorch implementation of our paper LivePortrait: Efficient Portrait Animation with Stitching and Retargeting Control.
We are actively updating and improving this repository. If you find any bugs or have suggestions, welcome to raise issues or submit pull requests (PR) 💖.
Getting Started 🏁
1. Clone the code and prepare the environment 🛠️
[!Note]
Make sure your system has git, conda, and FFmpeg installed. For details on FFmpeg installation, see how to install FFmpeg.
git clone https://github.com/KlingTeam/LivePortrait
cd LivePortrait

# create env using conda
conda create -n LivePortrait python=3.10
conda activate LivePortrait
For Linux 🐧 or Windows 🪟 Users
X-Pose, required by Animals mode, is a dependency that needs to be installed. The step of Check your CUDA versions is optional if you only want to run Humans mode.
Check your CUDA versions
Firstly, check your current CUDA version by:
nvcc -V # example versions: 11.1, 11.8, 12.1, etc.
Then, install the corresponding torch version. Here are examples for different CUDA versions. Visit the PyTorch Official Website for installation commands if your CUDA version is not listed:
# for CUDA 11.1
pip install torch==1.10.1+cu111 torchvision==0.11.2 torchaudio==0.10.1 -f https://download.pytorch.org/whl/cu111/torch_stable.html
# for CUDA 11.8
pip install torch==2.3.0 torchvision==0.18.0 torchaudio==2.3.0 --index-url https://download.pytorch.org/whl/cu118
# for CUDA 12.1
pip install torch==2.3.0 torchvision==0.18.0 torchaudio==2.3.0 --index-url https://download.pytorch.org/whl/cu121
# ...
Note: On Windows systems, some higher versions of CUDA (such as 12.4, 12.6, etc.) may lead to unknown issues. You may consider downgrading CUDA to version 11.8 for stability. See the downgrade guide by @dimitribarbot.
Finally, install the remaining dependencies:
pip install -r requirements.txt
For macOS with Apple Silicon Users
The X-Pose dependency does not support macOS, so you can skip its installation. While Humans mode works as usual, Animals mode is not supported. Use the provided requirements file for macOS with Apple Silicon:
# for macOS with Apple Silicon users
pip install -r requirements_macOS.txt
2. Download pretrained weights 📥
The easiest way to download the pretrained weights is from HuggingFace:
# !pip install -U "huggingface_hub[cli]"
huggingface-cli download KlingTeam/LivePortrait --local-dir pretrained_weights --exclude "*.git*" "README.md" "docs"
If you cannot access to Huggingface, you can use hf-mirror to download:
# !pip install -U "huggingface_hub[cli]"
export HF_ENDPOINT=https://hf-mirror.com
huggingface-cli download KlingTeam/LivePortrait --local-dir pretrained_weights --exclude "*.git*" "README.md" "docs"
Alternatively, you can download all pretrained weights from Google Drive or Baidu Yun. Unzip and place them in ./pretrained_weights.
Ensuring the directory structure is as or contains this.
3. Inference 🚀
Fast hands-on (humans) 👤
# For Linux and Windows users
python inference.py

# For macOS users with Apple Silicon (Intel is not tested). NOTE: this maybe 20x slower than RTX 4090
PYTORCH_ENABLE_MPS_FALLBACK=1 python inference.py
If the script runs successfully, you will get an output mp4 file named animations/s6--d0_concat.mp4. This file includes the following results: driving video, input image or video, and generated result.
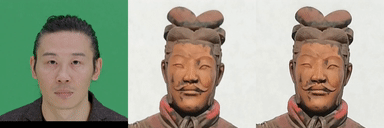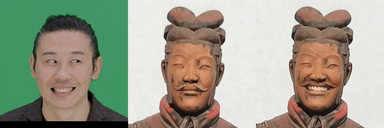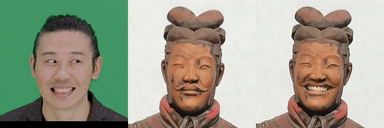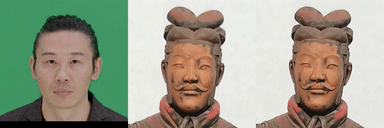
Or, you can change the input by specifying the -s and -d arguments:
# source input is an image
python inference.py -s assets/examples/source/s9.jpg -d assets/examples/driving/d0.mp4

# source input is a video ✨
python inference.py -s assets/examples/source/s13.mp4 -d assets/examples/driving/d0.mp4

# more options to see
python inference.py -h
Fast hands-on (animals) 🐱🐶
Animals mode is ONLY tested on Linux and Windows with NVIDIA GPU.
You need to build an OP named MultiScaleDeformableAttention first (refer to the Check your CUDA versions if needed), which is used by X-Pose, a general keypoint detection framework.
cd src/utils/dependencies/XPose/models/UniPose/ops
python setup.py build install
cd - # equal to cd ../../../../../../../
Then
python inference_animals.py -s assets/examples/source/s39.jpg -d assets/examples/driving/wink.pkl --driving_multiplier 1.75 --no_flag_stitching
If the script runs successfully, you will get an output mp4 file named animations/s39--wink_concat.mp4.
Driving video auto-cropping 📢📢📢
[!IMPORTANT]
To use your own driving video, we recommend: ⬇️
- Crop it to a 1:1 aspect ratio (e.g., 512x512 or 256x256 pixels), or enable auto-cropping by
--flag_crop_driving_video.
- Focus on the head area, similar to the example videos.
- Minimize shoulder movement.
- Make sure the first frame of driving video is a frontal face with neutral expression.
Below is an auto-cropping case by --flag_crop_driving_video:
python inference.py -s assets/examples/source/s9.jpg -d assets/examples/driving/d13.mp4 --flag_crop_driving_video
If you find the results of auto-cropping is not well, you can modify the --scale_crop_driving_video, --vy_ratio_crop_driving_video options to adjust the scale and offset, or do it manually.
Motion template making
You can also use the auto-generated motion template files ending with .pkl to speed up inference, and protect privacy, such as:
python inference.py -s assets/examples/source/s9.jpg -d assets/examples/driving/d5.pkl # portrait animation
python inference.py -s assets/examples/source/s13.mp4 -d assets/examples/driving/d5.pkl # portrait video editing
4. Gradio interface 🤗
We also provide a Gradio  interface for a better experience, just run by:
# For Linux and Windows users (and macOS with Intel??)
python app.py # humans mode

# For macOS with Apple Silicon users, Intel not supported, this maybe 20x slower than RTX 4090
PYTORCH_ENABLE_MPS_FALLBACK=1 python app.py # humans mode
We also provide a Gradio interface of animals mode, which is only tested on Linux with NVIDIA GPU:
python app_animals.py # animals mode 🐱🐶
You can specify the --server_port, --share, --server_name arguments to satisfy your needs!
🚀 We also provide an acceleration option --flag_do_torch_compile. The first-time inference triggers an optimization process (about one minute), making subsequent inferences 20-30% faster. Performance gains may vary with different CUDA versions.
# enable torch.compile for faster inference
python app.py --flag_do_torch_compile
Note: This method is not supported on Windows and macOS.
Or, try it out effortlessly on HuggingFace 🤗
5. Inference speed evaluation 🚀🚀🚀
We have also provided a script to evaluate the inference speed of each module:
# For NVIDIA GPU
python speed.py
The results are here.
Discover the invaluable resources contributed by our community to enhance your LivePortrait experience.
Playgrounds, 🤗 HuggingFace Spaces and Others
Video Tutorials
And so MANY amazing contributions from our community, too many to list them all 💖
Acknowledgements 💐
We would like to thank the contributors of FOMM, Open Facevid2vid, SPADE, InsightFace and X-Pose repositories, for their open research and contributions.
Ethics Considerations 🛡️
Portrait animation technologies come with social risks, particularly the potential for misuse in creating deepfakes. To mitigate these risks, it’s crucial to follow ethical guidelines and adopt responsible usage practices. At present, the synthesized results contain visual artifacts that may




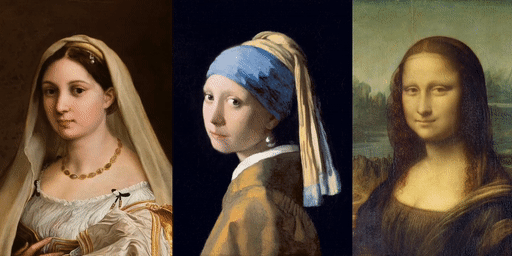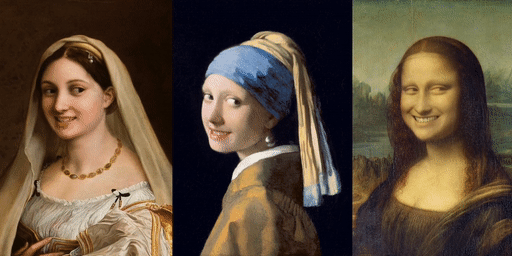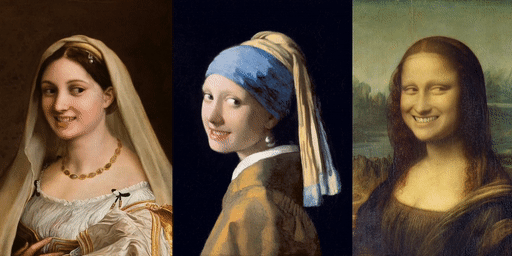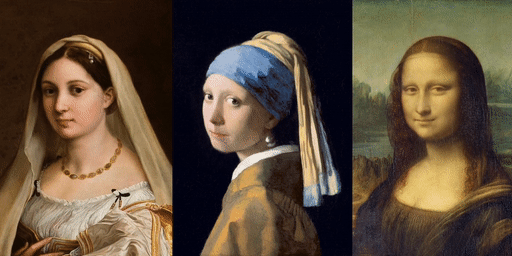

 LivePortrait 可以用一段驱动视频让静态人像照片动起来——它是快手科技论文《Efficient Portrait Animation with Stitching and Retargeting Control》的官方 PyTorch 实现。除了真人,也支持猫和狗。