
ComfyUI-Ref2VA-VSA README

The project's README from github.com/Kablex/ComfyUI-Ref2VA-VSA. As one markdown file: README.md.

ComfyUI-Ref2VA-VSA: Ultra-Fast Character Video Generation (72s on RTX 4090)

ComfyUI MiniMax-H3 Speed Hardware

Breakthrough inference speed for MiniMax H3 Reference-to-Video (Ref2VA / R2VA): Generate a full 5-second, 24 fps video conditioned on reference character images in ~72s (warm) / 95s (first run) on a single consumer NVIDIA GeForce RTX 4090 (24GB).


🎬 Empirical Benchmark & Results

Both videos were generated on the exact same NVIDIA GeForce RTX 4090 (24GB), using the exact same prompt, character reference image, seed (981445682258077), and resolution (1344×768, 5.16s @ 24 fps / 124 frames).

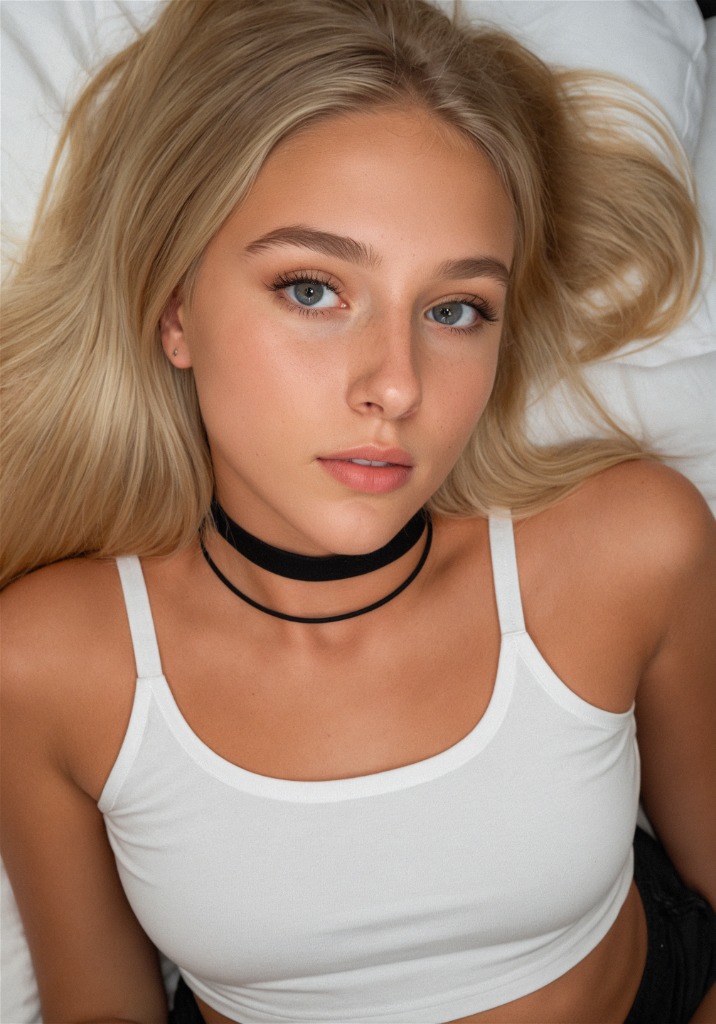
Input Reference Character
Input Character Reference Image

🚀 Ref2VA VSA (Ours - 4 Steps)

⏱️ 95s (1st run) / ~72s (warm)

🔬 Video Delta Net / VDN-H3 (8 Steps)

⏱️ 213s (1st run) / ~135s (warm)
Ref2VA VSA Preview
▶ Download Full 1344x768 Video (MP4)
VDN-H3 Preview
▶ Download Full 1344x768 Video (MP4)
  • Sampling: 4 steps (euler / simple)
  • Attention: 75% video sparsity top-k (sparse DiT)
  • Speedup: 2.24x faster than VDN; 9x faster than native H3
  • Peak VRAM: ~13.5 GB
  • Sampling: 8 steps (er_sde / beta)
  • Attention: Hybrid (windowed dense + linear delta state)
  • Speedup: ~3.5x faster than native H3
  • Peak VRAM: ~18.5 GB

📊 Comprehensive Performance Comparison (RTX 4090)

Pipeline Attention Mechanism Steps / Sampler 1st Run Latency Warm Wall Time Peak VRAM
MiniMax H3 Native Dense Dense Global Softmax 50 steps / Euler ~650s ~650s (10.8 min) ~22.5 GB
H3 Turbo LoRA (Dense) Dense Global Softmax 4 steps / Euler ~210s ~190s (3.1 min) ~21.0 GB
Video Delta Net (VDN-H3) Windowed + Linear Delta 8 steps / er_sde 213.0s ~135s (2.2 min) ~18.5 GB
Ref2VA VSA (This Repo) 🚀 75% Video Sparsity + Dense Prefix 4 steps / Euler 95.2s ~72 seconds ~13.5 GB

🧠 Technical Architecture: Why Ref2VA was Hard for VSA

FastVideo pioneered Visual Sparse Attention (VSA) for text-to-video (T2V) by clustering video tokens into 3D spatial-temporal tiles (4×4×4) and dynamically pruning 75–90% of tiles via a learned gating projection (to_gate_compress).

However, Ref2VA (Reference-to-Video) was widely considered incompatible with VSA because:

  1. Ref2VA prepends dynamic multimodal condition segments (reference image latents, reference audio latents, and text prompt tokens) ahead of the generated video sequence.
  2. Naive 3D tiling causes tokens from different modalities to straddle the same tile, corrupting the conditioning masks and breaking identity fidelity.

The Solution: Ref2VAVSAGatePatch

Our patch resolves this with an engineered two-tier attention layout:

  1. Multimodal Dense-Exempt Prefix: The geometry mapper isolates text, reference image, and reference audio tokens into segment-pure tiles that are completely exempt from top-k pruning. Reference tokens always remain 100% dense, guaranteeing strict character identity adherence.
  2. Video-Only Sparse Attention: VSA top-k pruning is applied strictly to generated-video key tiles.
  3. Gate Transplant: The 50 learned to_gate_compress projection matrices are transplanted directly onto the Ref2VA base model (minimax_h3_ref2va_pruned_int8_convrot.safetensors).

📦 Requirements

Place the following files in your ComfyUI/models/ directories:

Model Type File Name Destination Directory Download Link
Diffusion Model minimax_h3_ref2va_pruned_int8_convrot.safetensors models/diffusion_models/ Download from Comfy-Org
VSA Gate fasth3_vsa_gate.safetensors models/loras/ Download from Hugging Face
Turbo LoRA (4-Step) minimax_h3_ref2v_turbo_4step_v0.1_comfyui_bf16.safetensors models/loras/ Download from LightX2V
Text Encoder qwen3vl_32b_minimax_h3_nvfp4_awq.safetensors models/text_encoders/ Download from Comfy-Org
Video VAE minimax_h3_video_vae_fp16.safetensors models/vae/ Download from Comfy-Org
Audio VAE minimax_h3_audio_vae_fp32.safetensors models/vae/ Download from Comfy-Org

💡 Tip: The VSA Gate can also be extracted locally from any official FastH3 base checkpoint using the included tools/extract_vsa_gate.py script.


🚀 Quick Start

  1. Clone or copy this repository into your ComfyUI custom_nodes directory:

    cd ComfyUI/custom_nodes
    git clone https://github.com/Kablex/ComfyUI-Ref2VA-VSA
    
  2. Copy the example character image into your ComfyUI input folder:

    cp ComfyUI-Ref2VA-VSA/assets/example_character.jpg ComfyUI/input/
    
  3. Restart ComfyUI. The node appears under: FastH3/VSA -> Ref2VA VSA Gate Transplant (EXPERIMENTAL)

  4. Load the ready-to-use workflow from workflows/ref2va_vsa_4step_rtx4090.json and click Queue Prompt.


🛠️ Node Wiring

[UNETLoader (Ref2VA INT8)]
        │
        ▼
[LoraLoaderModelOnly (Turbo 4-Step LoRA, strength=1.0)]
        │
        ▼
[Ref2VAVSAGatePatch (fasth3_vsa_gate.safetensors, sparsity=0.75)]
        │
        ▼
[MiniMaxH3SigmaShift (shift_video=12, shift_audio=3)]
        │
        ├──► [BasicScheduler (steps=4, scheduler=simple)]
        │
        └──► [BasicGuider] ──► [SamplerCustomAdvanced (sampler=euler)]

🧰 Extracting the Gate File (tools/extract_vsa_gate.py)

If you have a FastH3 VSA base checkpoint (minimax_h3_fastvideo_vsa_datafree_1300step_4step_int8_convrot.safetensors), you can extract fasth3_vsa_gate.safetensors yourself:

python tools/extract_vsa_gate.py \
    --input /path/to/minimax_h3_fastvideo_vsa_datafree_1300step_4step_int8_convrot.safetensors \
    --output /path/to/ComfyUI/models/loras/fasth3_vsa_gate.safetensors

📄 License & Acknowledgements

ComfyUI-Ref2VA-VSA (Kablex/ComfyUI-Ref2VA-VSA)

Searching Database…

这是什么?这是一个 ComfyUI 自定义节点,可大幅加速 MiniMax H3 模型的 Reference-to-Video(Ref2VA)生成:在单张 RTX 4090 上约 72 秒就能产出完整的 5 秒 24fps 人物视频,而不是原来的 10 多分钟。
怎么让它在 ComfyUI 里跑起来?把仓库克隆到你的 ComfyUI custom_nodes 目录,将所需的检查点文件(扩散模型、VSA gate、turbo LoRA、文本编码器、视频/音频 VAE)下载到对应的 ComfyUI/models 子文件夹,重启 ComfyUI,然后加载 workflows/ref2va_vsa_4step_rtx4090.json 中现成的工作流。
它需要什么硬件和软件?你需要原生支持 MiniMax-H3 的 ComfyUI、支持 CUDA Sol-Attention 的 comfy-kitchen、PyTorch 2.4+/CUDA 12.1+,以及一台显存 24GB 的 NVIDIA GPU,如 RTX 3090、RTX 4090、A5000 或 L40S。
它适合日常使用了吗?该节点在界面中被明确标注为实验性,而且需要手动把多个大型检查点文件下载到指定的 ComfyUI 模型文件夹后才能工作。
我能在更小的消费级 GPU 上运行吗?不行。它至少需要一张 24GB 显存的 NVIDIA 显卡;生成时的峰值占用约 13.5GB,但检查点和流水线都是围绕 24GB 级显卡设计的。
为什么在此之前 Ref2VA 被认为与稀疏注意力不兼容?Ref2VA 会把参考图像、音频和文本 token 放到视频序列前面,而朴素的 3D 分块会把不同模态的 token 混进同一个块里,破坏条件掩码并损害角色的一致性。
什么是 VSA(视觉稀疏注意力)?VSA 是 FastVideo 的一项技术,它把视频 token 聚类成 3D 时空块,并通过学习到的门控投影剪除其中 75-90%,从而削减视频扩散模型的注意力计算量。
它比标准的 MiniMax H3 流水线快多少?它比原生的 50 步稠密 H3 流水线快约 9 倍,比另一种 Video Delta Net(VDN-H3)加速方案快 2.24 倍。
我可以自己提取 VSA gate 文件而不用下载吗?可以。自带的 tools/extract_vsa_gate.py 脚本能从任何官方 FastH3 VSA 基座检查点中提取 gate 权重。
Creator
Kablex
Size
4.1 MB
Stars
743
Updated
CommitOct 17
Age
1mo
Commits · 90 Days