

20.1K ·GitHub
Что это такое?
 Tongyi DeepResearch — открытая агентная LLM от Tongyi Lab (Alibaba), созданная для длительного и глубокого поиска информации в интернете. В этом репозитории лежат веса модели, а также скрипты на Python для инференса и запуска бенчмарков.
Так это приложение, которое я устанавливаю, или модель, которую мне нужно запускать самому?Это модель, а не готовое приложение: всего 30,5 млрд параметров, из которых на каждый токен активируется лишь 3,3 млрд, плюс контекстное окно на 128K. Вы скачиваете веса и запускаете их с помощью инференс-скриптов из репозитория — или не размещаете ничего сами и обращаетесь к модели через API сервиса OpenRouter.
Это модель, а не готовое приложение: всего 30,5 млрд параметров, из которых на каждый токен активируется лишь 3,3 млрд, плюс контекстное окно на 128K. Вы скачиваете веса и запускаете их с помощью инференс-скриптов из репозитория — или не размещаете ничего сами и обращаетесь к модели через API сервиса OpenRouter.Как мне её запустить?Создайте изолированное окружение Python 3.10 (conda или virtualenv), установите зависимости, скопируйте пример файла .env и впишите свои API-ключи, укажите инференс-скрипту путь к весам модели и файлу с вопросами, затем запустите его.
Создайте изолированное окружение Python 3.10 (conda или virtualenv), установите зависимости, скопируйте пример файла .env и впишите свои API-ключи, укажите инференс-скрипту путь к весам модели и файлу с вопросами, затем запустите его.Какие сервисы и ключи нужны, чтобы она реально искала в интернете?Ключ Serper.dev для веб-поиска и Google Scholar, Jina.ai для чтения страниц, OpenAI-совместимый API для суммаризации страниц, Dashscope для разбора файлов и эндпоинт SandboxFusion для песочницы Python — всё настраивается в .env.
Ключ Serper.dev для веб-поиска и Google Scholar, Jina.ai для чтения страниц, OpenAI-совместимый API для суммаризации страниц, Dashscope для разбора файлов и эндпоинт SandboxFusion для песочницы Python — всё настраивается в .env.Можно ли просто попробовать её где-то онлайн?Да — есть демо-версии на ModelScope, HuggingFace и сервисе bailian от Alibaba. Они подходят только для быстрого знакомства: из-за задержек модели и лимитов QPS инструментов могут работать медленно или периодически сбоить.
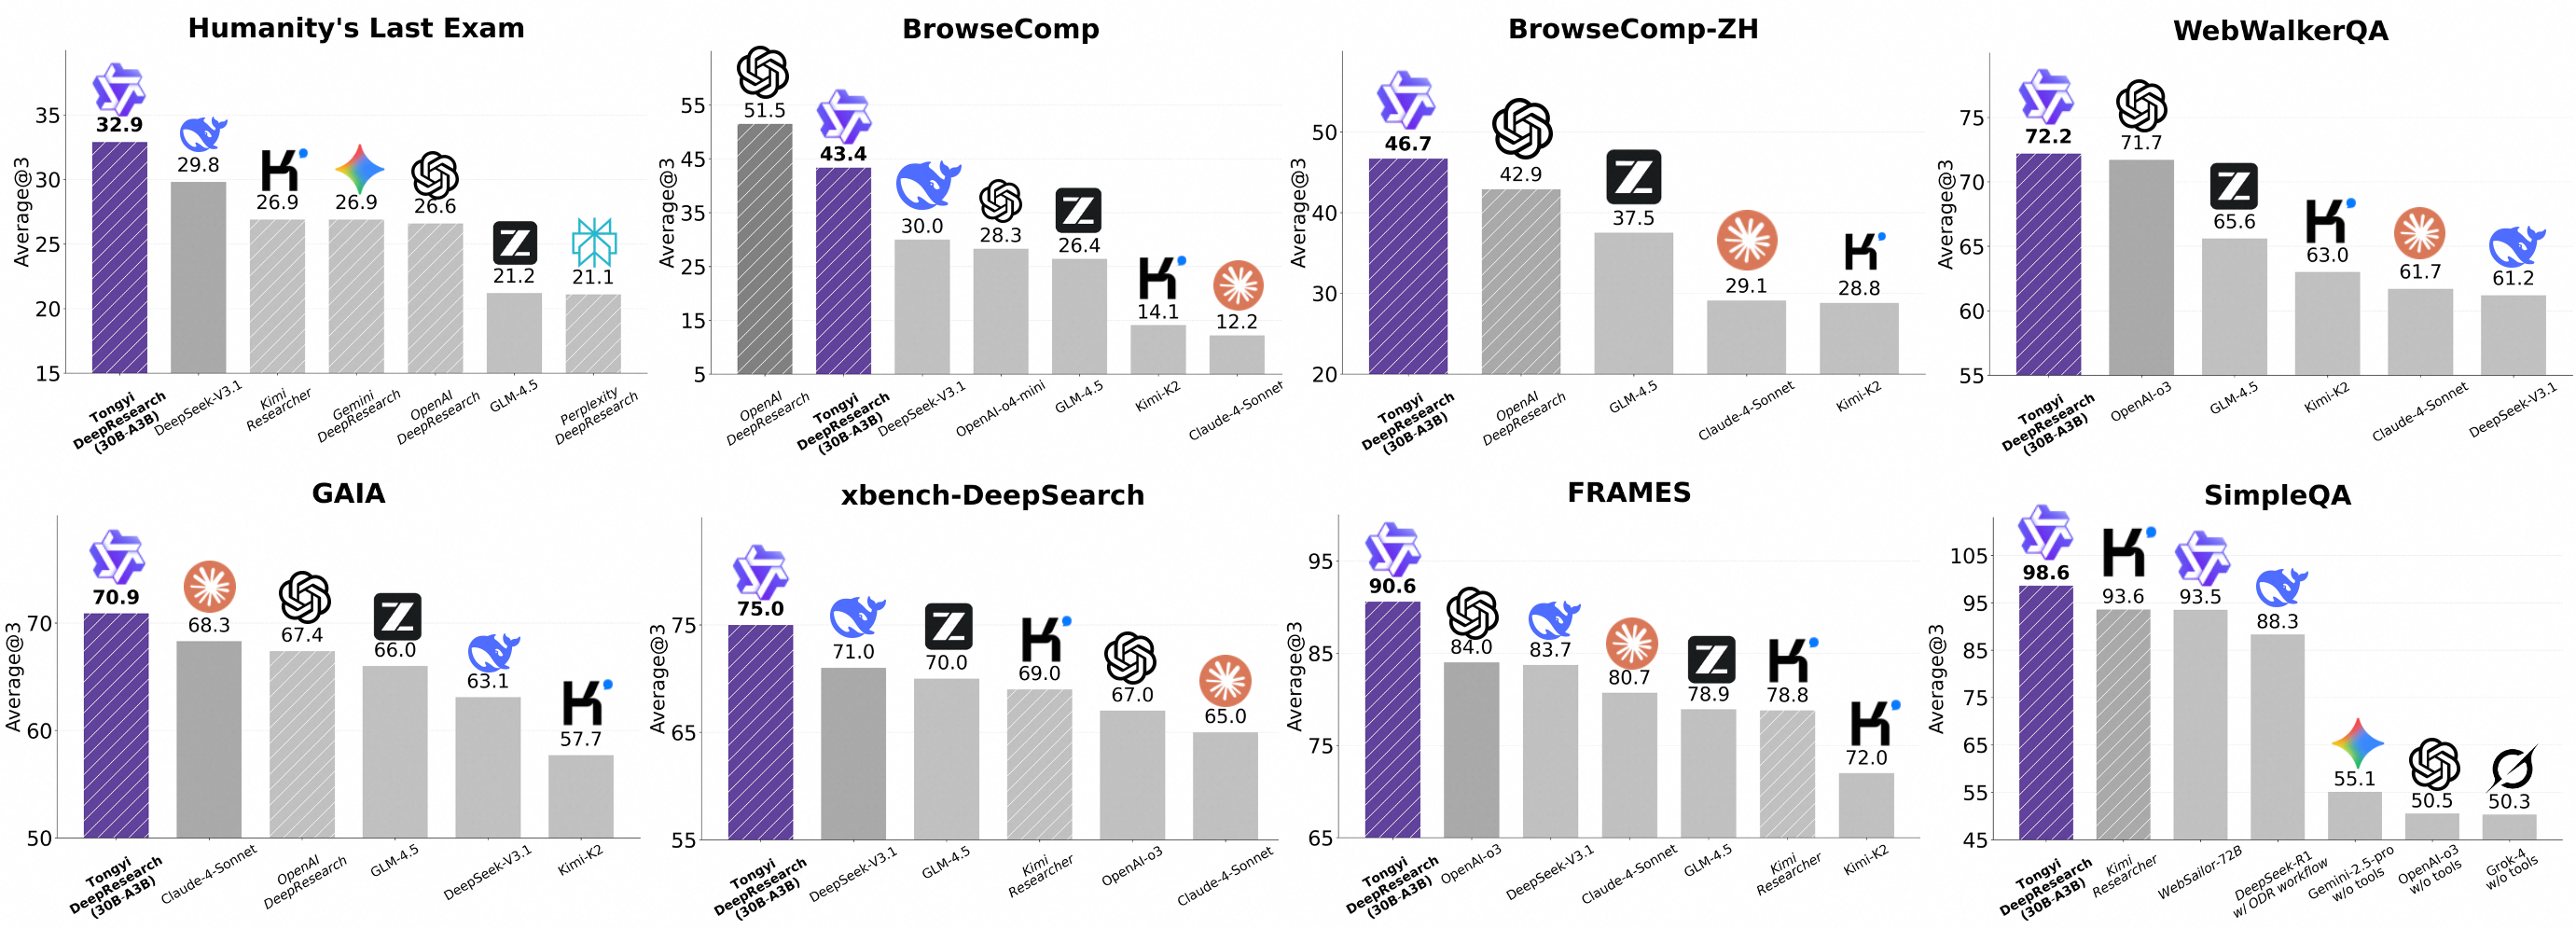
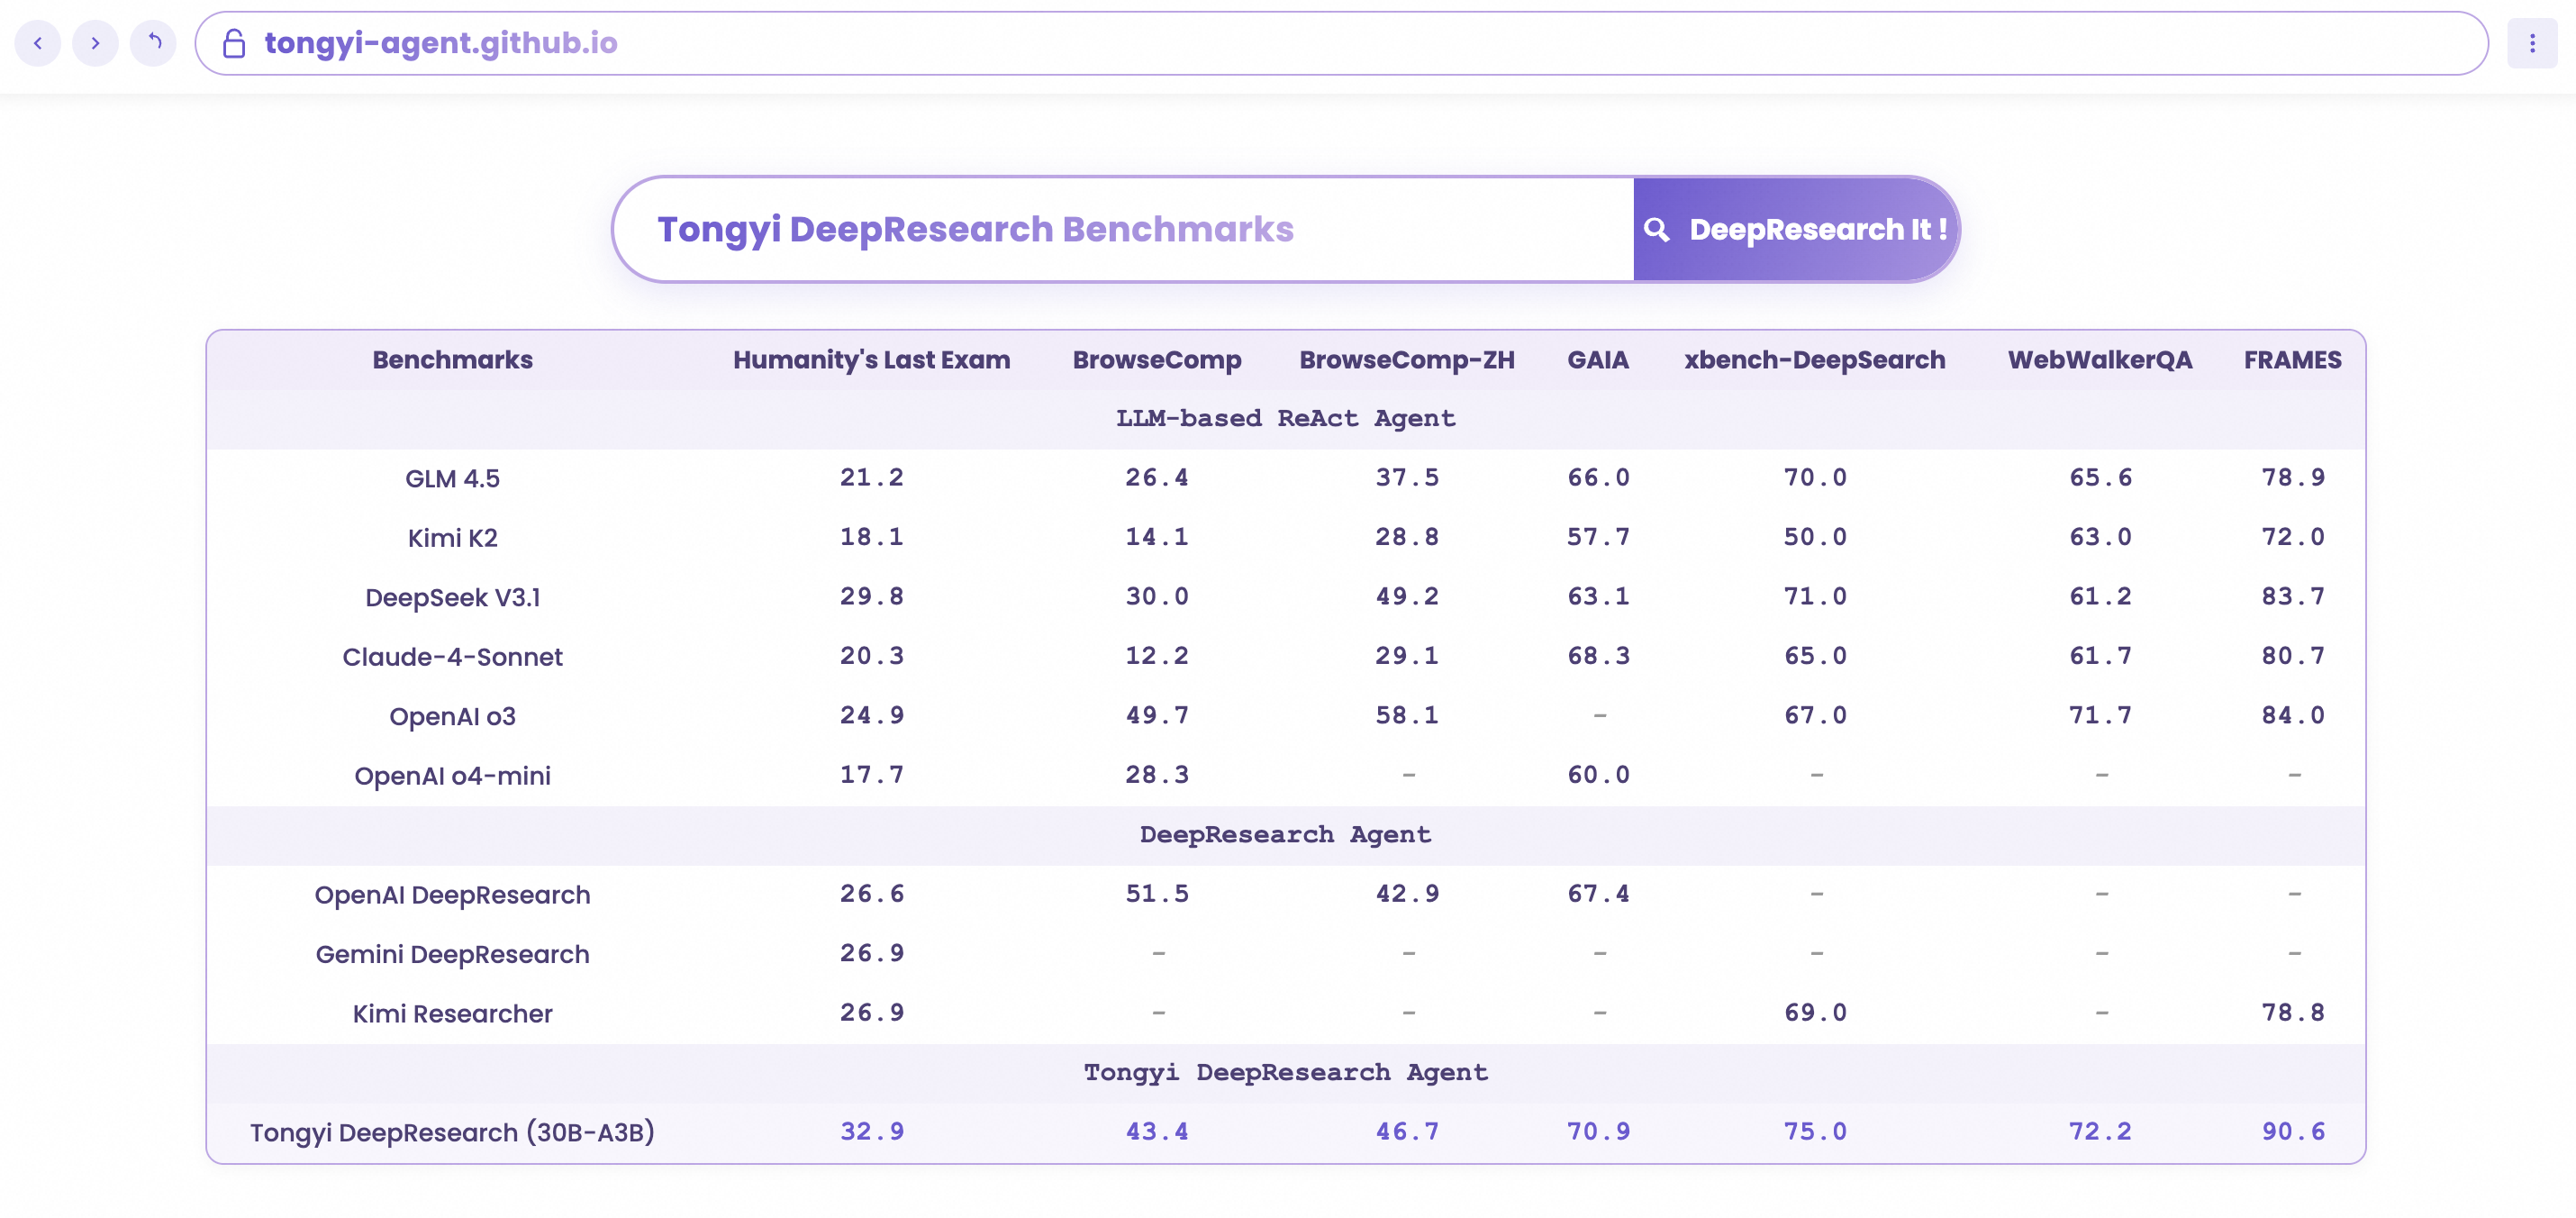
Да — есть демо-версии на ModelScope, HuggingFace и сервисе bailian от Alibaba. Они подходят только для быстрого знакомства: из-за задержек модели и лимитов QPS инструментов могут работать медленно или периодически сбоить.Насколько она сильная на самом деле?По заявлениям авторов, она показывает результаты уровня SOTA в бенчмарках агентного поиска, включая Humanity's Last Exam, BrowseComp, BrowseComp-ZH, WebWalkerQA, xbench-DeepSearch, FRAMES и SimpleQA.
По заявлениям авторов, она показывает результаты уровня SOTA в бенчмарках агентного поиска, включая Humanity's Last Exam, BrowseComp, BrowseComp-ZH, WebWalkerQA, xbench-DeepSearch, FRAMES и SimpleQA.Что такое режим 'Heavy'?Один из двух режимов инференса, которые поддерживает модель: 'Heavy' на основе IterResearch использует test-time scaling, чтобы выжать максимальное качество, а обычный режим ReAct показывает базовые собственные способности модели.
Один из двух режимов инференса, которые поддерживает модель: 'Heavy' на основе IterResearch использует test-time scaling, чтобы выжать максимальное качество, а обычный режим ReAct показывает базовые собственные способности модели.Как обучали модель?Через полностью автоматизированный конвейер синтетических данных, на котором построены агентное продолжающееся предобучение (continual pre-training), дообучение с учителем (SFT) и обучение с подкреплением — этап RL строго on-policy, на базе доработанного фреймворка GRPO с policy-градиентами на уровне токенов.
Через полностью автоматизированный конвейер синтетических данных, на котором построены агентное продолжающееся предобучение (continual pre-training), дообучение с учителем (SFT) и обучение с подкреплением — этап RL строго on-policy, на базе доработанного фреймворка GRPO с policy-градиентами на уровне токенов.Что ей скармливать — мне тоже нужно писать ответы?Оценка запускается на файлах JSON или JSONL с парами вопрос/ответ, но поле с ответом — это правильный ответ (ground truth), который используется только для автоматической проверки ответов модели: сам агент получает лишь вопрос. Файлы для инструмента разбора документов кладутся в evaldata/filecorpus/.
Оценка запускается на файлах JSON или JSONL с парами вопрос/ответ, но поле с ответом — это правильный ответ (ground truth), который используется только для автоматической проверки ответов модели: сам агент получает лишь вопрос. Файлы для инструмента разбора документов кладутся в evaldata/filecorpus/.What are similar projects?NeoHorse, DeepAnalyze, Qwen3.8, minimind, gpt-researcher, Qwen3-Coder, GLM-5, ZDTaichu5.0-9B
NeoHorse, DeepAnalyze, Qwen3.8, minimind, gpt-researcher, Qwen3-Coder, GLM-5, ZDTaichu5.0-9BWhich topics is it in?long-context, alibaba, deep-research, web-search, moe, reinforcement-learning, evaluation, openai-compatible, artificial-intelligence, agentic-ai, huggingface, benchmark
long-context, alibaba, deep-research, web-search, moe, reinforcement-learning, evaluation, openai-compatible, artificial-intelligence, agentic-ai, huggingface, benchmark