SentrySearch
Semantic search over video footage. Type what you're looking for, get a trimmed clip back.
[!IMPORTANT]
Official source: github.com/ssrajadh/sentrysearch is the only official home of SentrySearch. Other sites republishing or mirroring this project are not affiliated with or endorsed by the maintainer, always download from this repository.
Languages: English · 简体中文
New: SentrySearch codebase walkthrough video
The Pipeline:
- SentrySearch (find an event in your footage)
- SentryMerge (auto-cut the multi-cam footage into one video that follows the subject across cameras)
- SentryBlur (auto-redact sensitive information)
Table of Contents
How it works
SentrySearch splits your videos into overlapping chunks, embeds each chunk as video using Google's Gemini Embedding API, Alibaba DashScope (qwen-cloud), or a local Qwen3-VL model, and stores the vectors in a local ChromaDB database. When you search, your text query (or image, see search by image) is embedded into the same vector space and matched against the stored video embeddings. The top match is automatically trimmed from the original file and saved as a clip.
Getting Started
- Install uv (if you don't have it):
macOS/Linux:
curl -LsSf https://astral.sh/uv/install.sh | sh
Windows:
powershell -c "irm https://astral.sh/uv/install.ps1 | iex"
- Clone and install:
git clone https://github.com/ssrajadh/sentrysearch.git
cd sentrysearch
uv tool install .
Requires Python 3.11 or 3.12 (PyTorch wheels don't yet support 3.13+). If your default Python is newer, install a managed 3.12 and pin the tool install:
uv python install 3.12
uv tool install --python 3.12 .
- Set up your API key (or use a local model instead) — only needed for the default Gemini backend; skip if you use
--backend local or --backend qwen-cloud with DASHSCOPE_API_KEY in .env.
sentrysearch init
This prompts for your Gemini API key, writes it to .env, and validates it with a test embedding.
- Index your footage:
sentrysearch index /path/to/footage
- Search:
sentrysearch search "red truck running a stop sign"
ffmpeg is required for video chunking and trimming. If you don't have it system-wide, the bundled imageio-ffmpeg is used automatically.
Manual setup: If you prefer not to use sentrysearch init, you can copy .env.example to .env and add your key from aistudio.google.com/apikey manually.
Usage
Init
$ sentrysearch init
Enter your Gemini API key (get one at https://aistudio.google.com/apikey): ****
Validating API key...
Setup complete. You're ready to go — run `sentrysearch index <directory>` to get started.
If a key is already configured, you'll be asked whether to overwrite it.
Tip: Set a spending limit at aistudio.google.com/billing to prevent accidental overspending.
$ sentrysearch index /path/to/video/footage
Indexing file 1/3: front_2024-01-15_14-30.mp4 [chunk 1/4]
Indexing file 1/3: front_2024-01-15_14-30.mp4 [chunk 2/4]
...
Indexed 12 new chunks from 3 files. Total: 12 chunks from 3 files.
Options:
--chunk-duration 30 — seconds per chunk--overlap 5 — overlap between chunks--no-preprocess — skip downscaling/frame rate reduction (send raw chunks)--target-resolution 480 — target height in pixels for preprocessing--target-fps 5 — target frame rate for preprocessing--no-skip-still — embed all chunks, even ones with no visual change--rpm 10 — cap requests per minute to the cloud API (details below)--backend local — use a local model instead of Gemini (details below)
Search
$ sentrysearch search "red truck running a stop sign"
  #1 [0.87] front_2024-01-15_14-30.mp4 @ 02:15-02:45
  #2 [0.74] left_2024-01-15_14-30.mp4 @ 02:10-02:40
  #3 [0.61] front_2024-01-20_09-15.mp4 @ 00:30-01:00

Saved clip: ./match_front_2024-01-15_14-30_02m15s-02m45s.mp4
If the best result's similarity score is below the confidence threshold (default 0.41), you'll be prompted before trimming:
No confident match found (best score: 0.28). Show results anyway? [y/N]:
With --no-trim, low-confidence results are shown with a note instead of a prompt.
Options: --results N, --output-dir DIR, --no-trim to skip auto-trimming, --threshold 0.5 to adjust the confidence cutoff, --save-top N to save the top N clips instead of just the best match, --dedupe to drop results too similar to a higher-ranked pick (prevents near-duplicate chunks of the same event from filling the list), and --rerank to ask a VLM to re-rank the returned candidates before trimming. Backend and model are auto-detected from the index — pass --backend or --model only to override.
# Save top 5 clips, dropping near-duplicates
sentrysearch search "red truck" --save-top 5 --dedupe 0.9

# Re-rank the top 10 embedding matches with a VLM before trimming
sentrysearch search "pedestrian crossing behind the car" --rerank --results 10
The --dedupe value is a cosine similarity ceiling (0–1). Any result whose similarity to an already-kept higher-ranked result exceeds this value is dropped. Lower values are stricter: 0.8 requires results to be very distinct, 0.95 only removes near-identical chunks. 0.9 is a good default.
--rerank extracts each returned candidate clip, sends it to a VLM with the query, and sorts likely visual matches ahead of embedding-only results. Gemini and qwen-cloud searches use Gemini 2.5 Flash for reranking; local searches use a local Qwen3-VL Instruct reranker. If reranking cannot run or a candidate cannot be scored, SentrySearch keeps the embedding-ranked results instead of failing the search.
Search by image
Use a reference image as the query — useful for "find clips that look like this" when describing the scene in words is awkward (a screenshot of a specific car, a reference frame from another video, etc.).
$ sentrysearch img ~/Downloads/image.jpg
  #1 [0.72] 2026-03-12_10-44-17-left_repeater.mp4 @ 00:00-00:30
  #2 [0.69] 2026-03-12_10-44-17-left_repeater.mp4 @ 00:25-00:55
  #3 [0.67] 2026-02-12_20-02-15-front.mp4 @ 00:00-00:18

Saved clip: ./match_2026-03-12_10-44-17-left_repeater_00m00s-00m30s.mp4
The image is embedded into the same vector space as the indexed video chunks and ranked by cosine similarity. Image search supports --results, --threshold, --save-top, --dedupe, --overlay, --no-trim, --backend, and --model.
Supported formats: JPG, PNG, WEBP, GIF, HEIC/HEIF on the Gemini backend; the local backend additionally accepts anything PIL can decode (BMP, TIFF, etc.).
Note: Image search returns visually similar matches, not necessarily the same object. A red sedan query may surface other red sedans of similar shape — calibrate expectations accordingly.
Highlights
Don't know what to search for? sentrysearch highlights ranks the most anomalous clips in your index — chunks whose embeddings sit far from everything else — and trims them automatically. Good for skimming a fresh dump of footage.
$ sentrysearch highlights -n 3
  #1 [0.165] 2026-02-12_20-02-15-back.mp4 @ 00:00-00:18
  #2 [0.163] 2026-02-12_20-02-15-right_repeater.mp4 @ 00:00-00:18
  #3 [0.149] 2026-02-12_20-02-15-front.mp4 @ 00:00-00:18
...
Scoring methods (--method):
knn (default) — mean cosine distance to a chunk's k nearest neighbors. Robust; surfaces clips with no near-twins.centroid — distance from the index mean. Cheapest, biased toward whatever's underrepresented.lof — Local Outlier Factor. Best when the index has multiple distinct "normal" modes (day vs. night vs. garage).
Refinement options:
--against "<query>" — score anomaly relative to a query. With --against-mode within (default), ranks anomalies among the top matches of the query ("the weird pedestrians in pedestrian clips"). With --against-mode global, finds clips that match the query but are unlike the rest of the index ("rare events of this type").--dedupe 0.9 — drop results too similar to a higher-ranked pick (default 0.9 cosine similarity). Prevents near-duplicate frames from filling the list.--exclude-baseline — drop the half of the index nearest the centroid before scoring. Useful when the index is dominated by repetitive "boring" footage.-k, --neighbors 10 — k for knn/lof.--no-trim — print the ranking without writing clips.
Caveat: Statistically anomalous ≠ interesting. Sensor glitches, lens flare, night frames in a mostly-daytime index, and the lone garage clip all rank high. Use --exclude-baseline and --dedupe to filter the noise, or --against to constrain by topic.
Qwen Cloud (Alibaba DashScope)
Use the optional qwen-cloud backend for DashScope / Model Studio multimodal embeddings (default model qwen3-vl-embedding, overridable with --dashscope-model or DASHSCOPE_EMBEDDING_MODEL):
uv tool install ".[qwen-cloud]"
export DASHSCOPE_API_KEY=...
sentrysearch index /path/to/footage --backend qwen-cloud
sentrysearch search "your query" --backend qwen-cloud
Video uploads: local chunk files are sent to DashScope-managed temporary OSS by the official Python SDK before the API consumes them (the HTTP API expects a URL; the SDK handles upload for you).
Local Backend (no API key needed)
Index and search using a local Qwen3-VL-Embedding model instead of the Gemini API. Free, private, and runs entirely on your machine. For the best search quality, use the Gemini backend — the local 8B model is a solid alternative when you need offline/private search, and the 2B model is a fallback when hardware can't support 8B.
The model is auto-detected from your hardware — qwen8b for NVIDIA GPUs and Macs with 24 GB+ RAM, qwen2b for smaller Macs and CPU-only systems. You can override with --model qwen2b or --model qwen8b. Pick an install based on your hardware:
| Hardware |
Install command |
Auto-detected model |
Notes |
| Apple Silicon, 24 GB+ RAM |
uv tool install ".[local]" |
qwen8b |
Full float16 via MPS |
| Apple Silicon, 16 GB RAM |
uv tool install ".[local]" |
qwen2b |
8B won't fit; 2B uses ~6 GB |
| Apple Silicon, 8 GB RAM |
uv tool install ".[local]" |
qwen2b |
Tight — may swap under load; Gemini API recommended instead |
| NVIDIA, 18 GB+ VRAM |
uv tool install ".[local]" |
qwen8b |
Full bf16 precision (CUDA wheels pulled automatically on Linux/Windows) |
| NVIDIA, 8–16 GB VRAM |
uv tool install ".[local-quantized]" |
qwen8b |
4-bit quantization (~6–8 GB) |
Won't work well: Intel Macs and machines without a dedicated GPU. These fall back to CPU with float32 — too slow and memory-hungry for practical use. Use the Gemini API backend (the default) instead.
Not sure? On Mac, use ".[local]". On NVIDIA, use ".[local-quantized]" — 4-bit quantization works on the widest range of NVIDIA hardware with minimal quality loss. (bitsandbytes requires CUDA and does not work on Mac/MPS.)
Python version: PyTorch wheels lag behind new Python releases, so the local backend requires Python 3.11 or 3.12. If your default Python is 3.13+, install a managed 3.12 and pin the tool install to it:
uv python install 3.12
uv tool install --python 3.12 ".[local]"
Mac prerequisite: Install system FFmpeg (the local model's video processor requires it — the Gemini backend uses a bundled ffmpeg instead):
brew install ffmpeg
Index with --backend local and search — no extra flags needed:
sentrysearch index /path/to/footage --backend local
sentrysearch search "car running a red light"
The search command auto-detects the backend and model from whatever you indexed with. You can also use --model as a shorthand — it implies --backend local:
sentrysearch index /path/to/footage --model qwen2b   # same as --backend local --model qwen2b
sentrysearch search "car running a red light"          # auto-detects local/qwen2b from index
Options:
--model qwen2b — smaller model, lower quality but only ~6 GB memory (also accepts full HuggingFace IDs)--quantize / --no-quantize — force 4-bit quantization on or off (default: auto-detect based on whether bitsandbytes is installed)
Notes:
- First run downloads the model (~16 GB for 8B, ~4 GB for 2B).
- Local
--rerank downloads a separate Qwen3-VL Instruct model (Qwen/Qwen3-VL-8B-Instruct or Qwen/Qwen3-VL-2B-Instruct) in addition to the embedding model.
- Embeddings from different backends and models are not compatible. Each backend/model combination gets its own isolated index, so they can't accidentally mix. If you search with a model that has no indexed data, you'll be told which model was actually used.
- Speed varies by GPU core count — base M-series chips are slower than Pro/Max but produce identical results.
Why the local model is fast
The local backend stays fast and memory-efficient through a few techniques that compound:
- Preprocessing shrinks chunks before they hit the model. Each 30s chunk is downscaled to 480p at 5fps via ffmpeg before embedding. A ~19 MB dashcam chunk becomes ~1 MB — a 95% reduction in pixels the model has to process. Model inference time scales with pixel count, not video duration, so this is the single biggest speedup.
- Low frame sampling. The video processor sends at most 32 frames per chunk to the model (
fps=1.0, max_frames=32). A 30-second chunk produces ~30 frames — not hundreds.
- MRL dimension truncation. Qwen3-VL-Embedding supports Matryoshka Representation Learning. Only the first 768 dimensions of each embedding are kept and L2-normalized, reducing storage and distance computation in ChromaDB.
- Auto-quantization. On NVIDIA GPUs with limited VRAM, the 8B model is automatically loaded in 4-bit (bitsandbytes) — dropping from ~18 GB to ~6-8 GB with minimal quality loss. A 4090 (24 GB) runs the full bf16 model with headroom to spare.
- Still-frame skipping. Chunks with no meaningful visual change (e.g. a parked car) are detected by comparing JPEG file sizes across sampled frames and skipped entirely — saving a full forward pass per chunk.
With all of this, expect ~2-5s per chunk on an A100 and ~3-8s on a T4. On a 4090, the 8B model in bf16 should be in the low single digits per chunk.
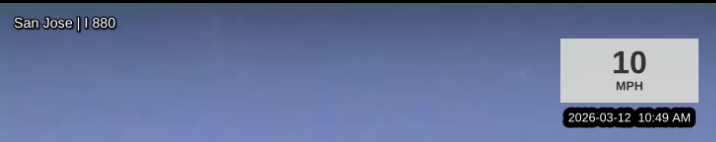
Burn speed, location, and time onto trimmed clips:
sentrysearch search "car cutting me off" --overlay
This extracts telemetry embedded in Tesla dashcam files (speed, GPS) and renders a HUD overlay. The overlay shows:
- Top center: speed and MPH label on a light gray card
- Below card: date and time (12-hour with AM/PM)
- Top left: city and road name (via reverse geocoding)
Requirements:
- Tesla firmware 2025.44.25 or later, HW3+
- SEI metadata is only present in driving footage (not parked/Sentry Mode)
- Reverse geocoding uses OpenStreetMap's Nominatim API via geopy (optional)
Install with Tesla overlay support:
uv tool install ".[tesla]"
Without geopy, the overlay still works but omits the city/road name.
Source: teslamotors/dashcam
Stitch with SentryMerge
SentryMerge is a sibling tool that auto-cuts a single cross-camera video of one event from a SentrySearch result. Every time sentrysearch search runs, it caches the result list to ~/.sentrysearch/last_search.json; SentryMerge picks that up via --last, picks the best multi-camera clip-set, asks a VLM for sub-second visibility ranges per camera, and stitches one frame-accurate video that follows the subject across cameras:
sentrysearch search "<query>"
sentrymerge --last                      # → merge.mp4
--last works without re-running search; sentrymerge --query "..." re-runs search under the hood. See the SentryMerge README for install instructions, VLM backend options (Gemini / OpenAI / local Qwen), and the modular cam-config system for non-Tesla dashcams.
Redact with SentryBlur
SentryBlur is a sibling tool for local face, license plate, and natural-language redaction of video. Every time sentrysearch search saves a clip, it caches the path to ~/.sentrysearch/last_clip.json; SentryBlur picks that up via --last, so search-then-redact is two commands and no path-passing:
sentrysearch search "car cuts me off"
sentryblur prompt --last "road signs"   # → match_<...>_blurred.mp4
sentryblur faces --last and sentryblur plates --last work the same way. Pick faces or plates for fast CPU detectors; use prompt "<text>" for arbitrary objects (phone screens, monitors, name tags) — prompt requires an NVIDIA GPU or Apple Silicon. See the SentryBlur README for install instructions and hardware notes.
Managing the index
# Show index info (files marked [missing] no longer exist on disk)
sentrysearch stats

# Remove specific files by path substring
sentrysearch remove path/to/footage

# Wipe the entire index
sentrysearch reset
Failed chunks and retrying
If a chunk cannot be embedded after retries, SentrySearch records it in a
dead-letter queue (DLQ) at ~/.sentrysearch/dlq.json and continues indexing
the rest of your footage. Chunks usually land there because of repeated
transient API/backend failures, decoder errors for a specific file, missing
files, or out-of-memory errors. Permanent-looking failures such as missing
files, decode errors, and OOM are recorded immediately because retrying the
same chunk with the same settings is unlikely to help.
Inspect failed chunks:
sentrysearch dlq list
Retry them on the next index run

 SentrySearch 是一个命令行工具,让你对视频素材(如 Tesla 行车记录仪片段)进行语义搜索:输入你想找的内容,就能得到裁剪好的对应时刻片段。