Что это такое?
 Noise — это бенчмарк и соревнование по скорости для предобучения трансформера без единого запуска обратного распространения ошибки; проверяется, могут ли другие алгоритмы назначения кредита сравняться с backprop или превзойти его.
Это библиотека или репозиторий соревнования?Это репозиторий соревнования с фиксированной моделью, датасетом и скриптом подсчёта результатов: чтобы отправить рекорд, вы открываете pull request, который правит скрипт обучения трека на месте, а не устанавливаете пакет.
Это репозиторий соревнования с фиксированной моделью, датасетом и скриптом подсчёта результатов: чтобы отправить рекорд, вы открываете pull request, который правит скрипт обучения трека на месте, а не устанавливаете пакет.Как самому запустить бенчмарк?Запустите utils/preparedata.py, чтобы загрузить и токенизировать образец FineWeb в data/train.pt и data/val.pt, затем выполните run.py нужного трека; utils/eval.py после этого пересчитывает результат для любой контрольной точки.
Запустите utils/preparedata.py, чтобы загрузить и токенизировать образец FineWeb в data/train.pt и data/val.pt, затем выполните run.py нужного трека; utils/eval.py после этого пересчитывает результат для любой контрольной точки.Какое железо и инструменты нужны для участия?Нужны Linux, NVIDIA GPU с поддержкой bfloat16 и инструмент Python uv; официальные рекорды замеряются на одном узле с 8xH100.
Нужны Linux, NVIDIA GPU с поддержкой bfloat16 и инструмент Python uv; официальные рекорды замеряются на одном узле с 8xH100.Что считается читерством по правилам?Любой autograd (в прямом или обратном режиме) или написанный вручную проход назад дисквалифицирует заявку; сигнал для обучения должен идти только из прямых вычислений, а на треках 1 и 2 веса модели должны строго соответствовать фиксированной архитектуре.
Любой autograd (в прямом или обратном режиме) или написанный вручную проход назад дисквалифицирует заявку; сигнал для обучения должен идти только из прямых вычислений, а на треках 1 и 2 веса модели должны строго соответствовать фиксированной архитектуре.Что такое Dust?Dust — это эталонный проект, на котором строится этот бенчмарк: он предоставляет трансформер на 37,7 млн параметров, данные для обучения и валидации, полученные из FineWeb, и оценщик без backprop, который текущие рекорды Noise пытаются превзойти.
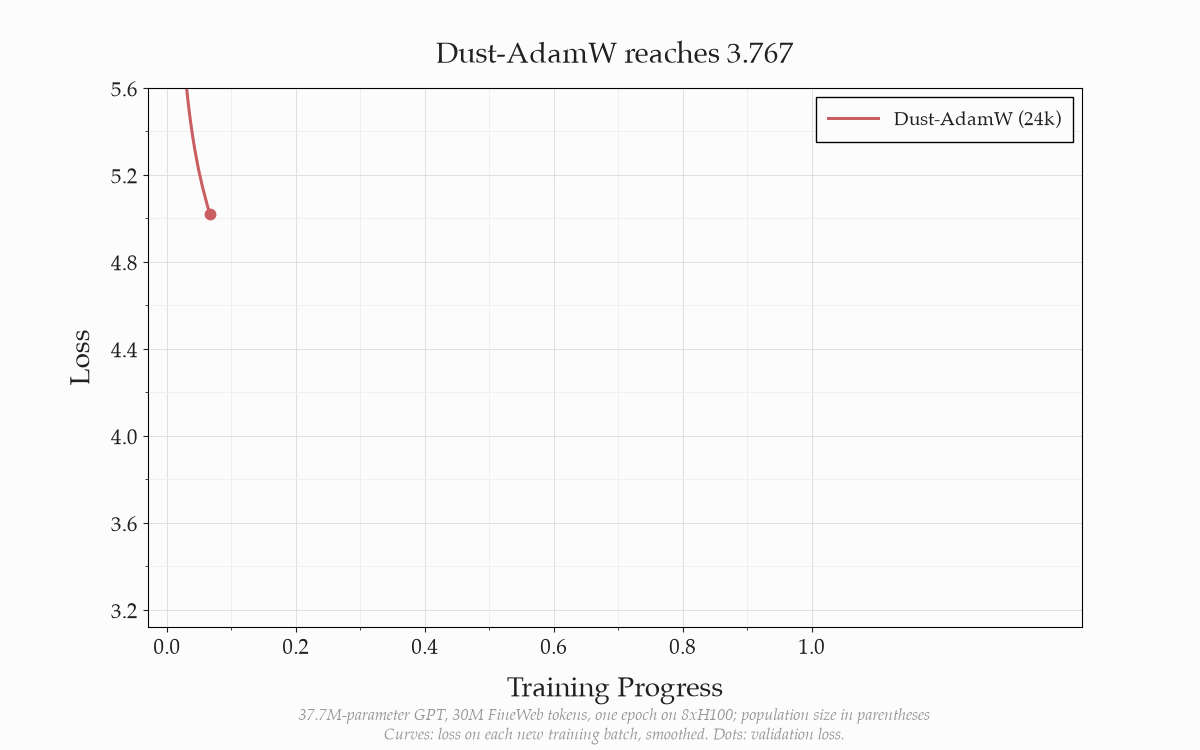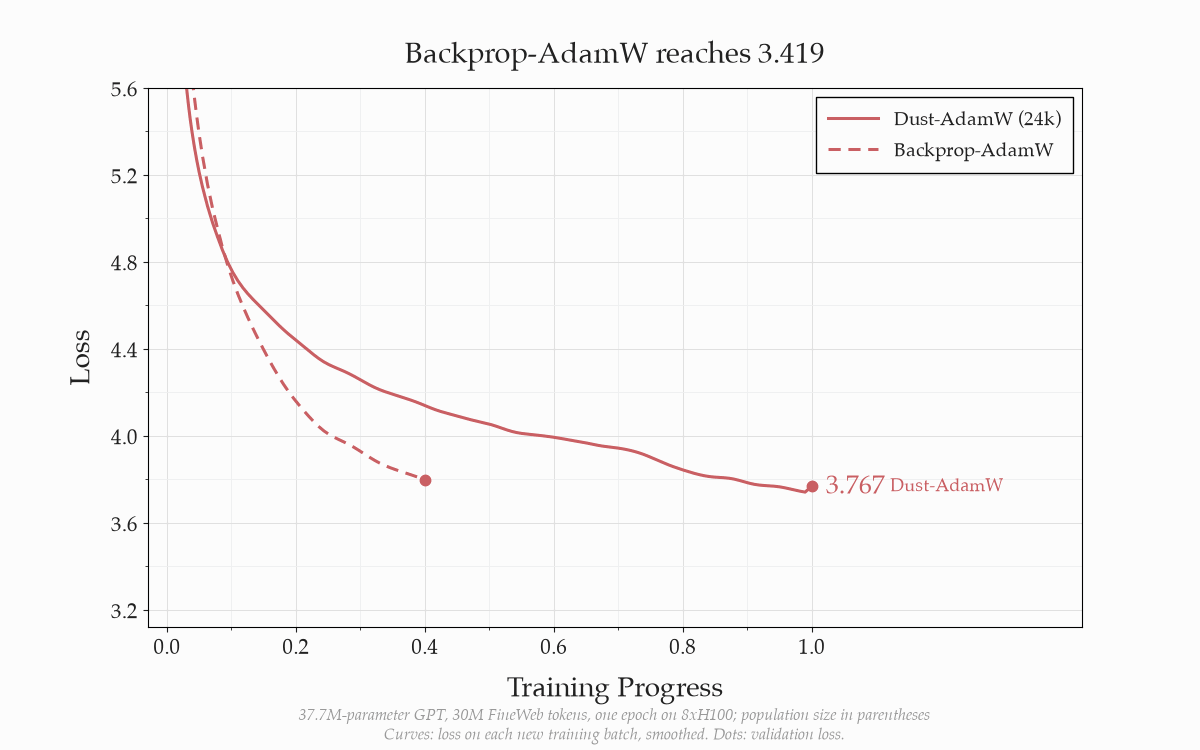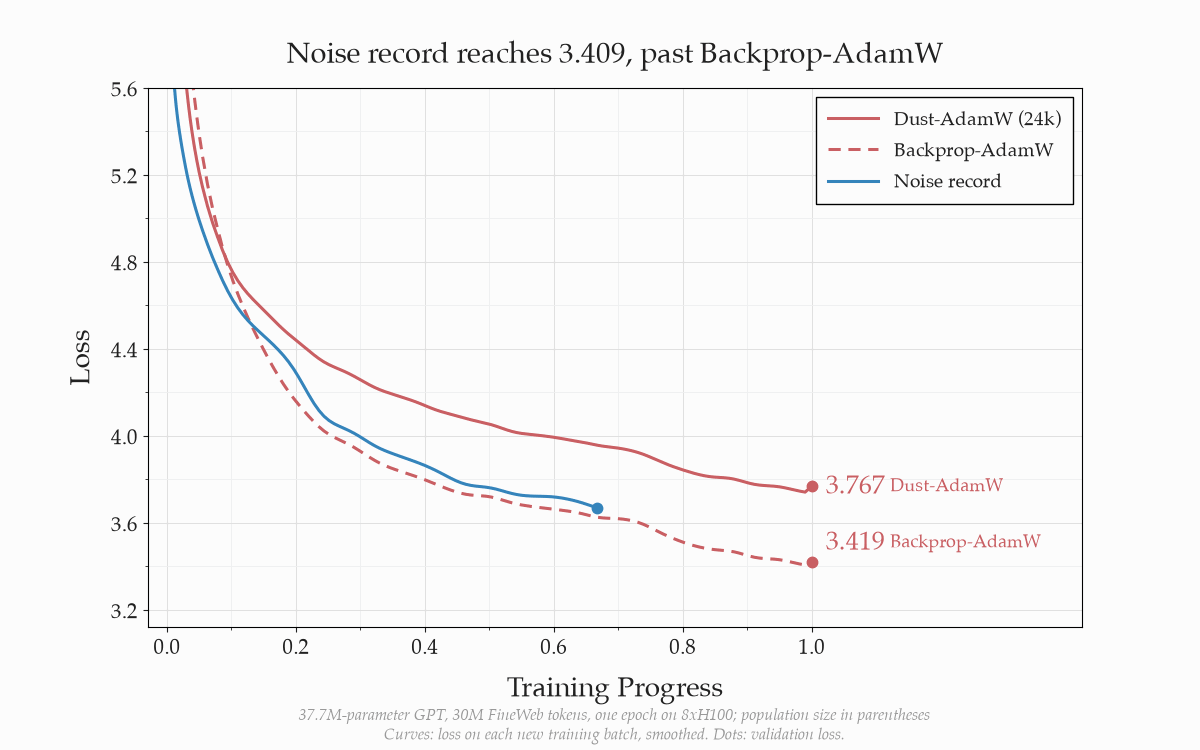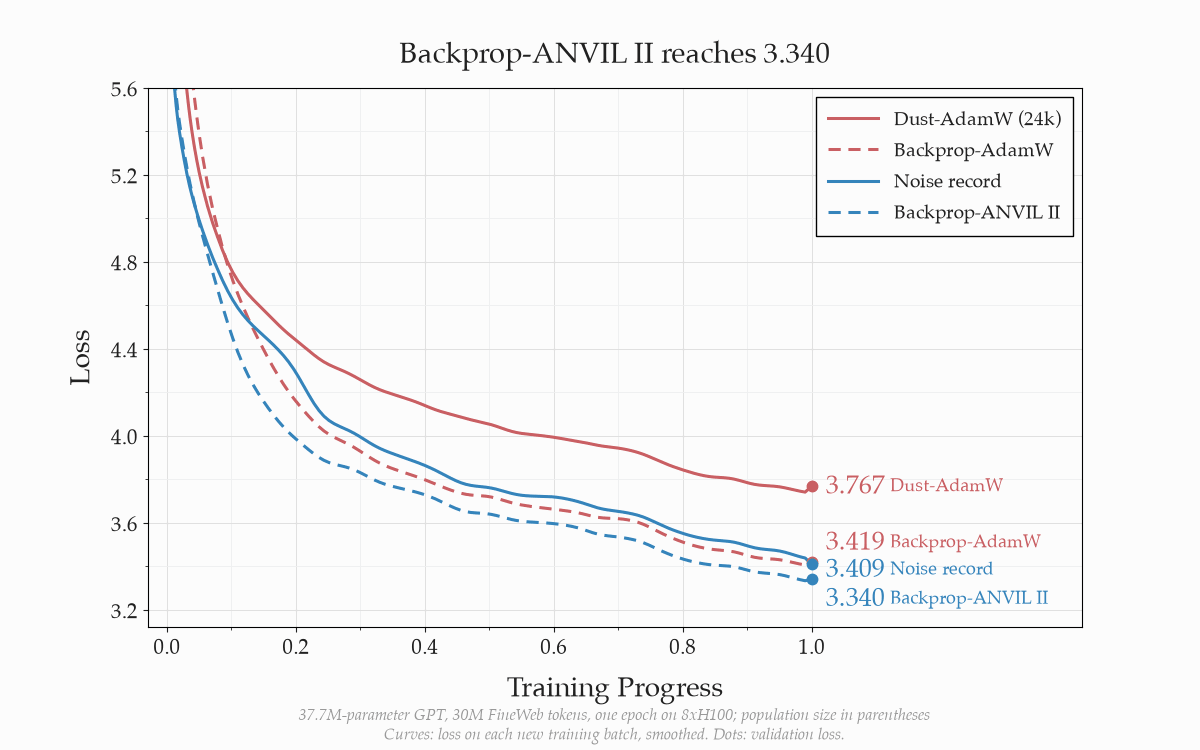
Dust — это эталонный проект, на котором строится этот бенчмарк: он предоставляет трансформер на 37,7 млн параметров, данные для обучения и валидации, полученные из FineWeb, и оценщик без backprop, который текущие рекорды Noise пытаются превзойти.Насколько близко методы без backprop подобрались к backprop?С Adam и охлаждением learning rate обычный backprop достигает функции потерь на валидации 3,419; текущий лучший рекорд без backprop немного его опережает с 3,409, а базовая заявка на основе поиска по популяции доходит лишь до 3,767.
С Adam и охлаждением learning rate обычный backprop достигает функции потерь на валидации 3,419; текущий лучший рекорд без backprop немного его опережает с 3,409, а базовая заявка на основе поиска по популяции доходит лишь до 3,767.Чем отличаются три трека?Трек 1 — это самая низкая функция потерь на валидации без ограничения по времени, трек 2 — самый быстрый запуск до функции потерь 3,5 на валидации, а трек 3 сохраняет правила трека 1, но также позволяет участникам менять саму архитектуру модели.
Трек 1 — это самая низкая функция потерь на валидации без ограничения по времени, трек 2 — самый быстрый запуск до функции потерь 3,5 на валидации, а трек 3 сохраняет правила трека 1, но также позволяет участникам менять саму архитектуру модели.Зачем вообще отказываться от backpropagation?Авторы считают, что по мере роста вычислительных мощностей более универсальные алгоритмы обучения на основе полного перебора и поиска в конце концов обгонят архитектуры и железо, заточенные под backprop, поэтому они стараются сократить это отставание заранее.
Авторы считают, что по мере роста вычислительных мощностей более универсальные алгоритмы обучения на основе полного перебора и поиска в конце концов обгонят архитектуры и железо, заточенные под backprop, поэтому они стараются сократить это отставание заранее.Какие есть похожие проекты?train-llm-from-scratch, Agent-Reflex, nanoGPT, SolarWM, jeeves, pointdit, Attention-Residuals, Intern-Decision
train-llm-from-scratch, Agent-Reflex, nanoGPT, SolarWM, jeeves, pointdit, Attention-Residuals, Intern-DecisionВ каких он темах?model-training, optimization, neural-network, evaluation, transformer, academic-research, large-language-models, nvidia, pytorch, cuda, benchmark, deep-learning
model-training, optimization, neural-network, evaluation, transformer, academic-research, large-language-models, nvidia, pytorch, cuda, benchmark, deep-learning