


This repo is the official implementation of "Swin Transformer: Hierarchical Vision Transformer using Shifted Windows" as well as the follow-ups. It currently includes code and models for the following tasks:
Image Classification: Included in this repo. See get_started.md for a quick start.
Object Detection and Instance Segmentation: See Swin Transformer for Object Detection.
Semantic Segmentation: See Swin Transformer for Semantic Segmentation.
Video Action Recognition: See Video Swin Transformer.
Semi-Supervised Object Detection: See Soft Teacher.
SSL: Contrasitive Learning: See Transformer-SSL.
SSL: Masked Image Modeling: See get_started.md#simmim-support.
Mixture-of-Experts: See get_started for more instructions.
Feature-Distillation: See Feature-Distillation.
Updates
12/29/2022
- Nvidia's FasterTransformer now supports Swin Transformer V2 inference, which have significant speed improvements on
T4 and A100 GPUs.
11/30/2022
- Models and codes of Feature Distillation are released. Please refer to Feature-Distillation for details, and the checkpoints (FD-EsViT-Swin-B, FD-DeiT-ViT-B, FD-DINO-ViT-B, FD-CLIP-ViT-B, FD-CLIP-ViT-L).
09/24/2022
Merged SimMIM, which is a Masked Image Modeling based pre-training approach applicable to Swin and SwinV2 (and also applicable for ViT and ResNet). Please refer to get started with SimMIM to play with SimMIM pre-training.
Released a series of Swin and SwinV2 models pre-trained using the SimMIM approach (see MODELHUB for SimMIM), with model size ranging from SwinV2-Small-50M to SwinV2-giant-1B, data size ranging from ImageNet-1K-10% to ImageNet-22K, and iterations from 125k to 500k. You may leverage these models to study the properties of MIM methods. Please look into the data scaling paper for more details.
07/09/2022
News:
- SwinV2-G achieves
61.4 mIoU on ADE20K semantic segmentation (+1.5 mIoU over the previous SwinV2-G model), using an additional feature distillation (FD) approach, setting a new recrod on this benchmark. FD is an approach that can generally improve the fine-tuning performance of various pre-trained models, including DeiT, DINO, and CLIP. Particularly, it improves CLIP pre-trained ViT-L by +1.6% to reach 89.0% on ImageNet-1K image classification, which is the most accurate ViT-L model.
- Merged a PR from Nvidia that links to faster Swin Transformer inference that have significant speed improvements on
T4 and A100 GPUs.
- Merged a PR from Nvidia that enables an option to use
pure FP16 (Apex O2) in training, while almost maintaining the accuracy.
06/03/2022
- Added Swin-MoE, the Mixture-of-Experts variant of Swin Transformer implemented using Tutel (an optimized Mixture-of-Experts implementation). Swin-MoE is introduced in the TuTel paper.
05/12/2022
- Pretrained models of Swin Transformer V2 on ImageNet-1K and ImageNet-22K are released.
- ImageNet-22K pretrained models for Swin-V1-Tiny and Swin-V2-Small are released.
03/02/2022
- Swin Transformer V2 and SimMIM got accepted by CVPR 2022. SimMIM is a self-supervised pre-training approach based on masked image modeling, a key technique that works out the 3-billion-parameter Swin V2 model using
40x less labelled data than that of previous billion-scale models based on JFT-3B.
02/09/2022
- Integrated into Huggingface Spaces 🤗 using Gradio. Try out the Web Demo

10/12/2021
- Swin Transformer received ICCV 2021 best paper award (Marr Prize).
08/09/2021
- Soft Teacher will appear at ICCV2021. The code will be released at GitHub Repo.
Soft Teacher is an end-to-end semi-supervisd object detection method, achieving a new record on the COCO test-dev: 61.3 box AP and 53.0 mask AP.
07/03/2021
- Add Swin MLP, which is an adaption of
Swin Transformer by replacing all multi-head self-attention (MHSA) blocks by MLP layers (more precisely it is a group linear layer). The shifted window configuration can also significantly improve the performance of vanilla MLP architectures.
06/25/2021
- Video Swin Transformer is released at Video-Swin-Transformer.
Video Swin Transformer achieves state-of-the-art accuracy on a broad range of video recognition benchmarks, including action recognition (84.9 top-1 accuracy on Kinetics-400 and 86.1 top-1 accuracy on Kinetics-600 with ~20x less pre-training data and ~3x smaller model size) and temporal modeling (69.6 top-1 accuracy on Something-Something v2).
05/12/2021
- Used as a backbone for
Self-Supervised Learning: Transformer-SSL
Using Swin-Transformer as the backbone for self-supervised learning enables us to evaluate the transferring performance of the learnt representations on down-stream tasks, which is missing in previous works due to the use of ViT/DeiT, which has not been well tamed for down-stream tasks.
04/12/2021
Initial commits:
- Pretrained models on ImageNet-1K (Swin-T-IN1K, Swin-S-IN1K, Swin-B-IN1K) and ImageNet-22K (Swin-B-IN22K, Swin-L-IN22K) are provided.
- The supported code and models for ImageNet-1K image classification, COCO object detection and ADE20K semantic segmentation are provided.
- The cuda kernel implementation for the local relation layer is provided in branch LR-Net.
Introduction
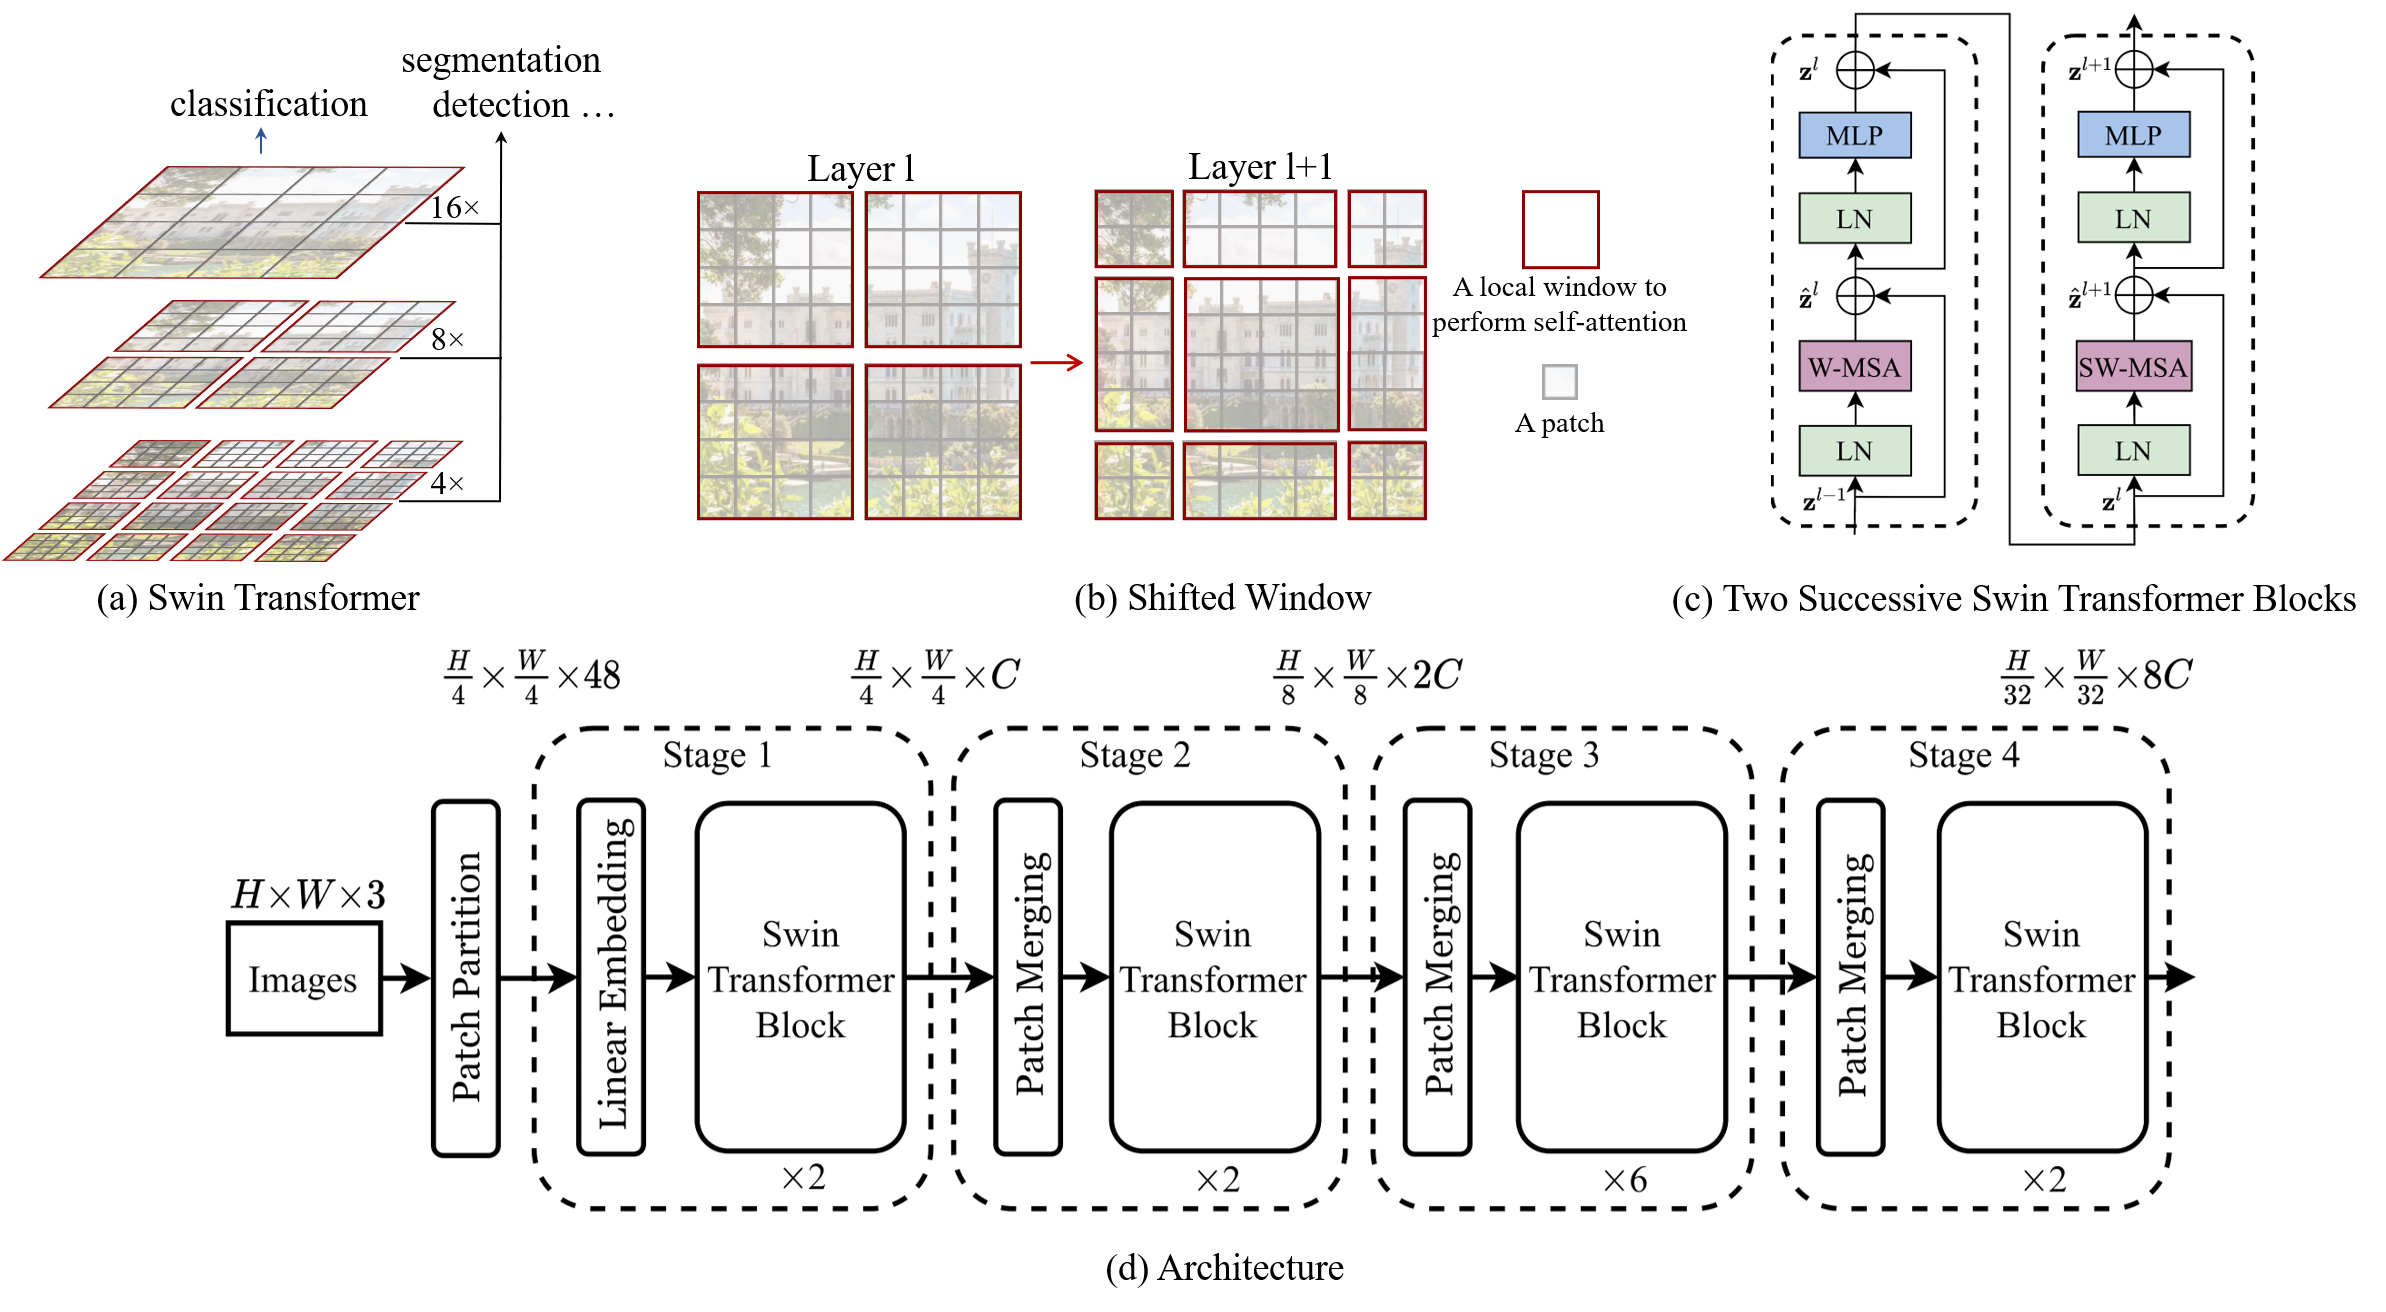
Swin Transformer (the name Swin stands for Shifted window) is initially described in arxiv, which capably serves as a
general-purpose backbone for computer vision. It is basically a hierarchical Transformer whose representation is
computed with shifted windows. The shifted windowing scheme brings greater efficiency by limiting self-attention
computation to non-overlapping local windows while also allowing for cross-window connection.
Swin Transformer achieves strong performance on COCO object detection (58.7 box AP and 51.1 mask AP on test-dev) and
ADE20K semantic segmentation (53.5 mIoU on val), surpassing previous models by a large margin.
Main Results on ImageNet with Pretrained Models
ImageNet-1K and ImageNet-22K Pretrained Swin-V1 Models
ImageNet-1K and ImageNet-22K Pretrained Swin-V2 Models
Note:
- SwinV2-B* (SwinV2-L*) with input resolution of 256x256 and 384x384 both fine-tuned from the same pre-training model using a smaller input resolution of 192x192.
- SwinV2-B* (384x384) achieves 78.08 acc@1 on ImageNet-1K-V2 while SwinV2-L* (384x384) achieves 78.31.
ImageNet-1K Pretrained Swin MLP Models

 这是微软官方对 Swin Transformer 论文及其后续研究的实现:一种分层视觉 Transformer,通过滑动窗口来计算注意力,可作为通用的骨干网络,用于各种计算机视觉任务。