

Swin-Transformer README

The project's README from github.com/microsoft/Swin-Transformer. As one markdown file: README.md.

Swin Transformer

PWC PWC PWC PWC

This repo is the official implementation of "Swin Transformer: Hierarchical Vision Transformer using Shifted Windows" as well as the follow-ups. It currently includes code and models for the following tasks:

Image Classification: Included in this repo. See get_started.md for a quick start.

Object Detection and Instance Segmentation: See Swin Transformer for Object Detection.

Semantic Segmentation: See Swin Transformer for Semantic Segmentation.

Video Action Recognition: See Video Swin Transformer.

Semi-Supervised Object Detection: See Soft Teacher.

SSL: Contrasitive Learning: See Transformer-SSL.

SSL: Masked Image Modeling: See get_started.md#simmim-support.

Mixture-of-Experts: See get_started for more instructions.

Feature-Distillation: See Feature-Distillation.

Updates

12/29/2022

  1. Nvidia's FasterTransformer now supports Swin Transformer V2 inference, which have significant speed improvements on T4 and A100 GPUs.

11/30/2022

  1. Models and codes of Feature Distillation are released. Please refer to Feature-Distillation for details, and the checkpoints (FD-EsViT-Swin-B, FD-DeiT-ViT-B, FD-DINO-ViT-B, FD-CLIP-ViT-B, FD-CLIP-ViT-L).

09/24/2022

  1. Merged SimMIM, which is a Masked Image Modeling based pre-training approach applicable to Swin and SwinV2 (and also applicable for ViT and ResNet). Please refer to get started with SimMIM to play with SimMIM pre-training.

  2. Released a series of Swin and SwinV2 models pre-trained using the SimMIM approach (see MODELHUB for SimMIM), with model size ranging from SwinV2-Small-50M to SwinV2-giant-1B, data size ranging from ImageNet-1K-10% to ImageNet-22K, and iterations from 125k to 500k. You may leverage these models to study the properties of MIM methods. Please look into the data scaling paper for more details.

07/09/2022

News:

  1. SwinV2-G achieves 61.4 mIoU on ADE20K semantic segmentation (+1.5 mIoU over the previous SwinV2-G model), using an additional feature distillation (FD) approach, setting a new recrod on this benchmark. FD is an approach that can generally improve the fine-tuning performance of various pre-trained models, including DeiT, DINO, and CLIP. Particularly, it improves CLIP pre-trained ViT-L by +1.6% to reach 89.0% on ImageNet-1K image classification, which is the most accurate ViT-L model.
  2. Merged a PR from Nvidia that links to faster Swin Transformer inference that have significant speed improvements on T4 and A100 GPUs.
  3. Merged a PR from Nvidia that enables an option to use pure FP16 (Apex O2) in training, while almost maintaining the accuracy.

06/03/2022

  1. Added Swin-MoE, the Mixture-of-Experts variant of Swin Transformer implemented using Tutel (an optimized Mixture-of-Experts implementation). Swin-MoE is introduced in the TuTel paper.

05/12/2022

  1. Pretrained models of Swin Transformer V2 on ImageNet-1K and ImageNet-22K are released.
  2. ImageNet-22K pretrained models for Swin-V1-Tiny and Swin-V2-Small are released.

03/02/2022

  1. Swin Transformer V2 and SimMIM got accepted by CVPR 2022. SimMIM is a self-supervised pre-training approach based on masked image modeling, a key technique that works out the 3-billion-parameter Swin V2 model using 40x less labelled data than that of previous billion-scale models based on JFT-3B.

02/09/2022

  1. Integrated into Huggingface Spaces 🤗 using Gradio. Try out the Web Demo Hugging Face Spaces

10/12/2021

  1. Swin Transformer received ICCV 2021 best paper award (Marr Prize).

08/09/2021

  1. Soft Teacher will appear at ICCV2021. The code will be released at GitHub Repo. Soft Teacher is an end-to-end semi-supervisd object detection method, achieving a new record on the COCO test-dev: 61.3 box AP and 53.0 mask AP.

07/03/2021

  1. Add Swin MLP, which is an adaption of Swin Transformer by replacing all multi-head self-attention (MHSA) blocks by MLP layers (more precisely it is a group linear layer). The shifted window configuration can also significantly improve the performance of vanilla MLP architectures.

06/25/2021

  1. Video Swin Transformer is released at Video-Swin-Transformer. Video Swin Transformer achieves state-of-the-art accuracy on a broad range of video recognition benchmarks, including action recognition (84.9 top-1 accuracy on Kinetics-400 and 86.1 top-1 accuracy on Kinetics-600 with ~20x less pre-training data and ~3x smaller model size) and temporal modeling (69.6 top-1 accuracy on Something-Something v2).

05/12/2021

  1. Used as a backbone for Self-Supervised Learning: Transformer-SSL

Using Swin-Transformer as the backbone for self-supervised learning enables us to evaluate the transferring performance of the learnt representations on down-stream tasks, which is missing in previous works due to the use of ViT/DeiT, which has not been well tamed for down-stream tasks.

04/12/2021

Initial commits:

  1. Pretrained models on ImageNet-1K (Swin-T-IN1K, Swin-S-IN1K, Swin-B-IN1K) and ImageNet-22K (Swin-B-IN22K, Swin-L-IN22K) are provided.
  2. The supported code and models for ImageNet-1K image classification, COCO object detection and ADE20K semantic segmentation are provided.
  3. The cuda kernel implementation for the local relation layer is provided in branch LR-Net.

Introduction

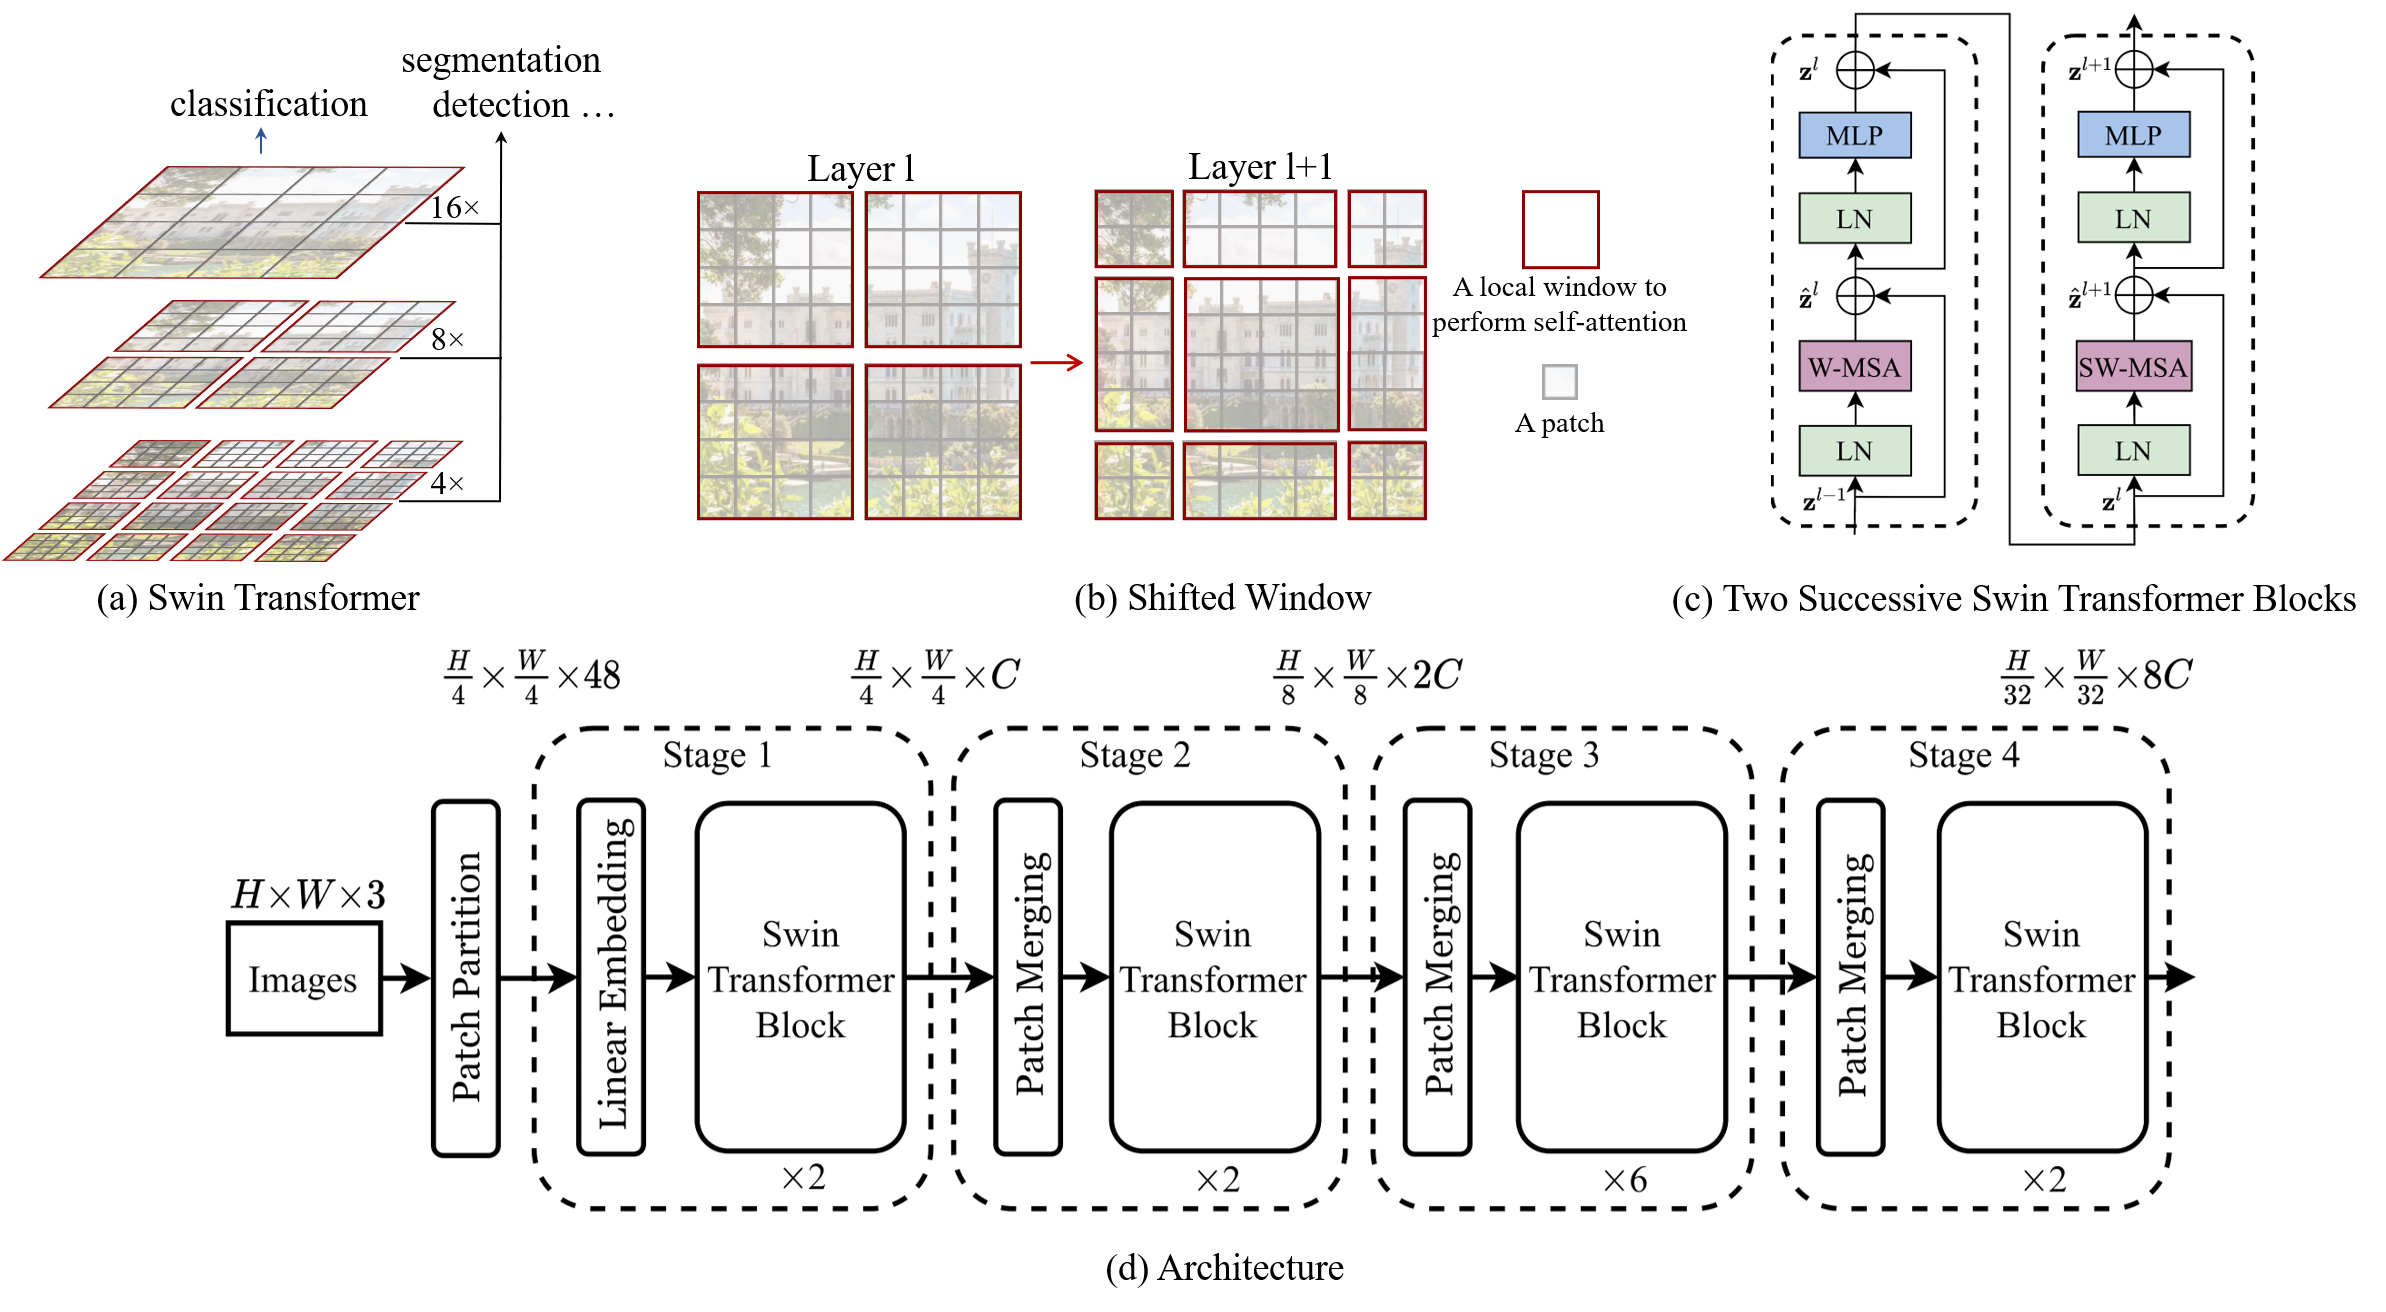
Swin Transformer (the name Swin stands for Shifted window) is initially described in arxiv, which capably serves as a general-purpose backbone for computer vision. It is basically a hierarchical Transformer whose representation is computed with shifted windows. The shifted windowing scheme brings greater efficiency by limiting self-attention computation to non-overlapping local windows while also allowing for cross-window connection.

Swin Transformer achieves strong performance on COCO object detection (58.7 box AP and 51.1 mask AP on test-dev) and ADE20K semantic segmentation (53.5 mIoU on val), surpassing previous models by a large margin.

teaser

Main Results on ImageNet with Pretrained Models

ImageNet-1K and ImageNet-22K Pretrained Swin-V1 Models

name pretrain resolution acc@1 acc@5 #params FLOPs FPS 22K model 1K model
Swin-T ImageNet-1K 224x224 81.2 95.5 28M 4.5G 755 - github/baidu/config/log
Swin-S ImageNet-1K 224x224 83.2 96.2 50M 8.7G 437 - github/baidu/config/log
Swin-B ImageNet-1K 224x224 83.5 96.5 88M 15.4G 278 - github/baidu/config/log
Swin-B ImageNet-1K 384x384 84.5 97.0 88M 47.1G 85 - github/baidu/config
Swin-T ImageNet-22K 224x224 80.9 96.0 28M 4.5G 755 github/baidu/config github/baidu/config
Swin-S ImageNet-22K 224x224 83.2 97.0 50M 8.7G 437 github/baidu/config github/baidu/config
Swin-B ImageNet-22K 224x224 85.2 97.5 88M 15.4G 278 github/baidu/config github/baidu/config
Swin-B ImageNet-22K 384x384 86.4 98.0 88M 47.1G 85 github/baidu github/baidu/config
Swin-L ImageNet-22K 224x224 86.3 97.9 197M 34.5G 141 github/baidu/config github/baidu/config
Swin-L ImageNet-22K 384x384 87.3 98.2 197M 103.9G 42 github/baidu github/baidu/config

ImageNet-1K and ImageNet-22K Pretrained Swin-V2 Models

name pretrain resolution window acc@1 acc@5 #params FLOPs FPS 22K model 1K model
SwinV2-T ImageNet-1K 256x256 8x8 81.8 95.9 28M 5.9G 572 - github/baidu/config
SwinV2-S ImageNet-1K 256x256 8x8 83.7 96.6 50M 11.5G 327 - github/baidu/config
SwinV2-B ImageNet-1K 256x256 8x8 84.2 96.9 88M 20.3G 217 - github/baidu/config
SwinV2-T ImageNet-1K 256x256 16x16 82.8 96.2 28M 6.6G 437 - github/baidu/config
SwinV2-S ImageNet-1K 256x256 16x16 84.1 96.8 50M 12.6G 257 - github/baidu/config
SwinV2-B ImageNet-1K 256x256 16x16 84.6 97.0 88M 21.8G 174 - github/baidu/config
SwinV2-B* ImageNet-22K 256x256 16x16 86.2 97.9 88M 21.8G 174 github/baidu/config github/baidu/config
SwinV2-B* ImageNet-22K 384x384 24x24 87.1 98.2 88M 54.7G 57 github/baidu/config github/baidu/config
SwinV2-L* ImageNet-22K 256x256 16x16 86.9 98.0 197M 47.5G 95 github/baidu/config github/baidu/config
SwinV2-L* ImageNet-22K 384x384 24x24 87.6 98.3 197M 115.4G 33 github/baidu/config github/baidu/config

Note:

ImageNet-1K Pretrained Swin MLP Models

name pretrain resolution acc@1 acc@5 #params FLOPs FPS 1K model
Mixer-B/16 ImageNet-1K 224x224 76.4 - 59M 12.7G - official repo
ResMLP-S24 Imag

Swin-Transformer (microsoft/Swin-Transformer)

Searching Database…

16.1K ·GitHub
archived
Что это такое?Официальная реализация от Microsoft статьи про Swin Transformer и её продолжений: иерархический vision Transformer, который вычисляет внимание через сдвигаемые окна и служит универсальной основой (backbone) для задач компьютерного зрения.
Это готовое приложение или код и модели для исследователей?Это исследовательская кодовая база, а не приложение: код для обучения и оценки плюс MODELHUB с предобученными чекпоинтами (Swin-T/S/B/L, SwinV2, Swin MLP), которые вы скачиваете и дообучаете под свою задачу.
С чего начать работу с ним?Начните с быстрого старта в getstarted.md для классификации изображений, затем перейдите по ссылкам на репозитории для детекции, сегментации и остальных задач; предобученные модели ImageNet-1K/22K скачиваются по ссылкам на GitHub или Baidu из таблиц с результатами.
Проект ещё активно развивается?Нет. Репозиторий заархивирован и доступен только для чтения, а его changelog заканчивается декабрём 2022 года — относитесь к нему как к исследовательскому артефакту, сопровождающему статьи, а не как к поддерживаемому инструменту.
Какое железо нужно, чтобы запускать или обучать эти модели?GPU от Nvidia: заявленные показатели FPS предполагают инференс на GPU, обучение можно запускать в чистом FP16 через Nvidia Apex O2, а FasterTransformer даёт значительное ускорение инференса на GPU T4 и A100. Размер моделей — от 28 млн до примерно 3 млрд параметров, так что выбирайте под свои задачи.
В чём идея сдвигаемых окон и почему она важна?Swin вычисляет self-attention внутри непересекающихся локальных окон и сдвигает разбиение на окна между слоями, ограничивая объём вычислений, но сохраняя связи между окнами. Именно эта эффективность позволяет масштабировать его как универсальную основу для детекции и сегментации, а не только для классификации.
Какие задачи и продолжения охватывает репозиторий?Помимо классификации на ImageNet, он содержит ссылки на код и модели для детекции объектов и сегментации экземпляров на COCO, семантической сегментации на ADE20K, распознавания действий в видео (Video Swin), полуконтролируемой детекции (Soft Teacher), самоконтролируемого предобучения (SimMIM, Transformer-SSL), Swin-MoE и дистилляции признаков.
Насколько точны предобученные модели?Swin-L на 384px достигает 87.3% top-1 на ImageNet-1K после предобучения на ImageNet-22K, 58.7 box AP на COCO и 53.5 mIoU на ADE20K. SwinV2-G доводит ADE20K до рекордных 61.4 mIoU, а линейка масштабируется от Swin-T (28 млн параметров) до SwinV2-G с 3 млрд параметров.
Можно попробовать без установки чего-либо?Да — модель интегрирована в Huggingface Spaces с веб-демо на Gradio, так что вы можете попробовать её в браузере, прежде чем настраивать окружение с GPU.
Creator
microsoft
Size
1.1 MB
Stars
16.1K
Updated
CommitJul 15
Age
5y
Commits · 90 Days