sherpa-onnx README

The project's README from github.com/k2-fsa/sherpa-onnx. As one markdown file: README.md.

Ask DeepWiki

Supported functions

Speech recognition Speech synthesis Source separation
✔️ ✔️ ✔️
Speaker identification Speaker diarization Speaker verification
✔️ ✔️ ✔️
Spoken Language identification Audio tagging Voice activity detection
✔️ ✔️ ✔️
Keyword spotting Add punctuation Speech enhancement
✔️ ✔️ ✔️

Supported platforms

Architecture Android iOS Windows macOS linux HarmonyOS
x64 ✔️ ✔️ ✔️ ✔️ ✔️
x86 ✔️ ✔️
arm64 ✔️ ✔️ ✔️ ✔️ ✔️ ✔️
arm32 ✔️ ✔️ ✔️
riscv64 ✔️

Supported programming languages

1. C++ 2. C 3. Python 4. JavaScript
✔️ ✔️ ✔️ ✔️
5. Java 6. C# 7. Kotlin 8. Swift
✔️ ✔️ ✔️ ✔️
9. Go 10. Dart 11. Rust 12. Pascal
✔️ ✔️ ✔️ ✔️

It also supports WebAssembly.

Supported frameworks

Flutter

Architecture Android iOS Windows macOS Linux Web
x64 ✔️ ✔️ ✔️ ✔️ ✔️
x86 ✔️ ✔️
arm64 ✔️ ✔️ ✔️ ✔️ ✔️ ✔️
arm32 ✔️ ✔️

Tauri

Architecture Android iOS Windows macOS Linux
x64 ✔️ ✔️ ✔️ ✔️
x86 ✔️
arm64 ✔️ ✔️ ✔️ ✔️ ✔️
arm32 ✔️

Supported NPUs

1. Rockchip NPU (RKNN) 2. Qualcomm NPU (QNN) 3. Ascend NPU
✔️ ✔️ ✔️
4. Axera NPU 5. Intel NPU (OpenVINO)
✔️ ✔️

Join our discord

Introduction

This repository supports running the following functions locally

on the following platforms and operating systems:

with the following APIs

You can visit the following Huggingface spaces to try sherpa-onnx without installing anything. All you need is a browser.
Description URL 中国镜像
Speaker diarization Click me 镜像
Speech recognition Click me 镜像
Speech recognition with Whisper Click me 镜像
Speech synthesis Click me 镜像
Generate subtitles Click me 镜像
Audio tagging Click me 镜像
Source separation Click me 镜像
Spoken language identification with Whisper Click me 镜像

We also have spaces built using WebAssembly. They are listed below:

Description Huggingface space ModelScope space
Voice activity detection with silero-vad Click me 地址
Real-time speech recognition (Chinese + English) with Zipformer Click me 地址
Real-time speech recognition (Chinese + English) with Paraformer Click me 地址
Real-time speech recognition (Chinese + English + Cantonese) with Paraformer-large Click me 地址
Real-time speech recognition (English) Click me 地址
VAD + speech recognition (Chinese) with Zipformer CTC Click me 地址
VAD + speech recognition (Chinese + English + Korean + Japanese + Cantonese) with SenseVoice Click me 地址
VAD + speech recognition (English) with Whisper tiny.en Click me 地址
VAD + speech recognition (English) with Moonshine tiny Click me 地址
VAD + speech recognition (English) with Zipformer trained with GigaSpeech Click me 地址
VAD + speech recognition (Chinese) with Zipformer trained with WenetSpeech Click me 地址
VAD + speech recognition (Japanese) with Zipformer trained with ReazonSpeech Click me 地址
VAD + speech recognition (Thai) with Zipformer trained with GigaSpeech2 Click me 地址
VAD + speech recognition (Chinese 多种方言) with a TeleSpeech-ASR CTC model Click me 地址
VAD + speech recognition (English + Chinese, 及多种中文方言) with Paraformer-large Click me 地址
VAD + speech recognition (English + Chinese, 及多种中文方言) with Paraformer-small Click me 地址
VAD + speech recognition (多语种及多种中文方言) with Dolphin-base Click me 地址
Speech synthesis (Piper, English) Click me 地址
Speech synthesis (Piper, German) Click me 地址
Speech synthesis (Matcha, Chinese) Click me 地址
Speech synthesis (Matcha, English) Click me 地址
Speech synthesis (Matcha, Chinese+English) Click me 地址
Speaker diarization Click me 地址
Voice cloning with ZipVoice (Chinese+English) Click me 地址
Voice cloning with Pocket TTS (English) Click me 地址
You can find pre-built Android APKs for this repository in the following table
Description URL 中国用户
Speaker diarization Address 点此
Streaming speech recognition Address 点此
Simulated-streaming speech recognition Address 点此
Text-to-speech Address 点此
Voice activity detection (VAD) Address 点此
VAD + non-streaming speech recognition Address 点此
Two-pass speech recognition Address 点此
Audio tagging Address 点此
Audio tagging (WearOS) Address 点此
Speaker identification Address 点此
Spoken language identification Address 点此
Keyword spotting Address 点此

Real-time speech recognition

Description URL 中国用户
Streaming speech recognition Address 点此

Text-to-speech

Description URL 中国用户
Android (arm64-v8a, armeabi-v7a, x86_64) Address 点此
Linux (x64) Address 点此
macOS (x64) Address 点此
macOS (arm64) Address 点此
Windows (x64) Address 点此

Note: You need to build from source for iOS.

Generating subtitles

Description URL 中国用户
Generate subtitles (生成字幕) Address 点此
Description URL
Speech recognition (speech to text, ASR) Address
Text-to-speech (TTS) Address
VAD Address
Keyword spotting Address
Audio tagging Address
Speaker identification (Speaker ID) Address
Spoken language identification (Language ID) See multi-lingual Whisper ASR models from Speech recognition
Punctuation Address
Speaker segmentation Address
Speech enhancement Address
Source separation Address

Some pre-trained ASR models (Streaming)

Please see

for more models. The following table lists only SOME of them.

Name Supported Languages Description
sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20 Chinese, English See also
sherpa-onnx-streaming-zipformer-small-bilingual-zh-en-2023-02-16 Chinese, English See also
sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23 Chinese Suitable for Cortex A7 CPU. See also
sherpa-onnx-streaming-zipformer-en-20M-2023-02-17 English Suitable for Cortex A7 CPU. See also
sherpa-onnx-streaming-zipformer-korean-2024-06-16 Korean See also
sherpa-onnx-streaming-zipformer-fr-2023-04-14 French See also

Some pre-trained ASR models (Non-Streaming)

Please see

for more models. The following table lists only SOME of them.

Name Supported Languages Description
sherpa-onnx-nemo-parakeet-tdt-0.6b-v2-int8 English It is converted from https://huggingface.co/nvidia/parakeet-tdt-0.6b-v2
Whisper tiny.en English See also
Moonshine tiny English See also
sherpa-onnx-zipformer-ctc-zh-int8-2025-07-03 Chinese A Zipformer CTC model
sherpa-onnx-sense-voice-zh-en-ja-ko-yue-2024-07-17 Chinese, Cantonese, English, Korean, Japanese 支持多种中文方言. See also
sherpa-onnx-paraformer-zh-2024-03-09 Chinese, English 也支持多种中文方言. See also
sherpa-onnx-zipformer-ja-reazonspeech-2024-08-01 Japanese See also
sherpa-onnx-nemo-transducer-giga-am-russian-2024-10-24 Russian See also
sherpa-onnx-nemo-ctc-giga-am-russian-2024-10-24 Russian See also
sherpa-onnx-zipformer-ru-2024-09-18 Russian See also
sherpa-onnx-zipformer-korean-2024-06-24 Korean See also
sherpa-onnx-zipformer-thai-2024-06-20 Thai See also
sherpa-onnx-telespeech-ctc-int8-zh-2024-06-04 Chinese 支持多种方言. See also

How to reach us

Please see https://k2-fsa.github.io/sherpa/social-groups.html for 新一代 Kaldi 微信交流群 and QQ 交流群.

Projects using sherpa-onnx

Sherpa Voice / @siteed/sherpa-onnx.rn

React Native wrapper and demo app for validating sherpa-onnx on iOS, Android, and Web, including ASR, TTS, VAD, KWS, speaker ID, diarization, language ID, punctuation, audio tagging, and speech enhancement.

Speed of Sound

A voice-typing application for the Linux desktop (GTK4/Adwaita). It captures microphone audio, transcribes it offline using Sherpa ONNX ASR models, optionally polishes the text with an LLM, and types the result into the active window via XDG Remote Desktop Portal keyboard simulation.

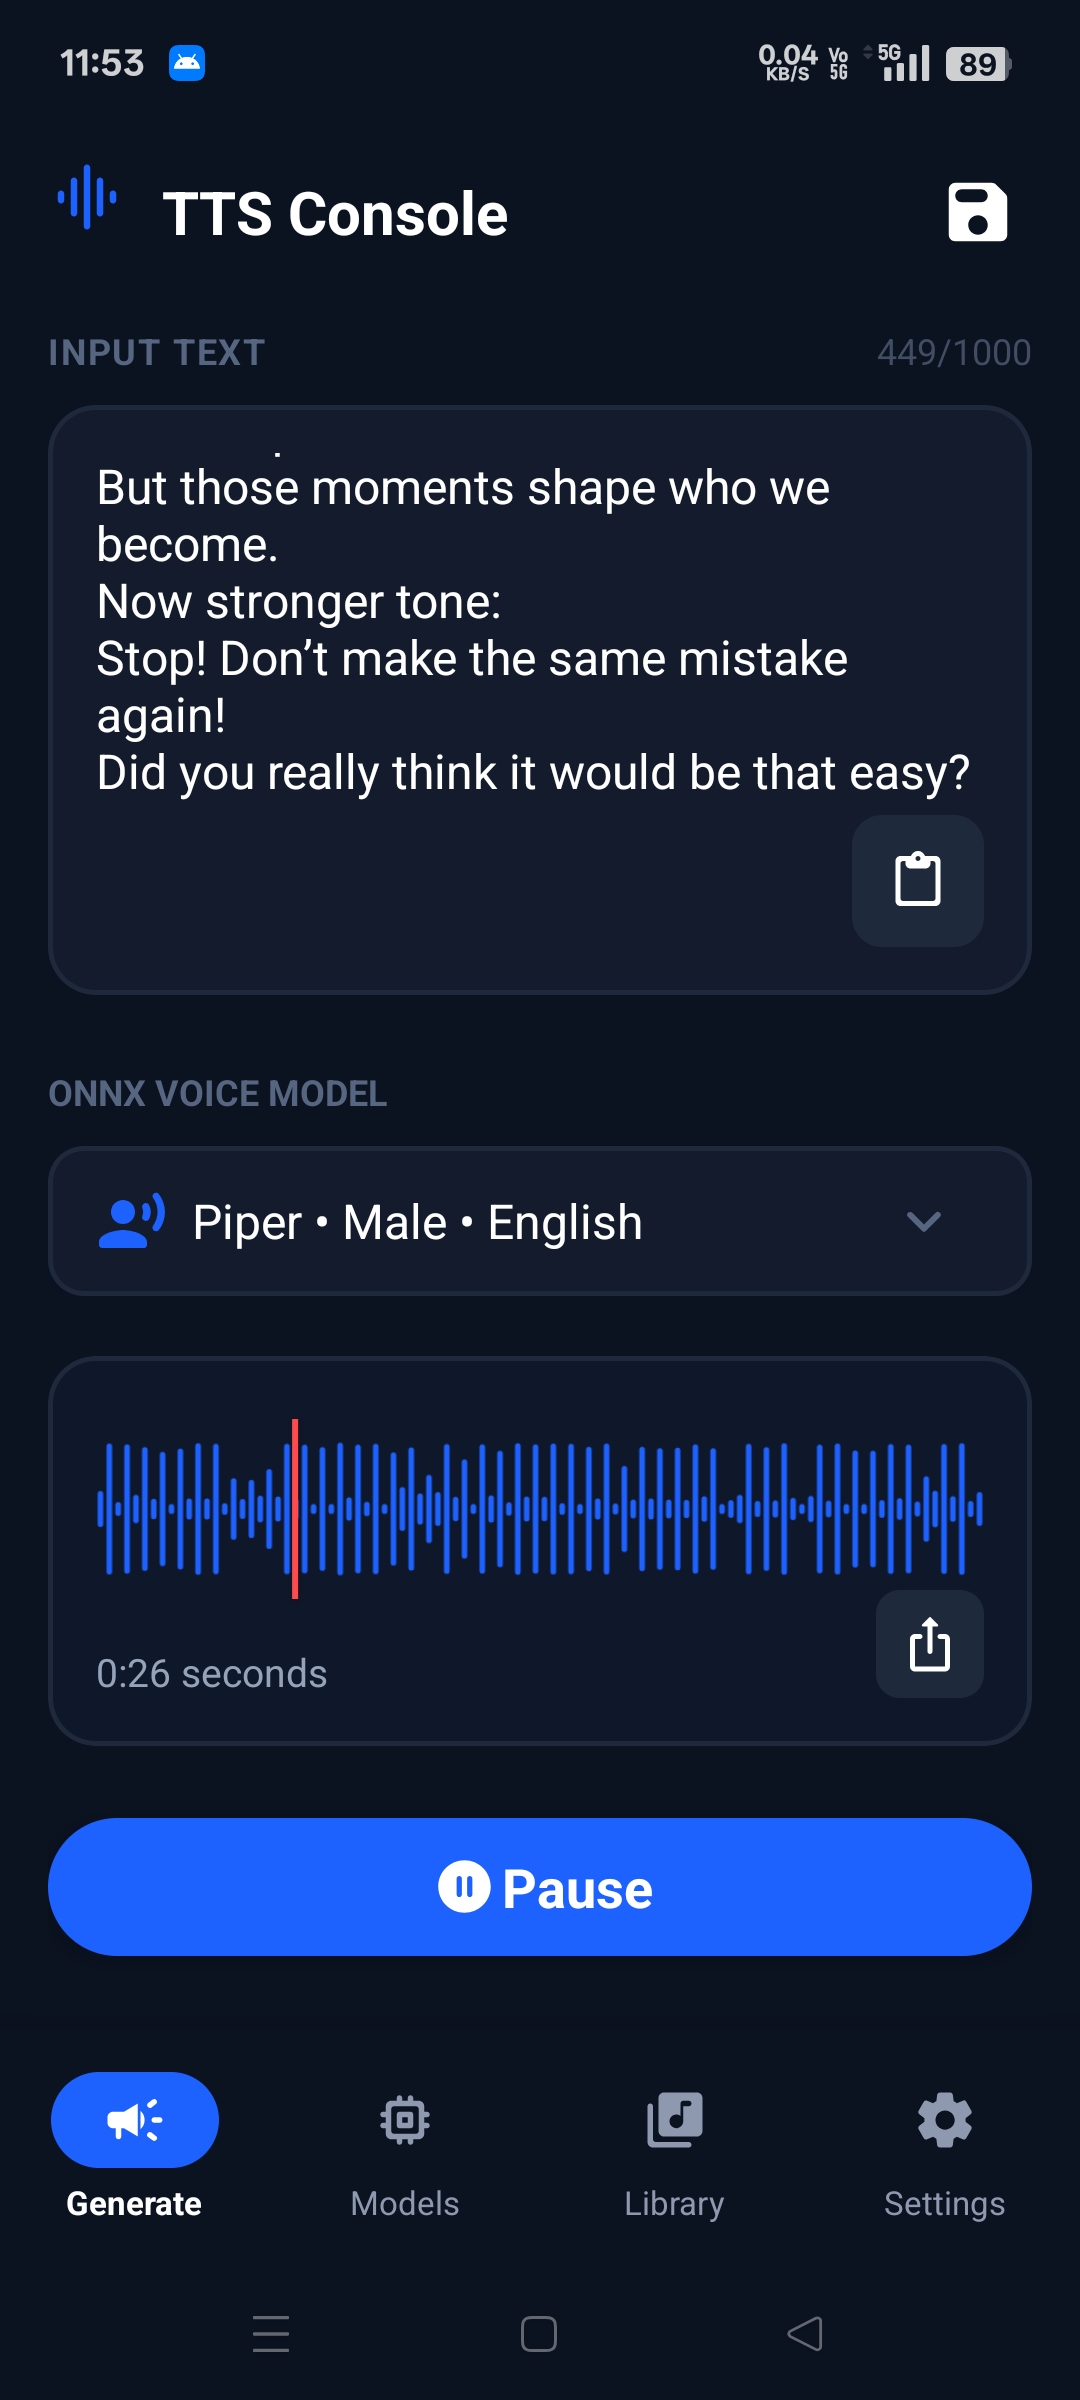
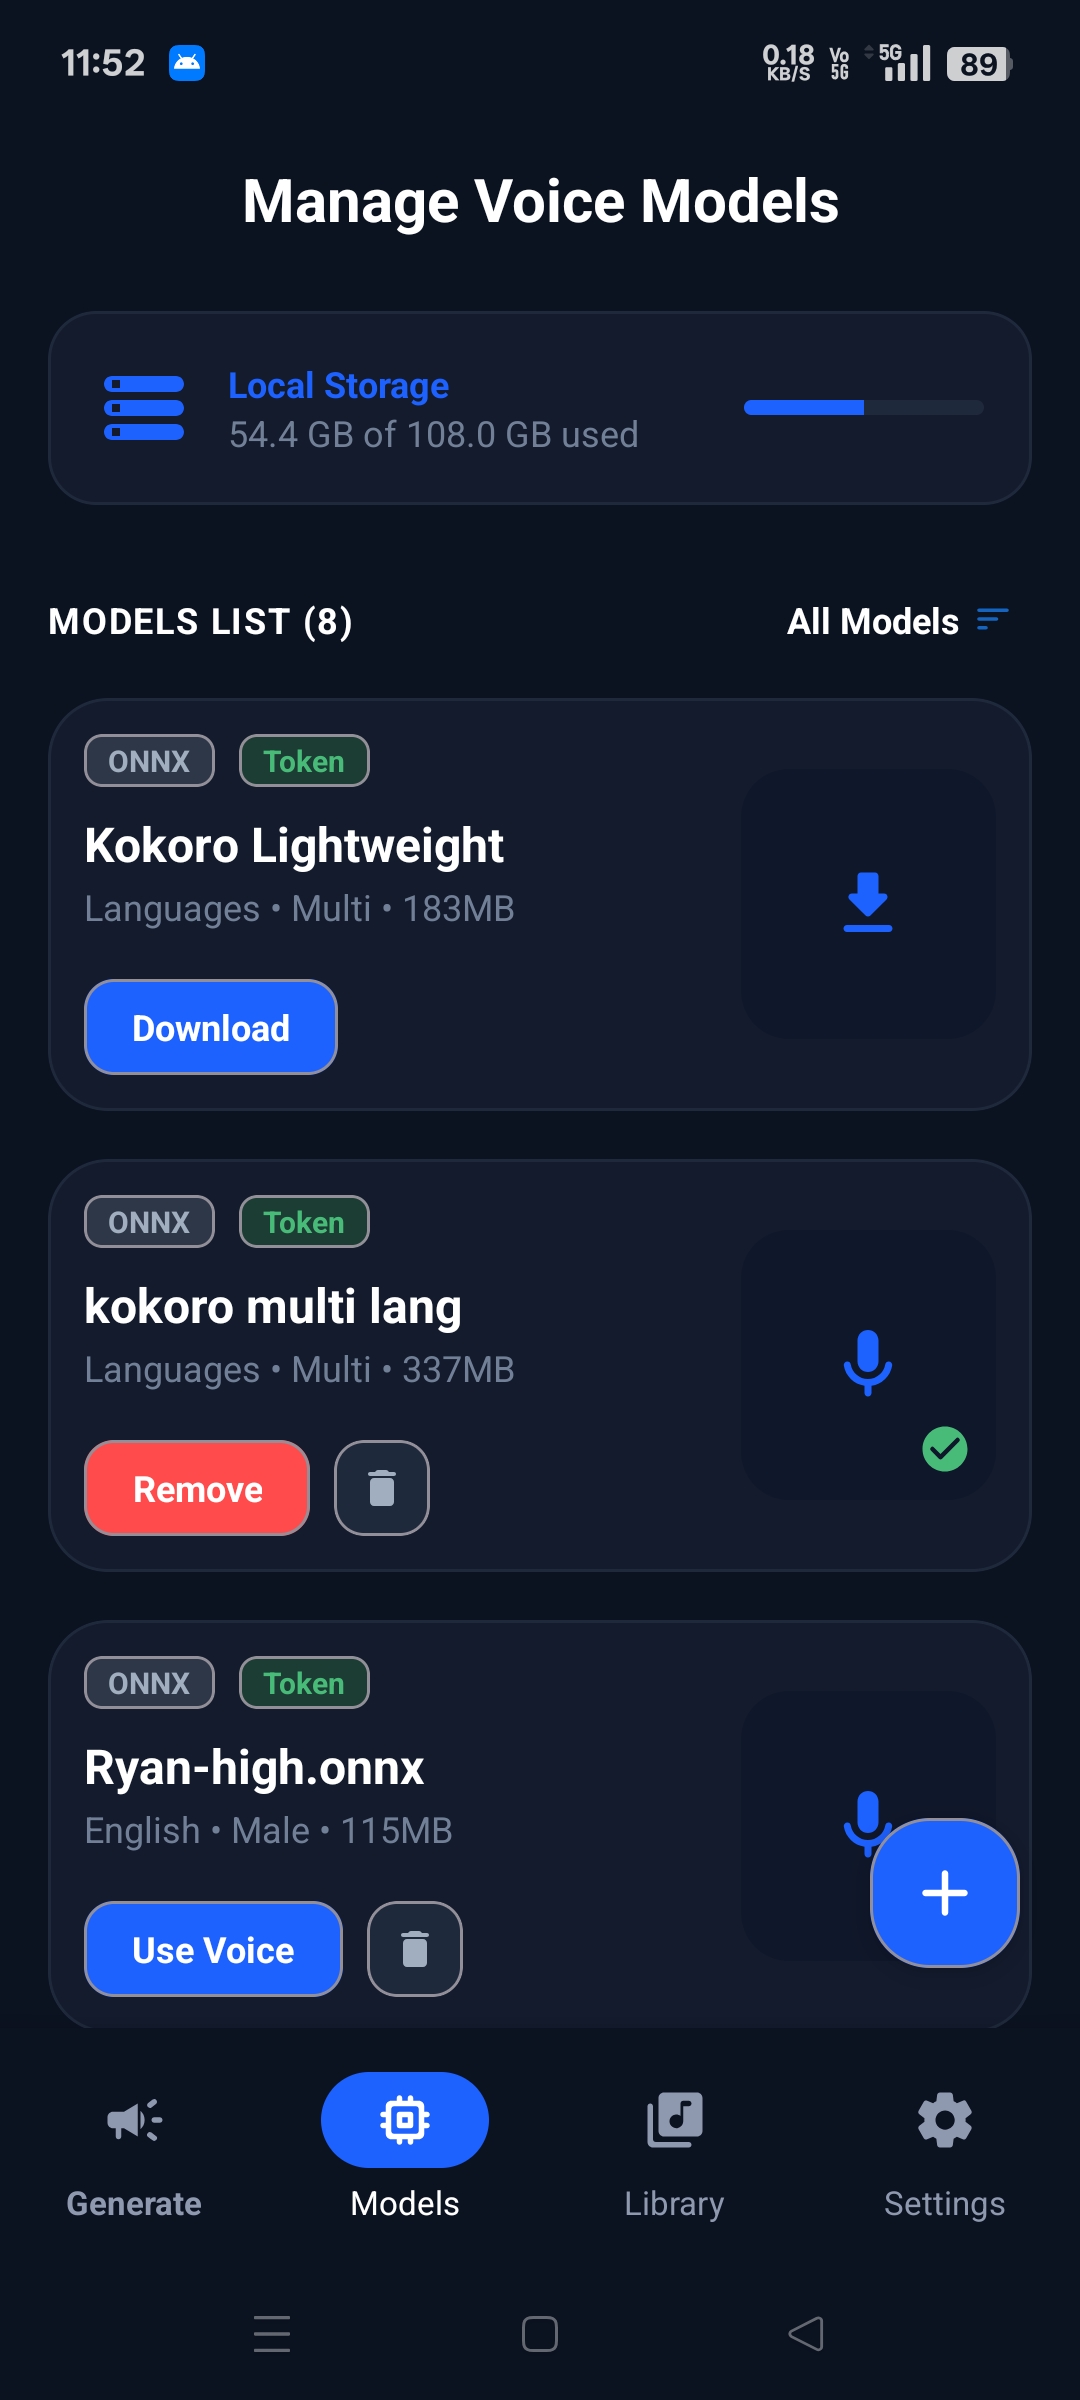
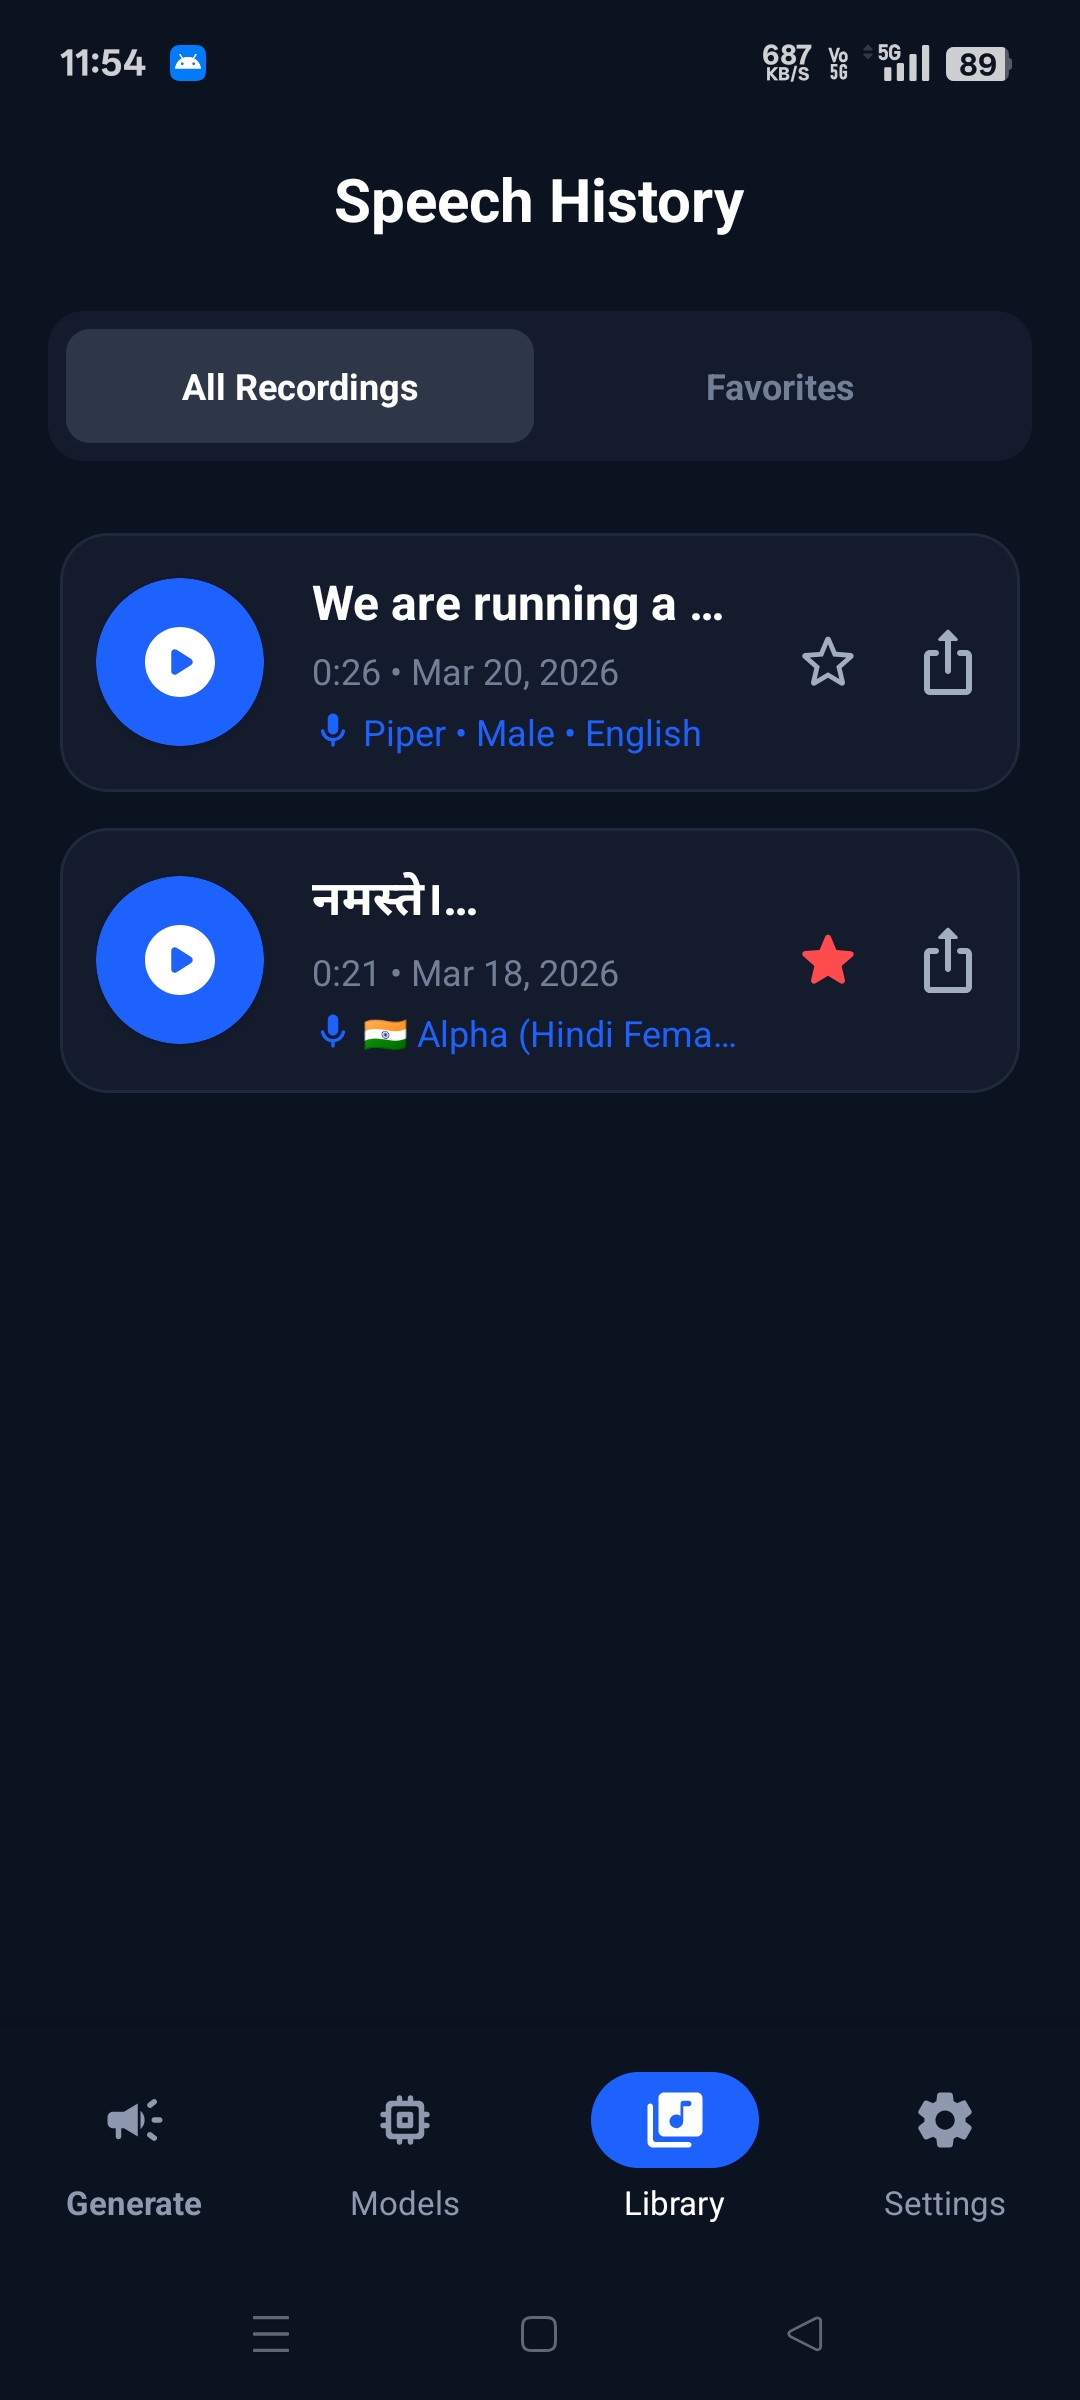
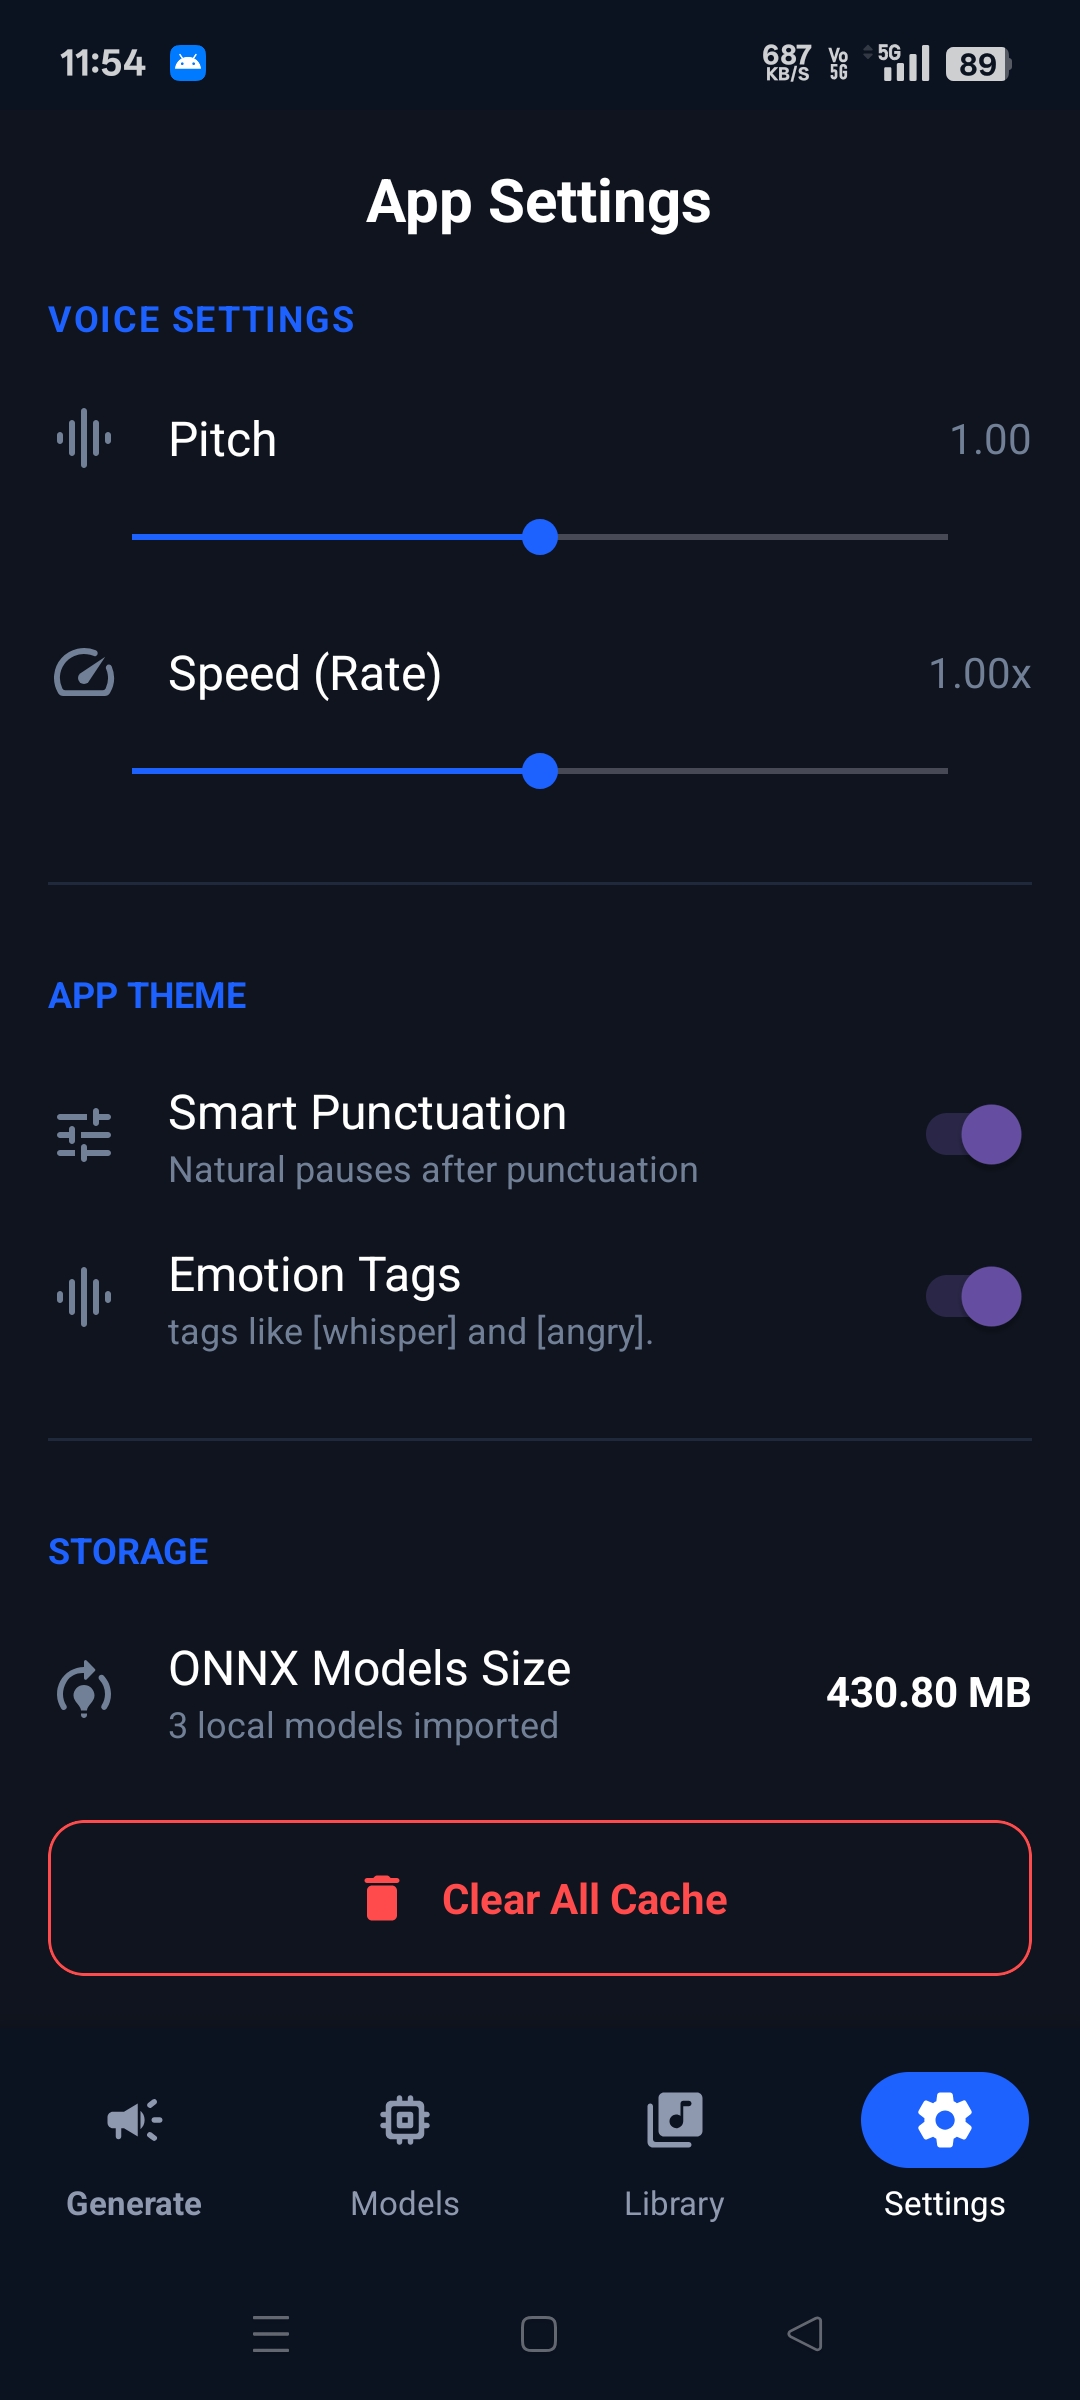
VoxSherpa TTS

VoxSherpa TTS is a 100% offline Android Text-to-Speech app powered by Sherpa-ONNX. It supports Kokoro-82M, Piper, and VITS engines with multilingual support including Hindi, English, British English, Japanese, Chinese and 50+ more languages.

Generate Models Library Settings

BreezeApp from MediaTek Research

BreezeAPP is a mobile AI application developed for both Android and iOS platforms. Users can download it directly from the App Store and enjoy a variety of features offline, including speech-to-text, text-to-speech, text-based chatbot interactions, and image question-answering

1 2 3

Open-LLM-VTuber

Talk to any LLM with hands-free voice interaction, voice interruption, and Live2D taking face running locally across platforms

See also https://github.com/t41372/Open-LLM-VTuber/pull/50

voiceapi

Streaming ASR and TTS based on FastAPI

It shows how to use the ASR and TTS Python APIs with FastAPI.

腾讯会议摸鱼工具 TMSpeech

Uses streaming ASR in C# with graphical user interface.

Video demo in Chinese: 【开源】Windows实时字幕软件(网课/开会必备)

lol互动助手

It uses the JavaScript API of sherpa-onnx along with Electron

Video demo in Chinese: 爆了!炫神教你开打字挂!真正影响胜率的英雄联盟工具!英雄联盟的最后一块拼图!和游戏中的每个人无障碍沟通!

Sherpa-ONNX 语音识别服务器

A server based on nodejs providing Restful API for speech recognition.

QSmartAssistant

一个模块化,全过程可离线,低占用率的对话机器人/智能音箱

It uses QT. Both ASR and TTS are used.

Flutter-EasySpeechRecognition

It extends ./flutter-examples/streaming_asr by downloading models inside the app to reduce the size of the app.

Note: [Team B] Sherpa AI backend also uses sherpa-onnx in a Flutter APP.

sherpa-onnx-unity

sherpa-onnx in Unity. See also #1695, #1892, and #1859

xiaozhi-esp32-server

本项目为xiaozhi-esp32提供后端服务,帮助您快速搭建ESP32设备控制服务器 Backend service for xiaozhi-esp32, helps you quickly build an ESP32 device control server.

See also

KaithemAutomation

Pure Python, GUI-focused home automation/consumer grade SCADA.

It uses TTS from sherpa-onnx. See also ✨ Speak command that uses the new globally configured TTS model.

Open-XiaoAI KWS

Enable custom wake word for XiaoAi Speakers. 让小爱音箱支持自定义唤醒词。

Video demo in Chinese: 小爱同学启动~˶╹ꇴ╹˶!

C++ WebSocket ASR Server

It provides a WebSocket server based on C++ for ASR using sherpa-onnx.

Go WebSocket Server

It provides a WebSocket server based on the Go programming language for sherpa-onnx.

Making robot Paimon, Ep10 "The AI Part 1"

It is a YouTube video, showing how the author tried to use AI so he can have a conversation with Paimon.

It uses sherpa-onnx for speech-to-text and text-to-speech.

1

TtsReader - Desktop application

A desktop text-to-speech application built using Kotlin Multiplatform.

MentraOS

Smart glasses OS, with dozens of built-in apps. Users get AI assistant, notifications, translation, screen mirror, captions, and more. Devs get to write 1 app that runs on any pair of smart glasses.

It uses sherpa-onnx for real-time speech recognition on iOS and Android devices. See also https://github.com/Mentra-Community/MentraOS/pull/861

It uses Swift for iOS and Java for Android.

flet_sherpa_onnx

Flet ASR/STT component based on sherpa-onnx. Example a chat box agent

achatbot-go

a multimodal chatbot based on go with sherpa-onnx's speech lib api.

fcitx5-vinput

Local offline voice input plugin for Fcitx5 (Linux input method framework). It uses C++ with offline ASR for speech recognition, supporting push-to-talk, command mode, and optional LLM post-processing.

Video demo in Chinese: fcitx5-vinput

Wake Word

A VS Code extension for hands-free voice-activated coding. It uses sherpa-onnx for real-time keyword spotting (KWS) to detect custom wake phrases and trigger VS Code commands by voice. Audio capture is handled by decibri, a cross-platform Node.js microphone streaming library with prebuilt native binaries.

SmartSub

SmartSub is a local-first cross-platform desktop application for the complete subtitle production pipeline: audio/video transcription, subtitle translation, proofreading, and subtitle burning/muxing.

It natively integrates sherpa-onnx to power three offline ASR engines — FunASR, Qwen3-ASR, and FireRedASR — delivering high-accuracy Chinese and multilingual speech recognition entirely on-device, with no file uploads required.

Fono

Talk to your computer. Fono is an open-source (GPL-3.0), complete voice-AI stack (speech-to-text, text-to-speech, a local LLM, wake word, speaker ID) in one small binary for the Linux, macOS, and Windows desktop. Press a key and speak: it types into any app, answers as a voice assistant, or drives a coding agent.

It uses sherpa-onnx's Supertonic TTS models for text-to-speech, with the Supertonic text frontend ported to Rust. See also #3750, which fixes dropped diacritics in the Supertonic frontend for Romanian, Czech, Polish, Hungarian, Turkish, Vietnamese, and other non-English Latin-script languages.

Domia

Domia is an open-source local AI companion you talk to, living entirely on hardware you own. Each Domia is its own character, with a distinct personality, voice, emotional state, and memory of you and its place — and it acts, not just talks: skills connect it to the real world over MCP, Home Assistant included. Domia nodes form a local peer-to-peer mesh that shares speech and reasoning compute, while room satellites bring each companion into the spaces where you live without giving up its identity. No cloud, no accounts, and no data leaving your network.

Domia runs sherpa-onnx in-process for keyword spotting, voice activity detection, streaming and offline speech recognition, and text-to-speech. Speech engines and models are selected through per-companion configuration, making it easy to match supported sherpa-onnx models to different hardware.

qwen-audio-agent

A realtime full-duplex voice runtime for AI coding agents (Claude Code, Codex, OpenCode, and other ACP agents). It uses sherpa-onnx keyword spotting with the 3M-parameter zh-en transducer model to implement a local voice wake word: the app sleeps on idle but keeps the microphone open, and the wake phrase brings the session back with no cloud calls.

sherpa-onnx (k2-fsa/sherpa-onnx)

Searching Database…

Что это такое?sherpa-onnx — это инструментарий, который работает офлайн, для распознавания речи, синтеза речи, диаризации говорящих, идентификации и верификации говорящего, определения языка речи, разметки аудио, VAD, улучшения речи, поиска ключевых слов и разделения источников. Он построен на next-gen Kaldi и ONNX Runtime и не требует подключения к интернету.
Это библиотека для встраивания или отдельное приложение?В первую очередь это библиотека/SDK с ядром на C++ и привязками для 12 языков (C, Python, Go, C#, Java, Kotlin, JavaScript, Swift, Rust, Dart, Object Pascal). Но в проекте также есть готовые демо-приложения (APK-файлы для Android, приложения на Flutter, приложения на Lazarus) и сборки под WebAssembly.
Как это попробовать или добавить в проект?Попробовать можно сразу в браузере через Huggingface Spaces (ничего устанавливать не нужно), скачать готовые APK-файлы для Android или приложения на Flutter/Lazarus, а также подключить библиотеку через привязки нужного языка (например, pip install для Python) с предобученными моделями ONNX из ссылок на модели.
Что нужно для запуска, например Python или GPU?Интернет-соединение и облачный API не нужны: всё работает полностью офлайн благодаря onnxruntime. Поддерживается работа только на CPU, но есть и запуск на платах с GPU, например NVIDIA Jetson. Для сборки из репозитория используются инструменты на Python, Java, Swift и Make.
Есть ли подвох с конкретными платформами?Поддержка зависит от архитектуры и ОС: например, arm32 на iOS не поддерживается, riscv64 работает только в Linux, а TTS-приложение на Flutter для iOS нужно собирать из исходного кода, готового пакета для неё нет.
Для кого это и где работает?Это для разработчиков, которые создают офлайн-голосовые приложения: от встраиваемых плат (Raspberry Pi, RISC-V, NPU от RK, Axera и Ascend) до мобильных систем (Android, iOS, HarmonyOS), десктопов (Windows, macOS, Linux) и серверов, и всё это без привязки к облаку.
Может ли он распознавать речь в реальном времени?Да, поддерживается как потоковое, так и непотоковое распознавание речи, включая живые демо, например распознавание китайского и английского в реальном времени на Zipformer.
Можно ли запускать его на NPU вместо CPU/GPU?Да, поддерживаются NPU от Rockchip (RKNN), Qualcomm (QNN), Ascend, Axera и Intel (OpenVINO) для ускоренного инференса.
Можно ли запустить в браузере без установки?Да, есть сборки под WebAssembly и демо на Huggingface Spaces для распознавания речи, синтеза речи, VAD, диаризации говорящих, разметки аудио и клонирования голоса, которые работают прямо в браузере.
Какие фреймворки поддерживаются для создания приложений?Есть официальная поддержка Flutter и Tauri, а готовые демо-приложения доступны для Android, iOS, Windows, macOS, Linux и веба.
Creator
k2-fsa
Size
16.4 MB
Stars
15.3K
Age
4y
Commits · 90 Days
