
higgsfield README

The project's README from github.com/higgsfield-ai/higgsfield. As one markdown file: README.md.

higgsfield - multi node training without crying

Higgsfield is an open-source, fault-tolerant, highly scalable GPU orchestration, and a machine learning framework designed for training models with billions to trillions of parameters, such as Large Language Models (LLMs).

PyPI version

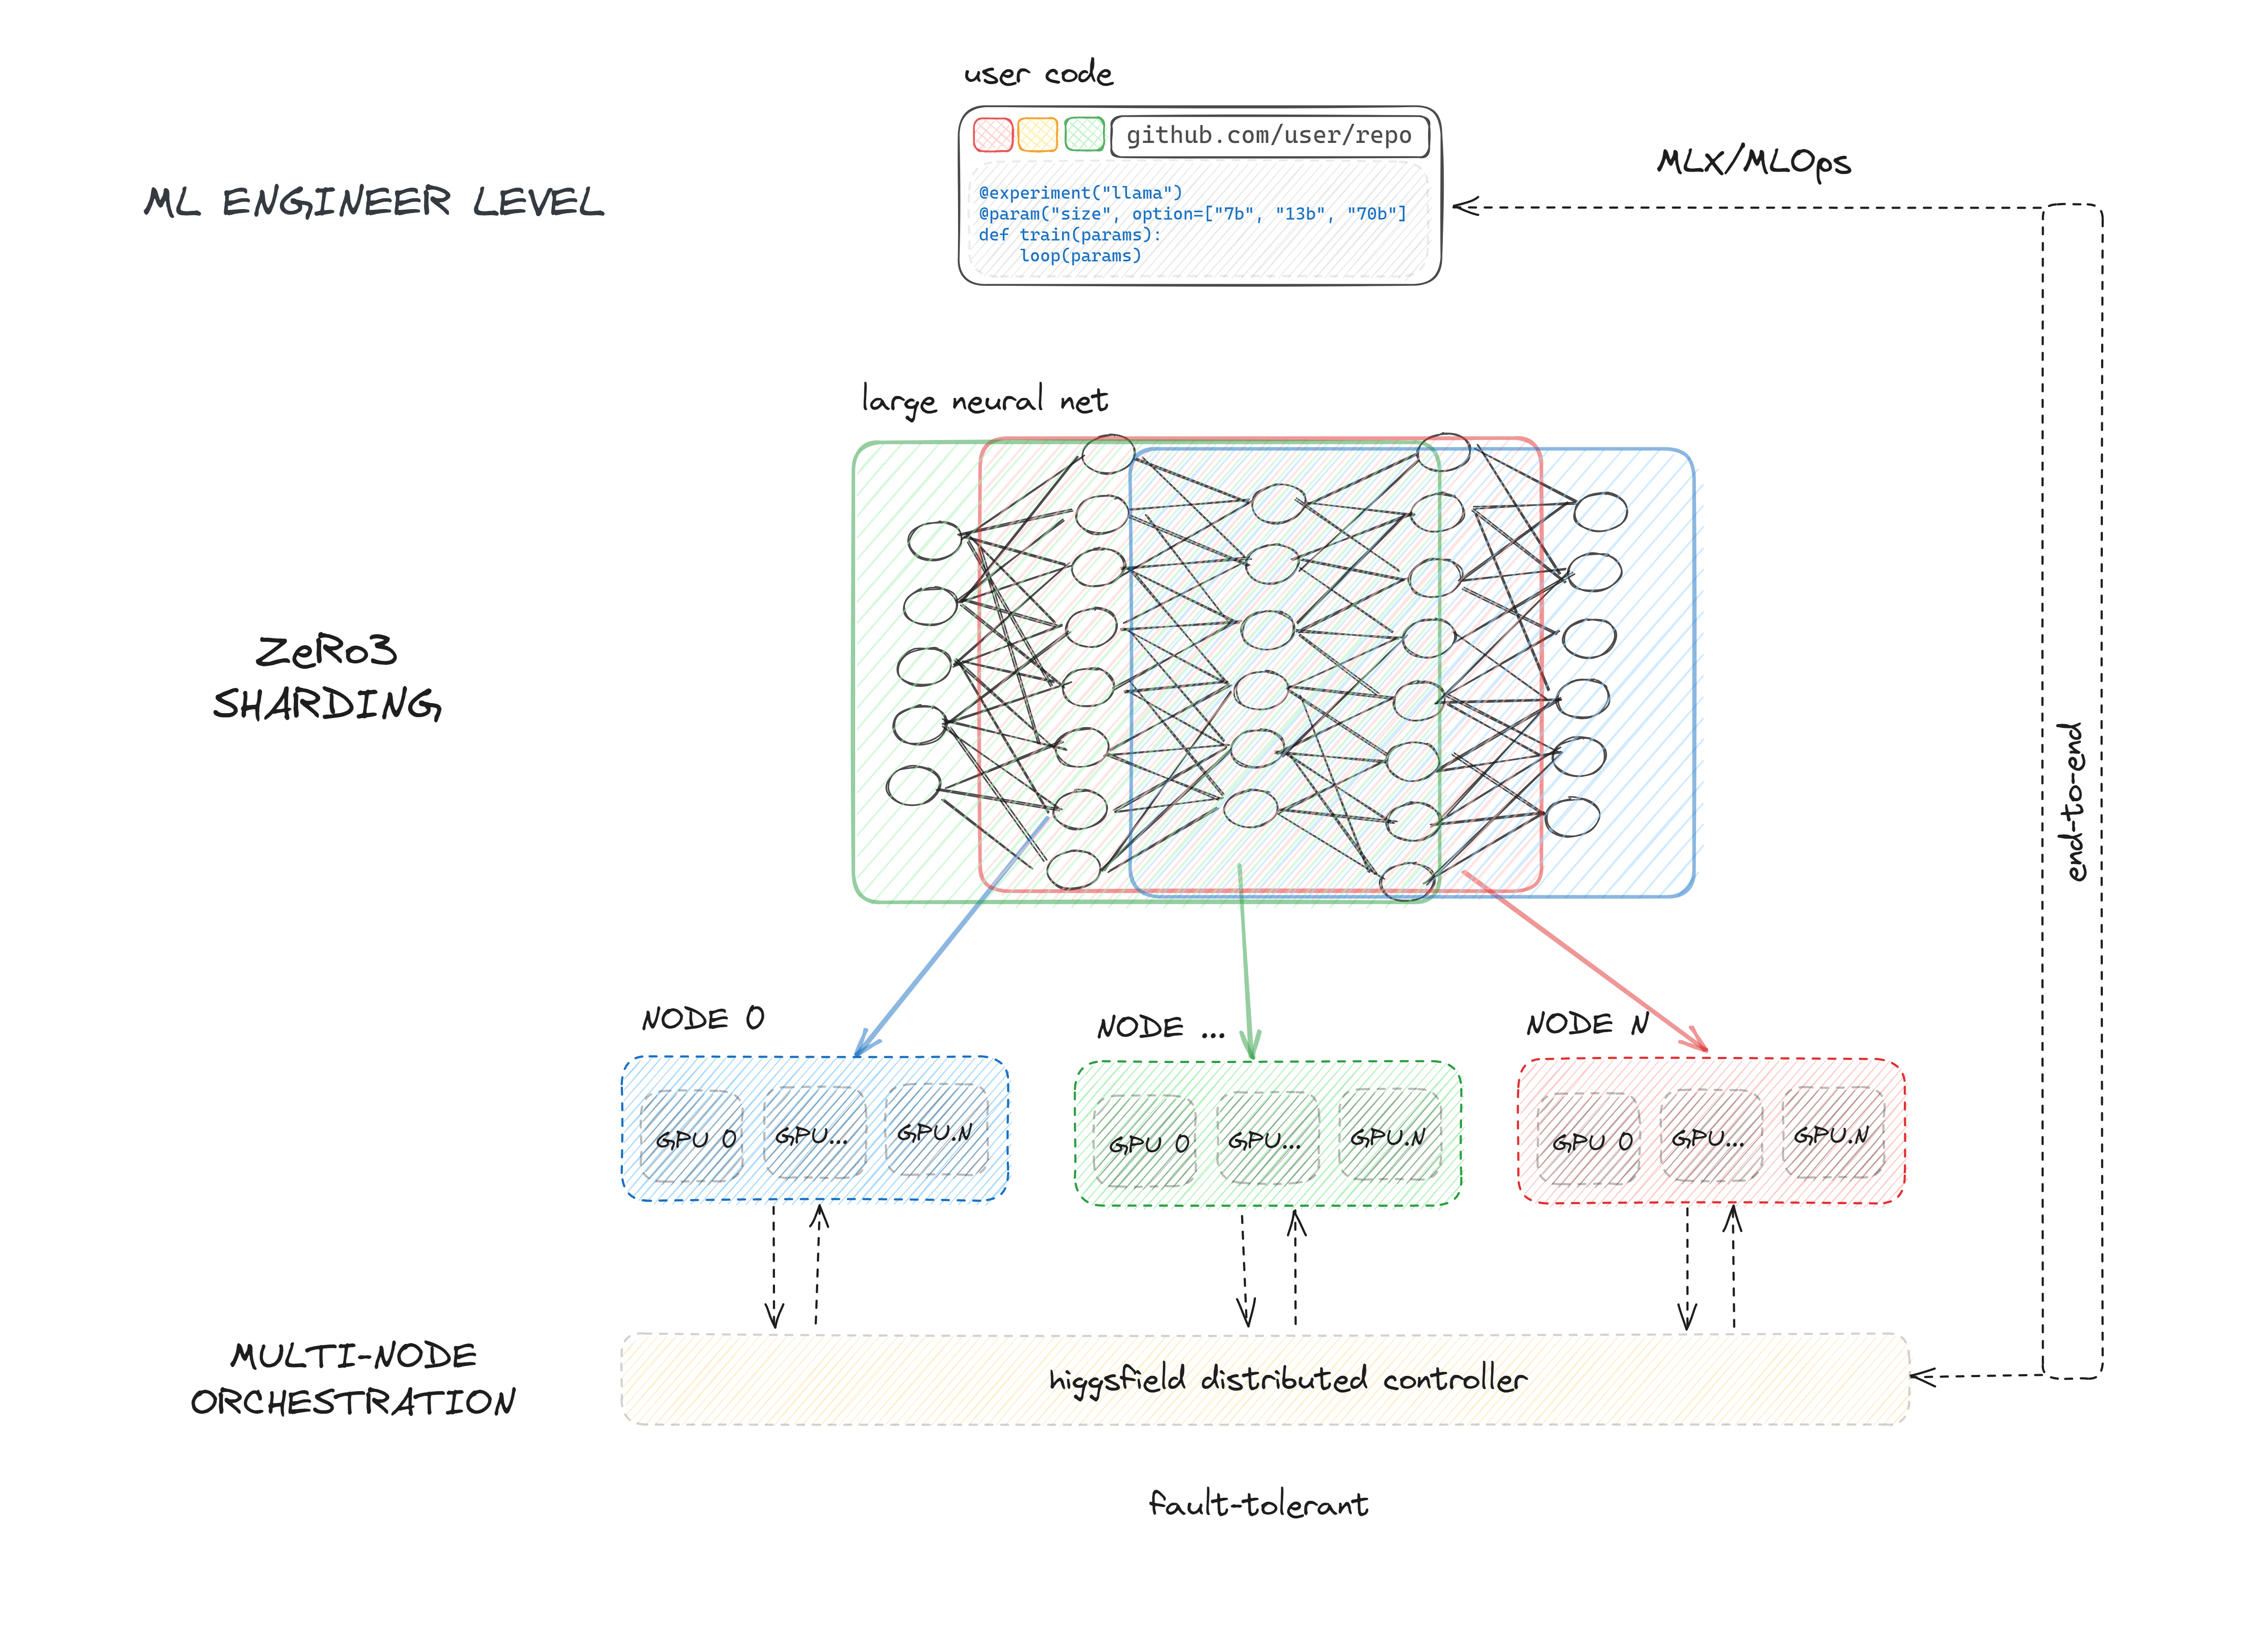
architecture

Higgsfield serves as a GPU workload manager and machine learning framework with five primary functions:

  1. Allocating exclusive and non-exclusive access to compute resources (nodes) to users for their training tasks.
  2. Supporting ZeRO-3 deepspeed API and fully sharded data parallel API of PyTorch, enabling efficient sharding for trillion-parameter models.
  3. Offering a framework for initiating, executing, and monitoring the training of large neural networks on allocated nodes.
  4. Managing resource contention by maintaining a queue for running experiments.
  5. Facilitating continuous integration of machine learning development through seamless integration with GitHub and GitHub Actions. Higgsfield streamlines the process of training massive models and empowers developers with a versatile and robust toolset.

Install

$ pip install higgsfield==0.0.3

Train example

That's all you have to do in order to train LLaMa in a distributed setting:

from higgsfield.llama import Llama70b
from higgsfield.loaders import LlamaLoader
from higgsfield.experiment import experiment

import torch.optim as optim
from alpaca import get_alpaca_data

@experiment("alpaca")
def train(params):
    model = Llama70b(zero_stage=3, fast_attn=False, precision="bf16")

    optimizer = optim.AdamW(model.parameters(), lr=1e-5, weight_decay=0.0)

    dataset = get_alpaca_data(split="train")
    train_loader = LlamaLoader(dataset, max_words=2048)

    for batch in train_loader:
        optimizer.zero_grad()
        loss = model(batch)
        loss.backward()
        optimizer.step()

    model.push_to_hub('alpaca-70b')

How it's all done?

  1. We install all the required tools in your server (Docker, your project's deploy keys, higgsfield binary).
  2. Then we generate deploy & run workflows for your experiments.
  3. As soon as it gets into Github, it will automatically deploy your code on your nodes.
  4. Then you access your experiments' run UI through Github, which will launch experiments and save the checkpoints.

Design

We follow the standard pytorch workflow. Thus you can incorporate anything besides what we provide, deepspeed, accelerate, or just implement your custom pytorch sharding from scratch.

Enviroment hell

No more different versions of pytorch, nvidia drivers, data processing libraries. You can easily orchestrate experiments and their environments, document and track the specific versions and configurations of all dependencies to ensure reproducibility.

Config hell

No need to define 600 arguments for your experiment. No more yaml witchcraft. You can use whatever you want, whenever you want. We just introduce a simple interface to define your experiments. We have even taken it further, now you only need to design the way to interact.

Compatibility

We need you to have nodes with:

Clouds we have tested on:

Feel free to open an issue if you have any problems with other clouds.

Getting started

Setup

Here you can find the quick start guide on how to setup your nodes and start training.

Tutorial

API for common tasks in Large Language Models training.

Platform Purpose Estimated Response Time Support Level
Github Issues Bug reports, feature requests, install issues, usage issues, etc. < 1 day Higgsfield Team
Twitter For staying up-to-date on new features. Daily Higgsfield Team
Website Discussion, news. < 2 days Higgsfield Team

higgsfield (higgsfield-ai/higgsfield)

Searching Database…

这是什么?Higgsfield 是一个开源的容错 GPU 编排系统和机器学习框架,用于训练从数十亿到数万亿参数规模的超大模型,例如 LLM。
这是集群调度器、训练框架,还是两者都是?两者都是:它既是给用户分配算力并对实验排队的 GPU 工作负载管理器,又是基于 PyTorch、用于启动、运行和监控分布式训练任务的框架。
怎么让训练任务跑起来?先安装 higgsfield 二进制文件,它会在你的服务器上配置好 Docker、部署密钥和工具,然后生成 deploy 和 run 的 GitHub 工作流,这样推送到 GitHub 就会自动把代码部署到你的节点。
我的训练节点需要满足什么条件?每个节点必须运行 Ubuntu,可通过 SSH 访问,并拥有一个具有免密 sudo 权限的非 root 用户。
哪些云服务商真正可用?它只在 Azure、LambdaLabs 和 FluidStack 上测试过;其他云平台也许能用但没有保证,如果遇到问题,项目希望你提交 issue 反馈。
它支持 DeepSpeed 或 PyTorch FSDP 分片吗?支持。Higgsfield 支持 ZeRO-3 DeepSpeed API 和 PyTorch 的全分片数据并行(FSDP)API,可高效地对万亿参数模型进行分片。
实验队列解决的是什么问题?它通过为待运行实验维护一个队列来管理用户间的资源竞争,从而公平分配独占和非独占的节点访问。
为什么不直接写原始的 PyTorch 训练脚本?Higgsfield 的存在就是为了消灭“环境地狱”和“配置地狱”:它在各节点间统一依赖/驱动版本,并用简单的实验接口取代庞杂的 YAML 配置。
GitHub 在训练工作流中扮演什么角色?GitHub Actions 被用作部署主干:实验代码一旦进入 GitHub,工作流就会自动将其部署到你的节点,你还可以通过 GitHub 的界面查看运行和检查点。
Size
5 MB
Stars
6.1K
Age
8y
Commits · 90 Days