📰 News
https://github.com/user-attachments/assets/51b2c303-0eb3-406f-8b02-b53dfa715683
A 78-second narrated walkthrough — the loop, worked through one
game from its first playable version to the build development delivers, and
what it does across the benchmark. Unmute to play with sound.
Abstract
Recent advances in large language models have made automatic game generation increasingly feasible, yet reliably improving generated games beyond a playable version remains challenging. Naive iterative refinement can easily overfit a small set of test cases, producing fragile games with unresolved bugs, missing behaviors, and poor generalization to broader player interactions.
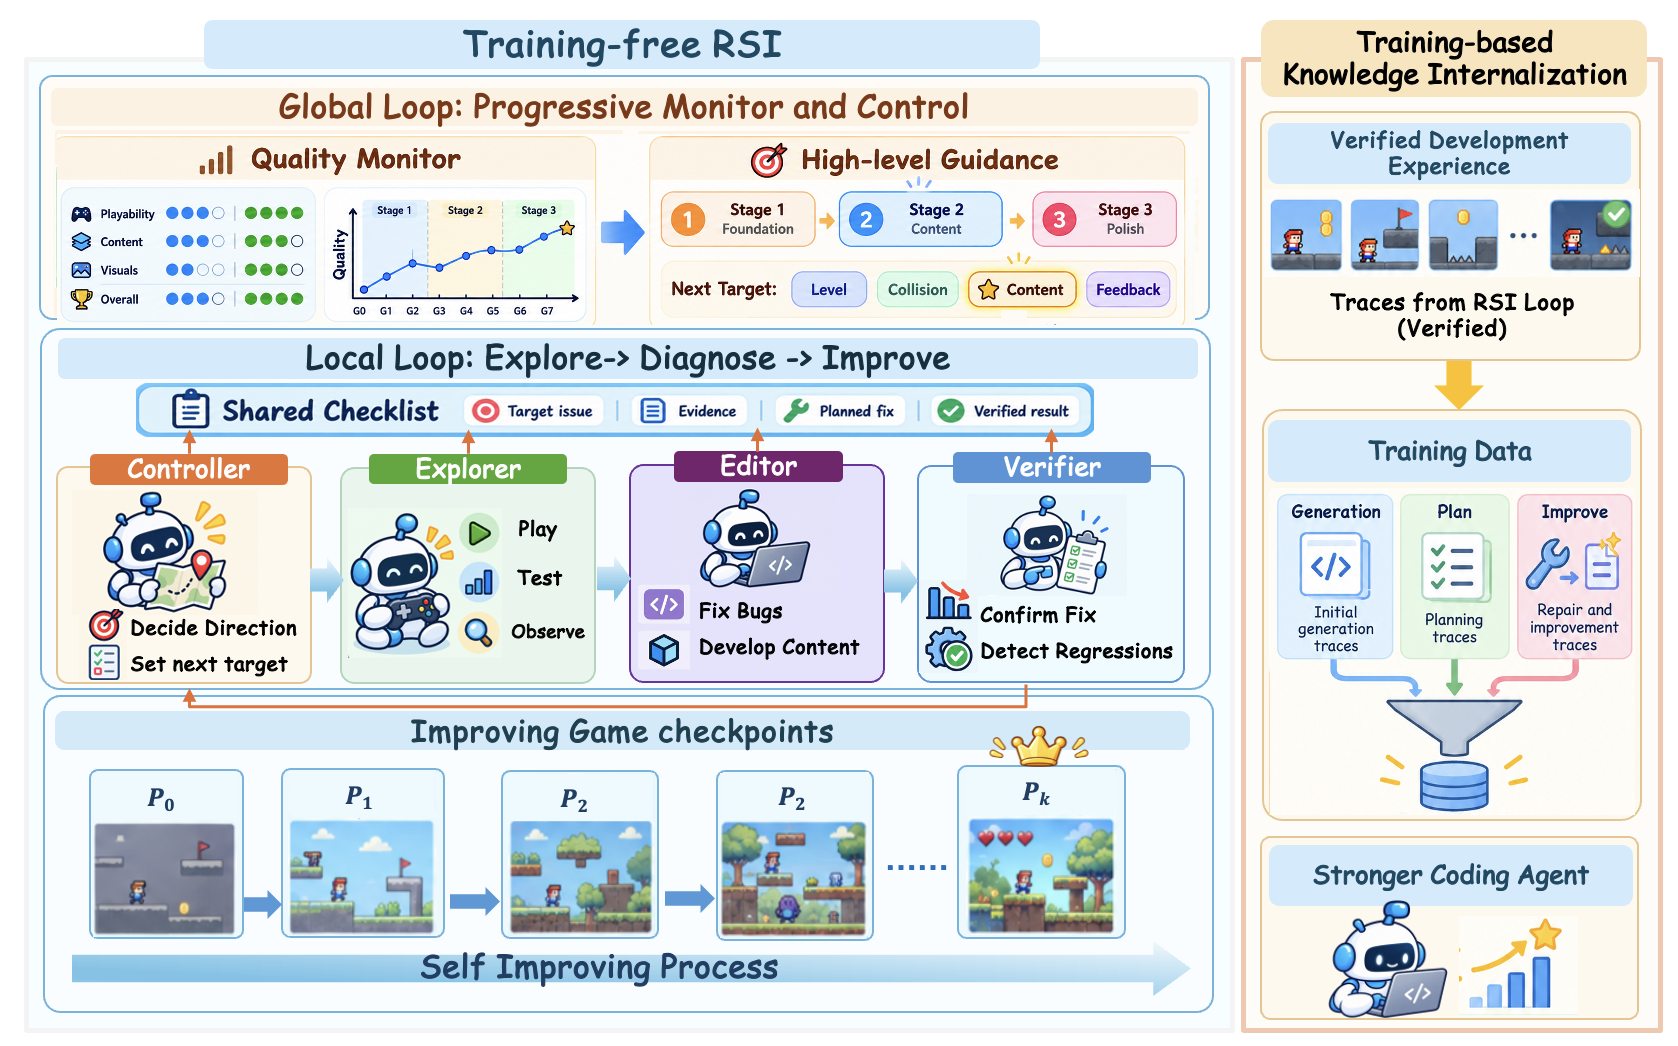
We introduce RSIGame, an autonomous agentic game development framework with recursive self-improvement. RSIGame organizes development into complementary local and global loops. Concretely, a local explore-diagnose-improve loop broadly explores the executable game, diagnoses and prioritizes discovered issues, and performs evidence-grounded revision, where an evolving checklist continually accumulates new testing and improvement guidance. A global loop tracks overall quality, preserves the best checkpoint, and detects saturation or regression over long-horizon development.
Beyond test-time improvement, RSIGame further internalizes successful development experience into the generator through training. Across 140 GameCraft-Bench tasks, two game engines, and five generators, RSIGame consistently improves game quality under matched development budgets. Notably, experience internalization enables Qwen3.8-27B to reach 61.38 on Godot and 58.53 on Phaser, exceeding GPT-5.5 one-shot scores while reducing Qwen's generation tokens by 11 times.
What development does
Left is the initial generation, right is what RSIGame delivers. Same game, same
scripted inputs, replayed on both builds.
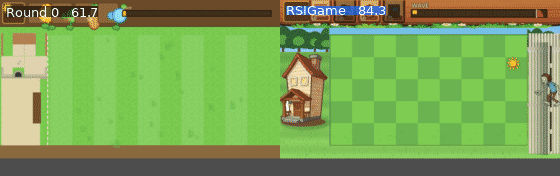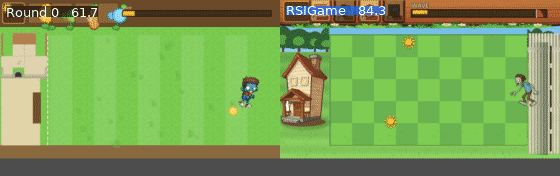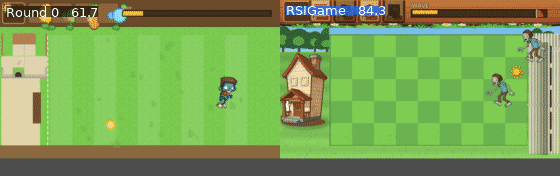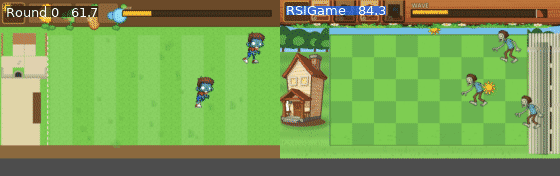
Lawn Guardians · tower defence · Godot
61.7 → 84.3 over 46 rounds |
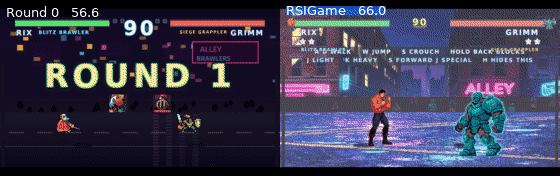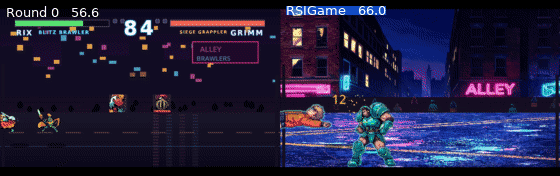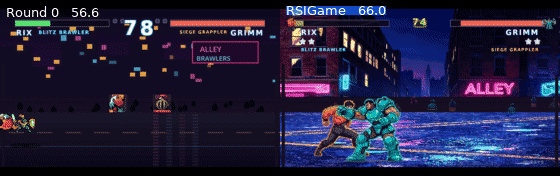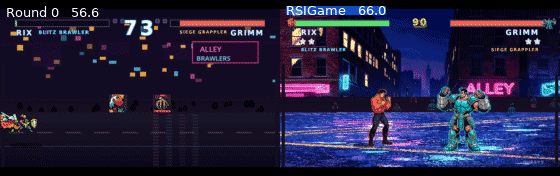
Alley Brawlers · fighting · Godot
56.6 → 66.0 over 41 rounds |
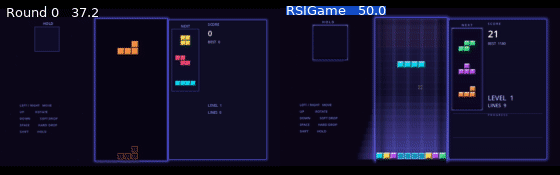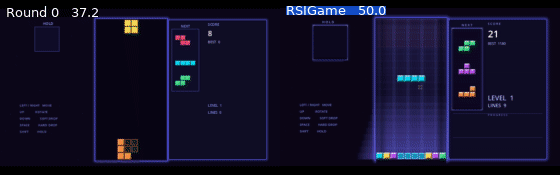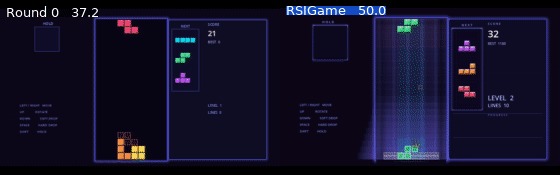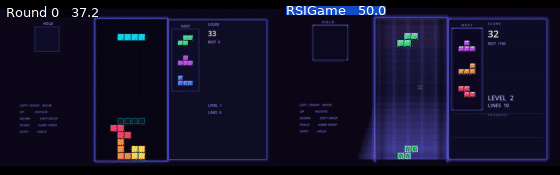
Block Cascade · puzzle · Godot
37.2 → 50.0 |
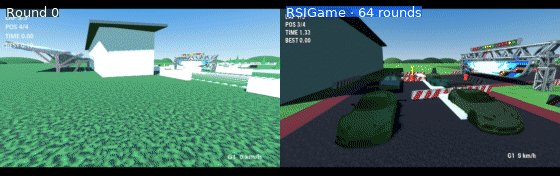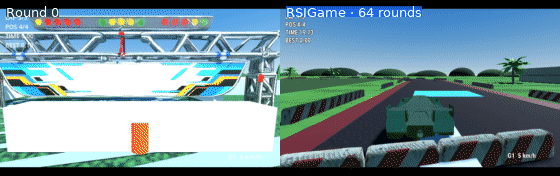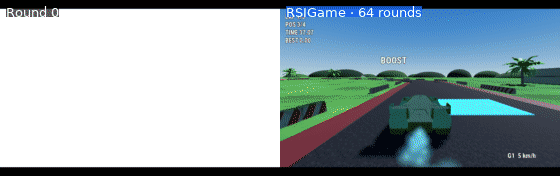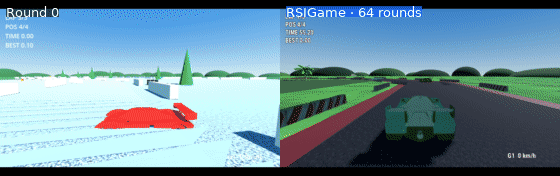
Circuit GT · racing 3D · Godot
64 rounds |
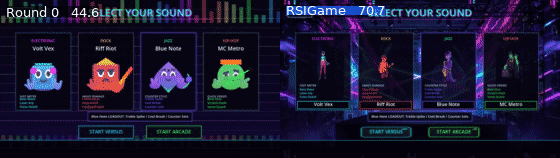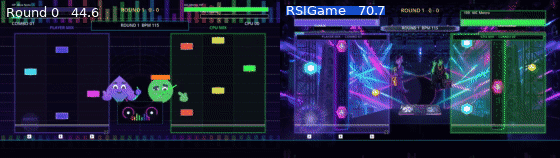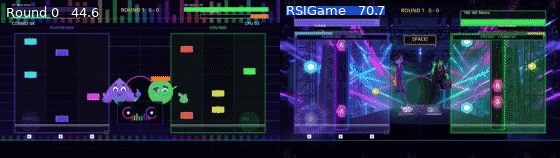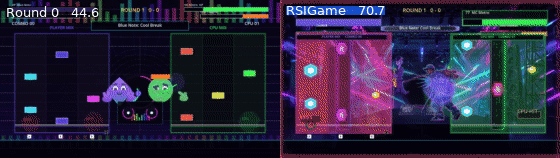
Rhythm DJ Arena · rhythm · Godot
44.6 → 70.7 over 30 rounds |
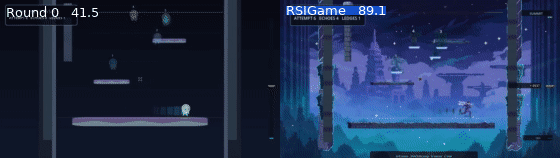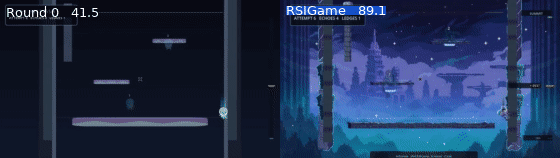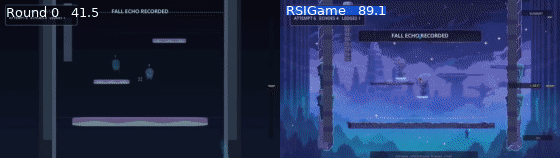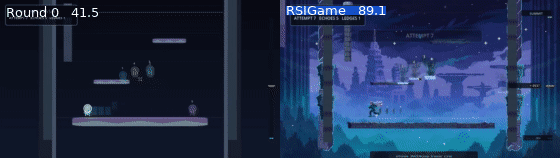
Echo Climb · platformer · Godot
41.5 → 89.1 over 30 rounds |
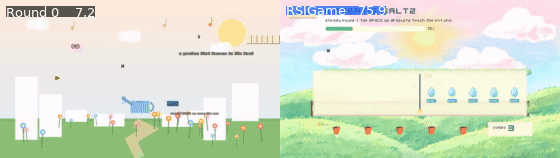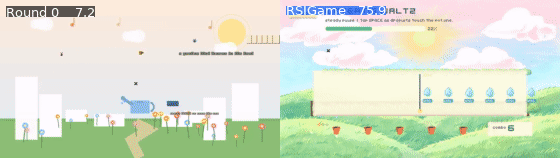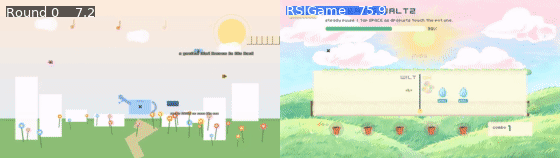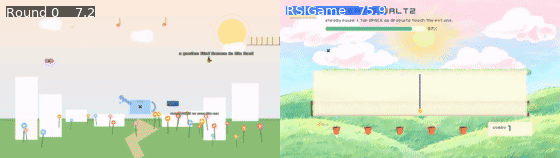
Rhythm Garden · rhythm · Godot
7.2 → 75.9 over 30 rounds |
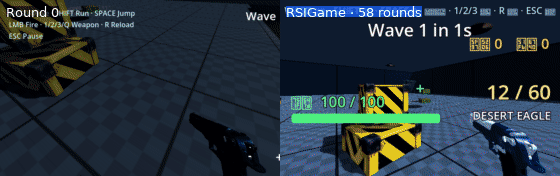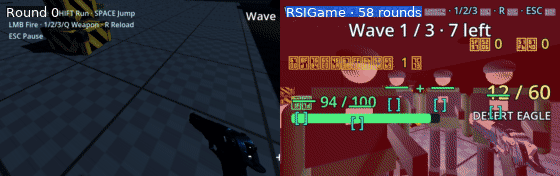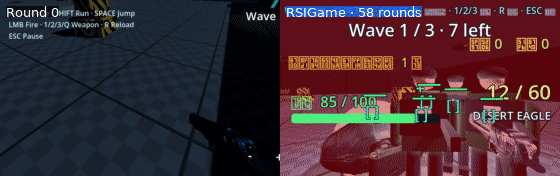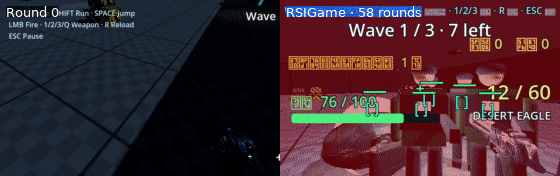
FPS Arena · shooter 3D · Godot
58 rounds |
More at the project page, where five of these are playable in the browser
How it works
The inner loop, once per round:
|
|
| Explore |
an agent plays the executable game and records what actually happens — logs, metrics, screenshots |
| Diagnose |
that evidence becomes one concrete objective: the place with the most improvement headroom, not a guess |
| Edit |
a repair agent changes code or content against that single objective |
| Verify |
an independent agent replays the game: did the change land, and did anything that worked before break |
The outer loop, across rounds. A Global Quality Monitor scores progress,
holds the globally best checkpoint, and detects saturation — three consecutive
checkpoints where nothing beat the held build. Saturation is not the end: sparse
high-level guidance, from a person or a stronger model, opens the next stage.
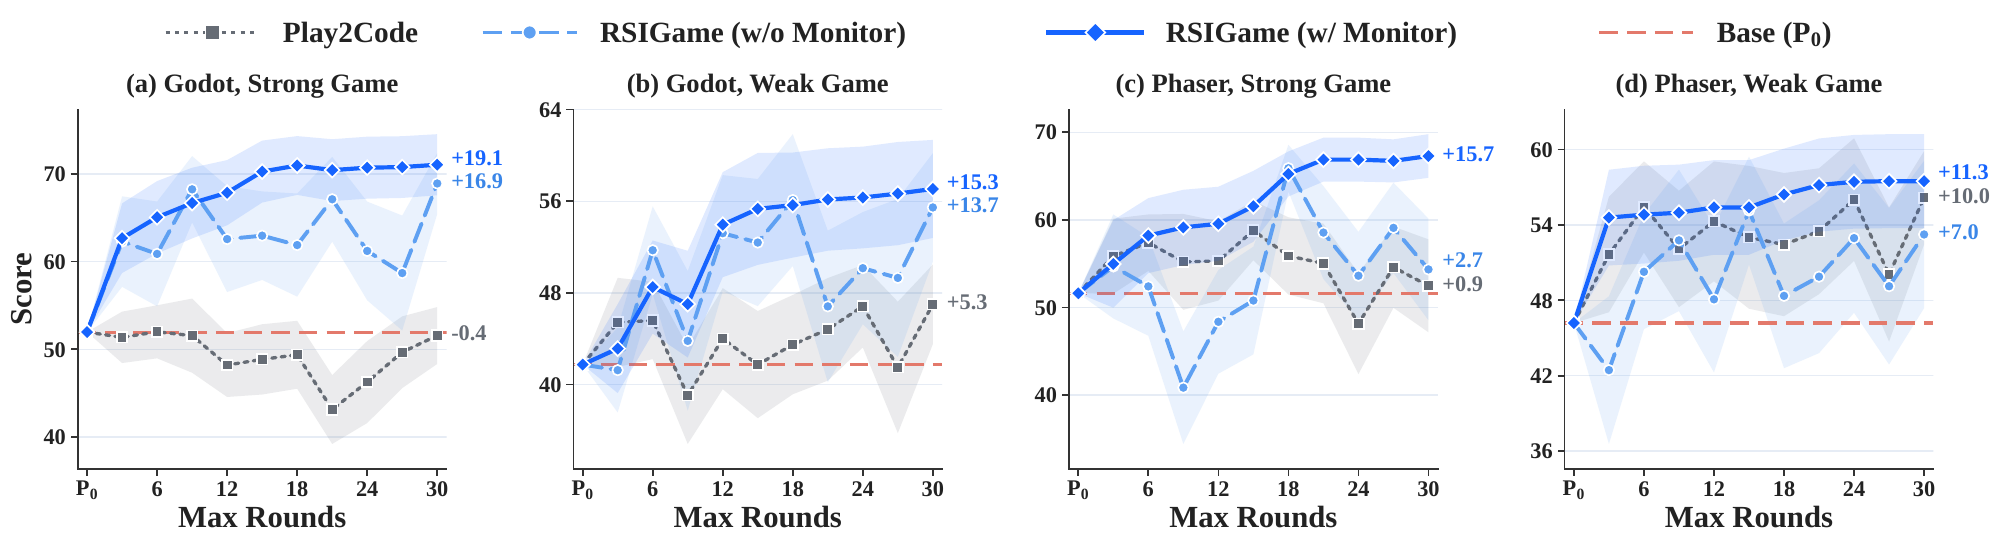 Mean Overall of the build a budget of k rounds delivers. A free-form
playtest-and-revise baseline finishes a strong base where it started; the
Global Quality Monitor is what keeps late rounds from undoing earlier gains.
Installation
Requires Linux (or macOS): the loop runs its agents in process groups and
cleans them up with os.killpg, which Windows does not have.
git clone https://github.com/WenyiWU0111/RSIGame.git && cd RSIGame
pip install -e .
GameCraft-Bench supplies the tasks, rubrics and replay harness. It is a
separate checkout, patched by the files in patches/ (see patches/README.txt)
and installed into the same environment:
git clone https://github.com/FreedomIntelligence/gamecraft-bench.git ../gamecraft-bench
git -C ../gamecraft-bench checkout a43347534374df9a0c1a6c001aa9380862783f6d
git -C ../gamecraft-bench apply ../RSIGame/patches/gamecraft-bench_rsigame_scoring.patch
git -C ../gamecraft-bench apply ../RSIGame/patches/gamecraft-bench_openrouter_provider_pin.patch
pip install -e ../gamecraft-bench
The repair agent is a Node script in
OpenGame-RSIGame, our fork of
OpenGame. Both engines need it.
Upstream OpenGame does not have agent_repair.ts or the changes it depends on.
It needs Node 20+:
git clone https://github.com/WenyiWU0111/OpenGame-RSIGame.git ../OpenGame-RSIGame
cd ../OpenGame-RSIGame && npm install && npm run build && cd -
Godot 4.6.2 for the Godot line, and the replay tools GameCraft-Bench drives:
sudo apt-get install -y --no-install-recommends xvfb xdotool ffmpeg \
    libxcursor1 libxinerama1 libxrandr2 libxi6 libgl1 libegl1
# Godot: https://github.com/godotengine/godot/releases/tag/4.6.2-stable
Quick start
cp .env.example .env            # a model API key, plus the image-generation keys for art rounds
$EDITOR configs/default.toml    # [paths]: bench, bench_godot_bin, opengame_agent_test

rsigame config                  # what a run would actually use, resolved
rsigame check                   # paths, keys and the repair agent, before anything runs
A run develops a base game from a corpus directory with one sub-directory per
task. The base games behind Table 1 are on Hugging Face. For example, the GPT-5.5
Godot bases are in
t1/gpt55/base/games.tar.gz:
huggingface-cli download RSIGame/RSIGame-TableArtifacts t1/gpt55/base/games.tar.gz \
    --repo-type dataset --local-dir .
mkdir -p corpus_godot_gpt55 && tar -xzf t1/gpt55/base/games.tar.gz -C corpus_godot_gpt55
rsigame -c paper_godot_gpt develop puzzle-sokoban-dungeon \
    --corpus corpus_godot_gpt55 --root runs/paper_godot_gpt
-c can go before or after the subcommand. rsigame check is worth running
first: a missing bench path, key or repair agent used to surface at round 12,
not at round 0.
Configuration
Three layers, each overriding the one above:
configs/default.toml — every knob and the default the code itself uses-c configs/experiment/<name>.toml — what one experiment changes- environment variables — a temporary override mid-run
Every variable this project owns is RSIGAME_<SECTION>_<KEY>, matching
[section] key in the toml exactly. Secrets are read from .env only, never
from a toml.
Stopping early
The monitor decides which build is the best seen so far, and the saturation stop decides
when development has stopped paying: K consecutive checkpoints with an unchanged
champion. [monitor] live picks how it runs:
|
what happens |
what a run costs |
live = false (default) |
every round runs; scripts/vm_replay.py replays the checkpoints afterwards and python -m rsigame.monitor.value_stop reads where the run would have stopped |
the full budget, every arm the same — this is what the paper reports |
live = true |
the monitor judges each checkpoint as the run goes and ends the run when the saturation stop fires |
fewer rounds, and arms no longer share a budget |
A live monitor never kills a round mid-flight, never rolls the tree back, and
drops itself for the rest of the run if the estimator fails — an outage must not
look like saturation.
What a run cost
Every model call the run makes goes through a loopback proxy, so the accounting
covers the whole loop — Controller, Explorer, Verifier and Monitor, not only the
repair subprocess. Two files land beside the rounds:
| file |
what is in it |
all_token_calls.jsonl |
one line per call: endpoint, model, prompt/completion/cached/reasoning tokens, cost |
all_token_totals.json |
the same summed, written when the run ends — including a run that stopped early |
The proxy forwards to one upstream and signs with one key, so it only takes over
an endpoint that already points at that upstream; anything left unmetered (a
monitor pointed at its own provider, say) is named in the run log.
Scoring
Both engines are scored by the same GameCraft-Bench rubric,
Overall = BUILD × (0.15·Mechanics + 0.35·Depth + 0.15·Visuals + 0.35·Art),
by replaying scripted demos and judging the recordings.
python -m rsigame.eval.score_game --project <tree> --game <task> --output <dir>   # Godot
scripts/score_checkpoints.py      <run root>                                      # Godot, every Nth round
scripts/score_checkpoints_web.py  <run root>                                      # Phaser, every Nth round
The engines differ in about 900 lines out of 48k: the build gate (Godot's
headless import against the web build check on dist/), how a demo is replayed,
how a project tree is read, and the engine-specific half of the repair prompt.
Everything else is shared.
Layout
src/rsigame/
  loop.py            one development round: explore → diagnose → edit → verify
  project.py         a game project: copy it, build it, import it, read it
  cli.py  config.py  paths.py  preflight.py

  planning/          what a round is for, and what it will work on
  checklist/         what the task asked for, and what is true of it now
  view/              what the build contains, read from the tree
  controller/        how the work is chosen and how the repair is asked for
  evidence/          what was observed, frozen so a later round can cite it
  polish/            the quality pass: the largest remaining bottleneck
  verify/            replay a repair and decide whether it earned its commit
  monitor/           the champion across rounds, and the saturation stop
  eval/              scoring, the proxy estimator, pairwise judging
  agent/             the exploration arm: sessions, probes, the repair agent
  review/            the human review tool used for outer guidance

  data_pipeline/     recorded sessions -> a supervised fine-tuning corpus
  training/          the corpus -> a LoRA adapter, merged for serving
configs/             every knob, with its default and a comment
scripts/             scoring and replay entry points
patches/             the changes this work applies to GameCraft-Bench
Data
Base games, run trees, recordings and scores are not in this repo. The scoring
artefacts every number in the paper is read from are on Hugging Face at
RSIGame/RSIGame-TableArtifacts:
for every row of Tables 1 and 2, the base game, the build that was scored, and
the judge's records.
Coming soon. The base games, run trees, supervised corpus and model
weights are going through our company's internal review, and will be released
under RSIGame as soon as it is approved.
Until then, data_pipeline/ documents how the corpus is built from recordings
and training/ how one arm is trained, so both can be rebuilt rather than taken
on trust.
Notes
tests/test_no_leaks.py runs on every commit: no credentials, no absolute
machine paths, no internal endpoints, no personal emails, no legacy variable
names.tests/test_imports_resolve.py resolves every internal import at any nesting
depth, including imports inside functions — the kind a passing test suite
otherwise hides until a real run reaches that line.- Two prompt strings in
eval/estimator/ are Chinese and stay that way: they are
sent to the judge, and the paper's numbers were produced with that wording.
License
Apache-2.0. This work builds on OpenGame
(Apache-2.0) for the Phaser line and on
GameCraft-Bench for
the tasks and the scoring harness; see NOTICE. No source from either is
redistributed here.
Citation
@misc{wu2026rsigame,
  title  = {RSIGame: Autonomous Agentic Game Development with Recursive Self-improvement},
  author = {Wu, Wenyi and Fu, Minghao and You, Jieyu and Zhou, Kun and Liu, Siqi and
            Salvi, Aayush and Lin, Yiheng and Zhang, Ce and Lan, Xiaohan and Zhu, Jiahui and
            Zhong, Yujie and She, Qi and Huang, Biwei},
  year   = {2026},
  eprint = {2609.39045},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  url    = {https://arxiv.org/abs/2609.39045}
}




 RSIGame 是一个自主的智能体游戏开发框架,在游戏生成出第一个可玩版本之后持续改进它,运行“探索-诊断-改进”循环,不断修复并验证游戏,直到改进趋于饱和。